You are viewing a plain text version of this content. The canonical link for it is here.
Posted to dev@hugegraph.apache.org by "bitflicker64 (via GitHub)" <gi...@apache.org> on 2026/09/23 11:11:43 UTC
[I] [Bug] A Store rebuilt with an empty volume never rejoins its raft groups; retirement (Tombstone + patrol) cannot repair it and every health surface reads healthy [hugegraph]
bitflicker64 opened a new issue, #3227:
URL: https://github.com/apache/hugegraph/issues/3227

   ### Bug Type (问题类型)
   server status (启动/运行异常)

   ### Before submit
   - [x] I have confirmed and searched that there are no similar problems in the historical issue and documents

   ### Environment (环境信息)
   - Server Version: master `83ef9f3` (Docker Hub `:latest` of 2026-09-21: pd `sha256:69dc1d4e8625`, store `sha256:7bc0cbd81550`, server `sha256:9229e5a5f1bf`)
   - Backend: HStore, 3 PD + 3 Store + 3 Server, shard count 3, 12 shard groups
   - OS: kind v0.33 (Kubernetes 1.37.0), 12 CPUs, 15G RAM, deployed with the Helm chart from hugegraph/hugegraph#221
   - Data Size: about 9k vertices, 9k edges

   ### Expected & Actual behavior (期望与实际表现)

   Rebuilding one Store from scratch (delete its data volume, restart it at the same DNS/raft address, as a Kubernetes StatefulSet does) and retiring the old store id should end with three full replicas per shard group.

   Measured on 2026-09-22:

   1. The rebuilt Store registers a new id (`7279...`) at the same raft address; the old id (`1190...`) stays with all 12 groups.
   2. `POST /v1/store/{oldId}` with `{"storeState":"Tombstone"}` returns 200. `patrolPartitions` on the PD leader logs `shardOffline` for all 12 partitions and `reallocShards ShardGroup N, add shards from 2 to 3` with the NEW id in the computed list, and fires the conf change.
   3. The Store leader logs `Raft N changePeers start, old peer is [... same address ...]`: the new peer's endpoint is already in the raft configuration, so jraft has nothing to add and the rebuilt Store never receives a snapshot.
   4. `PartitionEngine.onConfigurationCommitted` then maps each endpoint back to a store id through the local shard group (`PartitionManager.getStoreByRaftEndpoint`, hg-store-core, PartitionManager.java:873-881), which still lists the OLD id, and pushes that group to PD (PartitionEngine.java:631-681), overwriting PD's corrected record.
   5. End state, stable for 20+ minutes across three patrols, `DELETE /v1/store/{oldId}` and `balancePartitions` (`movedPartitions is empty ... newId=0`): all 12 groups name a store id that no longer exists, the rebuilt Store answers 500 for every `GET :8520/v1/partition/{id}` (no partition engines), and every group runs on two live replicas.

   The failure is invisible: `/v1/stores` counts 3 Up, cluster state stays `Cluster_OK`, Hubble shows 3 Stores UP, all Pods Ready. Writes kept working (2/3 replicas), 0 lost of 4498 acknowledged.

   Related: #3150 (closed stale) reported Tombstone not migrating replicas in a 5-store bare-metal cluster; same code area, different trigger. This report is the address-reuse case, which is what any StatefulSet rebuild produces.

   Possible directions (not verified): resolve endpoint-to-id against PD's current store list preferring Up over Tombstone; drive remove-then-add when the new id shares an endpoint so the rebuilt Store gets a snapshot; refuse or auto-retire a non-Tombstone store record at registration when a new id claims its raft address.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: dev-unsubscribe@hugegraph.apache.org.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
Re: [I] [Bug] A Store rebuilt with an empty volume never rejoins its raft groups; retirement (Tombstone + patrol) cannot repair it and every health surface reads healthy [hugegraph]
Posted by "bitflicker64 (via GitHub)" <gi...@apache.org>.
bitflicker64 commented on issue #3227:
URL: https://github.com/apache/hugegraph/issues/3227#issuecomment-5811759906

   Fix is up in #3234. When a ChangeShard names a new store id at an unchanged raft address, the Store leader now creates the raft node on the rebuilt Store (jraft installs a snapshot into it) and takes PD's store id, so the heartbeat stops writing the old id back. On images from the branch the scenario from this report converged 17 s after the Tombstone; the images it was measured on still fail the same way in the control run. Evidence is linked in the PR.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [I] [Bug] A Store rebuilt with an empty volume never rejoins its raft groups; retirement (Tombstone + patrol) cannot repair it and every health surface reads healthy [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin closed issue #3227: [Bug] A Store rebuilt with an empty volume never rejoins its raft groups; retirement (Tombstone + patrol) cannot repair it and every health surface reads healthy
URL: https://github.com/apache/hugegraph/issues/3227


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: dev-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
Re: [I] [Bug] A Store rebuilt with an empty volume never rejoins its raft groups; retirement (Tombstone + patrol) cannot repair it and every health surface reads healthy [hugegraph]
Posted by "bitflicker64 (via GitHub)" <gi...@apache.org>.
bitflicker64 commented on issue #3227:
URL: https://github.com/apache/hugegraph/issues/3227#issuecomment-5795391573
Diagram of the mechanism, and answers to the two questions from review: how rare the trigger is, and whether the fix is contained.
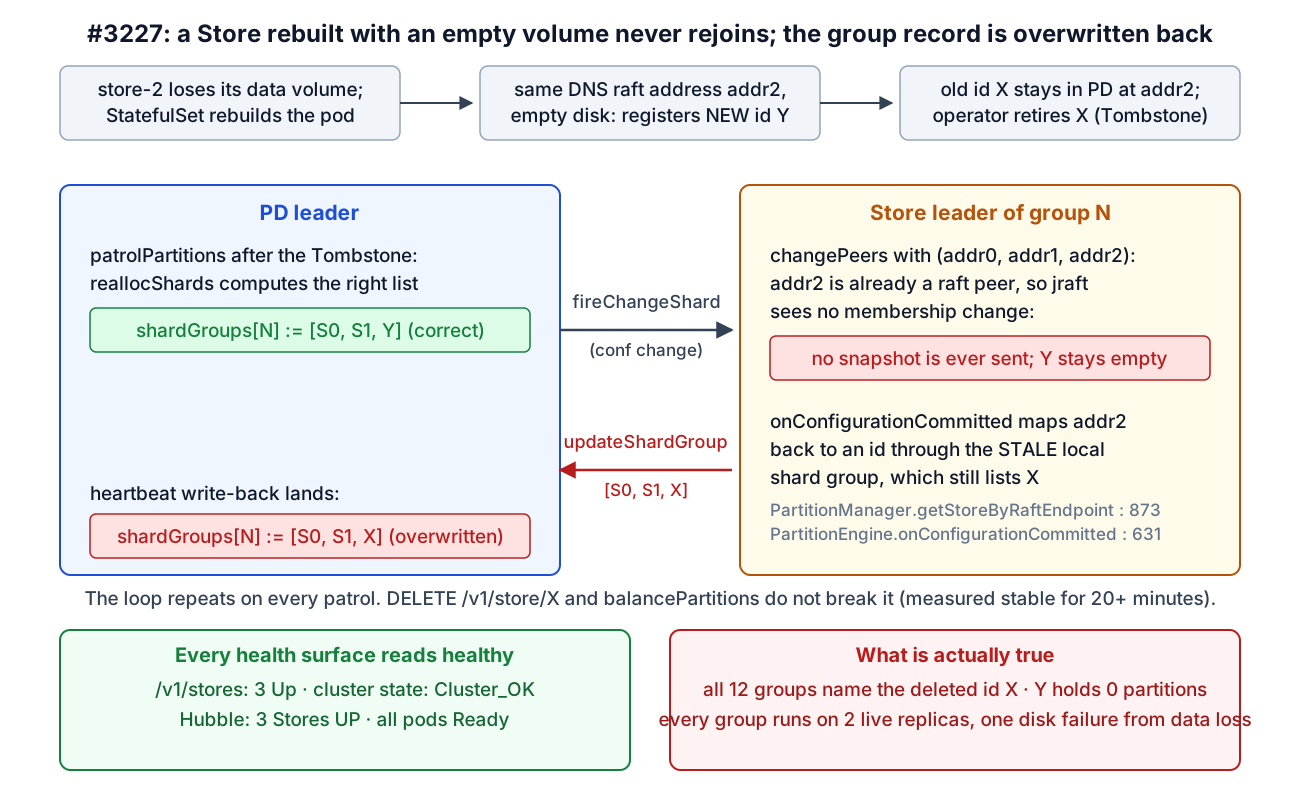
**Trigger.** The event is uncommon (a Store's data volume lost: disk failure, PVC deletion, node loss with local storage). The path is not: on Kubernetes a StatefulSet always rebuilds the pod at the same DNS raft address, so this is the default recovery route after any volume loss, and a bare-metal rebuild reusing host:port hits the same code. The multiplier is silence: nothing reports the lost replica, so the state persists until the next failure makes it two of three lost.
**Fix shape.** Two bounded parts, no protocol change:
1. Stop the overwrite: `getStoreByRaftEndpoint` falls back to PD's store list (preferring `Up`) when the id its local group holds for that address is no longer an active store. Small, `hg-store-core` only, fixes the bookkeeping.
2. Make data flow: the group needs a real membership change so jraft installs a snapshot on the new id. Either PD drives remove-then-add when `reallocShards` swaps the id at an unchanged address, or the Store creates the missing partition engine when a conf notice names an address it serves with no engine. A few hundred lines in one module, depending on which layer owns it.
Which layer do you prefer for part 2? I can build it and re-run the measured scenario from this report as the regression check.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org