You are viewing a plain text version of this content. The canonical link for it is here.
Posted to github@arrow.apache.org by GitBox <gi...@apache.org> on 2021/03/02 20:41:31 UTC
[GitHub] [arrow] lidavidm opened a new pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
lidavidm opened a new pull request #9620:
URL: https://github.com/apache/arrow/pull/9620


   This provides an async Parquet reader where the unit of concurrency is a single row group.

   There are some caveats still:
   - [ ] This implementation is unsafe if pre_buffer=True in ArrowReaderProperties. Instead, the user needs to manually call file_reader()->parquet_reader()->PreBuffer(). I expect the kind of application using the async reader would also want to control this anyways, so I'd lean towards just failing the call if the user has pre_buffer=True, but the other commit in this PR provides a version that is safe with pre_buffer=True at the cost of some code duplication.
   - [ ] There are some TODOs scattered around for after #9607 is merged.
   - [ ] Docstrings need writing.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r643102629


##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -563,6 +692,28 @@ std::unique_ptr<ParquetFileReader> ParquetFileReader::OpenFile(
   return Open(std::move(source), props, std::move(metadata));
 }

+::arrow::Future<std::unique_ptr<ParquetFileReader>> ParquetFileReader::OpenAsync(
+    std::shared_ptr<::arrow::io::RandomAccessFile> source, const ReaderProperties& props,
+    std::shared_ptr<FileMetaData> metadata) {
+  BEGIN_PARQUET_CATCH_EXCEPTIONS
+  auto fut = SerializedFile::OpenAsync(std::move(source), props, std::move(metadata));
+  // TODO(ARROW-12259): workaround since we have Future<(move-only type)>

Review comment:
       The workaround is using AddCallback and marking a future complete manually instead of using Then.

##########
File path: cpp/src/arrow/util/future.h
##########
@@ -829,6 +829,9 @@ Future<std::vector<Result<T>>> All(std::vector<Future<T>> futures) {
   return out;
 }

+template <>
+inline Future<>::Future(Status s) : Future(internal::Empty::ToResult(std::move(s))) {}

Review comment:
       This is because the usual implicit constructor for `Future<Status>` delegates to `Future(Result<ValueType>(Status))` which errors on an OK Status (the assumption being that an OK Status will never arise); however for `Future<>` we actually do want to handle an OK Status.

   It's not inline because it's a specialization for `Future<>`. I tried to use `enable_if` to do it inline but couldn't figure out the right template magic needed to get it to work.

##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -21,6 +21,8 @@
 #include <memory>
 #include <vector>

+#include "arrow/util/async_generator.h"

Review comment:
       I think we've run into this before - with the current definition of AsyncGenerator we can't easily provide a forward declaration, right?

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -264,23 +264,92 @@ class SerializedFile : public ParquetFileReader::Contents {
       }
     }
     PARQUET_THROW_NOT_OK(cached_source_->Cache(ranges));
-    return cached_source_->Wait();
   }

+  ::arrow::Future<> WhenBuffered(const std::vector<int>& row_groups,
+                                 const std::vector<int>& column_indices) const {
+    if (!cached_source_) {
+      return ::arrow::Status::Invalid("Must call PreBuffer before WhenBuffered");
+    }
+    std::vector<::arrow::io::ReadRange> ranges;
+    for (int row : row_groups) {
+      for (int col : column_indices) {
+        ranges.push_back(
+            ComputeColumnChunkRange(file_metadata_.get(), source_size_, row, col));
+      }
+    }
+    return cached_source_->WaitFor(ranges);
+  }
+
+  // Metadata/footer parsing. Divided up to separate sync/async paths, and to use
+  // exceptions for error handling (with the async path converting to Future/Status).
+
   void ParseMetaData() {

Review comment:
       Originally I did do that but found I was having issues with the encryption test flaking on Windows. I couldn't see why this change affected that (since we wait for the future to complete) but refactoring it like this fixed it. Also, this means we don't need a custom StatusDetail to preserve the original exception class thrown.

##########
File path: cpp/src/parquet/encryption/test_encryption_util.cc
##########
@@ -334,7 +335,10 @@ void FileDecryptor::DecryptFile(
     reader_properties.file_decryption_properties(file_decryption_properties->DeepClone());
   }

-  auto file_reader = parquet::ParquetFileReader::OpenFile(file, false, reader_properties);
+  std::shared_ptr<::arrow::io::RandomAccessFile> source;
+  PARQUET_ASSIGN_OR_THROW(
+      source, ::arrow::io::ReadableFile::Open(file, reader_properties.memory_pool()));

Review comment:
       I was having issues with the encryption tests on Windows, which would flake because the temp Parquet file was still in use when it deleted it. This was an attempt at fixing that.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-812701516
Okay, now that I've actually checked out the right branch…
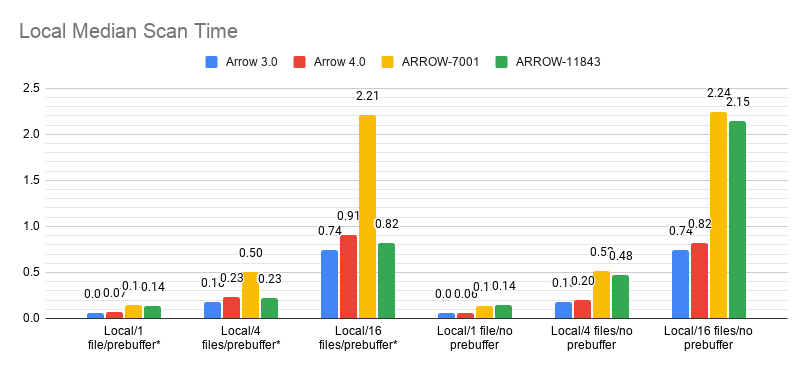
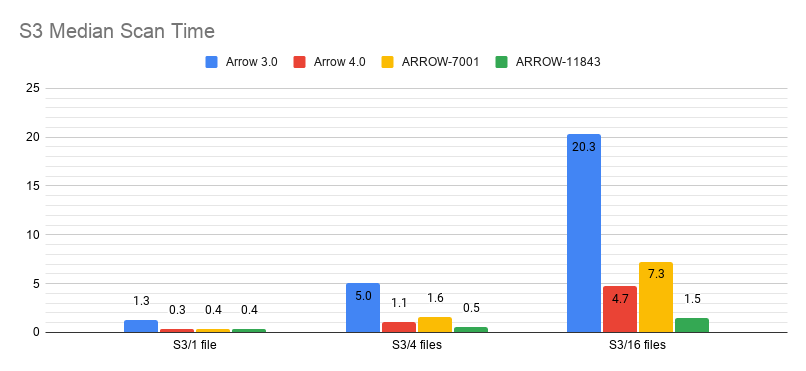
So long as pre-buffering is enabled, this PR in conjunction with ARROW-7001 is either a big win (for S3) or no effect (locally). Hence I'd argue we should just always enable pre-buffer. (The reason is that without refactoring the Parquet reader heavily, without enabling pre-buffer, the generator is effectively synchronous. I could go through and do the refactor, but pre-buffering gives us an 'easy' way to convert the I/O to be async. If we want, we could change the read range cache to optionally be lazy, which would effectively be the same as refactoring the Parquet reader.)
Also, this changes the ParquetScanTask so that it manages intra-file concurrency internally. Hence, ParquetFileFragment only needs to generate one scan task now and doesn't have to do anything complicated around pre-buffering.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-812174345


   (FWIW, I'm currently reworking this so that it gives just `AsyncGenerator<RecordBatch>`, and to manage pre-buffering internally so that the user doesn't have to worry about it, similar to CSV and IPC. The granularity of pre-buffering will be per-row-group which is not ideal for small row groups, but that could be improved.)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] github-actions[bot] commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
github-actions[bot] commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-789283600


   https://issues.apache.org/jira/browse/ARROW-11843


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r622647276


##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,
+                              reader_fut.MoveResult());
+        std::shared_ptr<parquet::FileMetaData> metadata = reader->metadata();
+        auto arrow_properties = MakeArrowReaderProperties(*self, *metadata);
+        if (options) {
+          arrow_properties.set_batch_size(options->batch_size);
+        }
+        if (options && !options->use_threads) {
+          arrow_properties.set_use_threads(
+              parquet_scan_options->enable_parallel_column_conversion);

Review comment:
       This could be a nice win for async in the HDD/SSD space (still recommending a follow-up future).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r643133844


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +980,102 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch generators (where each sub-generator is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using RecordBatchGenerator =
+      ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(std::shared_ptr<FileReaderImpl> arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(std::move(arrow_reader)),
+        executor_(executor),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)),
+        index_(0) {}
+
+  ::arrow::Future<RecordBatchGenerator> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::AsyncGeneratorEnd<RecordBatchGenerator>();
+    }
+    int row_group = row_groups_[index_++];
+    std::vector<int> column_indices = column_indices_;
+    auto reader = arrow_reader_;
+    if (!reader->properties().pre_buffer()) {
+      return SubmitRead(executor_, reader, row_group, column_indices);
+    }
+    auto ready = reader->parquet_reader()->WhenBuffered({row_group}, column_indices);
+    if (executor_) ready = executor_->Transfer(ready);
+    return ready.Then([=]() -> ::arrow::Result<RecordBatchGenerator> {

Review comment:
       I filed ARROW-12916.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-849715920


   @pitrou would you have time to review the Parquet reader parts of this PR? Particularly where the footer reading code has been refactored.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on a change in pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r643132246


##########
File path: cpp/src/arrow/util/future.h
##########
@@ -829,6 +829,9 @@ Future<std::vector<Result<T>>> All(std::vector<Future<T>> futures) {
   return out;
 }

+template <>
+inline Future<>::Future(Status s) : Future(internal::Empty::ToResult(std::move(s))) {}

Review comment:
       Ah, thank you.

##########
File path: cpp/src/parquet/encryption/test_encryption_util.cc
##########
@@ -334,7 +335,10 @@ void FileDecryptor::DecryptFile(
     reader_properties.file_decryption_properties(file_decryption_properties->DeepClone());
   }

-  auto file_reader = parquet::ParquetFileReader::OpenFile(file, false, reader_properties);
+  std::shared_ptr<::arrow::io::RandomAccessFile> source;
+  PARQUET_ASSIGN_OR_THROW(
+      source, ::arrow::io::ReadableFile::Open(file, reader_properties.memory_pool()));

Review comment:
       Fair enough, thanks :-)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591935894


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(

Review comment:
       Ok, if you plan to do that buffering elsewhere then this is fine.  I guess I misunderstood then.  So the point in breaking things into tasks here is to allow for parallelism?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r622646719


##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,
+                              reader_fut.MoveResult());
+        std::shared_ptr<parquet::FileMetaData> metadata = reader->metadata();
+        auto arrow_properties = MakeArrowReaderProperties(*self, *metadata);
+        if (options) {
+          arrow_properties.set_batch_size(options->batch_size);
+        }
+        if (options && !options->use_threads) {
+          arrow_properties.set_use_threads(
+              parquet_scan_options->enable_parallel_column_conversion);

Review comment:
       Ah, actually, that makes sense.  It would get stuck here: https://github.com/lidavidm/arrow/blob/parquet-reentrant/cpp/src/parquet/arrow/reader.cc#L959

   `ParallelFor` does a blocking wait.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-832281967


   > Sync -> exception and Async -> no exception is easy enough to remember (although tricky to implement it seems). Do you think there are any utilities we could add to futures to make that easier?

   I think the existing utilities (combined with the implicit Future(Status) constructor) do a good enough job. Also, it's isolated to the Parquet codebase, so I'm not too worried about exceptions. The changes were less about exceptions per se and more about just disentangling the I/O from the footer logic so we could make it sync/async as needed.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r643540804


##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -264,23 +264,92 @@ class SerializedFile : public ParquetFileReader::Contents {
       }
     }
     PARQUET_THROW_NOT_OK(cached_source_->Cache(ranges));
-    return cached_source_->Wait();
   }

+  ::arrow::Future<> WhenBuffered(const std::vector<int>& row_groups,
+                                 const std::vector<int>& column_indices) const {
+    if (!cached_source_) {
+      return ::arrow::Status::Invalid("Must call PreBuffer before WhenBuffered");
+    }
+    std::vector<::arrow::io::ReadRange> ranges;
+    for (int row : row_groups) {
+      for (int col : column_indices) {
+        ranges.push_back(
+            ComputeColumnChunkRange(file_metadata_.get(), source_size_, row, col));
+      }
+    }
+    return cached_source_->WaitFor(ranges);
+  }
+
+  // Metadata/footer parsing. Divided up to separate sync/async paths, and to use
+  // exceptions for error handling (with the async path converting to Future/Status).
+
   void ParseMetaData() {

Review comment:
       I've updated the current encryption tests to test both Open and OpenAsync (though let's hope they don't make the test flaky again).

##########
File path: cpp/src/parquet/arrow/arrow_reader_writer_test.cc
##########
@@ -2331,6 +2330,63 @@ TEST(TestArrowReadWrite, GetRecordBatchReaderNoColumns) {
   ASSERT_EQ(actual_batch->num_rows(), num_rows);
 }

+TEST(TestArrowReadWrite, GetRecordBatchGenerator) {
+  ArrowReaderProperties properties = default_arrow_reader_properties();
+  const int num_rows = 1024;
+  const int row_group_size = 512;
+  const int num_columns = 2;
+
+  std::shared_ptr<Table> table;
+  ASSERT_NO_FATAL_FAILURE(MakeDoubleTable(num_columns, num_rows, 1, &table));
+
+  std::shared_ptr<Buffer> buffer;
+  ASSERT_NO_FATAL_FAILURE(WriteTableToBuffer(table, row_group_size,
+                                             default_arrow_writer_properties(), &buffer));
+
+  std::shared_ptr<FileReader> reader;
+  {
+    std::unique_ptr<FileReader> unique_reader;
+    FileReaderBuilder builder;
+    ASSERT_OK(builder.Open(std::make_shared<BufferReader>(buffer)));
+    ASSERT_OK(builder.properties(properties)->Build(&unique_reader));
+    reader = std::move(unique_reader);
+  }
+
+  auto check_batches = [](const std::shared_ptr<::arrow::RecordBatch>& batch,
+                          int num_columns, int num_rows) {
+    ASSERT_NE(batch, nullptr);
+    ASSERT_EQ(batch->num_columns(), num_columns);
+    ASSERT_EQ(batch->num_rows(), num_rows);

Review comment:
       I've adjusted the test to check equality below.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm edited a comment on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm edited a comment on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-812194926


   What I pushed is still not quite what I want. Ideally, we'd be able to ask the read cache for a future that finishes when all I/O for the given row group has completed. That way, we can then kick off a decoding task. On master, currently, you just spawn a bunch of tasks that block and wait for I/O and then proceed (wasting threads), and in this PR, we have hijinks to manually pre-buffer each row group separately (wasting the effectiveness of pre-buffering).

   That is, we should be able to say

   ```
   reader->PreBuffer(row_groups, columns)
   ...
   // I/O generator
   return reader->WhenBuffered({current_row_group}, {columns});

   // Decoding generator
   return cpu_executor_->Transfer(io_generator()).Then([]() { return ReadRowGroup(current_row_group); });
   ```

   and this will let us coalesce read ranges across row groups while only performing work on the CPU pool when it's truly ready.

   Also, the range cache will have to be swappable for something that just does normal file I/O for the non-S3 case so that local file scans are still reasonable.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-856112569


   Travis-CI build at https://travis-ci.com/github/pitrou/arrow/builds/228224255


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591938334


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(
+                              &ReadOneRowGroup, self, row_group, column_indices));
+    return fut;
+  }
+
+ private:
+  static ::arrow::Result<Item> ReadOneRowGroup(FileReaderImpl* self, const int row_group,
+                                               const std::vector<int>& column_indices) {
+    std::shared_ptr<::arrow::Table> table;
+    // Call the version that skips bound checks/pre-buffering, since we've done that
+    // already
+    RETURN_NOT_OK(self->ReadRowGroupsImpl({row_group}, column_indices, &table));
+    auto table_reader = std::make_shared<::arrow::TableBatchReader>(*table);
+    ::arrow::RecordBatchVector batches;
+    while (true) {
+      std::shared_ptr<::arrow::RecordBatch> batch;
+      RETURN_NOT_OK(table_reader->ReadNext(&batch));
+      if (!batch) {
+        break;
+      }
+      batches.push_back(batch);
+    }
+    return ::arrow::util::make_optional<::arrow::RecordBatchVector>(std::move(batches));
+  }
+
+  FileReaderImpl* self_;
+  size_t index_;
+  std::vector<int> row_groups_;
+  std::vector<int> column_indices_;
+};
+
+::arrow::Result<
+    ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+FileReaderImpl::GetRecordBatchGenerator(const std::vector<int>& row_groups,
+                                        const std::vector<int>& column_indices) {
+  RETURN_NOT_OK(BoundsCheck(row_groups, column_indices));
+  if (reader_properties_.pre_buffer()) {
+    // PARQUET-1698/PARQUET-1820: pre-buffer row groups/column chunks if enabled
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    reader_->PreBuffer(row_groups, column_indices, reader_properties_.io_context(),
+                       reader_properties_.cache_options());
+    END_PARQUET_CATCH_EXCEPTIONS
+  }
+  // N.B. we (and underlying Parquet reader) must outlive generator
+  return RowGroupGenerator(this, row_groups, column_indices);

Review comment:
       I can go ahead and copy the scan task into the `Then` callback to preserve its lifetime but can you add a comment to `ScanTask` explaining this requirement?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-795970642


   CC @westonpace here as well. `AsyncGenerator<vector<shared_ptr<RecordBatch>>>` might be a little annoying to work with if the target type is `AsyncGenerator<shared_ptr<RecordBatch>>`, thoughts?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r620702796


##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,
+                              reader_fut.MoveResult());
+        std::shared_ptr<parquet::FileMetaData> metadata = reader->metadata();
+        auto arrow_properties = MakeArrowReaderProperties(*self, *metadata);
+        if (options) {
+          arrow_properties.set_batch_size(options->batch_size);
+        }
+        if (options && !options->use_threads) {
+          arrow_properties.set_use_threads(
+              parquet_scan_options->enable_parallel_column_conversion);

Review comment:
       I don't think we need to look at `enable_parallel_column_conversion` anymore since we're async?

##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -188,17 +223,51 @@ Result<std::shared_ptr<Buffer>> ReadRangeCache::Read(ReadRange range) {
       [](const RangeCacheEntry& entry, const ReadRange& range) {
         return entry.range.offset + entry.range.length < range.offset + range.length;
       });
+  std::unique_lock<std::mutex> guard = impl_->TakeGuard();
   if (it != impl_->entries.end() && it->range.Contains(range)) {
-    ARROW_ASSIGN_OR_RAISE(auto buf, it->future.result());
+    auto fut = impl_->GetFuture(&*it);

Review comment:
       `&*it` -> `it` unless I'm missing something

##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -150,11 +153,44 @@ struct ReadRangeCache::Impl {
       entries = std::move(new_entries);
     }
   }
+
+  virtual std::unique_lock<std::mutex> TakeGuard() {
+    return std::unique_lock<std::mutex>();
+  }
+
+  virtual Future<std::shared_ptr<Buffer>> GetFuture(RangeCacheEntry* entry) {
+    return entry->future;
+  }
+
+  virtual RangeCacheEntry Cache(const ReadRange& range) {
+    return {range, file->ReadAsync(ctx, range.offset, range.length)};
+  }
+};
+
+struct ReadRangeCache::LazyImpl : public ReadRangeCache::Impl {
+  std::mutex entry_mutex;
+
+  virtual ~LazyImpl() = default;
+
+  std::unique_lock<std::mutex> TakeGuard() override {
+    return std::unique_lock<std::mutex>(entry_mutex);
+  }
+
+  Future<std::shared_ptr<Buffer>> GetFuture(RangeCacheEntry* entry) override {

Review comment:
       `GetFuture` is not a very clear name.  I'm not sure what a better one would be.  Maybe `GetOrIssueRead`?

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -996,6 +1100,13 @@ Status FileReaderImpl::ReadRowGroups(const std::vector<int>& row_groups,
     END_PARQUET_CATCH_EXCEPTIONS
   }

+  return ReadRowGroupsImpl(row_groups, column_indices, out);
+}
+
+// Also used by RowGroupGenerator - skip bounds check/pre-buffer to avoid doing that twice
+Status FileReaderImpl::ReadRowGroupsImpl(const std::vector<int>& row_groups,

Review comment:
       Naming nit: Maybe `DecodeRowGroup`?

##########
File path: cpp/src/arrow/python/io.cc
##########
@@ -265,6 +266,14 @@ Result<std::shared_ptr<Buffer>> PyReadableFile::ReadAt(int64_t position, int64_t
   });
 }

+Future<std::shared_ptr<Buffer>> PyReadableFile::ReadAsync(const io::IOContext&,

Review comment:
       This could become a problem (to be addressed in ARROW-12560) if nothing actually creates a thread task.

##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -150,11 +153,44 @@ struct ReadRangeCache::Impl {
       entries = std::move(new_entries);
     }
   }
+
+  virtual std::unique_lock<std::mutex> TakeGuard() {
+    return std::unique_lock<std::mutex>();
+  }
+
+  virtual Future<std::shared_ptr<Buffer>> GetFuture(RangeCacheEntry* entry) {
+    return entry->future;
+  }
+
+  virtual RangeCacheEntry Cache(const ReadRange& range) {
+    return {range, file->ReadAsync(ctx, range.offset, range.length)};
+  }
+};
+
+struct ReadRangeCache::LazyImpl : public ReadRangeCache::Impl {
+  std::mutex entry_mutex;

Review comment:
       Since this only exists on the lazy impl I'm guessing that means we are guarding `entries` because two or more threads might try to find-or-create `entry->future` at the same time but I'm not sure.

   If that is the case it seems like the mutex could be specific to `LazyImpl` (and not part of the interface)

   On the other hand, maybe you're guarding against modifying `entries` while iterating `entries` but I don't think made any changes regarding where `entries`' size is modified so if that is a concern it would be a concern with the eager version as well.

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -277,43 +292,56 @@ class SerializedFile : public ParquetFileReader::Contents {
     }

     int64_t footer_read_size = std::min(source_size_, kDefaultFooterReadSize);
-    PARQUET_ASSIGN_OR_THROW(
-        auto footer_buffer,
-        source_->ReadAt(source_size_ - footer_read_size, footer_read_size));
-
-    // Check if all bytes are read. Check if last 4 bytes read have the magic bits
-    if (footer_buffer->size() != footer_read_size ||
-        (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetMagic, 4) != 0 &&
-         memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) != 0)) {
-      throw ParquetInvalidOrCorruptedFileException(
-          "Parquet magic bytes not found in footer. Either the file is corrupted or this "
-          "is not a parquet file.");
-    }
-
-    if (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) == 0) {
-      // Encrypted file with Encrypted footer.
-      ParseMetaDataOfEncryptedFileWithEncryptedFooter(footer_buffer, footer_read_size);
-      return;
-    }
+    return source_->ReadAsync(source_size_ - footer_read_size, footer_read_size)
+        .Then([=](const std::shared_ptr<::arrow::Buffer>& footer_buffer)
+                  -> ::arrow::Future<> {
+          // Check if all bytes are read. Check if last 4 bytes read have the magic bits
+          if (footer_buffer->size() != footer_read_size ||
+              (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetMagic, 4) !=
+                   0 &&
+               memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) !=
+                   0)) {
+            return ::arrow::Status::FromDetailAndArgs(
+                ::arrow::StatusCode::IOError,
+                ParquetInvalidOrCorruptedFileStatusDetail::Instance(),
+                "Parquet magic bytes not found in footer. Either the file is corrupted "
+                "or this is not a parquet file.");
+          }

-    // No encryption or encryption with plaintext footer mode.
-    std::shared_ptr<Buffer> metadata_buffer;
-    uint32_t metadata_len, read_metadata_len;
-    ParseUnencryptedFileMetadata(footer_buffer, footer_read_size, &metadata_buffer,
-                                 &metadata_len, &read_metadata_len);
+          if (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) ==
+              0) {
+            // Encrypted file with Encrypted footer.
+            BEGIN_PARQUET_CATCH_EXCEPTIONS
+            return ParseMetaDataOfEncryptedFileWithEncryptedFooter(footer_buffer,

Review comment:
       Does this function throw exceptions?  It looks to me like that got changed when it changed to future.

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +979,99 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(FileReaderImpl* arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(arrow_reader),

Review comment:
       Do we want this to take `std::shared_ptr<FileReaderImpl>` so that we don't have to remember to keep the reader alive elsewhere?  On the other hand, if you don't want to take in `shared_ptr` then aren't you assuming `FileReaderImpl` is valid for the lifetime and you could make `SubmitRead` and `ReadOneRowGroup` non-static (and remove the `FileReaderImpl* self`)?

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +979,99 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;

Review comment:
       I could be sold on using `Item` for brevity since it is constrained to this file but maybe `Batches` or `Items` instead of `Item`?

##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -33,7 +34,7 @@ namespace io {

 CacheOptions CacheOptions::Defaults() {
   return CacheOptions{internal::ReadRangeCache::kDefaultHoleSizeLimit,
-                      internal::ReadRangeCache::kDefaultRangeSizeLimit};
+                      internal::ReadRangeCache::kDefaultRangeSizeLimit, false};

Review comment:
       `/*lazy=*/false`?  I'm not really sure what the rules are for those inline names.

##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,

Review comment:
       I'm a little bit surprised this works at all honestly.  Futures aren't really compatible with move-only types.  I thought you would have gotten a compile error.  This reminded me to create ARROW-12559.  As long as this works I think you're ok.  There is only one callback being added to `reader_fut` and you don't access the value that gets passed in as an arg here.

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +979,99 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(FileReaderImpl* arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(arrow_reader),
+        executor_(executor),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)),
+        index_(0) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::IterationEnd<Item>());
+    }
+    int row_group = row_groups_[index_++];
+    std::vector<int> column_indices = column_indices_;
+    auto reader = arrow_reader_;
+    if (!reader->properties().pre_buffer()) {
+      return SubmitRead(executor_, reader, row_group, column_indices);
+    }
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    auto ready = reader->parquet_reader()->WhenBuffered({row_group}, column_indices);
+    if (executor_) ready = executor_->Transfer(ready);
+    return ready.Then(
+        [=](const ::arrow::Result<::arrow::detail::Empty>& s) -> ::arrow::Result<Item> {
+          RETURN_NOT_OK(s);

Review comment:
       I think you can just take in `::arrow::detail::Empty&` and then you don't need the `RETURN_NOT_OK`

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +979,99 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(FileReaderImpl* arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(arrow_reader),
+        executor_(executor),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)),
+        index_(0) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::IterationEnd<Item>());
+    }
+    int row_group = row_groups_[index_++];
+    std::vector<int> column_indices = column_indices_;
+    auto reader = arrow_reader_;
+    if (!reader->properties().pre_buffer()) {
+      return SubmitRead(executor_, reader, row_group, column_indices);
+    }
+    BEGIN_PARQUET_CATCH_EXCEPTIONS

Review comment:
       I don't know the rules around `PARQUET_CATCH_EXCEPTIONS` but will it be a problem that `ReadOneRowGroup` runs (presumably) outside of this guard?

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -531,14 +584,42 @@ std::unique_ptr<ParquetFileReader::Contents> ParquetFileReader::Contents::Open(

   if (metadata == nullptr) {
     // Validates magic bytes, parses metadata, and initializes the SchemaDescriptor
-    file->ParseMetaData();
+    auto fut = file->ParseMetaData();
+    PARQUET_THROW_NOT_OK(fut.status());
   } else {
     file->set_metadata(std::move(metadata));
   }

   return result;
 }

+::arrow::Future<std::unique_ptr<ParquetFileReader::Contents>>
+ParquetFileReader::Contents::OpenAsync(std::shared_ptr<ArrowInputFile> source,
+                                       const ReaderProperties& props,
+                                       std::shared_ptr<FileMetaData> metadata) {
+  BEGIN_PARQUET_CATCH_EXCEPTIONS
+  std::unique_ptr<ParquetFileReader::Contents> result(
+      new SerializedFile(std::move(source), props));
+  SerializedFile* file = static_cast<SerializedFile*>(result.get());
+  if (metadata == nullptr) {

Review comment:
       Is this all to allow `unique_ptr` to work?  If so, maybe add a todo comment reference ARROW-12559


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r621179845


##########
File path: cpp/src/arrow/python/io.cc
##########
@@ -265,6 +266,14 @@ Result<std::shared_ptr<Buffer>> PyReadableFile::ReadAt(int64_t position, int64_t
   });
 }

+Future<std::shared_ptr<Buffer>> PyReadableFile::ReadAsync(const io::IOContext&,

Review comment:
       The issue is when the main thread holds the GIL and calls back into libarrow, and then libarrow tries to call back into Python. This is OK if it's all on the same thread but not if it's on different threads. Really, this is an implementation error (any such bindings in pyarrow should release the GIL) but I remember it bit me somewhere during this PR.

##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -33,7 +34,7 @@ namespace io {

 CacheOptions CacheOptions::Defaults() {
   return CacheOptions{internal::ReadRangeCache::kDefaultHoleSizeLimit,
-                      internal::ReadRangeCache::kDefaultRangeSizeLimit};
+                      internal::ReadRangeCache::kDefaultRangeSizeLimit, false};

Review comment:
       Note I split this out into ARROW-12522/#10145 so I'll fix things there and rebase here.

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +979,99 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(FileReaderImpl* arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(arrow_reader),
+        executor_(executor),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)),
+        index_(0) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::IterationEnd<Item>());
+    }
+    int row_group = row_groups_[index_++];
+    std::vector<int> column_indices = column_indices_;
+    auto reader = arrow_reader_;
+    if (!reader->properties().pre_buffer()) {
+      return SubmitRead(executor_, reader, row_group, column_indices);
+    }
+    BEGIN_PARQUET_CATCH_EXCEPTIONS

Review comment:
       It just expands to a `try { } catch`. However I'll audit these again…I dislike working in this module because we're mixing exceptions/Status and the OpenAsync work has just exacerbated that problem a lot.

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -277,43 +292,56 @@ class SerializedFile : public ParquetFileReader::Contents {
     }

     int64_t footer_read_size = std::min(source_size_, kDefaultFooterReadSize);
-    PARQUET_ASSIGN_OR_THROW(
-        auto footer_buffer,
-        source_->ReadAt(source_size_ - footer_read_size, footer_read_size));
-
-    // Check if all bytes are read. Check if last 4 bytes read have the magic bits
-    if (footer_buffer->size() != footer_read_size ||
-        (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetMagic, 4) != 0 &&
-         memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) != 0)) {
-      throw ParquetInvalidOrCorruptedFileException(
-          "Parquet magic bytes not found in footer. Either the file is corrupted or this "
-          "is not a parquet file.");
-    }
-
-    if (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) == 0) {
-      // Encrypted file with Encrypted footer.
-      ParseMetaDataOfEncryptedFileWithEncryptedFooter(footer_buffer, footer_read_size);
-      return;
-    }
+    return source_->ReadAsync(source_size_ - footer_read_size, footer_read_size)
+        .Then([=](const std::shared_ptr<::arrow::Buffer>& footer_buffer)
+                  -> ::arrow::Future<> {
+          // Check if all bytes are read. Check if last 4 bytes read have the magic bits
+          if (footer_buffer->size() != footer_read_size ||
+              (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetMagic, 4) !=
+                   0 &&
+               memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) !=
+                   0)) {
+            return ::arrow::Status::FromDetailAndArgs(
+                ::arrow::StatusCode::IOError,
+                ParquetInvalidOrCorruptedFileStatusDetail::Instance(),
+                "Parquet magic bytes not found in footer. Either the file is corrupted "
+                "or this is not a parquet file.");
+          }

-    // No encryption or encryption with plaintext footer mode.
-    std::shared_ptr<Buffer> metadata_buffer;
-    uint32_t metadata_len, read_metadata_len;
-    ParseUnencryptedFileMetadata(footer_buffer, footer_read_size, &metadata_buffer,
-                                 &metadata_len, &read_metadata_len);
+          if (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) ==
+              0) {
+            // Encrypted file with Encrypted footer.
+            BEGIN_PARQUET_CATCH_EXCEPTIONS
+            return ParseMetaDataOfEncryptedFileWithEncryptedFooter(footer_buffer,

Review comment:
       I'm going to try and rework what's here as mixing exceptions/Status/Future is painful + confusing.

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +979,99 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(FileReaderImpl* arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(arrow_reader),

Review comment:
       I'll change the API to have the user pass in the pointer. I'd rather have `shared_from_this` but I guess that won't work since it's typically used as a unique_ptr.

##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,

Review comment:
       In this case it works since Future internally heap-allocates its implementation, and yes, this is rather iffy, but works since this is the only callback. I'll add a TODO referencing ARROW-12259.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-843532932


   Sorry to bother you @emkornfield, but would you have time to review the changes here under src/parquet/reader.{cc,h}, since it refactors the footer parsing? Otherwise, I'll ask Antoine to take a look when he's back from leave. (I know there's a lot of other stuff in this PR, which Weston has looked through already.)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r621371508


##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -188,17 +223,51 @@ Result<std::shared_ptr<Buffer>> ReadRangeCache::Read(ReadRange range) {
       [](const RangeCacheEntry& entry, const ReadRange& range) {
         return entry.range.offset + entry.range.length < range.offset + range.length;
       });
+  std::unique_lock<std::mutex> guard = impl_->TakeGuard();
   if (it != impl_->entries.end() && it->range.Contains(range)) {
-    ARROW_ASSIGN_OR_RAISE(auto buf, it->future.result());
+    auto fut = impl_->GetFuture(&*it);

Review comment:
       Ah, ok, a new trick for me to learn then :)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-856015342


   Rebased, will merge. Thank you!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591890348


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(

Review comment:
       Ah, ok - I was envisioning that the caller would explicitly buffer beforehand (since we had been talking about splitting up ScanTask in that way) but we can have this manage buffering internally as well. (Either way, either the IPC reader or the Parquet reader will need some refactoring to meet Datasets' needs.)

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(
+                              &ReadOneRowGroup, self, row_group, column_indices));
+    return fut;
+  }
+
+ private:
+  static ::arrow::Result<Item> ReadOneRowGroup(FileReaderImpl* self, const int row_group,
+                                               const std::vector<int>& column_indices) {
+    std::shared_ptr<::arrow::Table> table;
+    // Call the version that skips bound checks/pre-buffering, since we've done that
+    // already
+    RETURN_NOT_OK(self->ReadRowGroupsImpl({row_group}, column_indices, &table));
+    auto table_reader = std::make_shared<::arrow::TableBatchReader>(*table);
+    ::arrow::RecordBatchVector batches;
+    while (true) {
+      std::shared_ptr<::arrow::RecordBatch> batch;
+      RETURN_NOT_OK(table_reader->ReadNext(&batch));
+      if (!batch) {
+        break;
+      }
+      batches.push_back(batch);
+    }
+    return ::arrow::util::make_optional<::arrow::RecordBatchVector>(std::move(batches));
+  }
+
+  FileReaderImpl* self_;
+  size_t index_;
+  std::vector<int> row_groups_;
+  std::vector<int> column_indices_;
+};
+
+::arrow::Result<
+    ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+FileReaderImpl::GetRecordBatchGenerator(const std::vector<int>& row_groups,
+                                        const std::vector<int>& column_indices) {
+  RETURN_NOT_OK(BoundsCheck(row_groups, column_indices));
+  if (reader_properties_.pre_buffer()) {
+    // PARQUET-1698/PARQUET-1820: pre-buffer row groups/column chunks if enabled
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    reader_->PreBuffer(row_groups, column_indices, reader_properties_.io_context(),
+                       reader_properties_.cache_options());
+    END_PARQUET_CATCH_EXCEPTIONS
+  }
+  // N.B. we (and underlying Parquet reader) must outlive generator
+  return RowGroupGenerator(this, row_groups, column_indices);

Review comment:
       Note that it's true for the RecordBatchReader for Parquet as well; if you look at ParquetScanTask in dataset/file_parquet.cc, there's a similar note there. I think it's solely because we don't have enable_shared_from_this for the Parquet readers, I'm not sure if there's a reason why we omit that.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591937851


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(
+                              &ReadOneRowGroup, self, row_group, column_indices));
+    return fut;
+  }
+
+ private:
+  static ::arrow::Result<Item> ReadOneRowGroup(FileReaderImpl* self, const int row_group,
+                                               const std::vector<int>& column_indices) {
+    std::shared_ptr<::arrow::Table> table;
+    // Call the version that skips bound checks/pre-buffering, since we've done that
+    // already
+    RETURN_NOT_OK(self->ReadRowGroupsImpl({row_group}, column_indices, &table));
+    auto table_reader = std::make_shared<::arrow::TableBatchReader>(*table);
+    ::arrow::RecordBatchVector batches;
+    while (true) {
+      std::shared_ptr<::arrow::RecordBatch> batch;
+      RETURN_NOT_OK(table_reader->ReadNext(&batch));
+      if (!batch) {
+        break;
+      }
+      batches.push_back(batch);
+    }
+    return ::arrow::util::make_optional<::arrow::RecordBatchVector>(std::move(batches));
+  }
+
+  FileReaderImpl* self_;
+  size_t index_;
+  std::vector<int> row_groups_;
+  std::vector<int> column_indices_;
+};
+
+::arrow::Result<
+    ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+FileReaderImpl::GetRecordBatchGenerator(const std::vector<int>& row_groups,
+                                        const std::vector<int>& column_indices) {
+  RETURN_NOT_OK(BoundsCheck(row_groups, column_indices));
+  if (reader_properties_.pre_buffer()) {
+    // PARQUET-1698/PARQUET-1820: pre-buffer row groups/column chunks if enabled
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    reader_->PreBuffer(row_groups, column_indices, reader_properties_.io_context(),
+                       reader_properties_.cache_options());
+    END_PARQUET_CATCH_EXCEPTIONS
+  }
+  // N.B. we (and underlying Parquet reader) must outlive generator
+  return RowGroupGenerator(this, row_groups, column_indices);

Review comment:
       Ok, I might be breaking this.  The current Scanner::ToTable keeps the scan task alive while it iterates the batches...
   ```
   ARROW_ASSIGN_OR_RAISE(auto batch_it, scan_task->Execute());
   ARROW_ASSIGN_OR_RAISE(auto local, batch_it.ToVector());
   state->Emplace(std::move(local), id);
   ```
   However, the async version does not...
   ```
   ARROW_ASSIGN_OR_RAISE(auto batch_gen, scan_task->ExecuteAsync());
   return CollectAsyncGenerator(std::move(batch_gen))
           .Then([state, id](const RecordBatchVector& rbs) -> util::optional<bool> {
             state->Emplace(rbs, id);
             return true;
           });
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-814482382


   Ah, this exposes a deadlock in Python; now that we're using ReadAsync, if the underlying file is backed by Python, we'll deadlock over the GIL. Probably PyReadableFile needs to override ReadAsync.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r626128197


##########
File path: cpp/src/parquet/encryption/read_configurations_test.cc
##########
@@ -237,7 +239,9 @@ TEST_P(TestDecryptionConfiguration, TestDecryption) {
     CheckResults(file_name, decryption_config_num, encryption_config_num);
   }
   // Delete temporary test file.
-  ASSERT_EQ(std::remove(file_name.c_str()), 0);
+  ASSERT_OK_AND_ASSIGN(auto path,

Review comment:
       I don't think this is wrong, I'm just wondering what the reasoning is here for my own education.  Is it to allow paths to be more universal accross platorms?

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -563,6 +693,27 @@ std::unique_ptr<ParquetFileReader> ParquetFileReader::OpenFile(
   return Open(std::move(source), props, std::move(metadata));
 }

+::arrow::Future<std::unique_ptr<ParquetFileReader>> ParquetFileReader::OpenAsync(
+    std::shared_ptr<::arrow::io::RandomAccessFile> source, const ReaderProperties& props,
+    std::shared_ptr<FileMetaData> metadata) {
+  BEGIN_PARQUET_CATCH_EXCEPTIONS
+  auto fut = SerializedFile::OpenAsync(std::move(source), props, std::move(metadata));
+  auto completed = ::arrow::Future<std::unique_ptr<ParquetFileReader>>::Make();
+  fut.AddCallback([fut, completed](

Review comment:
       Why not use `auto completed = fut.Then`?  Or is this another workaround for ARROW-12259? (in which case maybe add a comment)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-851973512


   Also, can you avoid using the misleading term "reentrant" here? I don't think there is any reentrant code path in this PR.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r626141778


##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -563,6 +693,27 @@ std::unique_ptr<ParquetFileReader> ParquetFileReader::OpenFile(
   return Open(std::move(source), props, std::move(metadata));
 }

+::arrow::Future<std::unique_ptr<ParquetFileReader>> ParquetFileReader::OpenAsync(
+    std::shared_ptr<::arrow::io::RandomAccessFile> source, const ReaderProperties& props,
+    std::shared_ptr<FileMetaData> metadata) {
+  BEGIN_PARQUET_CATCH_EXCEPTIONS
+  auto fut = SerializedFile::OpenAsync(std::move(source), props, std::move(metadata));
+  auto completed = ::arrow::Future<std::unique_ptr<ParquetFileReader>>::Make();
+  fut.AddCallback([fut, completed](

Review comment:
       This is also another workaround, yes, since we have the move-only type. I've added a comment.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r621198702


##########
File path: cpp/src/arrow/python/io.cc
##########
@@ -265,6 +266,14 @@ Result<std::shared_ptr<Buffer>> PyReadableFile::ReadAt(int64_t position, int64_t
   });
 }

+Future<std::shared_ptr<Buffer>> PyReadableFile::ReadAsync(const io::IOContext&,

Review comment:
       Actually, yeah, I think I'll revert this, then track down the offending binding in PyArrow.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-814393897
Properly implementing OpenAsync mostly fixes the discrepancy between prebuffer/no prebuffer on local files, so it seems most of the bottleneck there was just synchronously opening files.
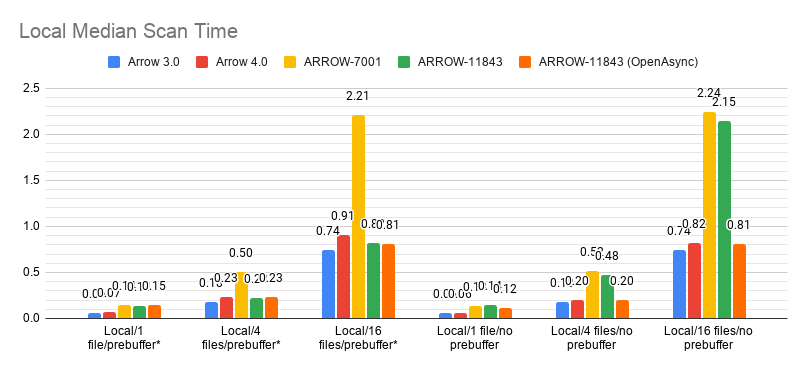
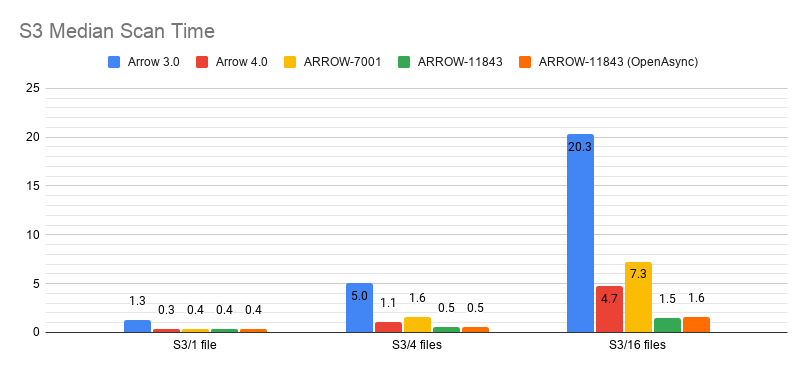
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou closed pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou closed pull request #9620:
URL: https://github.com/apache/arrow/pull/9620


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-828842325
The speedup for S3 is still quite unbelievable, threading issues notwithstanding.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-812194926


   What I pushed is still not quite what I want. Ideally, we'd be able to ask the read cache for a future that finishes when all I/O for the given row group has completed. That way, we can then kick off a decoding task. On master, currently, you just spawn a bunch of tasks that block and wait for I/O and then proceed (wasting threads), and in this PR, we have hijinks to manually pre-buffer each row group separately (wasting the effectiveness of pre-buffering).

   Also, the range cache will have to be swappable for something that just does normal file I/O for the non-S3 case so that local file scans are still reasonable.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r622646891


##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,
+                              reader_fut.MoveResult());
+        std::shared_ptr<parquet::FileMetaData> metadata = reader->metadata();
+        auto arrow_properties = MakeArrowReaderProperties(*self, *metadata);
+        if (options) {
+          arrow_properties.set_batch_size(options->batch_size);
+        }
+        if (options && !options->use_threads) {
+          arrow_properties.set_use_threads(
+              parquet_scan_options->enable_parallel_column_conversion);

Review comment:
       We could add `ParallelForAsync` which returns a Future but that can be done in a follow-up.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-854007519
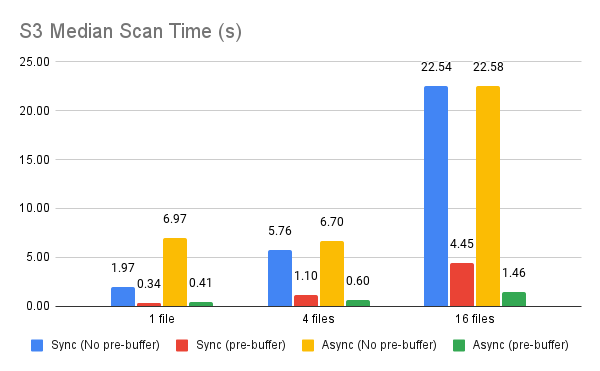
I re-tested S3 and also compared against the threaded reader with pre-buffering. I also corrected a logic error in file_parquet.cc that was leading to us needlessly spawning a thread.
I also ran Conbench on the EC2 instance. It seems with that dataset, async doesn't make much of a difference. (Note that the bucket is in a different zone than my instance, though both are in the same region.)
Threaded/pre-buffer:
```
"iterations": 10,
"max": "10.805500",
"mean": "10.117983",
"median": "10.099560",
"min": "9.663432",
"q1": "9.919561",
"q3": "10.197374",
"stdev": "0.309781",
```
Async/pre-buffer:
```
"iterations": 10,
"max": "10.660384",
"mean": "9.774189",
"median": "9.626739",
"min": "9.297837",
"q1": "9.391290",
"q3": "10.127940",
"run_id": "c3a226feb28e4025bc70fd2e90e405d4",
"stdev": "0.460085",
```
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r643134379


##########
File path: cpp/src/parquet/arrow/arrow_reader_writer_test.cc
##########
@@ -2331,6 +2330,63 @@ TEST(TestArrowReadWrite, GetRecordBatchReaderNoColumns) {
   ASSERT_EQ(actual_batch->num_rows(), num_rows);
 }

+TEST(TestArrowReadWrite, GetRecordBatchGenerator) {
+  ArrowReaderProperties properties = default_arrow_reader_properties();
+  const int num_rows = 1024;
+  const int row_group_size = 512;
+  const int num_columns = 2;
+
+  std::shared_ptr<Table> table;
+  ASSERT_NO_FATAL_FAILURE(MakeDoubleTable(num_columns, num_rows, 1, &table));
+
+  std::shared_ptr<Buffer> buffer;
+  ASSERT_NO_FATAL_FAILURE(WriteTableToBuffer(table, row_group_size,
+                                             default_arrow_writer_properties(), &buffer));
+
+  std::shared_ptr<FileReader> reader;
+  {
+    std::unique_ptr<FileReader> unique_reader;
+    FileReaderBuilder builder;
+    ASSERT_OK(builder.Open(std::make_shared<BufferReader>(buffer)));
+    ASSERT_OK(builder.properties(properties)->Build(&unique_reader));
+    reader = std::move(unique_reader);
+  }
+
+  auto check_batches = [](const std::shared_ptr<::arrow::RecordBatch>& batch,
+                          int num_columns, int num_rows) {
+    ASSERT_NE(batch, nullptr);
+    ASSERT_EQ(batch->num_columns(), num_columns);
+    ASSERT_EQ(batch->num_rows(), num_rows);
+  };
+  {
+    ASSERT_OK_AND_ASSIGN(auto batch_generator,
+                         reader->GetRecordBatchGenerator(reader, {0, 1}, {0, 1}));
+    auto fut1 = batch_generator();
+    auto fut2 = batch_generator();
+    auto fut3 = batch_generator();
+    ASSERT_OK_AND_ASSIGN(auto batch1, fut1.result());
+    ASSERT_OK_AND_ASSIGN(auto batch2, fut2.result());
+    ASSERT_OK_AND_ASSIGN(auto batch3, fut3.result());
+    ASSERT_EQ(batch3, nullptr);
+    check_batches(batch1, num_columns, row_group_size);
+    check_batches(batch2, num_columns, row_group_size);
+  }
+  {
+    // No columns case
+    ASSERT_OK_AND_ASSIGN(auto batch_generator,
+                         reader->GetRecordBatchGenerator(reader, {0, 1}, {}));

Review comment:
       Yes, I figured this is a lower-level API. We could add overloads to ease this.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-854007519

I re-tested S3 and also compared against the threaded reader with pre-buffering. I also corrected a logic error in file_parquet.cc that was leading to us needlessly spawning a thread.
I also ran Conbench on the EC2 instance. It seems with that dataset, async doesn't make much of a difference. (Note that the bucket is in a different zone than my instance, though both are in the same region.)
Threaded/pre-buffer:
```
"iterations": 10,
"max": "10.805500",
"mean": "10.117983",
"median": "10.099560",
"min": "9.663432",
"q1": "9.919561",
"q3": "10.197374",
"stdev": "0.309781",
```
Async/pre-buffer:
```
"iterations": 10,
"max": "10.660384",
"mean": "9.774189",
"median": "9.626739",
"min": "9.297837",
"q1": "9.391290",
"q3": "10.127940",
"run_id": "c3a226feb28e4025bc70fd2e90e405d4",
"stdev": "0.460085",
```
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r621377369


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +979,99 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(FileReaderImpl* arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(arrow_reader),
+        executor_(executor),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)),
+        index_(0) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::IterationEnd<Item>());
+    }
+    int row_group = row_groups_[index_++];
+    std::vector<int> column_indices = column_indices_;
+    auto reader = arrow_reader_;
+    if (!reader->properties().pre_buffer()) {
+      return SubmitRead(executor_, reader, row_group, column_indices);
+    }
+    BEGIN_PARQUET_CATCH_EXCEPTIONS

Review comment:
       Yes, I haven't really had to think through those problems yet since exceptions are a bug everywhere else.  It may be there are utilities we could add to the async code to help here.  Feel free to create JIRAs and assign them to me if that is the case.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-827782520


   This is now rebased on top of ARROW-12522 / #10145. I've reworked ParseMetadata so that the synchronous and asynchronous paths are truly synchronous/asynchronous, and to avoid mixing error handling methods (all parsing code uses exceptions, and the asynchronous path catches them and converts to Status).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-812679493
The benchmark discrepancy is simply because the generator was putting each row group on its own thread. The difference goes away if we don't force transfer onto a background thread.
With that fixed, here are benchmarks of reentrant Parquet + ARROW-7001 on EC2:
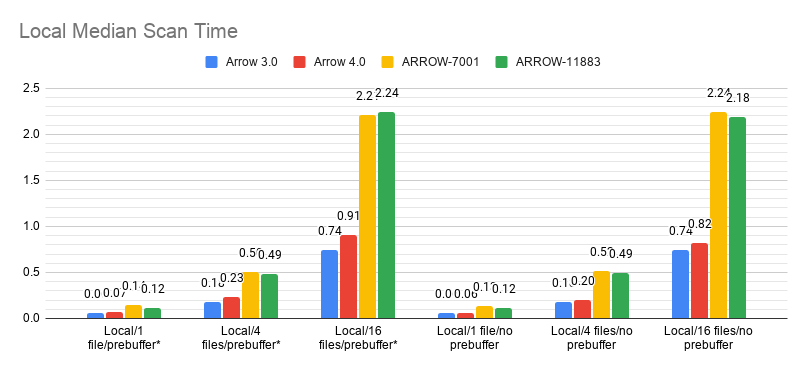
(note that Arrow 3.0 didn't have pre-buffering, so the results are duplicated here)
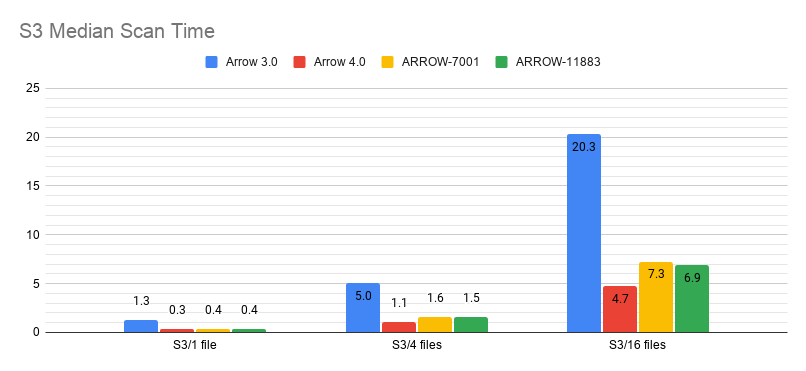
- Prebuffering appears to have no impact locally, so maybe we should always enable it.
- Non-prebuffered cases (except Arrow 3.0) are omitted from the S3 graphs because it's so much slower and skews the graphs. That is, ARROW-7001 without prebuffering took about ~75 seconds to read 16 files from S3, which is a significant regression from even the non-prebuffered Arrow 3.0 case.
- Local files have heavily regressed and need more investigation.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591875021


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(
+                              &ReadOneRowGroup, self, row_group, column_indices));
+    return fut;
+  }
+
+ private:
+  static ::arrow::Result<Item> ReadOneRowGroup(FileReaderImpl* self, const int row_group,
+                                               const std::vector<int>& column_indices) {
+    std::shared_ptr<::arrow::Table> table;
+    // Call the version that skips bound checks/pre-buffering, since we've done that
+    // already
+    RETURN_NOT_OK(self->ReadRowGroupsImpl({row_group}, column_indices, &table));
+    auto table_reader = std::make_shared<::arrow::TableBatchReader>(*table);
+    ::arrow::RecordBatchVector batches;
+    while (true) {
+      std::shared_ptr<::arrow::RecordBatch> batch;
+      RETURN_NOT_OK(table_reader->ReadNext(&batch));
+      if (!batch) {
+        break;
+      }
+      batches.push_back(batch);
+    }
+    return ::arrow::util::make_optional<::arrow::RecordBatchVector>(std::move(batches));
+  }
+
+  FileReaderImpl* self_;
+  size_t index_;
+  std::vector<int> row_groups_;
+  std::vector<int> column_indices_;
+};
+
+::arrow::Result<
+    ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+FileReaderImpl::GetRecordBatchGenerator(const std::vector<int>& row_groups,
+                                        const std::vector<int>& column_indices) {
+  RETURN_NOT_OK(BoundsCheck(row_groups, column_indices));
+  if (reader_properties_.pre_buffer()) {
+    // PARQUET-1698/PARQUET-1820: pre-buffer row groups/column chunks if enabled
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    reader_->PreBuffer(row_groups, column_indices, reader_properties_.io_context(),
+                       reader_properties_.cache_options());
+    END_PARQUET_CATCH_EXCEPTIONS
+  }
+  // N.B. we (and underlying Parquet reader) must outlive generator
+  return RowGroupGenerator(this, row_groups, column_indices);

Review comment:
       Hmm, historically that hasn't been the precedent for the generators.  They keep an ownership stake in their resources.  Is there some reason the generator can't have a shared pointer to the reader?

   Consider the dataset scanning example.  The scan tasks will be asked for a generator and the scanner will keep track of the generator but the scanner will have no idea what the reader is.  Who is keeping track of the reader there?  What if the scanner simply discarded the scan task after it got a generator from it.

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(

Review comment:
       This will be a problem.  I think this task will block (I'm assuming `ReadRowGroupsImpl` is synchronous and blocking?)  Blocking tasks should not be on the CPU pool.  You could put it on the I/O pool but that isn't necessarily ideal either as it complicates sizing the I/O pool.

   Ideally you want something like `reader_->PreBuffer(row_groups, ...).Then(NonBlockingReadRowGroupsImpl)`.

   I think you might kind of get away with it because the task they are waiting on is on the I/O thread pool (I assume the prebuffering tasks are on the I/O pool) so you won't have the nested deadlock problem.

   However, it will not have ideal performance.  If you are reading a bunch of files you will have some CPU threads tied up waiting that could be doing work.

##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -175,6 +177,22 @@ class PARQUET_EXPORT FileReader {
       const std::vector<int>& row_group_indices, const std::vector<int>& column_indices,
       std::unique_ptr<::arrow::RecordBatchReader>* out) = 0;

+  /// \brief Return a generator of record batch vectors, where each vector represents
+  ///     the contents of a row group from row_group_indices, whose columns are selected
+  ///     by column_indices.
+  ///
+  /// An empty optional indicates the end of the generator.
+  ///
+  /// Note that the ordering in row_group_indices and column_indices matter. FileReaders
+  /// must outlive their generators.
+  ///
+  /// \returns error Result if either row_group_indices or column_indices contains an
+  ///     invalid index
+  virtual ::arrow::Result<

Review comment:
       Answering your question I agree it would be better to have `AsyncGenerator<RecordBatch>` for consistency with the other readers.  You can use `MakeVectorGenerator` to get `AsyncGenerator<AsyncGenerator<RecordBatch>>`.  Then apply `MakeConcatMapGenerator` to the result to get to `AsyncGenerator<RecordBatch>`

##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -175,6 +177,22 @@ class PARQUET_EXPORT FileReader {
       const std::vector<int>& row_group_indices, const std::vector<int>& column_indices,
       std::unique_ptr<::arrow::RecordBatchReader>* out) = 0;

+  /// \brief Return a generator of record batch vectors, where each vector represents
+  ///     the contents of a row group from row_group_indices, whose columns are selected
+  ///     by column_indices.
+  ///
+  /// An empty optional indicates the end of the generator.
+  ///
+  /// Note that the ordering in row_group_indices and column_indices matter. FileReaders
+  /// must outlive their generators.
+  ///
+  /// \returns error Result if either row_group_indices or column_indices contains an
+  ///     invalid index
+  virtual ::arrow::Result<
+      ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+  GetRecordBatchGenerator(const std::vector<int>& row_group_indices,

Review comment:
       Would the scan task be the thing providing the `row_group_indices`?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm edited a comment on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm edited a comment on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-812679493


   The benchmark discrepancy is simply because the generator was putting each row group on its own thread. The difference goes away if we don't force transfer onto a background thread.

   (snipped when I realized I had benchmarked the wrong code for this PR)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on a change in pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r643133367


##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -21,6 +21,8 @@
 #include <memory>
 #include <vector>

+#include "arrow/util/async_generator.h"

Review comment:
       Hmm, then we can simply use the actual expansion, i.e. `std::function<Future<T>()>`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-827597876


   By the way, if it's easier, I can split the generator/OpenAsync/ScanBatchesAsync parts of this PR from each other. I think the OpenAsync part deserves some extra scrutiny in any case.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591937851


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(
+                              &ReadOneRowGroup, self, row_group, column_indices));
+    return fut;
+  }
+
+ private:
+  static ::arrow::Result<Item> ReadOneRowGroup(FileReaderImpl* self, const int row_group,
+                                               const std::vector<int>& column_indices) {
+    std::shared_ptr<::arrow::Table> table;
+    // Call the version that skips bound checks/pre-buffering, since we've done that
+    // already
+    RETURN_NOT_OK(self->ReadRowGroupsImpl({row_group}, column_indices, &table));
+    auto table_reader = std::make_shared<::arrow::TableBatchReader>(*table);
+    ::arrow::RecordBatchVector batches;
+    while (true) {
+      std::shared_ptr<::arrow::RecordBatch> batch;
+      RETURN_NOT_OK(table_reader->ReadNext(&batch));
+      if (!batch) {
+        break;
+      }
+      batches.push_back(batch);
+    }
+    return ::arrow::util::make_optional<::arrow::RecordBatchVector>(std::move(batches));
+  }
+
+  FileReaderImpl* self_;
+  size_t index_;
+  std::vector<int> row_groups_;
+  std::vector<int> column_indices_;
+};
+
+::arrow::Result<
+    ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+FileReaderImpl::GetRecordBatchGenerator(const std::vector<int>& row_groups,
+                                        const std::vector<int>& column_indices) {
+  RETURN_NOT_OK(BoundsCheck(row_groups, column_indices));
+  if (reader_properties_.pre_buffer()) {
+    // PARQUET-1698/PARQUET-1820: pre-buffer row groups/column chunks if enabled
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    reader_->PreBuffer(row_groups, column_indices, reader_properties_.io_context(),
+                       reader_properties_.cache_options());
+    END_PARQUET_CATCH_EXCEPTIONS
+  }
+  // N.B. we (and underlying Parquet reader) must outlive generator
+  return RowGroupGenerator(this, row_groups, column_indices);

Review comment:
       Ok, I might be breaking this.  The current Scanner::ToTable keeps the scan task alive while it iterates the batches...
   ```
   ARROW_ASSIGN_OR_RAISE(auto batch_it, scan_task->Execute());
   ARROW_ASSIGN_OR_RAISE(auto local, batch_it.ToVector());
   state->Emplace(std::move(local), id);
   ```
   However, the async version does not...
   ```
   ARROW_ASSIGN_OR_RAISE(auto batch_gen, scan_task->ExecuteAsync());
   auto fut =
       CollectAsyncGenerator(std::move(batch_gen))
           .Then([state, id](const RecordBatchVector& rbs) -> util::optional<bool> {
             state->Emplace(rbs, id);
             return true;
           });
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r622989137


##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,
+                              reader_fut.MoveResult());
+        std::shared_ptr<parquet::FileMetaData> metadata = reader->metadata();
+        auto arrow_properties = MakeArrowReaderProperties(*self, *metadata);
+        if (options) {
+          arrow_properties.set_batch_size(options->batch_size);
+        }
+        if (options && !options->use_threads) {
+          arrow_properties.set_use_threads(
+              parquet_scan_options->enable_parallel_column_conversion);

Review comment:
       I fixed this and added a TODO for ARROW-12597.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on a change in pull request #9620: ARROW-11843: [C++] Provide async Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r643132892


##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -264,23 +264,92 @@ class SerializedFile : public ParquetFileReader::Contents {
       }
     }
     PARQUET_THROW_NOT_OK(cached_source_->Cache(ranges));
-    return cached_source_->Wait();
   }

+  ::arrow::Future<> WhenBuffered(const std::vector<int>& row_groups,
+                                 const std::vector<int>& column_indices) const {
+    if (!cached_source_) {
+      return ::arrow::Status::Invalid("Must call PreBuffer before WhenBuffered");
+    }
+    std::vector<::arrow::io::ReadRange> ranges;
+    for (int row : row_groups) {
+      for (int col : column_indices) {
+        ranges.push_back(
+            ComputeColumnChunkRange(file_metadata_.get(), source_size_, row, col));
+      }
+    }
+    return cached_source_->WaitFor(ranges);
+  }
+
+  // Metadata/footer parsing. Divided up to separate sync/async paths, and to use
+  // exceptions for error handling (with the async path converting to Future/Status).
+
   void ParseMetaData() {

Review comment:
       Hmm, ok, I see. Is the async path for encryption tested somewhere?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591953537


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(

Review comment:
       Yes, this is to allow for parallelism when scanning a Parquet file. Though as I think about it, maybe this isn't necessary? We can do the parallelism at the scan task level already.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-825848916


   I'm also unable to replicate the failed Parquet encryption test on Windows. This PR already changes things to explicitly close the file handle, but I do feel like it's flakier than before.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r621217516


##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -150,11 +153,44 @@ struct ReadRangeCache::Impl {
       entries = std::move(new_entries);
     }
   }
+
+  virtual std::unique_lock<std::mutex> TakeGuard() {
+    return std::unique_lock<std::mutex>();
+  }
+
+  virtual Future<std::shared_ptr<Buffer>> GetFuture(RangeCacheEntry* entry) {
+    return entry->future;
+  }
+
+  virtual RangeCacheEntry Cache(const ReadRange& range) {
+    return {range, file->ReadAsync(ctx, range.offset, range.length)};
+  }
+};
+
+struct ReadRangeCache::LazyImpl : public ReadRangeCache::Impl {
+  std::mutex entry_mutex;

Review comment:
       Yes, it's to avoid two threads trying to find-or-create `entry->future`. The lock isn't acquired in `GetFuture` to avoid constantly locking/unlocking. I think what I'll do is move the implementations of the methods to the Impl, then have LazyImpl acquire the lock and defer to the superclass, while having ReadRangeCache defer essentially everything to Impl.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-825811974
Apart from the non-pre-buffered single-file case, this brings us back on par with or improves upon the threaded scanner.
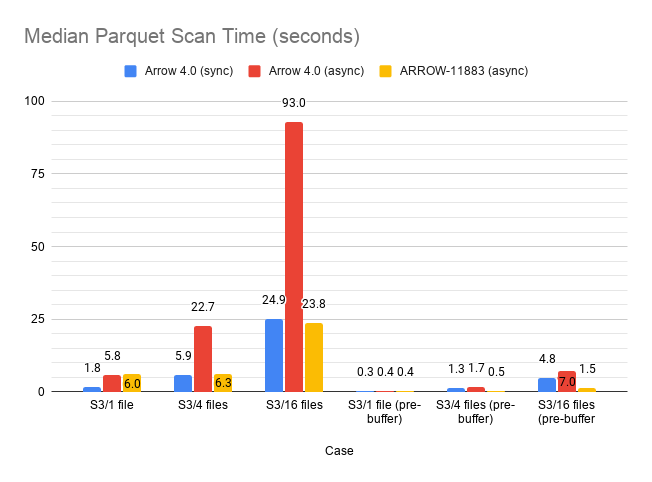
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r626139242


##########
File path: cpp/src/parquet/encryption/read_configurations_test.cc
##########
@@ -237,7 +239,9 @@ TEST_P(TestDecryptionConfiguration, TestDecryption) {
     CheckResults(file_name, decryption_config_num, encryption_config_num);
   }
   // Delete temporary test file.
-  ASSERT_EQ(std::remove(file_name.c_str()), 0);
+  ASSERT_OK_AND_ASSIGN(auto path,

Review comment:
       Hmm, I think I added these by accident - I was stumbling around trying to figure out why OpenAsync seemed to have made the encryption tests flaky on Windows. But after reworking it so OpenAsync and Open are separate, that isn't an issue anymore.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#issuecomment-812552565


   Ok, something wonky is going on here, but…
   ```
   --------------------------------------------------------------------------------------------
   Benchmark                                  Time             CPU   Iterations UserCounters...
   --------------------------------------------------------------------------------------------
   BM_ReadMultipleRowGroups            38393176 ns     38392591 ns           14 bytes_per_second=2.0349G/s items_per_second=2.18495G/s
   BM_ReadMultipleRowGroupsGenerator   37526258 ns       123436 ns          100 bytes_per_second=632.918G/s items_per_second=679.59G/s
   ```
   I confirmed that both benchmarks read the same number of rows/columns, but this still seems rather unbelievable/there must be some sort of measurement error.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
pitrou commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r642908613


##########
File path: cpp/src/arrow/util/future.h
##########
@@ -829,6 +829,9 @@ Future<std::vector<Result<T>>> All(std::vector<Future<T>> futures) {
   return out;
 }

+template <>
+inline Future<>::Future(Status s) : Future(internal::Empty::ToResult(std::move(s))) {}

Review comment:
       Hmm... can you explain what the point of this is? Also, why isn't the constructor defined directly at its declaration point in the class?

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -289,21 +358,94 @@ class SerializedFile : public ParquetFileReader::Contents {
           "Parquet magic bytes not found in footer. Either the file is corrupted or this "
           "is not a parquet file.");
     }
+    // Both encrypted/unencrypted footers have the same footer length check.
+    uint32_t metadata_len = ::arrow::util::SafeLoadAs<uint32_t>(
+        reinterpret_cast<const uint8_t*>(footer_buffer->data()) + footer_read_size -
+        kFooterSize);
+    if (metadata_len > source_size_ - kFooterSize) {
+      throw ParquetInvalidOrCorruptedFileException(
+          "Parquet file size is ", source_size_,
+          " bytes, smaller than the size reported by footer's (", metadata_len, "bytes)");
+    }
+    return metadata_len;
+  }
+
+  // Does not throw.
+  ::arrow::Future<> ParseMetaDataAsync() {
+    int64_t footer_read_size;
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    footer_read_size = GetFooterReadSize();
+    END_PARQUET_CATCH_EXCEPTIONS
+    // Assumes this is kept alive externally
+    return source_->ReadAsync(source_size_ - footer_read_size, footer_read_size)
+        .Then([=](const std::shared_ptr<::arrow::Buffer>& footer_buffer)
+                  -> ::arrow::Future<> {
+          uint32_t metadata_len;
+          BEGIN_PARQUET_CATCH_EXCEPTIONS
+          metadata_len = ParseFooterLength(footer_buffer, footer_read_size);
+          END_PARQUET_CATCH_EXCEPTIONS
+          int64_t metadata_start = source_size_ - kFooterSize - metadata_len;
+
+          std::shared_ptr<::arrow::Buffer> metadata_buffer;
+          if (footer_read_size >= (metadata_len + kFooterSize)) {
+            metadata_buffer =
+                SliceBuffer(footer_buffer, footer_read_size - metadata_len - kFooterSize,
+                            metadata_len);
+            return ParseMaybeEncryptedMetaDataAsync(footer_buffer,
+                                                    std::move(metadata_buffer),
+                                                    footer_read_size, metadata_len);
+          }
+          return source_->ReadAsync(metadata_start, metadata_len)
+              .Then([=](const std::shared_ptr<::arrow::Buffer>& metadata_buffer) {
+                return ParseMaybeEncryptedMetaDataAsync(footer_buffer, metadata_buffer,
+                                                        footer_read_size, metadata_len);
+              });
+        });
+  }

-    if (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) == 0) {
+  // Continuation
+  ::arrow::Future<> ParseMaybeEncryptedMetaDataAsync(
+      std::shared_ptr<::arrow::Buffer> footer_buffer,
+      std::shared_ptr<::arrow::Buffer> metadata_buffer, int64_t footer_read_size,
+      uint32_t metadata_len) {
+    // Parse the footer depending on encryption type
+    const bool is_encrypted_footer =
+        memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) == 0;
+    if (is_encrypted_footer) {
       // Encrypted file with Encrypted footer.
-      ParseMetaDataOfEncryptedFileWithEncryptedFooter(footer_buffer, footer_read_size);
-      return;
+      std::pair<int64_t, uint32_t> read_size;
+      BEGIN_PARQUET_CATCH_EXCEPTIONS
+      read_size =
+          ParseMetaDataOfEncryptedFileWithEncryptedFooter(metadata_buffer, metadata_len);
+      END_PARQUET_CATCH_EXCEPTIONS
+      // Read the actual footer
+      int64_t metadata_start = read_size.first;
+      metadata_len = read_size.second;
+      return source_->ReadAsync(metadata_start, metadata_len)
+          .Then([=](const std::shared_ptr<::arrow::Buffer>& metadata_buffer) {
+            // Continue and read the file footer
+            return ParseMetaDataAsync(std::move(footer_buffer), metadata_buffer,
+                                      footer_read_size, metadata_len,
+                                      is_encrypted_footer);
+          });
     }
+    return ParseMetaDataAsync(std::move(footer_buffer), std::move(metadata_buffer),
+                              footer_read_size, metadata_len, is_encrypted_footer);
+  }

-    // No encryption or encryption with plaintext footer mode.
-    std::shared_ptr<Buffer> metadata_buffer;
-    uint32_t metadata_len, read_metadata_len;
-    ParseUnencryptedFileMetadata(footer_buffer, footer_read_size, &metadata_buffer,
-                                 &metadata_len, &read_metadata_len);
-
+  // Continuation
+  ::arrow::Status ParseMetaDataAsync(std::shared_ptr<::arrow::Buffer> footer_buffer,

Review comment:
       This is not async, rename this function? For example `ParseMetadataBuffer`.

##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -21,6 +21,8 @@
 #include <memory>
 #include <vector>

+#include "arrow/util/async_generator.h"

Review comment:
       This is a heavy include, can we avoid adding it?

##########
File path: cpp/src/parquet/arrow/arrow_reader_writer_test.cc
##########
@@ -2331,6 +2330,63 @@ TEST(TestArrowReadWrite, GetRecordBatchReaderNoColumns) {
   ASSERT_EQ(actual_batch->num_rows(), num_rows);
 }

+TEST(TestArrowReadWrite, GetRecordBatchGenerator) {
+  ArrowReaderProperties properties = default_arrow_reader_properties();
+  const int num_rows = 1024;
+  const int row_group_size = 512;
+  const int num_columns = 2;
+
+  std::shared_ptr<Table> table;
+  ASSERT_NO_FATAL_FAILURE(MakeDoubleTable(num_columns, num_rows, 1, &table));
+
+  std::shared_ptr<Buffer> buffer;
+  ASSERT_NO_FATAL_FAILURE(WriteTableToBuffer(table, row_group_size,
+                                             default_arrow_writer_properties(), &buffer));
+
+  std::shared_ptr<FileReader> reader;
+  {
+    std::unique_ptr<FileReader> unique_reader;
+    FileReaderBuilder builder;
+    ASSERT_OK(builder.Open(std::make_shared<BufferReader>(buffer)));
+    ASSERT_OK(builder.properties(properties)->Build(&unique_reader));
+    reader = std::move(unique_reader);
+  }
+
+  auto check_batches = [](const std::shared_ptr<::arrow::RecordBatch>& batch,
+                          int num_columns, int num_rows) {
+    ASSERT_NE(batch, nullptr);
+    ASSERT_EQ(batch->num_columns(), num_columns);
+    ASSERT_EQ(batch->num_rows(), num_rows);

Review comment:
       This doesn't seem to actually check the contents read from file. Could you do that?

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -563,6 +692,28 @@ std::unique_ptr<ParquetFileReader> ParquetFileReader::OpenFile(
   return Open(std::move(source), props, std::move(metadata));
 }

+::arrow::Future<std::unique_ptr<ParquetFileReader>> ParquetFileReader::OpenAsync(
+    std::shared_ptr<::arrow::io::RandomAccessFile> source, const ReaderProperties& props,
+    std::shared_ptr<FileMetaData> metadata) {
+  BEGIN_PARQUET_CATCH_EXCEPTIONS
+  auto fut = SerializedFile::OpenAsync(std::move(source), props, std::move(metadata));
+  // TODO(ARROW-12259): workaround since we have Future<(move-only type)>

Review comment:
       I don't understand this comment. Where is the workaround?

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -264,23 +264,92 @@ class SerializedFile : public ParquetFileReader::Contents {
       }
     }
     PARQUET_THROW_NOT_OK(cached_source_->Cache(ranges));
-    return cached_source_->Wait();
   }

+  ::arrow::Future<> WhenBuffered(const std::vector<int>& row_groups,
+                                 const std::vector<int>& column_indices) const {
+    if (!cached_source_) {
+      return ::arrow::Status::Invalid("Must call PreBuffer before WhenBuffered");
+    }
+    std::vector<::arrow::io::ReadRange> ranges;
+    for (int row : row_groups) {
+      for (int col : column_indices) {
+        ranges.push_back(
+            ComputeColumnChunkRange(file_metadata_.get(), source_size_, row, col));
+      }
+    }
+    return cached_source_->WaitFor(ranges);
+  }
+
+  // Metadata/footer parsing. Divided up to separate sync/async paths, and to use
+  // exceptions for error handling (with the async path converting to Future/Status).
+
   void ParseMetaData() {

Review comment:
       Can we express this in terms of `ParseMetadataAsync`? I would rather not have duplicate code paths for this.

##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -175,6 +177,19 @@ class PARQUET_EXPORT FileReader {
       const std::vector<int>& row_group_indices, const std::vector<int>& column_indices,
       std::unique_ptr<::arrow::RecordBatchReader>* out) = 0;

+  /// \brief Return a generator of record batches.
+  ///
+  /// The FileReader must outlive the generator, so this requires that you pass in a
+  /// shared_ptr.
+  ///
+  /// \returns error Result if either row_group_indices or column_indices contains an
+  ///     invalid index
+  virtual ::arrow::Result<::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>>
+  GetRecordBatchGenerator(std::shared_ptr<FileReader> reader,
+                          const std::vector<int> row_group_indices,
+                          const std::vector<int> column_indices,
+                          ::arrow::internal::Executor* executor = NULLPTR) = 0;

Review comment:
       Should explain whether the executor is meant for IO or CPU work.

##########
File path: cpp/src/parquet/encryption/test_encryption_util.cc
##########
@@ -334,7 +335,10 @@ void FileDecryptor::DecryptFile(
     reader_properties.file_decryption_properties(file_decryption_properties->DeepClone());
   }

-  auto file_reader = parquet::ParquetFileReader::OpenFile(file, false, reader_properties);
+  std::shared_ptr<::arrow::io::RandomAccessFile> source;
+  PARQUET_ASSIGN_OR_THROW(
+      source, ::arrow::io::ReadableFile::Open(file, reader_properties.memory_pool()));

Review comment:
       For the record, why did you need to change this?

##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -21,6 +21,8 @@
 #include <memory>
 #include <vector>

+#include "arrow/util/async_generator.h"
+#include "arrow/util/optional.h"

Review comment:
       Is this being used?

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -325,10 +469,9 @@ class SerializedFile : public ParquetFileReader::Contents {

   std::shared_ptr<InternalFileDecryptor> file_decryptor_;

-  void ParseUnencryptedFileMetadata(const std::shared_ptr<Buffer>& footer_buffer,
-                                    int64_t footer_read_size,
-                                    std::shared_ptr<Buffer>* metadata_buffer,
-                                    uint32_t* metadata_len, uint32_t* read_metadata_len);
+  // \return The true length of the metadata

Review comment:
       Length in bytes?

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +980,102 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch generators (where each sub-generator is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using RecordBatchGenerator =
+      ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(std::shared_ptr<FileReaderImpl> arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(std::move(arrow_reader)),
+        executor_(executor),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)),
+        index_(0) {}
+
+  ::arrow::Future<RecordBatchGenerator> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::AsyncGeneratorEnd<RecordBatchGenerator>();
+    }
+    int row_group = row_groups_[index_++];
+    std::vector<int> column_indices = column_indices_;
+    auto reader = arrow_reader_;
+    if (!reader->properties().pre_buffer()) {
+      return SubmitRead(executor_, reader, row_group, column_indices);
+    }
+    auto ready = reader->parquet_reader()->WhenBuffered({row_group}, column_indices);
+    if (executor_) ready = executor_->Transfer(ready);
+    return ready.Then([=]() -> ::arrow::Result<RecordBatchGenerator> {
+      return ReadOneRowGroup(reader, row_group, column_indices);
+    });
+  }
+
+ private:
+  // Synchronous fallback for when pre-buffer isn't enabled.
+  //
+  // Making the Parquet reader truly asynchronous requires heavy refactoring, so the
+  // generator piggybacks on ReadRangeCache. The lazy ReadRangeCache can be used for
+  // async I/O without forcing readahead.
+  static ::arrow::Future<RecordBatchGenerator> SubmitRead(
+      ::arrow::internal::Executor* executor, std::shared_ptr<FileReaderImpl> self,
+      const int row_group, const std::vector<int>& column_indices) {
+    if (!executor) {
+      return Future<RecordBatchGenerator>::MakeFinished(
+          ReadOneRowGroup(self, row_group, column_indices));
+    }
+    // If we have an executor, then force transfer (even if I/O was complete)
+    return ::arrow::DeferNotOk(
+        executor->Submit(ReadOneRowGroup, self, row_group, column_indices));
+  }
+
+  static ::arrow::Result<RecordBatchGenerator> ReadOneRowGroup(
+      std::shared_ptr<FileReaderImpl> self, const int row_group,
+      const std::vector<int>& column_indices) {
+    std::shared_ptr<::arrow::Table> table;
+    // Skips bound checks/pre-buffering, since we've done that already
+    RETURN_NOT_OK(self->DecodeRowGroups({row_group}, column_indices, &table));
+    auto table_reader = std::make_shared<::arrow::TableBatchReader>(*table);
+    ::arrow::RecordBatchVector batches;
+    while (true) {
+      std::shared_ptr<::arrow::RecordBatch> batch;
+      RETURN_NOT_OK(table_reader->ReadNext(&batch));
+      if (!batch) {
+        break;
+      }
+      batches.push_back(batch);
+    }
+    return ::arrow::MakeVectorGenerator(std::move(batches));
+  }
+
+  std::shared_ptr<FileReaderImpl> arrow_reader_;
+  ::arrow::internal::Executor* executor_;
+  std::vector<int> row_groups_;
+  std::vector<int> column_indices_;
+  size_t index_;
+};
+
+::arrow::Result<::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>>
+FileReaderImpl::GetRecordBatchGenerator(std::shared_ptr<FileReader> reader,
+                                        const std::vector<int> row_group_indices,
+                                        const std::vector<int> column_indices,
+                                        ::arrow::internal::Executor* executor) {
+  RETURN_NOT_OK(BoundsCheck(row_group_indices, column_indices));
+  if (reader_properties_.pre_buffer()) {
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    reader_->PreBuffer(row_group_indices, column_indices, reader_properties_.io_context(),
+                       reader_properties_.cache_options());
+    END_PARQUET_CATCH_EXCEPTIONS
+  }
+  ::arrow::AsyncGenerator<::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>>

Review comment:
       Use `auto`?

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -968,6 +980,102 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch generators (where each sub-generator is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using RecordBatchGenerator =
+      ::arrow::AsyncGenerator<std::shared_ptr<::arrow::RecordBatch>>;
+
+  explicit RowGroupGenerator(std::shared_ptr<FileReaderImpl> arrow_reader,
+                             ::arrow::internal::Executor* executor,
+                             std::vector<int> row_groups, std::vector<int> column_indices)
+      : arrow_reader_(std::move(arrow_reader)),
+        executor_(executor),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)),
+        index_(0) {}
+
+  ::arrow::Future<RecordBatchGenerator> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::AsyncGeneratorEnd<RecordBatchGenerator>();
+    }
+    int row_group = row_groups_[index_++];
+    std::vector<int> column_indices = column_indices_;
+    auto reader = arrow_reader_;
+    if (!reader->properties().pre_buffer()) {
+      return SubmitRead(executor_, reader, row_group, column_indices);
+    }
+    auto ready = reader->parquet_reader()->WhenBuffered({row_group}, column_indices);
+    if (executor_) ready = executor_->Transfer(ready);
+    return ready.Then([=]() -> ::arrow::Result<RecordBatchGenerator> {

Review comment:
       Can you open a JIRA to reuse @westonpace 's work to always transfer the future? (we don't want CPU-heavy Parquet decoding to happen on an IO thread)

##########
File path: cpp/src/parquet/file_reader.cc
##########
@@ -289,21 +358,94 @@ class SerializedFile : public ParquetFileReader::Contents {
           "Parquet magic bytes not found in footer. Either the file is corrupted or this "
           "is not a parquet file.");
     }
+    // Both encrypted/unencrypted footers have the same footer length check.
+    uint32_t metadata_len = ::arrow::util::SafeLoadAs<uint32_t>(
+        reinterpret_cast<const uint8_t*>(footer_buffer->data()) + footer_read_size -
+        kFooterSize);
+    if (metadata_len > source_size_ - kFooterSize) {
+      throw ParquetInvalidOrCorruptedFileException(
+          "Parquet file size is ", source_size_,
+          " bytes, smaller than the size reported by footer's (", metadata_len, "bytes)");
+    }
+    return metadata_len;
+  }
+
+  // Does not throw.
+  ::arrow::Future<> ParseMetaDataAsync() {
+    int64_t footer_read_size;
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    footer_read_size = GetFooterReadSize();
+    END_PARQUET_CATCH_EXCEPTIONS
+    // Assumes this is kept alive externally
+    return source_->ReadAsync(source_size_ - footer_read_size, footer_read_size)
+        .Then([=](const std::shared_ptr<::arrow::Buffer>& footer_buffer)
+                  -> ::arrow::Future<> {
+          uint32_t metadata_len;
+          BEGIN_PARQUET_CATCH_EXCEPTIONS
+          metadata_len = ParseFooterLength(footer_buffer, footer_read_size);
+          END_PARQUET_CATCH_EXCEPTIONS
+          int64_t metadata_start = source_size_ - kFooterSize - metadata_len;
+
+          std::shared_ptr<::arrow::Buffer> metadata_buffer;
+          if (footer_read_size >= (metadata_len + kFooterSize)) {
+            metadata_buffer =
+                SliceBuffer(footer_buffer, footer_read_size - metadata_len - kFooterSize,
+                            metadata_len);
+            return ParseMaybeEncryptedMetaDataAsync(footer_buffer,
+                                                    std::move(metadata_buffer),
+                                                    footer_read_size, metadata_len);
+          }
+          return source_->ReadAsync(metadata_start, metadata_len)
+              .Then([=](const std::shared_ptr<::arrow::Buffer>& metadata_buffer) {
+                return ParseMaybeEncryptedMetaDataAsync(footer_buffer, metadata_buffer,
+                                                        footer_read_size, metadata_len);
+              });
+        });
+  }

-    if (memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) == 0) {
+  // Continuation
+  ::arrow::Future<> ParseMaybeEncryptedMetaDataAsync(
+      std::shared_ptr<::arrow::Buffer> footer_buffer,
+      std::shared_ptr<::arrow::Buffer> metadata_buffer, int64_t footer_read_size,
+      uint32_t metadata_len) {
+    // Parse the footer depending on encryption type
+    const bool is_encrypted_footer =
+        memcmp(footer_buffer->data() + footer_read_size - 4, kParquetEMagic, 4) == 0;
+    if (is_encrypted_footer) {
       // Encrypted file with Encrypted footer.
-      ParseMetaDataOfEncryptedFileWithEncryptedFooter(footer_buffer, footer_read_size);
-      return;
+      std::pair<int64_t, uint32_t> read_size;
+      BEGIN_PARQUET_CATCH_EXCEPTIONS
+      read_size =
+          ParseMetaDataOfEncryptedFileWithEncryptedFooter(metadata_buffer, metadata_len);
+      END_PARQUET_CATCH_EXCEPTIONS
+      // Read the actual footer
+      int64_t metadata_start = read_size.first;
+      metadata_len = read_size.second;
+      return source_->ReadAsync(metadata_start, metadata_len)
+          .Then([=](const std::shared_ptr<::arrow::Buffer>& metadata_buffer) {
+            // Continue and read the file footer
+            return ParseMetaDataAsync(std::move(footer_buffer), metadata_buffer,
+                                      footer_read_size, metadata_len,
+                                      is_encrypted_footer);
+          });
     }
+    return ParseMetaDataAsync(std::move(footer_buffer), std::move(metadata_buffer),
+                              footer_read_size, metadata_len, is_encrypted_footer);
+  }

-    // No encryption or encryption with plaintext footer mode.
-    std::shared_ptr<Buffer> metadata_buffer;
-    uint32_t metadata_len, read_metadata_len;
-    ParseUnencryptedFileMetadata(footer_buffer, footer_read_size, &metadata_buffer,
-                                 &metadata_len, &read_metadata_len);
-
+  // Continuation
+  ::arrow::Status ParseMetaDataAsync(std::shared_ptr<::arrow::Buffer> footer_buffer,
+                                     std::shared_ptr<::arrow::Buffer> metadata_buffer,
+                                     int64_t footer_read_size, uint32_t metadata_len,
+                                     const bool is_encrypted_footer) {

Review comment:
       `footer_buffer` and `footer_read_size` don't seem used here?

##########
File path: cpp/src/parquet/arrow/arrow_reader_writer_test.cc
##########
@@ -2331,6 +2330,63 @@ TEST(TestArrowReadWrite, GetRecordBatchReaderNoColumns) {
   ASSERT_EQ(actual_batch->num_rows(), num_rows);
 }

+TEST(TestArrowReadWrite, GetRecordBatchGenerator) {
+  ArrowReaderProperties properties = default_arrow_reader_properties();
+  const int num_rows = 1024;
+  const int row_group_size = 512;
+  const int num_columns = 2;
+
+  std::shared_ptr<Table> table;
+  ASSERT_NO_FATAL_FAILURE(MakeDoubleTable(num_columns, num_rows, 1, &table));
+
+  std::shared_ptr<Buffer> buffer;
+  ASSERT_NO_FATAL_FAILURE(WriteTableToBuffer(table, row_group_size,
+                                             default_arrow_writer_properties(), &buffer));
+
+  std::shared_ptr<FileReader> reader;
+  {
+    std::unique_ptr<FileReader> unique_reader;
+    FileReaderBuilder builder;
+    ASSERT_OK(builder.Open(std::make_shared<BufferReader>(buffer)));
+    ASSERT_OK(builder.properties(properties)->Build(&unique_reader));
+    reader = std::move(unique_reader);
+  }
+
+  auto check_batches = [](const std::shared_ptr<::arrow::RecordBatch>& batch,
+                          int num_columns, int num_rows) {
+    ASSERT_NE(batch, nullptr);
+    ASSERT_EQ(batch->num_columns(), num_columns);
+    ASSERT_EQ(batch->num_rows(), num_rows);
+  };
+  {
+    ASSERT_OK_AND_ASSIGN(auto batch_generator,
+                         reader->GetRecordBatchGenerator(reader, {0, 1}, {0, 1}));
+    auto fut1 = batch_generator();
+    auto fut2 = batch_generator();
+    auto fut3 = batch_generator();
+    ASSERT_OK_AND_ASSIGN(auto batch1, fut1.result());
+    ASSERT_OK_AND_ASSIGN(auto batch2, fut2.result());
+    ASSERT_OK_AND_ASSIGN(auto batch3, fut3.result());
+    ASSERT_EQ(batch3, nullptr);
+    check_batches(batch1, num_columns, row_group_size);
+    check_batches(batch2, num_columns, row_group_size);
+  }
+  {
+    // No columns case
+    ASSERT_OK_AND_ASSIGN(auto batch_generator,
+                         reader->GetRecordBatchGenerator(reader, {0, 1}, {}));

Review comment:
       So you always have to pass columns explicitly?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r622621186


##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,
+                              reader_fut.MoveResult());
+        std::shared_ptr<parquet::FileMetaData> metadata = reader->metadata();
+        auto arrow_properties = MakeArrowReaderProperties(*self, *metadata);
+        if (options) {
+          arrow_properties.set_batch_size(options->batch_size);
+        }
+        if (options && !options->use_threads) {
+          arrow_properties.set_use_threads(
+              parquet_scan_options->enable_parallel_column_conversion);

Review comment:
       While benchmarking I noticed it got stuck due to this, so there's still nested parallelism coming in somewhere - I'll try to figure this out.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] westonpace commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
westonpace commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r622647276


##########
File path: cpp/src/arrow/dataset/file_parquet.cc
##########
@@ -325,6 +325,45 @@ Result<std::unique_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReader
   return std::move(arrow_reader);
 }

+Future<std::shared_ptr<parquet::arrow::FileReader>> ParquetFileFormat::GetReaderAsync(
+    const FileSource& source, ScanOptions* options) const {
+  ARROW_ASSIGN_OR_RAISE(auto parquet_scan_options,
+                        GetFragmentScanOptions<ParquetFragmentScanOptions>(
+                            kParquetTypeName, options, default_fragment_scan_options));
+  MemoryPool* pool = options ? options->pool : default_memory_pool();
+  auto properties = MakeReaderProperties(*this, parquet_scan_options.get(), pool);
+  ARROW_ASSIGN_OR_RAISE(auto input, source.Open());
+  // Some ugliness needed due to having Future<unique_ptr<>> here
+  auto reader_fut =
+      parquet::ParquetFileReader::OpenAsync(std::move(input), std::move(properties));
+  auto path = source.path();
+  auto self = checked_pointer_cast<const ParquetFileFormat>(shared_from_this());
+  return reader_fut.Then(
+      [=](const std::unique_ptr<parquet::ParquetFileReader>&) mutable
+      -> Result<std::shared_ptr<parquet::arrow::FileReader>> {
+        ARROW_ASSIGN_OR_RAISE(std::unique_ptr<parquet::ParquetFileReader> reader,
+                              reader_fut.MoveResult());
+        std::shared_ptr<parquet::FileMetaData> metadata = reader->metadata();
+        auto arrow_properties = MakeArrowReaderProperties(*self, *metadata);
+        if (options) {
+          arrow_properties.set_batch_size(options->batch_size);
+        }
+        if (options && !options->use_threads) {
+          arrow_properties.set_use_threads(
+              parquet_scan_options->enable_parallel_column_conversion);

Review comment:
       This could be a nice win for async in the HDD/SSD space (still recommending a follow-up PR).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591953765


##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(

Review comment:
       Maybe we can hold this until ARROW-7001 is through and then we can see what exactly we need to be reentrant to get the pipeline we want.

##########
File path: cpp/src/parquet/arrow/reader.cc
##########
@@ -967,6 +978,74 @@ Status FileReaderImpl::GetRecordBatchReader(const std::vector<int>& row_groups,
   return Status::OK();
 }

+/// Given a file reader and a list of row groups, this is a generator of record
+/// batch vectors (where each vector is the contents of a single row group).
+class RowGroupGenerator {
+ public:
+  using Item = ::arrow::util::optional<::arrow::RecordBatchVector>;
+
+  explicit RowGroupGenerator(FileReaderImpl* self, std::vector<int> row_groups,
+                             std::vector<int> column_indices)
+      : self_(self),
+        index_(0),
+        row_groups_(std::move(row_groups)),
+        column_indices_(std::move(column_indices)) {}
+
+  ::arrow::Future<Item> operator()() {
+    if (index_ >= row_groups_.size()) {
+      return ::arrow::Future<Item>::MakeFinished(::arrow::util::nullopt);
+    }
+    int row_group = row_groups_[index_++];
+    FileReaderImpl* self = self_;
+    std::vector<int> column_indices = column_indices_;
+    ARROW_ASSIGN_OR_RAISE(auto fut,
+                          ::arrow::internal::GetCpuThreadPool()->Submit(
+                              &ReadOneRowGroup, self, row_group, column_indices));
+    return fut;
+  }
+
+ private:
+  static ::arrow::Result<Item> ReadOneRowGroup(FileReaderImpl* self, const int row_group,
+                                               const std::vector<int>& column_indices) {
+    std::shared_ptr<::arrow::Table> table;
+    // Call the version that skips bound checks/pre-buffering, since we've done that
+    // already
+    RETURN_NOT_OK(self->ReadRowGroupsImpl({row_group}, column_indices, &table));
+    auto table_reader = std::make_shared<::arrow::TableBatchReader>(*table);
+    ::arrow::RecordBatchVector batches;
+    while (true) {
+      std::shared_ptr<::arrow::RecordBatch> batch;
+      RETURN_NOT_OK(table_reader->ReadNext(&batch));
+      if (!batch) {
+        break;
+      }
+      batches.push_back(batch);
+    }
+    return ::arrow::util::make_optional<::arrow::RecordBatchVector>(std::move(batches));
+  }
+
+  FileReaderImpl* self_;
+  size_t index_;
+  std::vector<int> row_groups_;
+  std::vector<int> column_indices_;
+};
+
+::arrow::Result<
+    ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+FileReaderImpl::GetRecordBatchGenerator(const std::vector<int>& row_groups,
+                                        const std::vector<int>& column_indices) {
+  RETURN_NOT_OK(BoundsCheck(row_groups, column_indices));
+  if (reader_properties_.pre_buffer()) {
+    // PARQUET-1698/PARQUET-1820: pre-buffer row groups/column chunks if enabled
+    BEGIN_PARQUET_CATCH_EXCEPTIONS
+    reader_->PreBuffer(row_groups, column_indices, reader_properties_.io_context(),
+                       reader_properties_.cache_options());
+    END_PARQUET_CATCH_EXCEPTIONS
+  }
+  // N.B. we (and underlying Parquet reader) must outlive generator
+  return RowGroupGenerator(this, row_groups, column_indices);

Review comment:
       I think _that's_ supposed to be ok: iterating the scan task should implicitly keep the scan task alive, what I meant is that the scan task is explicitly keeping the Parquet reader alive.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r591890623


##########
File path: cpp/src/parquet/arrow/reader.h
##########
@@ -175,6 +177,22 @@ class PARQUET_EXPORT FileReader {
       const std::vector<int>& row_group_indices, const std::vector<int>& column_indices,
       std::unique_ptr<::arrow::RecordBatchReader>* out) = 0;

+  /// \brief Return a generator of record batch vectors, where each vector represents
+  ///     the contents of a row group from row_group_indices, whose columns are selected
+  ///     by column_indices.
+  ///
+  /// An empty optional indicates the end of the generator.
+  ///
+  /// Note that the ordering in row_group_indices and column_indices matter. FileReaders
+  /// must outlive their generators.
+  ///
+  /// \returns error Result if either row_group_indices or column_indices contains an
+  ///     invalid index
+  virtual ::arrow::Result<
+      ::arrow::AsyncGenerator<::arrow::util::optional<::arrow::RecordBatchVector>>>
+  GetRecordBatchGenerator(const std::vector<int>& row_group_indices,

Review comment:
       Yes, currently scan tasks know which row group index they correspond to. As part of this we may want to make scan tasks less granular than a single row group as discussed.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] lidavidm commented on a change in pull request #9620: ARROW-11843: [C++] Provide reentrant Parquet reader
Posted by GitBox <gi...@apache.org>.
lidavidm commented on a change in pull request #9620:
URL: https://github.com/apache/arrow/pull/9620#discussion_r621215364


##########
File path: cpp/src/arrow/io/caching.cc
##########
@@ -188,17 +223,51 @@ Result<std::shared_ptr<Buffer>> ReadRangeCache::Read(ReadRange range) {
       [](const RangeCacheEntry& entry, const ReadRange& range) {
         return entry.range.offset + entry.range.length < range.offset + range.length;
       });
+  std::unique_lock<std::mutex> guard = impl_->TakeGuard();
   if (it != impl_->entries.end() && it->range.Contains(range)) {
-    ARROW_ASSIGN_OR_RAISE(auto buf, it->future.result());
+    auto fut = impl_->GetFuture(&*it);

Review comment:
       This is turning the iterator type into an actual pointer.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org