You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2021/01/06 17:24:05 UTC
[GitHub] [hudi] SureshK-T2S commented on issue #2406: [SUPPORT] Deltastreamer - Property hoodie.datasource.write.partitionpath.field not found
SureshK-T2S commented on issue #2406:
URL: https://github.com/apache/hudi/issues/2406#issuecomment-755441343
Thanks for your response @bvaradar. Entering the parameters in that way did the trick for this particular issue.
```
spark-submit --class org.apache.hudi.utilities.deltastreamer.HoodieDeltaStreamer \
> --packages org.apache.hudi:hudi-spark-bundle_2.11:0.6.0,org.apache.spark:spark-avro_2.11:2.4.4\
> --master yarn --deploy-mode client \
> /usr/lib/hudi/hudi-utilities-bundle.jar --table-type MERGE_ON_READ \
> --source-ordering-field updated_at \
> --source-class org.apache.hudi.utilities.sources.ParquetDFSSource \
> --target-base-path s3://mysqlcdc-stream-prod/kinesis-glue-original/hudi_order_table --target-table hudi_order_table \
> --hoodie-conf hoodie.datasource.write.keygenerator.class=org.apache.hudi.keygen.CustomKeyGenerator\
> --hoodie-conf hoodie.datasource.write.recordkey.field=id:TIMESTAMP\
> --hoodie-conf hoodie.deltastreamer.source.dfs.root=s3://mysqlcdc-stream-prod/kinesis-glue-original/order_table\
> --hoodie-conf hoodie.datasource.write.partitionpath.field=order_placed_on:TIMESTAMP
```
However, I ran into another error shortly after(NullPointerException) that I assume is the same as the one seen here: https://issues.apache.org/jira/browse/HUDI-1200
```
Caused by: java.lang.NullPointerException
at org.apache.hudi.keygen.SimpleKeyGenerator.<init>(SimpleKeyGenerator.java:35)
at org.apache.hudi.keygen.CustomKeyGenerator.getRecordKey(CustomKeyGenerator.java:128)
```
As suggested in that ticket I pivoted to using TimeBasedKeyGenerator, but again I ran into another issue:
```
spark-submit --class org.apache.hudi.utilities.deltastreamer.HoodieDeltaStreamer \
> --packages org.apache.hudi:hudi-spark-bundle_2.11:0.6.0,org.apache.spark:spark-avro_2.11:2.4.4\
> --master yarn --deploy-mode client \
> /usr/lib/hudi/hudi-utilities-bundle.jar --table-type MERGE_ON_READ \
> --source-ordering-field updated_at \
> --source-class org.apache.hudi.utilities.sources.ParquetDFSSource \
> --target-base-path s3://mysqlcdc-stream-prod/kinesis-glue-original/hudi_order_table_2 --target-table hudi_order_table_2 \
> --hoodie-conf hoodie.datasource.write.keygenerator.class=org.apache.hudi.keygen.TimestampBasedKeyGenerator\
> --hoodie-conf hoodie.datasource.write.recordkey.field=id\
> --hoodie-conf hoodie.deltastreamer.source.dfs.root=s3://mysqlcdc-stream-prod/kinesis-glue-original/order_table\
> --hoodie-conf hoodie.datasource.write.partitionpath.field=order_placed_on:TIMESTAMP\
> --hoodie-conf hoodie.deltastreamer.keygen.timebased.timestamp.type=DATE_STRING\
> --hoodie-conf hoodie.deltastreamer.keygen.timebased.input.dateformat="yyyy-MM-dd hh:mm:ss"\
> --hoodie-conf hoodie.deltastreamer.keygen.timebased.output.dateformat=yyyy/MM/dd
```
```
Caused by: java.lang.RuntimeException: hoodie.deltastreamer.keygen.timebased.timestamp.scalar.time.unit is not specified but scalar it supplied as time value
at org.apache.hudi.keygen.TimestampBasedKeyGenerator.convertLongTimeToMillis(TimestampBasedKeyGenerator.java:205)
```
I believe this is the same as the issue seen here: https://issues.apache.org/jira/browse/HUDI-1150
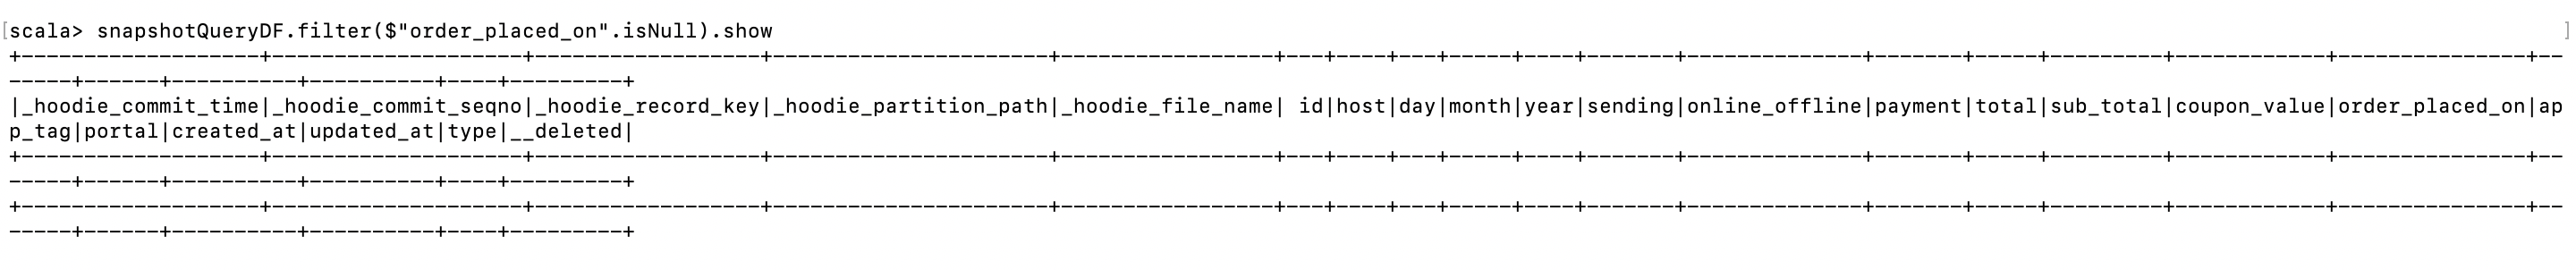
As per that ticket this might be caused by null values in the timestamp partition field. So I pivoted again, and opted for SimpleKeyGenerator on the same data with 3 simple fields instead, which worked great!
```
spark-submit --class org.apache.hudi.utilities.deltastreamer.HoodieDeltaStreamer \
> --packages org.apache.hudi:hudi-spark-bundle_2.11:0.6.0,org.apache.spark:spark-avro_2.11:2.4.4\
> --master yarn --deploy-mode client \
> /usr/lib/hudi/hudi-utilities-bundle.jar --table-type MERGE_ON_READ \
> --source-ordering-field updated_at \
> --source-class org.apache.hudi.utilities.sources.ParquetDFSSource \
> --target-base-path s3://mysqlcdc-stream-prod/kinesis-glue-original/hudi_order_table_2 --target-table hudi_order_table_2 \
> --hoodie-conf hoodie.datasource.write.keygenerator.class=org.apache.hudi.utilities.keygen.ComplexKeyGenerator\
> --hoodie-conf hoodie.datasource.write.recordkey.field=id\
> --hoodie-conf hoodie.deltastreamer.source.dfs.root=s3://mysqlcdc-stream-prod/kinesis-glue-original/order_table\
> --hoodie-conf hoodie.datasource.write.partitionpath.field=year,month,day
```
But when I loaded the data on Spark and checked the field in question there were no null values, only 1970-01-01 values. Could the null values automatically have been converted to those values at some part in the process?
Is it fine if I keep this ticket open while I troubleshoot further? If you'd rather I close this and open another ticket for a different issue please let me know.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org