You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@kylin.apache.org by GitBox <gi...@apache.org> on 2021/12/08 08:14:17 UTC
[GitHub] [kylin] fengpod opened a new pull request #1778: spark hive global dict
fengpod opened a new pull request #1778:
URL: https://github.com/apache/kylin/pull/1778


   ## Proposed changes

   Describe the big picture of your changes here to communicate to the maintainers why we should accept this pull request. If it fixes a bug or resolves a feature request, be sure to link to that issue.

   ## Github Branch

   As most of the development works are on Kylin 4, we need to switch it as main branch. Apache Kylin community changes the branch settings on Github since 2021-08-04 :

   1. The original branch _kylin-on-parquet-v2_ for **Kylin 4.X** (Parquet Storage) has been renamed to branch **main**, and configured as the **default** branch;
   2. The original branch _master_ for **Kylin 3.X** (HBase Storage) has been renamed to branch **kylin3** ;

   Please check [Intro to Kylin 4 architecture](https://kylin.apache.org/blog/2021/07/02/Apache-Kylin4-A-new-storage-and-compute-architecture/) and [INFRA-22166](https://issues.apache.org/jira/browse/INFRA-22166) if you are interested.

   ## Types of changes

   What types of changes does your code introduce to Kylin?
   _Put an `x` in the boxes that apply_

   - [ ] Bugfix (non-breaking change which fixes an issue)
   - [ ] New feature (non-breaking change which adds functionality)
   - [ ] Breaking change (fix or feature that would cause existing functionality to not work as expected)
   - [ ] Documentation Update (if none of the other choices apply)

   ## Checklist

   _Put an `x` in the boxes that apply. You can also fill these out after creating the PR. If you're unsure about any of them, don't hesitate to ask. We're here to help! This is simply a reminder of what we are going to look for before merging your code._

   - [ ] I have create an issue on [Kylin's jira](https://issues.apache.org/jira/browse/KYLIN), and have described the bug/feature there in detail
   - [ ] Commit messages in my PR start with the related jira ID, like "KYLIN-0000 Make Kylin project open-source"
   - [ ] Compiling and unit tests pass locally with my changes
   - [ ] I have added tests that prove my fix is effective or that my feature works
   - [ ] I have added necessary documentation (if appropriate)
   - [ ] Any dependent changes have been merged

   ## Further comments

   If this is a relatively large or complex change, kick off the discussion at user@kylin or dev@kylin by explaining why you chose the solution you did and what alternatives you considered, etc...


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] zhangayqian edited a comment on pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
zhangayqian edited a comment on pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#issuecomment-1002430840
@fengpod
The following three problems were found during the test:
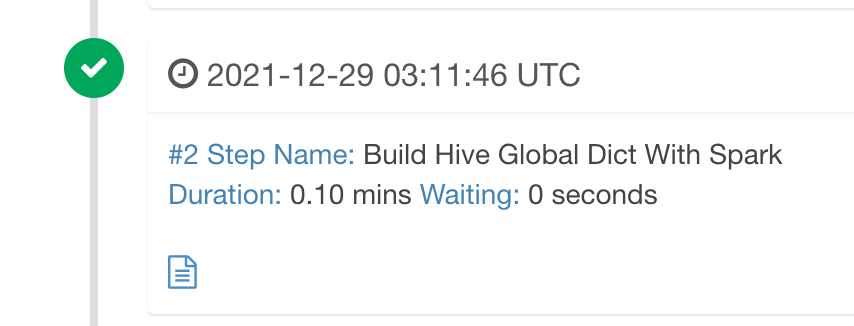
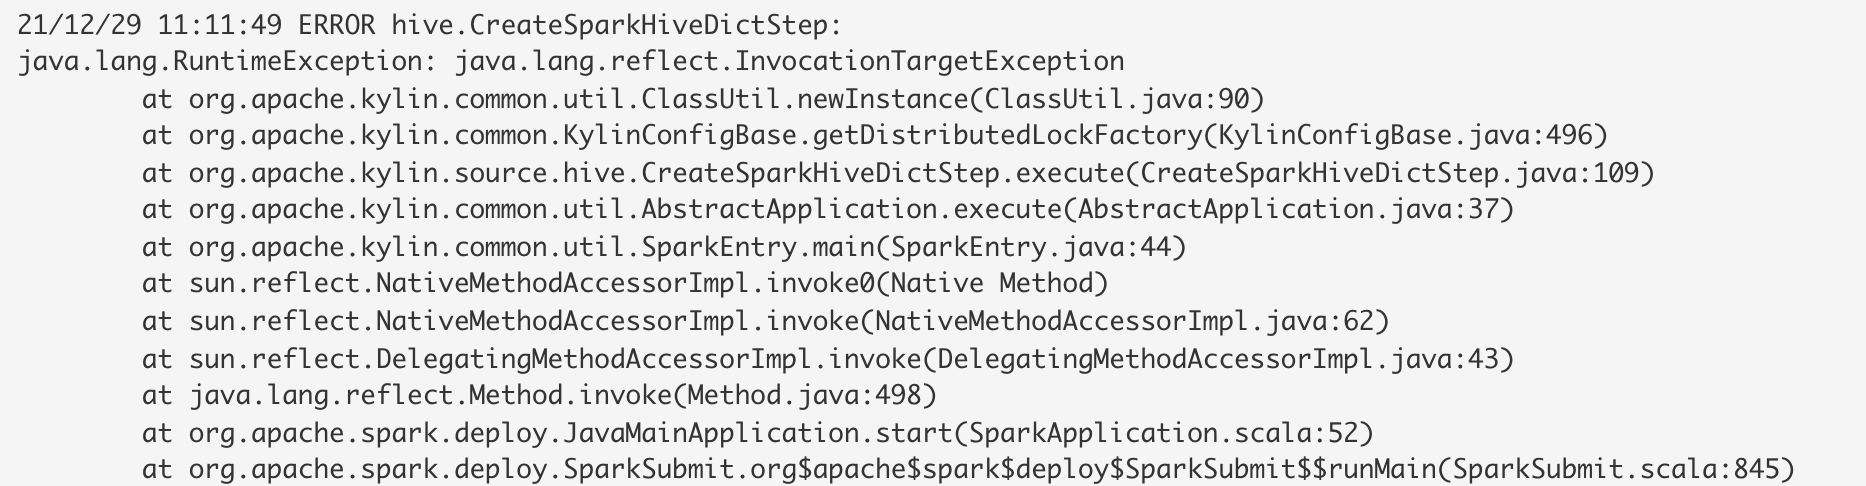
1. Step `Build Hive Global Dict With Spark` has actually made an error, but it still shows success. It should be that the exception is not thrown after being catch.
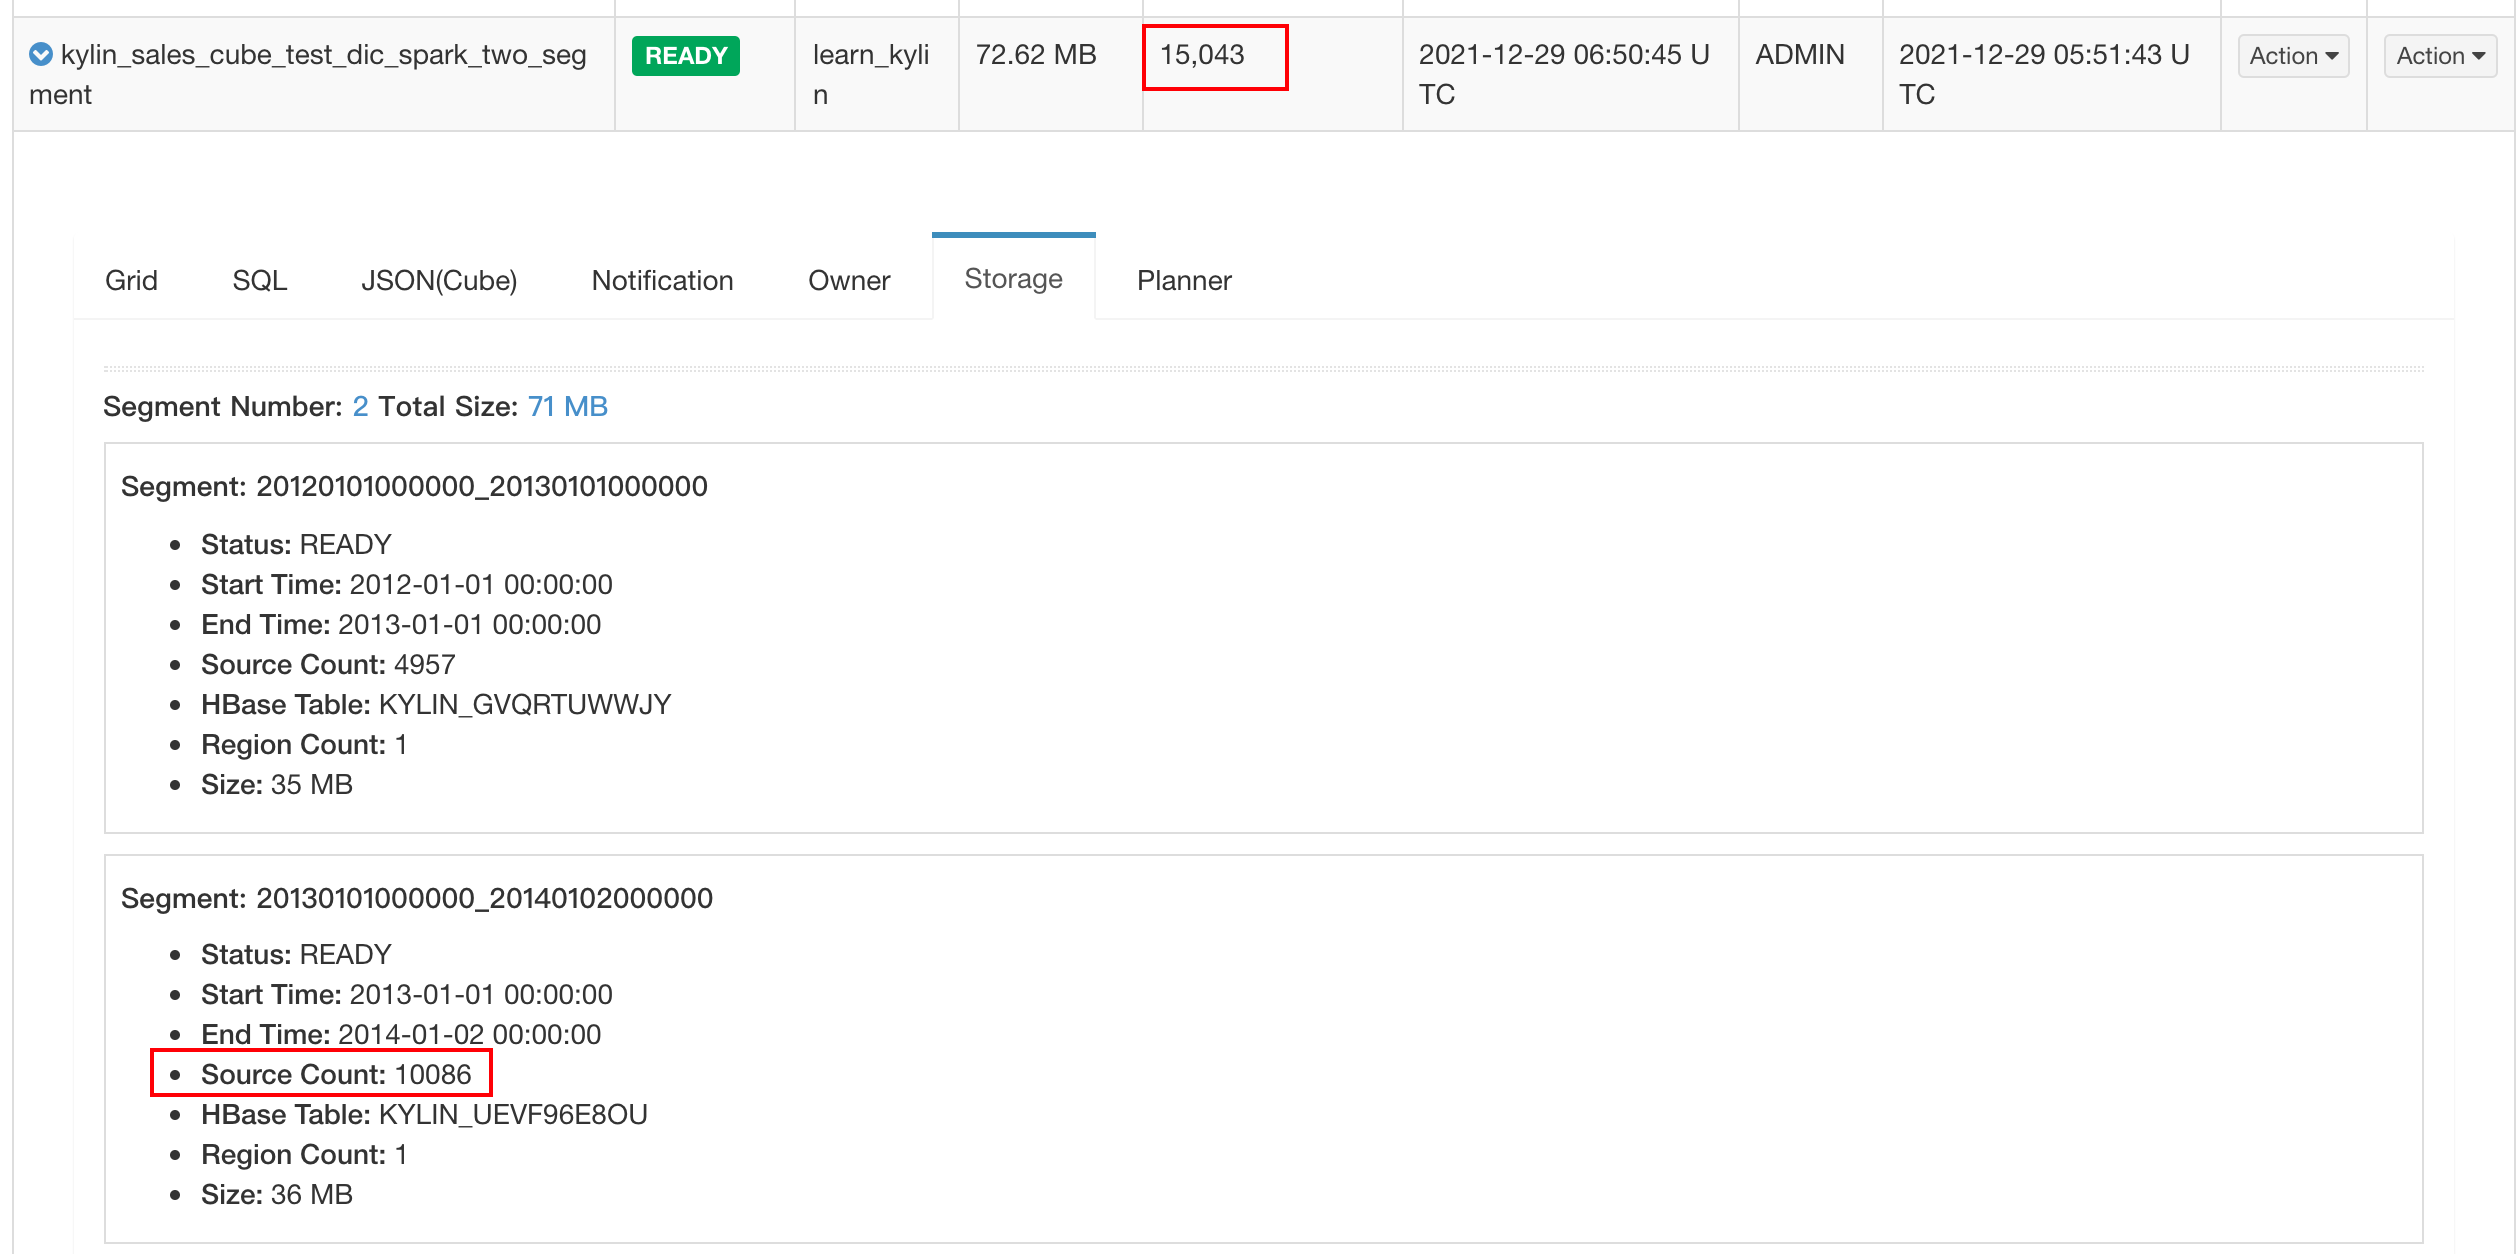
2. After building more than one segment, the total count of the fact table will become more than the actual number. Actually, `kylin_sales` has only 10000 pieces of data.
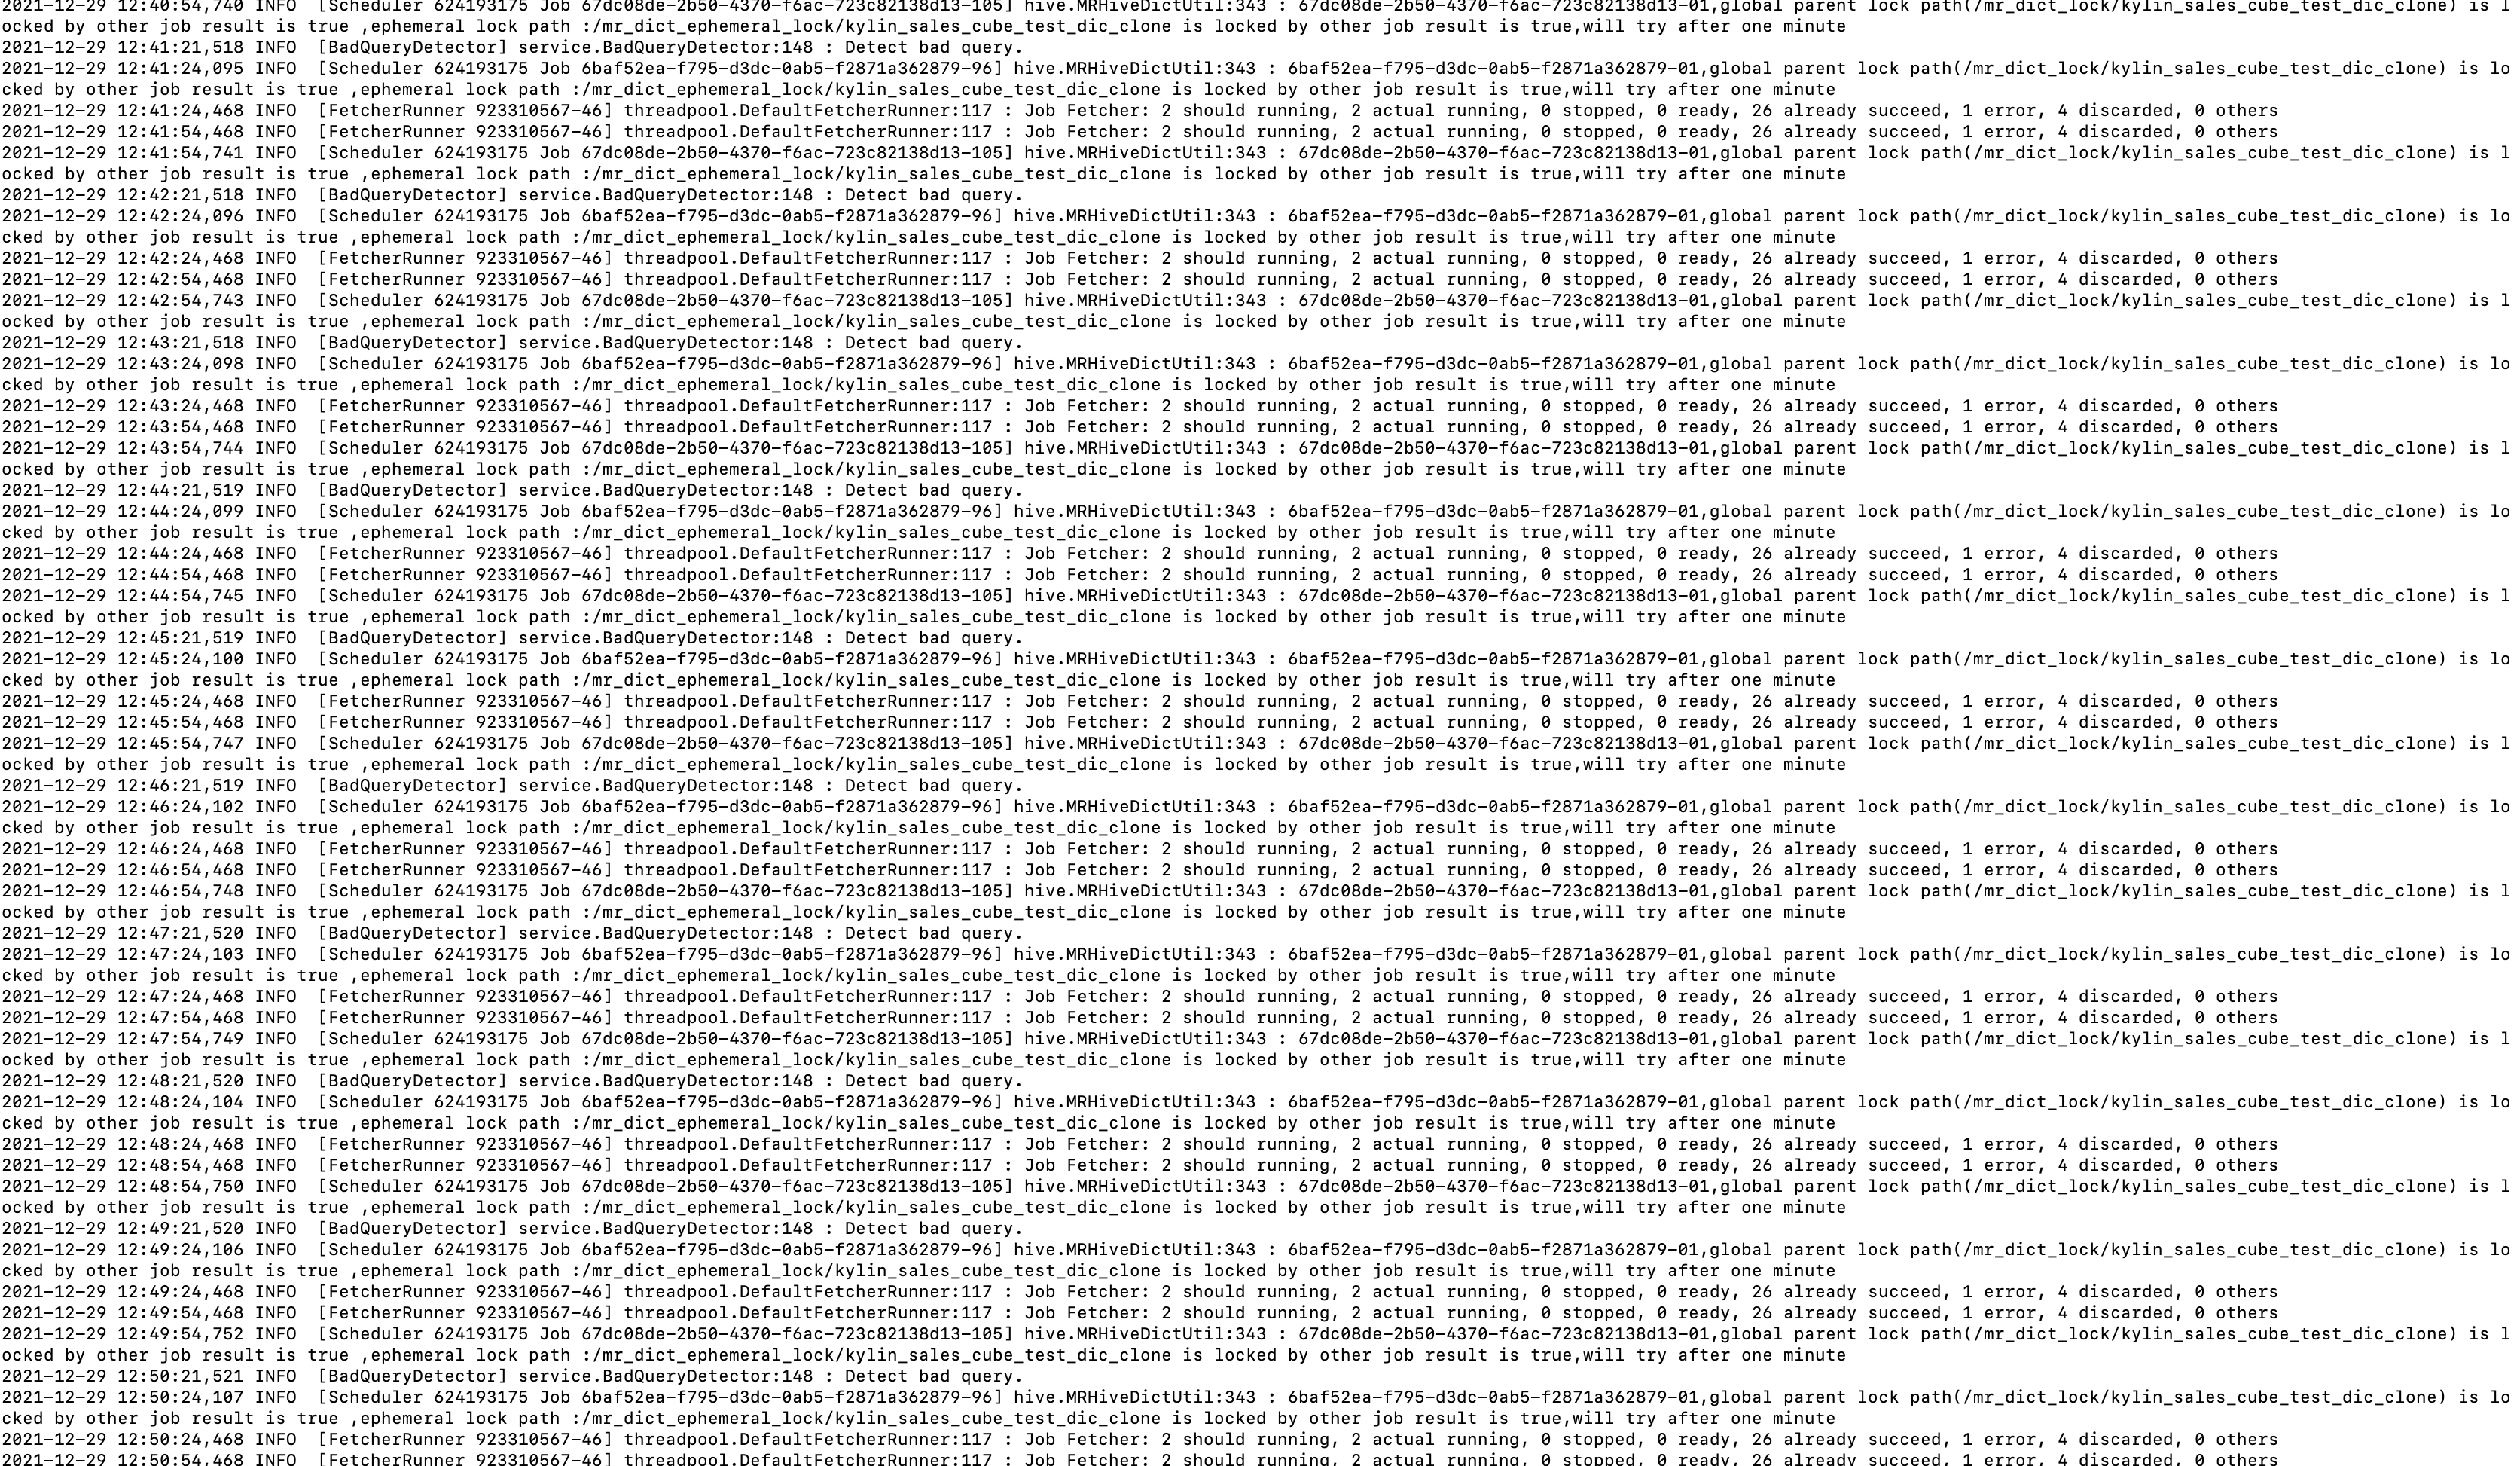
3. The original dictionary lock logic is destroyed. After using MR to build a global dictionary, the dictionary lock is not purged, resulting in the failure to obtain the lock when building the next segment of the same cube.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] codecov-commenter commented on pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
codecov-commenter commented on pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#issuecomment-988708459
# [Codecov](https://codecov.io/gh/apache/kylin/pull/1778?src=pr&el=h1&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation) Report
> :exclamation: No coverage uploaded for pull request base (`kylin3@a247fd9`). [Click here to learn what that means](https://docs.codecov.io/docs/error-reference?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#section-missing-base-commit).
> The diff coverage is `n/a`.
[](https://codecov.io/gh/apache/kylin/pull/1778?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation)
```diff
@@ Coverage Diff @@
## kylin3 #1778 +/- ##
=========================================
Coverage ? 25.07%
Complexity ? 6789
=========================================
Files ? 1520
Lines ? 95502
Branches ? 13333
=========================================
Hits ? 23951
Misses ? 69159
Partials ? 2392
```
------
[Continue to review full report at Codecov](https://codecov.io/gh/apache/kylin/pull/1778?src=pr&el=continue&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation).
> **Legend** - [Click here to learn more](https://docs.codecov.io/docs/codecov-delta?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation)
> `Δ = absolute <relative> (impact)`, `ø = not affected`, `? = missing data`
> Powered by [Codecov](https://codecov.io/gh/apache/kylin/pull/1778?src=pr&el=footer&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation). Last update [a247fd9...440a9a2](https://codecov.io/gh/apache/kylin/pull/1778?src=pr&el=lastupdated&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation). Read the [comment docs](https://docs.codecov.io/docs/pull-request-comments?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation).
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] zhangayqian commented on a change in pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
zhangayqian commented on a change in pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#discussion_r776139094


##########
File path: source-hive/src/main/java/org/apache/kylin/source/hive/CreateSparkHiveDictStep.java
##########
@@ -0,0 +1,294 @@
+/*
+ * Licensed to the Apache Software Foundation (ASF) under one
+ * or more contributor license agreements.  See the NOTICE file
+ * distributed with this work for additional information
+ * regarding copyright ownership.  The ASF licenses this file
+ * to you under the Apache License, Version 2.0 (the
+ * "License"); you may not use this file except in compliance
+ * with the License.  You may obtain a copy of the License at
+ *
+ *     http://www.apache.org/licenses/LICENSE-2.0
+ *
+ * Unless required by applicable law or agreed to in writing, software
+ * distributed under the License is distributed on an "AS IS" BASIS,
+ * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+ * See the License for the specific language governing permissions and
+ * limitations under the License.
+ */
+package org.apache.kylin.source.hive;
+
+import org.apache.commons.cli.Option;
+import org.apache.commons.cli.OptionBuilder;
+import org.apache.commons.cli.Options;
+import org.apache.kylin.common.KylinConfig;
+import org.apache.kylin.common.lock.DistributedLock;
+import org.apache.kylin.common.util.AbstractApplication;
+import org.apache.kylin.common.util.OptionsHelper;
+import org.apache.kylin.cube.CubeInstance;
+import org.apache.kylin.cube.CubeManager;
+import org.apache.kylin.cube.CubeSegment;
+import org.apache.kylin.engine.EngineFactory;
+import org.apache.kylin.engine.mr.common.AbstractHadoopJob;
+import org.apache.kylin.engine.mr.common.BatchConstants;
+import org.apache.kylin.engine.mr.common.SerializableConfiguration;
+import org.apache.kylin.job.common.PatternedLogger;
+import org.apache.kylin.metadata.model.IJoinedFlatTableDesc;
+import org.apache.kylin.shaded.com.google.common.collect.Lists;
+import org.apache.kylin.shaded.com.google.common.collect.Maps;
+import org.apache.spark.TaskContext;
+import org.apache.spark.api.java.function.MapPartitionsFunction;
+import org.apache.spark.sql.Dataset;
+import org.apache.spark.sql.Encoders;
+import org.apache.spark.sql.Row;
+import org.apache.spark.sql.RowFactory;
+import org.apache.spark.sql.SparkSession;
+import org.apache.spark.sql.types.DataTypes;
+import org.apache.spark.sql.types.StructField;
+import org.apache.spark.sql.types.StructType;
+import org.slf4j.Logger;
+import org.slf4j.LoggerFactory;
+
+import java.io.Serializable;
+import java.util.Iterator;
+import java.util.List;
+import java.util.Locale;
+import java.util.Map;
+import java.util.UUID;
+import java.util.concurrent.locks.Lock;
+import java.util.concurrent.locks.ReentrantLock;
+
+public class CreateSparkHiveDictStep extends AbstractApplication implements Serializable {
+
+    private static final Logger logger = LoggerFactory.getLogger(CreateSparkHiveDictStep.class);
+
+    private transient final PatternedLogger stepLogger = new PatternedLogger(logger);
+
+    public static final Option OPTION_CUBE_NAME = OptionBuilder.withArgName(BatchConstants.ARG_CUBE_NAME).hasArg().isRequired(true).withDescription("Cube Name").create(BatchConstants.ARG_CUBE_NAME);
+    public static final Option OPTION_HIVE_DICT_COLUMNS = OptionBuilder.withArgName("hiveDictColumns").hasArg().isRequired(true).withDescription("Hive Dict Columns").create("hiveDictColumns");
+    public static final Option OPTION_META_URL = OptionBuilder.withArgName("metaUrl").hasArg().isRequired(true).withDescription("Meta Url").create("metaUrl");
+    public static final Option OPTION_SEGMENT_ID = OptionBuilder.withArgName("segmentId").hasArg().isRequired(true).withDescription("Segment Id").create("segmentId");
+    public static final Option OPTION_FLOW_JOB_ID = OptionBuilder.withArgName("flowJobId").hasArg().isRequired(true).withDescription("Flow Job Id").create("flowJobId");
+    public static final Option OPTION_WAREHOUSE_DIR = OptionBuilder.withArgName("wareHouseDir").hasArg().isRequired(true).withDescription("WareHouse Dir").create("wareHouseDir");
+
+    private final Lock threadLock = new ReentrantLock();
+
+    private Options options;
+
+    public CreateSparkHiveDictStep() {
+        options = new Options();
+        options.addOption(OPTION_CUBE_NAME);
+        options.addOption(OPTION_HIVE_DICT_COLUMNS);
+        options.addOption(OPTION_META_URL);
+        options.addOption(OPTION_SEGMENT_ID);
+        options.addOption(OPTION_FLOW_JOB_ID);
+        options.addOption(OPTION_WAREHOUSE_DIR);
+    }
+
+    private String cubeName;
+    private String segmentId;
+    private String[] hiveDictColumns;
+    private String metaUrl;
+    private String flowJobId;
+    private String wareHouseDir;
+
+    private void initParam(OptionsHelper optionsHelper) {
+        cubeName = optionsHelper.getOptionValue(OPTION_CUBE_NAME);
+        segmentId = optionsHelper.getOptionValue(OPTION_SEGMENT_ID);
+        hiveDictColumns = optionsHelper.getOptionValue(OPTION_HIVE_DICT_COLUMNS).split(",");
+        metaUrl = optionsHelper.getOptionValue(OPTION_META_URL);
+        flowJobId = optionsHelper.getOptionValue(OPTION_FLOW_JOB_ID);
+        wareHouseDir = optionsHelper.getOptionValue(OPTION_WAREHOUSE_DIR);
+    }
+
+    @Override
+    protected void execute(OptionsHelper optionsHelper) {
+        initParam(optionsHelper);
+
+        DistributedLock lock = null;
+        try {
+            lock = KylinConfig.getInstanceFromEnv().getDistributedLockFactory().lockForCurrentThread();
+
+            createSparkHiveDict(lock);
+
+        } catch (Exception e) {
+            logger.error("", e);

Review comment:
       Why not throw this exception?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] hit-lacus commented on pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
hit-lacus commented on pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#issuecomment-1000246339


   @fengpod  Did you met this issues before?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] lgtm-com[bot] commented on pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
lgtm-com[bot] commented on pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#issuecomment-988617237


   This pull request **introduces 1 alert** when merging 440a9a2b18b8563c08e125b98d99ad75a8777127 into a247fd98274fd6ae078cb23c237e32903ef0fe7e - [view on LGTM.com](https://lgtm.com/projects/g/apache/kylin/rev/pr-b7117b6aa44731002fb55372cbff75dab0bcb26c)

   **new alerts:**

   * 1 for Boxed variable is never null


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] zhangayqian commented on pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
zhangayqian commented on pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#issuecomment-1002430840
@fengpod
The following three problems were found during the test:
1. Step `Build Hive Global Dict With Spark` has actually made an error, but it still shows success. It should be that the exception is not thrown after being catch.


2. After building more than one segment, the total count of the fact table will become more than the actual number. Actually, kylin_sales has only 10000 pieces of data.

3. The original dictionary lock logic is destroyed. After using MR to build a global dictionary, the dictionary lock is not purged, resulting in the failure to obtain the lock when building the next segment of the same cube.

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] hit-lacus commented on pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
hit-lacus commented on pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#issuecomment-1000214302


   Find Exception.

   ```java
   2021-12-23 17:17:43,212 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO storage.BlockManagerInfo: Added broadcast_7_piece0 in memory on cdh-worker-2:41969 (size: 28.6 KB, free: 912.2 MB)
   2021-12-23 17:17:43,212 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO spark.SparkContext: Created broadcast 7 from
   2021-12-23 17:17:43,371 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO mapred.FileInputFormat: Total input paths to process : 4
   2021-12-23 17:17:43,430 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 ERROR hive.CreateSparkHiveDictStep:
   2021-12-23 17:17:43,430 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : org.apache.spark.SparkException: Task not serializable
   2021-12-23 17:17:43,430 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.ensureSerializable(ClosureCleaner.scala:403)
   2021-12-23 17:17:43,430 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.org$apache$spark$util$ClosureCleaner$$clean(ClosureCleaner.scala:393)
   2021-12-23 17:17:43,430 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.clean(ClosureCleaner.scala:162)
   2021-12-23 17:17:43,430 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.SparkContext.clean(SparkContext.scala:2326)
   2021-12-23 17:17:43,430 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.SparkContext.runJob(SparkContext.scala:2100)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.SparkContext.runJob(SparkContext.scala:2126)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDD$$anonfun$collect$1.apply(RDD.scala:990)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDDOperationScope$.withScope(RDDOperationScope.scala:151)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDDOperationScope$.withScope(RDDOperationScope.scala:112)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDD.withScope(RDD.scala:385)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDD.collect(RDD.scala:989)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SparkPlan.executeCollect(SparkPlan.scala:299)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset.org$apache$spark$sql$Dataset$$collectFromPlan(Dataset.scala:3389)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset$$anonfun$collectAsList$1.apply(Dataset.scala:2800)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset$$anonfun$collectAsList$1.apply(Dataset.scala:2799)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset$$anonfun$52.apply(Dataset.scala:3370)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SQLExecution$$anonfun$withNewExecutionId$1.apply(SQLExecution.scala:80)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SQLExecution$.withSQLConfPropagated(SQLExecution.scala:127)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SQLExecution$.withNewExecutionId(SQLExecution.scala:75)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset.withAction(Dataset.scala:3369)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset.collectAsList(Dataset.scala:2799)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.source.hive.CreateSparkHiveDictStep.getPartitionDataCountMap(CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.source.hive.CreateSparkHiveDictStep.createSparkHiveDict(CreateSparkHiveDictStep.java:183)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.source.hive.CreateSparkHiveDictStep.execute(CreateSparkHiveDictStep.java:110)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.common.util.AbstractApplication.execute(AbstractApplication.java:37)
   2021-12-23 17:17:43,431 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.common.util.SparkEntry.main(SparkEntry.java:44)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at java.lang.reflect.Method.invoke(Method.java:498)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.JavaMainApplication.start(SparkApplication.scala:52)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.org$apache$spark$deploy$SparkSubmit$$runMain(SparkSubmit.scala:845)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.doRunMain$1(SparkSubmit.scala:161)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.submit(SparkSubmit.scala:184)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.doSubmit(SparkSubmit.scala:86)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit$$anon$2.doSubmit(SparkSubmit.scala:920)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit$.main(SparkSubmit.scala:929)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.main(SparkSubmit.scala)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : Caused by: java.io.NotSerializableException: org.apache.kylin.job.common.PatternedLogger
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : Serialization stack:
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object not serializable (class: org.apache.kylin.job.common.PatternedLogger, value: org.apache.kylin.job.common.PatternedLogger@43905ade)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.kylin.source.hive.CreateSparkHiveDictStep, name: stepLogger, type: class org.apache.kylin.job.common.PatternedLogger)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.kylin.source.hive.CreateSparkHiveDictStep, org.apache.kylin.source.hive.CreateSparkHiveDictStep@6f67291f)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.kylin.source.hive.CreateSparkHiveDictStep$2, name: this$0, type: class org.apache.kylin.source.hive.CreateSparkHiveDictStep)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.kylin.source.hive.CreateSparkHiveDictStep$2, org.apache.kylin.source.hive.CreateSparkHiveDictStep$2@4f2ab774)
   2021-12-23 17:17:43,432 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.sql.Dataset$$anonfun$43, name: f$5, type: interface org.apache.spark.api.java.function.MapPartitionsFunction)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.sql.Dataset$$anonfun$43, <function1>)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.sql.execution.MapPartitionsExec, name: func, type: interface scala.Function1)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.sql.execution.MapPartitionsExec, MapPartitions <function1>, obj#50: java.lang.String
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : +- DeserializeToObject createexternalrow(dict_key#40.toString, StructField(dict_key,StringType,true)), obj#49: org.apache.spark.sql.Row
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 :    +- InMemoryTableScan [dict_key#40]
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 :          +- InMemoryRelation [dict_key#40], StorageLevel(disk, memory, deserialized, 1 replicas)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 :                +- Scan hive yaqian.kylin_intermediate_kylin_sales_cube_test_dic_spark_898e2825_6401_9864_424d_190fd4868a6f_distinct_value [dict_key#40], HiveTableRelation `yaqian`.`kylin_intermediate_kylin_sales_cube_test_dic_spark_898e2825_6401_9864_424d_190fd4868a6f_distinct_value`, org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe, [dict_key#40], [dict_column#41], [isnotnull(dict_column#41), (dict_column#41 = KYLIN_SALES_OPS_USER_ID)]
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : )
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.sql.execution.MapPartitionsExec$$anonfun$5, name: $outer, type: class org.apache.spark.sql.execution.MapPartitionsExec)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.sql.execution.MapPartitionsExec$$anonfun$5, <function1>)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1, name: f$24, type: interface scala.Function1)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1, <function0>)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1$$anonfun$apply$24, name: $outer, type: class org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1$$anonfun$apply$24, <function3>)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.MapPartitionsRDD, name: f, type: interface scala.Function3)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.MapPartitionsRDD, MapPartitionsRDD[36] at collectAsList at CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,433 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.NarrowDependency, name: _rdd, type: class org.apache.spark.rdd.RDD)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.OneToOneDependency, org.apache.spark.OneToOneDependency@74a680d3)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeObject data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.List$SerializationProxy, scala.collection.immutable.List$SerializationProxy@2bd24c09)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeReplace data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.$colon$colon, List(org.apache.spark.OneToOneDependency@74a680d3))
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD, name: org$apache$spark$rdd$RDD$$dependencies_, type: interface scala.collection.Seq)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.MapPartitionsRDD, MapPartitionsRDD[37] at collectAsList at CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.NarrowDependency, name: _rdd, type: class org.apache.spark.rdd.RDD)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.OneToOneDependency, org.apache.spark.OneToOneDependency@7ec9d826)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeObject data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.List$SerializationProxy, scala.collection.immutable.List$SerializationProxy@420849f6)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeReplace data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.$colon$colon, List(org.apache.spark.OneToOneDependency@7ec9d826))
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD, name: org$apache$spark$rdd$RDD$$dependencies_, type: interface scala.collection.Seq)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.MapPartitionsRDD, MapPartitionsRDD[38] at collectAsList at CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$collect$1, name: $outer, type: class org.apache.spark.rdd.RDD)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$collect$1, <function0>)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$collect$1$$anonfun$15, name: $outer, type: class org.apache.spark.rdd.RDD$$anonfun$collect$1)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$collect$1$$anonfun$15, <function1>)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.serializer.SerializationDebugger$.improveException(SerializationDebugger.scala:40)
   2021-12-23 17:17:43,434 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.serializer.JavaSerializationStream.writeObject(JavaSerializer.scala:46)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.serializer.JavaSerializerInstance.serialize(JavaSerializer.scala:100)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.ensureSerializable(ClosureCleaner.scala:400)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	... 37 more
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 ERROR hive.CreateSparkHiveDictStep:
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : org.apache.spark.SparkException: Task not serializable
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.ensureSerializable(ClosureCleaner.scala:403)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.org$apache$spark$util$ClosureCleaner$$clean(ClosureCleaner.scala:393)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.clean(ClosureCleaner.scala:162)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.SparkContext.clean(SparkContext.scala:2326)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.SparkContext.runJob(SparkContext.scala:2100)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.SparkContext.runJob(SparkContext.scala:2126)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDD$$anonfun$collect$1.apply(RDD.scala:990)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDDOperationScope$.withScope(RDDOperationScope.scala:151)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDDOperationScope$.withScope(RDDOperationScope.scala:112)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDD.withScope(RDD.scala:385)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.rdd.RDD.collect(RDD.scala:989)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SparkPlan.executeCollect(SparkPlan.scala:299)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset.org$apache$spark$sql$Dataset$$collectFromPlan(Dataset.scala:3389)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset$$anonfun$collectAsList$1.apply(Dataset.scala:2800)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset$$anonfun$collectAsList$1.apply(Dataset.scala:2799)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset$$anonfun$52.apply(Dataset.scala:3370)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SQLExecution$$anonfun$withNewExecutionId$1.apply(SQLExecution.scala:80)
   2021-12-23 17:17:43,435 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SQLExecution$.withSQLConfPropagated(SQLExecution.scala:127)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.execution.SQLExecution$.withNewExecutionId(SQLExecution.scala:75)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset.withAction(Dataset.scala:3369)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.sql.Dataset.collectAsList(Dataset.scala:2799)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.source.hive.CreateSparkHiveDictStep.getPartitionDataCountMap(CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.source.hive.CreateSparkHiveDictStep.createSparkHiveDict(CreateSparkHiveDictStep.java:183)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.source.hive.CreateSparkHiveDictStep.execute(CreateSparkHiveDictStep.java:110)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.common.util.AbstractApplication.execute(AbstractApplication.java:37)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.kylin.common.util.SparkEntry.main(SparkEntry.java:44)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at java.lang.reflect.Method.invoke(Method.java:498)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.JavaMainApplication.start(SparkApplication.scala:52)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.org$apache$spark$deploy$SparkSubmit$$runMain(SparkSubmit.scala:845)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.doRunMain$1(SparkSubmit.scala:161)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.submit(SparkSubmit.scala:184)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.doSubmit(SparkSubmit.scala:86)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit$$anon$2.doSubmit(SparkSubmit.scala:920)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit$.main(SparkSubmit.scala:929)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.deploy.SparkSubmit.main(SparkSubmit.scala)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : Caused by: java.io.NotSerializableException: org.apache.kylin.job.common.PatternedLogger
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : Serialization stack:
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object not serializable (class: org.apache.kylin.job.common.PatternedLogger, value: org.apache.kylin.job.common.PatternedLogger@43905ade)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.kylin.source.hive.CreateSparkHiveDictStep, name: stepLogger, type: class org.apache.kylin.job.common.PatternedLogger)
   2021-12-23 17:17:43,436 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.kylin.source.hive.CreateSparkHiveDictStep, org.apache.kylin.source.hive.CreateSparkHiveDictStep@6f67291f)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.kylin.source.hive.CreateSparkHiveDictStep$2, name: this$0, type: class org.apache.kylin.source.hive.CreateSparkHiveDictStep)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.kylin.source.hive.CreateSparkHiveDictStep$2, org.apache.kylin.source.hive.CreateSparkHiveDictStep$2@4f2ab774)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.sql.Dataset$$anonfun$43, name: f$5, type: interface org.apache.spark.api.java.function.MapPartitionsFunction)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.sql.Dataset$$anonfun$43, <function1>)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.sql.execution.MapPartitionsExec, name: func, type: interface scala.Function1)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.sql.execution.MapPartitionsExec, MapPartitions <function1>, obj#50: java.lang.String
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : +- DeserializeToObject createexternalrow(dict_key#40.toString, StructField(dict_key,StringType,true)), obj#49: org.apache.spark.sql.Row
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 :    +- InMemoryTableScan [dict_key#40]
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 :          +- InMemoryRelation [dict_key#40], StorageLevel(disk, memory, deserialized, 1 replicas)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 :                +- Scan hive yaqian.kylin_intermediate_kylin_sales_cube_test_dic_spark_898e2825_6401_9864_424d_190fd4868a6f_distinct_value [dict_key#40], HiveTableRelation `yaqian`.`kylin_intermediate_kylin_sales_cube_test_dic_spark_898e2825_6401_9864_424d_190fd4868a6f_distinct_value`, org.apache.hadoop.hive.serde2.lazy.LazySimpleSerDe, [dict_key#40], [dict_column#41], [isnotnull(dict_column#41), (dict_column#41 = KYLIN_SALES_OPS_USER_ID)]
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : )
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.sql.execution.MapPartitionsExec$$anonfun$5, name: $outer, type: class org.apache.spark.sql.execution.MapPartitionsExec)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.sql.execution.MapPartitionsExec$$anonfun$5, <function1>)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1, name: f$24, type: interface scala.Function1)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1, <function0>)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1$$anonfun$apply$24, name: $outer, type: class org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1)
   2021-12-23 17:17:43,437 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$mapPartitionsInternal$1$$anonfun$apply$24, <function3>)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.MapPartitionsRDD, name: f, type: interface scala.Function3)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.MapPartitionsRDD, MapPartitionsRDD[36] at collectAsList at CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.NarrowDependency, name: _rdd, type: class org.apache.spark.rdd.RDD)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.OneToOneDependency, org.apache.spark.OneToOneDependency@74a680d3)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeObject data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.List$SerializationProxy, scala.collection.immutable.List$SerializationProxy@2bd24c09)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeReplace data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.$colon$colon, List(org.apache.spark.OneToOneDependency@74a680d3))
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD, name: org$apache$spark$rdd$RDD$$dependencies_, type: interface scala.collection.Seq)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.MapPartitionsRDD, MapPartitionsRDD[37] at collectAsList at CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.NarrowDependency, name: _rdd, type: class org.apache.spark.rdd.RDD)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.OneToOneDependency, org.apache.spark.OneToOneDependency@7ec9d826)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeObject data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.List$SerializationProxy, scala.collection.immutable.List$SerializationProxy@420849f6)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- writeReplace data (class: scala.collection.immutable.List$SerializationProxy)
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class scala.collection.immutable.$colon$colon, List(org.apache.spark.OneToOneDependency@7ec9d826))
   2021-12-23 17:17:43,438 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD, name: org$apache$spark$rdd$RDD$$dependencies_, type: interface scala.collection.Seq)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.MapPartitionsRDD, MapPartitionsRDD[38] at collectAsList at CreateSparkHiveDictStep.java:262)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$collect$1, name: $outer, type: class org.apache.spark.rdd.RDD)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$collect$1, <function0>)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- field (class: org.apache.spark.rdd.RDD$$anonfun$collect$1$$anonfun$15, name: $outer, type: class org.apache.spark.rdd.RDD$$anonfun$collect$1)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	- object (class org.apache.spark.rdd.RDD$$anonfun$collect$1$$anonfun$15, <function1>)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.serializer.SerializationDebugger$.improveException(SerializationDebugger.scala:40)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.serializer.JavaSerializationStream.writeObject(JavaSerializer.scala:46)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.serializer.JavaSerializerInstance.serialize(JavaSerializer.scala:100)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	at org.apache.spark.util.ClosureCleaner$.ensureSerializable(ClosureCleaner.scala:400)
   2021-12-23 17:17:43,439 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 	... 37 more
   2021-12-23 17:17:43,536 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO zookeeper.ZookeeperDistributedLock: 1-12139@cdh-worker-2 purged all locks under /mr_dict_lock/kylin_sales_cube_test_dic_SPARK
   2021-12-23 17:17:43,536 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO hive.CreateSparkHiveDictStep: zookeeper unlock path :/mr_dict_lock/kylin_sales_cube_test_dic_SPARK
   2021-12-23 17:17:43,536 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO hive.MRHiveDictUtil: 27ee316a-470b-4633-4a75-8de88142c05f unlock full lock path :/mr_dict_lock/kylin_sales_cube_test_dic_SPARK success
   2021-12-23 17:17:43,550 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO zookeeper.ZookeeperDistributedLock: 1-12139@cdh-worker-2 purged all locks under /mr_dict_ephemeral_lock/kylin_sales_cube_test_dic_SPARK
   2021-12-23 17:17:43,550 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO hive.CreateSparkHiveDictStep: zookeeper unlock path :/mr_dict_ephemeral_lock/kylin_sales_cube_test_dic_SPARK
   2021-12-23 17:17:43,550 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO hive.MRHiveDictUtil: 27ee316a-470b-4633-4a75-8de88142c05f unlock full lock path :/mr_dict_ephemeral_lock/kylin_sales_cube_test_dic_SPARK success
   2021-12-23 17:17:43,551 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO util.ZKUtil: Going to remove 1 cached curator clients
   2021-12-23 17:17:43,554 INFO  [pool-20-thread-1] spark.SparkExecutable:41 : 21/12/23 17:17:43 INFO spark.SparkContext: Invoking stop() from shutdown hook
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [kylin] fengpod commented on pull request #1778: KYLIN-5097 spark hive global dict
Posted by GitBox <gi...@apache.org>.
fengpod commented on pull request #1778:
URL: https://github.com/apache/kylin/pull/1778#issuecomment-1001896249


   @hit-lacus i have fixed it,and resolved conflicts


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@kylin.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org