You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2020/11/10 08:39:41 UTC
[GitHub] [hudi] kpurella opened a new issue #2240: [SUPPORT] HUDI MOR ,UPSERT Job running forever
kpurella opened a new issue #2240:
URL: https://github.com/apache/hudi/issues/2240
**_Tips before filing an issue_**
- Have you gone through our [FAQs](https://cwiki.apache.org/confluence/display/HUDI/FAQ)? yes
- Join the mailing list to engage in conversations and get faster support at dev-subscribe@hudi.apache.org.
- If you have triaged this as a bug, then file an [issue](https://issues.apache.org/jira/projects/HUDI/issues) directly.
**Describe the problem you faced**
A clear and concise description of the problem.
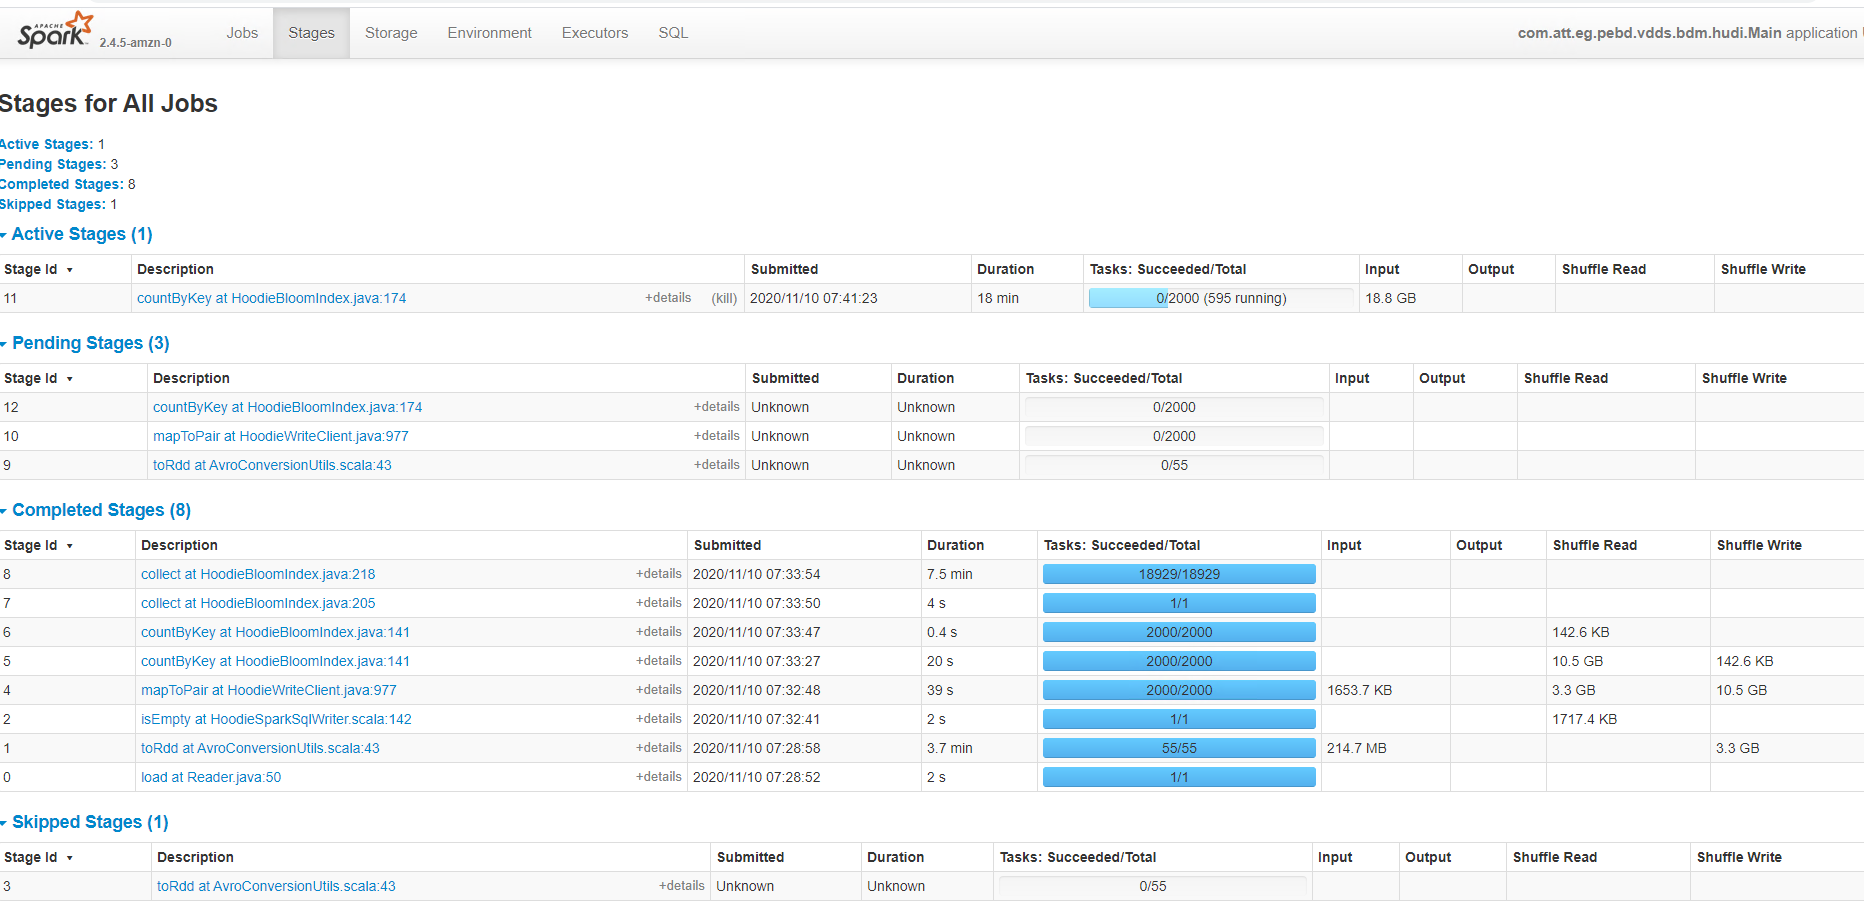
- We are seeing a strange issue with Hudi's job, as we are trying to write more than a billion updates to the master hudi table which holds 10 billion records. the job got stuck st stage 11 from the below screenshot, and waited forever to complete the write, Eventually, we have to kill the job.
**To Reproduce**
Steps to reproduce the behavior:
1.Ingest 10 Billion records ( each record size 1KB ) to hudi table using Bulk insert and MOR
2. try to write 1 Billion updates to the master.
3.
4.
**Expected behavior**
A clear and concise description of what you expected to happen.
- Hudi should complete the update process. as this is a simple hudi job without any transformation.
**Environment Description**
* Hudi version : 0.5.2incubating/0.6.0 ( tried on both the versions) on EMR
* Spark version : 2.4.5/2/4/6
* Hive version : 2.3.6
* Hadoop version :2.8.5/2.10
* Storage (HDFS/S3/GCS..) : S3
* Running on Docker? (yes/no) No
**Additional context**
Add any other context about the problem here.
- I also noticed that hudi is writing small ( 4 MB) files
Submit -
spark-submit --master yarn --deploy-mode cluster --num-executors 59 --executor-cores 5 --executor-memory 37G --driver-cores 5 --driver-memory 37G --conf spark.yarn.executor.memoryOverhead=4G --conf "spark.executor.extraJavaOptions = -XX:+UseG1GC -XX:+UnlockDiagnosticVMOptions -XX:+G1SummarizeConcMark -XX:InitiatingHeapOccupancyPercent=35 -verbose:gc -XX:+PrintGCDetails -XX:+PrintGCDateStamps -XX:OnOutOfMemoryError='kill -9 %p'" --conf "spark.driver.extraJavaOptions= -XX:+UseG1GC -XX:+UnlockDiagnosticVMOptions -XX:+G1SummarizeConcMark -XX:InitiatingHeapOccupancyPercent=35 -verbose:gc -XX:+PrintGCDetails -XX:+PrintGCDateStamps -XX:OnOutOfMemoryError='kill -9 %p'" --jars /usr/lib/spark/external/lib/spark-avro.jar,/usr/lib/hudi/hudi-spark-bundle.jar --class Main build.jar hudi.properties
DataFrameWriter<Row> writer = dsWithPartitionPath.write()
.format("org.apache.hudi")
.mode(SaveMode.Append)
.option(DataSourceWriteOptions.RECORDKEY_FIELD_OPT_KEY(), recordKey)
.option(DataSourceWriteOptions.PRECOMBINE_FIELD_OPT_KEY(), partitionKey)
.option(DataSourceWriteOptions.OPERATION_OPT_KEY(), operation)
.option(HoodieWriteConfig.TABLE_NAME, tableName)
.option(DataSourceWriteOptions.TABLE_TYPE_OPT_KEY(), tableType)
.option(DataSourceWriteOptions.HIVE_SYNC_ENABLED_OPT_KEY(), hiveSyncEnabled)
.option(DataSourceWriteOptions.KEYGENERATOR_CLASS_OPT_KEY(), keyGeneratorClass)
.option("hoodie.parquet.compression.codec", "snappy")
.option("hoodie.consistency.check.enabled", true)
.option("hoodie.compact.inline.max.delta.commits", 10)
.option("hoodie.compact.inline", true)
.option("hoodie.cleaner.commits.retained", 25)
.option("hoodie.keep.min.commits", 30)
.option("hoodie.index.type", "GLOBAL_BLOOM")
.option("hoodie.insert.shuffle.parallelism", 500)
.option("hoodie.upsert.shuffle.parallelism", 500);
.option("hoodie.bloom.index.update.partition.path", true)
.option(DataSourceWriteOptions.HIVE_DATABASE_OPT_KEY(), hiveDBName)
.option(DataSourceWriteOptions.HIVE_TABLE_OPT_KEY(), hiveTableName)
.option(DataSourceWriteOptions.HIVE_PARTITION_FIELDS_OPT_KEY(), hivePartitions)
.option(DataSourceWriteOptions.HIVE_PARTITION_EXTRACTOR_CLASS_OPT_KEY(), extractorClass)
.option(DataSourceWriteOptions.HIVE_URL_OPT_KEY(), hiveUrl);
writer.save(appConf.getString(Constants.HUDI_BASE_PATH_PROP));
Please suggest how I can tune this job to process updates efficiently.
Thank you
**Stacktrace**
```Add the stack trace of the error.```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-776190924


   @nsivabalan @bvaradar Thank you . for your support .. Sorry i forgot to update to this thread , we were achieved required Performance with @bvaradar  Suggestions. and we further  improved the Hudi Performance by redesigning our table Structure. With the new table structure we have to store very few records which is taking few min to update 15 mil records.

   Thank you for your support. you can close the ticket.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] vinothchandar commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-776311165


   great. if you have any stories to share for a blog or tuning guide, that would also help everyone!


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-724917083


   @bvaradar Thank you for your quick response.
   1) we are not using any ordering as my key is a composite key ( combination 4 attributes).
   -sure I will give a try with hoodie.bloom.index.prune.by.ranges=false
   2)Earlier we were seeing Duplicates as my records are stored across partitions( DAILY), so we switched to GLOBAL_BLOOM,i will give a  try with SIMPLE and BLOOM as well as GLOBAL_SIMPLE
   - Questions
   > How can I control the Hudi output file size?
   >is it gonna improve the performance if I use a single partition?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-729805782


   1) I don't see much improvement by enabling hoodie. clean.async=true
   2) Here is the hoodie partition :s3://mybucket/myapp/ouput/hudi-raw/default/
   3) list of files under .hoodie
                             PRE .aux/
                              PRE .temp/
   2020-11-10 22:33:34          0 .aux_$folder$
   2020-11-10 22:33:34          0 .temp_$folder$
   2020-11-10 22:45:43    4926823 20201110223331.deltacommit
   2020-11-10 22:42:25        984 20201110223331.deltacommit.inflight
   2020-11-10 22:35:24          0 20201110223331.deltacommit.requested
   2020-11-10 23:17:20    5274215 20201110230257.deltacommit
   2020-11-10 23:13:37    3916496 20201110230257.deltacommit.inflight
   2020-11-10 23:04:45          0 20201110230257.deltacommit.requested
   2020-11-10 23:22:47    5097604 20201110231726.commit
   2020-11-10 23:17:34          0 20201110231726.compaction.inflight
   2020-11-10 23:17:33    2218785 20201110231726.compaction.requested
   2020-11-11 00:10:21    1786853 20201110233218.clean
   2020-11-10 23:49:47    1659524 20201110233218.clean.inflight
   2020-11-10 23:49:46    1659524 20201110233218.clean.requested
   2020-11-10 23:46:54    5274215 20201110233218.deltacommit
   2020-11-10 23:43:12    3916496 20201110233218.deltacommit.inflight
   2020-11-10 23:33:50          0 20201110233218.deltacommit.requested
   2020-11-10 23:49:36    5097604 20201110234700.commit
   2020-11-10 23:47:10          0 20201110234700.compaction.inflight
   2020-11-10 23:47:10    2224673 20201110234700.compaction.requested
   2020-11-13 07:09:04    1798629 20201113063046.clean
   2020-11-13 06:49:04    1665412 20201113063046.clean.inflight
   2020-11-13 06:49:04    1665412 20201113063046.clean.requested
   2020-11-13 06:46:19    5274215 20201113063046.deltacommit
   2020-11-13 06:42:40    3916496 20201113063046.deltacommit.inflight
   2020-11-13 06:32:14          0 20201113063046.deltacommit.requested
   2020-11-13 06:48:56    5097604 20201113064625.commit
   2020-11-13 06:46:35          0 20201113064625.compaction.inflight
   2020-11-13 06:46:35    2224673 20201113064625.compaction.requested
   2020-11-13 07:44:42    1798629 20201113071234.clean
   2020-11-13 07:25:45    1665412 20201113071234.clean.inflight
   2020-11-13 07:25:45    1665412 20201113071234.clean.requested
   2020-11-13 07:23:04    5274215 20201113071234.deltacommit
   2020-11-13 07:19:55    3916496 20201113071234.deltacommit.inflight
   2020-11-13 07:14:16          0 20201113071234.deltacommit.requested
   2020-11-13 07:25:37    5097604 20201113072312.commit
   2020-11-13 07:23:22          0 20201113072312.compaction.inflight
   2020-11-13 07:23:21    2224673 20201113072312.compaction.requested
   2020-11-13 17:56:44    5274215 20201113174201.deltacommit
   2020-11-13 17:52:57    3916496 20201113174201.deltacommit.inflight
   2020-11-13 17:44:37          0 20201113174201.deltacommit.requested
   2020-11-13 17:59:22    5097604 20201113175651.commit
   2020-11-13 17:57:00          0 20201113175651.compaction.inflight
   2020-11-13 17:56:59    2224673 20201113175651.compaction.requested
   2020-11-13 18:35:38    1798629 20201113180714.clean
   2020-11-13 18:09:46    1665412 20201113180714.clean.inflight
   2020-11-13 18:09:45    1665412 20201113180714.clean.requested
   2020-11-13 18:21:58    5274215 20201113180714.deltacommit
   2020-11-13 18:17:48    3916496 20201113180714.deltacommit.inflight
   2020-11-13 18:08:42          0 20201113180714.deltacommit.requested
   2020-11-13 18:24:40    5097604 20201113182206.commit
   2020-11-13 18:22:18          0 20201113182206.compaction.inflight
   2020-11-13 18:22:17    2224673 20201113182206.compaction.requested
   2020-11-17 16:49:44    1798629 20201117162434.clean
   2020-11-17 16:26:53    1665412 20201117162434.clean.inflight
   2020-11-17 16:26:52    1665412 20201117162434.clean.requested
   2020-11-17 16:34:02    5274215 20201117162434.deltacommit
   2020-11-17 16:30:26    3916496 20201117162434.deltacommit.inflight
   2020-11-17 16:26:00          0 20201117162434.deltacommit.requested
   2020-11-17 16:36:41    5097604 20201117163409.commit
   2020-11-17 16:34:21          0 20201117163409.compaction.inflight
   2020-11-17 16:34:20    2224673 20201117163409.compaction.requested
   2020-11-10 22:33:34          0 archived_$folder$
   2020-11-10 22:33:36        325 hoodie.properties


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] bvaradar commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
bvaradar commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-728164009


   Yes, can you list all the files under hoodie folder and the partition


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-739681573


   @bvaradar Thank you for your response., I will run my tests and provide you more info-


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] bvaradar commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
bvaradar commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-730037189


   Just looking at the timestamps for last compaction, clean and delta commit operations,

   1. Compaction:
   2020-11-17 16:36:41 5097604 20201117163409.commit
   2020-11-17 16:34:21 0 20201117163409.compaction.inflight

   THis means that compaction took around 2.3 mins to finish

   Ingestion:
   2020-11-17 16:34:02 5274215 20201117162434.deltacommit
   2020-11-17 16:30:26 3916496 20201117162434.deltacommit.inflight
   2020-11-17 16:26:00 0 20201117162434.deltacommit.requested
   The data write part alone took like ~8 mins


   Cleaning:

   2020-11-17 16:49:44 1798629 20201117162434.clean
   2020-11-17 16:26:53 1665412 20201117162434.clean.inflight
   2020-11-17 16:26:52 1665412 20201117162434.clean.requested

   This seems to have taken like 25 mins. With a single partition, the listing performance should be similar for ingestion and cleaning. If cleaning was run asynchronously, you might need to give more executors to run parallel clean. I am also wondering if the deletes are getting throttled in your case which is slowing down clean. Can you take a look at executor logs to see if each file deletion is taking long time.  You can also try disabling cleaning "hoodie.clean.automatic=false" and enable it every N writes if the slowdown is not due to deletes throttling.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] bvaradar commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
bvaradar commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-724872433


   Does your record key has any natural ordering ? If not, you can disable "hoodie.bloom.index.prune.by.ranges=false".

   Also, you are using GLOBAL_BLOOM which is expected to scan all the partitions and will be more time consuming. Does your record move from one partition to another as part of updates ? If not, you should use BLOOM.

   Another point : Bloom Index is very effective when the number of records to be updated <<< the number of records in the table. With 0.6.0, You can try changing the index type "hoodie.index.type=SIMPLE"  (GLOBAL_SIMPLE for global) to Simple which would perform a join.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] bvaradar commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
bvaradar commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-726706132


   One optimization to do is to make cleaning run concurrently with ingestion using hoodie.clean.async=true

   Also, compaction can be made to run in parallel when you make your job run using Structured Streaming or DeltaStreamer : https://hudi.apache.org/blog/async-compaction-deployment-model/

   Regarding small files, can you list all the partitions and hoodie folder and attach ?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-786183675


   @vinothchandar Sure ,i will !!


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-726271983
@bvaradar
Thank you for your help-
I tried my job with 750 Mill records insert/upsert with SIMPLE index type, I see the initial load was completed in 13 min. but the subsequent jobs were taking long. the time increasing for every run.
Please see the below screenshots-
First Run -Took 13 min
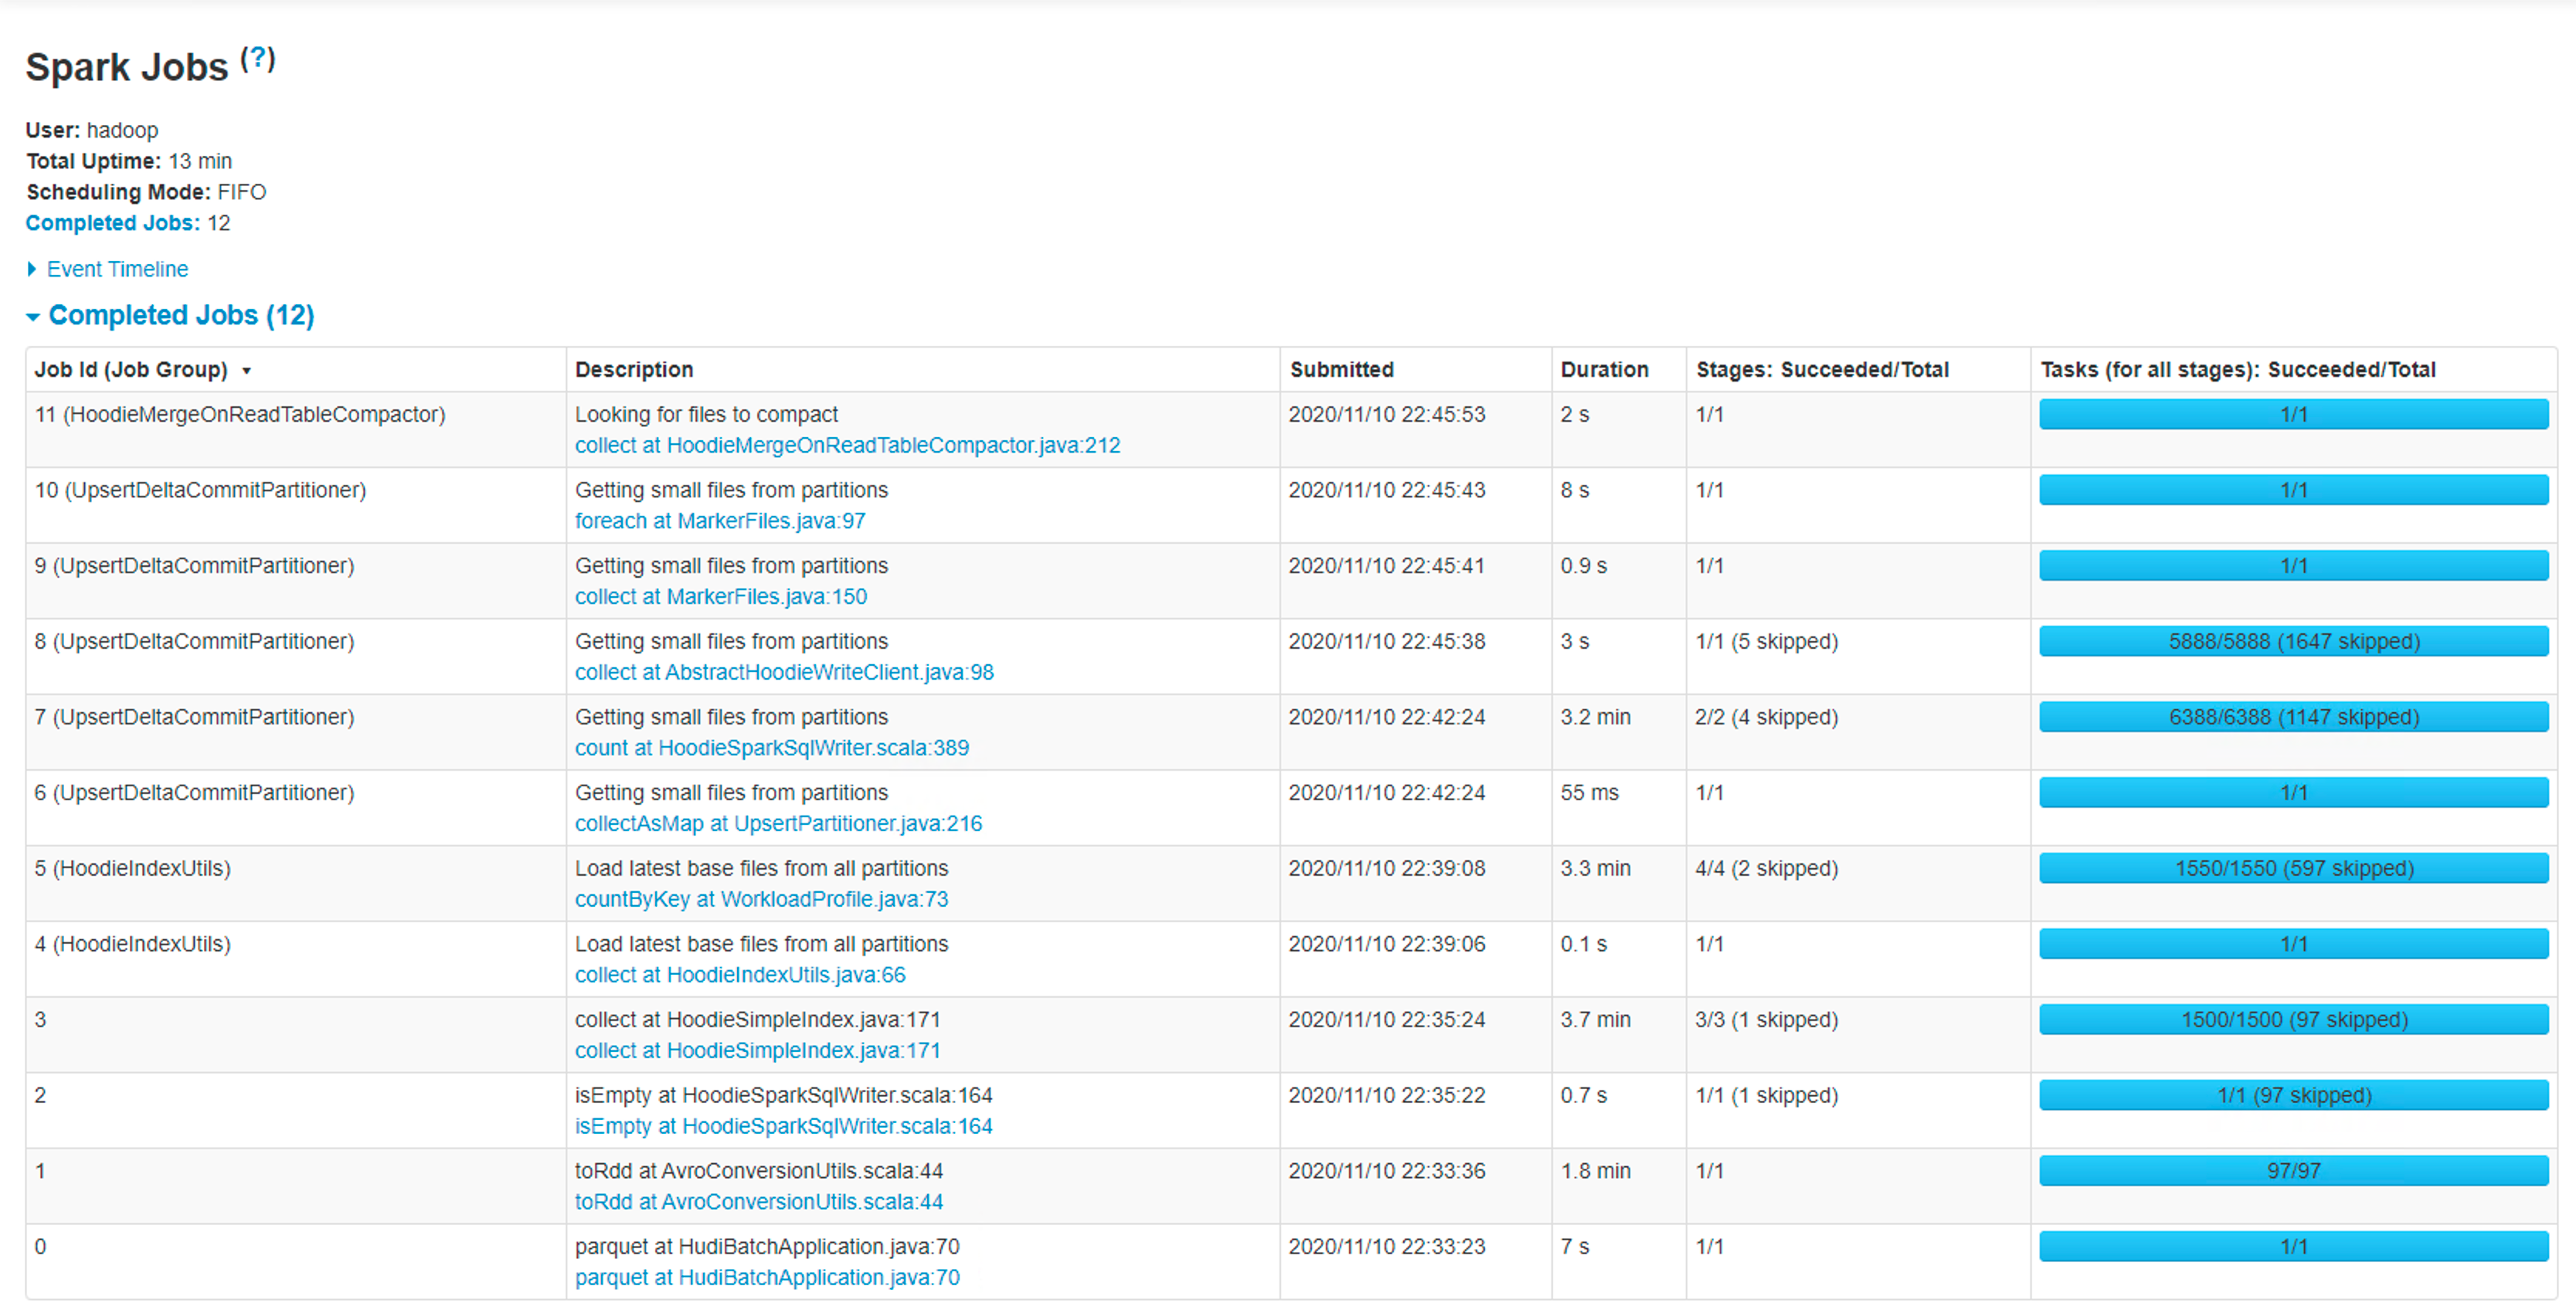
2ndRun Took 20 min
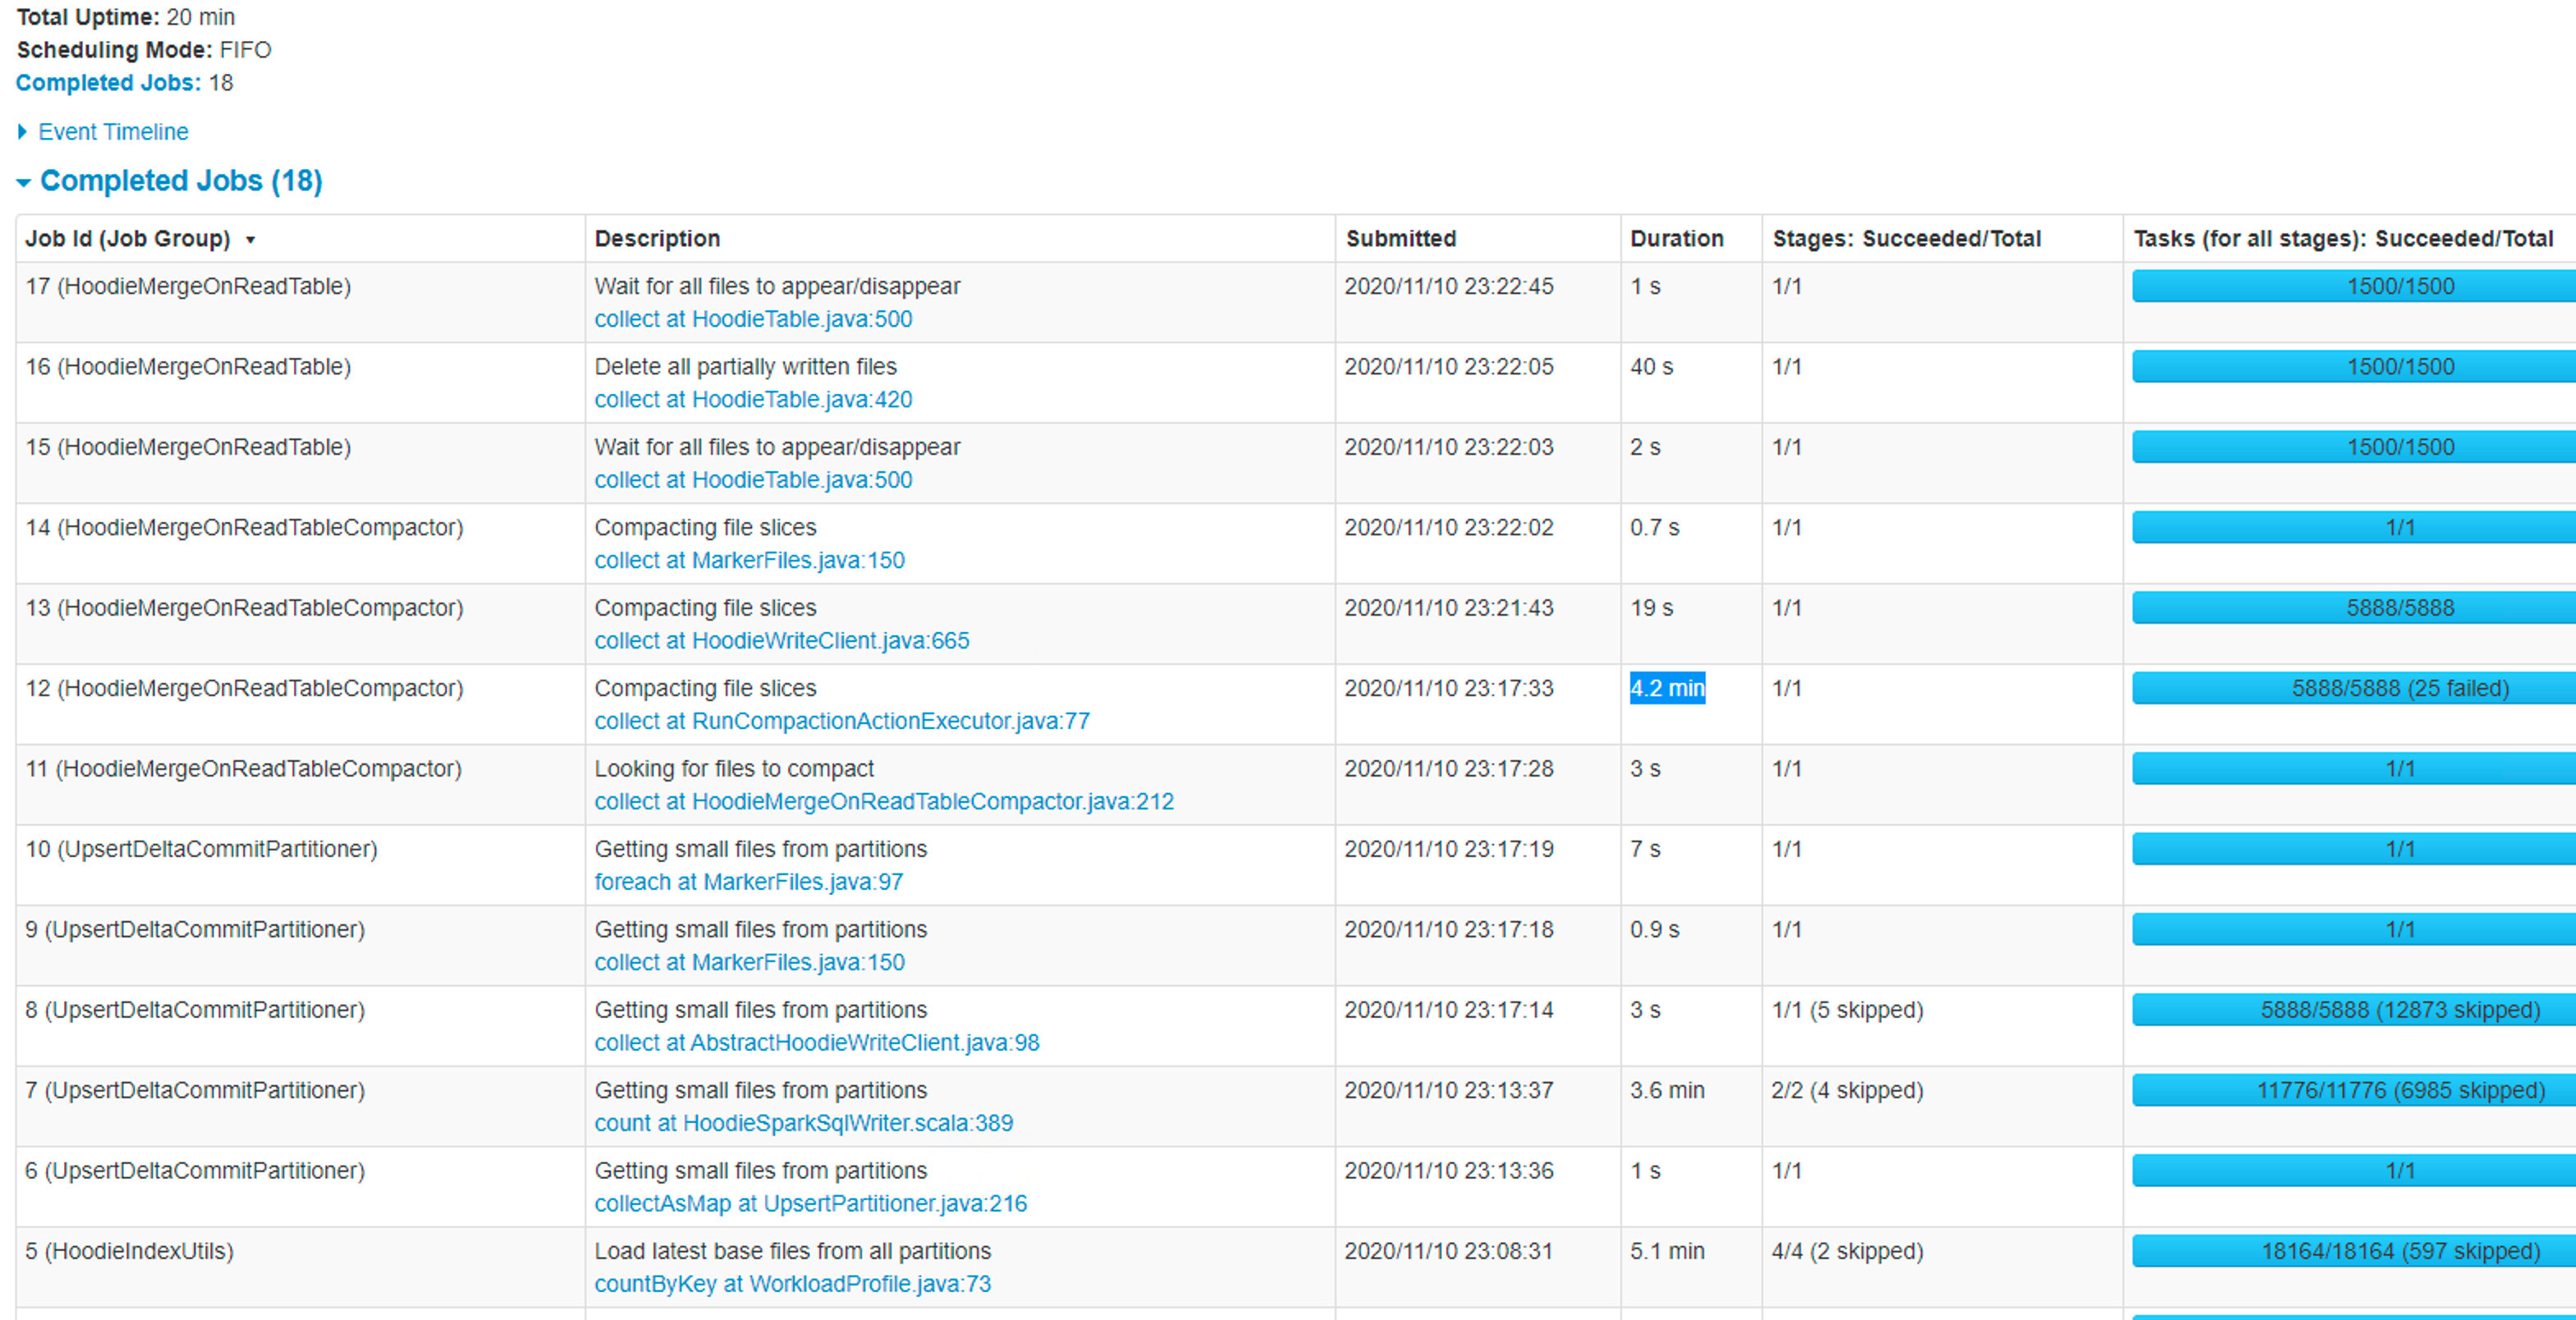
- In this case, it ran compaction due to that total time went up
3rd Run -39 min
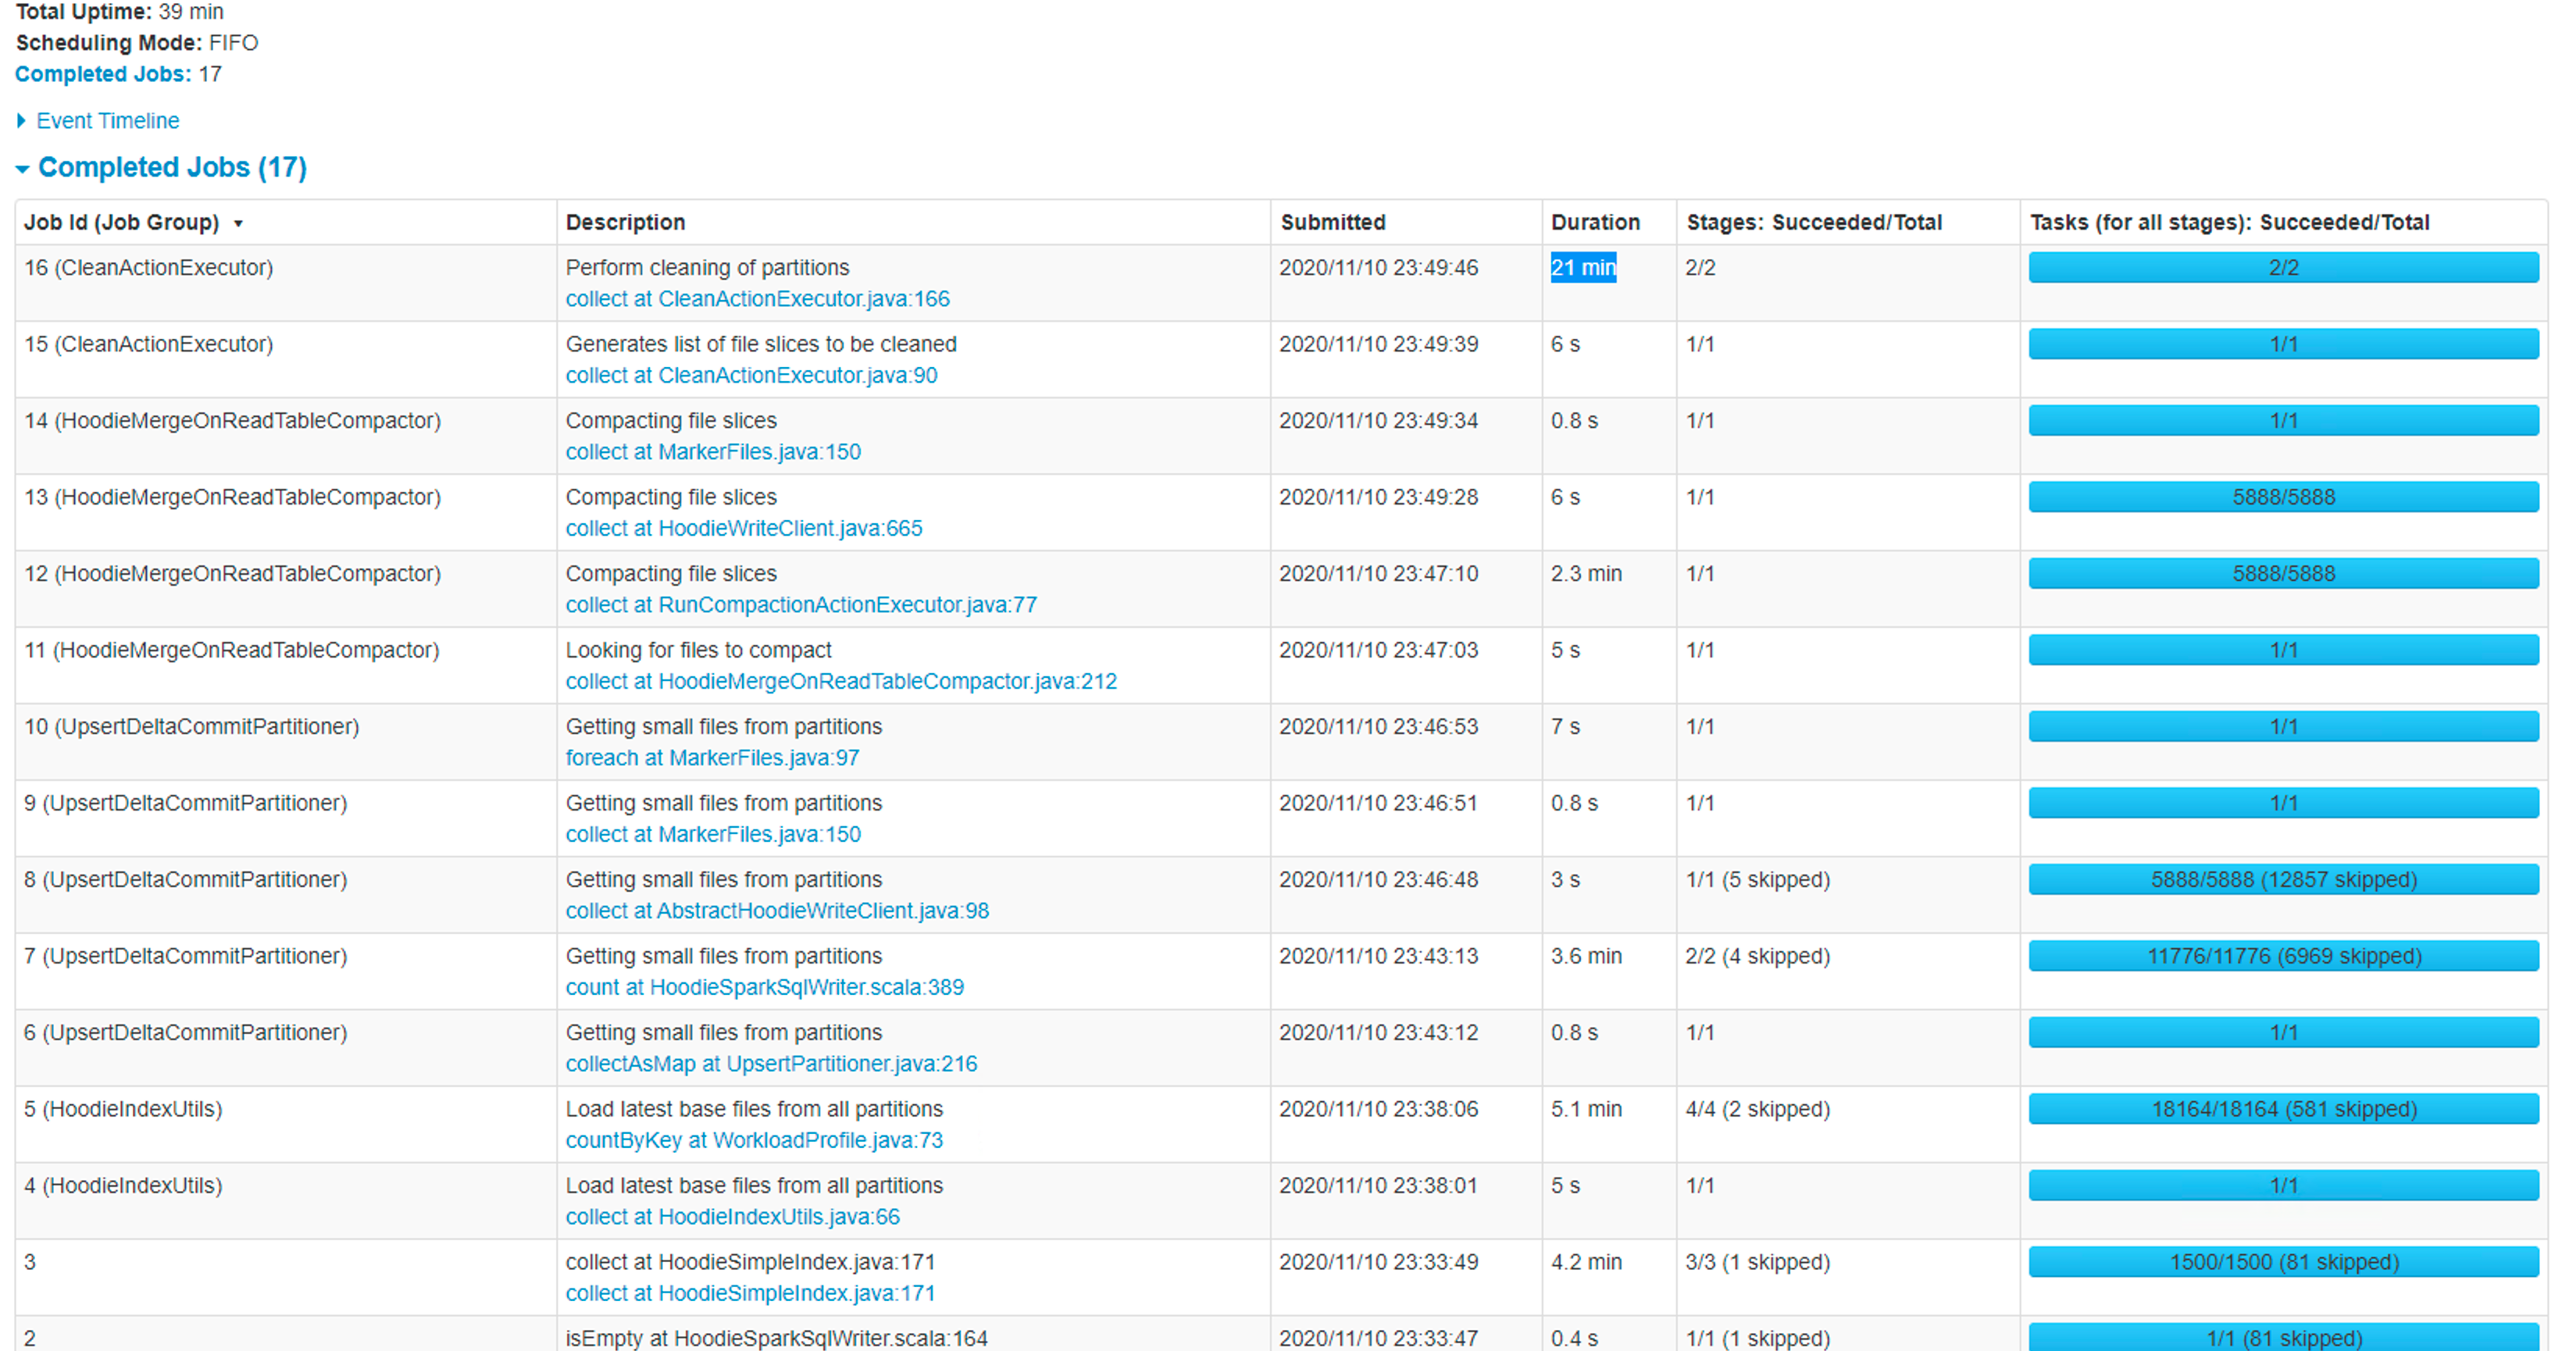
- In this case, Job triggered compaction and cleaning due to that, total time wentup..
but in any case, the job time was increasing over time. the good thing is the job is completing now.
how can I tune my job to get an optimal performance and predictable time?
- Coming to file size - I still see small files after setting the below attributes-
.option("hoodie.parquet.block.size",125829120)
.option("hoodie.parquet.small.file.limit",104857600)
.option("hoodie.parquet.max.file.size",125829120)
- I also see a lot of GC happening in my job-
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] bvaradar commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
bvaradar commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-725562535


   How can I control the Hudi output file size?
   https://cwiki.apache.org/confluence/display/HUDI/FAQ#FAQ-HowdoItoavoidcreatingtonsofsmallfiles

   is it gonna improve the performance if I use a single partition?
   Not necessarily, It depends on the amount of data in the table. Partitioning bounds the number of records in a directory and is helpful for certain queries as well.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella edited a comment on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella edited a comment on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-776190924


   @nsivabalan @bvaradar Thank you . for your support .. Sorry i forgot to update to this thread , we were able to achieve required Performance with @bvaradar  Suggestions.How ever cleanup an issue.So redesigned our table structure to store less rows which improved a lot in upsert performance.

   Thank you for your support. you can close the ticket.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-774519752


   @kpurella : with latest release from hudi (0.7.0) we have improved file listing with metadata table. You can try it out by setting these two configs:
   ```
   hoodie.metadata.enable=true
   hoodie.metadata.validate=true
   ```
   Also, if you can update the ticket with latest findings, would be great.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] kpurella commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
kpurella commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-726894877


   @bvaradar Thank you for your response
   1) hoodie.clean.async=true - sure let me try this.
   2) I will not able to enable parellel compaction as my job is a batch job.
   3) I have only one partition s3://mybucket/myapp/ouput/hudi-raw/default/
   4)regarding hoodie folder, do you need all files under .hoodie folder ?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] vinothchandar closed issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
vinothchandar closed issue #2240:
URL: https://github.com/apache/hudi/issues/2240


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] bvaradar commented on issue #2240: [SUPPORT] Performance Issue : HUDI MOR ,UPSERT Job running forever
Posted by GitBox <gi...@apache.org>.
bvaradar commented on issue #2240:
URL: https://github.com/apache/hudi/issues/2240#issuecomment-752990267


   @kpurella : Ay updates ?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org