You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@commons.apache.org by HiuKwok <gi...@git.apache.org> on 2018/08/08 12:13:42 UTC
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
GitHub user HiuKwok opened a pull request:

    https://github.com/apache/commons-lang/pull/340

    [LANG-1406]  StringIndexOutOfBoundsException in StringUtils.replaceIgnoreCase

    Fix for Lang-1406 to avoid any exception while performing String.UTils.replaceIgnoreCase() against uniCode String object.

    Plz let me if there have any extra things need to be done for this PR since I am the first timer for commons-lang project( add more test case?).

    All the best

You can merge this pull request into a Git repository by running:

    $ git pull https://github.com/HiuKwok/commons-lang master

Alternatively you can review and apply these changes as the patch at:

    https://github.com/apache/commons-lang/pull/340.patch

To close this pull request, make a commit to your master/trunk branch
with (at least) the following in the commit message:

    This closes #340

----
commit e0f6c7802b5e721019a602bf30b31c79dbf6d233
Author: Hiu Kwok <hi...@...>
Date:   2018-08-08T11:44:51Z

    toUpperCase() > toLowerCase() to avoid unicode string length miscalculation

commit 590f90889bf61a5570bd98b78e73410a07d7410b
Author: Hiu Kwok <hi...@...>
Date:   2018-08-08T11:46:29Z

    Assertion for example mentioned on LANG-1406 Description

----


---
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
Posted by HiuKwok <gi...@git.apache.org>.
Github user HiuKwok commented on a diff in the pull request:
https://github.com/apache/commons-lang/pull/340#discussion_r209574053
--- Diff: src/main/java/org/apache/commons/lang3/StringUtils.java ---
@@ -5596,8 +5596,8 @@ private static String replace(final String text, String searchString, final Stri
}
String searchText = text;
if (ignoreCase) {
- searchText = text.toLowerCase();
- searchString = searchString.toLowerCase();
+ searchText = text.toUpperCase();
+ searchString = searchString.toUpperCase();
--- End diff --
Hi @kinow, yes you are right after I did try to come up with a draft java main to generate all || most unicode in string and compare it's length between original, toLowerCase() and to UpperCase().
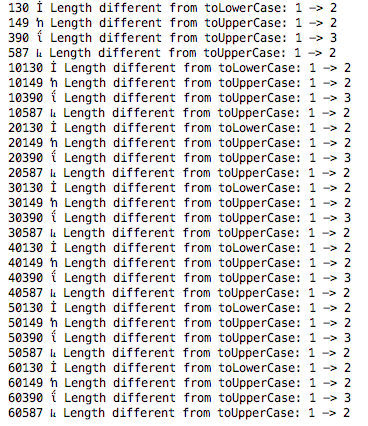
It's seem like no matter which one we pick (toLowerCase || toUpperCase), it would still tend to come up with a incorrect length.
Just a quick question what you mean by remove the ```length( )``` mean? Would you mind to specify more on that?
Thanks,
---
[GitHub] commons-lang issue #340: [LANG-1406] StringIndexOutOfBoundsException in Stri...
Posted by HiuKwok <gi...@git.apache.org>.
Github user HiuKwok commented on the issue:
https://github.com/apache/commons-lang/pull/340
To whom who interested in this issue, here is some founding that I discovered throughout this month of issue solving.
Problem:
- The exception would happened when any String object passed in with unicode character. In order to achieve ignore case replacement, the internal logic would first transform both `text` and `SearchString` to lowerCase( ) for comparaition.
- However if anyone passion enough to digger deeper into the src logic of `.toLowerCase( )`. Certain unicode character would be denormalized. In this way the result String length would tend to longer than original length(). Example like: 
So making use of the transformed String, Out bound exception would happen when trying to access the index that doesn't access at all (3 in this case vs 2 in length before lowerCase).
Flow:
- So the first thought into my mind is, why dun just normalize both `text` and `searchString` before performing ignore case comparation? In this way the String length would always stay consistence no matter `toLowerCase( )` or `toUpperCase( )` 3 -> 3. However the another problem would emerged, as you may noticed, while the String mentioned above denormalize, it would turn into a UpperCase I and a dot sign.
- But what happen if the search pattern emerge into searchText in decompose form. In this case let say I am trying to match a upper [I]. Then mismatch would happen and this is certain not the desire behavior of this method I believe.
BTW I Drafted a simple main method to demonstrate how mismatch would happen in here.
https://github.com/HiuKwok/commons-lang/blob/master/src/main/java/com/hiukwok/test.java#L10-L20
---
[GitHub] commons-lang issue #340: [LANG-1406] StringIndexOutOfBoundsException in Stri...
Posted by coveralls <gi...@git.apache.org>.
Github user coveralls commented on the issue:
https://github.com/apache/commons-lang/pull/340
[](https://coveralls.io/builds/18383289)
Coverage decreased (-0.04%) to 95.243% when pulling **590f90889bf61a5570bd98b78e73410a07d7410b on HiuKwok:master** into **a36c903d4f1065bc59f5e6d2bb0f9d92a5e71d83 on apache:master**.
---
[GitHub] commons-lang issue #340: [LANG-1406] StringIndexOutOfBoundsException in Stri...
Posted by kinow <gi...@git.apache.org>.
Github user kinow commented on the issue:

    https://github.com/apache/commons-lang/pull/340

    Good progress so far @HiuKwok . Understanding the problem well is a good first step to solve it 👍 my next development cycle for Apache will probably be for a release for Apache Commons Imaging, then after that Lang+Text. So will try to help here if you haven't found a way to solve it yet.


---
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
Posted by kinow <gi...@git.apache.org>.
Github user kinow commented on a diff in the pull request:

    https://github.com/apache/commons-lang/pull/340#discussion_r209907553

    --- Diff: src/main/java/org/apache/commons/lang3/StringUtils.java ---
    @@ -5596,8 +5596,8 @@ private static String replace(final String text, String searchString, final Stri
              }
              String searchText = text;
              if (ignoreCase) {
    -             searchText = text.toLowerCase();
    -             searchString = searchString.toLowerCase();
    +             searchText = text.toUpperCase();
    +             searchString = searchString.toUpperCase();
    --- End diff --

    Yeah, a very slippery problem. We still have the option to simply document that the method does not work well with unicode strings.

    But first I would like to spend at least a few hours with paper and pencil (and eraser, because this could take a bit till I give up or find a possible way around it), and perhaps even check in the mailing list if other devs have any idea.

    I think you found a very interesting problem (*)! Keep the ideas coming if you have any on how to solve this issue :+1:

    _* if I had more time, I would possibly either go through other methods checking for that or, just try some fuzzifier approach to test the whole project ! Not aware of any static or dynamic analysis tool that does that_


---
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
Posted by HiuKwok <gi...@git.apache.org>.
Github user HiuKwok commented on a diff in the pull request:

    https://github.com/apache/commons-lang/pull/340#discussion_r209659530

    --- Diff: src/main/java/org/apache/commons/lang3/StringUtils.java ---
    @@ -5596,8 +5596,8 @@ private static String replace(final String text, String searchString, final Stri
              }
              String searchText = text;
              if (ignoreCase) {
    -             searchText = text.toLowerCase();
    -             searchString = searchString.toLowerCase();
    +             searchText = text.toUpperCase();
    +             searchString = searchString.toUpperCase();
    --- End diff --

    @kinow May be try to store a original text.length before performance any upper || lower case operation and make use of it?

    haha, it's just a thought. Would try out later


---
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
Posted by HiuKwok <gi...@git.apache.org>.
Github user HiuKwok commented on a diff in the pull request:
https://github.com/apache/commons-lang/pull/340#discussion_r209878957
--- Diff: src/main/java/org/apache/commons/lang3/StringUtils.java ---
@@ -5596,8 +5596,8 @@ private static String replace(final String text, String searchString, final Stri
}
String searchText = text;
if (ignoreCase) {
- searchText = text.toLowerCase();
- searchString = searchString.toLowerCase();
+ searchText = text.toUpperCase();
+ searchString = searchString.toUpperCase();
--- End diff --
@kinow It turn out the problem is large than that, because the incorrect length basically affecting the whole method, especially the part which involve parsing inside the while loop.
https://github.com/apache/commons-lang/blob/590f90889bf61a5570bd98b78e73410a07d7410b/src/main/java/org/apache/commons/lang3/StringUtils.java#L5612-L5619
While string like following is entered, then Exception would be thrown on here instead.
https://github.com/apache/commons-lang/blob/590f90889bf61a5570bd98b78e73410a07d7410b/src/main/java/org/apache/commons/lang3/StringUtils.java#L5613

---
[GitHub] commons-lang issue #340: [LANG-1406] StringIndexOutOfBoundsException in Stri...
Posted by kinow <gi...@git.apache.org>.
Github user kinow commented on the issue:

    https://github.com/apache/commons-lang/pull/340

    Oh, that does make sense now. So the first visible character we see is the ["Latin Capital Letter I with Dot Above"](https://unicode-table.com/en/#0130) (see also [this other link](https://en.wikipedia.org/wiki/Dotted_and_dotless_I)), and the second an `x`. And doing `toUpperCase()` simply won't change it as it's considered already upper case.

    When doing a `toLowerCase`, it gets translated into two visible characters. The second is the normal `x`. While the first contains two codepoints. I tested in Python, and got the lower case `i` (`print(u"\u0069")`) followed by a character invisible by itself (`print (u"\u0307")`).

    The special/invisible character, is visible when coming after certain letters.

    ```python
    >>> print(u"\u0307")

    >>> print(u"\u0069\u0307")
    i̇
    >>> print(u"\u0068\u0307")
    ḣ
    >>> print(u"\u0067\u0307")
    ġ
    >>> print(u"\u0067\u0307")
    ```

    When we get these invisible characters, as we have one code point more, the length returned is not 2, but 3. Resulting in exception in this issue.

    I don't believe the fix here would fix the reverse case, where we had a lower case, single codepoint, unicode; that would be represented by a two code codepoint. The exception could happen again (I haven't investigated whether such case exist, but I'm assuming there could be such case - if not now, maybe a character could still be added in future editions).

    What do you think @HiuKwok ? Any suggestions? I'm not sure if there's any easy way to fix this case, except by adding a note to the documentation saying that the method is not intended to be used with unicode strings, as it doesn't handle supplementary characters well. Or maybe we could try to remove the `length()` call around the `StringBuilder`'s near the end of the method...


---
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
Posted by kinow <gi...@git.apache.org>.
Github user kinow commented on a diff in the pull request:

    https://github.com/apache/commons-lang/pull/340#discussion_r208851249

    --- Diff: src/main/java/org/apache/commons/lang3/StringUtils.java ---
    @@ -5596,8 +5596,8 @@ private static String replace(final String text, String searchString, final Stri
              }
              String searchText = text;
              if (ignoreCase) {
    -             searchText = text.toLowerCase();
    -             searchString = searchString.toLowerCase();
    +             searchText = text.toUpperCase();
    +             searchString = searchString.toUpperCase();
    --- End diff --

    Just leaving a comment here too to have a review here in GitHub. While your example works, as the character is considered already in upper case, the reverse case would still fail after changing from `toLowerCase` to `toUpperCase`. So I think we should find another solution or update the documentation stating how the code works with unicode.


---
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
Posted by HiuKwok <gi...@git.apache.org>.
Github user HiuKwok commented on a diff in the pull request:

    https://github.com/apache/commons-lang/pull/340#discussion_r214529178

    --- Diff: src/main/java/org/apache/commons/lang3/StringUtils.java ---
    @@ -5596,8 +5596,8 @@ private static String replace(final String text, String searchString, final Stri
              }
              String searchText = text;
              if (ignoreCase) {
    -             searchText = text.toLowerCase();
    -             searchString = searchString.toLowerCase();
    +             searchText = text.toUpperCase();
    +             searchString = searchString.toUpperCase();
    --- End diff --

    Hi all, Just a quick update finally I kind of figure the way out of this problem,
    while I am trying to make it happen (the implementation).
    But the concept is mainly Normalize incoming word at the beginning of the method call by ```Normalizer.normalize()```


---
[GitHub] commons-lang pull request #340: [LANG-1406] StringIndexOutOfBoundsException ...
Posted by kinow <gi...@git.apache.org>.
Github user kinow commented on a diff in the pull request:

    https://github.com/apache/commons-lang/pull/340#discussion_r209587514

    --- Diff: src/main/java/org/apache/commons/lang3/StringUtils.java ---
    @@ -5596,8 +5596,8 @@ private static String replace(final String text, String searchString, final Stri
              }
              String searchText = text;
              if (ignoreCase) {
    -             searchText = text.toLowerCase();
    -             searchString = searchString.toLowerCase();
    +             searchText = text.toUpperCase();
    +             searchString = searchString.toUpperCase();
    --- End diff --

    Oohh, great testing @HiuKwok ! Thanks for sharing here.

    >Just a quick question what you mean by remove the length( ) mean? Would you mind to specify more on that?

    Sure. I think there could be a possibility to fix the issue by addressing how the length of the lower'ed/upper'ed text is used https://github.com/apache/commons-lang/blob/590f90889bf61a5570bd98b78e73410a07d7410b/src/main/java/org/apache/commons/lang3/StringUtils.java#L5603

    So maybe there could be another way to work around the way we use the strings lengths, and avoid the exception.


---
[GitHub] commons-lang issue #340: [LANG-1406] StringIndexOutOfBoundsException in Stri...
Posted by kinow <gi...@git.apache.org>.
Github user kinow commented on the issue:

    https://github.com/apache/commons-lang/pull/340

    I'm surprised by this bug. Had no idea something like this could happen. Will debug later and see if I can understand why that happens (might have to train my brain to default to always use uppercase instead of lowercase?). Thanks for the pull request, we will review the code and if everything looks OK a committer will merge it.


---