You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@uniffle.apache.org by "advancedxy (via GitHub)" <gi...@apache.org> on 2023/02/21 02:51:08 UTC
[GitHub] [incubator-uniffle] advancedxy commented on pull request #603: [#291] feat: Support async read
advancedxy commented on PR #603:
URL: https://github.com/apache/incubator-uniffle/pull/603#issuecomment-1437786883
> > Do we need some performance tests?
>
> Benchmark Table1: 100g, dtypes: Array[(String, String)] = Array((v1,StringType), (k1,IntegerType)). And all columns of k1 have the same value (value = 10)
>
> Table2: 10 records, dtypes: Array[(String, String)] = Array((k2,IntegerType), (v2,StringType)). And it has the only one record of k2=10
>
> Environment: 100 executors(1core2g) SQL: spark.sql("select * from Table1,Table2 where k1 = k2").write.mode("overwrite").parquet("xxxxxx")
>
> Uniffle with patch: shuffle-read cost 55s 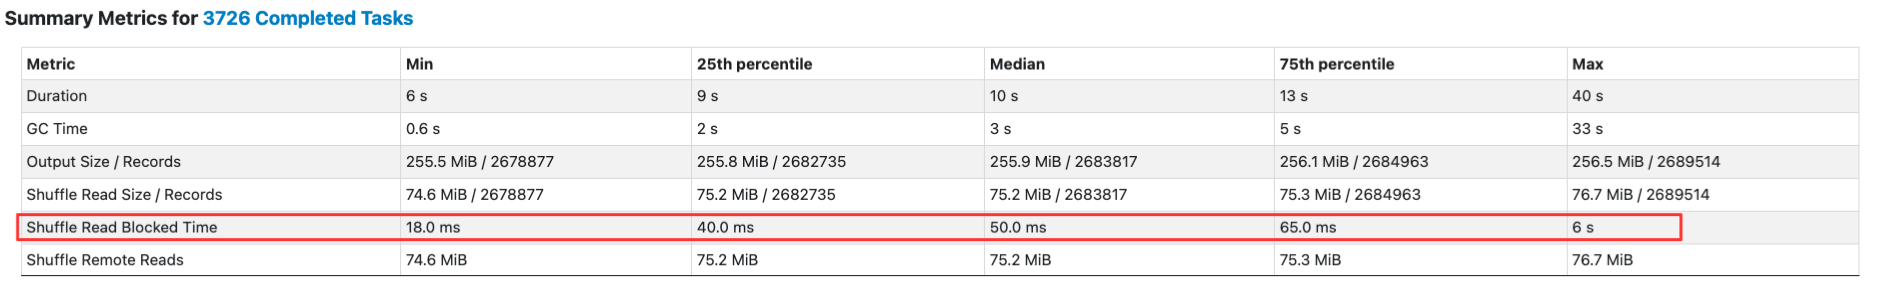
>
> Uniffle without patch: shuffle-read cost 1.1min 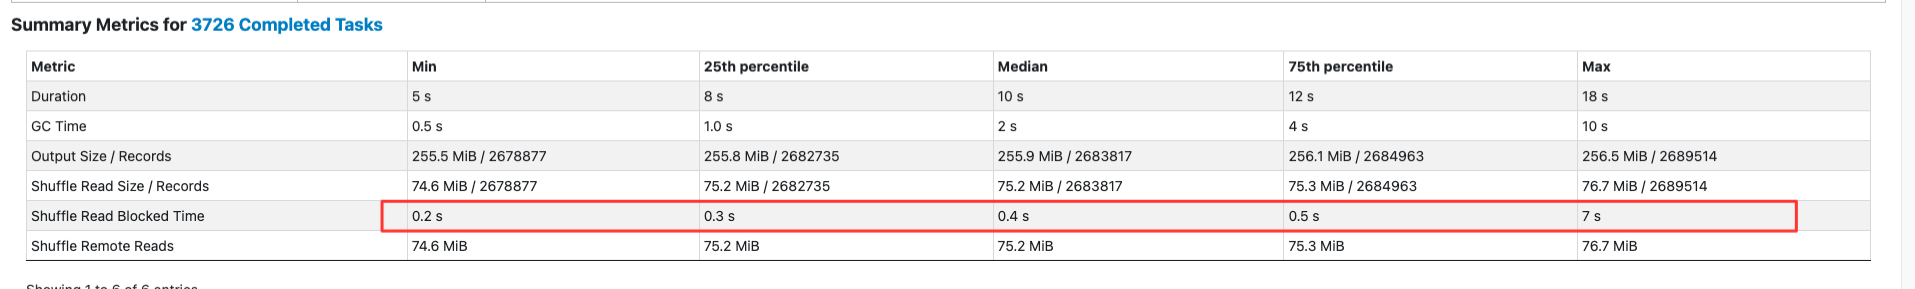
To be fair, the e2e comparison doesn't seem that promising: 55s vs 66s(1.1min). Do you have benchmark with larger dataset? or could we setup a micro benchmark to demonstrate the improvement?
> In current codebase, the sequence of reading is fetching and then handling. If we could read and fetch data async, the performance will be improved.
Yes, multiplexing IO threads is a key to performance.. However it's always hard to do concurrent fetch/processing correct.. We may have to add a lot of tests to ensure correctness.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: issues-unsubscribe@uniffle.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@uniffle.apache.org
For additional commands, e-mail: issues-help@uniffle.apache.org