You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2021/12/14 19:54:57 UTC
[GitHub] [hudi] JohnEngelhart opened a new issue #4311: Duplicate Records in Merge on Read [SUPPORT]
JohnEngelhart opened a new issue #4311:
URL: https://github.com/apache/hudi/issues/4311
**Describe the problem you faced**
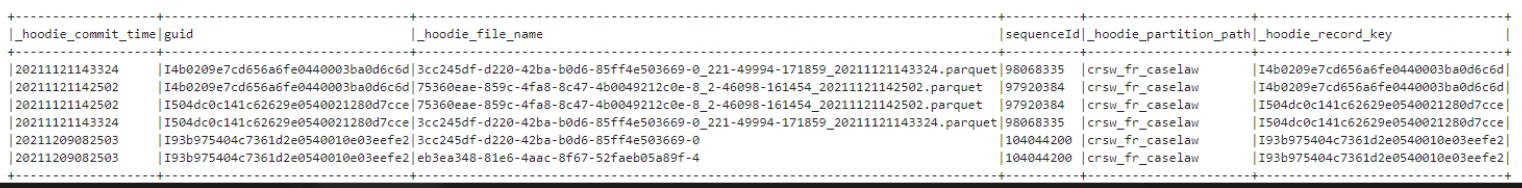
We are incrementally upserting data into our Hudi table/s every 5 minutes. As we begin to read this data we notice that duplicate records occur. The only command we execute is Upsert. We never call bulk insert/insert.
The duplicates appear to be happen in two respective areas.
1. In the same upsert command. (The hudi commit time in the table is the same)
2. In different upsert commands. (The hudi commit time is different)
The screenshot below shows both use cases above
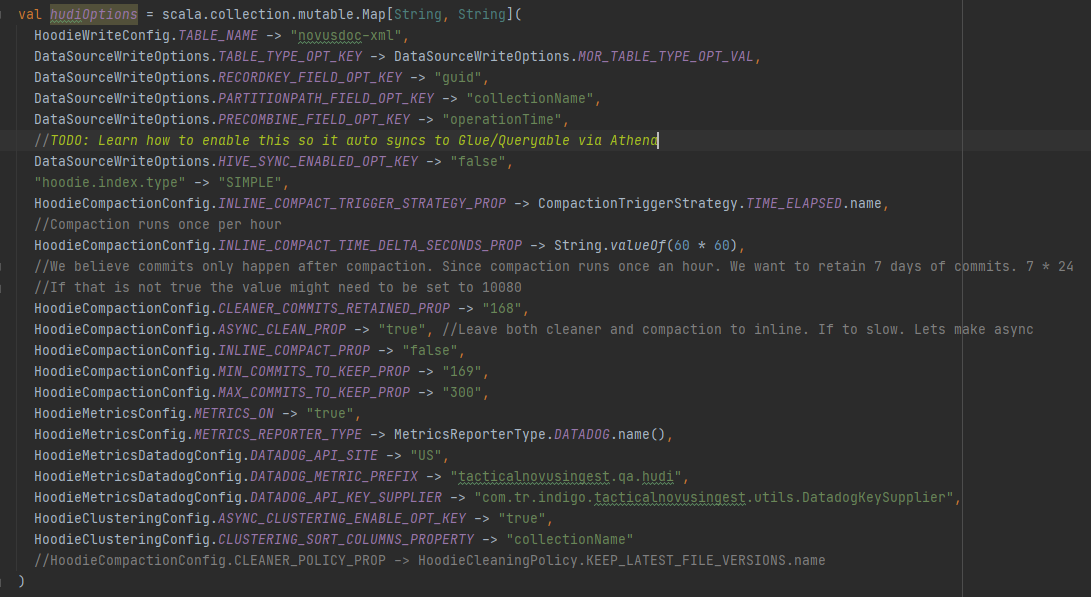
Options used during Upsert
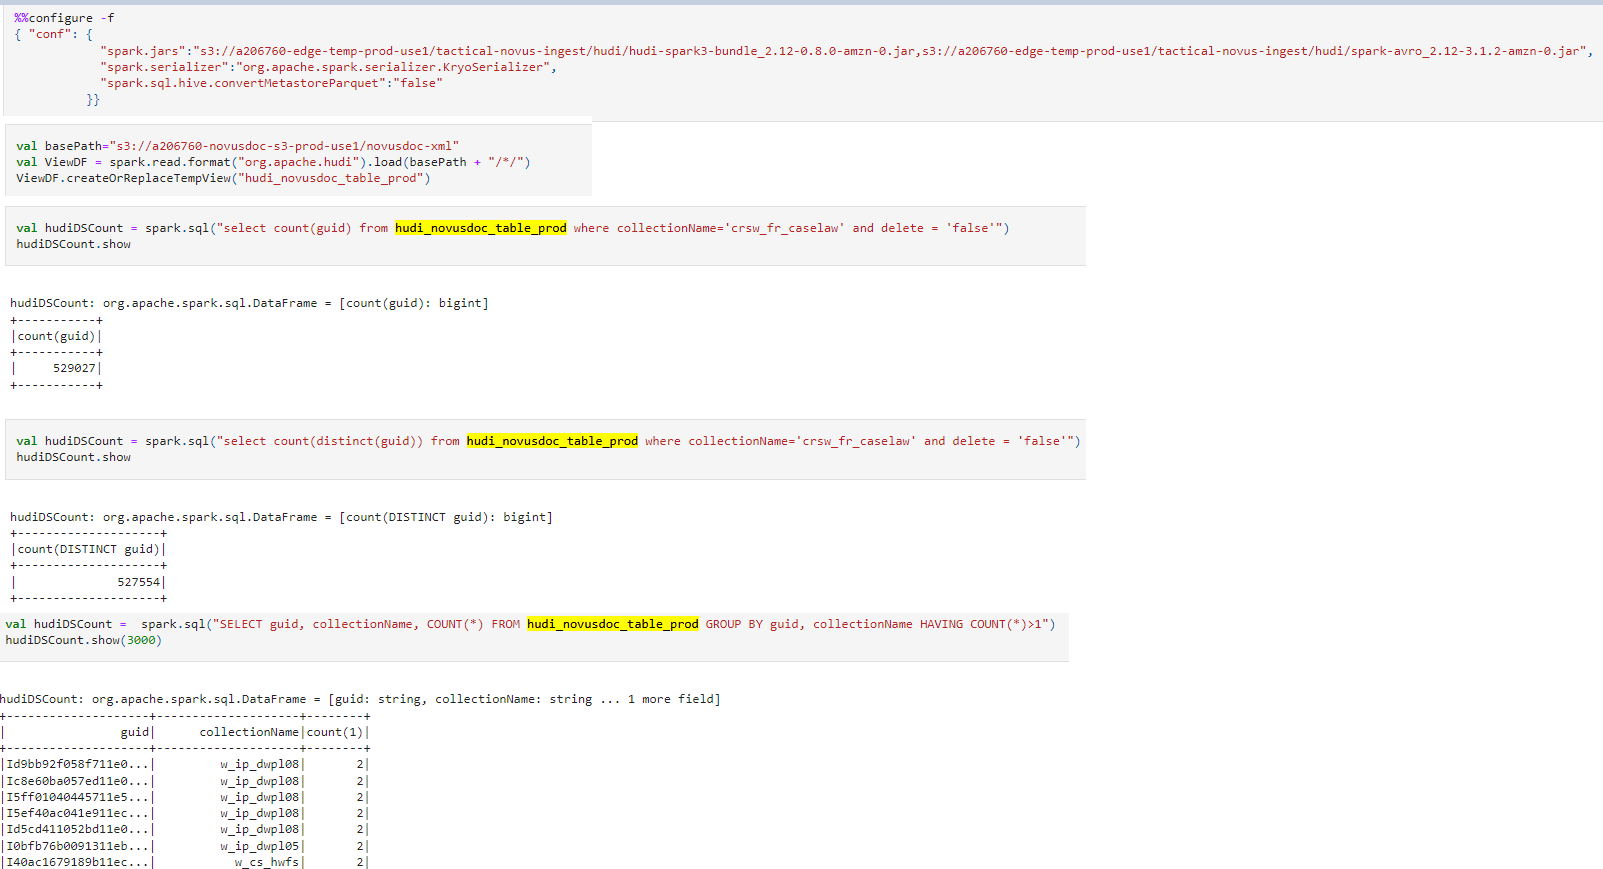
Command Executed During Read. I have tried other different ways to query. Regular Spark code and Spark Sql.
**Expected behavior**
When reading data I expect to not have duplicates in my dataframe.
**Environment Description**
* Hudi version : 0.8.0
* Spark version : 3.1.2-amzn-0
* Hive version : Hive not install on EMR Cluster. But if needed to be installed. Version would be 3.1.2 based on EMR 6.4
* Hadoop version : 3.2.1
* Storage (HDFS/S3/GCS..) : S3
* Running on Docker? (yes/no) : no
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan edited a comment on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan edited a comment on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-997054268


   hmmm, very strange. Was there any multi writer involved? also, I see you have clustering enabled. Can you post the contents of .hoodie. wanted to check the commits pertaining the commit times where duplicates are seen.

   seeing duplicates with same commit time and same file is very strange which I have not come across.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-997056284


   Can you confirm the operation is "upsert" right? bcoz, with "insert" there could be duplicates.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1039641351


   sorry to have dropped the ball on this. I will look into the issue and update it by this week.
   @scxwhite : I see you are also reporting an issue w/ clustering. Can you file a new issue may be just so we don't miss out.
   Can you update w/ all hoodie write configs you use (whether inline or async clustering) as well and which table type etc when you create the ticket. and thanks a lot for given steps to reproduce.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] scxwhite edited a comment on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
scxwhite edited a comment on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1015246379


   I reproduced this problem using the following code. In the following code, I repeatedly update 10000 pieces of data, but if I execute the following code more than 5 times, the program will report an error.
   The problem may occur in clustering. When merging small files, the old submitted files are obtained(SparkSizeBasedClusteringPlanStrategy#getFileSlicesEligibleForClustering).
   @xushiyan @nsivabalan @vinothchandar @yihua

   ```

   import org.apache.hudi.DataSourceWriteOptions;
   import org.apache.hudi.client.clustering.update.strategy.SparkRejectUpdateStrategy;
   import org.apache.hudi.common.config.HoodieMetadataConfig;
   import org.apache.hudi.common.model.*;
   import org.apache.hudi.common.table.HoodieTableConfig;
   import org.apache.hudi.common.table.marker.MarkerType;
   import org.apache.hudi.config.*;
   import org.apache.hudi.keygen.constant.KeyGeneratorOptions;
   import org.apache.spark.sql.*;

   import java.util.*;

   import static org.apache.hudi.common.model.HoodieTableType.*;

   /**
    * Created by sucx
    */
   public class Test {


       public static void main(String[] args) {
           List<String> data = new ArrayList<>();
           List<String> dtList = new ArrayList<>();
           dtList.add("197001");
           Random random = new Random();
           for (int i = 0; i < 100000; i++) {
               String dt = dtList.get(random.nextInt(dtList.size()));
               data.add("{\"dt\":\"" + dt + "\",\"id\":\"" + random.nextInt(10000) + "\",\"gmt_modified\":" + System.currentTimeMillis() + "}");
           }

           SparkSession sparkSession = SparkSession.builder().config("spark.serializer","org.apache.spark.serializer.KryoSerializer").master("local[*]").getOrCreate();

           Dataset<String> dataset = sparkSession.createDataset(data, Encoders.STRING());
           Dataset<Row> json = sparkSession.read().json(dataset);
           json.printSchema();
           int dataKeepTime = 5;
           json.selectExpr("dt", "id", "gmt_modified", "'' as name").toDF()
                   .write()
                   .format("org.apache.hudi")
                   .option(HoodieTableConfig.TYPE.key(), MERGE_ON_READ.name())
                   .option(DataSourceWriteOptions.OPERATION().key(), WriteOperationType.UPSERT.value())
                   .option(DataSourceWriteOptions.TABLE_TYPE().key(), MERGE_ON_READ.name())
                   .option(KeyGeneratorOptions.RECORDKEY_FIELD_NAME.key(), "id")
                   .option(KeyGeneratorOptions.PARTITIONPATH_FIELD_NAME.key(), "dt")
                   .option(KeyGeneratorOptions.HIVE_STYLE_PARTITIONING_ENABLE.key(), true)
                   .option(HoodieWriteConfig.PRECOMBINE_FIELD_NAME.key(), "gmt_modified")
                   .option(HoodieWriteConfig.COMBINE_BEFORE_UPSERT.key(), true)
                   .option(HoodieWriteConfig.UPSERT_PARALLELISM_VALUE.key(), 200)
                   .option(HoodieWriteConfig.FINALIZE_WRITE_PARALLELISM_VALUE.key(), 200)
                   .option(HoodieWriteConfig.WRITE_PAYLOAD_CLASS_NAME.key(), DefaultHoodieRecordPayload.class.getName())
                   .option(HoodieWriteConfig.AVRO_EXTERNAL_SCHEMA_TRANSFORMATION_ENABLE.key(), false)
                   .option(HoodieWriteConfig.MARKERS_TYPE.key(), MarkerType.DIRECT.toString())
                   .option(HoodieCompactionConfig.PAYLOAD_CLASS_NAME.key(), DefaultHoodieRecordPayload.class.getName())
                   .option(HoodieCompactionConfig.CLEANER_FILE_VERSIONS_RETAINED.key(), dataKeepTime)
                   .option(HoodieCompactionConfig.AUTO_CLEAN.key(), false)
                   .option(HoodieCompactionConfig.CLEANER_INCREMENTAL_MODE_ENABLE.key(), false)
                   .option(HoodieCompactionConfig.CLEANER_COMMITS_RETAINED.key(), dataKeepTime)
                   .option(HoodieCompactionConfig.MIN_COMMITS_TO_KEEP.key(), dataKeepTime + 1)
                   .option(HoodieCompactionConfig.MAX_COMMITS_TO_KEEP.key(), dataKeepTime + 2)
                   .option(HoodieCompactionConfig.TARGET_IO_PER_COMPACTION_IN_MB.key(), 500 * 1024)
                   .option(HoodieCompactionConfig.CLEANER_POLICY.key(), HoodieCleaningPolicy.KEEP_LATEST_FILE_VERSIONS.name())
                   .option(HoodieCompactionConfig.PARQUET_SMALL_FILE_LIMIT.key(), 128 * 1024 * 1024)
                   .option(HoodieCompactionConfig.FAILED_WRITES_CLEANER_POLICY.key(), HoodieFailedWritesCleaningPolicy.EAGER.name())
                   .option(HoodieStorageConfig.PARQUET_MAX_FILE_SIZE.key(), 256 * 1024 * 1024)
                   .option(HoodieCompactionConfig.INLINE_COMPACT.key(), true)
                   .option(HoodieCompactionConfig.INLINE_COMPACT_NUM_DELTA_COMMITS.key(), 1)
                   .option(HoodieClusteringConfig.INLINE_CLUSTERING.key(), true)
                   .option(HoodieClusteringConfig.INLINE_CLUSTERING_MAX_COMMITS.key(), 1)
                   .option(HoodieClusteringConfig.PLAN_STRATEGY_MAX_BYTES_PER_OUTPUT_FILEGROUP.key(), 256 * 1024 * 1024L)
                   .option(HoodieClusteringConfig.PLAN_STRATEGY_TARGET_FILE_MAX_BYTES.key(), 256 * 1024 * 1024L)
                   .option(HoodieClusteringConfig.PLAN_STRATEGY_SMALL_FILE_LIMIT.key(), 128 * 1024 * 1024L)
                   .option(HoodieClusteringConfig.UPDATES_STRATEGY.key(), SparkRejectUpdateStrategy.class.getName())
                   .option(HoodieMetadataConfig.ENABLE.key(), true)
                   .option(HoodieMetadataConfig.MIN_COMMITS_TO_KEEP.key(), dataKeepTime + 1)
                   .option(HoodieMetadataConfig.MAX_COMMITS_TO_KEEP.key(), dataKeepTime + 2)
                   .option(HoodieMetadataConfig.CLEANER_COMMITS_RETAINED.key(), dataKeepTime)
                   .option(HoodieClusteringConfig.PRESERVE_COMMIT_METADATA.key(), true)
                   .option(HoodiePayloadProps.PAYLOAD_ORDERING_FIELD_PROP_KEY, "gmt_modified")
                   .option(HoodiePayloadProps.PAYLOAD_EVENT_TIME_FIELD_PROP_KEY, "gmt_modified")
                   .option(HoodieIndexConfig.BLOOM_INDEX_KEYS_PER_BUCKET.key(), 100000)
                   .option(HoodieIndexConfig.BLOOM_INDEX_PARALLELISM.key(), 200)
                   .option(HoodieIndexConfig.BLOOM_INDEX_PRUNE_BY_RANGES.key(), true)
                   .option(HoodieTableConfig.NAME.key(), "sucx")
                   .mode(SaveMode.Append)
                   .save("/tmp/hudi/sucx_test");
           long hudi = sparkSession.read().format("hudi")
                   .load("/tmp/hudi/sucx_test")
                   .count();
           if (hudi > 10000) {
               throw new RuntimeException("count grater than 10000:" + hudi);
           }
           System.out.println("the count is:" + hudi);
       }

   }


   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-997054268


   hmmm, very strange. Was there any multi writer involved? also, I see you have clustering enabled. Can you post the contents of .hoodie. wanted to check the commits pertaining the commit times where duplicates are seen.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1073073951


   @SabyasachiDasTR : we do know of few bugs w/ metadata with older versions. We have fixed lot of bugs around it with 0.11. Do you think you can give it a try w/ 0.11 and let us know how it goes. we would definitely want to get to the bottom and fish out any issues arising from simple index and metadata table.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] Gatsby-Lee edited a comment on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
Gatsby-Lee edited a comment on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1051883576


   @scxwhite
   hi, have you tried with Hudi Metadata Table disabled?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan edited a comment on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan edited a comment on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1039641351


   hey folks: sorry to have dropped the ball on this. I will look into the issue and update it by this week.
   @scxwhite : I see you are also reporting an issue w/ clustering. Can you file a new issue may be just so we don't miss out.
   Can you update w/ all hoodie write configs you use (whether inline or async clustering) as well and which table type etc when you create the ticket. and thanks a lot for given steps to reproduce.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] sunilknataraj commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
sunilknataraj commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-999721245


   Yes, we are using upsert operation only. Code snippet is given below. hudiOptions is mentioned in the original issue description.
   `        dataframe.write.format("org.apache.hudi")
             .option("hoodie.insert.shuffle.parallelism", hudiParallelism)
             .option("hoodie.upsert.shuffle.parallelism", hudiParallelism)
             .option("hoodie.metadata.enable", value = true)
             .option(DataSourceWriteOptions.OPERATION_OPT_KEY, DataSourceWriteOptions.UPSERT_OPERATION_OPT_VAL)
             .options(hudiOptions).mode(SaveMode.Append)
             .save(s3Location)`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1002341204


   Not sure if Sunil and JohnEngelhart are talking about the same issue or you folks belong to two diff orgs/company. anyways, I see you have enabled metadata table. Can you disable metadata and verify if the duplicates go away. Also, the rollbacks you are talking about, is it in the data table or metadata table? Do you happened to know why there are so may rollbacks in your dataset. Can you post the timeline of your dataset please (contents of .hoodie).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] scxwhite commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
scxwhite commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1015018131
I encountered the same problem with 0.9.0. I used clustering and set hoodie.clustering.preserve.commit.metadata to true The same data was found.
I think there may be something wrong with clustering. Or when reading data

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] liujinhui1994 commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
liujinhui1994 commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1015349498


   Clustering does not currently support updates, this should be your problem. @scxwhite  cc@nsivabalan


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] scxwhite commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
scxwhite commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1015379301


   > Clustering does not currently support updates, this should be your problem. @scxwhite cc@nsivabalan

   To be clear, there is only one job to perform the upsert operation, so there is no problem of concurrent updates


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1039641351


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] sunilknataraj commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
sunilknataraj commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1002566382


   Myself and John belong to same company and talking about same issue. As I mentioned in my post, John already provided the hudiOptions in the original issue description and I was mentioning the upsert operation details.
   1. We will disable metadata and verify the same.
   2. We have seen multiple .rollback files under .hoodie folder hence it is data table related, not metadata table.
   3. Not sure why rollbacks are happening.
   3. Attaching all the rollback files and few clean, clean.inflight, clean.requested, deltacommit, deltacommit.inflight files FYR
   [.hoodie files.zip](https://github.com/apache/hudi/files/7788785/default.hoodie.files.zip)
   .


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] Gatsby-Lee commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
Gatsby-Lee commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1051883576


   @scxwhite
   hi, have you tried with Hudi Metadata Table disabled?
   In my case, I had the same issue when I enabled "Hudi Metadata Table"
   After I disabled it, the issue was resolved.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan edited a comment on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan edited a comment on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1039641351


   hey folks: sorry to have dropped the ball on this. I will look into the issue and update it by this week.
   @scxwhite : I see you are also reporting an issue w/ clustering. Can you file a new issue may be just so we don't miss out.
   Can you update w/ all hoodie write configs you use (whether inline or async clustering) as well and which table type etc when you create the ticket. and thanks a lot for given steps to reproduce.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1039644986


   @SabyasachiDasTR : thanks for the update.
   I can't think of a way to fix an existing table (i.e. to dedup). Unfortunately you may have to rebootstrap the entire table. sorry about that.
   @prashantwason : user claims that with hudi 0.9.0, using SIMPLE index and metadata enabled results in duplicate data. but if they use BLOOM index w/ metadata enabled, things are working fine. Do you happened to know of any intricacies w/ SIMPLE index w/ metadata table.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] SabyasachiDasTR commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
SabyasachiDasTR commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1019997016


   Hi @nsivabalan & @prashantwason ,

   Adding to the original issue reported by @JohnEngelhart  and @sunilknataraj
   I am from same organization and mentioning the same issue.

   Regarding the possible reasons for duplicates
   1. We are not using bulk_insert, but only upsert .[PFA Upsert query]
   2. No multi writer is involved.
   3. hoodiecombinebeforeupsert is default true.

   Below are the recent findings
   We could replicate the issue for a new dataset with below hoodie configurations, when upserting to a new table.[PFA]
   "hoodie.index.type" -> "SIMPLE",
   "hoodie.metadata.enable" -> "true",

   Below combination are not producing duplicates when upserting to a new table.
   Index	metadata
   SIMPLE	FALSE
   BLOOM	FALSE
   BLOOM	TRUE


   However when we are using same table which had duplicates originally and updating the Index & metadata configuration,
   these combinations are still causing duplicates with latest consumed data.
   Our data can be of small size and large size datasets and have a high incremental updates.
   As suggested we updated Index = BLOOM and metadata = false.
   Observed no duplicate for a new table and fresh dataset but duplicates are created on same table for which issue was reported.
   Compactions is working as expected with inline type but we are seeing a lot of log files generated in partition table along with the data parquet files.

   Deleting existing table and Re-ingesting the whole data may be an option to evaluate but is costly for us.
   Please suggest if any way possible to get rid of the existing duplicates and avoid ingesting duplicates for existing table data.

   [PFA]
   1. .hoodie files attached
   2. hudiOptions used.
   3. Upsert query.
   [hudiOptions.txt](https://github.com/apache/hudi/files/7925096/hudiOptions.txt)
   [upsertQuery.txt](https://github.com/apache/hudi/files/7925097/upsertQuery.txt)

   [hoodie_folder_SIMPLE_META_Enabled.zip](https://github.com/apache/hudi/files/7925088/hoodie_folder_SIMPLE_META_Enabled.zip)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] scxwhite commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
scxwhite commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1015248403


   In addition, my Hudi version is 0.9.0 and spark version is 3.0.0


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] sunilknataraj commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
sunilknataraj commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-999812284
.hoodie folder at table level contains thousands of .rollback, .clean and .inflight files.
Below given is the content of .hoodie_partition_metadata for one of the partition where we see duplicates and it contains so many files as shown in the image below,
_#partition metadata
_#Sun Nov 21 14:25:16 GMT 2021_
_commitTime=20211121142502_
_partitionDepth=1__

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1004101626


   thanks for the timeline.
   Here are our findings so far. unfortunately we don't have a root cause yet. but updating some findings for now.

   1. We see same data file being cleaned up by multiple clean instants. we need to understand how this could be possible. Only reason I can see this happening, if a new clean is scheduled even before previously clean is completed and hence the scheduling of new clean adds the same file to be cleaned up that previously scheduled clean will also be attempting to clean.
   2. We inspected the active timeline, yet to inspect the archive timeline. but from active timeline, could not decipher much except the repeated clean reported in (1). but that also does not answer why duplicates could occur.
   3. Do you happened to know why rollbacks are kicking in? It could happen only if there are partial write failures and the next writer will try to rollback the old failed write before starting the new write.

   Here are the reasons why duplicates could occur.
   1. If any of your writer used bulk_insert instead of upsert.
   2. Was there any multi writer involved at any point in time. Inserts from multiple concurrent writers could result in duplicates.
   3. https://hudi.apache.org/docs/configurations/#hoodiecombinebeforeupsert is set to false during "UPSERT" operation. Or "INSERT" was used which does not do de-dup by default. So, if incoming batch has duplicates, it could result in storage having duplicates as well. your 3rd use-case might fall into this likely. (where duplicates have same commit time, but diff file names)

   I see you are using SIMPLE index. Can you try using BLOOM index. Very unlikely index lookup has issues. just to rule that out.

   Just something to try out if feasible. Can you read this table and upsert to a new table and see how that pans out? Atleast after initial bootstrap, you should not see duplicates. but if you tee your incremental ingestion to both tables, does the new table result in duplicates?

   @prashantwason : Can you help us triage this issue please.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] scxwhite commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
scxwhite commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1015246379


   I reproduced this problem using the following code. In the following code, I repeatedly update 10000 pieces of data, but if I execute the following code more than 5 times, the program will report an error.
   The problem may occur in clustering. When merging small files, the old submitted files are obtained(SparkSizeBasedClusteringPlanStrategy#getFileSlicesEligibleForClustering).
   @xushiyan @nsivabalan @vinothchandar @yihua

   ```
    @Test
       public void write() {
           List<String> data = new ArrayList<>();
           List<String> dtList = new ArrayList<>();
           dtList.add("197001");
           Random random = new Random();
           for (int i = 0; i < 100000; i++) {
               String dt = dtList.get(random.nextInt(dtList.size()));
               data.add("{\"dt\":\"" + dt + "\",\"id\":\"" + random.nextInt(10000) + "\",\"gmt_modified\":" + System.currentTimeMillis() + "}");
           }

           Dataset<String> dataset = sparkSession.createDataset(data, Encoders.STRING());
           Dataset<Row> json = sparkSession.read().json(dataset);
           json.printSchema();
           int dataKeepTime = 5;
           json.selectExpr("dt", "id", "gmt_modified", "'' as name").toDF()
                   .write()
                   .format("org.apache.hudi")
                   .option(HoodieTableConfig.TYPE.key(), HoodieTableType.MERGE_ON_READ.name())
                   .option(DataSourceWriteOptions.OPERATION().key(), WriteOperationType.UPSERT.value())
                   .option(DataSourceWriteOptions.TABLE_TYPE().key(), HoodieTableType.MERGE_ON_READ.name())
                   .option(KeyGeneratorOptions.RECORDKEY_FIELD_NAME.key(), "id")
                   .option(KeyGeneratorOptions.PARTITIONPATH_FIELD_NAME.key(), Constants.DT)
                   .option(KeyGeneratorOptions.HIVE_STYLE_PARTITIONING_ENABLE.key(), true)
                   .option(HoodieWriteConfig.PRECOMBINE_FIELD_NAME.key(), Constants.UPDATE_TIME)
                   .option(HoodieWriteConfig.COMBINE_BEFORE_UPSERT.key(), true)
                   .option(HoodieWriteConfig.UPSERT_PARALLELISM_VALUE.key(), 200)
                   .option(HoodieWriteConfig.FINALIZE_WRITE_PARALLELISM_VALUE.key(), 200)
                   .option(HoodieWriteConfig.WRITE_PAYLOAD_CLASS_NAME.key(), DefaultHoodieRecordPayload.class.getName())
                   .option(HoodieWriteConfig.AVRO_EXTERNAL_SCHEMA_TRANSFORMATION_ENABLE.key(), false)
                   .option(HoodieWriteConfig.MARKERS_TYPE.key(), MarkerType.DIRECT.toString())
                   .option(HoodieCompactionConfig.PAYLOAD_CLASS_NAME.key(), DefaultHoodieRecordPayload.class.getName())
                   .option(HoodieCompactionConfig.CLEANER_FILE_VERSIONS_RETAINED.key(), dataKeepTime)
                   .option(HoodieCompactionConfig.AUTO_CLEAN.key(), false)
                   .option(HoodieCompactionConfig.CLEANER_INCREMENTAL_MODE_ENABLE.key(), false)
                   .option(HoodieCompactionConfig.CLEANER_COMMITS_RETAINED.key(), dataKeepTime)
                   .option(HoodieCompactionConfig.MIN_COMMITS_TO_KEEP.key(), dataKeepTime + 1)
                   .option(HoodieCompactionConfig.MAX_COMMITS_TO_KEEP.key(), dataKeepTime + 2)
                   .option(HoodieCompactionConfig.TARGET_IO_PER_COMPACTION_IN_MB.key(), 500 * 1024)
                   .option(HoodieCompactionConfig.CLEANER_POLICY.key(), HoodieCleaningPolicy.KEEP_LATEST_FILE_VERSIONS.name())
                   .option(HoodieCompactionConfig.PARQUET_SMALL_FILE_LIMIT.key(), 128 * 1024 * 1024)
                   .option(HoodieCompactionConfig.FAILED_WRITES_CLEANER_POLICY.key(), HoodieFailedWritesCleaningPolicy.EAGER.name())
                   .option(HoodieStorageConfig.PARQUET_MAX_FILE_SIZE.key(), 256 * 1024 * 1024)
                   .option(HoodieCompactionConfig.INLINE_COMPACT.key(), true)
                   .option(HoodieCompactionConfig.INLINE_COMPACT_NUM_DELTA_COMMITS.key(), 1)
                   .option(HoodieClusteringConfig.INLINE_CLUSTERING.key(), true)
                   .option(HoodieClusteringConfig.INLINE_CLUSTERING_MAX_COMMITS.key(), 1)
                   .option(HoodieClusteringConfig.PLAN_STRATEGY_MAX_BYTES_PER_OUTPUT_FILEGROUP.key(), 256 * 1024 * 1024L)
                   .option(HoodieClusteringConfig.PLAN_STRATEGY_TARGET_FILE_MAX_BYTES.key(), 256 * 1024 * 1024L)
                   .option(HoodieClusteringConfig.PLAN_STRATEGY_SMALL_FILE_LIMIT.key(), 128 * 1024 * 1024L)
                   .option(HoodieClusteringConfig.UPDATES_STRATEGY.key(), SparkRejectUpdateStrategy.class.getName())
                   .option(HoodieMetadataConfig.ENABLE.key(), true)
                   .option(HoodieMetadataConfig.MIN_COMMITS_TO_KEEP.key(), dataKeepTime + 1)
                   .option(HoodieMetadataConfig.MAX_COMMITS_TO_KEEP.key(), dataKeepTime + 2)
                   .option(HoodieMetadataConfig.CLEANER_COMMITS_RETAINED.key(), dataKeepTime)
                   .option(HoodieClusteringConfig.PRESERVE_COMMIT_METADATA.key(), true)
                   .option(HoodiePayloadProps.PAYLOAD_ORDERING_FIELD_PROP_KEY, Constants.UPDATE_TIME)
                   .option(HoodiePayloadProps.PAYLOAD_EVENT_TIME_FIELD_PROP_KEY, Constants.UPDATE_TIME)
                   .option(HoodieIndexConfig.BLOOM_INDEX_KEYS_PER_BUCKET.key(), 100000)
                   .option(HoodieIndexConfig.BLOOM_INDEX_PARALLELISM.key(), 200)
                   .option(HoodieIndexConfig.BLOOM_INDEX_PRUNE_BY_RANGES.key(), true)
                   .option(HoodieTableConfig.NAME.key(), "sucx")
                   .mode(SaveMode.Append)
                   .save("/tmp/hudi/sucx_test");
           long hudi = sparkSession.read().format("hudi")
                   .load("/tmp/hudi/sucx_test")
                   .count();
           if (hudi > 10000) {
               throw new RuntimeException("count grater than 10000:" + hudi);
           }
           System.out.println("the count is:" + hudi);
       }
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] prashantwason commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
prashantwason commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1042009960


   Am not aware of any such issue.

   The test case by @scxwhite  is interesting. I see that the min-commits-to-keep is set to 5 and the test case fails after 5 runs. There could be some hint from running the test case and. collecting logs. Let me see if I can get to it today.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] WTa-hash commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
WTa-hash commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-994128863


   I have a similar issue with MOR table type where I see duplicate records: https://github.com/apache/hudi/issues/2255, https://issues.apache.org/jira/browse/HUDI-1608


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] sunilknataraj commented on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
sunilknataraj commented on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-1003283781


   @nsivabalan  Attaching entire .hoodie contents (all the files under .hoodie, metadata, .aux and archived folders under .hoodie)
   [files.zip](https://github.com/apache/hudi/files/7795457/files.zip)
   [metadataAND.aux.zip](https://github.com/apache/hudi/files/7795459/metadataAND.aux.zip)
   [archived.zip](https://github.com/apache/hudi/files/7795460/archived.zip)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] sunilknataraj edited a comment on issue #4311: Duplicate Records in Merge on Read [SUPPORT]
Posted by GitBox <gi...@apache.org>.
sunilknataraj edited a comment on issue #4311:
URL: https://github.com/apache/hudi/issues/4311#issuecomment-999721245
Yes, we are using upsert operation only. Code snippet is given below. hudiOptions is mentioned in the original issue description.

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org