You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@airflow.apache.org by GitBox <gi...@apache.org> on 2021/06/14 07:26:54 UTC
[GitHub] [airflow] ephraimbuddy opened a new pull request #16401: Add 'queued' state to DagRun
ephraimbuddy opened a new pull request #16401:
URL: https://github.com/apache/airflow/pull/16401


   Closes: #9975, #16366,
   This change adds queued state to DagRun. Newly created DagRuns
   start in the queued state, are then moved to the running state after
   satisfying the DAG's max_active_runs. If the Dag doesn't have
   max_active_runs, the DagRuns are moved to running state immediately

   Clearing a DagRun sets the state to queued state


   ---
   **^ Add meaningful description above**

   Read the **[Pull Request Guidelines](https://github.com/apache/airflow/blob/main/CONTRIBUTING.rst#pull-request-guidelines)** for more information.
   In case of fundamental code change, Airflow Improvement Proposal ([AIP](https://cwiki.apache.org/confluence/display/AIRFLOW/Airflow+Improvements+Proposals)) is needed.
   In case of a new dependency, check compliance with the [ASF 3rd Party License Policy](https://www.apache.org/legal/resolved.html#category-x).
   In case of backwards incompatible changes please leave a note in [UPDATING.md](https://github.com/apache/airflow/blob/main/UPDATING.md).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659622069


##########
File path: tests/jobs/test_scheduler_job.py
##########
@@ -3457,37 +3445,43 @@ def test_do_schedule_max_active_runs_dag_timed_out(self):
         dagbag.bag_dag(dag=dag, root_dag=dag)
         dagbag.sync_to_db(session=session)

+        dag = SerializedDAG.from_dict(SerializedDAG.to_dict(dag))
+
         run1 = dag.create_dagrun(
             run_type=DagRunType.SCHEDULED,
             execution_date=DEFAULT_DATE,
-            state=State.RUNNING,
+            state=State.QUEUED,
             session=session,
         )
+        self.scheduler_job = SchedulerJob(subdir=os.devnull)
+        self.scheduler_job.executor = MockExecutor()
+        self.scheduler_job.processor_agent = mock.MagicMock(spec=DagFileProcessorAgent)
+
+        self.scheduler_job._do_scheduling(session)
+
         run1_ti = run1.get_task_instance(task1.task_id, session)
         run1_ti.state = State.RUNNING

-        sleep(1)
-
         run2 = dag.create_dagrun(
             run_type=DagRunType.SCHEDULED,
             execution_date=DEFAULT_DATE + timedelta(seconds=10),
-            state=State.RUNNING,
+            state=State.QUEUED,
             session=session,
         )

         dag.sync_to_db(session=session)
-
-        self.scheduler_job = SchedulerJob(subdir=os.devnull)
-        self.scheduler_job.executor = MockExecutor()
-        self.scheduler_job.processor_agent = mock.MagicMock(spec=DagFileProcessorAgent)
-
-        _ = self.scheduler_job._do_scheduling(session)
-
+        sleep(2)  # Should add this so it's timed out

Review comment:
       Rather than sleeping in the test, could set set "state=running, start_date = 2 seconds ago"?

   I.e. I want tests to be quick, and 2 second sleep isn't the end of the world, but if we can avoid that entirely then lets go for it. Every second counts almost.

   The other option would be to look at the time stepping feature of freezegun.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r662346425


##########
File path: airflow/migrations/versions/97cdd93827b8_add_queued_at_column_to_dagrun_table.py
##########
@@ -0,0 +1,44 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements.  See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership.  The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License.  You may obtain a copy of the License at
+#
+#   http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied.  See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""Add queued_at column to dagrun table
+
+Revision ID: 97cdd93827b8
+Revises: 30867afad44a
+Create Date: 2021-06-29 21:53:48.059438
+
+"""
+
+import sqlalchemy as sa
+from alembic import op
+
+# revision identifiers, used by Alembic.
+revision = '97cdd93827b8'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+    """Apply Add queued_at column to dagrun table"""
+    op.add_column('dag_run', sa.Column('queued_at', sa.DateTime(), nullable=True))

Review comment:
       Oh, we need to have this be different for mssql :(

   Check out `airflow/migrations/versions/74effc47d867_change_datetime_to_datetime2_6_on_mssql_.py`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651655645


##########
File path: airflow/www/views.py
##########
@@ -3889,7 +3889,7 @@ def duration_f(self):
         lazy_gettext('Clear'),
         lazy_gettext(
             'Are you sure you want to clear the state of the selected task'
-            ' instance(s) and set their dagruns to the running state?'
+            ' instance(s) and set their dagruns to the NONE state?'

Review comment:
       Mistake, I will correct that


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil edited a comment on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil edited a comment on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-866371716


   Merge conflicts :(

   Can you also squash those commits


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659610472


##########
File path: tests/api_connexion/endpoints/test_dag_run_endpoint.py
##########
@@ -928,7 +930,7 @@ def test_should_respond_200(self, name, request_json):
             "execution_date": response.json["execution_date"],
             "external_trigger": True,
             "start_date": response.json["start_date"],

Review comment:
       ```suggestion
               "start_date": None,
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651731166


##########
File path: tests/api_connexion/endpoints/test_dag_run_endpoint.py
##########
@@ -532,7 +535,7 @@ class TestGetDagRunsEndDateFilters(TestDagRunEndpoint):
             (
                 f"api/v1/dags/TEST_DAG_ID/dagRuns?end_date_lte="
                 f"{(timezone.utcnow() + timedelta(days=1)).isoformat()}",
-                ["TEST_DAG_RUN_ID_1"],
+                ["TEST_DAG_RUN_ID_1", "TEST_DAG_RUN_ID_2"],

Review comment:
       I have decided to just change from 'running' to 'queued' than adding this. Done


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660080113


##########
File path: tests/models/test_cleartasks.py
##########
@@ -68,6 +70,41 @@ def test_clear_task_instances(self):
         assert ti1.try_number == 2
         assert ti1.max_tries == 3

+    @parameterized.expand([(State.QUEUED, None), (State.RUNNING, DEFAULT_DATE)])
+    def test_clear_task_instances_dr_state(self, state, last_scheduling):
+        """Test that DR state is set to None after clear.
+        And that DR.last_scheduling_decision is handled OK.
+        start

Review comment:
       ```suggestion
           start_date is also set to None
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] uranusjr commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
uranusjr commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r650310229


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -823,8 +822,7 @@ def _change_state_for_tis_without_dagrun(
             .filter(models.TaskInstance.state.in_(old_states))
             .filter(
                 or_(
-                    # pylint: disable=comparison-with-callable
-                    models.DagRun.state != State.RUNNING,
+                    models.DagRun.state not in [State.RUNNING, State.QUEUED],

Review comment:
       ```suggestion
                       models.DagRun.state.notin_([State.RUNNING, State.QUEUED]),
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651682360


##########
File path: docs/apache-airflow/migrations-ref.rst
##########
@@ -23,7 +23,9 @@ Here's the list of all the Database Migrations that are executed via when you ru
 +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
 | Revision ID                    | Revises ID       | Airflow Version | Description                                                                           |
 +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
-| ``e9304a3141f0`` (head)        | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |
+| ``a84a5abfca95`` (head)        | ``e9304a3141f0`` |                 | Set default start_time for dagrun to null and set default state to QUEUED             |
++--------------------------------|------------------|-----------------|---------------------------------------------------------------------------------------|
+| ``e9304a3141f0``               | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |

Review comment:
       ```suggestion
   | ``a84a5abfca95`` (head)        | ``e9304a3141f0`` |                 | Set default ``start_time`` for dagrun to null and set default state to ``QUEUED``     |
   +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
   | ``e9304a3141f0``               | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659623303


##########
File path: tests/models/test_dagrun.py
##########
@@ -692,9 +698,10 @@ def test_wait_for_downstream(self, prev_ti_state, is_ti_success):
         ti.run()
         assert (ti.state == State.SUCCESS) == is_ti_success

-    def test_next_dagruns_to_examine_only_unpaused(self):
+    def test_next_running_dagruns_to_examine_only_unpaused(self):

Review comment:
       This might be a case to use parameterized.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659618668


##########
File path: tests/jobs/test_scheduler_job.py
##########
@@ -3174,8 +3174,50 @@ def test_create_dag_runs(self, stats_timing):
         with create_session() as session:
             self.scheduler_job._create_dag_runs([dag_model], session)

+        dr = session.query(DagRun).filter(DagRun.dag_id == dag.dag_id).first()
+        # Assert dr state is queued
+        assert dr.state == State.QUEUED

Review comment:
       ```suggestion
           assert dr.state == State.QUEUED
           assert dr.start_date is None
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659700001


##########
File path: tests/dag_processing/test_processor.py
##########
@@ -560,11 +560,10 @@ def test_scheduler_job_add_new_task(self):

     def test_runs_respected_after_clear(self):

Review comment:
       I Will do a PR after this one 👍


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660149354
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
# are not updated.
# We opted to check DagRun existence instead
# of catching an Integrity error and rolling back the session i.e
- # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+ # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
# create a new one. This is so that in the next Scheduling loop we try to create new runs
# instead of falling in a loop of Integrity Error.
- if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
- run = dag.create_dagrun(
+ if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+ dag.create_dagrun(
run_type=DagRunType.SCHEDULED,
execution_date=dag_model.next_dagrun,
- start_date=timezone.utcnow(),
- state=State.RUNNING,
+ state=State.QUEUED,
external_trigger=False,
session=session,
dag_hash=dag_hash,
creating_job_id=self.id,
)
-
- expected_start_date = dag.following_schedule(run.execution_date)
- if expected_start_date:
- schedule_delay = run.start_date - expected_start_date
- Stats.timing(
- f'dagrun.schedule_delay.{dag.dag_id}',
- schedule_delay,
- )
-
- self._update_dag_next_dagruns(dag_models, session)
+ dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+ dag_model.next_dagrun
+ )
# TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
# memory for larger dags? or expunge_all()
- def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+ def _start_queued_dagruns(
+ self,
+ session: Session,
+ ) -> int:
"""
- Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+ Find DagRuns in queued state and decide moving them to running state
- We batch the select queries to get info about all the dags at once
+ :param dag_run: The DagRun to schedule
"""
- # Check max_active_runs, to see if we are _now_ at the limit for any of
- # these dag? (we've just created a DagRun for them after all)
- active_runs_of_dags = dict(
+ dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+ active_runs_of_dags = defaultdict(
+ lambda: 0,
session.query(DagRun.dag_id, func.count('*'))
- .filter(
- DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+ .filter( # We use `list` here because SQLA doesn't accept a set
+ DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),
Review comment:
```suggestion
DagRun.dag_id.in_(list(dr.dag_id for dr in dag_runs)),
```
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
+ )
+
+
+def downgrade():
+ """Unapply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=None,
+ server_default=timezone.utcnow(),
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.QUEUED,
+ server_default=State.RUNNING,
Review comment:
same here
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
Review comment:
```suggestion
```
We don't want to set `server_defaults` instead we set Python-side defaults
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
+ )
+
+
+def downgrade():
+ """Unapply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=None,
+ server_default=timezone.utcnow(),
Review comment:
same here
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -215,7 +214,7 @@ def _change_state_for_tis_without_dagrun(
.filter(models.TaskInstance.state.in_(old_states))
.filter(
or_(
- models.DagRun.state != State.RUNNING,
+ models.DagRun.state.notin_([State.RUNNING, State.QUEUED]),
Review comment:
L200 needs updating to say "not in the running or queued state"
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
Review comment:
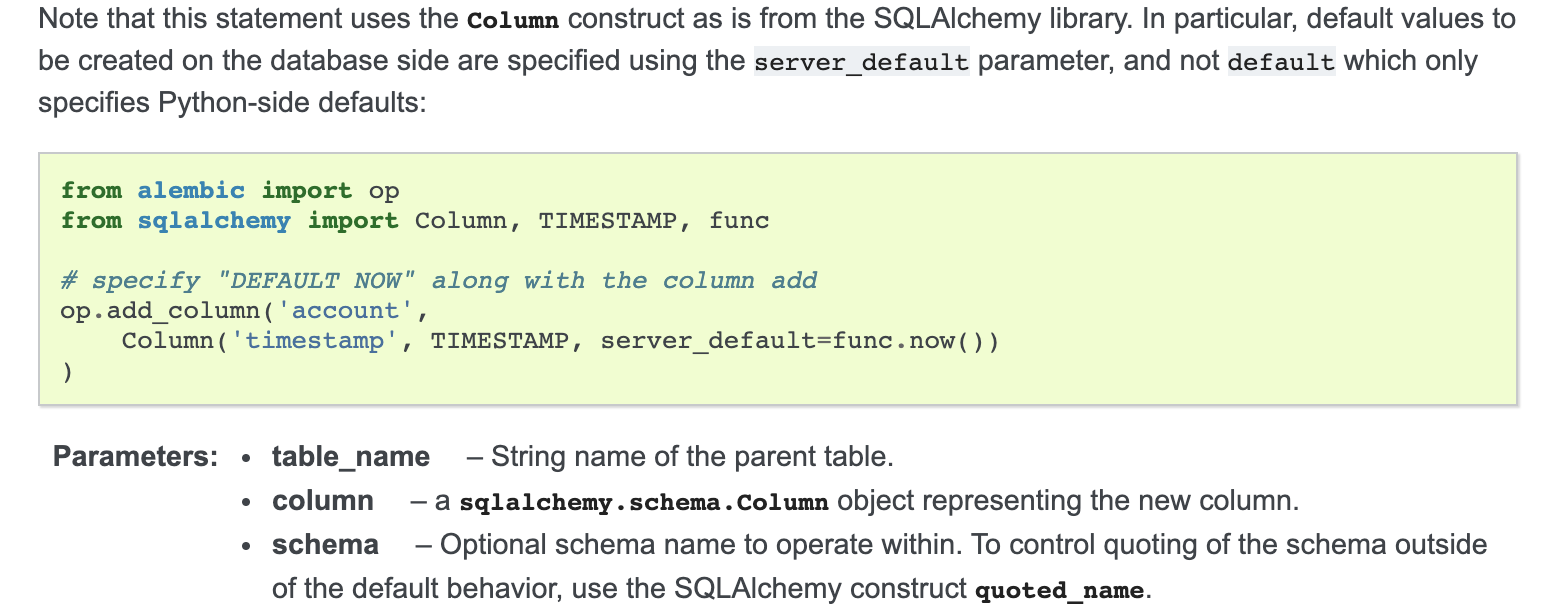
https://alembic.sqlalchemy.org/en/latest/ops.html#alembic.operations.Operations.add_column
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
# are not updated.
# We opted to check DagRun existence instead
# of catching an Integrity error and rolling back the session i.e
- # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+ # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
# create a new one. This is so that in the next Scheduling loop we try to create new runs
# instead of falling in a loop of Integrity Error.
- if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
- run = dag.create_dagrun(
+ if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+ dag.create_dagrun(
run_type=DagRunType.SCHEDULED,
execution_date=dag_model.next_dagrun,
- start_date=timezone.utcnow(),
- state=State.RUNNING,
+ state=State.QUEUED,
external_trigger=False,
session=session,
dag_hash=dag_hash,
creating_job_id=self.id,
)
-
- expected_start_date = dag.following_schedule(run.execution_date)
- if expected_start_date:
- schedule_delay = run.start_date - expected_start_date
- Stats.timing(
- f'dagrun.schedule_delay.{dag.dag_id}',
- schedule_delay,
- )
-
- self._update_dag_next_dagruns(dag_models, session)
+ dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+ dag_model.next_dagrun
+ )
# TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
# memory for larger dags? or expunge_all()
- def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+ def _start_dagrun(
+ self,
+ guard,
+ session: Session,
+ ) -> int:
"""
- Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
- We batch the select queries to get info about all the dags at once
+ Find DagRuns in queued state and decide moving them to running state
+ :param dag_run: The DagRun to schedule
Review comment:
We don't have a `dag_run` param on this method though on this method
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
Review comment:
We don't have any `server_default`, we just had a `default`:
https://docs.sqlalchemy.org/en/14/core/defaults.html#scalar-defaults
https://docs.sqlalchemy.org/en/14/core/metadata.html#sqlalchemy.schema.Column.params.server_default
https://docs.sqlalchemy.org/en/14/core/metadata.html#sqlalchemy.schema.Column.params.default
##########
File path: airflow/models/dag.py
##########
@@ -1423,7 +1423,7 @@ def clear(
confirm_prompt=False,
include_subdags=True,
include_parentdag=True,
- dag_run_state: str = State.RUNNING,
+ dag_run_state: str = State.QUEUED,
Review comment:
Similarly, we should update L1552 too:
https://github.com/apache/airflow/blob/0ed4445635a70645e53fdf433356829b504e7d53/airflow/models/dag.py#L1552
##########
File path: docs/apache-airflow/migrations-ref.rst
##########
@@ -23,7 +23,9 @@ Here's the list of all the Database Migrations that are executed via when you ru
+--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
| Revision ID | Revises ID | Airflow Version | Description |
+--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
-| ``30867afad44a`` (head) | ``e9304a3141f0`` | | Rename ``concurrency`` column in ``dag`` table to`` max_active_tasks`` |
+| ``a84a5abfca95`` (head) | ``30867afad44a`` | | Set default start_time for dagrun to null and set default state to QUEUED |
Review comment:
We might not need a migration at all!
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
# are not updated.
# We opted to check DagRun existence instead
# of catching an Integrity error and rolling back the session i.e
- # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+ # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
# create a new one. This is so that in the next Scheduling loop we try to create new runs
# instead of falling in a loop of Integrity Error.
- if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
- run = dag.create_dagrun(
+ if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+ dag.create_dagrun(
run_type=DagRunType.SCHEDULED,
execution_date=dag_model.next_dagrun,
- start_date=timezone.utcnow(),
- state=State.RUNNING,
+ state=State.QUEUED,
Review comment:
Can be a separate PR but do you think it is worth adding `queued_dttm` similar to TaskInstances:
https://github.com/apache/airflow/blob/57dcac22137bc958c1ed9f12fa54484e13411a6f/airflow/models/taskinstance.py#L307
This can help in future for benchmarking difference between Queued and Start time for a DagRun
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
Review comment:
```suggestion
```
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
Review comment:
tbh I don't think we need a migration at all !!
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
# are not updated.
# We opted to check DagRun existence instead
# of catching an Integrity error and rolling back the session i.e
- # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+ # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
# create a new one. This is so that in the next Scheduling loop we try to create new runs
# instead of falling in a loop of Integrity Error.
- if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
- run = dag.create_dagrun(
+ if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+ dag.create_dagrun(
run_type=DagRunType.SCHEDULED,
execution_date=dag_model.next_dagrun,
- start_date=timezone.utcnow(),
- state=State.RUNNING,
+ state=State.QUEUED,
external_trigger=False,
session=session,
dag_hash=dag_hash,
creating_job_id=self.id,
)
-
- expected_start_date = dag.following_schedule(run.execution_date)
- if expected_start_date:
- schedule_delay = run.start_date - expected_start_date
- Stats.timing(
- f'dagrun.schedule_delay.{dag.dag_id}',
- schedule_delay,
- )
-
- self._update_dag_next_dagruns(dag_models, session)
+ dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+ dag_model.next_dagrun
+ )
# TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
# memory for larger dags? or expunge_all()
- def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+ def _start_queued_dagruns(
+ self,
+ session: Session,
+ ) -> int:
"""
- Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+ Find DagRuns in queued state and decide moving them to running state
- We batch the select queries to get info about all the dags at once
+ :param dag_run: The DagRun to schedule
"""
- # Check max_active_runs, to see if we are _now_ at the limit for any of
- # these dag? (we've just created a DagRun for them after all)
- active_runs_of_dags = dict(
+ dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+ active_runs_of_dags = defaultdict(
+ lambda: 0,
session.query(DagRun.dag_id, func.count('*'))
- .filter(
- DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+ .filter( # We use `list` here because SQLA doesn't accept a set
+ DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),
Review comment:
oh yeah that makes sense, can you add a comment about removing duplicates (unless you have already and I missed it)
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-875444617


   This will be 2.1.3 -- 2.1.2 is a quick follow on fix due to breaking Triggering DAGs via the UI, so we wan't to get that out quicker (i.e. 2.1.2 is a small change on 2.1.1, and this is a bigger change that needs a bit more testing time 😄 )


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r652194421


##########
File path: airflow/api_connexion/openapi/v1.yaml
##########
@@ -1892,13 +1892,14 @@ components:
           description: |
             The start time. The time when DAG run was actually created.
           readOnly: true
+          nullable: true
         end_date:
           type: string
           format: date-time
           readOnly: true
           nullable: true
         state:
-          $ref: '#/components/schemas/DagState'
+          $ref: '#/components/schemas/DagRunState'

Review comment:
       ```suggestion
             $ref: '#/components/schemas/DagState'
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660165653


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_queued_dagruns(
+        self,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+        Find DagRuns in queued state and decide moving them to running state

-        We batch the select queries to get info about all the dags at once
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
+        dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+        active_runs_of_dags = defaultdict(
+            lambda: 0,
             session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+            .filter(  # We use `list` here because SQLA doesn't accept a set
+                DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),

Review comment:
       oh yeah that makes sense, can you add a comment about removing duplicates (unless you have already and I missed it)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-873958776


   One teeny tiny comment then LGTM!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-873958776


   One teeny tiny comment then LGTM!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659897924


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -984,89 +956,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_queued_dagruns(
+        self,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+        Find DagRuns in queued state and decide moving them to running state

-        We batch the select queries to get info about all the dags at once
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
+        dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+        active_runs_of_dags = defaultdict(
+            lambda: 0,
             session.query(DagRun.dag_id, func.count('*'))
             .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+                DagRun.dag_id.in_([dr.dag_id for dr in dag_runs]),

Review comment:
       This will potentially put a lot of the same dag_id in the query multiple times which could produce an inefficient query.

   ```suggestion
                   DagRun.dag_id.in_(list(set(dr.dag_id for dr in dag_runs))),
   ```

   And probably needs a comment saying why you need `list(set())` (which is that _I think_ SQLA doesn't accept a set)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] fj-sanchez commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
fj-sanchez commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-875438057


   Really nice to see this merged!! :tada:

   So, is this planned for 2.1.3 instead of 2.1.2?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] fj-sanchez commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
fj-sanchez commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-865221307


   Really looking forward to having this one in. :clap:


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r652194566


##########
File path: airflow/api_connexion/openapi/v1.yaml
##########
@@ -3059,12 +3060,13 @@ components:
         - scheduled
         - removed

-    DagState:
-      description: DAG State.
+    DagRunState:
+      description: DagRun State.

Review comment:
       ```suggestion
       DagState:
         description: Dag State.
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660073357


##########
File path: airflow/models/taskinstance.py
##########
@@ -237,7 +237,8 @@ def clear_task_instances(
         )
         for dr in drs:
             dr.state = dag_run_state
-            dr.start_date = timezone.utcnow()
+            dr.start_date = None
+            dr.last_scheduling_decision = None

Review comment:
       I have set this and added test. Thanks!

##########
File path: tests/models/test_cleartasks.py
##########
@@ -68,6 +70,41 @@ def test_clear_task_instances(self):
         assert ti1.try_number == 2
         assert ti1.max_tries == 3

+    @parameterized.expand([(State.QUEUED, None), (State.RUNNING, DEFAULT_DATE)])
+    def test_clear_task_instances_dr_state(self, state, last_scheduling):
+        """Test that DR state is set to None after clear.
+        And that DR.last_scheduling_decision is handled OK.
+        start

Review comment:
       ```suggestion
           start_date is also set to None
   ```

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_queued_dagruns(
+        self,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+        Find DagRuns in queued state and decide moving them to running state

-        We batch the select queries to get info about all the dags at once
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
+        dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+        active_runs_of_dags = defaultdict(
+            lambda: 0,
             session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+            .filter(  # We use `list` here because SQLA doesn't accept a set
+                DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),

Review comment:
       The reason for the set is so we don't have duplicate values. @ashb suggested we use a set, What do you think?

##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements.  See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership.  The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License.  You may obtain a copy of the License at
+#
+#   http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied.  See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+    """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+    with op.batch_alter_table('dag_run') as batch_op:
+        batch_op.alter_column(
+            'start_date',
+            type_=sa.TIMESTAMP(timezone=True),
+            existing_server_default=timezone.utcnow(),
+            server_default=None,
+        )
+        batch_op.alter_column(
+            'state',
+            type_=sa.String(length=50),
+            existing_server_default=State.RUNNING,
+            server_default=State.QUEUED,

Review comment:
       It works without migration but I'm a bit confused. I will remove it then

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_queued_dagruns(
+        self,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+        Find DagRuns in queued state and decide moving them to running state

-        We batch the select queries to get info about all the dags at once
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
+        dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+        active_runs_of_dags = defaultdict(
+            lambda: 0,
             session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+            .filter(  # We use `list` here because SQLA doesn't accept a set
+                DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),

Review comment:
       I will update the comment

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,

Review comment:
       Yeah. That's cool, separate PR is cool


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r662349972


##########
File path: airflow/models/dagrun.py
##########
@@ -126,6 +130,10 @@ def __init__(
     ):
         self.dag_id = dag_id
         self.run_id = run_id
+        if queued_at is self.__NO_VALUE:
+            self.queued_at = timezone.utcnow() if state == State.QUEUED else None
+        else:
+            self.queued_at = queued_at

Review comment:
       We need to do this after `self.state = state` (current L141), and `def set_state` should also set queued_at when state is being _changed_ to queued.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660073357


##########
File path: airflow/models/taskinstance.py
##########
@@ -237,7 +237,8 @@ def clear_task_instances(
         )
         for dr in drs:
             dr.state = dag_run_state
-            dr.start_date = timezone.utcnow()
+            dr.start_date = None
+            dr.last_scheduling_decision = None

Review comment:
       I have set this and added test. Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651682360


##########
File path: docs/apache-airflow/migrations-ref.rst
##########
@@ -23,7 +23,9 @@ Here's the list of all the Database Migrations that are executed via when you ru
 +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
 | Revision ID                    | Revises ID       | Airflow Version | Description                                                                           |
 +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
-| ``e9304a3141f0`` (head)        | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |
+| ``a84a5abfca95`` (head)        | ``e9304a3141f0`` |                 | Set default start_time for dagrun to null and set default state to QUEUED             |
++--------------------------------|------------------|-----------------|---------------------------------------------------------------------------------------|
+| ``e9304a3141f0``               | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |

Review comment:
       ```suggestion
   | ``a84a5abfca95`` (head)        | ``e9304a3141f0`` |                 | Set default start_time for dagrun to null and set default state to QUEUED             |
   +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
   | ``e9304a3141f0``               | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659618256


##########
File path: tests/jobs/test_scheduler_job.py
##########
@@ -3143,14 +3143,14 @@ def test_send_sla_callbacks_to_processor_sla_with_task_slas(self):
                 full_filepath=dag.fileloc, dag_id=dag_id
             )

-    @freeze_time(DEFAULT_DATE + datetime.timedelta(days=1, seconds=9))
-    @mock.patch('airflow.jobs.scheduler_job.Stats.timing')
-    def test_create_dag_runs(self, stats_timing):
+    # @freeze_time(DEFAULT_DATE + datetime.timedelta(days=1, seconds=9))

Review comment:
       ```suggestion
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-868261283


   > Merge conflicts :(
   >
   > Can you also squash those commits

   Just saw the `squash` the commits now! Done. Thanks


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r662347512


##########
File path: airflow/models/dag.py
##########
@@ -1892,6 +1892,7 @@ def create_dagrun(
         state: State,
         execution_date: Optional[datetime] = None,
         run_id: Optional[str] = None,
+        queued_at: Optional[datetime] = None,

Review comment:
       We shouldn't pass this here -- it's overriding the default to `DagRun()` with an explicit None/NULL value.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660177421


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,

Review comment:
       Yeah. That's cool, separate PR is cool


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-872069179


   Ahhhh cool!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] uranusjr commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
uranusjr commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-875445478


   Yes. The timeline didn't change, but 2.1.2 was assigned to fix a critical issue in 2.1.1, so everything that was supposed to be in 2.1.2 automatically belongs to 2.1.3 now.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r663775799


##########
File path: airflow/models/dagrun.py
##########
@@ -153,6 +161,7 @@ def set_state(self, state):
         if self._state != state:
             self._state = state
             self.end_date = timezone.utcnow() if self._state in State.finished else None
+            self.queued_at = timezone.utcnow() if self._state == State.QUEUED else self.queued_at

Review comment:
       ```suggestion
               if state == State.QUEUED:
                   self.queued_at = timezone.utcnow()
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil merged pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil merged pull request #16401:
URL: https://github.com/apache/airflow/pull/16401


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651728776


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(
+        self,
+        guard,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
-        We batch the select queries to get info about all the dags at once
+        Find DagRuns in queued state and decide moving them to running state
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
-            session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
-                DagRun.state == State.RUNNING,  # pylint: disable=comparison-with-callable
-                DagRun.external_trigger == expression.false(),
-            )
-            .group_by(DagRun.dag_id)
-            .all()
-        )
+        dag_runs = self._get_next_queued_dagruns_to_examine(session)
+
+        def _update_state(dag_run):
+            dag_run.state = State.RUNNING
+            dag_run.start_date = timezone.utcnow()
+            expected_start_date = dag.following_schedule(dag_run.execution_date)
+            if expected_start_date:
+                schedule_delay = dag_run.start_date - expected_start_date
+                Stats.timing(
+                    f'dagrun.schedule_delay.{dag.dag_id}',
+                    schedule_delay,
+                )
+            # commit the session - Release the write lock on DagModel table.
+            # Commit one dag_run at a time

-        for dag_model in dag_models:
-            # Get the DAG in a try_except to not stop the Scheduler when a Serialized DAG is not found
-            # This takes care of Dynamic DAGs especially
+            guard.commit()
+            # END: create dagruns
+
+        for dag_run in dag_runs:
             try:
-                dag = self.dagbag.get_dag(dag_model.dag_id, session=session)
+                dag = dag_run.dag = self.dagbag.get_dag(dag_run.dag_id, session=session)
             except SerializedDagNotFound:
-                self.log.exception("DAG '%s' not found in serialized_dag table", dag_model.dag_id)
+                self.log.exception("DAG '%s' not found in serialized_dag table", dag_run.dag_id)
                 continue
-            active_runs_of_dag = active_runs_of_dags.get(dag.dag_id, 0)
-            if dag.max_active_runs and active_runs_of_dag >= dag.max_active_runs:
-                self.log.info(
-                    "DAG %s is at (or above) max_active_runs (%d of %d), not creating any more runs",
+            # pylint: disable=comparison-with-callable
+            total_active_dagruns = (
+                session.query(func.count(DR.dag_id))
+                .filter(DR.state == State.RUNNING, DR.dag_id == dag.dag_id)
+                .scalar()
+            )

Review comment:
       Also, I no longer have the `dag_models` passed here. The method that ran the active_runs_of_dags was deleted, so it would be to move the total_active_dagruns up. Should I?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660495661


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,

Review comment:
       Actually to avoid a _second_ migration, I think it makes sense to do in this PR, sorry.

   (Migrations are relatively slow, so if we are already altering a table it's better to do all the changes at once.)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r652195144


##########
File path: airflow/api_connexion/openapi/v1.yaml
##########
@@ -3060,11 +3061,12 @@ components:
         - removed

     DagState:
-      description: DAG State.
+      description: Dag State.

Review comment:
       ```suggestion
         description: DAG State.
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651654584


##########
File path: tests/api_connexion/endpoints/test_dag_run_endpoint.py
##########
@@ -532,7 +535,7 @@ class TestGetDagRunsEndDateFilters(TestDagRunEndpoint):
             (
                 f"api/v1/dags/TEST_DAG_ID/dagRuns?end_date_lte="
                 f"{(timezone.utcnow() + timedelta(days=1)).isoformat()}",
-                ["TEST_DAG_RUN_ID_1"],
+                ["TEST_DAG_RUN_ID_1", "TEST_DAG_RUN_ID_2"],

Review comment:
       This is because instead of changing 'running' to 'queued' for many affected tests, I decided to pass any given state to the second DagModel at line 135(_create_test_dag_run function). So when 'success' is passed to the function's state argument, then two dag_runs will have their end_date set.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-872068158


   > I think setting `queued_at` should be handled internally inside `DagRun()` -- 99% of cases (maybe everything outside of tests) will always want to use "now" for that, so we should do something like we do for variables:
   >
   > ```python
   > class DagRun:
   >
   >     __NO_VALUE = object()
   >
   >     def __init__(
   >         self,
   >         state
   >         # ...
   >         queued_at = __NO_VALUE,
   >     ):
   >         self.state = state
   >         if queued_at is self.__NO_VALUE:
   >             self.queued_at = utcnow() if state == State.QUEUED else None
   >         else:
   >             self.queued_at = queued_at
   > ```
   >
   > This special "no value" object lets us have a default value that is semantically distinct from None.
   >
   > And by handling this internally in the DagRun class we then have less places in the code to update (and less places to get wrong). That said: we should also set `self.queued_at` in side `DagRun.set_state`
   >
   > Wasn't there previously a migration in this PR that changed start_date on the DagRun table to be nullable? What happened to that?

   We had a migration but from @kaxil’s review we discovered we don’t need migration for `start_date` or the `state` because they both don’t have a `server_default` values set. Their values are python values and no server_default set for them. That was why I deleted the migration


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-866371716


   Merge conflicts :(


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659897924


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -984,89 +956,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_queued_dagruns(
+        self,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+        Find DagRuns in queued state and decide moving them to running state

-        We batch the select queries to get info about all the dags at once
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
+        dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+        active_runs_of_dags = defaultdict(
+            lambda: 0,
             session.query(DagRun.dag_id, func.count('*'))
             .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+                DagRun.dag_id.in_([dr.dag_id for dr in dag_runs]),

Review comment:
       This will potentially put a lot of the same dag_id in the query multiple times which could produce an inefficient query.

   ```suggestion
                   DagRun.dag_id.in_(list(set(dr.dag_id for dr in dag_runs))),
   ```

   And probably needs a comment saying why you need `list(set())` (which is that _I think_ SQLA doesn't accept a set)

##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,122 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements.  See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership.  The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License.  You may obtain a copy of the License at
+#
+#   http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied.  See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+from sqlalchemy.dialects import mysql
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+    """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+    conn = op.get_bind()
+    if conn.dialect.name == "mysql":
+        conn.execute("SET time_zone = '+00:00'")
+        cur = conn.execute("SELECT @@explicit_defaults_for_timestamp")
+        res = cur.fetchall()
+        if res[0][0] == 0:
+            raise Exception("Global variable explicit_defaults_for_timestamp needs to be on (1) for mysql")
+        op.alter_column(
+            'dag_run',
+            'start_date',
+            type_=mysql.DATETIME(fsp=6),
+            existing_server_default=timezone.utcnow(),
+            server_default=None,
+        )
+
+    else:
+        # sqlite and mssql datetime are fine as is.  Therefore, not converting
+        if conn.dialect.name in ("sqlite", "mssql"):
+            return

Review comment:
       We're changing the default aren't we -- that should apply equally to all database types

##########
File path: airflow/models/taskinstance.py
##########
@@ -237,7 +237,8 @@ def clear_task_instances(
         )
         for dr in drs:
             dr.state = dag_run_state
-            dr.start_date = timezone.utcnow()
+            dr.start_date = None
+            dr.last_scheduling_decision = None

Review comment:
       Oh, _technically_ someone could set a state other than queued here -- so maybe we need an `if dag_run_state == State.QUEUED: ... else: ...` here?

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,

Review comment:
       Actually to avoid a _second_ migration, I think it makes sense to do in this PR, sorry.

   (Migrations are relatively slow, so if we are already altering a table it's better to do all the changes at once.)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660163349


##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements.  See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership.  The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License.  You may obtain a copy of the License at
+#
+#   http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied.  See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+    """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+    with op.batch_alter_table('dag_run') as batch_op:
+        batch_op.alter_column(
+            'start_date',
+            type_=sa.TIMESTAMP(timezone=True),
+            existing_server_default=timezone.utcnow(),
+            server_default=None,
+        )
+        batch_op.alter_column(
+            'state',
+            type_=sa.String(length=50),
+            existing_server_default=State.RUNNING,
+            server_default=State.QUEUED,

Review comment:
       It works without migration but I'm a bit confused. I will remove it then


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659614032


##########
File path: tests/dag_processing/test_processor.py
##########
@@ -560,11 +560,10 @@ def test_scheduler_job_add_new_task(self):

     def test_runs_respected_after_clear(self):

Review comment:
       This is in the wrong file -- it should be in test_scheduler_job (make this a separate PR, before or after.)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r662490438


##########
File path: airflow/migrations/versions/97cdd93827b8_add_queued_at_column_to_dagrun_table.py
##########
@@ -0,0 +1,44 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements.  See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership.  The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License.  You may obtain a copy of the License at
+#
+#   http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied.  See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""Add queued_at column to dagrun table
+
+Revision ID: 97cdd93827b8
+Revises: 30867afad44a
+Create Date: 2021-06-29 21:53:48.059438
+
+"""
+
+import sqlalchemy as sa
+from alembic import op
+
+# revision identifiers, used by Alembic.
+revision = '97cdd93827b8'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+    """Apply Add queued_at column to dagrun table"""
+    op.add_column('dag_run', sa.Column('queued_at', sa.DateTime(), nullable=True))

Review comment:
       wow. Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651561908


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(
+        self,
+        guard,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
-        We batch the select queries to get info about all the dags at once
+        Find DagRuns in queued state and decide moving them to running state
+        :param dag_run: The DagRun to schedule

Review comment:
       ```suggestion

           :param dag_run: The DagRun to schedule
   ```

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(

Review comment:
       ```suggestion
       def _start_queued_dagruns(
   ```

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(
+        self,
+        guard,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
-        We batch the select queries to get info about all the dags at once
+        Find DagRuns in queued state and decide moving them to running state
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
-            session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
-                DagRun.state == State.RUNNING,  # pylint: disable=comparison-with-callable
-                DagRun.external_trigger == expression.false(),
-            )
-            .group_by(DagRun.dag_id)
-            .all()
-        )
+        dag_runs = self._get_next_queued_dagruns_to_examine(session)
+
+        def _update_state(dag_run):
+            dag_run.state = State.RUNNING
+            dag_run.start_date = timezone.utcnow()
+            expected_start_date = dag.following_schedule(dag_run.execution_date)
+            if expected_start_date:
+                schedule_delay = dag_run.start_date - expected_start_date
+                Stats.timing(
+                    f'dagrun.schedule_delay.{dag.dag_id}',
+                    schedule_delay,
+                )
+            # commit the session - Release the write lock on DagModel table.
+            # Commit one dag_run at a time

-        for dag_model in dag_models:
-            # Get the DAG in a try_except to not stop the Scheduler when a Serialized DAG is not found
-            # This takes care of Dynamic DAGs especially
+            guard.commit()
+            # END: create dagruns

Review comment:
       Additionally: let's not commit inside this function, but only outside -- the general rule is that if a function accepts a session object it is the caller's responsibility to commit.

   This means we also don't have to pass the `guard` in here.

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1454,39 +1453,11 @@ def _do_scheduling(self, session) -> int:
             if settings.USE_JOB_SCHEDULE:
                 self._create_dagruns_for_dags(guard, session)

-            dag_runs = self._get_next_dagruns_to_examine(session)
+            self._start_dagrun(guard, session)

Review comment:
       ```suggestion
               self._start_queued_dagrun(session)
               guard.commit()
   ```

   (as per my other comments)

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(
+        self,
+        guard,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
-        We batch the select queries to get info about all the dags at once
+        Find DagRuns in queued state and decide moving them to running state
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
-            session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
-                DagRun.state == State.RUNNING,  # pylint: disable=comparison-with-callable
-                DagRun.external_trigger == expression.false(),
-            )
-            .group_by(DagRun.dag_id)
-            .all()
-        )
+        dag_runs = self._get_next_queued_dagruns_to_examine(session)
+
+        def _update_state(dag_run):
+            dag_run.state = State.RUNNING
+            dag_run.start_date = timezone.utcnow()
+            expected_start_date = dag.following_schedule(dag_run.execution_date)
+            if expected_start_date:
+                schedule_delay = dag_run.start_date - expected_start_date
+                Stats.timing(
+                    f'dagrun.schedule_delay.{dag.dag_id}',
+                    schedule_delay,
+                )
+            # commit the session - Release the write lock on DagModel table.
+            # Commit one dag_run at a time

-        for dag_model in dag_models:
-            # Get the DAG in a try_except to not stop the Scheduler when a Serialized DAG is not found
-            # This takes care of Dynamic DAGs especially
+            guard.commit()
+            # END: create dagruns

Review comment:
       This is too early -- it releases the lock after the first time it's called, but we want to keep the lock for the _entire_  `for dag_run in dag_runs` loop.

##########
File path: airflow/models/dagrun.py
##########
@@ -228,6 +228,51 @@ def next_dagruns_to_examine(
             query.limit(max_number), of=cls, session=session, **skip_locked(session=session)
         )

+    @classmethod
+    def next_queued_dagruns_to_examine(

Review comment:
       This is almost identical to the previous function -- rather than a new function let's keep it called `next_dagruns_to_examine` but add a new required`state` parameter.

##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(
+        self,
+        guard,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
-        We batch the select queries to get info about all the dags at once
+        Find DagRuns in queued state and decide moving them to running state
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
-            session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
-                DagRun.state == State.RUNNING,  # pylint: disable=comparison-with-callable
-                DagRun.external_trigger == expression.false(),
-            )
-            .group_by(DagRun.dag_id)
-            .all()
-        )
+        dag_runs = self._get_next_queued_dagruns_to_examine(session)
+
+        def _update_state(dag_run):
+            dag_run.state = State.RUNNING
+            dag_run.start_date = timezone.utcnow()
+            expected_start_date = dag.following_schedule(dag_run.execution_date)
+            if expected_start_date:
+                schedule_delay = dag_run.start_date - expected_start_date
+                Stats.timing(
+                    f'dagrun.schedule_delay.{dag.dag_id}',
+                    schedule_delay,
+                )
+            # commit the session - Release the write lock on DagModel table.
+            # Commit one dag_run at a time

-        for dag_model in dag_models:
-            # Get the DAG in a try_except to not stop the Scheduler when a Serialized DAG is not found
-            # This takes care of Dynamic DAGs especially
+            guard.commit()
+            # END: create dagruns
+
+        for dag_run in dag_runs:
             try:
-                dag = self.dagbag.get_dag(dag_model.dag_id, session=session)
+                dag = dag_run.dag = self.dagbag.get_dag(dag_run.dag_id, session=session)
             except SerializedDagNotFound:
-                self.log.exception("DAG '%s' not found in serialized_dag table", dag_model.dag_id)
+                self.log.exception("DAG '%s' not found in serialized_dag table", dag_run.dag_id)
                 continue
-            active_runs_of_dag = active_runs_of_dags.get(dag.dag_id, 0)
-            if dag.max_active_runs and active_runs_of_dag >= dag.max_active_runs:
-                self.log.info(
-                    "DAG %s is at (or above) max_active_runs (%d of %d), not creating any more runs",
+            # pylint: disable=comparison-with-callable
+            total_active_dagruns = (
+                session.query(func.count(DR.dag_id))
+                .filter(DR.state == State.RUNNING, DR.dag_id == dag.dag_id)
+                .scalar()
+            )

Review comment:
       This does one query per dag run loop -- which is "expensive", instead we should have the same query we had before (`active_runs_of_dags`) and then add 1 to the value in the dict when we start a new dag.

##########
File path: tests/api_connexion/endpoints/test_dag_run_endpoint.py
##########
@@ -532,7 +535,7 @@ class TestGetDagRunsEndDateFilters(TestDagRunEndpoint):
             (
                 f"api/v1/dags/TEST_DAG_ID/dagRuns?end_date_lte="
                 f"{(timezone.utcnow() + timedelta(days=1)).isoformat()}",
-                ["TEST_DAG_RUN_ID_1"],
+                ["TEST_DAG_RUN_ID_1", "TEST_DAG_RUN_ID_2"],

Review comment:
       Hmmm, why did these tests need changing? I would have expected they would have passed as they were.

##########
File path: airflow/www/views.py
##########
@@ -3889,7 +3889,7 @@ def duration_f(self):
         lazy_gettext('Clear'),
         lazy_gettext(
             'Are you sure you want to clear the state of the selected task'
-            ' instance(s) and set their dagruns to the running state?'
+            ' instance(s) and set their dagruns to the NONE state?'

Review comment:
       We should set it to the queued state, no?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659608901


##########
File path: tests/api_connexion/endpoints/test_dag_run_endpoint.py
##########
@@ -269,7 +271,7 @@ def test_should_respond_200(self, session):
                     'dag_id': 'TEST_DAG_ID',
                     'dag_run_id': 'TEST_DAG_RUN_ID_2',
                     'end_date': None,
-                    'state': 'running',
+                    'state': 'queued',
                     'execution_date': self.default_time_2,
                     'external_trigger': True,
                     'start_date': self.default_time,

Review comment:
       Lets update the `create_test_dag_run` to be more reflective of new "reality" and not set start_date if the state is queued.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651690166


##########
File path: docs/apache-airflow/migrations-ref.rst
##########
@@ -23,7 +23,9 @@ Here's the list of all the Database Migrations that are executed via when you ru
 +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
 | Revision ID                    | Revises ID       | Airflow Version | Description                                                                           |
 +--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
-| ``e9304a3141f0`` (head)        | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |
+| ``a84a5abfca95`` (head)        | ``e9304a3141f0`` |                 | Set default start_time for dagrun to null and set default state to QUEUED             |
++--------------------------------|------------------|-----------------|---------------------------------------------------------------------------------------|
+| ``e9304a3141f0``               | ``83f031fd9f1c`` |                 | Make XCom primary key columns non-nullable                                            |

Review comment:
       Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660021617


##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,122 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements.  See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership.  The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License.  You may obtain a copy of the License at
+#
+#   http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied.  See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+from sqlalchemy.dialects import mysql
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+    """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+    conn = op.get_bind()
+    if conn.dialect.name == "mysql":
+        conn.execute("SET time_zone = '+00:00'")
+        cur = conn.execute("SELECT @@explicit_defaults_for_timestamp")
+        res = cur.fetchall()
+        if res[0][0] == 0:
+            raise Exception("Global variable explicit_defaults_for_timestamp needs to be on (1) for mysql")
+        op.alter_column(
+            'dag_run',
+            'start_date',
+            type_=mysql.DATETIME(fsp=6),
+            existing_server_default=timezone.utcnow(),
+            server_default=None,
+        )
+
+    else:
+        # sqlite and mssql datetime are fine as is.  Therefore, not converting
+        if conn.dialect.name in ("sqlite", "mssql"):
+            return

Review comment:
       We're changing the default aren't we -- that should apply equally to all database types

##########
File path: airflow/models/taskinstance.py
##########
@@ -237,7 +237,8 @@ def clear_task_instances(
         )
         for dr in drs:
             dr.state = dag_run_state
-            dr.start_date = timezone.utcnow()
+            dr.start_date = None
+            dr.last_scheduling_decision = None

Review comment:
       Oh, _technically_ someone could set a state other than queued here -- so maybe we need an `if dag_run_state == State.QUEUED: ... else: ...` here?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] fj-sanchez commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
fj-sanchez commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-865221307


   Really looking forward to having this one in. :clap:


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r659605662


##########
File path: airflow/models/taskinstance.py
##########
@@ -237,7 +237,7 @@ def clear_task_instances(
         )
         for dr in drs:
             dr.state = dag_run_state
-            dr.start_date = timezone.utcnow()
+            dr.start_date = None

Review comment:
       ```suggestion
               dr.start_date = None
               dr.last_scheduling_decision = None
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660162919


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_queued_dagruns(
+        self,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+        Find DagRuns in queued state and decide moving them to running state

-        We batch the select queries to get info about all the dags at once
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
+        dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+        active_runs_of_dags = defaultdict(
+            lambda: 0,
             session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+            .filter(  # We use `list` here because SQLA doesn't accept a set
+                DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),

Review comment:
       The reason for the set is so we don't have duplicate values. @ashb suggested we use a set, What do you think?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651742864


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(
+        self,
+        guard,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
-        We batch the select queries to get info about all the dags at once
+        Find DagRuns in queued state and decide moving them to running state
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
-            session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
-                DagRun.state == State.RUNNING,  # pylint: disable=comparison-with-callable
-                DagRun.external_trigger == expression.false(),
-            )
-            .group_by(DagRun.dag_id)
-            .all()
-        )
+        dag_runs = self._get_next_queued_dagruns_to_examine(session)
+
+        def _update_state(dag_run):
+            dag_run.state = State.RUNNING
+            dag_run.start_date = timezone.utcnow()
+            expected_start_date = dag.following_schedule(dag_run.execution_date)
+            if expected_start_date:
+                schedule_delay = dag_run.start_date - expected_start_date
+                Stats.timing(
+                    f'dagrun.schedule_delay.{dag.dag_id}',
+                    schedule_delay,
+                )
+            # commit the session - Release the write lock on DagModel table.
+            # Commit one dag_run at a time

-        for dag_model in dag_models:
-            # Get the DAG in a try_except to not stop the Scheduler when a Serialized DAG is not found
-            # This takes care of Dynamic DAGs especially
+            guard.commit()
+            # END: create dagruns
+
+        for dag_run in dag_runs:
             try:
-                dag = self.dagbag.get_dag(dag_model.dag_id, session=session)
+                dag = dag_run.dag = self.dagbag.get_dag(dag_run.dag_id, session=session)
             except SerializedDagNotFound:
-                self.log.exception("DAG '%s' not found in serialized_dag table", dag_model.dag_id)
+                self.log.exception("DAG '%s' not found in serialized_dag table", dag_run.dag_id)
                 continue
-            active_runs_of_dag = active_runs_of_dags.get(dag.dag_id, 0)
-            if dag.max_active_runs and active_runs_of_dag >= dag.max_active_runs:
-                self.log.info(
-                    "DAG %s is at (or above) max_active_runs (%d of %d), not creating any more runs",
+            # pylint: disable=comparison-with-callable
+            total_active_dagruns = (
+                session.query(func.count(DR.dag_id))
+                .filter(DR.state == State.RUNNING, DR.dag_id == dag.dag_id)
+                .scalar()
+            )

Review comment:
       Since the dag runs are locked, no other scheduler will be able to update them, so the info won't be stale.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-860708590

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil commented on pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil commented on pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#issuecomment-874789356


   Very well done @ephraimbuddy 👏


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ashb commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ashb commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r663775799


##########
File path: airflow/models/dagrun.py
##########
@@ -153,6 +161,7 @@ def set_state(self, state):
         if self._state != state:
             self._state = state
             self.end_date = timezone.utcnow() if self._state in State.finished else None
+            self.queued_at = timezone.utcnow() if self._state == State.QUEUED else self.queued_at

Review comment:
       ```suggestion
               if state == State.QUEUED:
                   self.queued_at = timezone.utcnow()
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] kaxil commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
kaxil commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660149354
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
# are not updated.
# We opted to check DagRun existence instead
# of catching an Integrity error and rolling back the session i.e
- # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+ # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
# create a new one. This is so that in the next Scheduling loop we try to create new runs
# instead of falling in a loop of Integrity Error.
- if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
- run = dag.create_dagrun(
+ if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+ dag.create_dagrun(
run_type=DagRunType.SCHEDULED,
execution_date=dag_model.next_dagrun,
- start_date=timezone.utcnow(),
- state=State.RUNNING,
+ state=State.QUEUED,
external_trigger=False,
session=session,
dag_hash=dag_hash,
creating_job_id=self.id,
)
-
- expected_start_date = dag.following_schedule(run.execution_date)
- if expected_start_date:
- schedule_delay = run.start_date - expected_start_date
- Stats.timing(
- f'dagrun.schedule_delay.{dag.dag_id}',
- schedule_delay,
- )
-
- self._update_dag_next_dagruns(dag_models, session)
+ dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+ dag_model.next_dagrun
+ )
# TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
# memory for larger dags? or expunge_all()
- def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+ def _start_queued_dagruns(
+ self,
+ session: Session,
+ ) -> int:
"""
- Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+ Find DagRuns in queued state and decide moving them to running state
- We batch the select queries to get info about all the dags at once
+ :param dag_run: The DagRun to schedule
"""
- # Check max_active_runs, to see if we are _now_ at the limit for any of
- # these dag? (we've just created a DagRun for them after all)
- active_runs_of_dags = dict(
+ dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+ active_runs_of_dags = defaultdict(
+ lambda: 0,
session.query(DagRun.dag_id, func.count('*'))
- .filter(
- DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+ .filter( # We use `list` here because SQLA doesn't accept a set
+ DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),
Review comment:
```suggestion
DagRun.dag_id.in_(list(dr.dag_id for dr in dag_runs)),
```
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
+ )
+
+
+def downgrade():
+ """Unapply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=None,
+ server_default=timezone.utcnow(),
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.QUEUED,
+ server_default=State.RUNNING,
Review comment:
same here
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
Review comment:
```suggestion
```
We don't want to set `server_defaults` instead we set Python-side defaults
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
+ )
+
+
+def downgrade():
+ """Unapply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=None,
+ server_default=timezone.utcnow(),
Review comment:
same here
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -215,7 +214,7 @@ def _change_state_for_tis_without_dagrun(
.filter(models.TaskInstance.state.in_(old_states))
.filter(
or_(
- models.DagRun.state != State.RUNNING,
+ models.DagRun.state.notin_([State.RUNNING, State.QUEUED]),
Review comment:
L200 needs updating to say "not in the running or queued state"
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
Review comment:

https://alembic.sqlalchemy.org/en/latest/ops.html#alembic.operations.Operations.add_column
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
# are not updated.
# We opted to check DagRun existence instead
# of catching an Integrity error and rolling back the session i.e
- # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+ # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
# create a new one. This is so that in the next Scheduling loop we try to create new runs
# instead of falling in a loop of Integrity Error.
- if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
- run = dag.create_dagrun(
+ if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+ dag.create_dagrun(
run_type=DagRunType.SCHEDULED,
execution_date=dag_model.next_dagrun,
- start_date=timezone.utcnow(),
- state=State.RUNNING,
+ state=State.QUEUED,
external_trigger=False,
session=session,
dag_hash=dag_hash,
creating_job_id=self.id,
)
-
- expected_start_date = dag.following_schedule(run.execution_date)
- if expected_start_date:
- schedule_delay = run.start_date - expected_start_date
- Stats.timing(
- f'dagrun.schedule_delay.{dag.dag_id}',
- schedule_delay,
- )
-
- self._update_dag_next_dagruns(dag_models, session)
+ dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+ dag_model.next_dagrun
+ )
# TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
# memory for larger dags? or expunge_all()
- def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+ def _start_dagrun(
+ self,
+ guard,
+ session: Session,
+ ) -> int:
"""
- Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
- We batch the select queries to get info about all the dags at once
+ Find DagRuns in queued state and decide moving them to running state
+ :param dag_run: The DagRun to schedule
Review comment:
We don't have a `dag_run` param on this method though on this method
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
Review comment:
We don't have any `server_default`, we just had a `default`:
https://docs.sqlalchemy.org/en/14/core/defaults.html#scalar-defaults
https://docs.sqlalchemy.org/en/14/core/metadata.html#sqlalchemy.schema.Column.params.server_default
https://docs.sqlalchemy.org/en/14/core/metadata.html#sqlalchemy.schema.Column.params.default
##########
File path: airflow/models/dag.py
##########
@@ -1423,7 +1423,7 @@ def clear(
confirm_prompt=False,
include_subdags=True,
include_parentdag=True,
- dag_run_state: str = State.RUNNING,
+ dag_run_state: str = State.QUEUED,
Review comment:
Similarly, we should update L1552 too:
https://github.com/apache/airflow/blob/0ed4445635a70645e53fdf433356829b504e7d53/airflow/models/dag.py#L1552
##########
File path: docs/apache-airflow/migrations-ref.rst
##########
@@ -23,7 +23,9 @@ Here's the list of all the Database Migrations that are executed via when you ru
+--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
| Revision ID | Revises ID | Airflow Version | Description |
+--------------------------------+------------------+-----------------+---------------------------------------------------------------------------------------+
-| ``30867afad44a`` (head) | ``e9304a3141f0`` | | Rename ``concurrency`` column in ``dag`` table to`` max_active_tasks`` |
+| ``a84a5abfca95`` (head) | ``30867afad44a`` | | Set default start_time for dagrun to null and set default state to QUEUED |
Review comment:
We might not need a migration at all!
##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
# are not updated.
# We opted to check DagRun existence instead
# of catching an Integrity error and rolling back the session i.e
- # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+ # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
# create a new one. This is so that in the next Scheduling loop we try to create new runs
# instead of falling in a loop of Integrity Error.
- if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
- run = dag.create_dagrun(
+ if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+ dag.create_dagrun(
run_type=DagRunType.SCHEDULED,
execution_date=dag_model.next_dagrun,
- start_date=timezone.utcnow(),
- state=State.RUNNING,
+ state=State.QUEUED,
Review comment:
Can be a separate PR but do you think it is worth adding `queued_dttm` similar to TaskInstances:
https://github.com/apache/airflow/blob/57dcac22137bc958c1ed9f12fa54484e13411a6f/airflow/models/taskinstance.py#L307
This can help in future for benchmarking difference between Queued and Start time for a DagRun
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
Review comment:
```suggestion
```
##########
File path: airflow/migrations/versions/a84a5abfca95_update_dagrun_state_and_datetime.py
##########
@@ -0,0 +1,70 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing,
+# software distributed under the License is distributed on an
+# "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+# KIND, either express or implied. See the License for the
+# specific language governing permissions and limitations
+# under the License.
+
+"""update-dagrun-state-and-datetime
+
+Revision ID: a84a5abfca95
+Revises: 30867afad44a
+Create Date: 2021-06-13 11:08:18.705168
+
+"""
+import sqlalchemy as sa
+from alembic import op
+
+from airflow.utils.dates import timezone
+from airflow.utils.state import State
+
+# revision identifiers, used by Alembic.
+revision = 'a84a5abfca95'
+down_revision = '30867afad44a'
+branch_labels = None
+depends_on = None
+
+
+def upgrade():
+ """Apply Set default start_time for dagrun to None and set default state to QUEUED"""
+ with op.batch_alter_table('dag_run') as batch_op:
+ batch_op.alter_column(
+ 'start_date',
+ type_=sa.TIMESTAMP(timezone=True),
+ existing_server_default=timezone.utcnow(),
+ server_default=None,
+ )
+ batch_op.alter_column(
+ 'state',
+ type_=sa.String(length=50),
+ existing_server_default=State.RUNNING,
+ server_default=State.QUEUED,
Review comment:
tbh I don't think we need a migration at all !!
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r651707574


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -1591,89 +1567,85 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_dagrun(
+        self,
+        guard,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
-
-        We batch the select queries to get info about all the dags at once
+        Find DagRuns in queued state and decide moving them to running state
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
-            session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
-                DagRun.state == State.RUNNING,  # pylint: disable=comparison-with-callable
-                DagRun.external_trigger == expression.false(),
-            )
-            .group_by(DagRun.dag_id)
-            .all()
-        )
+        dag_runs = self._get_next_queued_dagruns_to_examine(session)
+
+        def _update_state(dag_run):
+            dag_run.state = State.RUNNING
+            dag_run.start_date = timezone.utcnow()
+            expected_start_date = dag.following_schedule(dag_run.execution_date)
+            if expected_start_date:
+                schedule_delay = dag_run.start_date - expected_start_date
+                Stats.timing(
+                    f'dagrun.schedule_delay.{dag.dag_id}',
+                    schedule_delay,
+                )
+            # commit the session - Release the write lock on DagModel table.
+            # Commit one dag_run at a time

-        for dag_model in dag_models:
-            # Get the DAG in a try_except to not stop the Scheduler when a Serialized DAG is not found
-            # This takes care of Dynamic DAGs especially
+            guard.commit()
+            # END: create dagruns
+
+        for dag_run in dag_runs:
             try:
-                dag = self.dagbag.get_dag(dag_model.dag_id, session=session)
+                dag = dag_run.dag = self.dagbag.get_dag(dag_run.dag_id, session=session)
             except SerializedDagNotFound:
-                self.log.exception("DAG '%s' not found in serialized_dag table", dag_model.dag_id)
+                self.log.exception("DAG '%s' not found in serialized_dag table", dag_run.dag_id)
                 continue
-            active_runs_of_dag = active_runs_of_dags.get(dag.dag_id, 0)
-            if dag.max_active_runs and active_runs_of_dag >= dag.max_active_runs:
-                self.log.info(
-                    "DAG %s is at (or above) max_active_runs (%d of %d), not creating any more runs",
+            # pylint: disable=comparison-with-callable
+            total_active_dagruns = (
+                session.query(func.count(DR.dag_id))
+                .filter(DR.state == State.RUNNING, DR.dag_id == dag.dag_id)
+                .scalar()
+            )

Review comment:
       I think that we may end up having stale data?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [airflow] ephraimbuddy commented on a change in pull request #16401: Add 'queued' state to DagRun
Posted by GitBox <gi...@apache.org>.
ephraimbuddy commented on a change in pull request #16401:
URL: https://github.com/apache/airflow/pull/16401#discussion_r660166198


##########
File path: airflow/jobs/scheduler_job.py
##########
@@ -980,89 +952,86 @@ def _create_dag_runs(self, dag_models: Iterable[DagModel], session: Session) ->
             # are not updated.
             # We opted to check DagRun existence instead
             # of catching an Integrity error and rolling back the session i.e
-            # we need to run self._update_dag_next_dagruns if the Dag Run already exists or if we
+            # we need to set dag.next_dagrun_info if the Dag Run already exists or if we
             # create a new one. This is so that in the next Scheduling loop we try to create new runs
             # instead of falling in a loop of Integrity Error.
-            if (dag.dag_id, dag_model.next_dagrun) not in active_dagruns:
-                run = dag.create_dagrun(
+            if (dag.dag_id, dag_model.next_dagrun) not in existing_dagruns:
+                dag.create_dagrun(
                     run_type=DagRunType.SCHEDULED,
                     execution_date=dag_model.next_dagrun,
-                    start_date=timezone.utcnow(),
-                    state=State.RUNNING,
+                    state=State.QUEUED,
                     external_trigger=False,
                     session=session,
                     dag_hash=dag_hash,
                     creating_job_id=self.id,
                 )
-
-                expected_start_date = dag.following_schedule(run.execution_date)
-                if expected_start_date:
-                    schedule_delay = run.start_date - expected_start_date
-                    Stats.timing(
-                        f'dagrun.schedule_delay.{dag.dag_id}',
-                        schedule_delay,
-                    )
-
-        self._update_dag_next_dagruns(dag_models, session)
+            dag_model.next_dagrun, dag_model.next_dagrun_create_after = dag.next_dagrun_info(
+                dag_model.next_dagrun
+            )

         # TODO[HA]: Should we do a session.flush() so we don't have to keep lots of state/object in
         # memory for larger dags? or expunge_all()

-    def _update_dag_next_dagruns(self, dag_models: Iterable[DagModel], session: Session) -> None:
+    def _start_queued_dagruns(
+        self,
+        session: Session,
+    ) -> int:
         """
-        Bulk update the next_dagrun and next_dagrun_create_after for all the dags.
+        Find DagRuns in queued state and decide moving them to running state

-        We batch the select queries to get info about all the dags at once
+        :param dag_run: The DagRun to schedule
         """
-        # Check max_active_runs, to see if we are _now_ at the limit for any of
-        # these dag? (we've just created a DagRun for them after all)
-        active_runs_of_dags = dict(
+        dag_runs = self._get_next_dagruns_to_examine(State.QUEUED, session)
+
+        active_runs_of_dags = defaultdict(
+            lambda: 0,
             session.query(DagRun.dag_id, func.count('*'))
-            .filter(
-                DagRun.dag_id.in_([o.dag_id for o in dag_models]),
+            .filter(  # We use `list` here because SQLA doesn't accept a set
+                DagRun.dag_id.in_(list({dr.dag_id for dr in dag_runs})),

Review comment:
       I will update the comment


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@airflow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org