You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@zeppelin.apache.org by zj...@apache.org on 2020/04/21 07:22:17 UTC
[zeppelin] branch branch-0.9 updated: [ZEPPELIN-4717]. Support
savepoint for insert statement and non-sql paragraph
This is an automated email from the ASF dual-hosted git repository.
zjffdu pushed a commit to branch branch-0.9
in repository https://gitbox.apache.org/repos/asf/zeppelin.git
The following commit(s) were added to refs/heads/branch-0.9 by this push:
new 3cf32a0 [ZEPPELIN-4717]. Support savepoint for insert statement and non-sql paragraph
3cf32a0 is described below
commit 3cf32a093fc5712f6ec626be5b0fdfcd84983838
Author: Jeff Zhang <zj...@apache.org>
AuthorDate: Thu Apr 2 11:43:38 2020 +0800
[ZEPPELIN-4717]. Support savepoint for insert statement and non-sql paragraph
### What is this PR for?
This PR is to support setting savepoint for flink job and resume job from savepoint. It works for both flink sql and flink table api.
### What type of PR is it?
[Bug Fix | Improvement | Feature | Documentation | Hot Fix | Refactoring]
### Todos
* [ ] - Task
### What is the Jira issue?
* https://issues.apache.org/jira/browse/ZEPPELIN-4717
### How should this be tested?
Unit test is added
### Screenshots (if appropriate)
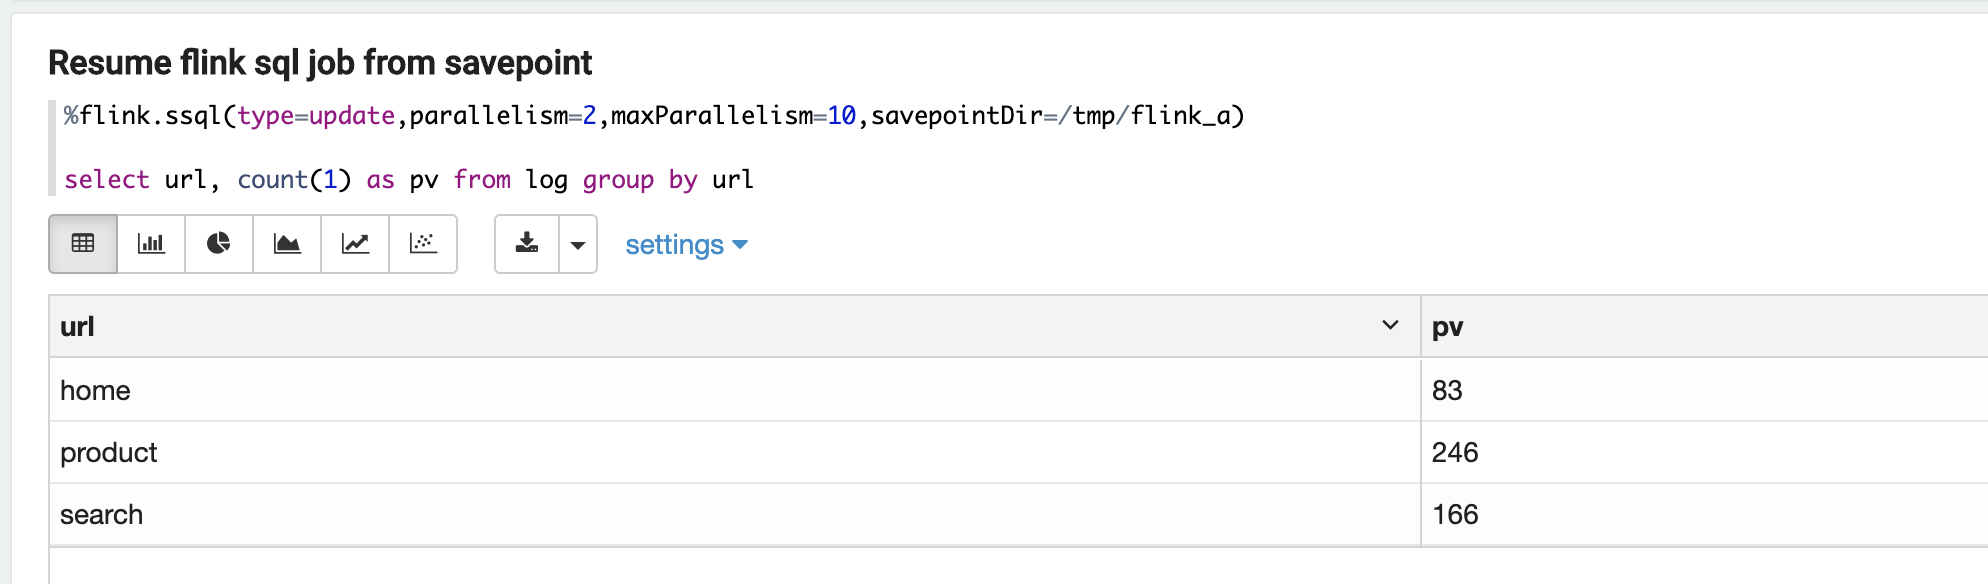
### Questions:
* Does the licenses files need update? No
* Is there breaking changes for older versions? No
* Does this needs documentation? No
Author: Jeff Zhang <zj...@apache.org>
Closes #3717 from zjffdu/ZEPPELIN-4717 and squashes the following commits:
4db897bb5 [Jeff Zhang] [ZEPPELIN-4717]. Support savepoint for insert statement and non-sql paragraph
(cherry picked from commit d340867ae31b2605c3f0c8644ebee19ebeaf54bb)
Signed-off-by: Jeff Zhang <zj...@apache.org>
---
flink/pom.xml | 7 +
.../zeppelin/flink/FlinkBatchSqlInterpreter.java | 3 +-
.../apache/zeppelin/flink/FlinkInterpreter.java | 15 ++
.../apache/zeppelin/flink/FlinkSqlInterrpeter.java | 161 +++++++++------------
.../zeppelin/flink/FlinkStreamSqlInterpreter.java | 25 +---
.../apache/zeppelin/flink/IPyFlinkInterpreter.java | 4 +-
.../java/org/apache/zeppelin/flink/JobManager.java | 20 ++-
.../apache/zeppelin/flink/PyFlinkInterpreter.java | 29 ++--
.../zeppelin/flink/sql/AbstractStreamSqlJob.java | 13 +-
.../zeppelin/flink/sql/AppendStreamSqlJob.java | 4 +-
.../zeppelin/flink/sql/UpdateStreamSqlJob.java | 2 +-
.../zeppelin/flink/FlinkScalaInterpreter.scala | 40 ++++-
.../flink/FlinkBatchSqlInterpreterTest.java | 4 +-
.../zeppelin/flink/FlinkInterpreterTest.java | 122 +++++++++++++++-
.../flink/FlinkStreamSqlInterpreterTest.java | 125 ++++++++++++++--
.../zeppelin/flink/IPyFlinkInterpreterTest.java | 160 +++++++++++++++++---
.../zeppelin/flink/PyFlinkInterpreterTest.java | 60 +++-----
.../apache/zeppelin/flink/SqlInterpreterTest.java | 10 +-
flink/src/test/resources/init_stream.scala | 9 +-
flink/src/test/resources/log4j.properties | 1 +
flink/src/test/resources/log4j2.properties | 64 --------
.../zeppelin/interpreter/InterpreterOutput.java | 9 ++
22 files changed, 605 insertions(+), 282 deletions(-)
diff --git a/flink/pom.xml b/flink/pom.xml
index d74c0d9..69f0b32 100644
--- a/flink/pom.xml
+++ b/flink/pom.xml
@@ -546,6 +546,13 @@
</exclusions>
</dependency>
+ <dependency>
+ <groupId>net.jodah</groupId>
+ <artifactId>concurrentunit</artifactId>
+ <version>0.4.4</version>
+ <scope>test</scope>
+ </dependency>
+
</dependencies>
<build>
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreter.java b/flink/src/main/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreter.java
index ba5319c..dab4524 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreter.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreter.java
@@ -44,7 +44,6 @@ public class FlinkBatchSqlInterpreter extends FlinkSqlInterrpeter {
public void open() throws InterpreterException {
super.open();
this.tbenv = flinkInterpreter.getJavaBatchTableEnvironment("blink");
- this.tbenv_2 = flinkInterpreter.getJavaBatchTableEnvironment("flink");
this.z = flinkInterpreter.getZeppelinContext();
}
@@ -63,7 +62,7 @@ public class FlinkBatchSqlInterpreter extends FlinkSqlInterrpeter {
@Override
public void cancel(InterpreterContext context) throws InterpreterException {
- flinkInterpreter.getJobManager().cancelJob(context);
+ flinkInterpreter.cancel(context);
}
@Override
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/FlinkInterpreter.java b/flink/src/main/java/org/apache/zeppelin/flink/FlinkInterpreter.java
index a9afc1d..4565fc0 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/FlinkInterpreter.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/FlinkInterpreter.java
@@ -17,10 +17,13 @@
package org.apache.zeppelin.flink;
+import org.apache.commons.lang3.StringUtils;
import org.apache.flink.api.scala.ExecutionEnvironment;
import org.apache.flink.configuration.Configuration;
+import org.apache.flink.runtime.jobgraph.SavepointConfigOptions;
import org.apache.flink.streaming.api.scala.StreamExecutionEnvironment;
import org.apache.flink.table.api.TableEnvironment;
+import org.apache.flink.table.api.config.ExecutionConfigOptions;
import org.apache.flink.table.api.scala.StreamTableEnvironment;
import org.apache.zeppelin.interpreter.Interpreter;
import org.apache.zeppelin.interpreter.InterpreterContext;
@@ -72,6 +75,9 @@ public class FlinkInterpreter extends Interpreter {
ClassLoader originClassLoader = Thread.currentThread().getContextClassLoader();
try {
Thread.currentThread().setContextClassLoader(getFlinkScalaShellLoader());
+ createPlannerAgain();
+ setParallelismIfNecessary(context);
+ setSavePointIfNecessary(context);
return innerIntp.interpret(st, context);
} finally {
Thread.currentThread().setContextClassLoader(originClassLoader);
@@ -159,4 +165,13 @@ public class FlinkInterpreter extends Interpreter {
public FlinkScalaInterpreter getInnerIntp() {
return this.innerIntp;
}
+
+ public void setSavePointIfNecessary(InterpreterContext context) {
+ this.innerIntp.setSavePointIfNecessary(context);
+ }
+
+ public void setParallelismIfNecessary(InterpreterContext context) {
+ this.innerIntp.setParallelismIfNecessary(context);
+ }
+
}
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/FlinkSqlInterrpeter.java b/flink/src/main/java/org/apache/zeppelin/flink/FlinkSqlInterrpeter.java
index 2a5c2d9..2332704 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/FlinkSqlInterrpeter.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/FlinkSqlInterrpeter.java
@@ -26,7 +26,6 @@ import org.apache.flink.api.common.JobExecutionResult;
import org.apache.flink.configuration.ConfigOption;
import org.apache.flink.core.execution.JobClient;
import org.apache.flink.core.execution.JobListener;
-import org.apache.flink.python.PythonConfig;
import org.apache.flink.python.PythonOptions;
import org.apache.flink.table.api.Table;
import org.apache.flink.table.api.TableEnvironment;
@@ -88,15 +87,15 @@ public abstract class FlinkSqlInterrpeter extends Interpreter {
protected FlinkInterpreter flinkInterpreter;
protected TableEnvironment tbenv;
- protected TableEnvironment tbenv_2;
private SqlSplitter sqlSplitter;
private int defaultSqlParallelism;
private ReentrantReadWriteLock.WriteLock lock = new ReentrantReadWriteLock().writeLock();
// all the available sql config options. see
// https://ci.apache.org/projects/flink/flink-docs-release-1.10/dev/table/config.html
private Map<String, ConfigOption> tableConfigOptions;
- // represent the current paragraph's configOptions
- private Map<String, String> currentConfigOptions = new HashMap<>();
+ // represent paragraph's tableConfig
+ // paragraphId --> tableConfig
+ private Map<String, Map<String, String>> paragraphTableConfigMap = new HashMap<>();
public FlinkSqlInterrpeter(Properties properties) {
super(properties);
@@ -167,6 +166,8 @@ public abstract class FlinkSqlInterrpeter extends Interpreter {
ClassLoader originClassLoader = Thread.currentThread().getContextClassLoader();
try {
Thread.currentThread().setContextClassLoader(flinkInterpreter.getFlinkScalaShellLoader());
+ flinkInterpreter.setParallelismIfNecessary(context);
+ flinkInterpreter.setSavePointIfNecessary(context);
return runSqlList(st, context);
} finally {
Thread.currentThread().setContextClassLoader(originClassLoader);
@@ -174,58 +175,69 @@ public abstract class FlinkSqlInterrpeter extends Interpreter {
}
private InterpreterResult runSqlList(String st, InterpreterContext context) {
- currentConfigOptions.clear();
- List<String> sqls = sqlSplitter.splitSql(st);
- for (String sql : sqls) {
- Optional<SqlCommandParser.SqlCommandCall> sqlCommand = SqlCommandParser.parse(sql);
- if (!sqlCommand.isPresent()) {
- try {
- context.out.write("%text Invalid Sql statement: " + sql + "\n");
- context.out.write(MESSAGE_HELP.toString());
- } catch (IOException e) {
- return new InterpreterResult(InterpreterResult.Code.ERROR, e.toString());
+ // clear current paragraph's tableConfig before running any sql statements
+ Map<String, String> tableConfig = paragraphTableConfigMap.getOrDefault(context.getParagraphId(), new HashMap<>());
+ tableConfig.clear();
+ paragraphTableConfigMap.put(context.getParagraphId(), tableConfig);
+
+ try {
+ List<String> sqls = sqlSplitter.splitSql(st);
+ for (String sql : sqls) {
+ Optional<SqlCommandParser.SqlCommandCall> sqlCommand = SqlCommandParser.parse(sql);
+ if (!sqlCommand.isPresent()) {
+ try {
+ context.out.write("%text Invalid Sql statement: " + sql + "\n");
+ context.out.write(MESSAGE_HELP.toString());
+ } catch (IOException e) {
+ return new InterpreterResult(InterpreterResult.Code.ERROR, e.toString());
+ }
+ return new InterpreterResult(InterpreterResult.Code.ERROR);
}
- return new InterpreterResult(InterpreterResult.Code.ERROR);
- }
- try {
- callCommand(sqlCommand.get(), context);
- context.out.flush();
- } catch (Throwable e) {
- LOGGER.error("Fail to run sql:" + sql, e);
try {
- context.out.write("%text Fail to run sql command: " +
- sql + "\n" + ExceptionUtils.getStackTrace(e) + "\n");
- } catch (IOException ex) {
- LOGGER.warn("Unexpected exception:", ex);
- return new InterpreterResult(InterpreterResult.Code.ERROR,
- ExceptionUtils.getStackTrace(e));
+ callCommand(sqlCommand.get(), context);
+ context.out.flush();
+ } catch (Throwable e) {
+ LOGGER.error("Fail to run sql:" + sql, e);
+ try {
+ context.out.write("%text Fail to run sql command: " +
+ sql + "\n" + ExceptionUtils.getStackTrace(e) + "\n");
+ } catch (IOException ex) {
+ LOGGER.warn("Unexpected exception:", ex);
+ return new InterpreterResult(InterpreterResult.Code.ERROR,
+ ExceptionUtils.getStackTrace(e));
+ }
+ return new InterpreterResult(InterpreterResult.Code.ERROR);
}
- return new InterpreterResult(InterpreterResult.Code.ERROR);
}
- }
- boolean runAsOne = Boolean.parseBoolean(context.getStringLocalProperty("runAsOne", "false"));
- if (runAsOne) {
- try {
- lock.lock();
- if (context.getLocalProperties().containsKey("parallelism")) {
- this.tbenv.getConfig().getConfiguration()
- .set(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM,
- Integer.parseInt(context.getLocalProperties().get("parallelism")));
+ boolean runAsOne = Boolean.parseBoolean(context.getStringLocalProperty("runAsOne", "false"));
+ if (runAsOne) {
+ try {
+ lock.lock();
+ this.tbenv.execute(st);
+ context.out.write("Insertion successfully.\n");
+ } catch (Exception e) {
+ LOGGER.error("Fail to execute sql as one job", e);
+ return new InterpreterResult(InterpreterResult.Code.ERROR, ExceptionUtils.getStackTrace(e));
+ } finally {
+ if (lock.isHeldByCurrentThread()) {
+ lock.unlock();
+ }
}
- this.tbenv.execute(st);
- context.out.write("Insertion successfully.\n");
- } catch (Exception e) {
- LOGGER.error("Fail to execute sql as one job", e);
- return new InterpreterResult(InterpreterResult.Code.ERROR, ExceptionUtils.getStackTrace(e));
- } finally {
- if (lock.isHeldByCurrentThread()) {
- lock.unlock();
+ }
+ } finally {
+ // reset parallelism
+ this.tbenv.getConfig().getConfiguration()
+ .set(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM,
+ defaultSqlParallelism);
+ // reset table config
+ for (ConfigOption configOption: tableConfigOptions.values()) {
+ // some may has no default value, e.g. ExecutionConfigOptions#TABLE_EXEC_DISABLED_OPERATORS
+ if (configOption.defaultValue() != null) {
+ this.tbenv.getConfig().getConfiguration().set(configOption, configOption.defaultValue());
}
- this.tbenv.getConfig().getConfiguration()
- .set(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM,
- defaultSqlParallelism);
}
+ this.tbenv.getConfig().getConfiguration().addAll(flinkInterpreter.getFlinkConfiguration());
}
return new InterpreterResult(InterpreterResult.Code.SUCCESS);
@@ -466,34 +478,17 @@ public abstract class FlinkSqlInterrpeter extends Interpreter {
public void callSelect(String sql, InterpreterContext context) throws IOException {
try {
lock.lock();
- // set parallelism from paragraph local property
- if (context.getLocalProperties().containsKey("parallelism")) {
- this.tbenv.getConfig().getConfiguration()
- .set(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM,
- Integer.parseInt(context.getLocalProperties().get("parallelism")));
- }
-
// set table config from set statement until now.
- for (Map.Entry<String, String> entry : currentConfigOptions.entrySet()) {
+ Map<String, String> paragraphTableConfig = paragraphTableConfigMap.get(context.getParagraphId());
+ for (Map.Entry<String, String> entry : paragraphTableConfig.entrySet()) {
this.tbenv.getConfig().getConfiguration().setString(entry.getKey(), entry.getValue());
}
+
callInnerSelect(sql, context);
} finally {
if (lock.isHeldByCurrentThread()) {
lock.unlock();
}
- // reset parallelism
- this.tbenv.getConfig().getConfiguration()
- .set(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM,
- defaultSqlParallelism);
- // reset table config
- for (ConfigOption configOption: tableConfigOptions.values()) {
- // some may has no default value, e.g. ExecutionConfigOptions#TABLE_EXEC_DISABLED_OPERATORS
- if (configOption.defaultValue() != null) {
- this.tbenv.getConfig().getConfiguration().set(configOption, configOption.defaultValue());
- }
- }
- this.tbenv.getConfig().getConfiguration().addAll(flinkInterpreter.getFlinkConfiguration());
}
}
@@ -504,24 +499,20 @@ public abstract class FlinkSqlInterrpeter extends Interpreter {
throw new IOException(key + " is not a valid table/sql config, please check link: " +
"https://ci.apache.org/projects/flink/flink-docs-release-1.10/dev/table/config.html");
}
- currentConfigOptions.put(key, value);
+ paragraphTableConfigMap.get(context.getParagraphId()).put(key, value);
}
- private void callInsertInto(String sql,
+ public void callInsertInto(String sql,
InterpreterContext context) throws IOException {
if (!isBatch()) {
context.getLocalProperties().put("flink.streaming.insert_into", "true");
}
try {
lock.lock();
- if (context.getLocalProperties().containsKey("parallelism")) {
- this.tbenv.getConfig().getConfiguration()
- .set(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM,
- Integer.parseInt(context.getLocalProperties().get("parallelism")));
- }
// set table config from set statement until now.
- for (Map.Entry<String, String> entry : currentConfigOptions.entrySet()) {
+ Map<String, String> paragraphTableConfig = paragraphTableConfigMap.get(context.getParagraphId());
+ for (Map.Entry<String, String> entry : paragraphTableConfig.entrySet()) {
this.tbenv.getConfig().getConfiguration().setString(entry.getKey(), entry.getValue());
}
@@ -537,22 +528,14 @@ public abstract class FlinkSqlInterrpeter extends Interpreter {
if (lock.isHeldByCurrentThread()) {
lock.unlock();
}
-
- // reset parallelism
- this.tbenv.getConfig().getConfiguration()
- .set(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM,
- defaultSqlParallelism);
- // reset table config
- for (ConfigOption configOption: tableConfigOptions.values()) {
- // some may has no default value, e.g. ExecutionConfigOptions#TABLE_EXEC_DISABLED_OPERATORS
- if (configOption.defaultValue() != null) {
- this.tbenv.getConfig().getConfiguration().set(configOption, configOption.defaultValue());
- }
- }
- this.tbenv.getConfig().getConfiguration().addAll(flinkInterpreter.getFlinkConfiguration());
}
}
+ @Override
+ public void cancel(InterpreterContext context) throws InterpreterException {
+ this.flinkInterpreter.cancel(context);
+ }
+
private static AttributedString formatCommand(SqlCommand cmd, String description) {
return new AttributedStringBuilder()
.style(AttributedStyle.DEFAULT.bold())
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreter.java b/flink/src/main/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreter.java
index 9c3d266..f4d2319 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreter.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreter.java
@@ -19,6 +19,7 @@
package org.apache.zeppelin.flink;
import org.apache.commons.lang3.StringUtils;
+import org.apache.flink.runtime.jobgraph.SavepointConfigOptions;
import org.apache.flink.table.api.config.ExecutionConfigOptions;
import org.apache.zeppelin.flink.sql.UpdateStreamSqlJob;
import org.apache.zeppelin.flink.sql.SingleRowStreamSqlJob;
@@ -47,7 +48,6 @@ public class FlinkStreamSqlInterpreter extends FlinkSqlInterrpeter {
public void open() throws InterpreterException {
super.open();
this.tbenv = flinkInterpreter.getJavaStreamTableEnvironment("blink");
- this.tbenv_2 = flinkInterpreter.getJavaStreamTableEnvironment("flink");
}
@Override
@@ -57,18 +57,8 @@ public class FlinkStreamSqlInterpreter extends FlinkSqlInterrpeter {
@Override
public void callInnerSelect(String sql, InterpreterContext context) throws IOException {
- String savepointDir = context.getLocalProperties().get("savepointDir");
- if (!StringUtils.isBlank(savepointDir)) {
- Object savepointPath = flinkInterpreter.getZeppelinContext()
- .angular(context.getParagraphId() + "_savepointpath", context.getNoteId(), null);
- if (savepointPath == null) {
- LOGGER.info("savepointPath is null because it is the first run");
- } else {
- LOGGER.info("set savepointPath to: " + savepointPath.toString());
- this.flinkInterpreter.getFlinkConfiguration()
- .setString("execution.savepoint.path", savepointPath.toString());
- }
- }
+ flinkInterpreter.setSavePointIfNecessary(context);
+ flinkInterpreter.setParallelismIfNecessary(context);
String streamType = context.getLocalProperties().get("type");
if (streamType == null) {
@@ -104,11 +94,12 @@ public class FlinkStreamSqlInterpreter extends FlinkSqlInterrpeter {
}
@Override
+ public void callInsertInto(String sql, InterpreterContext context) throws IOException {
+ super.callInsertInto(sql, context);
+ }
+
public void cancel(InterpreterContext context) throws InterpreterException {
- this.flinkInterpreter.getZeppelinContext().setInterpreterContext(context);
- this.flinkInterpreter.getZeppelinContext().setNoteGui(context.getNoteGui());
- this.flinkInterpreter.getZeppelinContext().setGui(context.getGui());
- this.flinkInterpreter.getJobManager().cancelJob(context);
+ this.flinkInterpreter.cancel(context);
}
@Override
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/IPyFlinkInterpreter.java b/flink/src/main/java/org/apache/zeppelin/flink/IPyFlinkInterpreter.java
index 5564a57..7ffafb2 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/IPyFlinkInterpreter.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/IPyFlinkInterpreter.java
@@ -89,6 +89,8 @@ public class IPyFlinkInterpreter extends IPythonInterpreter {
throw new InterpreterException("Fail to initJavaThread: " +
result.toString());
}
+ flinkInterpreter.setSavePointIfNecessary(context);
+ flinkInterpreter.setParallelismIfNecessary(context);
return super.internalInterpret(st, context);
} finally {
if (getKernelProcessLauncher().isRunning()) {
@@ -103,8 +105,8 @@ public class IPyFlinkInterpreter extends IPythonInterpreter {
@Override
public void cancel(InterpreterContext context) throws InterpreterException {
- super.cancel(context);
flinkInterpreter.cancel(context);
+ super.cancel(context);
}
@Override
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/JobManager.java b/flink/src/main/java/org/apache/zeppelin/flink/JobManager.java
index 480f6bb..bb044c3 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/JobManager.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/JobManager.java
@@ -74,6 +74,7 @@ public class JobManager {
FlinkJobProgressPoller jobProgressPoller =
this.jobProgressPollerMap.remove(jobClient.getJobID());
jobProgressPoller.cancel();
+ jobProgressPoller.interrupt();
}
public void sendFlinkJobUrl(InterpreterContext context) {
@@ -86,7 +87,6 @@ public class JobManager {
infos.put("tooltip", "View in Flink web UI");
infos.put("noteId", context.getNoteId());
infos.put("paraId", context.getParagraphId());
- LOGGER.info("Job is started at: " + jobUrl);
context.getIntpEventClient().onParaInfosReceived(infos);
} else {
LOGGER.warn("No job is associated with paragraph: " + context.getParagraphId());
@@ -110,7 +110,8 @@ public class JobManager {
}
public void cancelJob(InterpreterContext context) throws InterpreterException {
- JobClient jobClient = this.jobs.remove(context.getParagraphId());
+ LOGGER.info("Canceling job associated of paragraph: "+ context.getParagraphId());
+ JobClient jobClient = this.jobs.get(context.getParagraphId());
if (jobClient == null) {
LOGGER.warn("Unable to remove Job from paragraph {} as no job associated to this paragraph",
context.getParagraphId());
@@ -125,19 +126,24 @@ public class JobManager {
} else {
LOGGER.info("Trying to stop job of paragraph {} with save point dir: {}",
context.getParagraphId(), savepointDir);
- String savePointPath = jobClient.stopWithSavepoint(false, savepointDir).get();
+ String savePointPath = jobClient.stopWithSavepoint(true, savepointDir).get();
z.angularBind(context.getParagraphId() + "_savepointpath", savePointPath);
+ LOGGER.info("Job {} of paragraph {} is stopped with save point path: {}",
+ jobClient.getJobID(), context.getParagraphId(), savePointPath);
}
} catch (Exception e) {
String errorMessage = String.format("Fail to cancel job %s that is associated " +
"with paragraph %s", jobClient.getJobID(), context.getParagraphId());
LOGGER.warn(errorMessage, e);
throw new InterpreterException(errorMessage, e);
+ } finally {
+ FlinkJobProgressPoller jobProgressPoller = jobProgressPollerMap.remove(jobClient.getJobID());
+ if (jobProgressPoller != null) {
+ jobProgressPoller.cancel();
+ jobProgressPoller.interrupt();
+ }
+ this.jobs.remove(context.getParagraphId());
}
-
- FlinkJobProgressPoller jobProgressPoller = jobProgressPollerMap.remove(jobClient.getJobID());
- jobProgressPoller.cancel();
- jobProgressPoller.interrupt();
}
public void shutdown() {
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/PyFlinkInterpreter.java b/flink/src/main/java/org/apache/zeppelin/flink/PyFlinkInterpreter.java
index eaebd64..ace08cb 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/PyFlinkInterpreter.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/PyFlinkInterpreter.java
@@ -105,18 +105,21 @@ public class PyFlinkInterpreter extends PythonInterpreter {
@Override
public InterpreterResult interpret(String st, InterpreterContext context) throws InterpreterException {
try {
- if (isOpened) {
- // set InterpreterContext in the python thread first, otherwise flink job could not be
- // associated with paragraph in JobListener
- this.curInterpreterContext = context;
- InterpreterResult result =
- super.interpret("intp.initJavaThread()", context);
- if (result.code() != InterpreterResult.Code.SUCCESS) {
- throw new InterpreterException("Fail to initJavaThread: " +
- result.toString());
+ if (!useIPython()) {
+ if (isOpened) {
+ // set InterpreterContext in the python thread first, otherwise flink job could not be
+ // associated with paragraph in JobListener
+ this.curInterpreterContext = context;
+ InterpreterResult result =
+ super.interpret("intp.initJavaThread()", context);
+ if (result.code() != InterpreterResult.Code.SUCCESS) {
+ throw new InterpreterException("Fail to initJavaThread: " +
+ result.toString());
+ }
}
+ flinkInterpreter.setSavePointIfNecessary(context);
+ flinkInterpreter.setParallelismIfNecessary(context);
}
- flinkInterpreter.createPlannerAgain();
return super.interpret(st, context);
} finally {
if (useIPython() || (!useIPython() && getPythonProcessLauncher().isRunning())) {
@@ -149,8 +152,12 @@ public class PyFlinkInterpreter extends PythonInterpreter {
@Override
public void cancel(InterpreterContext context) throws InterpreterException {
- super.cancel(context);
flinkInterpreter.cancel(context);
+ if (useIPython()) {
+ // only cancel it in the case of ipython, because python interpreter will
+ // kill the current python process which usually is not what user expect.
+ super.cancel(context);
+ }
}
@Override
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/sql/AbstractStreamSqlJob.java b/flink/src/main/java/org/apache/zeppelin/flink/sql/AbstractStreamSqlJob.java
index f293fad..fd47175 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/sql/AbstractStreamSqlJob.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/sql/AbstractStreamSqlJob.java
@@ -95,13 +95,13 @@ public abstract class AbstractStreamSqlJob {
protected abstract String getType();
- public InterpreterResult run(String st) throws IOException {
+ public String run(String st) throws IOException {
Table table = stenv.sqlQuery(st);
String tableName = "UnnamedTable_" + st + "_" + SQL_INDEX.getAndIncrement();
return run(table, tableName);
}
- public InterpreterResult run(Table table, String tableName) throws IOException {
+ public String run(Table table, String tableName) throws IOException {
try {
int parallelism = Integer.parseInt(context.getLocalProperties()
.getOrDefault("parallelism", defaultParallelism + ""));
@@ -151,16 +151,16 @@ public abstract class AbstractStreamSqlJob {
ResultRetrievalThread retrievalThread = new ResultRetrievalThread(refreshScheduler);
retrievalThread.start();
- LOGGER.info("Run job without savePointPath, " + ", parallelism: " + parallelism);
+ LOGGER.info("Run job: " + tableName + ", parallelism: " + parallelism);
stenv.execute(tableName);
- LOGGER.info("Flink Job is finished");
+ LOGGER.info("Flink Job is finished, tableName: " + tableName);
// wait for retrieve thread consume all data
LOGGER.info("Waiting for retrieve thread to be done");
retrievalThread.join();
refresh(context);
String finalResult = buildResult();
LOGGER.info("Final Result: " + finalResult);
- return new InterpreterResult(InterpreterResult.Code.SUCCESS, finalResult);
+ return finalResult;
} catch (Exception e) {
LOGGER.error("Fail to run stream sql job", e);
throw new IOException("Fail to run stream sql job", e);
@@ -207,7 +207,7 @@ public abstract class AbstractStreamSqlJob {
final Tuple2<Boolean, Row> change = iterator.next();
processRecord(change);
}
- } catch (Exception e) {
+ } catch (Throwable e) {
// ignore socket exceptions
LOGGER.error("Fail to process record", e);
}
@@ -242,6 +242,7 @@ public abstract class AbstractStreamSqlJob {
if (!enableToRefresh) {
resultLock.wait();
}
+ LOGGER.info("Refresh result of paragraph: " + context.getParagraphId());
refresh(context);
}
} catch (Exception e) {
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/sql/AppendStreamSqlJob.java b/flink/src/main/java/org/apache/zeppelin/flink/sql/AppendStreamSqlJob.java
index 25b2064..fea0841 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/sql/AppendStreamSqlJob.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/sql/AppendStreamSqlJob.java
@@ -125,8 +125,10 @@ public class AppendStreamSqlJob extends AbstractStreamSqlJob {
context.out().clear();
try {
jobManager.sendFlinkJobUrl(context);
- context.out.write(buildResult());
+ String result = buildResult();
+ context.out.write(result);
context.out.flush();
+ LOGGER.debug("Refresh with data: " + result);
} catch (IOException e) {
LOGGER.error("Fail to refresh data", e);
}
diff --git a/flink/src/main/java/org/apache/zeppelin/flink/sql/UpdateStreamSqlJob.java b/flink/src/main/java/org/apache/zeppelin/flink/sql/UpdateStreamSqlJob.java
index bfcbce7..9c69616 100644
--- a/flink/src/main/java/org/apache/zeppelin/flink/sql/UpdateStreamSqlJob.java
+++ b/flink/src/main/java/org/apache/zeppelin/flink/sql/UpdateStreamSqlJob.java
@@ -108,9 +108,9 @@ public class UpdateStreamSqlJob extends AbstractStreamSqlJob {
try {
jobManager.sendFlinkJobUrl(context);
String result = buildResult();
- LOGGER.debug(("Refresh with data: " + result));
context.out.write(result);
context.out.flush();
+ LOGGER.debug("Refresh with data: " + result);
this.lastSnapshot.clear();
for (Row row : materializedTable) {
this.lastSnapshot.add(row);
diff --git a/flink/src/main/scala/org/apache/zeppelin/flink/FlinkScalaInterpreter.scala b/flink/src/main/scala/org/apache/zeppelin/flink/FlinkScalaInterpreter.scala
index b45637c..6e69629 100644
--- a/flink/src/main/scala/org/apache/zeppelin/flink/FlinkScalaInterpreter.scala
+++ b/flink/src/main/scala/org/apache/zeppelin/flink/FlinkScalaInterpreter.scala
@@ -35,6 +35,7 @@ import org.apache.flink.core.execution.{JobClient, JobListener}
import org.apache.flink.streaming.api.TimeCharacteristic
import org.apache.flink.streaming.api.environment.{StreamExecutionEnvironmentFactory, StreamExecutionEnvironment => JStreamExecutionEnvironment}
import org.apache.flink.api.java.{ExecutionEnvironmentFactory, ExecutionEnvironment => JExecutionEnvironment}
+import org.apache.flink.runtime.jobgraph.SavepointConfigOptions
import org.apache.flink.streaming.api.scala.StreamExecutionEnvironment
import org.apache.flink.table.api.config.ExecutionConfigOptions
import org.apache.flink.table.api.java.internal.StreamTableEnvironmentImpl
@@ -410,7 +411,7 @@ class FlinkScalaInterpreter(val properties: Properties) {
this.benv.registerJobListener(jobListener)
this.senv.registerJobListener(jobListener)
- //register hive catalog
+ // register hive catalog
if (properties.getProperty("zeppelin.flink.enableHive", "false").toBoolean) {
LOGGER.info("Hive is enabled, registering hive catalog.")
val hiveConfDir =
@@ -564,7 +565,6 @@ class FlinkScalaInterpreter(val properties: Properties) {
}
def interpret(code: String, context: InterpreterContext): InterpreterResult = {
- createPlannerAgain()
val originalStdOut = System.out
val originalStdErr = System.err;
if (context != null) {
@@ -614,6 +614,42 @@ class FlinkScalaInterpreter(val properties: Properties) {
}
}
+ def setSavePointIfNecessary(context: InterpreterContext): Unit = {
+ val savepointDir = context.getLocalProperties.get("savepointDir")
+ if (!StringUtils.isBlank(savepointDir)) {
+ val savepointPath = z.angular(context.getParagraphId + "_savepointpath", context.getNoteId, null)
+ if (savepointPath == null) {
+ LOGGER.info("savepointPath is null because it is the first run")
+ // remove the SAVEPOINT_PATH which may be set by last job.
+ configuration.removeConfig(SavepointConfigOptions.SAVEPOINT_PATH)
+ } else {
+ LOGGER.info("Set savepointPath to: " + savepointPath.toString)
+ configuration.setString("execution.savepoint.path", savepointPath.toString)
+ }
+ } else {
+ // remove the SAVEPOINT_PATH which may be set by last job.
+ configuration.removeConfig(SavepointConfigOptions.SAVEPOINT_PATH)
+ }
+ }
+
+ def setParallelismIfNecessary(context: InterpreterContext): Unit = {
+ val parallelismStr = context.getLocalProperties.get("parallelism")
+ if (!StringUtils.isBlank(parallelismStr)) {
+ val parallelism = parallelismStr.toInt
+ this.senv.setParallelism(parallelism)
+ this.benv.setParallelism(parallelism)
+ this.stenv.getConfig.getConfiguration
+ .setString(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM.key(), parallelism + "")
+ this.btenv.getConfig.getConfiguration
+ .setString(ExecutionConfigOptions.TABLE_EXEC_RESOURCE_DEFAULT_PARALLELISM.key(), parallelism + "")
+ }
+ val maxParallelismStr = context.getLocalProperties.get("maxParallelism")
+ if (!StringUtils.isBlank(maxParallelismStr)) {
+ val maxParallelism = maxParallelismStr.toInt
+ senv.setParallelism(maxParallelism)
+ }
+ }
+
def cancel(context: InterpreterContext): Unit = {
jobManager.cancelJob(context)
}
diff --git a/flink/src/test/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreterTest.java b/flink/src/test/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreterTest.java
index 3a34273..19dedfa 100644
--- a/flink/src/test/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreterTest.java
+++ b/flink/src/test/java/org/apache/zeppelin/flink/FlinkBatchSqlInterpreterTest.java
@@ -84,7 +84,7 @@ public class FlinkBatchSqlInterpreterTest extends SqlInterpreterTest {
// select which use scala udf
context = getInterpreterContext();
result = sqlInterpreter.interpret("SELECT addOne(id) as add_one FROM source_table", context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
resultMessages = context.out.toInterpreterResultMessage();
assertEquals(1, resultMessages.size());
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
@@ -109,7 +109,7 @@ public class FlinkBatchSqlInterpreterTest extends SqlInterpreterTest {
// select which use python udf
context = getInterpreterContext();
result = sqlInterpreter.interpret("SELECT python_upper(name) as name FROM source_table", context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
resultMessages = context.out.toInterpreterResultMessage();
assertEquals(1, resultMessages.size());
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
diff --git a/flink/src/test/java/org/apache/zeppelin/flink/FlinkInterpreterTest.java b/flink/src/test/java/org/apache/zeppelin/flink/FlinkInterpreterTest.java
index 6a20aca..6136108 100644
--- a/flink/src/test/java/org/apache/zeppelin/flink/FlinkInterpreterTest.java
+++ b/flink/src/test/java/org/apache/zeppelin/flink/FlinkInterpreterTest.java
@@ -17,6 +17,9 @@
package org.apache.zeppelin.flink;
+import junit.framework.TestCase;
+import net.jodah.concurrentunit.Waiter;
+import org.apache.commons.io.FileUtils;
import org.apache.zeppelin.display.AngularObjectRegistry;
import org.apache.zeppelin.display.ui.CheckBox;
import org.apache.zeppelin.display.ui.Select;
@@ -32,11 +35,15 @@ import org.apache.zeppelin.interpreter.thrift.InterpreterCompletion;
import org.junit.After;
import org.junit.Before;
import org.junit.Test;
+import org.slf4j.Logger;
+import org.slf4j.LoggerFactory;
+import java.io.File;
import java.io.IOException;
import java.util.Arrays;
import java.util.List;
import java.util.Properties;
+import java.util.concurrent.TimeoutException;
import static org.junit.Assert.assertArrayEquals;
import static org.junit.Assert.assertEquals;
@@ -46,7 +53,10 @@ import static org.mockito.Mockito.mock;
public class FlinkInterpreterTest {
+ private static final Logger LOGGER = LoggerFactory.getLogger(FlinkInterpreterTest.class);
+
private FlinkInterpreter interpreter;
+ private AngularObjectRegistry angularObjectRegistry;
@Before
public void setUp() throws InterpreterException {
@@ -54,11 +64,14 @@ public class FlinkInterpreterTest {
p.setProperty("zeppelin.flink.printREPLOutput", "true");
p.setProperty("zeppelin.flink.scala.color", "false");
p.setProperty("flink.execution.mode", "local");
+ p.setProperty("local.number-taskmanager", "4");
interpreter = new FlinkInterpreter(p);
InterpreterGroup intpGroup = new InterpreterGroup();
interpreter.setInterpreterGroup(intpGroup);
interpreter.open();
+
+ angularObjectRegistry = new AngularObjectRegistry("flink", null);
}
@After
@@ -216,7 +229,7 @@ public class FlinkInterpreterTest {
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
context = getInterpreterContext();
result = interpreter.interpret("z.show(data)", context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
assertEquals("_1\t_2\n1\tjeff\n2\tandy\n3\tjames\n", resultMessages.get(0).getData());
@@ -285,12 +298,113 @@ public class FlinkInterpreterTest {
}
}
+ @Test
+ public void testCancelStreamSql() throws IOException, InterpreterException, InterruptedException, TimeoutException {
+ String initStreamScalaScript = FlinkStreamSqlInterpreterTest.getInitStreamScript(1000);
+ InterpreterResult result = interpreter.interpret(initStreamScalaScript,
+ getInterpreterContext());
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+
+ final Waiter waiter = new Waiter();
+ Thread thread = new Thread(() -> {
+ try {
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ InterpreterResult result2 = interpreter.interpret(
+ "val table = stenv.sqlQuery(\"select url, count(1) as pv from " +
+ "log group by url\")\nz.show(table, streamType=\"update\")", context);
+ LOGGER.info("---------------" + context.out.toString());
+ LOGGER.info("---------------" + result2);
+ waiter.assertTrue(context.out.toString().contains("Job was cancelled"));
+ waiter.assertEquals(InterpreterResult.Code.ERROR, result2.code());
+ } catch (Exception e) {
+ e.printStackTrace();
+ waiter.fail("Should not fail here");
+ }
+ waiter.resume();
+ });
+ thread.start();
+
+ // the streaming job will run for 20 seconds. check init_stream.scala
+ // sleep 10 seconds to make sure the job is started but not finished
+ Thread.sleep(10 * 1000);
+
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ interpreter.cancel(context);
+ waiter.await(10 * 1000);
+ // resume job
+ interpreter.interpret("val table = stenv.sqlQuery(\"select url, count(1) as pv from " +
+ "log group by url\")\nz.show(table, streamType=\"update\")", context);
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+ List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
+ assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
+ TestCase.assertTrue(resultMessages.toString(),
+ resultMessages.get(0).getData().contains("url\tpv\n"));
+ }
+
+ // TODO(zjffdu) flaky test
+ // @Test
+ public void testResumeStreamSqlFromSavePoint() throws IOException, InterpreterException, InterruptedException, TimeoutException {
+ String initStreamScalaScript = FlinkStreamSqlInterpreterTest.getInitStreamScript(1000);
+ InterpreterResult result = interpreter.interpret(initStreamScalaScript,
+ getInterpreterContext());
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+
+ File savePointDir = FileUtils.getTempDirectory();
+ final Waiter waiter = new Waiter();
+ Thread thread = new Thread(() -> {
+ try {
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ context.getLocalProperties().put("savepointDir", savePointDir.getAbsolutePath());
+ context.getLocalProperties().put("parallelism", "1");
+ context.getLocalProperties().put("maxParallelism", "10");
+ InterpreterResult result2 = interpreter.interpret(
+ "val table = stenv.sqlQuery(\"select url, count(1) as pv from " +
+ "log group by url\")\nz.show(table, streamType=\"update\")", context);
+ System.out.println("------------" + context.out.toString());
+ System.out.println("------------" + result2);
+ waiter.assertTrue(context.out.toString().contains("url\tpv\n"));
+ waiter.assertEquals(InterpreterResult.Code.SUCCESS, result2.code());
+ } catch (Exception e) {
+ e.printStackTrace();
+ waiter.fail("Should not fail here");
+ }
+ waiter.resume();
+ });
+ thread.start();
+
+ // the streaming job will run for 60 seconds. check init_stream.scala
+ // sleep 20 seconds to make sure the job is started but not finished
+ Thread.sleep(20 * 1000);
+
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ context.getLocalProperties().put("savepointDir", savePointDir.getAbsolutePath());
+ context.getLocalProperties().put("parallelism", "2");
+ context.getLocalProperties().put("maxParallelism", "10");
+ interpreter.cancel(context);
+ waiter.await(20 * 1000);
+ // resume job from savepoint
+ interpreter.interpret(
+ "val table = stenv.sqlQuery(\"select url, count(1) as pv from " +
+ "log group by url\")\nz.show(table, streamType=\"update\")", context);
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+ List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
+ assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
+ TestCase.assertTrue(resultMessages.toString(),
+ resultMessages.get(0).getData().contains("url\tpv\n"));
+ }
+
private InterpreterContext getInterpreterContext() {
- return InterpreterContext.builder()
+ InterpreterContext context = InterpreterContext.builder()
+ .setParagraphId("paragraphId")
.setInterpreterOut(new InterpreterOutput(null))
- .setAngularObjectRegistry(new AngularObjectRegistry("flink", null))
+ .setAngularObjectRegistry(angularObjectRegistry)
.setIntpEventClient(mock(RemoteInterpreterEventClient.class))
- .setInterpreterOut(new InterpreterOutput(null))
.build();
+ InterpreterContext.set(context);
+ return context;
}
}
diff --git a/flink/src/test/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreterTest.java b/flink/src/test/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreterTest.java
index 943906f..55f229a 100644
--- a/flink/src/test/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreterTest.java
+++ b/flink/src/test/java/org/apache/zeppelin/flink/FlinkStreamSqlInterpreterTest.java
@@ -17,6 +17,7 @@
*/
package org.apache.zeppelin.flink;
+import net.jodah.concurrentunit.Waiter;
import org.apache.commons.io.FileUtils;
import org.apache.commons.io.IOUtils;
import org.apache.zeppelin.interpreter.InterpreterContext;
@@ -30,6 +31,7 @@ import java.io.IOException;
import java.nio.file.Files;
import java.util.List;
import java.util.Properties;
+import java.util.concurrent.TimeoutException;
import static junit.framework.TestCase.assertTrue;
import static org.junit.Assert.assertEquals;
@@ -43,7 +45,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
@Test
public void testSingleStreamSql() throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(getClass().getResource("/init_stream.scala"));
+ String initStreamScalaScript = getInitStreamScript(100);
InterpreterContext context = getInterpreterContext();
InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript, context);
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -62,7 +64,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
@Test
public void testSingleStreamTableApi() throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(getClass().getResource("/init_stream.scala"));
+ String initStreamScalaScript = getInitStreamScript(100);
InterpreterContext context = getInterpreterContext();
InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript, context);
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -70,7 +72,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
context = getInterpreterContext();
String code = "val table = stenv.sqlQuery(\"select max(rowtime), count(1) from log\")\nz.show(table,streamType=\"single\", configs = Map(\"template\" -> \"Total Count: {1} <br/> {0}\"))";
result = flinkInterpreter.interpret(code, context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.HTML, resultMessages.get(0).getType());
assertTrue(resultMessages.toString(),
@@ -78,7 +80,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
context = getInterpreterContext();
result = sqlInterpreter.interpret("show tables", context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
assertEquals("table\nlog\n", resultMessages.get(0).getData());
@@ -86,7 +88,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
@Test
public void testUpdateStreamSql() throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(getClass().getResource("/init_stream.scala"));
+ String initStreamScalaScript = getInitStreamScript(100);
InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript,
getInterpreterContext());
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -104,7 +106,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
@Test
public void testUpdateStreamTableApi() throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(getClass().getResource("/init_stream.scala"));
+ String initStreamScalaScript = getInitStreamScript(100);
InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript,
getInterpreterContext());
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -112,7 +114,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
InterpreterContext context = getInterpreterContext();
String code = "val table = stenv.sqlQuery(\"select url, count(1) as pv from log group by url\")\nz.show(table, streamType=\"update\")";
result = flinkInterpreter.interpret(code, context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
assertTrue(resultMessages.toString(),
@@ -121,7 +123,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
@Test
public void testAppendStreamSql() throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(getClass().getResource("/init_stream.scala"));
+ String initStreamScalaScript = getInitStreamScript(100);
InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript,
getInterpreterContext());
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -140,7 +142,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
@Test
public void testAppendStreamTableApi() throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(getClass().getResource("/init_stream.scala"));
+ String initStreamScalaScript = getInitStreamScript(100);
InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript,
getInterpreterContext());
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -150,7 +152,101 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
"start_time, url, count(1) as pv from log group by " +
"TUMBLE(rowtime, INTERVAL '5' SECOND), url\")\nz.show(table, streamType=\"append\")";
result = flinkInterpreter.interpret(code, context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
+ List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
+ assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
+ assertTrue(resultMessages.toString(),
+ resultMessages.get(0).getData().contains("url\tpv\n"));
+ }
+
+ @Test
+ public void testCancelStreamSql() throws IOException, InterpreterException, InterruptedException, TimeoutException {
+ String initStreamScalaScript = getInitStreamScript(1000);
+ InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript,
+ getInterpreterContext());
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+
+ final Waiter waiter = new Waiter();
+ Thread thread = new Thread(() -> {
+ try {
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ InterpreterResult result2 = sqlInterpreter.interpret("select url, count(1) as pv from " +
+ "log group by url", context);
+ waiter.assertTrue(context.out.toString().contains("Job was cancelled"));
+ waiter.assertEquals(InterpreterResult.Code.ERROR, result2.code());
+ } catch (Exception e) {
+ e.printStackTrace();
+ waiter.fail("Should not fail here");
+ }
+ waiter.resume();
+ });
+ thread.start();
+
+ // the streaming job will run for 20 seconds. check init_stream.scala
+ // sleep 10 seconds to make sure the job is started but not finished
+ Thread.sleep(10 * 1000);
+
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ sqlInterpreter.cancel(context);
+ waiter.await(10 * 1000);
+ // resume job
+ sqlInterpreter.interpret("select url, count(1) as pv from " +
+ "log group by url", context);
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+ List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
+ assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
+ assertTrue(resultMessages.toString(),
+ resultMessages.get(0).getData().contains("url\tpv\n"));
+ }
+
+ // TODO(zjffdu) flaky test
+ // @Test
+ public void testResumeStreamSqlFromSavePoint() throws IOException, InterpreterException, InterruptedException, TimeoutException {
+ String initStreamScalaScript = getInitStreamScript(1000);
+ InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript,
+ getInterpreterContext());
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+
+ File savePointDir = FileUtils.getTempDirectory();
+ final Waiter waiter = new Waiter();
+ Thread thread = new Thread(() -> {
+ try {
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ context.getLocalProperties().put("savepointDir", savePointDir.getAbsolutePath());
+ context.getLocalProperties().put("parallelism", "1");
+ context.getLocalProperties().put("maxParallelism", "10");
+ InterpreterResult result2 = sqlInterpreter.interpret("select url, count(1) as pv from " +
+ "log group by url", context);
+ System.out.println("------------" + context.out.toString());
+ System.out.println("------------" + result2);
+ waiter.assertTrue(context.out.toString().contains("url\tpv\n"));
+ waiter.assertEquals(InterpreterResult.Code.SUCCESS, result2.code());
+ } catch (Exception e) {
+ e.printStackTrace();
+ waiter.fail("Should not fail here");
+ }
+ waiter.resume();
+ });
+ thread.start();
+
+ // the streaming job will run for 20 seconds. check init_stream.scala
+ // sleep 10 seconds to make sure the job is started but not finished
+ Thread.sleep(10 * 1000);
+
+ InterpreterContext context = getInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ context.getLocalProperties().put("savepointDir", savePointDir.getAbsolutePath());
+ context.getLocalProperties().put("parallelism", "2");
+ context.getLocalProperties().put("maxParallelism", "10");
+ sqlInterpreter.cancel(context);
+ waiter.await(10 * 1000);
+ // resume job from savepoint
+ sqlInterpreter.interpret("select url, count(1) as pv from " +
+ "log group by url", context);
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
assertTrue(resultMessages.toString(),
@@ -159,7 +255,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
@Test
public void testStreamUDF() throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(getClass().getResource("/init_stream.scala"));
+ String initStreamScalaScript = getInitStreamScript(100);
InterpreterResult result = flinkInterpreter.interpret(initStreamScalaScript,
getInterpreterContext());
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -174,7 +270,7 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
context.getLocalProperties().put("type", "update");
result = sqlInterpreter.interpret("select myupper(url), count(1) as pv from " +
"log group by url", context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
// assertEquals(InterpreterResult.Type.TABLE,
// updatedOutput.toInterpreterResultMessage().getType());
// assertTrue(updatedOutput.toInterpreterResultMessage().getData(),
@@ -289,4 +385,9 @@ public class FlinkStreamSqlInterpreterTest extends SqlInterpreterTest {
assertEquals(InterpreterResult.Type.TEXT, resultMessages.get(0).getType());
assertEquals("Table has been created.\n", resultMessages.get(0).getData());
}
+
+ public static String getInitStreamScript(int sleep_interval) throws IOException {
+ return IOUtils.toString(FlinkStreamSqlInterpreterTest.class.getResource("/init_stream.scala"))
+ .replace("{{sleep_interval}}", sleep_interval + "");
+ }
}
diff --git a/flink/src/test/java/org/apache/zeppelin/flink/IPyFlinkInterpreterTest.java b/flink/src/test/java/org/apache/zeppelin/flink/IPyFlinkInterpreterTest.java
index 1a604d3..e857508 100644
--- a/flink/src/test/java/org/apache/zeppelin/flink/IPyFlinkInterpreterTest.java
+++ b/flink/src/test/java/org/apache/zeppelin/flink/IPyFlinkInterpreterTest.java
@@ -19,8 +19,11 @@ package org.apache.zeppelin.flink;
import com.google.common.io.Files;
-import org.apache.commons.io.IOUtils;
+import junit.framework.TestCase;
+import net.jodah.concurrentunit.Waiter;
+import org.apache.commons.io.FileUtils;
import org.apache.commons.lang3.exception.ExceptionUtils;
+import org.apache.zeppelin.display.AngularObjectRegistry;
import org.apache.zeppelin.interpreter.Interpreter;
import org.apache.zeppelin.interpreter.InterpreterContext;
import org.apache.zeppelin.interpreter.InterpreterException;
@@ -34,11 +37,15 @@ import org.apache.zeppelin.python.IPythonInterpreterTest;
import org.junit.After;
import org.junit.Before;
import org.junit.Test;
+import org.slf4j.Logger;
+import org.slf4j.LoggerFactory;
+import java.io.File;
import java.io.IOException;
import java.util.ArrayList;
import java.util.List;
import java.util.Properties;
+import java.util.concurrent.TimeoutException;
import static junit.framework.TestCase.assertTrue;
import static org.junit.Assert.assertEquals;
@@ -47,10 +54,14 @@ import static org.mockito.Mockito.mock;
public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
+ private static final Logger LOGGER = LoggerFactory.getLogger(IPyFlinkInterpreterTest.class);
+ public static AngularObjectRegistry angularObjectRegistry;
+
private RemoteInterpreterEventClient mockIntpEventClient =
mock(RemoteInterpreterEventClient.class);
private LazyOpenInterpreter flinkScalaInterpreter;
+
protected Properties initIntpProperties() {
Properties p = new Properties();
p.setProperty("zeppelin.pyflink.python", "python");
@@ -58,6 +69,7 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
p.setProperty("zeppelin.flink.test", "true");
p.setProperty("zeppelin.dep.localrepo", Files.createTempDir().getAbsolutePath());
p.setProperty("zeppelin.python.gatewayserver_address", "127.0.0.1");
+ p.setProperty("local.number-taskmanager", "4");
return p;
}
@@ -84,6 +96,8 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
interpreter.setInterpreterGroup(intpGroup);
interpreter.open();
+
+ angularObjectRegistry = new AngularObjectRegistry("flink", null);
}
@Before
@@ -122,6 +136,17 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
testAppendStreamTableApi(interpreter, flinkScalaInterpreter);
}
+ @Test
+ public void testCancelStreamSql() throws InterpreterException, IOException, TimeoutException, InterruptedException {
+ testCancelStreamSql(interpreter, flinkScalaInterpreter);
+ }
+
+ // TODO(zjffdu) flaky test
+ // @Test
+ public void testResumeStreamSqlFromSavePoint() throws InterpreterException, IOException, TimeoutException, InterruptedException {
+ testResumeStreamSqlFromSavePoint(interpreter, flinkScalaInterpreter);
+ }
+
public static void testBatchPyFlink(Interpreter pyflinkInterpreter, Interpreter flinkScalaInterpreter) throws InterpreterException, IOException {
InterpreterContext context = createInterpreterContext();
InterpreterResult result = pyflinkInterpreter.interpret(
@@ -241,9 +266,9 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
, context);
assertEquals(result.toString(),InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
- assertEquals(new String(context.out.toByteArray()), 1, resultMessages.size());
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
- assertEquals(new String(context.out.toByteArray()), "a\tb\tc\n1\thi\thello\n2\thi\thello\n", resultMessages.get(0).getData());
+ assertEquals(context.out.toString(), 1, resultMessages.size());
+ assertEquals(context.out.toString(), InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
+ assertEquals(context.out.toString(), "a\tb\tc\n1\thi\thello\n2\thi\thello\n", resultMessages.get(0).getData());
}
@Override
@@ -295,7 +320,7 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
public static void testSingleStreamTableApi(Interpreter interpreter,
Interpreter flinkScalaInterpreter) throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(IPyFlinkInterpreterTest.class.getResource("/init_stream.scala"));
+ String initStreamScalaScript = FlinkStreamSqlInterpreterTest.getInitStreamScript(100);
InterpreterContext context = createInterpreterContext();
InterpreterResult result = flinkScalaInterpreter.interpret(initStreamScalaScript, context);
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -303,7 +328,7 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
context = createInterpreterContext();
String code = "table = st_env.sql_query('select max(rowtime), count(1) from log')\nz.show(table,stream_type='single',template = 'Total Count: {1} <br/> {0}')";
result = interpreter.interpret(code, context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.HTML, resultMessages.get(0).getType());
assertTrue(resultMessages.toString(),
@@ -312,7 +337,7 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
public static void testUpdateStreamTableApi(Interpreter interpreter,
Interpreter flinkScalaInterpreter) throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(IPyFlinkInterpreterTest.class.getResource("/init_stream.scala"));
+ String initStreamScalaScript = FlinkStreamSqlInterpreterTest.getInitStreamScript(100);
InterpreterContext context = createInterpreterContext();
InterpreterResult result = flinkScalaInterpreter.interpret(initStreamScalaScript, context);
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -320,7 +345,7 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
context = createInterpreterContext();
String code = "table = st_env.sql_query('select url, count(1) as pv from log group by url')\nz.show(table,stream_type='update')";
result = interpreter.interpret(code, context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
assertTrue(resultMessages.toString(),
@@ -329,7 +354,7 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
public static void testAppendStreamTableApi(Interpreter interpreter,
Interpreter flinkScalaInterpreter) throws IOException, InterpreterException {
- String initStreamScalaScript = IOUtils.toString(IPyFlinkInterpreterTest.class.getResource("/init_stream.scala"));
+ String initStreamScalaScript = FlinkStreamSqlInterpreterTest.getInitStreamScript(100);
InterpreterContext context = createInterpreterContext();
InterpreterResult result = flinkScalaInterpreter.interpret(initStreamScalaScript, context);
assertEquals(InterpreterResult.Code.SUCCESS, result.code());
@@ -339,28 +364,129 @@ public class IPyFlinkInterpreterTest extends IPythonInterpreterTest {
"start_time, url, count(1) as pv from log group by " +
"TUMBLE(rowtime, INTERVAL '5' SECOND), url\")\nz.show(table,stream_type='append')";
result = interpreter.interpret(code, context);
- assertEquals(new String(context.out.toByteArray()), InterpreterResult.Code.SUCCESS, result.code());
+ assertEquals(context.out.toString(), InterpreterResult.Code.SUCCESS, result.code());
List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
assertTrue(resultMessages.toString(),
resultMessages.get(0).getData().contains("url\tpv\n"));
}
+ public static void testCancelStreamSql(Interpreter interpreter, Interpreter flinkScalaInterpreter) throws IOException, InterpreterException, InterruptedException, TimeoutException {
+ String initStreamScalaScript = FlinkStreamSqlInterpreterTest.getInitStreamScript(1000);
+ InterpreterResult result = flinkScalaInterpreter.interpret(initStreamScalaScript,
+ createInterpreterContext());
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+
+ final Waiter waiter = new Waiter();
+ Thread thread = new Thread(() -> {
+ try {
+ InterpreterContext context = createInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ InterpreterResult result2 = interpreter.interpret(
+ "table = st_env.sql_query('select url, count(1) as pv from " +
+ "log group by url')\nz.show(table, stream_type='update')", context);
+ LOGGER.info("---------------" + context.out.toString());
+ LOGGER.info("---------------" + result2);
+ waiter.assertEquals(InterpreterResult.Code.ERROR, result2.code());
+ } catch (Exception e) {
+ e.printStackTrace();
+ waiter.fail("Should not fail here");
+ }
+ waiter.resume();
+ });
+ thread.start();
+
+ // the streaming job will run for 20 seconds. check init_stream.scala
+ // sleep 10 seconds to make sure the job is started but not finished
+ Thread.sleep(10 * 1000);
+
+ InterpreterContext context = createInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ interpreter.cancel(context);
+ waiter.await(10 * 1000);
+ // resume job
+ interpreter.interpret("table = st_env.sql_query('select url, count(1) as pv from " +
+ "log group by url')\nz.show(table, stream_type='update')", context);
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+ List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
+ assertEquals(InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
+ TestCase.assertTrue(resultMessages.toString(),
+ resultMessages.get(0).getData().contains("url\tpv\n"));
+ }
+
+ public static void testResumeStreamSqlFromSavePoint(Interpreter interpreter, Interpreter flinkScalaInterpreter) throws IOException, InterpreterException, InterruptedException, TimeoutException {
+ String initStreamScalaScript = FlinkStreamSqlInterpreterTest.getInitStreamScript(1000);
+ InterpreterResult result = flinkScalaInterpreter.interpret(initStreamScalaScript,
+ createInterpreterContext());
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+
+ File savePointDir = FileUtils.getTempDirectory();
+ final Waiter waiter = new Waiter();
+ Thread thread = new Thread(() -> {
+ try {
+ InterpreterContext context = createInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ context.getLocalProperties().put("savepointDir", savePointDir.getAbsolutePath());
+ context.getLocalProperties().put("parallelism", "1");
+ context.getLocalProperties().put("maxParallelism", "10");
+ InterpreterResult result2 = interpreter.interpret(
+ "table = st_env.sql_query('select url, count(1) as pv from " +
+ "log group by url')\nz.show(table, stream_type='update')", context);
+ System.out.println("------------" + context.out.toString());
+ System.out.println("------------" + result2);
+ waiter.assertTrue(context.out.toString().contains("url\tpv\n"));
+ } catch (Exception e) {
+ e.printStackTrace();
+ waiter.fail("Should not fail here");
+ }
+ waiter.resume();
+ });
+ thread.start();
+
+ // the streaming job will run for 60 seconds. check init_stream.scala
+ // sleep 20 seconds to make sure the job is started but not finished
+ Thread.sleep(20 * 1000);
+
+ InterpreterContext context = createInterpreterContext();
+ context.getLocalProperties().put("type", "update");
+ context.getLocalProperties().put("savepointDir", savePointDir.getAbsolutePath());
+ context.getLocalProperties().put("parallelism", "2");
+ context.getLocalProperties().put("maxParallelism", "10");
+ interpreter.cancel(context);
+ waiter.await(20 * 1000);
+ // resume job from savepoint
+ interpreter.interpret(
+ "table = st_env.sql_query('select url, count(1) as pv from " +
+ "log group by url')\nz.show(table, stream_type='update')", context);
+ assertEquals(InterpreterResult.Code.SUCCESS, result.code());
+ List<InterpreterResultMessage> resultMessages = context.out.toInterpreterResultMessage();
+ LOGGER.info("---------------" + context.out.toString());
+ assertEquals(resultMessages.get(0).toString(), InterpreterResult.Type.TABLE, resultMessages.get(0).getType());
+ TestCase.assertTrue(resultMessages.toString(),
+ resultMessages.get(0).getData().contains("url\tpv\n"));
+ }
+
private static InterpreterContext createInterpreterContext() {
- return InterpreterContext.builder()
- .setNoteId("noteId")
- .setParagraphId("paragraphId")
- .setInterpreterOut(new InterpreterOutput(null))
- .setIntpEventClient(mock(RemoteInterpreterEventClient.class))
- .build();
+ InterpreterContext context = InterpreterContext.builder()
+ .setNoteId("noteId")
+ .setParagraphId("paragraphId")
+ .setInterpreterOut(new InterpreterOutput(null))
+ .setIntpEventClient(mock(RemoteInterpreterEventClient.class))
+ .setAngularObjectRegistry(angularObjectRegistry)
+ .build();
+ InterpreterContext.set(context);
+ return context;
}
protected InterpreterContext getInterpreterContext() {
- return InterpreterContext.builder()
+ InterpreterContext context = InterpreterContext.builder()
.setNoteId("noteId")
.setParagraphId("paragraphId")
.setInterpreterOut(new InterpreterOutput(null))
+ .setAngularObjectRegistry(angularObjectRegistry)
.setIntpEventClient(mock(RemoteInterpreterEventClient.class))
.build();
+ InterpreterContext.set(context);
+ return context;
}
}
diff --git a/flink/src/test/java/org/apache/zeppelin/flink/PyFlinkInterpreterTest.java b/flink/src/test/java/org/apache/zeppelin/flink/PyFlinkInterpreterTest.java
index d6a24a2..6553722 100644
--- a/flink/src/test/java/org/apache/zeppelin/flink/PyFlinkInterpreterTest.java
+++ b/flink/src/test/java/org/apache/zeppelin/flink/PyFlinkInterpreterTest.java
@@ -25,9 +25,6 @@ import org.apache.zeppelin.interpreter.InterpreterContext;
import org.apache.zeppelin.interpreter.InterpreterException;
import org.apache.zeppelin.interpreter.InterpreterGroup;
import org.apache.zeppelin.interpreter.InterpreterOutput;
-import org.apache.zeppelin.interpreter.InterpreterOutputListener;
-import org.apache.zeppelin.interpreter.InterpreterResult;
-import org.apache.zeppelin.interpreter.InterpreterResultMessageOutput;
import org.apache.zeppelin.interpreter.LazyOpenInterpreter;
import org.apache.zeppelin.interpreter.remote.RemoteInterpreterEventClient;
import org.apache.zeppelin.python.PythonInterpreterTest;
@@ -36,24 +33,17 @@ import org.junit.Test;
import java.io.IOException;
import java.util.LinkedList;
import java.util.Properties;
+import java.util.concurrent.TimeoutException;
import static org.mockito.Mockito.mock;
public class PyFlinkInterpreterTest extends PythonInterpreterTest {
- private RemoteInterpreterEventClient mockRemoteEventClient =
- mock(RemoteInterpreterEventClient.class);
-
private Interpreter flinkScalaInterpreter;
private Interpreter streamSqlInterpreter;
private Interpreter batchSqlInterpreter;
- // catch the streaming appendOutput in onAppend
- protected volatile String appendOutput = "";
- protected volatile InterpreterResult.Type appendOutputType;
- // catch the flinkInterpreter appendOutput in onUpdate
- protected InterpreterResultMessageOutput updatedOutput;
@Override
public void setUp() throws InterpreterException {
@@ -64,15 +54,14 @@ public class PyFlinkInterpreterTest extends PythonInterpreterTest {
properties.setProperty("zeppelin.pyflink.useIPython", "false");
properties.setProperty("zeppelin.flink.test", "true");
properties.setProperty("zeppelin.python.gatewayserver_address", "127.0.0.1");
+ properties.setProperty("local.number-taskmanager", "4");
// create interpreter group
intpGroup = new InterpreterGroup();
intpGroup.put("session_1", new LinkedList<>());
- InterpreterContext context = InterpreterContext.builder()
- .setInterpreterOut(new InterpreterOutput(null))
- .setIntpEventClient(mockRemoteEventClient)
- .build();
+ IPyFlinkInterpreterTest.angularObjectRegistry = new AngularObjectRegistry("flink", null);
+ InterpreterContext context = getInterpreterContext();
InterpreterContext.set(context);
flinkScalaInterpreter = new LazyOpenInterpreter(new FlinkInterpreter(properties));
intpGroup.get("session_1").add(flinkScalaInterpreter);
@@ -129,35 +118,26 @@ public class PyFlinkInterpreterTest extends PythonInterpreterTest {
IPyFlinkInterpreterTest.testAppendStreamTableApi(interpreter, flinkScalaInterpreter);
}
+ @Test
+ public void testCancelStreamSql() throws InterpreterException, IOException, TimeoutException, InterruptedException {
+ IPyFlinkInterpreterTest.testCancelStreamSql(interpreter, flinkScalaInterpreter);
+ }
+
+ // TODO(zjffdu) flaky test
+ // @Test
+ public void testResumeStreamSqlFromSavePoint() throws InterpreterException, IOException, TimeoutException, InterruptedException {
+ IPyFlinkInterpreterTest.testResumeStreamSqlFromSavePoint(interpreter, flinkScalaInterpreter);
+ }
+
protected InterpreterContext getInterpreterContext() {
- appendOutput = "";
InterpreterContext context = InterpreterContext.builder()
+ .setNoteId("noteId")
+ .setParagraphId("paragraphId")
.setInterpreterOut(new InterpreterOutput(null))
- .setAngularObjectRegistry(new AngularObjectRegistry("flink", null))
- .setIntpEventClient(mockRemoteEventClient)
+ .setAngularObjectRegistry(IPyFlinkInterpreterTest.angularObjectRegistry)
+ .setIntpEventClient(mock(RemoteInterpreterEventClient.class))
.build();
- context.out = new InterpreterOutput(
- new InterpreterOutputListener() {
- @Override
- public void onUpdateAll(InterpreterOutput out) {
- System.out.println();
- }
-
- @Override
- public void onAppend(int index, InterpreterResultMessageOutput out, byte[] line) {
- try {
- appendOutputType = out.toInterpreterResultMessage().getType();
- appendOutput = out.toInterpreterResultMessage().getData();
- } catch (IOException e) {
- e.printStackTrace();
- }
- }
-
- @Override
- public void onUpdate(int index, InterpreterResultMessageOutput out) {
- updatedOutput = out;
- }
- });
+ InterpreterContext.set(context);
return context;
}
}
diff --git a/flink/src/test/java/org/apache/zeppelin/flink/SqlInterpreterTest.java b/flink/src/test/java/org/apache/zeppelin/flink/SqlInterpreterTest.java
index 3ee48e5..31ea6ad 100644
--- a/flink/src/test/java/org/apache/zeppelin/flink/SqlInterpreterTest.java
+++ b/flink/src/test/java/org/apache/zeppelin/flink/SqlInterpreterTest.java
@@ -83,6 +83,8 @@ public abstract class SqlInterpreterTest {
protected PyFlinkInterpreter pyFlinkInterpreter;
protected FlinkSqlInterrpeter sqlInterpreter;
+ private AngularObjectRegistry angularObjectRegistry;
+
@HiveSQL(files = {})
protected static HiveShell hiveShell;
@@ -93,6 +95,7 @@ public abstract class SqlInterpreterTest {
p.setProperty("taskmanager.managed.memory.size", "32");
p.setProperty("zeppelin.flink.hive.version", "2.3.4");
p.setProperty("zeppelin.pyflink.useIPython", "false");
+ p.setProperty("local.number-taskmanager", "4");
File hiveConfDir = Files.createTempDir();
hiveShell.getHiveConf().writeXml(new FileWriter(new File(hiveConfDir, "hive-site.xml")));
p.setProperty("HIVE_CONF_DIR", hiveConfDir.getAbsolutePath());
@@ -116,6 +119,7 @@ public abstract class SqlInterpreterTest {
intpGroup.addInterpreterToSession(iPyFlinkInterpreter, "session_1");
intpGroup.addInterpreterToSession(pyFlinkInterpreter, "session_1");
+ angularObjectRegistry = new AngularObjectRegistry("flink", null);
InterpreterContext.set(getInterpreterContext());
flinkInterpreter.open();
sqlInterpreter.open();
@@ -364,13 +368,15 @@ public abstract class SqlInterpreterTest {
}
protected InterpreterContext getInterpreterContext() {
- return InterpreterContext.builder()
+ InterpreterContext context = InterpreterContext.builder()
.setParagraphId("paragraphId")
.setInterpreterOut(new InterpreterOutput(null))
- .setAngularObjectRegistry(new AngularObjectRegistry("flink", null))
+ .setAngularObjectRegistry(angularObjectRegistry)
.setIntpEventClient(mock(RemoteInterpreterEventClient.class))
.setInterpreterOut(new InterpreterOutput(null))
.build();
+ InterpreterContext.set(context);
+ return context;
}
public static File createInputFile(String data) throws IOException {
diff --git a/flink/src/test/resources/init_stream.scala b/flink/src/test/resources/init_stream.scala
index 4f53cc4..f8d27ae 100644
--- a/flink/src/test/resources/init_stream.scala
+++ b/flink/src/test/resources/init_stream.scala
@@ -6,20 +6,21 @@ import java.util.Collections
import scala.collection.JavaConversions._
senv.setStreamTimeCharacteristic(TimeCharacteristic.EventTime)
-senv.enableCheckpointing(1000)
+senv.enableCheckpointing(5000)
val data = senv.addSource(new SourceFunction[(Long, String)] with ListCheckpointed[java.lang.Long] {
val pages = Seq("home", "search", "search", "product", "product", "product")
var count: Long = 0
+ var running : Boolean = true
// startTime is 2018/1/1
var startTime: Long = new java.util.Date(2018 - 1900,0,1).getTime
- var sleepInterval = 100
+ var sleepInterval = {{sleep_interval}}
override def run(ctx: SourceFunction.SourceContext[(Long, String)]): Unit = {
val lock = ctx.getCheckpointLock
- while (count < 20) {
+ while (count < 60 && running) {
lock.synchronized({
ctx.collect((startTime + count * sleepInterval, pages(count.toInt % pages.size)))
count += 1
@@ -29,7 +30,7 @@ val data = senv.addSource(new SourceFunction[(Long, String)] with ListCheckpoint
}
override def cancel(): Unit = {
-
+ running = false
}
override def snapshotState(checkpointId: Long, timestamp: Long): java.util.List[java.lang.Long] = {
diff --git a/flink/src/test/resources/log4j.properties b/flink/src/test/resources/log4j.properties
index 8017840..24ec949 100644
--- a/flink/src/test/resources/log4j.properties
+++ b/flink/src/test/resources/log4j.properties
@@ -23,4 +23,5 @@ log4j.appender.stdout.layout.ConversionPattern=%5p [%d] ({%t} %F[%M]:%L) - %m%n
log4j.logger.org.apache.hive=WARN
log4j.logger.org.apache.flink=WARN
+log4j.logger.org.apache.zeppelin.flink=DEBUG
diff --git a/flink/src/test/resources/log4j2.properties b/flink/src/test/resources/log4j2.properties
deleted file mode 100755
index 1bce906..0000000
--- a/flink/src/test/resources/log4j2.properties
+++ /dev/null
@@ -1,64 +0,0 @@
-# Licensed to the Apache Software Foundation (ASF) under one
-# or more contributor license agreements. See the NOTICE file
-# distributed with this work for additional information
-# regarding copyright ownership. The ASF licenses this file
-# to you under the Apache License, Version 2.0 (the
-# "License"); you may not use this file except in compliance
-# with the License. You may obtain a copy of the License at
-#
-# http://www.apache.org/licenses/LICENSE-2.0
-#
-# Unless required by applicable law or agreed to in writing, software
-# distributed under the License is distributed on an "AS IS" BASIS,
-# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-# See the License for the specific language governing permissions and
-# limitations under the License.
-
-status = INFO
-name = HiveLog4j2
-packages = org.apache.hadoop.hive.ql.log
-
-# list of properties
-property.hive.log.level = WARN
-property.hive.root.logger = console
-property.hive.perflogger.log.level = WARN
-
-# list of all appenders
-appenders = console
-
-# console appender
-appender.console.type = Console
-appender.console.name = console
-appender.console.target = SYSTEM_ERR
-appender.console.layout.type = PatternLayout
-appender.console.layout.pattern = %d{ISO8601} %5p [%t] %c{2}: %m%n
-
-# list of all loggers
-loggers = NIOServerCnxn, ClientCnxnSocketNIO, DataNucleus, Datastore, JPOX, PerfLogger
-
-logger.NIOServerCnxn.name = org.apache.zookeeper.server.NIOServerCnxn
-logger.NIOServerCnxn.level = WARN
-
-logger.ClientCnxnSocketNIO.name = org.apache.zookeeper.ClientCnxnSocketNIO
-logger.ClientCnxnSocketNIO.level = WARN
-
-logger.DataNucleus.name = DataNucleus
-logger.DataNucleus.level = ERROR
-
-logger.Datastore.name = Datastore
-logger.Datastore.level = ERROR
-
-logger.JPOX.name = JPOX
-logger.JPOX.level = ERROR
-
-logger.flink.name = org.apache.zeppelin.flink
-logger.flink.level = INFO
-
-logger.PerfLogger.name = org.apache.hadoop.hive.ql.log.PerfLogger
-logger.PerfLogger.level = WARN
-
-# root logger
-rootLogger.level = ${sys:hive.log.level}
-rootLogger.appenderRefs = root
-rootLogger.appenderRef.root.ref = WARN
-
diff --git a/zeppelin-interpreter/src/main/java/org/apache/zeppelin/interpreter/InterpreterOutput.java b/zeppelin-interpreter/src/main/java/org/apache/zeppelin/interpreter/InterpreterOutput.java
index 83b6cc4..a9d9243 100644
--- a/zeppelin-interpreter/src/main/java/org/apache/zeppelin/interpreter/InterpreterOutput.java
+++ b/zeppelin-interpreter/src/main/java/org/apache/zeppelin/interpreter/InterpreterOutput.java
@@ -362,6 +362,15 @@ public class InterpreterOutput extends OutputStream {
}
@Override
+ public String toString() {
+ try {
+ return new String(toByteArray());
+ } catch (IOException e) {
+ return e.toString();
+ }
+ }
+
+ @Override
public void close() throws IOException {
synchronized (resultMessageOutputs) {
for (InterpreterResultMessageOutput out : resultMessageOutputs) {