You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@dolphinscheduler.apache.org by "8debug (via GitHub)" <gi...@apache.org> on 2023/03/27 01:38:36 UTC
[GitHub] [dolphinscheduler] 8debug opened a new issue, #13792: data_quality 任务中,语句中的字段如果是汉字,则任务执行失败。
8debug opened a new issue, #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792
### Search before asking
- [X] I had searched in the [issues](https://github.com/apache/dolphinscheduler/issues?q=is%3Aissue) and found no similar issues.
### What happened
3.0.2 版本,data_quality 任务中,`两表值对比`中若语句中字段是汉字,则执行失败。
### What you expected to happen
data_quality 任务中,语句中的字段名是汉字,任务也能正常执行
### How to reproduce
我使用的是 3.0.2 版本,我在HIVE中创建了两个数据库表,表名是英文,字段名是中文。如下
```sql
CREATE TABLE append.gl004_empcost
(
`同步时间` DATE,
`日期` DATE
) USING orc;
CREATE TABLE append.gl004_empcost_release
(
`同步时间` DATE,
`日期` DATE
) USING orc
```
然后我创建 data_quality 任务,选择 `两表值对比` ,`实际值计算SQL`为
```sql
select datediff(max(e.`日期`), date(now())) as dev_days from append.gl004_empcost e
```
`期望值计算SQL`为
```sql
select datediff(max(e.`日期`), date(now())) as release_days from append.gl004_empcost_release e
```
`阈值`为100,`失败策略`为Block。
创建成功后,执行此任务报错,通过观察错误日志发现,带有汉字字段的语句无法正常执行,如下图

### 完整错误日志如下
```error
[INFO] 2023-03-27 08:22:07.447 +0800 - -> 2023-03-27 08:22:07,193 INFO yarn.Client: Application report for application_1678704143533_20746 (state: FINISHED)
2023-03-27 08:22:07,193 INFO yarn.Client:
client token: N/A
diagnostics: User class threw exception: org.apache.spark.sql.catalyst.parser.ParseException:
mismatched input ')' expecting {'ADD', 'AFTER', 'ALL', 'ALTER', 'ANALYZE', 'AND', 'ANTI', 'ANY', 'ARCHIVE', 'ARRAY', 'AS', 'ASC', 'AT', 'AUTHORIZATION', 'BETWEEN', 'BOTH', 'BUCKET', 'BUCKETS', 'BY', 'CACHE', 'CASCADE', 'CASE', 'CAST', 'CHANGE', 'CHECK', 'CLEAR', 'CLUSTER', 'CLUSTERED', 'CODEGEN', 'COLLATE', 'COLLECTION', 'COLUMN', 'COLUMNS', 'COMMENT', 'COMMIT', 'COMPACT', 'COMPACTIONS', 'COMPUTE', 'CONCATENATE', 'CONSTRAINT', 'COST', 'CREATE', 'CROSS', 'CUBE', 'CURRENT', 'CURRENT_DATE', 'CURRENT_TIME', 'CURRENT_TIMESTAMP', 'CURRENT_USER', 'DAY', 'DATA', 'DATABASE', DATABASES, 'DBPROPERTIES', 'DEFINED', 'DELETE', 'DELIMITED', 'DESC', 'DESCRIBE', 'DFS', 'DIRECTORIES', 'DIRECTORY', 'DISTINCT', 'DISTRIBUTE', 'DIV', 'DROP', 'ELSE', 'END', 'ESCAPE', 'ESCAPED', 'EXCEPT', 'EXCHANGE', 'EXISTS', 'EXPLAIN', 'EXPORT', 'EXTENDED', 'EXTERNAL', 'EXTRACT', 'FALSE', 'FETCH', 'FIELDS', 'FILTER', 'FILEFORMAT', 'FIRST', 'FOLLOWING', 'FOR', 'FOREIGN', 'FORMAT', 'FORMATTED', 'FROM', 'FULL', 'FUNCTION
', 'FUNCTIONS', 'GLOBAL', 'GRANT', 'GROUP', 'GROUPING', 'HAVING', 'HOUR', 'IF', 'IGNORE', 'IMPORT', 'IN', 'INDEX', 'INDEXES', 'INNER', 'INPATH', 'INPUTFORMAT', 'INSERT', 'INTERSECT', 'INTERVAL', 'INTO', 'IS', 'ITEMS', 'JOIN', 'KEYS', 'LAST', 'LATERAL', 'LAZY', 'LEADING', 'LEFT', 'LIKE', 'LIMIT', 'LINES', 'LIST', 'LOAD', 'LOCAL', 'LOCATION', 'LOCK', 'LOCKS', 'LOGICAL', 'MACRO', 'MAP', 'MATCHED', 'MERGE', 'MINUTE', 'MONTH', 'MSCK', 'NAMESPACE', 'NAMESPACES', 'NATURAL', 'NO', NOT, 'NULL', 'NULLS', 'OF', 'ON', 'ONLY', 'OPTION', 'OPTIONS', 'OR', 'ORDER', 'OUT', 'OUTER', 'OUTPUTFORMAT', 'OVER', 'OVERLAPS', 'OVERLAY', 'OVERWRITE', 'PARTITION', 'PARTITIONED', 'PARTITIONS', 'PERCENT', 'PIVOT', 'PLACING', 'POSITION', 'PRECEDING', 'PRIMARY', 'PRINCIPALS', 'PROPERTIES', 'PURGE', 'QUERY', 'RANGE', 'RECORDREADER', 'RECORDWRITER', 'RECOVER', 'REDUCE', 'REFERENCES', 'REFRESH', 'RENAME', 'REPAIR', 'REPLACE', 'RESET', 'RESPECT', 'RESTRICT', 'REVOKE', 'RIGHT', RLIKE, 'ROLE', 'ROLES', 'ROLLBACK', 'ROLL
UP', 'ROW', 'ROWS', 'SECOND', 'SCHEMA', 'SELECT', 'SEMI', 'SEPARATED', 'SERDE', 'SERDEPROPERTIES', 'SESSION_USER', 'SET', 'MINUS', 'SETS', 'SHOW', 'SKEWED', 'SOME', 'SORT', 'SORTED', 'START', 'STATISTICS', 'STORED', 'STRATIFY', 'STRUCT', 'SUBSTR', 'SUBSTRING', 'SYNC', 'TABLE', 'TABLES', 'TABLESAMPLE', 'TBLPROPERTIES', TEMPORARY, 'TERMINATED', 'THEN', 'TIME', 'TO', 'TOUCH', 'TRAILING', 'TRANSACTION', 'TRANSACTIONS', 'TRANSFORM', 'TRIM', 'TRUE', 'TRUNCATE', 'TRY_CAST', 'TYPE', 'UNARCHIVE', 'UNBOUNDED', 'UNCACHE', 'UNION', 'UNIQUE', 'UNKNOWN', 'UNLOCK', 'UNSET', 'UPDATE', 'USE', 'USER', 'USING', 'VALUES', 'VIEW', 'VIEWS', 'WHEN', 'WHERE', 'WINDOW', 'WITH', 'YEAR', 'ZONE', IDENTIFIER, BACKQUOTED_IDENTIFIER}(line 1, pos 486)
== SQL ==
select 3 as rule_type,'(multi_table_value_comparison)' as rule_name,0 as process_definition_id,71301 as process_instance_id,302276 as task_instance_id,dev_days AS statistics_value,release_days AS comparison_value,0 AS comparison_type,1 as check_type,100 as threshold,3 as operator,1 as failure_strategy,'hdfs://hahadoop:8020/data-quality-error-data/0_71301_dev' as error_output_path,'2023-03-27 08:21:38' as create_time,'2023-03-27 08:21:38' as update_time from ( select datediff(max(e.), date(now())) as dev_days from append.gl004_empcost e ) tmp1 join ( select datediff(max(e.), date(now())) as release_days from append.gl004_empcost_release e ) tmp2
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------^^^
at org.apache.spark.sql.catalyst.parser.ParseException.withCommand(ParseDriver.scala:266)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parse(ParseDriver.scala:127)
at org.apache.spark.sql.execution.SparkSqlParser.parse(SparkSqlParser.scala:51)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parsePlan(ParseDriver.scala:77)
at org.apache.spark.sql.SparkSession.$anonfun$sql$2(SparkSession.scala:616)
at org.apache.spark.sql.catalyst.QueryPlanningTracker.measurePhase(QueryPlanningTracker.scala:111)
at org.apache.spark.sql.SparkSession.$anonfun$sql$1(SparkSession.scala:616)
at org.apache.spark.sql.SparkSession.withActive(SparkSession.scala:775)
at org.apache.spark.sql.SparkSession.sql(SparkSession.scala:613)
at org.apache.dolphinscheduler.data.quality.flow.batch.writer.JdbcWriter.write(JdbcWriter.java:74)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.executeWriter(SparkBatchExecution.java:130)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.execute(SparkBatchExecution.java:58)
at org.apache.dolphinscheduler.data.quality.context.DataQualityContext.execute(DataQualityContext.java:62)
at org.apache.dolphinscheduler.data.quality.DataQualityApplication.main(DataQualityApplication.java:70)
at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
at java.lang.reflect.Method.invoke(Method.java:498)
at org.apache.spark.deploy.yarn.ApplicationMaster$$anon$2.run(ApplicationMaster.scala:737)
ApplicationMaster host: hs.med.hadoop.worker3
ApplicationMaster RPC port: 41511
queue: default
start time: 1679876506945
final status: FAILED
tracking URL: http://hs.med.hadoop.master2:8088/proxy/application_1678704143533_20746/
user: hadoop
2023-03-27 08:22:07,201 ERROR yarn.Client: Application diagnostics message: User class threw exception: org.apache.spark.sql.catalyst.parser.ParseException:
mismatched input ')' expecting {'ADD', 'AFTER', 'ALL', 'ALTER', 'ANALYZE', 'AND', 'ANTI', 'ANY', 'ARCHIVE', 'ARRAY', 'AS', 'ASC', 'AT', 'AUTHORIZATION', 'BETWEEN', 'BOTH', 'BUCKET', 'BUCKETS', 'BY', 'CACHE', 'CASCADE', 'CASE', 'CAST', 'CHANGE', 'CHECK', 'CLEAR', 'CLUSTER', 'CLUSTERED', 'CODEGEN', 'COLLATE', 'COLLECTION', 'COLUMN', 'COLUMNS', 'COMMENT', 'COMMIT', 'COMPACT', 'COMPACTIONS', 'COMPUTE', 'CONCATENATE', 'CONSTRAINT', 'COST', 'CREATE', 'CROSS', 'CUBE', 'CURRENT', 'CURRENT_DATE', 'CURRENT_TIME', 'CURRENT_TIMESTAMP', 'CURRENT_USER', 'DAY', 'DATA', 'DATABASE', DATABASES, 'DBPROPERTIES', 'DEFINED', 'DELETE', 'DELIMITED', 'DESC', 'DESCRIBE', 'DFS', 'DIRECTORIES', 'DIRECTORY', 'DISTINCT', 'DISTRIBUTE', 'DIV', 'DROP', 'ELSE', 'END', 'ESCAPE', 'ESCAPED', 'EXCEPT', 'EXCHANGE', 'EXISTS', 'EXPLAIN', 'EXPORT', 'EXTENDED', 'EXTERNAL', 'EXTRACT', 'FALSE', 'FETCH', 'FIELDS', 'FILTER', 'FILEFORMAT', 'FIRST', 'FOLLOWING', 'FOR', 'FOREIGN', 'FORMAT', 'FORMATTED', 'FROM', 'FULL', 'FUNCTION
', 'FUNCTIONS', 'GLOBAL', 'GRANT', 'GROUP', 'GROUPING', 'HAVING', 'HOUR', 'IF', 'IGNORE', 'IMPORT', 'IN', 'INDEX', 'INDEXES', 'INNER', 'INPATH', 'INPUTFORMAT', 'INSERT', 'INTERSECT', 'INTERVAL', 'INTO', 'IS', 'ITEMS', 'JOIN', 'KEYS', 'LAST', 'LATERAL', 'LAZY', 'LEADING', 'LEFT', 'LIKE', 'LIMIT', 'LINES', 'LIST', 'LOAD', 'LOCAL', 'LOCATION', 'LOCK', 'LOCKS', 'LOGICAL', 'MACRO', 'MAP', 'MATCHED', 'MERGE', 'MINUTE', 'MONTH', 'MSCK', 'NAMESPACE', 'NAMESPACES', 'NATURAL', 'NO', NOT, 'NULL', 'NULLS', 'OF', 'ON', 'ONLY', 'OPTION', 'OPTIONS', 'OR', 'ORDER', 'OUT', 'OUTER', 'OUTPUTFORMAT', 'OVER', 'OVERLAPS', 'OVERLAY', 'OVERWRITE', 'PARTITION', 'PARTITIONED', 'PARTITIONS', 'PERCENT', 'PIVOT', 'PLACING', 'POSITION', 'PRECEDING', 'PRIMARY', 'PRINCIPALS', 'PROPERTIES', 'PURGE', 'QUERY', 'RANGE', 'RECORDREADER', 'RECORDWRITER', 'RECOVER', 'REDUCE', 'REFERENCES', 'REFRESH', 'RENAME', 'REPAIR', 'REPLACE', 'RESET', 'RESPECT', 'RESTRICT', 'REVOKE', 'RIGHT', RLIKE, 'ROLE', 'ROLES', 'ROLLBACK', 'ROLL
UP', 'ROW', 'ROWS', 'SECOND', 'SCHEMA', 'SELECT', 'SEMI', 'SEPARATED', 'SERDE', 'SERDEPROPERTIES', 'SESSION_USER', 'SET', 'MINUS', 'SETS', 'SHOW', 'SKEWED', 'SOME', 'SORT', 'SORTED', 'START', 'STATISTICS', 'STORED', 'STRATIFY', 'STRUCT', 'SUBSTR', 'SUBSTRING', 'SYNC', 'TABLE', 'TABLES', 'TABLESAMPLE', 'TBLPROPERTIES', TEMPORARY, 'TERMINATED', 'THEN', 'TIME', 'TO', 'TOUCH', 'TRAILING', 'TRANSACTION', 'TRANSACTIONS', 'TRANSFORM', 'TRIM', 'TRUE', 'TRUNCATE', 'TRY_CAST', 'TYPE', 'UNARCHIVE', 'UNBOUNDED', 'UNCACHE', 'UNION', 'UNIQUE', 'UNKNOWN', 'UNLOCK', 'UNSET', 'UPDATE', 'USE', 'USER', 'USING', 'VALUES', 'VIEW', 'VIEWS', 'WHEN', 'WHERE', 'WINDOW', 'WITH', 'YEAR', 'ZONE', IDENTIFIER, BACKQUOTED_IDENTIFIER}(line 1, pos 486)
== SQL ==
select 3 as rule_type,'(multi_table_value_comparison)' as rule_name,0 as process_definition_id,71301 as process_instance_id,302276 as task_instance_id,dev_days AS statistics_value,release_days AS comparison_value,0 AS comparison_type,1 as check_type,100 as threshold,3 as operator,1 as failure_strategy,'hdfs://hahadoop:8020/data-quality-error-data/0_71301_dev' as error_output_path,'2023-03-27 08:21:38' as create_time,'2023-03-27 08:21:38' as update_time from ( select datediff(max(e.), date(now())) as dev_days from append.gl004_empcost e ) tmp1 join ( select datediff(max(e.), date(now())) as release_days from append.gl004_empcost_release e ) tmp2
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------^^^
at org.apache.spark.sql.catalyst.parser.ParseException.withCommand(ParseDriver.scala:266)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parse(ParseDriver.scala:127)
at org.apache.spark.sql.execution.SparkSqlParser.parse(SparkSqlParser.scala:51)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parsePlan(ParseDriver.scala:77)
at org.apache.spark.sql.SparkSession.$anonfun$sql$2(SparkSession.scala:616)
at org.apache.spark.sql.catalyst.QueryPlanningTracker.measurePhase(QueryPlanningTracker.scala:111)
at org.apache.spark.sql.SparkSession.$anonfun$sql$1(SparkSession.scala:616)
at org.apache.spark.sql.SparkSession.withActive(SparkSession.scala:775)
at org.apache.spark.sql.SparkSession.sql(SparkSession.scala:613)
at org.apache.dolphinscheduler.data.quality.flow.batch.writer.JdbcWriter.write(JdbcWriter.java:74)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.executeWriter(SparkBatchExecution.java:130)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.execute(SparkBatchExecution.java:58)
at org.apache.dolphinscheduler.data.quality.context.DataQualityContext.execute(DataQualityContext.java:62)
at org.apache.dolphinscheduler.data.quality.DataQualityApplication.main(DataQualityApplication.java:70)
at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
at java.lang.reflect.Method.invoke(Method.java:498)
at org.apache.spark.deploy.yarn.ApplicationMaster$$anon$2.run(ApplicationMaster.scala:737)
Exception in thread "main" org.apache.spark.SparkException: Application application_1678704143533_20746 finished with failed status
at org.apache.spark.deploy.yarn.Client.run(Client.scala:1283)
at org.apache.spark.deploy.yarn.YarnClusterApplication.start(Client.scala:1677)
at org.apache.spark.deploy.SparkSubmit.org$apache$spark$deploy$SparkSubmit$$runMain(SparkSubmit.scala:955)
at org.apache.spark.deploy.SparkSubmit.doRunMain$1(SparkSubmit.scala:180)
at org.apache.spark.deploy.SparkSubmit.submit(SparkSubmit.scala:203)
at org.apache.spark.deploy.SparkSubmit.doSubmit(SparkSubmit.scala:90)
at org.apache.spark.deploy.SparkSubmit$$anon$2.doSubmit(SparkSubmit.scala:1043)
at org.apache.spark.deploy.SparkSubmit$.main(SparkSubmit.scala:1052)
at org.apache.spark.deploy.SparkSubmit.main(SparkSubmit.scala)
2023-03-27 08:22:07,204 INFO util.ShutdownHookManager: Shutdown hook called
2023-03-27 08:22:07,205 INFO util.ShutdownHookManager: Deleting directory /opt/utils/spark/spark-869a6101-7e54-4b72-9ad7-8ed488a7dfee
2023-03-27 08:22:07,208 INFO util.ShutdownHookManager: Deleting directory /tmp/spark-8cb6394f-e904-482a-b970-3a61169d3250
[INFO] 2023-03-27 08:22:07.447 +0800 - FINALIZE_SESSION
```
### data_quality 任务的完整配置如下
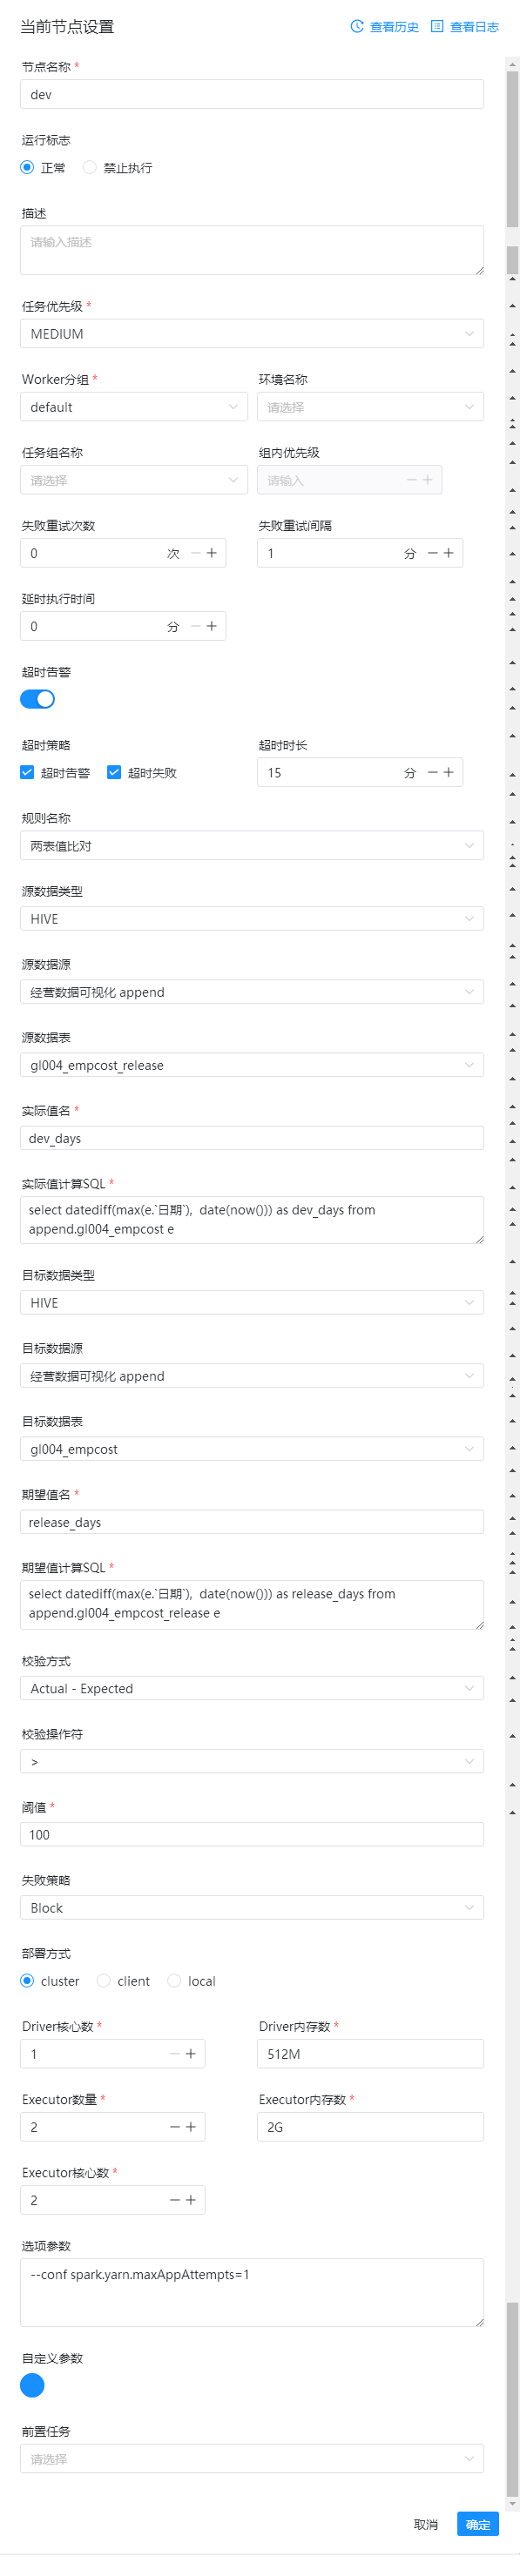
### Anything else
符合以上条件,每次都执行失败
### Version
3.0.x
### Are you willing to submit PR?
- [ ] Yes I am willing to submit a PR!
### Code of Conduct
- [X] I agree to follow this project's [Code of Conduct](https://www.apache.org/foundation/policies/conduct)
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] github-actions[bot] commented on issue #13792: In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "github-actions[bot] (via GitHub)" <gi...@apache.org>.
github-actions[bot] commented on issue #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792#issuecomment-1484342139
### Search before asking
- [X] I had searched in the [issues](https://github.com/apache/dolphinscheduler/issues?q=is%3Aissue) and found no similar issues.
### What happened
In version 3.0.2, in the data_quality task, if the field in the statement is a Chinese character in `comparison of two table values`, the execution will fail.
### What you expected to happen
In the data_quality task, the field names in the statement are Chinese characters, and the task can also be executed normally
### How to reproduce
I am using version 3.0.2, and I have created two database tables in HIVE, the table names are in English, and the field names are in Chinese. as follows
```sql
CREATE TABLE append.gl004_empcost
(
`Sync Time` DATE,
`date` DATE
) USING orc;
CREATE TABLE append.gl004_empcost_release
(
`Sync Time` DATE,
`date` DATE
) USING orc
```
Then I create a data_quality task, select `comparison of two table values`, and `actual value calculation SQL` is
```sql
select datediff(max(e.`date`), date(now())) as dev_days from append.gl004_empcost e
```
`Expected value calculation SQL` is
```sql
select datediff(max(e.`date`), date(now())) as release_days from append.gl004_empcost_release e
```
`Threshold` is 100 and `Failure Strategy` is Block.
After the creation is successful, an error is reported when executing this task. By observing the error log, it is found that the statement with the Chinese character field cannot be executed normally, as shown in the following figure

### The complete error log is as follows
```error
[INFO] 2023-03-27 08:22:07.447 +0800 - -> 2023-03-27 08:22:07,193 INFO yarn.Client: Application report for application_1678704143533_20746 (state: FINISHED)
2023-03-27 08:22:07,193 INFO yarn.Client:
client token: N/A
diagnostics: User class threw exception: org.apache.spark.sql.catalyst.parser.ParseException:
mismatched input ')' expecting {'ADD', 'AFTER', 'ALL', 'ALTER', 'ANALYZE', 'AND', 'ANTI', 'ANY', 'ARCHIVE', 'ARRAY', 'AS' , 'ASC', 'AT', 'AUTHORIZATION', 'BETWEEN', 'BOTH', 'BUCKET', 'BUCKETS', 'BY', 'CACHE', 'CASCADE', 'CASE', 'CAST', ' CHANGE', 'CHECK', 'CLEAR', 'CLUSTER', 'CLUSTERED', 'CODEGEN', 'COLLATE', 'COLLECTION', 'COLUMN', 'COLUMNS', 'COMMENT', 'COMMIT', 'COMPACT' , 'COMPACTIONS', 'COMPUTE', 'CONCATENATE', 'CONSTRAINT', 'COST', 'CREATE', 'CROSS', 'CUBE', 'CURRENT', 'CURRENT_DATE', 'CURRENT_TIME', 'CURRENT_TIMESTAMP', ' CURRENT_USER', 'DAY', 'DATA', 'DATABASE', DATABASES, 'DBPROPERTIES', 'DEFINED', 'DELETE', 'DELIMITED', 'DESC', 'DESCRIBE', 'DFS', 'DIRECTORIES', ' DIRECTORY', 'DISTINCT', 'DISTRIBUTE', 'DIV', 'DROP', 'ELSE', 'END', 'ESCAPE', 'ESCAPED', 'EXCEPT', 'EXCHANGE', 'EXISTS', 'EXPLAIN' , 'EXPORT', 'EXTENDED', 'EXTERNAL', 'EXTRACT', 'FALSE', 'FETCH', 'FIELDS', 'FILTER', 'FILEFORMAT', 'FIRST', 'FOLLOWING', 'FOR', ' FOREIGN', 'FORMAT', 'FORMATTED', 'FROM', 'FULL', 'FU
NCTION', 'F UNCTIONS', 'GLOBAL', 'GRANT', 'GROUP', 'GROUPING', 'HAVING', 'HOUR', 'IF', 'IGNORE', 'IMPORT', 'IN', 'INDEX', 'INDEXES' , 'INNER', 'INPATH', 'INPUTFORMAT', 'INSERT', 'INTERSECT', 'INTERVAL', 'INTO', 'IS', 'ITEMS', 'JOIN', 'KEYS', 'LAST', ' LATERAL', 'LAZY', 'LEADING', 'LEFT', 'LIKE', 'LIMIT', 'LINES', 'LIST', 'LOAD', 'LOCAL', 'LOCATION', 'LOCK', 'LOCKS' , 'LOGICAL', 'MACRO', 'MAP', 'MATCHED', 'MERGE', 'MINUTE', 'MONTH', 'MSCK', 'NAMESPACE', 'NAMESPACES', 'NATURAL', 'NO', NOT , 'NULL', 'NULLS', 'OF', 'ON', 'ONLY', 'OPTION', 'OPTIONS', 'OR', 'ORDER', 'OUT', 'OUTER', 'OUTPUTFORMAT', ' OVER', 'OVERLAPS', 'OVERLAY', 'OVERWRITE', 'PARTITION', 'PARTITIONED', 'PARTITIONS', 'PERCENT', 'PIVOT', 'PLACING', 'POSITION', 'PRECEDING', 'PRIMARY' , 'PRINCIPALS', 'PROPERTIES', 'PURGE', 'QUERY', 'RANGE', 'RECORDREADER', 'RECORDWRITER', 'RECOVER', 'REDUCE', 'REFERENCES', 'REFRESH', 'RENAME', ' REPAIR', 'REPLACE', 'RESET', 'RESPECT', 'RESTRICT', 'REVOKE', 'RIGHT', RLIKE, 'ROLE', 'ROLES', 'RO
LLBACK', 'ROLLUP', 'RO W', 'ROWS', 'SECOND', 'SCHEMA', 'SELECT', 'SEMI', 'SEPARATED', 'SERDE', 'SERDEPROPERTIES', 'SESSION_USER', 'SET', 'MINUS', 'SETS' , 'SHOW', 'SKEWED', 'SOME', 'SORT', 'SORTED', 'START', 'STATISTICS', 'STORED', 'STRATIFY', 'STRUCT', 'SUBSTR', 'SUBSTRING', ' SYNC', 'TABLE', 'TABLES', 'TABLESAMPLE', 'TBLPROPERTIES', TEMPORARY, 'TERMINATED', 'THEN', 'TIME', 'TO', 'TOUCH', 'TRAILING', 'TRANSACTION', ' TRANSACTIONS', 'TRANSFORM', 'TRIM', 'TRUE', 'TRUNCATE', 'TRY_CAST', 'TYPE', 'UNARCHIVE', 'UNBOUNDED', 'UNCACHE', 'UNION', 'UNIQUE', 'UNKNOWN' , 'UNLOCK', 'UNSET', 'UPDATE', 'USE', 'USER', 'USING', 'VALUES', 'VIEW', 'VIEWS', 'WHEN', 'WHERE', 'WINDOW', ' WITH', 'YEAR', 'ZONE', IDENTIFIER, BACKQUOTED_IDENTIFIER}(line 1, pos 486)
==SQL==
select 3 as rule_type,'(multi_table_value_comparison)' as rule_name,0 as process_definition_id,71301 as process_instance_id,302276 as task_instance_id,dev_days AS statistics_value,release_days AS comparison_value,0 AS comparison_type,1 as check_type,100 as threshold,3 as operator,1 as failure_strategy,'hdfs://hahadoop:8020/data-quality-error-data/0_71301_dev' as error_output_path,'2023-03-27 08:21:38' as create_time,'2023-03-27 08:21: 38' as update_time from ( select datediff(max(e.), date(now())) as dev_days from append.gl004_empcost e ) tmp1 join ( select datediff(max(e.), date(now())) as release_days from append.gl004_empcost_release e ) tmp2
-------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- ------------------------------------^^^
at org.apache.spark.sql.catalyst.parser.ParseException.withCommand(ParseDriver.scala:266)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parse(ParseDriver.scala:127)
at org.apache.spark.sql.execution.SparkSqlParser.parse(SparkSqlParser.scala:51)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parsePlan(ParseDriver.scala:77)
at org.apache.spark.sql.SparkSession.$anonfun$sql$2(SparkSession.scala:616)
at org.apache.spark.sql.catalyst.QueryPlanningTracker.measurePhase(QueryPlanningTracker.scala:111)
at org.apache.spark.sql.SparkSession.$anonfun$sql$1(SparkSession.scala:616)
at org.apache.spark.sql.SparkSession.withActive(SparkSession.scala:775)
at org.apache.spark.sql.SparkSession.sql(SparkSession.scala:613)
at org.apache.dolphinscheduler.data.quality.flow.batch.writer.JdbcWriter.write(JdbcWriter.java:74)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.executeWriter(SparkBatchExecution.java:130)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.execute(SparkBatchExecution.java:58)
at org.apache.dolphinscheduler.data.quality.context.DataQualityContext.execute(DataQualityContext.java:62)
at org.apache.dolphinscheduler.data.quality.DataQualityApplication.main(DataQualityApplication.java:70)
at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
at java.lang.reflect.Method.invoke(Method.java:498)
at org.apache.spark.deploy.yarn.ApplicationMaster$$anon$2.run(ApplicationMaster.scala:737)
ApplicationMaster host: hs.med.hadoop.worker3
ApplicationMaster RPC port: 41511
queue: default
start time: 1679876506945
final status: FAILED
Tracking URL: http://hs.med.hadoop.master2:8088/proxy/application_1678704143533_20746/
user: hadoop
2023-03-27 08:22:07,201 ERROR yarn.Client: Application diagnostics message: User class threw exception: org.apache.spark.sql.catalyst.parser.ParseException:
mismatched input ')' expecting {'ADD', 'AFTER', 'ALL', 'ALTER', 'ANALYZE', 'AND', 'ANTI', 'ANY', 'ARCHIVE', 'ARRAY', 'AS' , 'ASC', 'AT', 'AUTHORIZATION', 'BETWEEN', 'BOTH', 'BUCKET', 'BUCKETS', 'BY', 'CACHE', 'CASCADE', 'CASE', 'CAST', ' CHANGE', 'CHECK', 'CLEAR', 'CLUSTER', 'CLUSTERED', 'CODEGEN', 'COLLATE', 'COLLECTION', 'COLUMN', 'COLUMNS', 'COMMENT', 'COMMIT', 'COMPACT' , 'COMPACTIONS', 'COMPUTE', 'CONCATENATE', 'CONSTRAINT', 'COST', 'CREATE', 'CROSS', 'CUBE', 'CURRENT', 'CURRENT_DATE', 'CURRENT_TIME', 'CURRENT_TIMESTAMP', ' CURRENT_USER', 'DAY', 'DATA', 'DATABASE', DATABASES, 'DBPROPERTIES', 'DEFINED', 'DELETE', 'DELIMITED', 'DESC', 'DESCRIBE', 'DFS', 'DIRECTORIES', ' DIRECTORY', 'DISTINCT', 'DISTRIBUTE', 'DIV', 'DROP', 'ELSE', 'END', 'ESCAPE', 'ESCAPED', 'EXCEPT', 'EXCHANGE', 'EXISTS', 'EXPLAIN' , 'EXPORT', 'EXTENDED', 'EXTERNAL', 'EXTRACT', 'FALSE', 'FETCH', 'FIELDS', 'FILTER', 'FILEFORMAT', 'FIRST', 'FOLLOWING', 'FOR', ' FOREIGN', 'FORMAT', 'FORMATTED', 'FROM', 'FULL', 'FU
NCTION', 'F UNCTIONS', 'GLOBAL', 'GRANT', 'GROUP', 'GROUPING', 'HAVING', 'HOUR', 'IF', 'IGNORE', 'IMPORT', 'IN', 'INDEX', 'INDEXES' , 'INNER', 'INPATH', 'INPUTFORMAT', 'INSERT', 'INTERSECT', 'INTERVAL', 'INTO', 'IS', 'ITEMS', 'JOIN', 'KEYS', 'LAST', ' LATERAL', 'LAZY', 'LEADING', 'LEFT', 'LIKE', 'LIMIT', 'LINES', 'LIST', 'LOAD', 'LOCAL', 'LOCATION', 'LOCK', 'LOCKS' , 'LOGICAL', 'MACRO', 'MAP', 'MATCHED', 'MERGE', 'MINUTE', 'MONTH', 'MSCK', 'NAMESPACE', 'NAMESPACES', 'NATURAL', 'NO', NOT , 'NULL', 'NULLS', 'OF', 'ON', 'ONLY', 'OPTION', 'OPTIONS', 'OR', 'ORDER', 'OUT', 'OUTER', 'OUTPUTFORMAT', ' OVER', 'OVERLAPS', 'OVERLAY', 'OVERWRITE', 'PARTITION', 'PARTITIONED', 'PARTITIONS', 'PERCENT', 'PIVOT', 'PLACING', 'POSITION', 'PRECEDING', 'PRIMARY' , 'PRINCIPALS', 'PROPERTIES', 'PURGE', 'QUERY', 'RANGE', 'RECORDREADER', 'RECORDWRITER', 'RECOVER', 'REDUCE', 'REFERENCES', 'REFRESH', 'RENAME', ' REPAIR', 'REPLACE', 'RESET', 'RESPECT', 'RESTRICT', 'REVOKE', 'RIGHT', RLIKE, 'ROLE', 'ROLES', 'RO
LLBACK', 'ROLLUP', 'RO W', 'ROWS', 'SECOND', 'SCHEMA', 'SELECT', 'SEMI', 'SEPARATED', 'SERDE', 'SERDEPROPERTIES', 'SESSION_USER', 'SET', 'MINUS', 'SETS' , 'SHOW', 'SKEWED', 'SOME', 'SORT', 'SORTED', 'START', 'STATISTICS', 'STORED', 'STRATIFY', 'STRUCT', 'SUBSTR', 'SUBSTRING', ' SYNC', 'TABLE', 'TABLES', 'TABLESAMPLE', 'TBLPROPERTIES', TEMPORARY, 'TERMINATED', 'THEN', 'TIME', 'TO', 'TOUCH', 'TRAILING', 'TRANSACTION', ' TRANSACTIONS', 'TRANSFORM', 'TRIM', 'TRUE', 'TRUNCATE', 'TRY_CAST', 'TYPE', 'UNARCHIVE', 'UNBOUNDED', 'UNCACHE', 'UNION', 'UNIQUE', 'UNKNOWN' , 'UNLOCK', 'UNSET', 'UPDATE', 'USE', 'USER', 'USING', 'VALUES', 'VIEW', 'VIEWS', 'WHEN', 'WHERE', 'WINDOW', ' WITH', 'YEAR', 'ZONE', IDENTIFIER, BACKQUOTED_IDENTIFIER}(line 1, pos 486)
==SQL==
select 3 as rule_type,'(multi_table_value_comparison)' as rule_name,0 as process_definition_id,71301 as process_instance_id,302276 as task_instance_id,dev_days AS statistics_value,release_days AS comparison_value,0 AS comparison_type,1 as check_type,100 as threshold,3 as operator,1 as failure_strategy,'hdfs://hahadoop:8020/data-quality-error-data/0_71301_dev' as error_output_path,'2023-03-27 08:21:38' as create_time,'2023-03-27 08:21: 38' as update_time from ( select datediff(max(e.), date(now())) as dev_days from append.gl004_empcost e ) tmp1 join ( select datediff(max(e.), date(now())) as release_days from append.gl004_empcost_release e ) tmp2
-------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- -------------------------------------------------- ------------------------------------^^^
at org.apache.spark.sql.catalyst.parser.ParseException.withCommand(ParseDriver.scala:266)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parse(ParseDriver.scala:127)
at org.apache.spark.sql.execution.SparkSqlParser.parse(SparkSqlParser.scala:51)
at org.apache.spark.sql.catalyst.parser.AbstractSqlParser.parsePlan(ParseDriver.scala:77)
at org.apache.spark.sql.SparkSession.$anonfun$sql$2(SparkSession.scala:616)
at org.apache.spark.sql.catalyst.QueryPlanningTracker.measurePhase(QueryPlanningTracker.scala:111)
at org.apache.spark.sql.SparkSession.$anonfun$sql$1(SparkSession.scala:616)
at org.apache.spark.sql.SparkSession.withActive(SparkSession.scala:775)
at org.apache.spark.sql.SparkSession.sql(SparkSession.scala:613)
at org.apache.dolphinscheduler.data.quality.flow.batch.writer.JdbcWriter.write(JdbcWriter.java:74)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.executeWriter(SparkBatchExecution.java:130)
at org.apache.dolphinscheduler.data.quality.execution.SparkBatchExecution.execute(SparkBatchExecution.java:58)
at org.apache.dolphinscheduler.data.quality.context.DataQualityContext.execute(DataQualityContext.java:62)
at org.apache.dolphinscheduler.data.quality.DataQualityApplication.main(DataQualityApplication.java:70)
at sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)
at sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)
at sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)
at java.lang.reflect.Method.invoke(Method.java:498)
at org.apache.spark.deploy.yarn.ApplicationMaster$$anon$2.run(ApplicationMaster.scala:737)
Exception in thread "main" org.apache.spark.SparkException: Application application_1678704143533_20746 finished with failed status
at org.apache.spark.deploy.yarn.Client.run(Client.scala:1283)
at org.apache.spark.deploy.yarn.YarnClusterApplication.start(Client.scala:1677)
at org.apache.spark.deploy.SparkSubmit.org$apache$spark$deploy$SparkSubmit$$runMain(SparkSubmit.scala:955)
at org.apache.spark.deploy.SparkSubmit.doRunMain$1(SparkSubmit.scala:180)
at org.apache.spark.deploy.SparkSubmit.submit(SparkSubmit.scala:203)
at org.apache.spark.deploy.SparkSubmit.doSubmit(SparkSubmit.scala:90)
at org.apache.spark.deploy.SparkSubmit$$anon$2.doSubmit(SparkSubmit.scala:1043)
at org.apache.spark.deploy.SparkSubmit$.main(SparkSubmit.scala:1052)
at org.apache.spark.deploy.SparkSubmit.main(SparkSubmit.scala)
2023-03-27 08:22:07,204 INFO util.ShutdownHookManager: Shutdown hook called
2023-03-27 08:22:07,205 INFO util.ShutdownHookManager: Deleting directory /opt/utils/spark/spark-869a6101-7e54-4b72-9ad7-8ed488a7dfee
2023-03-27 08:22:07,208 INFO util.ShutdownHookManager: Deleting directory /tmp/spark-8cb6394f-e904-482a-b970-3a61169d3250
[INFO] 2023-03-27 08:22:07.447 +0800 - FINALIZE_SESSION
```
### The complete configuration of the data_quality task is as follows

### Anything else
If the above conditions are met, the execution fails every time
### Version
3.0.x
### Are you willing to submit PR?
- [ ] Yes I am willing to submit a PR!
### Code of Conduct
- [X] I agree to follow this project's [Code of Conduct](https://www.apache.org/foundation/policies/conduct)
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] github-actions[bot] closed issue #13792: [Bug][DataQuality] In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "github-actions[bot] (via GitHub)" <gi...@apache.org>.
github-actions[bot] closed issue #13792: [Bug][DataQuality] In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
URL: https://github.com/apache/dolphinscheduler/issues/13792


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] EricGao888 commented on issue #13792: In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "EricGao888 (via GitHub)" <gi...@apache.org>.
EricGao888 commented on issue #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792#issuecomment-1484544332

   @zixi0825 Could u plz help take a look when available? Thx : )


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] github-actions[bot] commented on issue #13792: [Bug][DataQuality] In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "github-actions[bot] (via GitHub)" <gi...@apache.org>.
github-actions[bot] commented on issue #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792#issuecomment-1528904166

   This issue has been automatically marked as stale because it has not had recent activity for 30 days. It will be closed in next 7 days if no further activity occurs.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] github-actions[bot] commented on issue #13792: [Bug][DataQuality] In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "github-actions[bot] (via GitHub)" <gi...@apache.org>.
github-actions[bot] commented on issue #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792#issuecomment-1537581521

   This issue has been closed because it has not received response for too long time. You could reopen it if you encountered similar problems in the future.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] github-actions[bot] commented on issue #13792: In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "github-actions[bot] (via GitHub)" <gi...@apache.org>.
github-actions[bot] commented on issue #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792#issuecomment-1484342299

   Thank you for your feedback, we have received your issue, Please wait patiently for a reply.
   * In order for us to understand your request as soon as possible, please provide detailed information, version or pictures.
   * If you haven't received a reply for a long time, you can [join our slack](https://s.apache.org/dolphinscheduler-slack) and send your question to channel `#troubleshooting`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] 8debug commented on issue #13792: [Bug][DataQuality] In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "8debug (via GitHub)" <gi...@apache.org>.
8debug commented on issue #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792#issuecomment-1486017729

   我发现可能是 ` 这个符号转义的问题


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [dolphinscheduler] 8debug commented on issue #13792: [Bug][DataQuality] In the data_quality task, if the fields in the statement are Chinese characters, the task execution will fail.
Posted by "8debug (via GitHub)" <gi...@apache.org>.
8debug commented on issue #13792:
URL: https://github.com/apache/dolphinscheduler/issues/13792#issuecomment-1486018554

   @caishunfeng 我怀疑可能是 ` 这个符号的问题


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@dolphinscheduler.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org