You are viewing a plain text version of this content. The canonical link for it is here.
Posted to github@beam.apache.org by GitBox <gi...@apache.org> on 2022/07/01 21:34:11 UTC
[GitHub] [beam] azhurkevich opened a new pull request, #22131: Initial commit
azhurkevich opened a new pull request, #22131:
URL: https://github.com/apache/beam/pull/22131
**Please** add a meaningful description for your change here
Integration of TensorRT into Apache Beam.
------------------------
Thank you for your contribution! Follow this checklist to help us incorporate your contribution quickly and easily:
- [ ] [**Choose reviewer(s)**](https://beam.apache.org/contribute/#make-your-change) and mention them in a comment (`R: @tvalentyn @AnandInguva @ryanthompson591 @yeandy`).
- [ ] Mention the appropriate issue in your description (for example: `addresses #123`), if applicable. This will automatically add a link to the pull request in the issue. If you would like the issue to automatically close on merging the pull request, comment `fixes #<ISSUE NUMBER>` instead.
- [ ] Update `CHANGES.md` with noteworthy changes.
- [ ] If this contribution is large, please file an Apache [Individual Contributor License Agreement](https://www.apache.org/licenses/icla.pdf).
See the [Contributor Guide](https://beam.apache.org/contribute) for more tips on [how to make review process smoother](https://beam.apache.org/contribute/#make-reviewers-job-easier).
To check the build health, please visit [https://github.com/apache/beam/blob/master/.test-infra/BUILD_STATUS.md](https://github.com/apache/beam/blob/master/.test-infra/BUILD_STATUS.md)
GitHub Actions Tests Status (on master branch)
------------------------------------------------------------------------------------------------
[](https://github.com/apache/beam/actions?query=workflow%3A%22Build+python+source+distribution+and+wheels%22+branch%3Amaster+event%3Aschedule)
[](https://github.com/apache/beam/actions?query=workflow%3A%22Python+Tests%22+branch%3Amaster+event%3Aschedule)
[](https://github.com/apache/beam/actions?query=workflow%3A%22Java+Tests%22+branch%3Amaster+event%3Aschedule)
See [CI.md](https://github.com/apache/beam/blob/master/CI.md) for more information about GitHub Actions CI.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917943285


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):
+      is_input = False
+      if engine.binding_is_input(i):
+        is_input = True
+      name = engine.get_binding_name(i)
+      dtype = engine.get_binding_dtype(i)
+      shape = engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      allocation = cuda.mem_alloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+      }
+      allocations.append(allocation)
+      if engine.binding_is_input(i):
+        inputs.append(binding)
+      else:
+        outputs.append(binding)
+
+    assert batch_size > 0
+    assert len(inputs) > 0
+    assert len(outputs) > 0
+    assert len(allocations) > 0
+    # Prepare the output data
+    predictions = []
+    for output in outputs:
+      predictions.append(np.zeros(output['shape'], output['dtype']))
+    # Process I/O and execute the network
+    cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))

Review Comment:
   Is this only intended to work with single-input models?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917935179


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)

Review Comment:
   This needs to use the same builder that was used to create the network in `_load_onnx()`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919413984


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):
+      is_input = False
+      if engine.binding_is_input(i):
+        is_input = True
+      name = engine.get_binding_name(i)
+      dtype = engine.get_binding_dtype(i)
+      shape = engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      allocation = cuda.mem_alloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+      }
+      allocations.append(allocation)
+      if engine.binding_is_input(i):
+        inputs.append(binding)
+      else:
+        outputs.append(binding)
+
+    assert batch_size > 0
+    assert len(inputs) > 0
+    assert len(outputs) > 0
+    assert len(allocations) > 0
+    # Prepare the output data
+    predictions = []
+    for output in outputs:
+      predictions.append(np.zeros(output['shape'], output['dtype']))
+    # Process I/O and execute the network
+    cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))

Review Comment:
   @pranavm-nvidia Great point. My experience with TensorRT is mostly CV models that take image or a batch of images. Obviously there are models out there with multiple inputs. Any suggestions from the top of your head how to handle them?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920476249


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    nums = prediction_result.inference[0]
+    boxes = prediction_result.inference[1]
+    scores = prediction_result.inference[2]
+    classes = prediction_result.inference[3]
+    detections = []
+    for i in range(int(nums[0])):
+        detections.append({
+                'ymin': str(boxes[i][0] * im_height),
+                'xmin': str(boxes[i][1] * im_width),
+                'ymax': str(boxes[i][2] * im_height),
+                'xmax': str(boxes[i][3] * im_width),
+                'score': str(scores[i]),
+                'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+            })
+    yield filename + ',' + str(detections)
+
+def parse_known_args(argv):
+  """Parses args for the workflow."""
+  parser = argparse.ArgumentParser()
+  parser.add_argument(
+      '--input',
+      dest='input',
+      required=True,
+      help='Path to the text file containing image names.')
+  parser.add_argument(
+      '--output',
+      dest='output',
+      required=True,
+      help='Path where to save output predictions.'
+      ' text file.')
+  parser.add_argument(
+      '--engine_path',
+      dest='engine_path',
+      required=True,
+      help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+      'TensorRT engine.')
+  parser.add_argument(
+      '--images_dir',
+      default=None,
+      help='Path to the directory where images are stored.'
+      'Not required if image names in the input file have absolute path.')
+  return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+  """
+  Args:
+    argv: Command line arguments defined for this example.
+  """
+  known_args, pipeline_args = parse_known_args(argv)
+  pipeline_options = PipelineOptions(pipeline_args)
+  pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+  engine_handler = KeyedModelHandler(
+      TensorRTEngineHandlerNumPy(
+          min_batch_size=1, max_batch_size=1,
+        engine_path=known_args.engine_path))
+
+  with beam.Pipeline(options=pipeline_options) as p:
+    filename_value_pair = (
+        p
+        | 'ReadImageNames' >> beam.io.ReadFromText(
+            known_args.input, skip_header_lines=0)
+        | 'ReadImageData' >> beam.Map(
+            lambda image_name: read_image(
+                image_file_name=image_name, path_to_dir=known_args.images_dir))
+        | 'AttachImageSizeToKey' >> beam.Map(attach_im_size_to_key)
+        | 'PreprocessImages' >> beam.MapTuple(
+            lambda file_name, data: (file_name, preprocess_image(data))))
+    predictions = (
+        filename_value_pair
+        | 'PyTorchRunInference' >> RunInference(engine_handler)
+        | 'ProcessOutput' >> beam.ParDo(PostProcessor()))
+
+    if known_args.output:
+      predictions | "WriteOutputToGCS" >> beam.io.WriteToText(
+        known_args.output,
+        shard_name_template='',
+        append_trailing_newlines=True)
+

Review Comment:
   @yeandy makes sense now, thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920590956


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   @yeandy brilliant solution that works! I'll brush up the code, make sure I am able to run all tests and will commit it tomorrow. After that two things will be left to do:

   1. See how to handle models with multiple inputs. So far looking back at my experience I've  subconsciously assumed there will be just one input which is obviously not the case for every single model. I'll have to think how to handle that, will create a new ONNX probably to test it + write tests and etc.
   2. I'll ask Pranav to do one more quick code review.

   After these 2 I think we will be done for now. If model with multiple inputs will take a lot of time, we'll push it to next release. I am hoping to finish everything by Friday, at the latest Monday to give you some headroom before merging.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922187794


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)

Review Comment:
   Should there be error checking here? Maybe a `check_cuda` helper function would work (I believe the error code is always the first return value)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922185674


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s

Review Comment:
   Slightly more concise:
   ```suggestion
         size = trt.volume(shape) * dtype.itemsize
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958753627


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,

Review Comment:
   looks good.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] damccorm commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
damccorm commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1249390407

   Run Python PreCommit


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r923866411


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda

Review Comment:
   @azhurkevich Your original code imported cuda before tensorrt. Do you know if cuda has to be imported first? I reversed the order due to the `isort` command for the lint checks. However, if necessary, we can disable the sorting requirements here, and revert back to the previous order that you had.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r923892808


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda

Review Comment:
   @pranavm-nvidia thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1189325427

   @yeandy With Sphinx, you can specify modules to mock in your `conf.py` ([example](https://github.com/NVIDIA/TensorRT/blob/main/tools/Polygraphy/docs/conf.py#L34)). With that, you won't need to have TensorRT installed.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] codecov[bot] commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
codecov[bot] commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1172742280

   # [Codecov](https://codecov.io/gh/apache/beam/pull/22131?src=pr&el=h1&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation) Report
   > Merging [#22131](https://codecov.io/gh/apache/beam/pull/22131?src=pr&el=desc&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation) (1109810) into [master](https://codecov.io/gh/apache/beam/commit/eb5b7cc256d8d15173475cf51af758979a33bd16?el=desc&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation) (eb5b7cc) will **decrease** coverage by `0.07%`.
   > The diff coverage is `0.00%`.

   ```diff
   @@            Coverage Diff             @@
   ##           master   #22131      +/-   ##
   ==========================================
   - Coverage   74.19%   74.12%   -0.08%
   ==========================================
     Files         702      703       +1
     Lines       92791    92924     +133
   ==========================================
   + Hits        68848    68881      +33
   - Misses      22675    22775     +100
     Partials     1268     1268
   ```

   | Flag | Coverage Δ | |
   |---|---|---|
   | python | `83.46% <0.00%> (-0.12%)` | :arrow_down: |

   Flags with carried forward coverage won't be shown. [Click here](https://docs.codecov.io/docs/carryforward-flags?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#carryforward-flags-in-the-pull-request-comment) to find out more.

   | [Impacted Files](https://codecov.io/gh/apache/beam/pull/22131?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation) | Coverage Δ | |
   |---|---|---|
   | [...hon/apache\_beam/ml/inference/tensorrt\_inference.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vbWwvaW5mZXJlbmNlL3RlbnNvcnJ0X2luZmVyZW5jZS5weQ==) | `0.00% <0.00%> (ø)` | |
   | [.../apache\_beam/runners/interactive/dataproc/types.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vcnVubmVycy9pbnRlcmFjdGl2ZS9kYXRhcHJvYy90eXBlcy5weQ==) | `93.10% <0.00%> (-3.45%)` | :arrow_down: |
   | [...python/apache\_beam/runners/worker/worker\_status.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vcnVubmVycy93b3JrZXIvd29ya2VyX3N0YXR1cy5weQ==) | `78.26% <0.00%> (-1.45%)` | :arrow_down: |
   | [...hon/apache\_beam/runners/direct/test\_stream\_impl.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vcnVubmVycy9kaXJlY3QvdGVzdF9zdHJlYW1faW1wbC5weQ==) | `93.28% <0.00%> (-0.75%)` | :arrow_down: |
   | [.../python/apache\_beam/typehints/trivial\_inference.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vdHlwZWhpbnRzL3RyaXZpYWxfaW5mZXJlbmNlLnB5) | `96.41% <0.00%> (ø)` | |
   | [...hon/apache\_beam/runners/worker/bundle\_processor.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vcnVubmVycy93b3JrZXIvYnVuZGxlX3Byb2Nlc3Nvci5weQ==) | `93.54% <0.00%> (ø)` | |
   | [sdks/python/apache\_beam/typehints/schemas.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vdHlwZWhpbnRzL3NjaGVtYXMucHk=) | `94.65% <0.00%> (+0.10%)` | :arrow_up: |
   | [...eam/runners/interactive/interactive\_environment.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vcnVubmVycy9pbnRlcmFjdGl2ZS9pbnRlcmFjdGl2ZV9lbnZpcm9ubWVudC5weQ==) | `92.02% <0.00%> (+0.30%)` | :arrow_up: |
   | [sdks/python/apache\_beam/utils/interactive\_utils.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vdXRpbHMvaW50ZXJhY3RpdmVfdXRpbHMucHk=) | `97.56% <0.00%> (+2.43%)` | :arrow_up: |
   | [sdks/python/apache\_beam/typehints/row\_type.py](https://codecov.io/gh/apache/beam/pull/22131/diff?src=pr&el=tree&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation#diff-c2Rrcy9weXRob24vYXBhY2hlX2JlYW0vdHlwZWhpbnRzL3Jvd190eXBlLnB5) | `95.91% <0.00%> (+6.44%)` | :arrow_up: |

   ------

   [Continue to review full report at Codecov](https://codecov.io/gh/apache/beam/pull/22131?src=pr&el=continue&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation).
   > **Legend** - [Click here to learn more](https://docs.codecov.io/docs/codecov-delta?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation)
   > `Δ = absolute <relative> (impact)`, `ø = not affected`, `? = missing data`
   > Powered by [Codecov](https://codecov.io/gh/apache/beam/pull/22131?src=pr&el=footer&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation). Last update [eb5b7cc...1109810](https://codecov.io/gh/apache/beam/pull/22131?src=pr&el=lastupdated&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation). Read the [comment docs](https://docs.codecov.io/docs/pull-request-comments?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=The+Apache+Software+Foundation).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r950641691


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Per meeting offline, let's try to go with having one context only for now and add use a lock where necessary to guard access to it. In this case, if there are multiple threads, they will have to wait.
   Later, we will conduct experiments evaluating GPU utilization and deciding whether having multiple contexts would be beneficial. @azhurkevich would you be comfortable making this change?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917940578


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   Context creation should be moved out of `run_inference`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917945253


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):
+      is_input = False
+      if engine.binding_is_input(i):
+        is_input = True
+      name = engine.get_binding_name(i)
+      dtype = engine.get_binding_dtype(i)
+      shape = engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      allocation = cuda.mem_alloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+      }
+      allocations.append(allocation)
+      if engine.binding_is_input(i):
+        inputs.append(binding)
+      else:
+        outputs.append(binding)
+
+    assert batch_size > 0
+    assert len(inputs) > 0
+    assert len(outputs) > 0
+    assert len(allocations) > 0
+    # Prepare the output data
+    predictions = []
+    for output in outputs:
+      predictions.append(np.zeros(output['shape'], output['dtype']))
+    # Process I/O and execute the network
+    cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))
+    context.execute_v2(allocations)
+    for output in range(len(predictions)):
+      cuda.memcpy_dtoh(predictions[output], outputs[output]['allocation'])

Review Comment:
   You might see some perf benefit by overlapping execution/memcpy's by using `memcpy_htod_async`, `execute_async_v2`, and `memcpy_dtoh_async`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920251928


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):

Review Comment:
   Good point. X is essentially a tuple consisting of a filename and image object: `('/mnt/val2017/000000000139.jpg', <PIL.Image.Image image mode=RGB size=640x426 at 0x7F19C054E040>)`

   I'll remake it into:
   ```
   def attach_im_size_to_key(data):
       filename, image = data
       width, height = image.size
       return ((filename, width, height), image)
   ```
   for clarity


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922190233


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert batch_size > 0
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return self.engine, self.context, self.inputs, self.outputs, self.gpu_allocations, self.cpu_allocations
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+    pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(self, network: trt.INetworkDefinition, builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:

Review Comment:
   I'm seeing this lint [error](https://ci-beam.apache.org/job/beam_PreCommit_PythonLint_Commit/14847/console):
   ```
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: error: Argument 1 of "run_inference" is incompatible with supertype "ModelHandler"; supertype defines the argument type as "Sequence[ndarray[Any, Any]]"  [override]
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: note: This violates the Liskov substitution principle
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: note: See https://mypy.readthedocs.io/en/stable/common_issues.html#incompatible-overrides
   ```
   I think it's because we need to adhere to the [interface](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/base.py#L91) for `run_inference` as found in `base.py`. Could we make it `Sequence[np.ndarray]` like it's done in [sklearn_inference.py](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/sklearn_inference.py#L105)?

   This may require some refactor some of the tests. I think particularly how the input examples are defined


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] kennknowles commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
kennknowles commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r921448175


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   The header should be the same as other files:

   ```
   # Licensed to the Apache Software Foundation (ASF) under one or more
   # contributor license agreements.  See the NOTICE file distributed with
   # this work for additional information regarding copyright ownership.
   # The ASF licenses this file to You under the Apache License, Version 2.0
   # (the "License"); you may not use this file except in compliance with
   # the License.  You may obtain a copy of the License at
   #
   #    http://www.apache.org/licenses/LICENSE-2.0
   #
   # Unless required by applicable law or agreed to in writing, software
   # distributed under the License is distributed on an "AS IS" BASIS,
   # WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
   # See the License for the specific language governing permissions and
   # limitations under the License.
   ```

   Other information about the origin of the code should go into NOTICE


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922245733


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert batch_size > 0
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return self.engine, self.context, self.inputs, self.outputs, self.gpu_allocations, self.cpu_allocations
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+    pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(self, network: trt.INetworkDefinition, builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    #Create CUDA Stream
+    err, stream = cuda.cuStreamCreate(0)

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919193145


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r923867773


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda

Review Comment:
   FWIW I think it should be ok to import CUDA after, but would be good to test that @azhurkevich


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1188250637

   @yeandy I think this will be it for the first initial TensorRT integration from my side. Moving multi-input models into future integration.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937045110


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Another possibility is to introduce a lock so that we the same context, but run in one thread at a time. As we know due to GIL there is a limit to thread-parallelism in Python within a single process. So perhaps it wouldn't have significant impact on actual performance? I suppose this needs some experimental evaluation to confirm. Or is that obviously a bad idea?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r933264761


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Mainly, it's:
   - Allocating memory for intermediate tensors
   - Allocating per-layer persistent host/device memory (e.g. for things like look-up tables to speed up computation)
   - Querying hardware information


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937077817


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Got it, I think I understand. Is engine.device_memory_size defined by the tensorrt model?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929971731


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Looks thread-safe. It would be good to share the engine between threads so you don't end up duplicating the model weights (maybe that can be future work). Each thread will still need a separate execution context.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972959624


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   Added `sdks/python/test-suites/containers/tensorrt_runinference/tensor_rt.dockerfile` and `sdks/python/test-suites/containers/tensorrt_runinference/README.md`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] AnandInguva commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
AnandInguva commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r965260515


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,258 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with
+TensorRT.
+"""
+
+import argparse
+import io
+import os
+from typing import Iterable
+from typing import Optional
+from typing import Tuple
+
+import numpy as np
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import KeyedModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.ml.inference.base import RunInference
+from apache_beam.ml.inference.tensorrt_inference import TensorRTEngineHandlerNumPy  # pylint: disable=line-too-long
+from apache_beam.options.pipeline_options import PipelineOptions
+from apache_beam.options.pipeline_options import SetupOptions
+from PIL import Image
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(
+    data: Tuple[str, Image.Image]) -> Tuple[Tuple[str, int, int], Image.Image]:
+  filename, image = data
+  width, height = image.size
+  return ((filename, width, height), image)
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(
+      ssd_mobilenet_v2_320x320_input_dims, resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  """Processes the PredictionResult that consists of
+  number of detections per image, box coordinates, scores and classes.
+
+  We loop over all detections to organize attributes on a per
+  detection basis. Box coordinates are normalized, hence we have to scale them
+  according to original image dimensions. Score is a floating point number
+  that provides probability percentage of a particular object. Class is
+  an integer that we can transform into actual string class using
+  COCO_OBJ_DET_CLASSES as reference.
+  """
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    num_detections = prediction_result.inference[0]
+    boxes = prediction_result.inference[1]
+    scores = prediction_result.inference[2]
+    classes = prediction_result.inference[3]
+    detections = []
+    for i in range(int(num_detections[0])):
+      detections.append({
+          'ymin': str(boxes[i][0] * im_height),
+          'xmin': str(boxes[i][1] * im_width),
+          'ymax': str(boxes[i][2] * im_height),
+          'xmax': str(boxes[i][3] * im_width),
+          'score': str(scores[i]),
+          'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+      })
+    yield filename + ',' + str(detections)
+
+
+def parse_known_args(argv):
+  """Parses args for the workflow."""
+  parser = argparse.ArgumentParser()
+  parser.add_argument(
+      '--input',
+      dest='input',
+      required=True,
+      help='Path to the text file containing image names.')
+  parser.add_argument(
+      '--output',
+      dest='output',
+      required=True,
+      help='Path where to save output predictions.'
+      ' text file.')
+  parser.add_argument(
+      '--engine_path',
+      dest='engine_path',
+      required=True,
+      help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+      'TensorRT engine.')
+  parser.add_argument(
+      '--images_dir',
+      default=None,
+      help='Path to the directory where images are stored.'
+      'Not required if image names in the input file have absolute path.')
+  return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+  """
+  Args:
+    argv: Command line arguments defined for this example.
+  """
+  known_args, pipeline_args = parse_known_args(argv)
+  pipeline_options = PipelineOptions(pipeline_args)
+  pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+  engine_handler = KeyedModelHandler(
+      TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path=known_args.engine_path))
+
+  with beam.Pipeline(options=pipeline_options) as p:
+    filename_value_pair = (
+        p
+        | 'ReadImageNames' >> beam.io.ReadFromText(
+            known_args.input, skip_header_lines=0)
+        | 'ReadImageData' >> beam.Map(
+            lambda image_name: read_image(
+                image_file_name=image_name, path_to_dir=known_args.images_dir))
+        | 'AttachImageSizeToKey' >> beam.Map(attach_im_size_to_key)
+        | 'PreprocessImages' >> beam.MapTuple(
+            lambda file_name, data: (file_name, preprocess_image(data))))
+    predictions = (
+        filename_value_pair
+        | 'PyTorchRunInference' >> RunInference(engine_handler)

Review Comment:
   ```suggestion
           | 'TensorRTRunInference' >> RunInference(engine_handler)
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1189341878

   Oh, great to know! Thanks @pranavm-nvidia, I'll check that out


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929452217


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   This might mean considering moving some imports within functions, instead of having them at the top of the file.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929449989


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)

Review Comment:
   Got it. Understood re TensorRT logger.
   Regarding regular logger: I think we could instantiate it without overriding default logging settings (e.g. forcing logs to be Info), so that users can continue to customize desired default logging levels.

   Typically the pattern is to define the logger like so: https://github.com/apache/beam/blob/ac7bb2bb95a6a47cbcf0bbe30d04eb46c2e8b9a8/sdks/python/apache_beam/io/textio.py#L47

   Will that work?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r947359320


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   We will have an internal sync this week to try to answer as detailed as possible with regards to memory related questions. I think it is not scheduled yet, but should happen this week. @tvalentyn My apologies, I should've kept you updated


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946801641


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   I guess doing it at the end of every single prediction call is not a good idea?


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   @pranavm-nvidia I guess doing it at the end of every single prediction call is not a good idea?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929440958


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Is this implementation thread-safe?
   Beam SDKs can start multiple concurrent threads within sdk_worker process, which will be processing the examples. Are there any concerns with that from hardware or software standpoint?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929456909


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Maybe you can propose a solution that you would like to see. I'll verify it works on my end and we can commit it.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r949668553


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,295 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):

Review Comment:
   Addressed


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r954112607


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Not sure what kind of change is required considering the way it is built rn is that it will be one context. With regards to locking mechanism, that one is definitely not in place, I wonder if access restriction to other thread will happen automatically. @pranavm-nvidia any ideas about Valentin's request?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r954068946


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   @tvalentyn Do you think we can close it?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] AnandInguva commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
AnandInguva commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r965265213


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,258 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with
+TensorRT.
+"""
+
+import argparse
+import io
+import os
+from typing import Iterable
+from typing import Optional
+from typing import Tuple
+
+import numpy as np
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import KeyedModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.ml.inference.base import RunInference
+from apache_beam.ml.inference.tensorrt_inference import TensorRTEngineHandlerNumPy  # pylint: disable=line-too-long
+from apache_beam.options.pipeline_options import PipelineOptions
+from apache_beam.options.pipeline_options import SetupOptions
+from PIL import Image
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(
+    data: Tuple[str, Image.Image]) -> Tuple[Tuple[str, int, int], Image.Image]:
+  filename, image = data
+  width, height = image.size
+  return ((filename, width, height), image)
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(
+      ssd_mobilenet_v2_320x320_input_dims, resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  """Processes the PredictionResult that consists of
+  number of detections per image, box coordinates, scores and classes.
+
+  We loop over all detections to organize attributes on a per
+  detection basis. Box coordinates are normalized, hence we have to scale them
+  according to original image dimensions. Score is a floating point number
+  that provides probability percentage of a particular object. Class is
+  an integer that we can transform into actual string class using
+  COCO_OBJ_DET_CLASSES as reference.
+  """
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    num_detections = prediction_result.inference[0]
+    boxes = prediction_result.inference[1]
+    scores = prediction_result.inference[2]
+    classes = prediction_result.inference[3]
+    detections = []
+    for i in range(int(num_detections[0])):
+      detections.append({
+          'ymin': str(boxes[i][0] * im_height),
+          'xmin': str(boxes[i][1] * im_width),
+          'ymax': str(boxes[i][2] * im_height),
+          'xmax': str(boxes[i][3] * im_width),
+          'score': str(scores[i]),
+          'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+      })
+    yield filename + ',' + str(detections)
+
+
+def parse_known_args(argv):
+  """Parses args for the workflow."""
+  parser = argparse.ArgumentParser()
+  parser.add_argument(
+      '--input',
+      dest='input',
+      required=True,
+      help='Path to the text file containing image names.')
+  parser.add_argument(
+      '--output',
+      dest='output',
+      required=True,
+      help='Path where to save output predictions.'
+      ' text file.')
+  parser.add_argument(
+      '--engine_path',
+      dest='engine_path',
+      required=True,
+      help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+      'TensorRT engine.')
+  parser.add_argument(
+      '--images_dir',
+      default=None,
+      help='Path to the directory where images are stored.'
+      'Not required if image names in the input file have absolute path.')
+  return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+  """
+  Args:
+    argv: Command line arguments defined for this example.
+  """
+  known_args, pipeline_args = parse_known_args(argv)
+  pipeline_options = PipelineOptions(pipeline_args)
+  pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+  engine_handler = KeyedModelHandler(
+      TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path=known_args.engine_path))
+
+  with beam.Pipeline(options=pipeline_options) as p:
+    filename_value_pair = (
+        p
+        | 'ReadImageNames' >> beam.io.ReadFromText(
+            known_args.input, skip_header_lines=0)

Review Comment:
   ```suggestion
               known_args.input)
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937059085


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file

Review Comment:
   Sounds not related,  I'll start a discussion off this PR. Thanks


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917008927


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   @yeandy One sec, checking with legal.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930336009


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)

Review Comment:
   sure, I think `raise ValueError(f"Failed to load ONNX file: {onnx_path}")`  would work and already existing logs won't hurt.

   The reason is there may be additional logic for handling exceptions and communicating the exceptions between sdk and the runners, which would result in a more clear message such as:
   we tried to run this workitem 4 times and it failed with message X. versus, a container with an SDK  process keeps crashing and restarting, and a user would need to dig further to find logs preceding the restart.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] damccorm commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
damccorm commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1249502622

   Run Python PreCommit


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919443298


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   Thanks for looking into the various solutions.

   1. We can denote this subpar version as v1 if we can't find a better workaround. (See proposed solution below)
   2. It wouldn't be ideal to break the RunInference API. It would be confusing to users to have an API whose pattern is different than the other RunInference transforms.
   3.  This is a possibility as we iterate on RunInference with new features. Probably won't happen in the short term though as we'd have to revisit our designs.

   ___
   **Another option?**

   As you know, the `run_inference()` API requires there to be a `model` passed. (see [base.py](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/base.py#L94
   )). I think you're currently passing in `engine: trt.ICudaEngine` (which by the way would probably break our type checking? though I haven't looked into it in too much detail yet) as the "model".

   One thing we could do is instead of making the parameter `engine: trt.ICudaEngine`, we could define a custom "model" class that contains the necessary parameters. So instead of this
   ```
   def load_model(self) -> trt.ICudaEngine:
     """Loads and initializes a TensorRT engine for processing."""
     return _load_engine(self.engine_path)
   ```

   We could do
   ```
   class TensorRTModel:
     def __init__(self, engine, context, allocations):
        self.engine = engine
        self.context = context
        self.allocations = allocations
        ...

     # Feel free to rename this function
     def get_model_components():
       return self.engine, self.context, self.allocations, ..., ...

   def load_model(self) -> :
     """Loads and initializes a TensorRT engine for processing."""
     engine = _load_engine(self.engine_path)
     # more logic to get allocations, etc.
     return TensorRTModel(engine, engine.create_execution_context(), ...)

   def run_inference(
       self,
       batch: np.ndarray,
       model: TensorRTModel,
       inference_args: Optional[Dict[str, Any]] = None
   ) -> Iterable[PredictionResult]:
     _validate_inference_args(inference_args)
     engine, context, allocations, ..., ... = model.get_all_components()

   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917936505


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda

Review Comment:
   I think you'd also need `import pycuda.autoinit` here.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922254331


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)

Review Comment:
   @pranavm-nvidia are you talking about something like this before first cuda call:
   ```
   def ASSERT_DRV(err):
       if isinstance(err, cuda.CUresult):
           if err != cuda.CUresult.CUDA_SUCCESS:
               raise RuntimeError("Cuda Error: {}".format(err))
       else:
           raise RuntimeError("Unknown error type: {}".format(err))
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922182382


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -80,9 +79,70 @@ def _validate_inference_args(inference_args):
         'engines do not need extra arguments in their execute_v2() call.')


+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert batch_size > 0

Review Comment:
   Is `batch_size` used anywhere? I think it can be removed otherwise


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922382645


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference_test.py:
##########
@@ -0,0 +1,218 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pytest
+import unittest
+
+import apache_beam as beam
+from apache_beam.testing.test_pipeline import TestPipeline
+from apache_beam.testing.util import assert_that, equal_to
+
+# Protect against environments where TensorRT python library is not available.
+# pylint: disable=wrong-import-order, wrong-import-position, ungrouped-imports
+try:
+  import tensorrt as trt
+  from apache_beam.ml.inference.base import PredictionResult, RunInference
+  from apache_beam.ml.inference.tensorrt_inference import \
+      TensorRTEngineHandlerNumPy
+except ImportError:
+  raise unittest.SkipTest('TensorRT dependencies are not installed')
+
+try:
+  from apache_beam.io.gcp.gcsfilesystem import GCSFileSystem
+except ImportError:
+  GCSFileSystem = None  # type: ignore
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+SINGLE_FEATURE_EXAMPLES = np.array([[1], [5], [-3], [10.0]], dtype=np.float32)
+
+SINGLE_FEATURE_PREDICTIONS = [
+    PredictionResult(ex, pred) for ex,
+    pred in zip(
+        SINGLE_FEATURE_EXAMPLES,
+        [[np.array(example * 2.0 + 0.5, dtype=np.float32)] for example in SINGLE_FEATURE_EXAMPLES])
+]
+
+TWO_FEATURES_EXAMPLES = np.array([[1, 5],[3, 10],[-14, 0],[0.5, 0.5]], dtype=np.float32)

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r932280529


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Yes, it can be expensive, so it would make sense to reuse. How frequently do you expect new threads to be spawned?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r932767094


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   TLDR: we reuse threads, but there can be some churn.

   Here's the relevant code:
   https://github.com/apache/beam/blob/9154f8b3cf01fce067cea7ad7522e1db3154ff89/sdks/python/apache_beam/runners/worker/sdk_worker.py#L352-L361
   https://github.com/apache/beam/blob/48b534939468cc8e6dd403f11689a4433ca2e5a4/sdks/python/apache_beam/utils/thread_pool_executor.py#L82-L107

   The treads are managed by a ThreadPool, which is backed by a LIFO queue. Inactive threads can be removed from the queue if their number exceed a threshold.
   W.r.t. our usecase, we could potentially consider modifying the underlying collection to be a deque, so that inactive threads are removed from one end, and use LIFO so there is a higher chance of reusing the same threads.

   In case of Batch jobs, I think the thread queue is low, in case of streaming jobs, I am not sure, likely low after all threads have spawned unless there is some bursty behavior. I can ask around. Could you also elaborate a bit now on the costs for creating the context?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940675742


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   @yeandy TRT does not currently support multi-GPU so we don't need to worry about that. Meaning you cannot take one big model and split it across multiple GPUs (model parallelism).

   In terms of multi-GPU machine and selecting specific GPU, we can just use [env variable](https://stackoverflow.com/questions/39649102/how-do-i-select-which-gpu-to-run-a-job-on) or whatever the underlying mechanism that Beam has. I guess it's more of a question how is Beam architected with regards to this and if you see a solution and need our advice, please ask. Maybe if solution is not clear, you can outline the use case and how we should get to solution abstractly. After that we can do detailed back and forth on how we can do this.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940467262


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   @yeandy When you are talking about multi-GPU. What are you envisioning as a workflow? Do you want to split TRT model between multiple-GPUs? Or if it is a multi-GPU machine you want to selected a specific one and use it for inference?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940598096


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   I was originally thinking of the latter. But now that I think about it again, I'm not sure how much utility, if any, we'd get out of trying to work with multiple GPUs.. We're already using Beam's `Shared` class to share both context and the engine across threads. We'd want to first resolve the thread-safety concern with 1 GPU.

   For the former, I reckon that probably require a significant rewrite of the logic, right? It would definitely be out of scope of this PR.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937076383


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   Given that we use async, is this a blocking call?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917046405


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917937743


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()

Review Comment:
   ```suggestion
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917941464


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):
+      is_input = False
+      if engine.binding_is_input(i):
+        is_input = True
+      name = engine.get_binding_name(i)
+      dtype = engine.get_binding_dtype(i)
+      shape = engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      allocation = cuda.mem_alloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+      }
+      allocations.append(allocation)
+      if engine.binding_is_input(i):
+        inputs.append(binding)
+      else:
+        outputs.append(binding)
+
+    assert batch_size > 0
+    assert len(inputs) > 0
+    assert len(outputs) > 0
+    assert len(allocations) > 0
+    # Prepare the output data
+    predictions = []
+    for output in outputs:
+      predictions.append(np.zeros(output['shape'], output['dtype']))

Review Comment:
   Host memory allocation can also be moved out of `run_inference`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919206889


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920218780
##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+ RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+ TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+ 'person',
+ 'bicycle',
+ 'car',
+ 'motorcycle',
+ 'airplane',
+ 'bus',
+ 'train',
+ 'truck',
+ 'boat',
+ 'traffic light',
+ 'fire hydrant',
+ 'street sign',
+ 'stop sign',
+ 'parking meter',
+ 'bench',
+ 'bird',
+ 'cat',
+ 'dog',
+ 'horse',
+ 'sheep',
+ 'cow',
+ 'elephant',
+ 'bear',
+ 'zebra',
+ 'giraffe',
+ 'hat',
+ 'backpack',
+ 'umbrella',
+ 'shoe',
+ 'eye glasses',
+ 'handbag',
+ 'tie',
+ 'suitcase',
+ 'frisbee',
+ 'skis',
+ 'snowboard',
+ 'sports ball',
+ 'kite',
+ 'baseball bat',
+ 'baseball glove',
+ 'skateboard',
+ 'surfboard',
+ 'tennis racket',
+ 'bottle',
+ 'plate',
+ 'wine glass',
+ 'cup',
+ 'fork',
+ 'knife',
+ 'spoon',
+ 'bowl',
+ 'banana',
+ 'apple',
+ 'sandwich',
+ 'orange',
+ 'broccoli',
+ 'carrot',
+ 'hot dog',
+ 'pizza',
+ 'donut',
+ 'cake',
+ 'chair',
+ 'couch',
+ 'potted plant',
+ 'bed',
+ 'mirror',
+ 'dining table',
+ 'window',
+ 'desk',
+ 'toilet',
+ 'door',
+ 'tv',
+ 'laptop',
+ 'mouse',
+ 'remote',
+ 'keyboard',
+ 'cell phone',
+ 'microwave',
+ 'oven',
+ 'toaster',
+ 'sink',
+ 'refrigerator',
+ 'blender',
+ 'book',
+ 'clock',
+ 'vase',
+ 'scissors',
+ 'teddy bear',
+ 'hair drier',
+ 'toothbrush',
+ 'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+ width, height = x[1].size
+ return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+ path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+ if path_to_dir is not None:
+ image_file_name = os.path.join(path_to_dir, image_file_name)
+ with FileSystems().open(image_file_name, 'r') as file:
+ data = Image.open(io.BytesIO(file.read())).convert('RGB')
+ return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+ ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+ image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+ resample=Image.Resampling.BILINEAR)
+ image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+ return image
+
+
+class PostProcessor(beam.DoFn):
+ def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+ key, prediction_result = element
+ filename, im_width, im_height = key
+ nums = prediction_result.inference[0]
+ boxes = prediction_result.inference[1]
+ scores = prediction_result.inference[2]
+ classes = prediction_result.inference[3]
+ detections = []
+ for i in range(int(nums[0])):
+ detections.append({
+ 'ymin': str(boxes[i][0] * im_height),
+ 'xmin': str(boxes[i][1] * im_width),
+ 'ymax': str(boxes[i][2] * im_height),
+ 'xmax': str(boxes[i][3] * im_width),
+ 'score': str(scores[i]),
+ 'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+ })
+ yield filename + ',' + str(detections)
+
+def parse_known_args(argv):
+ """Parses args for the workflow."""
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ '--input',
+ dest='input',
+ required=True,
+ help='Path to the text file containing image names.')
+ parser.add_argument(
+ '--output',
+ dest='output',
+ required=True,
+ help='Path where to save output predictions.'
+ ' text file.')
+ parser.add_argument(
+ '--engine_path',
+ dest='engine_path',
+ required=True,
+ help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+ 'TensorRT engine.')
+ parser.add_argument(
+ '--images_dir',
+ default=None,
+ help='Path to the directory where images are stored.'
+ 'Not required if image names in the input file have absolute path.')
+ return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+ """
+ Args:
+ argv: Command line arguments defined for this example.
+ """
+ known_args, pipeline_args = parse_known_args(argv)
+ pipeline_options = PipelineOptions(pipeline_args)
+ pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+ engine_handler = KeyedModelHandler(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1, max_batch_size=1,
+ engine_path=known_args.engine_path))
+
+ with beam.Pipeline(options=pipeline_options) as p:
+ filename_value_pair = (
+ p
+ | 'ReadImageNames' >> beam.io.ReadFromText(
+ known_args.input, skip_header_lines=0)
+ | 'ReadImageData' >> beam.Map(
+ lambda image_name: read_image(
+ image_file_name=image_name, path_to_dir=known_args.images_dir))
+ | 'AttachImageSizeToKey' >> beam.Map(attach_im_size_to_key)
+ | 'PreprocessImages' >> beam.MapTuple(
+ lambda file_name, data: (file_name, preprocess_image(data))))
+ predictions = (
+ filename_value_pair
+ | 'PyTorchRunInference' >> RunInference(engine_handler)
+ | 'ProcessOutput' >> beam.ParDo(PostProcessor()))
+
+ if known_args.output:
+ predictions | "WriteOutputToGCS" >> beam.io.WriteToText(
+ known_args.output,
+ shard_name_template='',
+ append_trailing_newlines=True)
+
Review Comment:
@ryanthompson591 Great suggestion. However, I wanted to show you with example what will happen. In object detection you are predicting a bunch of things per detection: 4 box coordinates, score, class. Considering that there are 100 detections per image. For every image it will look like this:
Do you think it is ok to print this to user in case no output file was specified? Let me know if I should implement this else clause or take it out.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920223250


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:

Review Comment:
   My bad, was looking at [pytorch_image_classification.py](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/examples/inference/pytorch_image_classification.py) postprocecssor and didn't see any description, hence thought it is not necessary, but I can see it is present in other examples. I'll write one rn


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929447344


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Re#2:

   If at all possible we should import the libraries requiring GPUs only in the portion of the code that will be executed on the workers. It would be a much more convenient user experience if a user does not need GPUs to launch a pipeline that will spin up workers with GPUs in the cloud.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929450790


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine

Review Comment:
   You'll get a classic:
   ```
   [TRT] [E] 1: [checkMacros.cpp::catchCudaError::272] Error Code 1: Cuda Runtime (CUDA driver version is insufficient for CUDA runtime version)
   ```
   What do you think?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r950642867


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,

Review Comment:
   per feedback offline, let's add experimental annotation here and in the docstring. Examples: https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/sklearn_inference.py#L126


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946966938


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   Fixed. Thank you @pranavm-nvidia


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922245216


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]

Review Comment:
   Noted


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922299039


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922382220


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):
+      is_input = False
+      if engine.binding_is_input(i):
+        is_input = True
+      name = engine.get_binding_name(i)
+      dtype = engine.get_binding_dtype(i)
+      shape = engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      allocation = cuda.mem_alloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+      }
+      allocations.append(allocation)
+      if engine.binding_is_input(i):
+        inputs.append(binding)
+      else:
+        outputs.append(binding)
+
+    assert batch_size > 0
+    assert len(inputs) > 0
+    assert len(outputs) > 0
+    assert len(allocations) > 0
+    # Prepare the output data
+    predictions = []
+    for output in outputs:
+      predictions.append(np.zeros(output['shape'], output['dtype']))
+    # Process I/O and execute the network
+    cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))

Review Comment:
   I'll keep this in mind, will be added in future releases.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917002315


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   @azhurkevich Does `SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.` have to be on one line? I made some formatting fixes, and added `# pylint: disable=line-too-long` for now to keep it all on one line.

   But if it can be broken up into two lines, then it'll look better if we make that change.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940669021


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   I see. For my education, what mechanism ensures that the predictions are computed by the time the function call returns? Thanks.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922245574


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -80,9 +79,70 @@ def _validate_inference_args(inference_args):
         'engines do not need extra arguments in their execute_v2() call.')


+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert batch_size > 0

Review Comment:
   Dumb mistake, noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922193026


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference_test.py:
##########
@@ -0,0 +1,218 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pytest
+import unittest
+
+import apache_beam as beam
+from apache_beam.testing.test_pipeline import TestPipeline
+from apache_beam.testing.util import assert_that, equal_to
+
+# Protect against environments where TensorRT python library is not available.
+# pylint: disable=wrong-import-order, wrong-import-position, ungrouped-imports
+try:
+  import tensorrt as trt
+  from apache_beam.ml.inference.base import PredictionResult, RunInference
+  from apache_beam.ml.inference.tensorrt_inference import \
+      TensorRTEngineHandlerNumPy
+except ImportError:
+  raise unittest.SkipTest('TensorRT dependencies are not installed')
+
+try:
+  from apache_beam.io.gcp.gcsfilesystem import GCSFileSystem
+except ImportError:
+  GCSFileSystem = None  # type: ignore
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+SINGLE_FEATURE_EXAMPLES = np.array([[1], [5], [-3], [10.0]], dtype=np.float32)

Review Comment:
   ```suggestion
   SINGLE_FEATURE_EXAMPLES = [np.array(1, dtype=np.float32), np.array(5, dtype=np.float32), np.array(-3, dtype=np.float32), np.array(10.0, dtype=np.float32)]
   ```

   `sklearn_inference_test.py` defines test inputs like [this](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/sklearn_inference_test.py#L135).


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert batch_size > 0
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return self.engine, self.context, self.inputs, self.outputs, self.gpu_allocations, self.cpu_allocations
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+    pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(self, network: trt.INetworkDefinition, builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:

Review Comment:
   I'm seeing this lint error:
   ```
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: error: Argument 1 of "run_inference" is incompatible with supertype "ModelHandler"; supertype defines the argument type as "Sequence[ndarray[Any, Any]]"  [override]
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: note: This violates the Liskov substitution principle
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: note: See https://mypy.readthedocs.io/en/stable/common_issues.html#incompatible-overrides
   ```
   I think we need to adhere to the [interface](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/base.py#L91) for `run_inference` as found in `base.py`. Could we make it `Sequence[np.ndarray]` like it's done in [sklearn_inference.py](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/sklearn_inference.py#L105)?

   This may require some refactor some of the tests. I think particularly how the input examples are defined


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference_test.py:
##########
@@ -0,0 +1,218 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pytest
+import unittest
+
+import apache_beam as beam
+from apache_beam.testing.test_pipeline import TestPipeline
+from apache_beam.testing.util import assert_that, equal_to
+
+# Protect against environments where TensorRT python library is not available.
+# pylint: disable=wrong-import-order, wrong-import-position, ungrouped-imports
+try:
+  import tensorrt as trt
+  from apache_beam.ml.inference.base import PredictionResult, RunInference
+  from apache_beam.ml.inference.tensorrt_inference import \
+      TensorRTEngineHandlerNumPy
+except ImportError:
+  raise unittest.SkipTest('TensorRT dependencies are not installed')
+
+try:
+  from apache_beam.io.gcp.gcsfilesystem import GCSFileSystem
+except ImportError:
+  GCSFileSystem = None  # type: ignore
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+SINGLE_FEATURE_EXAMPLES = np.array([[1], [5], [-3], [10.0]], dtype=np.float32)
+
+SINGLE_FEATURE_PREDICTIONS = [
+    PredictionResult(ex, pred) for ex,
+    pred in zip(
+        SINGLE_FEATURE_EXAMPLES,
+        [[np.array(example * 2.0 + 0.5, dtype=np.float32)] for example in SINGLE_FEATURE_EXAMPLES])
+]
+
+TWO_FEATURES_EXAMPLES = np.array([[1, 5],[3, 10],[-14, 0],[0.5, 0.5]], dtype=np.float32)

Review Comment:
   Same as above


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922190233


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert batch_size > 0
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return self.engine, self.context, self.inputs, self.outputs, self.gpu_allocations, self.cpu_allocations
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+    pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(self, network: trt.INetworkDefinition, builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:

Review Comment:
   I'm seeing this lint [error](https://ci-beam.apache.org/job/beam_PreCommit_PythonLint_Commit/14847/console):
   ```
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: error: Argument 1 of "run_inference" is incompatible with supertype "ModelHandler"; supertype defines the argument type as "Sequence[ndarray[Any, Any]]"  [override]
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: note: This violates the Liskov substitution principle
   19:21:43 apache_beam/ml/inference/tensorrt_inference.py:196: note: See https://mypy.readthedocs.io/en/stable/common_issues.html#incompatible-overrides
   ```
   I think we need to adhere to the [interface](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/base.py#L91) for `run_inference` as found in `base.py`. Could we make it `Sequence[np.ndarray]` like it's done in [sklearn_inference.py](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/ml/inference/sklearn_inference.py#L105)?

   This may require some refactor some of the tests. I think particularly how the input examples are defined


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] kennknowles commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
kennknowles commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922694908


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   The simplest thing is to use the header and nothing else.

   The Google CCLA (Corporate Contributor License Agreement) is an agreement between Google and the Apache Software Foundation.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r924614352


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda

Review Comment:
   Ack. Thanks for testing!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929456481


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Roughly speaking, at submission we create a DAG of the pipeline. The transforms and pipeline user code is represented in serialized form.
   On the runner the code will be deserialized and actually executed run.

   To test out the UX, one should try to run the example on Dataflow runner. First, launching from a machine with GPUs, then launch from a machine without GPUs. I assume we have already ran with the Direct  runner (all processing done on the same machine), if not do that first.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] kennknowles commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
kennknowles commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930203162


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference_test.py:
##########
@@ -0,0 +1,292 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file

Review Comment:
   ditto

   (or does pytype struggle with unit test files?)


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file

Review Comment:
   Just noticing this - why? I think any suppressions should be localized


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929444892


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   @pranavm-nvidia any comments?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929469848


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)

Review Comment:
   Can you give a bit more detailed example how you would like it to be structured?
   Do you want to replace `sys.exit(1)` with `raise ValueError("Something something")`
   Something like this? What do you want to see as text, we already logged failure to load ONNX.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1188256204

   Sounds good, thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930364058


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)

Review Comment:
   Sure. I'll add `raise ValueError(f"Failed to load ONNX file: {onnx_path}")` instead of `sys.exit(1)`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929432277


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)

Review Comment:
   We should raise a ValueError instead of exiting the process.


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine

Review Comment:
   We should check how does this fail when GPUs are not provided (as in: is there a clear / actionable error).


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   1. I assume one will need a NVIDIA GPU to successfully run this example.  I think we should mention it? Or without GPUs one can still run the example, but with a degraded performance?

   2. Related to 1: if we want to run the pipeline on the dataflow runner: will users still need a machine with GPU at _job submission time_? For example, to be able to install all the tensorrt dependencies and submit the pipeline for execution on Dataflow?


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)

Review Comment:
   Are these logging changes here just for debugging purposes while we are iterating on the PR?

   See related:

   https://github.com/apache/beam/blob/01fa485b31bbaf649873eb27623539e2e2b27cf2/sdks/python/apache_beam/pipeline.py#L160
   https://github.com/apache/beam/blob/01fa485b31bbaf649873eb27623539e2e2b27cf2/sdks/python/apache_beam/runners/worker/sdk_worker_main.py#L95


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r950643440


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations

Review Comment:
   Tbh, not sure why it has to be there. I think it was either added for some internal beam purposes or maybe I just left it there from pytorch implementation. Thanks for looking into it @tvalentyn


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946901633


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   Added [stream sync](https://github.com/apache/beam/pull/22131/commits/5d52984f5db83edce7a8e1cc54fe65ee019f3e03#diff-145530e8e39084aed7792a4d3b8104258ea1635db466ab48a58f168bce10dde3R269) before copying data to host.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] AnandInguva commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
AnandInguva commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1239963959

   Run Python 3.8 PostCommit


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917043653


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   @yeandy We can do this:
   ```
   SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
   Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
   ```
   Or we can do this:
   ```
   SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES.
   All rights reserved.
   ```
   Whatever you like more.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1222501179

   Run PythonLint PreCommit


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r948239867


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Great, thank you for helping to investigate this!

   > If you plan to use all N concurrently, then I'd just let TensorRT manage the per-context memory

   The assumption is that contexts will be used concurrently. Is the per-context memory allocation static? I think we will have to choose between:
   - creating contexts on demand as new threads spun up, possibly with a maximum limit for total # of contexts
   - pre-creating a limited number of contexts and block threads until shared contexts become available, or just limit thread parallelism to the number of context that we can afford for a particular engine.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r932595103


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Re summit, thanks @azhurkevich!

   ---

   Per my GCP testing, nothing to call out. Though I've only had a chance to run the unit tests, which didn't require Dataflow. FYI, this is what I did to run the unit tests:
   - Create GCE VM: Choose 2 `NVIDIA Tesla T4` GPUs and also `n1-standard-2` (2 vCPU, 7.5 GB memory) for machine type. Choose “Debian 10 based Deep Learning VM with CUDA 11.3 M94” for Boot Disk.
   - Build docker inside VM: `docker build -f Dev_Beam.dockerfile -t dev_beam .`
   - Clone Alexander's apache_beam fork and checkout to the `tensorrt_runinference` branch.
   - Build tensorrt engine and upload those files (and onnx files) to the `apache-beam-ml` GCS bucket.
   - Run tests: `docker run --rm -it --gpus all -v /home/yeandy/:/mnt -w /mnt/beam/sdks/python dev_beam python setup.py test -s apache_beam.ml.inference.tensorrt_inference_test`

   I'm catching up with @AnandInguva tomorrow to clarify our infra setup for these tests.

   ---

   Also caught up with @tvalentyn. I'm going to work on running the `tensorrt_object_detection` example on Dataflow by launching from both a machine with GPUs and a machine without GPUs, and see what code refactoring is necessary. This will require a bit of tinkering, which may take a few days. I will give an update as soon as I can.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r921646835


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   Resolved


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920251928


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):

Review Comment:
   Good point. X is essentially a tuple consisting on a filename and image object: `('/mnt/val2017/000000000139.jpg', <PIL.Image.Image image mode=RGB size=640x426 at 0x7F19C054E040>)`

   I'll remake it into:
   ```
   def attach_im_size_to_key(data):
       filename, image = data
       width, height = image.size
       return ((filename, width, height), image)
   ```
   for clarity


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919240158


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   So yeah. @pranavm-nvidia made a lot of recommendations about allocating memory on both host and device before run_inference(), which is obviously correct design. We should not do memory allocation every time we want to make inference call. However, again, the reason I did it this way is because it was compliant with RunInference() transform. To make everything properly, run_inference() will only have:
   ```
   cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))
   context.execute_v2(allocations)
   for output in range(len(predictions)):
       cuda.memcpy_dtoh(predictions[output], outputs[output]['allocation'])
   return [
       PredictionResult(x, [prediction[idx] for prediction in predictions])
       for idx,
       x in enumerate(batch)
   ]
   ```
   Rest of the current code in run_inference() will be handled in a separate function that will be called from load_model() (if you have prebuilt TRT engine) and build_engine() (if you have to build engine from ONNX).

   In summary, we need to pass `inputs`, `allocations` (GPU allocation), `outputs`, `context`, `batch`, `predictions` (CPU allocation) to run_inference. This is not compatible with RunInference() transform, but is the right way to do things with TRT.

   Choices:
   1. We either keep TRT's run_inference() in this subpar state but it is compatible with current RunInference().
   2. We create a new transform which is a copy of RunInference() but takes more arguments for run_inference() function.
   3. Or we somehow modify existing RunInference() to accommodate for additional TRT run_inference() arguments.

   Eager to hear what you guys think @ryanthompson591 @yeandy .


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920232336
##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+ RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+ TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+ 'person',
+ 'bicycle',
+ 'car',
+ 'motorcycle',
+ 'airplane',
+ 'bus',
+ 'train',
+ 'truck',
+ 'boat',
+ 'traffic light',
+ 'fire hydrant',
+ 'street sign',
+ 'stop sign',
+ 'parking meter',
+ 'bench',
+ 'bird',
+ 'cat',
+ 'dog',
+ 'horse',
+ 'sheep',
+ 'cow',
+ 'elephant',
+ 'bear',
+ 'zebra',
+ 'giraffe',
+ 'hat',
+ 'backpack',
+ 'umbrella',
+ 'shoe',
+ 'eye glasses',
+ 'handbag',
+ 'tie',
+ 'suitcase',
+ 'frisbee',
+ 'skis',
+ 'snowboard',
+ 'sports ball',
+ 'kite',
+ 'baseball bat',
+ 'baseball glove',
+ 'skateboard',
+ 'surfboard',
+ 'tennis racket',
+ 'bottle',
+ 'plate',
+ 'wine glass',
+ 'cup',
+ 'fork',
+ 'knife',
+ 'spoon',
+ 'bowl',
+ 'banana',
+ 'apple',
+ 'sandwich',
+ 'orange',
+ 'broccoli',
+ 'carrot',
+ 'hot dog',
+ 'pizza',
+ 'donut',
+ 'cake',
+ 'chair',
+ 'couch',
+ 'potted plant',
+ 'bed',
+ 'mirror',
+ 'dining table',
+ 'window',
+ 'desk',
+ 'toilet',
+ 'door',
+ 'tv',
+ 'laptop',
+ 'mouse',
+ 'remote',
+ 'keyboard',
+ 'cell phone',
+ 'microwave',
+ 'oven',
+ 'toaster',
+ 'sink',
+ 'refrigerator',
+ 'blender',
+ 'book',
+ 'clock',
+ 'vase',
+ 'scissors',
+ 'teddy bear',
+ 'hair drier',
+ 'toothbrush',
+ 'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+ width, height = x[1].size
+ return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+ path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+ if path_to_dir is not None:
+ image_file_name = os.path.join(path_to_dir, image_file_name)
+ with FileSystems().open(image_file_name, 'r') as file:
+ data = Image.open(io.BytesIO(file.read())).convert('RGB')
+ return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+ ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+ image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+ resample=Image.Resampling.BILINEAR)
+ image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+ return image
+
+
+class PostProcessor(beam.DoFn):
+ def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+ key, prediction_result = element
+ filename, im_width, im_height = key
+ nums = prediction_result.inference[0]
Review Comment:
It is number of detections per image. You can think of it as number of object detection boxes per image. For example:
. I'll rename it to num_detections, if it's ok
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919422907


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):
+      is_input = False
+      if engine.binding_is_input(i):
+        is_input = True
+      name = engine.get_binding_name(i)
+      dtype = engine.get_binding_dtype(i)
+      shape = engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      allocation = cuda.mem_alloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+      }
+      allocations.append(allocation)
+      if engine.binding_is_input(i):
+        inputs.append(binding)
+      else:
+        outputs.append(binding)
+
+    assert batch_size > 0
+    assert len(inputs) > 0
+    assert len(outputs) > 0
+    assert len(allocations) > 0
+    # Prepare the output data
+    predictions = []
+    for output in outputs:
+      predictions.append(np.zeros(output['shape'], output['dtype']))
+    # Process I/O and execute the network
+    cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))

Review Comment:
   It would be pretty much the same way you handle the outputs. Instead of passing in a single input, you could take a `feed_dict` argument (e.g. a `Dict[str, np.ndarray]`). Then when you memcpy, you would have something like:
   ```py
   for name, buffer in feed_dict.items():
       input_buffer = ... # Figure out which input buffer to copy to using, e.g. `get_binding_name()`
       cuda.memcpy_htod(input_buffer, np.ascontiguousarray(buffer))
   ```

   You can also refer to [how Polygraphy does it](https://github.com/NVIDIA/TensorRT/blob/main/tools/Polygraphy/polygraphy/backend/trt/runner.py#L221) for a more comprehensive example.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r921128666


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   Great to hear, thanks! And agreed; give it a go, but multiple inputs can come later :)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919462377


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   @yeandy was also thinking about it couple hours ago. Seems like a good idea. Let me think of how to implement it in practice. How much time do we have to make changes? July 19th? Or you want everything finalized for version 1 before that?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1188265962

   Actually, I have been experimenting around with the docs stuff in your branch. I can do a quick fix right now.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1189323009

   The Sphinx docs generation requires module imports `import tensorrt as trt` and `from cuda import cuda`. I think our script just needs to detect that those modules exist in `tensorrt_inference.py` via the import statements. @azhurkevich Want to confirm before I pursue a different route: To your knowledge, is there a way to install these two packages without having GPUs, drivers, toolkit, etc. set up? (I was trying pip installation [method](https://docs.nvidia.com/deeplearning/tensorrt/quick-start-guide/index.html#installing-pip) locally, but ran into issues)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r948263727


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   For models with static shapes, yes, the memory allocation would be static. When dynamic shapes are involved, there may be reallocations when the input shapes change.

   This:
   > just limit thread parallelism to the number of contexts that we can afford for a particular engine

   is required for both options.
   So then it's just a question of whether to create contexts up front or on-demand. I think the answer to that depends on what the typical usage scenario is.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r951346017


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations

Review Comment:
   I added this when I [refactored](https://github.com/apache/beam/pull/22131/commits/a79e91ffec286881a5e64b272496b1ad8350b746) the `cuda` and `tensorrt` imports inside the functions. Yeah, it looks to be the `3.6` version that doesn't support `__future__`. `3.7` should work. (It was also misleading when trying to debug because in `tox.ini`, our mypy test is called `py37-mypy`, which initially made me think we already have `3.7`)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r954088468


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,

Review Comment:
   @tvalentyn Just made a commit, please let me know if it has what you expected. Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r971328945


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   @AnandInguva @yeandy can we add the Dockerfile for this image somewhere?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958922077


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -160,6 +175,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.

Review Comment:
   Looks good to me, appreciate your input @yeandy! Thank you


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958938153


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.utils.annotations import experimental
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      raise ValueError(f"Failed to load ONNX file: {onnx_path}")
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+@experimental(extra_message="No backwards-compatibility guarantees.")
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    **NOTE:** This API and its implementation are under development and
+    do not provide backward compatibility guarantees.
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network

Review Comment:
   ```
   with context_lock:
      <move the code that is using shared context and needs to be guarded by a lock here.>
      # Process I/O and execute the network


   return [
      # PredictionResults
   ]
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958846472


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   @tvalentyn Do we have this mechanism that you are mentioning in PyTorch example? It would be easier for me to understand what you would like to see if there is a reference.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940720337


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   > We'd want to first resolve the thread-safety concern with 1 GPU.

   We need to address the thread safety concern per feedback in this thread. At minimum, let's add a lock and avoid sharing the context between the threads.

   I  discussed this a bit with lcwik. In short term, we should implement a shared object cache for managing shared execution contexts. We should avoid the affinity between thread IDs and contexts, and instead make it possible to transfer shared contexts between threads.

   We should be able to rely on `start_bundle` and `finish_bundle` to claim and release the contexts from the shared pool.

   Open question is GPU memory management:
   - How many contexts do we create and how much GPU memory should we allocate per each context. Can we know at runtime what's the max # of context we can create for a particular engine? What are the tradeoffs between creating more contexts with less memory per contexts vs less contexts? Will pipeline degrade gracefully when more memory is needed or something will crash? If we solve memory management, adding the shared pool should not be too complex. We can refer to `UnboundedThreadPoolExecutor` implementation for inspiration.

   - In the future, we can consider sharing the object cache w/ contexts between multiple SDK processes (not just between threads) via `multiprocessing`. This may be worthwhile with A100 accelerators that have more GPU memory that can be shared across multiple processes, and this could allow users benefiting from MPS.  We'd have to share contexts between processes - are these objects large in size? If it is just metadata, the overhead may not be significant.  This is something we should also consider for Tensorflow runinference, since Tensorflow does not work well when using the same GPU from multiple processes and manual GPU memory management is needed, so Beam RunInference could help make it easier.  In the medium term, we may need to recommend limiting pipelines to use 1 process only.

   Summary of questions asked above:
   - How many contexts can we create and how do you recommend to manage memory b/w them?
   - Are context objects small?
   - Does TensorRT support concurrent execution on multiple processes on the same GPU? I believe, I asked this and answer was `yes`, just, double checking...  If yes, how GPU memory management is solved?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940427887


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   @pranavm-nvidia Maybe you know better how to answer this.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940428328


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   I don't think it is a blocking call since it is on a separate stream


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] github-actions[bot] commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
github-actions[bot] commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1179204501

   Stopping reviewer notifications for this pull request: review requested by someone other than the bot, ceding control


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917010740
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -19,7 +19,6 @@
import numpy as np
import os
-import pycuda.autoinit
Review Comment:
@yeandy I would advise against deleting this line. [Autoinit](https://documen.tician.de/pycuda/util.html) automatically performs all the steps necessary to get CUDA ready to execute compute kernels. You would get this if you take it out:
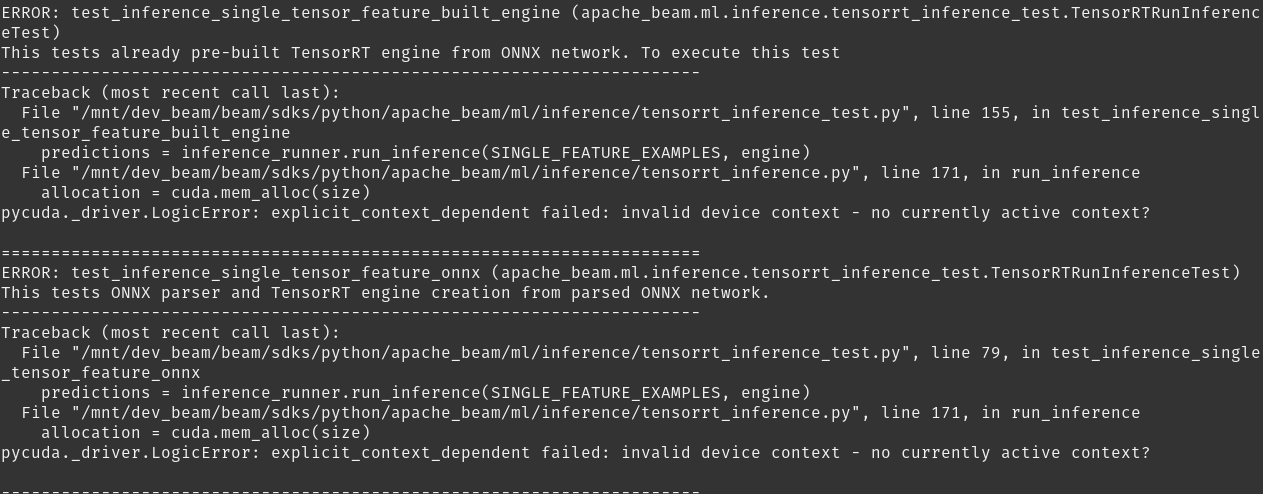
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] damccorm merged pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
damccorm merged PR #22131:
URL: https://github.com/apache/beam/pull/22131


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] damccorm commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
damccorm commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972993684


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   I added them, I'll merge once checks pass


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930152981


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Makes sense. Thank you @pranavm-nvidia!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r934942380


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Update:

   I'm able to kick off a DataFlow job for the `tensorrt_object_detection` pipeline from my local machine. It runs successfully, reading an input txt file and trt engine file from GCS, as well as writing predictions to GCS, with no issue.

   There may be cleaner ways to do this, so please let me know if you have any ideas. Here are the changes.

   1. Move any `tensorrt` or `cuda` imports inside helper functions
   2. Wrap `TRT_LOGGER = trt.Logger(trt.Logger.INFO)` inside a try/catch block so that I could get the job submission to work.
   3. Move `trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")` from the `__init__` function of `TensorRTEngineHandlerNumPy` to the `load_model` part. `trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")` needs to be called once, but we can't leave it in `__init__` because logic in here will be called at job submission time, which won't guarantee to have `tensorrt` installed locally.
   4. Add `from __future__ import annotations` to allow type-checking to pass. Otherwise, we will see `NameError: name 'trt' is not defined` in this line: `def __init__(self, engine: trt.ICudaEngine):`
   5. Slightly modified the Dockerfile to reintroduce `ENTRYPOINT [ "/opt/apache/beam/boot" ]` so that the pipeline could start.

   In addition. One thing we need to do is to be able to rebuild the TRT engine from the onnx file (already in GCS) every time. For this job, I did the engine building in a separate VM. The next thing to do is to create a job -- probably a Dataflow one -- to build the engine before running the actual test.

   Please see this [PR](https://github.com/azhurkevich/beam/pull/1) with my changes, and let me know what you think.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r935062001


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
    @yeandy Thanks for this crystal clear explanation! In the end, I just want to make sure that whatever I do is compliant with your vision. From the high level looks good to me, [I added a small suggestion](https://github.com/azhurkevich/beam/pull/1#issuecomment-1201944306). We can merge after it is addressed.
   I have diving deeper and figuring out GCP planned for this week. I am complete rookie so if you make any Dataflow suggestions, please be specific so that I can understand.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919212354


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   @pranavm-nvidia pointed out a great point. My original design was context creation in load_engine(), the way it should be done. However, this will be one more additional argument I will have to pass to run_inference(), hence it will break compatibility with RunInference() transform located in base.py. As a result pipeline tests will not work. Passing context as inference_args is not a good option because it goes contrary to the idea of inference_args (additional optional argument for inference call in pytorch). @ryanthompson591 @yeandy please propose your solution how to resolve this.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919214096


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   @ryanthompson591 @yeandy Give me couple hours, I think if I take out memory allocation out of run_inference(), I can pass context instead of engine and we won't have to change anything in RunInference() transform.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946768311


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   Ah good point. @azhurkevich you'd need to synchronize the CUDA stream at some point before using the predictions to ensure that all operations enqueued on the stream are completed


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r973053173


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972437142


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   actually, they could also be used for other runners, so could be a little up the tree, such as test-suites/containers/tensortt_runinference


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r954112607


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Not sure what kind of change is required considering the way it is built rn is that it will be one context. With regards to locking mechanism, that one is definitely not in place, I wonder if it'll happen automatically. @pranavm-nvidia any ideas about Valentin's request?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1247301691

   > I took a closer look, see suggestions. I haven't tested it.

   Pushed the suggestions, let's see if the tests pass.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r971341653


##########
build.gradle.kts:
##########
@@ -325,6 +325,8 @@ tasks.register("python38PostCommit") {
   dependsOn(":sdks:python:test-suites:direct:py38:postCommitIT")
   dependsOn(":sdks:python:test-suites:direct:py38:hdfsIntegrationTest")
   dependsOn(":sdks:python:test-suites:portable:py38:postCommitPy38")
+  // TODO: https://github.com/apache/beam/issues/22651

Review Comment:
   nit: @AnandInguva  in Beam we typically mention a TODO, and then add a short description that follows the TODO. Full description can be in the TODO itself.

   For example:

   // TODO(https://github.com/apache/beam/issues/22651): Build docker image for tensor RT at runtime.

   Also this todo seems a bit out of place here.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] ryanthompson591 commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
ryanthompson591 commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r918961572


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:

Review Comment:
   since this is sample code it would be nice to have a short description of what post processing is done and why.

   Something like:

   Converts a list of prediction results into a human readable string with the filename, prediction box location, score of the predicted objects, and the name of the predicted object.


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:

Review Comment:
   I'm not really familiar with what an onnx model is. Is this only used for tests?


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   @kennknowles Nvidia wants to add a copyright here. Personally I think it's fine, but just wanted to double check that Apache is fine.


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))

Review Comment:
   Is it possible to log instead of print errors?  I'm just thinking that if this is done on workers users might not see printed messages.


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:

Review Comment:
   I find the documentation generates better if you do this:

   ```
   Example Usage::

   pcoll | RunInference(
           TensorRTEngineHandlerNumPy(
             min_batch_size=1,
             max_batch_size=1,
             engine_path="my_uri"))
   ```

   Like how it's done in sklearn_inference.


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   yes, just for some context, anything that should only be done once per thread should be done in load_model if possible.


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    nums = prediction_result.inference[0]
+    boxes = prediction_result.inference[1]
+    scores = prediction_result.inference[2]
+    classes = prediction_result.inference[3]
+    detections = []
+    for i in range(int(nums[0])):
+        detections.append({
+                'ymin': str(boxes[i][0] * im_height),
+                'xmin': str(boxes[i][1] * im_width),
+                'ymax': str(boxes[i][2] * im_height),
+                'xmax': str(boxes[i][3] * im_width),
+                'score': str(scores[i]),
+                'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+            })
+    yield filename + ',' + str(detections)
+
+def parse_known_args(argv):
+  """Parses args for the workflow."""
+  parser = argparse.ArgumentParser()
+  parser.add_argument(
+      '--input',
+      dest='input',
+      required=True,
+      help='Path to the text file containing image names.')
+  parser.add_argument(
+      '--output',
+      dest='output',
+      required=True,
+      help='Path where to save output predictions.'
+      ' text file.')
+  parser.add_argument(
+      '--engine_path',
+      dest='engine_path',
+      required=True,
+      help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+      'TensorRT engine.')
+  parser.add_argument(
+      '--images_dir',
+      default=None,
+      help='Path to the directory where images are stored.'
+      'Not required if image names in the input file have absolute path.')
+  return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+  """
+  Args:
+    argv: Command line arguments defined for this example.
+  """
+  known_args, pipeline_args = parse_known_args(argv)
+  pipeline_options = PipelineOptions(pipeline_args)
+  pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+  engine_handler = KeyedModelHandler(
+      TensorRTEngineHandlerNumPy(
+          min_batch_size=1, max_batch_size=1,
+        engine_path=known_args.engine_path))
+
+  with beam.Pipeline(options=pipeline_options) as p:
+    filename_value_pair = (
+        p
+        | 'ReadImageNames' >> beam.io.ReadFromText(
+            known_args.input, skip_header_lines=0)
+        | 'ReadImageData' >> beam.Map(
+            lambda image_name: read_image(
+                image_file_name=image_name, path_to_dir=known_args.images_dir))
+        | 'AttachImageSizeToKey' >> beam.Map(attach_im_size_to_key)
+        | 'PreprocessImages' >> beam.MapTuple(
+            lambda file_name, data: (file_name, preprocess_image(data))))
+    predictions = (
+        filename_value_pair
+        | 'PyTorchRunInference' >> RunInference(engine_handler)
+        | 'ProcessOutput' >> beam.ParDo(PostProcessor()))
+
+    if known_args.output:
+      predictions | "WriteOutputToGCS" >> beam.io.WriteToText(
+        known_args.output,
+        shard_name_template='',
+        append_trailing_newlines=True)
+

Review Comment:
   you don't have to take this suggestion, but one thing you could do if there is no output directory is just print the results.
   ```
   if known_args.output:
         predictions | "WriteOutputToGCS" >> beam.io.WriteToText(
           known_args.output,
           shard_name_template='',
           append_trailing_newlines=True)
   else:
     predictions | "PrintPredictions" >> beam.Map(print)
   ```


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))

Review Comment:
   same here: maybe log instead of print (if possible).


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):

Review Comment:
   what is x here, can you add a more descriptive variable name?


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    nums = prediction_result.inference[0]

Review Comment:
   can this variable be more descriptive.  Is nums the number of inferences?

   maybe:
   num_inferences = prediction_result.inference[0][0]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919432190


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):
+      is_input = False
+      if engine.binding_is_input(i):
+        is_input = True
+      name = engine.get_binding_name(i)
+      dtype = engine.get_binding_dtype(i)
+      shape = engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      allocation = cuda.mem_alloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+      }
+      allocations.append(allocation)
+      if engine.binding_is_input(i):
+        inputs.append(binding)
+      else:
+        outputs.append(binding)
+
+    assert batch_size > 0
+    assert len(inputs) > 0
+    assert len(outputs) > 0
+    assert len(allocations) > 0
+    # Prepare the output data
+    predictions = []
+    for output in outputs:
+      predictions.append(np.zeros(output['shape'], output['dtype']))
+    # Process I/O and execute the network
+    cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))

Review Comment:
   @pranavm-nvidia ok, definitely need to come up with a use case to test it out. Thank you!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919201557


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))

Review Comment:
   Noted


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919192843


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)

Review Comment:
   Noted


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda

Review Comment:
   Noted, mentioned above


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920184539


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   @ryanthompson591 We first instantiate TensorRTEngineHandlerNumPy(), then we do load_model(). So instantiating TensorRTEngineHandlerNumPy() is always the first step no matter what. It follows PyTorch structure, you can think of it as PytorchModelHandlerTensor().


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920467817


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    nums = prediction_result.inference[0]
+    boxes = prediction_result.inference[1]
+    scores = prediction_result.inference[2]
+    classes = prediction_result.inference[3]
+    detections = []
+    for i in range(int(nums[0])):
+        detections.append({
+                'ymin': str(boxes[i][0] * im_height),
+                'xmin': str(boxes[i][1] * im_width),
+                'ymax': str(boxes[i][2] * im_height),
+                'xmax': str(boxes[i][3] * im_width),
+                'score': str(scores[i]),
+                'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+            })
+    yield filename + ',' + str(detections)
+
+def parse_known_args(argv):
+  """Parses args for the workflow."""
+  parser = argparse.ArgumentParser()
+  parser.add_argument(
+      '--input',
+      dest='input',
+      required=True,
+      help='Path to the text file containing image names.')
+  parser.add_argument(
+      '--output',
+      dest='output',
+      required=True,
+      help='Path where to save output predictions.'
+      ' text file.')
+  parser.add_argument(
+      '--engine_path',
+      dest='engine_path',
+      required=True,
+      help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+      'TensorRT engine.')
+  parser.add_argument(
+      '--images_dir',
+      default=None,
+      help='Path to the directory where images are stored.'
+      'Not required if image names in the input file have absolute path.')
+  return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+  """
+  Args:
+    argv: Command line arguments defined for this example.
+  """
+  known_args, pipeline_args = parse_known_args(argv)
+  pipeline_options = PipelineOptions(pipeline_args)
+  pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+  engine_handler = KeyedModelHandler(
+      TensorRTEngineHandlerNumPy(
+          min_batch_size=1, max_batch_size=1,
+        engine_path=known_args.engine_path))
+
+  with beam.Pipeline(options=pipeline_options) as p:
+    filename_value_pair = (
+        p
+        | 'ReadImageNames' >> beam.io.ReadFromText(
+            known_args.input, skip_header_lines=0)
+        | 'ReadImageData' >> beam.Map(
+            lambda image_name: read_image(
+                image_file_name=image_name, path_to_dir=known_args.images_dir))
+        | 'AttachImageSizeToKey' >> beam.Map(attach_im_size_to_key)
+        | 'PreprocessImages' >> beam.MapTuple(
+            lambda file_name, data: (file_name, preprocess_image(data))))
+    predictions = (
+        filename_value_pair
+        | 'PyTorchRunInference' >> RunInference(engine_handler)
+        | 'ProcessOutput' >> beam.ParDo(PostProcessor()))
+
+    if known_args.output:
+      predictions | "WriteOutputToGCS" >> beam.io.WriteToText(
+        known_args.output,
+        shard_name_template='',
+        append_trailing_newlines=True)
+

Review Comment:
   I'll just keep it required. I was looking at [pytorch_image_classification.py ](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/examples/inference/pytorch_image_classification.py) when designing it. For some reason output is actually [required](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/examples/inference/pytorch_image_classification.py#L82), hence no idea why even make an [if statement](https://github.com/apache/beam/blob/master/sdks/python/apache_beam/examples/inference/pytorch_image_classification.py#L138).  I just took it for granted and missed this small logic mistake. I'll just take out if statement considering rest of the code and documentation requires presence of an output.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922382389


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert batch_size > 0
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return self.engine, self.context, self.inputs, self.outputs, self.gpu_allocations, self.cpu_allocations
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+    pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(self, network: trt.INetworkDefinition, builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:

Review Comment:
   Noted


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference_test.py:
##########
@@ -0,0 +1,218 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pytest
+import unittest
+
+import apache_beam as beam
+from apache_beam.testing.test_pipeline import TestPipeline
+from apache_beam.testing.util import assert_that, equal_to
+
+# Protect against environments where TensorRT python library is not available.
+# pylint: disable=wrong-import-order, wrong-import-position, ungrouped-imports
+try:
+  import tensorrt as trt
+  from apache_beam.ml.inference.base import PredictionResult, RunInference
+  from apache_beam.ml.inference.tensorrt_inference import \
+      TensorRTEngineHandlerNumPy
+except ImportError:
+  raise unittest.SkipTest('TensorRT dependencies are not installed')
+
+try:
+  from apache_beam.io.gcp.gcsfilesystem import GCSFileSystem
+except ImportError:
+  GCSFileSystem = None  # type: ignore
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+SINGLE_FEATURE_EXAMPLES = np.array([[1], [5], [-3], [10.0]], dtype=np.float32)

Review Comment:
   Noted


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920470464


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    nums = prediction_result.inference[0]
+    boxes = prediction_result.inference[1]
+    scores = prediction_result.inference[2]
+    classes = prediction_result.inference[3]
+    detections = []
+    for i in range(int(nums[0])):
+        detections.append({
+                'ymin': str(boxes[i][0] * im_height),
+                'xmin': str(boxes[i][1] * im_width),
+                'ymax': str(boxes[i][2] * im_height),
+                'xmax': str(boxes[i][3] * im_width),
+                'score': str(scores[i]),
+                'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+            })
+    yield filename + ',' + str(detections)
+
+def parse_known_args(argv):
+  """Parses args for the workflow."""
+  parser = argparse.ArgumentParser()
+  parser.add_argument(
+      '--input',
+      dest='input',
+      required=True,
+      help='Path to the text file containing image names.')
+  parser.add_argument(
+      '--output',
+      dest='output',
+      required=True,
+      help='Path where to save output predictions.'
+      ' text file.')
+  parser.add_argument(
+      '--engine_path',
+      dest='engine_path',
+      required=True,
+      help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+      'TensorRT engine.')
+  parser.add_argument(
+      '--images_dir',
+      default=None,
+      help='Path to the directory where images are stored.'
+      'Not required if image names in the input file have absolute path.')
+  return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+  """
+  Args:
+    argv: Command line arguments defined for this example.
+  """
+  known_args, pipeline_args = parse_known_args(argv)
+  pipeline_options = PipelineOptions(pipeline_args)
+  pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+  engine_handler = KeyedModelHandler(
+      TensorRTEngineHandlerNumPy(
+          min_batch_size=1, max_batch_size=1,
+        engine_path=known_args.engine_path))
+
+  with beam.Pipeline(options=pipeline_options) as p:
+    filename_value_pair = (
+        p
+        | 'ReadImageNames' >> beam.io.ReadFromText(
+            known_args.input, skip_header_lines=0)
+        | 'ReadImageData' >> beam.Map(
+            lambda image_name: read_image(
+                image_file_name=image_name, path_to_dir=known_args.images_dir))
+        | 'AttachImageSizeToKey' >> beam.Map(attach_im_size_to_key)
+        | 'PreprocessImages' >> beam.MapTuple(
+            lambda file_name, data: (file_name, preprocess_image(data))))
+    predictions = (
+        filename_value_pair
+        | 'PyTorchRunInference' >> RunInference(engine_handler)
+        | 'ProcessOutput' >> beam.ParDo(PostProcessor()))
+
+    if known_args.output:
+      predictions | "WriteOutputToGCS" >> beam.io.WriteToText(
+        known_args.output,
+        shard_name_template='',
+        append_trailing_newlines=True)
+

Review Comment:
   Originally, the output wasn't required, which is why we had the if statement. We then changed it to be required, but forgot to take out the if statement.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929458567


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)

Review Comment:
   Sure, I'll put in this one liner to replace current logger stuff.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930210238


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file

Review Comment:
   @yeandy


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference_test.py:
##########
@@ -0,0 +1,292 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file

Review Comment:
   @yeandy


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930425229


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   we could introduce a context factory that will have a thread-level cache.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937052136


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   > which will let you bring your own memory.

   What would we need to do to manage memory in this case?


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   > which will let you bring your own memory.

   Thanks! What would we need to do to manage memory in this case?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937158987


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Using multiple GPUs efficiently may not be straightforward with Beam Python. I think we'd need to understand how common users would need something like this - users would need to utilize a single gpu to the fullest extent first, and it should be a condition where adding another GPU outweighs starting another worker with a single GPU.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r933375572


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   > The treads are managed by a ThreadPool, which is backed by a LIFO queue.

   Correct me if I overlooked something, but aren't we [instantiating](https://docs.python.org/3/library/queue.html#queue.Queue) a FIFO queue here?
   https://github.com/apache/beam/blob/48b534939468cc8e6dd403f11689a4433ca2e5a4/sdks/python/apache_beam/utils/thread_pool_executor.py#L76


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r934960498


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file

Review Comment:
   Looks like there was an [issue (BEAM-9064)](https://issues.apache.org/jira/browse/BEAM-9064) to add `pytype` checks to our lint checks. One of the prerequisite [tasks (BEAM-9071)](https://issues.apache.org/jira/browse/BEAM-9071) was to ignore pytype until the typing feature was fully developed. [(BEAM-9071)](https://issues.apache.org/jira/browse/BEAM-9071) was completed, which populated all of our python files with `# pytype: skip-file`, but it seems that [issue (BEAM-9064)](https://issues.apache.org/jira/browse/BEAM-9064) was never done as the PR was closed.

   And looks like `# pytype: skip-file` is present in both main module files as well as test files.

   @tvalentyn How should we handle this `# pytype: skip-file`? Maybe keep it for now until we have bandwidth to clean up our linting/typing processes?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r947359320


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   We will have an internal sync this week to try to answer as much as possible memory related questions. I think it is not scheduled yet, but should happen this week. @tvalentyn My apologies, I should've kept you updated


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r948239867


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Great, thank you for helping to investigate this!

   > If you plan to use all N concurrently, then I'd just let TensorRT manage the per-context memory

   The assumption is that contexts will be used concurrently. Is the per-context allocation static? I think we will have to choose between:
   - creating contexts on demand as new threads spun up, possibly with a maximum limit for total # of contexts
   - pre-creating a limited number of contexts and block threads until shared contexts become available, or just limit thread parallelism to the number of context that we can afford for a particular engine.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] ryanthompson591 commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
ryanthompson591 commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r948348979


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,295 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):

Review Comment:
   This method is no longer needed so you can clean this code up.

   https://github.com/apache/beam/pull/22282

   This is now validated in the base implementation.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r948361397


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,295 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):

Review Comment:
   Ok, I'll take it out


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r948239867


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Great, thank you for helping to investigate this!

   > If you plan to use all N concurrently, then I'd just let TensorRT manage the per-context memory

   The assumption is that contexts will be used concurrently. Is the per-context memory allocation static? I think we will have to choose between:
   - creating contexts on demand as new threads spun up, possibly with a maximum limit for total # of contexts
   - pre-creating a limited number of contexts and block threads until shared contexts become available, or just limit thread parallelism to the number of contexts that we can afford for a particular engine.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r954121173


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Sounds like `threading.Lock` should work here? Unless there is a separate API provided by Beam which would be preferred?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r954068946


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   @tvalentyn Do you think we can resolve this one?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937137836


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Another thing we have to consider is if users are using multiple GPUs. For Dataflow jobs, one would modify the count like so:
   ```
   python -m apache_beam.examples.inference.tensorrt_object_detection \
   --experiment="worker_accelerator=type:nvidia-tesla-t4;count:1;install-nvidia-driver" \
   ...
   ```
   or
   ```
   python -m apache_beam.examples.inference.tensorrt_object_detection \
   --experiment="worker_accelerator=type:nvidia-tesla-t4;count:2;install-nvidia-driver" \
   ...
   ```
   I'm wondering the best way to manage this. For example, an easy scenario is if we had 4 threads, and 1 GPU. But it would be a bit more complicated if there were 4 threads and 2 GPUs, or 4 threads and 4 GPUs.

   A user in this forum [discussion](https://github.com/NVIDIA/TensorRT/issues/219#issuecomment-559249117) was asking how to properly deal with multithreading with multiple GPUs. The solution was to make a custom class inheriting from Thread, where each thread has the correct mapping of engine and context for the correct GPU.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937077817


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Got it, I think I understand. Is `engine.device_memory_size` defined by a particular tensorrt model being used for predictions?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922235732


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   @kennknowles "Other information about the origin of the code should go into NOTICE" what does that mean in practice? Can you explain step by step, thanks.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922284256


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)

Review Comment:
   @pranavm-nvidia Do you think we should wrap every single CUDA call in ASSERT_DRV(), or just the first one will suffice?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r957571457


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   @tvalentyn any thoughts?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1240674518

   Run Python 3.8 PostCommit


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] AnandInguva commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
AnandInguva commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1247302588

   Run Python 3.8 PostCommit


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r971910739


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   I can paste the contents of the Dockerfile we used in a comment in https://github.com/apache/beam/issues/22651


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972262084


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   @tvalentyn Ideas on a good location? I was going to just upload to `apache_beam/ml/inference/` directory, if that's ok.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1249611573

   Good job everyone, and thanks @damccorm for the merge!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] damccorm commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
damccorm commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972992547


##########
sdks/python/test-suites/containers/tensorrt_runinference/README.md:
##########
@@ -0,0 +1,5 @@
+# TensorRT Dockerfile for Beam

Review Comment:
   ```suggestion
   <!--
       Licensed to the Apache Software Foundation (ASF) under one
       or more contributor license agreements.  See the NOTICE file
       distributed with this work for additional information
       regarding copyright ownership.  The ASF licenses this file
       to you under the Apache License, Version 2.0 (the
       "License"); you may not use this file except in compliance
       with the License.  You may obtain a copy of the License at

         http://www.apache.org/licenses/LICENSE-2.0

       Unless required by applicable law or agreed to in writing,
       software distributed under the License is distributed on an
       "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
       KIND, either express or implied.  See the License for the
       specific language governing permissions and limitations
       under the License.
   -->

   # TensorRT Dockerfile for Beam
   ```


##########
sdks/python/test-suites/containers/tensorrt_runinference/tensor_rt.dockerfile:
##########
@@ -0,0 +1,19 @@
+ARG BUILD_IMAGE=nvcr.io/nvidia/tensorrt:22.05-py3

Review Comment:
   ```suggestion
   # Licensed to the Apache Software Foundation (ASF) under one
   # or more contributor license agreements.  See the NOTICE file
   # distributed with this work for additional information
   # regarding copyright ownership.  The ASF licenses this file
   # to you under the Apache License, Version 2.0 (the
   # "License"); you may not use this file except in compliance
   # with the License.  You may obtain a copy of the License at
   #
   #     http://www.apache.org/licenses/LICENSE-2.0
   #
   # Unless required by applicable law or agreed to in writing, software
   # distributed under the License is distributed on an "AS IS" BASIS,
   # WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
   # See the License for the specific language governing permissions and
   # limitations under the License.

   ARG BUILD_IMAGE=nvcr.io/nvidia/tensorrt:22.05-py3
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972436770


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   no precedents, i like @damccorm 's idea. Could use: test-suites/dataflow/containers/tensortt_runinference


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917938842


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()
+    assert context
+    # Setup I/O bindings
+    inputs = []
+    outputs = []
+    allocations = []
+    for i in range(engine.num_bindings):

Review Comment:
   Memory allocation should be moved out of `run_inference` as it only needs to be done once


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r931694468


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   I think @pranavm-nvidia can give a better estimate on how expensive this might me.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922266240


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)

Review Comment:
   Right, maybe something like this:
   ```py
   def ASSERT_DRV(args):
       err, ret = args[0], args[1:]
       ... # Check error
       if len(ret) == 1: # Special case so that no unpacking is needed at call-site
           return ret[0]
       return ret
   ```

   That way you can use it like so:
   ```py
   allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922186717


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]

Review Comment:
   ```suggestion
         name = self.engine.get_binding_name(i)
         dtype = self.engine.get_binding_dtype(i)
         shape = self.engine.get_binding_shape(i)
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929456481


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Roughly speaking, at submission we create a DAG of the pipeline. The transforms and pipeline user code is represented in serialized form.
   On the runner the code will be deserialized and actually executed.

   To test out the UX, one should try to run the example on Dataflow runner. First, launching from a machine with GPUs, then launch from a machine without GPUs. I assume we have already ran with the Direct  runner (all processing done on the same machine), if not do that first.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r932767094


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   TLDR: we reuse threads, but there can be some churn.

   Here's the relevant code:
   https://github.com/apache/beam/blob/9154f8b3cf01fce067cea7ad7522e1db3154ff89/sdks/python/apache_beam/runners/worker/sdk_worker.py#L352-L361
   https://github.com/apache/beam/blob/48b534939468cc8e6dd403f11689a4433ca2e5a4/sdks/python/apache_beam/utils/thread_pool_executor.py#L82-L107

   The treads are managed by a ThreadPool, which is backed by a FIFO queue. Inactive threads can be removed from the queue if their number exceed a threshold.
   W.r.t. our usecase, we could potentially consider modifying the underlying collection to be a deque, so that inactive threads are removed from one end, and use LIFO so there is a higher chance of reusing the same threads.

   In case of Batch jobs, I think the thread queue is low, in case of streaming jobs, I am not sure, likely low after all threads have spawned unless there is some bursty behavior. I can ask around. Could you also elaborate a bit now on the costs for creating the context?


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Yes, we have a FIFO currently, that was a typo (corrected).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r934994527


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Yes, we have a FIFO currently, that was a typo.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] kennknowles commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
kennknowles commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r921450144


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   Since we are having this discussion, do you have an individual or corporate contribution license agreement on file with ASF?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1195976337

   Just a heads-up, Andy is OOO atm, so his responses may be delayed till next week.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930417691


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Thanks for the feedback!

   So, I think the return result of the load_model (i.e. the engine) will be shared between threads: https://github.com/apache/beam/pull/22131/files#diff-145530e8e39084aed7792a4d3b8104258ea1635db466ab48a58f168bce10dde3R204

   OTOH, it looks like we only create the execution context once, when we initialize the engine: https://github.com/apache/beam/pull/22131/files#diff-145530e8e39084aed7792a4d3b8104258ea1635db466ab48a58f168bce10dde3R114

   in this case, the context and the engine will both be shared across threads.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r917046241


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -19,7 +19,6 @@

 import numpy as np
 import os
-import pycuda.autoinit

Review Comment:
   Sounds good. I was getting a `pylint` error, but we can configure it to be ignored.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1179203641

   R: @yeandy @AnandInguva @tvalentyn


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919159083


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:

Review Comment:
   [ONNX](https://onnx.ai/) is a format with which you can save your ML models. It's a widely supported format and we use this format as a main one for TensorRT engine creation (parse ONNX -> create TRT engine). I expect a lot of people will use it, if not the majority. This is a very important use case and it's not just for testing.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940463189


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   `execute_async_v2` is a non-blocking call


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r947352378


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   > we should implement a shared object cache

   We can take over this work and I think I know someone who may be interested to help here, however I'd like to understand the limits of parallelization we can plan for. Do you have insights to questions above @pranavm-nvidia ?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946852538


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   Yeah makes sense. Ok, I'll add stream sync at the end of the inference func


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946910840


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   The device-to-host copy is also asynchronous, so the stream sync would have to be after that.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r950643616


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,

Review Comment:
   Will adding it in code above class like you've mentioned add it to docstring too? If some other process has to be added to address docstring, please specify


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] kennknowles commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
kennknowles commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r921449330


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long

Review Comment:
   This may help: https://www.apache.org/foundation/license-faq.html#provenance


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922255055


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+    TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+
+    # Setup I/O bindings
+    for i in range(self.engine.num_bindings):
+      is_input = False
+      if self.engine.binding_is_input(i):
+        is_input = True
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      if is_input:
+        batch_size = shape[0]
+      size = np.dtype(trt.nptype(dtype)).itemsize
+      for s in shape:
+        size *= s
+      err, allocation = cuda.cuMemAlloc(size)

Review Comment:
   Sorry, after since it takes err


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] ryanthompson591 commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
ryanthompson591 commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920232106


##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,238 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with TensorRT."""
+
+import argparse
+import io
+import numpy as np
+import os
+from PIL import Image
+from typing import Iterable, Optional, Tuple
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import (KeyedModelHandler, PredictionResult,
+                                           RunInference)
+from apache_beam.ml.inference.tensorrt_inference import \
+    TensorRTEngineHandlerNumPy
+from apache_beam.options.pipeline_options import PipelineOptions, SetupOptions
+
+COCO_OBJ_DET_CLASSES = [
+    'person',
+    'bicycle',
+    'car',
+    'motorcycle',
+    'airplane',
+    'bus',
+    'train',
+    'truck',
+    'boat',
+    'traffic light',
+    'fire hydrant',
+    'street sign',
+    'stop sign',
+    'parking meter',
+    'bench',
+    'bird',
+    'cat',
+    'dog',
+    'horse',
+    'sheep',
+    'cow',
+    'elephant',
+    'bear',
+    'zebra',
+    'giraffe',
+    'hat',
+    'backpack',
+    'umbrella',
+    'shoe',
+    'eye glasses',
+    'handbag',
+    'tie',
+    'suitcase',
+    'frisbee',
+    'skis',
+    'snowboard',
+    'sports ball',
+    'kite',
+    'baseball bat',
+    'baseball glove',
+    'skateboard',
+    'surfboard',
+    'tennis racket',
+    'bottle',
+    'plate',
+    'wine glass',
+    'cup',
+    'fork',
+    'knife',
+    'spoon',
+    'bowl',
+    'banana',
+    'apple',
+    'sandwich',
+    'orange',
+    'broccoli',
+    'carrot',
+    'hot dog',
+    'pizza',
+    'donut',
+    'cake',
+    'chair',
+    'couch',
+    'potted plant',
+    'bed',
+    'mirror',
+    'dining table',
+    'window',
+    'desk',
+    'toilet',
+    'door',
+    'tv',
+    'laptop',
+    'mouse',
+    'remote',
+    'keyboard',
+    'cell phone',
+    'microwave',
+    'oven',
+    'toaster',
+    'sink',
+    'refrigerator',
+    'blender',
+    'book',
+    'clock',
+    'vase',
+    'scissors',
+    'teddy bear',
+    'hair drier',
+    'toothbrush',
+    'hair brush',
+]
+
+
+def attach_im_size_to_key(x):
+    width, height = x[1].size
+    return ((x[0], width, height), x[1])
+
+
+def read_image(image_file_name: str,
+               path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+  if path_to_dir is not None:
+    image_file_name = os.path.join(path_to_dir, image_file_name)
+  with FileSystems().open(image_file_name, 'r') as file:
+    data = Image.open(io.BytesIO(file.read())).convert('RGB')
+    return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+  ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+  image = image.resize(ssd_mobilenet_v2_320x320_input_dims,
+    resample=Image.Resampling.BILINEAR)
+  image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+  return image
+
+
+class PostProcessor(beam.DoFn):
+  def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+    key, prediction_result = element
+    filename, im_width, im_height = key
+    nums = prediction_result.inference[0]
+    boxes = prediction_result.inference[1]
+    scores = prediction_result.inference[2]
+    classes = prediction_result.inference[3]
+    detections = []
+    for i in range(int(nums[0])):
+        detections.append({
+                'ymin': str(boxes[i][0] * im_height),
+                'xmin': str(boxes[i][1] * im_width),
+                'ymax': str(boxes[i][2] * im_height),
+                'xmax': str(boxes[i][3] * im_width),
+                'score': str(scores[i]),
+                'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+            })
+    yield filename + ',' + str(detections)
+
+def parse_known_args(argv):
+  """Parses args for the workflow."""
+  parser = argparse.ArgumentParser()
+  parser.add_argument(
+      '--input',
+      dest='input',
+      required=True,
+      help='Path to the text file containing image names.')
+  parser.add_argument(
+      '--output',
+      dest='output',
+      required=True,
+      help='Path where to save output predictions.'
+      ' text file.')
+  parser.add_argument(
+      '--engine_path',
+      dest='engine_path',
+      required=True,
+      help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+      'TensorRT engine.')
+  parser.add_argument(
+      '--images_dir',
+      default=None,
+      help='Path to the directory where images are stored.'
+      'Not required if image names in the input file have absolute path.')
+  return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+  """
+  Args:
+    argv: Command line arguments defined for this example.
+  """
+  known_args, pipeline_args = parse_known_args(argv)
+  pipeline_options = PipelineOptions(pipeline_args)
+  pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+  engine_handler = KeyedModelHandler(
+      TensorRTEngineHandlerNumPy(
+          min_batch_size=1, max_batch_size=1,
+        engine_path=known_args.engine_path))
+
+  with beam.Pipeline(options=pipeline_options) as p:
+    filename_value_pair = (
+        p
+        | 'ReadImageNames' >> beam.io.ReadFromText(
+            known_args.input, skip_header_lines=0)
+        | 'ReadImageData' >> beam.Map(
+            lambda image_name: read_image(
+                image_file_name=image_name, path_to_dir=known_args.images_dir))
+        | 'AttachImageSizeToKey' >> beam.Map(attach_im_size_to_key)
+        | 'PreprocessImages' >> beam.MapTuple(
+            lambda file_name, data: (file_name, preprocess_image(data))))
+    predictions = (
+        filename_value_pair
+        | 'PyTorchRunInference' >> RunInference(engine_handler)
+        | 'ProcessOutput' >> beam.ParDo(PostProcessor()))
+
+    if known_args.output:
+      predictions | "WriteOutputToGCS" >> beam.io.WriteToText(
+        known_args.output,
+        shard_name_template='',
+        append_trailing_newlines=True)
+

Review Comment:
   Yeah, looks like a little too much output to be human readable.

   I think what brought on my comment was that it seemed strange to run the pipeline with no output at all.

   Some other things you could do:
   ```
   else:
     LOG.warning('No output file specified. No output will be written')
   ```
   or just make the output field mandatory.

   It's up to you.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] ryanthompson591 commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
ryanthompson591 commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920100128


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      print("Failed to load ONNX file: {}".format(onnx_path))
+      for error in range(parser.num_errors):
+        print(parser.get_error(error))
+      sys.exit(1)
+  builder.reset()
+  return network
+
+
+def _build_engine(network):
+  builder = trt.Builder(LOGGER)
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              trt.ICudaEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage:
+      pcoll | RunInference(
+        TensorRTEngineHandlerNumPy(
+          min_batch_size=1,
+          max_batch_size=1,
+          engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+      currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> trt.ICudaEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    return _load_engine(self.engine_path)
+
+  def load_onnx(self) -> trt.INetworkDefinition:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  #
+  def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+    """Build an engine according to parsed/created network."""
+    return _build_engine(network)
+
+  def run_inference(
+      self,
+      batch: np.ndarray,
+      engine: trt.ICudaEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    _validate_inference_args(inference_args)
+    context = engine.create_execution_context()

Review Comment:
   To add some context that might help.

   In beam you have the runner and the workers. If you were to start beam up it would make a graph (in the runner) then pickle all the classes/methods/data and send that to the workers.

   runner (makes graph) -> pickled -> workers (unpickle graph)

   So my question would be, at which point does TensorRTEngineHandlerNumPy get instantiated? My feeling is that if it's in load model, it should work, but if it's in your runner code it might fail (because it fails to pickle).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r923892696


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda

Review Comment:
   @yeandy just tested, it is ok


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1188257817

   @yeandy I'll look into what you've mentioned tomorrow, will try to address the issues as soon as I figure them out.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930024028


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Ok, leave it for the future. Big thanks @pranavm-nvidia, any tips where I can read more about how to properly implement this?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930537831


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   @tvalentyn Any examples you can point me to implement something like this. I want to make sure I follow your specific vision of this.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929440958


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   Is this implementation thread-safe?
   Beam SDKs can start multiple concurrent threads within sdk_worker process, which will be processing the data. Are there any concerns with that from hardware or software standpoint?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929444449


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   1. README.md has a section about TRT dependencies. As soon as users will go through it, they will realize that they need a certain set of requirements. Not only software but hardware. In addition, it says: "TensorRT SDK for high-performance deep learning inference with NVIDIA GPUs". I think it is clear enough. Please let me know if you think otherwise and would like to change something. TensorRT only works with GPUs, there is no other version.

   2. You can install driver, CUDA, cuDNN, TRT without GPU being present. However, if you want to run something with TRT. You will need a GPU. Additional [good info](https://github.com/apache/beam/pull/22131#issuecomment-1189323009), cannot install trt or cuda python packages without CUDA library and TensorRT library.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929447344


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Re#2:

   If at all possible we should import the libraries requiring GPUs only in the portion of the code that will be executed on the worker. It would be a much more convenient user experience if a user does not need GPUs to launch a pipeline that will spin up workers with GPUs in the cloud.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929454305


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   What is executed on the workers and what is executed on a submission machine? I am not very familiar since I pretty much just ran unit tests and obj detection sample locally. Considering we can do this, how would we do smth like this? Can you give an example? Maybe Pytorch implementation handles it somehow, I don't think you need any pytroch packages (or any packages) on a submission machine.

   @yeandy You were testing on GCP, any interesting observations/comments about it? Maybe something you can recommend? (Btw, congrats on presenting at the [summit](https://2022.beamsummit.org/sessions/runinference/), saw photos, looked cool)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929451041


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine

Review Comment:
   It'll fail as soon as you will try to create `trt.Runtime`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929456218


##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
 ```
 Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.

+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
 tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:

Review Comment:
   Ok, you partially answered my question. It will make a mess though, every function in `tensorrt_inference.py` needs TRT.  Plus we need to maintain global trt logger. Maybe we can package it somehow and bounce it around.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937060028


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   The only requirement is that you set `context.device_memory` to point to a region of GPU memory at least as large as `engine.device_memory_size` (which is the size in bytes). You'd still need to make sure you're not using the same memory from different threads at the same time, but you would at least have a greater degree of control over the allocations.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937059085


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file

Review Comment:
   Sounds orthogonal to the PR,  I'll start a discussion off this PR. Thanks


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940720337


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   > We'd want to first resolve the thread-safety concern with 1 GPU.

   We need to address the thread safety concern per feedback in this thread. At minimum, let's add a lock and avoid sharing the context.

   I  discussed this a bit with lcwik. In short term, we should implement a shared object cache for managing shared execution contexts. We should avoid the affinity between thread IDs and contexts, and instead make it possible to transfer shared contexts between threads.

   We should be able to rely on `start_bundle` and `finish_bundle` to claim and release the contexts from the shared pool.

   Open question is GPU memory management:
   - How many contexts do we create and how much GPU memory should we allocate per each context. Can we know at runtime what's the max # of context we can create for a particular engine? What are the tradeoffs between creating more contexts with less memory per contexts vs less contexts? Will pipeline degrade gracefully when more memory is needed or something will crash? If we solve memory management, adding the shared pool should not be too complex. We can refer to `UnboundedThreadPoolExecutor` implementation for inspiration.

   - In the future, we can consider sharing the object cache w/ contexts between multiple SDK processes (not just between threads) via `multiprocessing`. This may be worthwhile with A100 accelerators that have more GPU memory that can be shared across multiple processes, and this could allow users benefiting from MPS.  We'd have to share contexts between processes - are these objects large in size? If it is just metadata, the overhead may not be significant.  This is something we should also consider for Tensorflow runinference, since Tensorflow does not work well when using the same GPU from multiple processes and manual GPU memory management is needed, so Beam RunInference could help make it easier.  In the medium term, we may need to recommend limiting pipelines to use 1 process only.

   Summary of questions asked above:
   - How many contexts can we create and how do you recommend to manage memory b/w them?
   - Are context objects small?
   - Does TensorRT support concurrent execution on multiple processes on the same GPU? I believe, I asked this and answer was `yes`, just, double checking...  If yes, how GPU memory management is solved?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r940428328


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   I don't think it is a blocking call


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958750785


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   We could use threading.RLock, so that the same thread can also aquire it if it somehow becomes necessary, I haven't look very close into where to place this lock.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] damccorm commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
damccorm commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972992087


##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
     }
   }
 }
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+  dependsOn 'installGcpTest'
+  dependsOn ':sdks:python:sdist'
+ doLast {
+  def testOpts = basicPytestOpts
+  def argMap = [
+    "runner": "DataflowRunner",
+    "machine_type":"n1-standard-4",
+    "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",

Review Comment:
   Looks like they're missing apache headers


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r934999778


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   If precious memory is allocated that is already a good motivation to reuse. That means, we'd have to also think how garbage collection would work so that creating these contexts wouldn't cause OOMs in a long running streaming job.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1231993737

   @ryanthompson591 My bad, forgot about implementation. Pushed now, thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958938153


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.utils.annotations import experimental
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      raise ValueError(f"Failed to load ONNX file: {onnx_path}")
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+@experimental(extra_message="No backwards-compatibility guarantees.")
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    **NOTE:** This API and its implementation are under development and
+    do not provide backward compatibility guarantees.
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network

Review Comment:
   ```
   with context_lock:
      # move the code that is using shared context and needs to be guarded by a lock here.

   return [
      # PredictionResults
   ]
   ```


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      log.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        log.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+  """CUDA error checking."""
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+    trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(

Review Comment:
   no. I took a closer look, see suggestions. I haven't tested it.


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.utils.annotations import experimental
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      raise ValueError(f"Failed to load ONNX file: {onnx_path}")
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,

Review Comment:
   ```suggestion
           self.context,
           self.context_lock,
   ```


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.utils.annotations import experimental
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      raise ValueError(f"Failed to load ONNX file: {onnx_path}")
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()

Review Comment:
   ```suggestion
       self.context = engine.create_execution_context()
       self.context_lock = threading.RLock()
   ```


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys

Review Comment:
   ```suggestion
   import sys
   import threading
   ```


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.utils.annotations import experimental
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      raise ValueError(f"Failed to load ONNX file: {onnx_path}")
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+@experimental(extra_message="No backwards-compatibility guarantees.")
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    **NOTE:** This API and its implementation are under development and
+    do not provide backward compatibility guarantees.
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    (
+        engine,
+        context,

Review Comment:
   ```suggestion
           context,
           context_lock,
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r947187307


##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+  import tensorrt as trt
+  TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+  trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+  LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+  TRT_LOGGER = None
+  msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+    'runner has tensorrt dependencies installed.'
+  LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+  import tensorrt as trt
+  file = FileSystems.open(engine_path, 'rb')
+  runtime = trt.Runtime(TRT_LOGGER)
+  engine = runtime.deserialize_cuda_engine(file.read())
+  assert engine
+  return engine
+
+
+def _load_onnx(onnx_path):
+  import tensorrt as trt
+  builder = trt.Builder(TRT_LOGGER)
+  network = builder.create_network(
+      flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+  parser = trt.OnnxParser(network, TRT_LOGGER)
+  with FileSystems.open(onnx_path) as f:
+    if not parser.parse(f.read()):
+      LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+      for error in range(parser.num_errors):
+        LOGGER.error(parser.get_error(error))
+      sys.exit(1)
+  return network, builder
+
+
+def _build_engine(network, builder):
+  import tensorrt as trt
+  config = builder.create_builder_config()
+  runtime = trt.Runtime(TRT_LOGGER)
+  plan = builder.build_serialized_network(network, config)
+  engine = runtime.deserialize_cuda_engine(plan)
+  builder.reset()
+  return engine
+
+
+def _validate_inference_args(inference_args):
+  """Confirms that inference_args is None.
+
+  TensorRT engines do not need extra arguments in their execute_v2() call.
+  However, since inference_args is an argument in the RunInference interface,
+  we want to make sure it is not passed here in TensorRT's implementation of
+  RunInference.
+  """
+  if inference_args:
+    raise ValueError(
+        'inference_args were provided, but should be None because TensorRT '
+        'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+  """CUDA error checking."""
+  from cuda import cuda
+  err, ret = args[0], args[1:]
+  if isinstance(err, cuda.CUresult):
+    if err != cuda.CUresult.CUDA_SUCCESS:
+      raise RuntimeError("Cuda Error: {}".format(err))
+  else:
+    raise RuntimeError("Unknown error type: {}".format(err))
+  # Special case so that no unpacking is needed at call-site.
+  if len(ret) == 1:
+    return ret[0]
+  return ret
+
+
+class TensorRTEngine:
+  def __init__(self, engine: trt.ICudaEngine):
+    """Implementation of the TensorRTEngine class which handles
+    allocations associated with TensorRT engine.
+
+    Example Usage::
+
+      TensorRTEngine(engine)
+
+    Args:
+      engine: trt.ICudaEngine object that contains TensorRT engine
+    """
+    from cuda import cuda
+    import tensorrt as trt
+    self.engine = engine
+    self.context = engine.create_execution_context()
+    self.inputs = []
+    self.outputs = []
+    self.gpu_allocations = []
+    self.cpu_allocations = []
+    """Setup I/O bindings."""
+    for i in range(self.engine.num_bindings):
+      name = self.engine.get_binding_name(i)
+      dtype = self.engine.get_binding_dtype(i)
+      shape = self.engine.get_binding_shape(i)
+      size = trt.volume(shape) * dtype.itemsize
+      allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+      binding = {
+          'index': i,
+          'name': name,
+          'dtype': np.dtype(trt.nptype(dtype)),
+          'shape': list(shape),
+          'allocation': allocation,
+          'size': size
+      }
+      self.gpu_allocations.append(allocation)
+      if self.engine.binding_is_input(i):
+        self.inputs.append(binding)
+      else:
+        self.outputs.append(binding)
+
+    assert self.context
+    assert len(self.inputs) > 0
+    assert len(self.outputs) > 0
+    assert len(self.gpu_allocations) > 0
+
+    for output in self.outputs:
+      self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+    # Create CUDA Stream.
+    self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+  def get_engine_attrs(self):
+    """Returns TensorRT engine attributes."""
+    return (
+        self.engine,
+        self.context,
+        self.inputs,
+        self.outputs,
+        self.gpu_allocations,
+        self.cpu_allocations,
+        self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+                                              PredictionResult,
+                                              TensorRTEngine]):
+  def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+    """Implementation of the ModelHandler interface for TensorRT.
+
+    Example Usage::
+
+      pcoll | RunInference(
+          TensorRTEngineHandlerNumPy(
+            min_batch_size=1,
+            max_batch_size=1,
+            engine_path="my_uri"))
+
+    Args:
+      min_batch_size: minimum accepted batch size.
+      max_batch_size: maximum accepted batch size.
+      kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+        currently supported.
+
+    See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+    for details
+    """
+    self.min_batch_size = min_batch_size
+    self.max_batch_size = max_batch_size
+    if 'engine_path' in kwargs:
+      self.engine_path = kwargs.get('engine_path')
+    elif 'onnx_path' in kwargs:
+      self.onnx_path = kwargs.get('onnx_path')
+
+  def batch_elements_kwargs(self):
+    """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+    return {
+        'min_batch_size': self.min_batch_size,
+        'max_batch_size': self.max_batch_size
+    }
+
+  def load_model(self) -> TensorRTEngine:
+    """Loads and initializes a TensorRT engine for processing."""
+    engine = _load_engine(self.engine_path)
+    return TensorRTEngine(engine)
+
+  def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+    """Loads and parses an onnx model for processing."""
+    return _load_onnx(self.onnx_path)
+
+  def build_engine(
+      self, network: trt.INetworkDefinition,
+      builder: trt.Builder) -> TensorRTEngine:
+    """Build an engine according to parsed/created network."""
+    engine = _build_engine(network, builder)
+    return TensorRTEngine(engine)
+
+  def run_inference(
+      self,
+      batch: Sequence[np.ndarray],
+      engine: TensorRTEngine,
+      inference_args: Optional[Dict[str, Any]] = None
+  ) -> Iterable[PredictionResult]:
+    """
+    Runs inferences on a batch of Tensors and returns an Iterable of
+    TensorRT Predictions.
+
+    Args:
+      batch: A np.ndarray or a np.ndarray that represents a concatenation
+        of multiple arrays as a batch.
+      engine: A TensorRT engine.
+      inference_args: Any additional arguments for an inference
+        that are not applicable to TensorRT.
+
+    Returns:
+      An Iterable of type PredictionResult.
+    """
+    from cuda import cuda
+    _validate_inference_args(inference_args)
+    (
+        engine,
+        context,
+        inputs,
+        outputs,
+        gpu_allocations,
+        cpu_allocations,
+        stream) = engine.get_engine_attrs()
+    # Process I/O and execute the network
+    _assign_or_fail(
+        cuda.cuMemcpyHtoDAsync(
+            inputs[0]['allocation'],
+            np.ascontiguousarray(batch),
+            inputs[0]['size'],
+            stream))
+    context.execute_async_v2(gpu_allocations, stream)

Review Comment:
   Would using `execute_v2()` not achieve the same effect as using the async version + doing a sync later?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@beam.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r947280258
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+ import tensorrt as trt
+ TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+ LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+ TRT_LOGGER = None
+ msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+ 'runner has tensorrt dependencies installed.'
+ LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+ import tensorrt as trt
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ import tensorrt as trt
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ LOGGER.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ import tensorrt as trt
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+ """CUDA error checking."""
+ from cuda import cuda
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ from cuda import cuda
+ import tensorrt as trt
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
+ self,
+ batch: Sequence[np.ndarray],
+ engine: TensorRTEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ from cuda import cuda
+ _validate_inference_args(inference_args)
+ (
+ engine,
+ context,
+ inputs,
+ outputs,
+ gpu_allocations,
+ cpu_allocations,
+ stream) = engine.get_engine_attrs()
+ # Process I/O and execute the network
+ _assign_or_fail(
+ cuda.cuMemcpyHtoDAsync(
+ inputs[0]['allocation'],
+ np.ascontiguousarray(batch),
+ inputs[0]['size'],
+ stream))
+ context.execute_async_v2(gpu_allocations, stream)
Review Comment:
It already supports multiple outputs, at least in case of object detection it will be able to handle 4 outputs: boxes, classes, scores and number of predictions per image. The only thing left is to add support for multiple inputs, probably in future.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946841828
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+ import tensorrt as trt
+ TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+ LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+ TRT_LOGGER = None
+ msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+ 'runner has tensorrt dependencies installed.'
+ LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+ import tensorrt as trt
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ import tensorrt as trt
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ LOGGER.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ import tensorrt as trt
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+ """CUDA error checking."""
+ from cuda import cuda
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ from cuda import cuda
+ import tensorrt as trt
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
+ self,
+ batch: Sequence[np.ndarray],
+ engine: TensorRTEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ from cuda import cuda
+ _validate_inference_args(inference_args)
+ (
+ engine,
+ context,
+ inputs,
+ outputs,
+ gpu_allocations,
+ cpu_allocations,
+ stream) = engine.get_engine_attrs()
+ # Process I/O and execute the network
+ _assign_or_fail(
+ cuda.cuMemcpyHtoDAsync(
+ inputs[0]['allocation'],
+ np.ascontiguousarray(batch),
+ inputs[0]['size'],
+ stream))
+ context.execute_async_v2(gpu_allocations, stream)
Review Comment:
In this case, synchronizing after each prediction call makes sense.
If instead, e.g., you synchronized after every other call, I don't see how you'd access the prediction results from the first call, as they'd be overwritten by the second call.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r946852538
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+ import tensorrt as trt
+ TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+ LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+ TRT_LOGGER = None
+ msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+ 'runner has tensorrt dependencies installed.'
+ LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+ import tensorrt as trt
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ import tensorrt as trt
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ LOGGER.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ import tensorrt as trt
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+ """CUDA error checking."""
+ from cuda import cuda
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ from cuda import cuda
+ import tensorrt as trt
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
+ self,
+ batch: Sequence[np.ndarray],
+ engine: TensorRTEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ from cuda import cuda
+ _validate_inference_args(inference_args)
+ (
+ engine,
+ context,
+ inputs,
+ outputs,
+ gpu_allocations,
+ cpu_allocations,
+ stream) = engine.get_engine_attrs()
+ # Process I/O and execute the network
+ _assign_or_fail(
+ cuda.cuMemcpyHtoDAsync(
+ inputs[0]['allocation'],
+ np.ascontiguousarray(batch),
+ inputs[0]['size'],
+ stream))
+ context.execute_async_v2(gpu_allocations, stream)
Review Comment:
Yeah makes sense. Ok, I'll add stream sync at the end of the call
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r950642496
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
Review Comment:
For some reason lint is failing.
Seeing 15:48:37 apache_beam/ml/inference/tensorrt_inference.py:20: error: Module '__future__' has no attribute 'annotations' [attr-defined]
Trying https://github.com/apache/beam/pull/22804/files to see if it fixes it.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r948016495
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
Like @azhurkevich said, we'll have more details after our internal sync, but I can provide a little background information until then.
The context mainly allocates three things:
1. Persistent host/device memory: This is for things like look-up tables to speed up computation.
2. Workspace/scratch memory: This is memory that is reused across layers and used during computation - e.g. if we compute Convolution as a GEMM, the generated matrix would be written to scratch memory.
3. Activation memory: This is to store intermediate tensors. TensorRT tries to reuse this across layers as much as possible, but the degree of reusability depends on the network architecture (e.g. parallel branches would require separate memory).
You can determine the total size of (2) and (3) by checking `engine.device_memory_size` and optionally manage both of these yourself by using `engine.create_execution_context_without_device_memory()` and setting `context.device_memory` to point to your own memory buffer. Otherwise, TensorRT will allocate them on a per-context basis.
Finally, to answer your questions:
> How many contexts can we create and how do you recommend to manage memory b/w them?
There's some nuance here, but effectively you're only limited by system resources. Regarding memory management, it depends on the use-case. Assuming you have N contexts, then:
- If you plan to use all N concurrently, then I'd just let TensorRT manage the per-context memory
- If you plan to use only some fraction, K, of them concurrently, then you can allocate enough memory for only K contexts and reuse that. The thing to be careful of is that contexts executing concurrently should not use the same memory.
> Are context objects small?
Generally no.
> Does TensorRT support concurrent execution on multiple processes on the same GPU? I believe, I asked this and answer was yes, just, double checking... If yes, how GPU memory management is solved?
Yes it does, but the CUDA context switching overhead might make this impractical (I'm not totally sure though, will need to double check this). For GPU memory management, I think it might be possible to use `nvshmem` to share memory across processes, but I don't have any experience with that.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r921600196
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
Review Comment:
@kennknowles I was added to Google CLA list, whatever that means. Have no idea about what is ASF.
With regards to header, I've reached out to legal. A person who was looking into my case is OOTO til next Monday, so hopefully he'll come and will resolve this issue. I am not legal, so I'd rather delegate this to him at the same time improving code on my end. Hope it's understandable.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922190967
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: {}".format(onnx_path))
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+
+ # Setup I/O bindings
+ for i in range(self.engine.num_bindings):
+ is_input = False
+ if self.engine.binding_is_input(i):
+ is_input = True
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ if is_input:
+ batch_size = shape[0]
+ size = np.dtype(trt.nptype(dtype)).itemsize
+ for s in shape:
+ size *= s
+ err, allocation = cuda.cuMemAlloc(size)
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert batch_size > 0
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return self.engine, self.context, self.inputs, self.outputs, self.gpu_allocations, self.cpu_allocations
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(self, network: trt.INetworkDefinition, builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
+ self,
+ batch: np.ndarray,
+ engine: TensorRTEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ _validate_inference_args(inference_args)
+ #Create CUDA Stream
+ err, stream = cuda.cuStreamCreate(0)
Review Comment:
The stream should also ideally persist across inference calls. Can it be moved into `TensorRTEngine`?
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r919467330
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ print("Failed to load ONNX file: {}".format(onnx_path))
+ for error in range(parser.num_errors):
+ print(parser.get_error(error))
+ sys.exit(1)
+ builder.reset()
+ return network
+
+
+def _build_engine(network):
+ builder = trt.Builder(LOGGER)
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ trt.ICudaEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage:
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> trt.ICudaEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ return _load_engine(self.engine_path)
+
+ def load_onnx(self) -> trt.INetworkDefinition:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ #
+ def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+ """Build an engine according to parsed/created network."""
+ return _build_engine(network)
+
+ def run_inference(
+ self,
+ batch: np.ndarray,
+ engine: trt.ICudaEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ _validate_inference_args(inference_args)
+ context = engine.create_execution_context()
Review Comment:
I actually initially tried to implement TensorRTEngineHandlerNumPy() with parameters like engine, builder, context, etc. However when used with Pipelines some part of Apache Beam would complain that objects are not picklable. Obviously, trt.Builder, trt.Runtime, trt.ICudaEngine are not picklable, hence I had to resort to TensorRTEngineHandlerNumPy() handling only simple parameters like strings and integers.
Let me see if I can overcome this issue with what you've suggested.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r922284886
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,245 @@
+#
+# SPDX-FileCopyrightText: NVIDIA CORPORATION & AFFILIATES
+# Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import numpy as np
+from cuda import cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence, Tuple
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: {}".format(onnx_path))
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+
+ # Setup I/O bindings
+ for i in range(self.engine.num_bindings):
+ is_input = False
+ if self.engine.binding_is_input(i):
+ is_input = True
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ if is_input:
+ batch_size = shape[0]
+ size = np.dtype(trt.nptype(dtype)).itemsize
+ for s in shape:
+ size *= s
+ err, allocation = cuda.cuMemAlloc(size)
Review Comment:
Should wrap all of them
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937050046
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
All the long running functions in `IExecutionContext` (`execute_async_v2`, `execute_v2`, etc.) release the GIL while they're running, so I think there could be a noticeable performance impact.
One way to mitigate the possibility of OOMs is to use [`create_execution_context_without_device_memory`](https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/infer/Core/Engine.html#tensorrt.ICudaEngine.create_execution_context_without_device_memory) which will let you bring your own memory.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r937102771
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
Yes, `device_memory_size` is tied to the model/engine.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r932767094
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
TLDR: we reuse threads, but there can be some churn.
Here's the relevant code:
https://github.com/apache/beam/blob/9154f8b3cf01fce067cea7ad7522e1db3154ff89/sdks/python/apache_beam/runners/worker/sdk_worker.py#L352-L361
https://github.com/apache/beam/blob/48b534939468cc8e6dd403f11689a4433ca2e5a4/sdks/python/apache_beam/utils/thread_pool_executor.py#L82-L107
The treads are managed by a ThreadPool, which is backed by a FIFO queue. Inactive threads can be removed from the queue if their number exceed a threshold.
W.r.t. our usecase, we could potentially consider modifying the underlying collection to be a deque, so that inactive threads are removed from one end, and use LIFO so there is a higher chance of reusing the same threads.
In case of Batch jobs, I think the thread churn is low, in case of streaming jobs, I am not sure, likely low after all threads have spawned unless there is some bursty behavior. I can ask around. Could you also elaborate a bit now on the costs for creating the context?
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r935683022
##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
```
Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.
+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:
Review Comment:
@yeandy Merged
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r935655939
##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -154,6 +169,52 @@ This writes the output to the `predictions.csv` with contents like:
```
Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.
+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:
Review Comment:
Updated the PR per your feedback. Tested, and it still works. Thanks!
And for dataflow, first make sure you have a GCP account, and can access your console and navigate to the Dataflow tab. I would suggest following [this](https://cloud.google.com/dataflow/docs/quickstarts/create-pipeline-python) or [this](https://beam.apache.org/get-started/quickstart-py/) (they are pretty similar) quickstart guide.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r920197102
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ print("Failed to load ONNX file: {}".format(onnx_path))
+ for error in range(parser.num_errors):
+ print(parser.get_error(error))
+ sys.exit(1)
+ builder.reset()
+ return network
+
+
+def _build_engine(network):
+ builder = trt.Builder(LOGGER)
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ trt.ICudaEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage:
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> trt.ICudaEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ return _load_engine(self.engine_path)
+
+ def load_onnx(self) -> trt.INetworkDefinition:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ #
+ def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+ """Build an engine according to parsed/created network."""
+ return _build_engine(network)
+
+ def run_inference(
+ self,
+ batch: np.ndarray,
+ engine: trt.ICudaEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ _validate_inference_args(inference_args)
+ context = engine.create_execution_context()
+ assert context
+ # Setup I/O bindings
+ inputs = []
+ outputs = []
+ allocations = []
+ for i in range(engine.num_bindings):
+ is_input = False
+ if engine.binding_is_input(i):
+ is_input = True
+ name = engine.get_binding_name(i)
+ dtype = engine.get_binding_dtype(i)
+ shape = engine.get_binding_shape(i)
+ if is_input:
+ batch_size = shape[0]
+ size = np.dtype(trt.nptype(dtype)).itemsize
+ for s in shape:
+ size *= s
+ allocation = cuda.mem_alloc(size)
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ }
+ allocations.append(allocation)
+ if engine.binding_is_input(i):
+ inputs.append(binding)
+ else:
+ outputs.append(binding)
+
+ assert batch_size > 0
+ assert len(inputs) > 0
+ assert len(outputs) > 0
+ assert len(allocations) > 0
+ # Prepare the output data
+ predictions = []
+ for output in outputs:
+ predictions.append(np.zeros(output['shape'], output['dtype']))
+ # Process I/O and execute the network
+ cuda.memcpy_htod(inputs[0]['allocation'], np.ascontiguousarray(batch))
+ context.execute_v2(allocations)
+ for output in range(len(predictions)):
+ cuda.memcpy_dtoh(predictions[output], outputs[output]['allocation'])
Review Comment:
Noted
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r921649875
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ print("Failed to load ONNX file: {}".format(onnx_path))
+ for error in range(parser.num_errors):
+ print(parser.get_error(error))
+ sys.exit(1)
+ builder.reset()
+ return network
+
+
+def _build_engine(network):
+ builder = trt.Builder(LOGGER)
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ trt.ICudaEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage:
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> trt.ICudaEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ return _load_engine(self.engine_path)
+
+ def load_onnx(self) -> trt.INetworkDefinition:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ #
+ def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+ """Build an engine according to parsed/created network."""
+ return _build_engine(network)
+
+ def run_inference(
+ self,
+ batch: np.ndarray,
+ engine: trt.ICudaEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ _validate_inference_args(inference_args)
+ context = engine.create_execution_context()
+ assert context
+ # Setup I/O bindings
+ inputs = []
+ outputs = []
+ allocations = []
+ for i in range(engine.num_bindings):
Review Comment:
Noted
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
+# SPDX-License-Identifier: Apache-2.0
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import numpy as np
+import pycuda.driver as cuda
+import sys
+import tensorrt as trt
+from typing import Any, Dict, Iterable, Optional, Sequence
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler, PredictionResult
+
+LOGGER = trt.Logger(trt.Logger.INFO)
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ print("Failed to load ONNX file: {}".format(onnx_path))
+ for error in range(parser.num_errors):
+ print(parser.get_error(error))
+ sys.exit(1)
+ builder.reset()
+ return network
+
+
+def _build_engine(network):
+ builder = trt.Builder(LOGGER)
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ trt.ICudaEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage:
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> trt.ICudaEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ return _load_engine(self.engine_path)
+
+ def load_onnx(self) -> trt.INetworkDefinition:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ #
+ def build_engine(self, network: trt.INetworkDefinition) -> trt.ICudaEngine:
+ """Build an engine according to parsed/created network."""
+ return _build_engine(network)
+
+ def run_inference(
+ self,
+ batch: np.ndarray,
+ engine: trt.ICudaEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ _validate_inference_args(inference_args)
+ context = engine.create_execution_context()
+ assert context
+ # Setup I/O bindings
+ inputs = []
+ outputs = []
+ allocations = []
+ for i in range(engine.num_bindings):
+ is_input = False
+ if engine.binding_is_input(i):
+ is_input = True
+ name = engine.get_binding_name(i)
+ dtype = engine.get_binding_dtype(i)
+ shape = engine.get_binding_shape(i)
+ if is_input:
+ batch_size = shape[0]
+ size = np.dtype(trt.nptype(dtype)).itemsize
+ for s in shape:
+ size *= s
+ allocation = cuda.mem_alloc(size)
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ }
+ allocations.append(allocation)
+ if engine.binding_is_input(i):
+ inputs.append(binding)
+ else:
+ outputs.append(binding)
+
+ assert batch_size > 0
+ assert len(inputs) > 0
+ assert len(outputs) > 0
+ assert len(allocations) > 0
+ # Prepare the output data
+ predictions = []
+ for output in outputs:
+ predictions.append(np.zeros(output['shape'], output['dtype']))
Review Comment:
Noted
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r923804497
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,213 @@
+#
+# SPDX-FileCopyrightText: Copyright (c) 2022 NVIDIA CORPORATION & AFFILIATES. All rights reserved. # pylint: disable=line-too-long
Review Comment:
@kennknowles ok, legal said I can use suggested header. I'll make a commit rn with this change.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r951559085
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,280 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+ import tensorrt as trt
+ TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+ LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+ TRT_LOGGER = None
+ msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+ 'runner has tensorrt dependencies installed.'
+ LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+ import tensorrt as trt
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ import tensorrt as trt
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ LOGGER.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ import tensorrt as trt
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _assign_or_fail(args):
+ """CUDA error checking."""
+ from cuda import cuda
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ from cuda import cuda
+ import tensorrt as trt
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
Review Comment:
No, as of now docstring has to be updated manually. https://github.com/apache/beam/issues/22265
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r947187307
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+ import tensorrt as trt
+ TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+ LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+ TRT_LOGGER = None
+ msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+ 'runner has tensorrt dependencies installed.'
+ LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+ import tensorrt as trt
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ import tensorrt as trt
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ LOGGER.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ import tensorrt as trt
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+ """CUDA error checking."""
+ from cuda import cuda
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ from cuda import cuda
+ import tensorrt as trt
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
+ self,
+ batch: Sequence[np.ndarray],
+ engine: TensorRTEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ from cuda import cuda
+ _validate_inference_args(inference_args)
+ (
+ engine,
+ context,
+ inputs,
+ outputs,
+ gpu_allocations,
+ cpu_allocations,
+ stream) = engine.get_engine_attrs()
+ # Process I/O and execute the network
+ _assign_or_fail(
+ cuda.cuMemcpyHtoDAsync(
+ inputs[0]['allocation'],
+ np.ascontiguousarray(batch),
+ inputs[0]['size'],
+ stream))
+ context.execute_async_v2(gpu_allocations, stream)
Review Comment:
Would using `execute_v2()` not achienve the same effect as using the async version + doing a sync later?
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r947191247
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,294 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+ import tensorrt as trt
+ TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+ LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+ TRT_LOGGER = None
+ msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+ 'runner has tensorrt dependencies installed.'
+ LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+ import tensorrt as trt
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ import tensorrt as trt
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ LOGGER.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ import tensorrt as trt
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def _assign_or_fail(args):
+ """CUDA error checking."""
+ from cuda import cuda
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ from cuda import cuda
+ import tensorrt as trt
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
+ self,
+ batch: Sequence[np.ndarray],
+ engine: TensorRTEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ from cuda import cuda
+ _validate_inference_args(inference_args)
+ (
+ engine,
+ context,
+ inputs,
+ outputs,
+ gpu_allocations,
+ cpu_allocations,
+ stream) = engine.get_engine_attrs()
+ # Process I/O and execute the network
+ _assign_or_fail(
+ cuda.cuMemcpyHtoDAsync(
+ inputs[0]['allocation'],
+ np.ascontiguousarray(batch),
+ inputs[0]['size'],
+ stream))
+ context.execute_async_v2(gpu_allocations, stream)
Review Comment:
Nearly, except that it wouldn't allow us to overlap the memcpys with inference. It probably makes no difference for single input/output scenarios, but it could help if you plan to eventually extend the interface to multiple inputs/outputs.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] damccorm commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
damccorm commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r972416730
##########
sdks/python/test-suites/dataflow/common.gradle:
##########
@@ -364,3 +364,38 @@ task validatesContainer() {
}
}
}
+
+def tensorRTTests = tasks.create("tensorRTtests") {
+ dependsOn 'installGcpTest'
+ dependsOn ':sdks:python:sdist'
+ doLast {
+ def testOpts = basicPytestOpts
+ def argMap = [
+ "runner": "DataflowRunner",
+ "machine_type":"n1-standard-4",
+ "sdk_container_image": "us.gcr.io/apache-beam-testing/python-postcommit-it/tensor_rt:latest",
Review Comment:
Do we do this for any other tests yet/do we have a pattern we can follow? If not, I'd probably vote we put it in a `test-suites/dataflow/containers` directory and add a small README in that folder that describes that it holds images used to run Dataflow tests. That way we have a reusable pattern for similar tests in the future.
Also btw, I tested the current implementation and it all worked so we should be good to merge this once the Dockerfile is in.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r965926496
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
Review Comment:
Looks like an unused import (according to pylint)
```suggestion
```
##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,258 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with
+TensorRT.
+"""
+
+import argparse
+import io
+import os
+from typing import Iterable
+from typing import Optional
+from typing import Tuple
+
+import numpy as np
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import KeyedModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.ml.inference.base import RunInference
+from apache_beam.ml.inference.tensorrt_inference import TensorRTEngineHandlerNumPy # pylint: disable=line-too-long
+from apache_beam.options.pipeline_options import PipelineOptions
+from apache_beam.options.pipeline_options import SetupOptions
+from PIL import Image
+
+COCO_OBJ_DET_CLASSES = [
+ 'person',
+ 'bicycle',
+ 'car',
+ 'motorcycle',
+ 'airplane',
+ 'bus',
+ 'train',
+ 'truck',
+ 'boat',
+ 'traffic light',
+ 'fire hydrant',
+ 'street sign',
+ 'stop sign',
+ 'parking meter',
+ 'bench',
+ 'bird',
+ 'cat',
+ 'dog',
+ 'horse',
+ 'sheep',
+ 'cow',
+ 'elephant',
+ 'bear',
+ 'zebra',
+ 'giraffe',
+ 'hat',
+ 'backpack',
+ 'umbrella',
+ 'shoe',
+ 'eye glasses',
+ 'handbag',
+ 'tie',
+ 'suitcase',
+ 'frisbee',
+ 'skis',
+ 'snowboard',
+ 'sports ball',
+ 'kite',
+ 'baseball bat',
+ 'baseball glove',
+ 'skateboard',
+ 'surfboard',
+ 'tennis racket',
+ 'bottle',
+ 'plate',
+ 'wine glass',
+ 'cup',
+ 'fork',
+ 'knife',
+ 'spoon',
+ 'bowl',
+ 'banana',
+ 'apple',
+ 'sandwich',
+ 'orange',
+ 'broccoli',
+ 'carrot',
+ 'hot dog',
+ 'pizza',
+ 'donut',
+ 'cake',
+ 'chair',
+ 'couch',
+ 'potted plant',
+ 'bed',
+ 'mirror',
+ 'dining table',
+ 'window',
+ 'desk',
+ 'toilet',
+ 'door',
+ 'tv',
+ 'laptop',
+ 'mouse',
+ 'remote',
+ 'keyboard',
+ 'cell phone',
+ 'microwave',
+ 'oven',
+ 'toaster',
+ 'sink',
+ 'refrigerator',
+ 'blender',
+ 'book',
+ 'clock',
+ 'vase',
+ 'scissors',
+ 'teddy bear',
+ 'hair drier',
+ 'toothbrush',
+ 'hair brush',
+]
+
+
+def attach_im_size_to_key(
+ data: Tuple[str, Image.Image]) -> Tuple[Tuple[str, int, int], Image.Image]:
+ filename, image = data
+ width, height = image.size
+ return ((filename, width, height), image)
+
+
+def read_image(image_file_name: str,
+ path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+ if path_to_dir is not None:
+ image_file_name = os.path.join(path_to_dir, image_file_name)
+ with FileSystems().open(image_file_name, 'r') as file:
+ data = Image.open(io.BytesIO(file.read())).convert('RGB')
+ return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+ ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+ image = image.resize(
+ ssd_mobilenet_v2_320x320_input_dims, resample=Image.Resampling.BILINEAR)
+ image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+ return image
+
+
+class PostProcessor(beam.DoFn):
+ """Processes the PredictionResult that consists of
+ number of detections per image, box coordinates, scores and classes.
+
+ We loop over all detections to organize attributes on a per
+ detection basis. Box coordinates are normalized, hence we have to scale them
+ according to original image dimensions. Score is a floating point number
+ that provides probability percentage of a particular object. Class is
+ an integer that we can transform into actual string class using
+ COCO_OBJ_DET_CLASSES as reference.
+ """
+ def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+ key, prediction_result = element
+ filename, im_width, im_height = key
+ num_detections = prediction_result.inference[0]
+ boxes = prediction_result.inference[1]
+ scores = prediction_result.inference[2]
+ classes = prediction_result.inference[3]
+ detections = []
+ for i in range(int(num_detections[0])):
+ detections.append({
+ 'ymin': str(boxes[i][0] * im_height),
+ 'xmin': str(boxes[i][1] * im_width),
+ 'ymax': str(boxes[i][2] * im_height),
+ 'xmax': str(boxes[i][3] * im_width),
+ 'score': str(scores[i]),
+ 'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+ })
+ yield filename + ',' + str(detections)
+
+
+def parse_known_args(argv):
+ """Parses args for the workflow."""
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ '--input',
+ dest='input',
+ required=True,
+ help='Path to the text file containing image names.')
+ parser.add_argument(
+ '--output',
+ dest='output',
+ required=True,
+ help='Path where to save output predictions.'
+ ' text file.')
+ parser.add_argument(
+ '--engine_path',
+ dest='engine_path',
+ required=True,
+ help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+ 'TensorRT engine.')
+ parser.add_argument(
+ '--images_dir',
+ default=None,
+ help='Path to the directory where images are stored.'
+ 'Not required if image names in the input file have absolute path.')
+ return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+ """
+ Args:
+ argv: Command line arguments defined for this example.
+ """
+ known_args, pipeline_args = parse_known_args(argv)
+ pipeline_options = PipelineOptions(pipeline_args)
+ pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+ engine_handler = KeyedModelHandler(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path=known_args.engine_path))
+
+ with beam.Pipeline(options=pipeline_options) as p:
+ filename_value_pair = (
+ p
+ | 'ReadImageNames' >> beam.io.ReadFromText(
+ known_args.input)
Review Comment:
```suggestion
| 'ReadImageNames' >> beam.io.ReadFromText(known_args.input)
```
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r965930470
##########
sdks/python/apache_beam/examples/inference/tensorrt_object_detection.py:
##########
@@ -0,0 +1,258 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+"""A pipeline that uses RunInference API to perform object detection with
+TensorRT.
+"""
+
+import argparse
+import io
+import os
+from typing import Iterable
+from typing import Optional
+from typing import Tuple
+
+import numpy as np
+
+import apache_beam as beam
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import KeyedModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.ml.inference.base import RunInference
+from apache_beam.ml.inference.tensorrt_inference import TensorRTEngineHandlerNumPy # pylint: disable=line-too-long
+from apache_beam.options.pipeline_options import PipelineOptions
+from apache_beam.options.pipeline_options import SetupOptions
+from PIL import Image
+
+COCO_OBJ_DET_CLASSES = [
+ 'person',
+ 'bicycle',
+ 'car',
+ 'motorcycle',
+ 'airplane',
+ 'bus',
+ 'train',
+ 'truck',
+ 'boat',
+ 'traffic light',
+ 'fire hydrant',
+ 'street sign',
+ 'stop sign',
+ 'parking meter',
+ 'bench',
+ 'bird',
+ 'cat',
+ 'dog',
+ 'horse',
+ 'sheep',
+ 'cow',
+ 'elephant',
+ 'bear',
+ 'zebra',
+ 'giraffe',
+ 'hat',
+ 'backpack',
+ 'umbrella',
+ 'shoe',
+ 'eye glasses',
+ 'handbag',
+ 'tie',
+ 'suitcase',
+ 'frisbee',
+ 'skis',
+ 'snowboard',
+ 'sports ball',
+ 'kite',
+ 'baseball bat',
+ 'baseball glove',
+ 'skateboard',
+ 'surfboard',
+ 'tennis racket',
+ 'bottle',
+ 'plate',
+ 'wine glass',
+ 'cup',
+ 'fork',
+ 'knife',
+ 'spoon',
+ 'bowl',
+ 'banana',
+ 'apple',
+ 'sandwich',
+ 'orange',
+ 'broccoli',
+ 'carrot',
+ 'hot dog',
+ 'pizza',
+ 'donut',
+ 'cake',
+ 'chair',
+ 'couch',
+ 'potted plant',
+ 'bed',
+ 'mirror',
+ 'dining table',
+ 'window',
+ 'desk',
+ 'toilet',
+ 'door',
+ 'tv',
+ 'laptop',
+ 'mouse',
+ 'remote',
+ 'keyboard',
+ 'cell phone',
+ 'microwave',
+ 'oven',
+ 'toaster',
+ 'sink',
+ 'refrigerator',
+ 'blender',
+ 'book',
+ 'clock',
+ 'vase',
+ 'scissors',
+ 'teddy bear',
+ 'hair drier',
+ 'toothbrush',
+ 'hair brush',
+]
+
+
+def attach_im_size_to_key(
+ data: Tuple[str, Image.Image]) -> Tuple[Tuple[str, int, int], Image.Image]:
+ filename, image = data
+ width, height = image.size
+ return ((filename, width, height), image)
+
+
+def read_image(image_file_name: str,
+ path_to_dir: Optional[str] = None) -> Tuple[str, Image.Image]:
+ if path_to_dir is not None:
+ image_file_name = os.path.join(path_to_dir, image_file_name)
+ with FileSystems().open(image_file_name, 'r') as file:
+ data = Image.open(io.BytesIO(file.read())).convert('RGB')
+ return image_file_name, data
+
+
+def preprocess_image(image: Image.Image) -> np.ndarray:
+ ssd_mobilenet_v2_320x320_input_dims = (300, 300)
+ image = image.resize(
+ ssd_mobilenet_v2_320x320_input_dims, resample=Image.Resampling.BILINEAR)
+ image = np.expand_dims(np.asarray(image, dtype=np.float32), axis=0)
+ return image
+
+
+class PostProcessor(beam.DoFn):
+ """Processes the PredictionResult that consists of
+ number of detections per image, box coordinates, scores and classes.
+
+ We loop over all detections to organize attributes on a per
+ detection basis. Box coordinates are normalized, hence we have to scale them
+ according to original image dimensions. Score is a floating point number
+ that provides probability percentage of a particular object. Class is
+ an integer that we can transform into actual string class using
+ COCO_OBJ_DET_CLASSES as reference.
+ """
+ def process(self, element: Tuple[str, PredictionResult]) -> Iterable[str]:
+ key, prediction_result = element
+ filename, im_width, im_height = key
+ num_detections = prediction_result.inference[0]
+ boxes = prediction_result.inference[1]
+ scores = prediction_result.inference[2]
+ classes = prediction_result.inference[3]
+ detections = []
+ for i in range(int(num_detections[0])):
+ detections.append({
+ 'ymin': str(boxes[i][0] * im_height),
+ 'xmin': str(boxes[i][1] * im_width),
+ 'ymax': str(boxes[i][2] * im_height),
+ 'xmax': str(boxes[i][3] * im_width),
+ 'score': str(scores[i]),
+ 'class': COCO_OBJ_DET_CLASSES[int(classes[i])]
+ })
+ yield filename + ',' + str(detections)
+
+
+def parse_known_args(argv):
+ """Parses args for the workflow."""
+ parser = argparse.ArgumentParser()
+ parser.add_argument(
+ '--input',
+ dest='input',
+ required=True,
+ help='Path to the text file containing image names.')
+ parser.add_argument(
+ '--output',
+ dest='output',
+ required=True,
+ help='Path where to save output predictions.'
+ ' text file.')
+ parser.add_argument(
+ '--engine_path',
+ dest='engine_path',
+ required=True,
+ help='Path to the pre-built TFOD ssd_mobilenet_v2_320x320_coco17_tpu-8'
+ 'TensorRT engine.')
+ parser.add_argument(
+ '--images_dir',
+ default=None,
+ help='Path to the directory where images are stored.'
+ 'Not required if image names in the input file have absolute path.')
+ return parser.parse_known_args(argv)
+
+
+def run(argv=None, save_main_session=True):
+ """
+ Args:
+ argv: Command line arguments defined for this example.
+ """
+ known_args, pipeline_args = parse_known_args(argv)
+ pipeline_options = PipelineOptions(pipeline_args)
+ pipeline_options.view_as(SetupOptions).save_main_session = save_main_session
+
+ engine_handler = KeyedModelHandler(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path=known_args.engine_path))
+
+ with beam.Pipeline(options=pipeline_options) as p:
+ filename_value_pair = (
+ p
+ | 'ReadImageNames' >> beam.io.ReadFromText(
+ known_args.input)
Review Comment:
Pushed a change
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
Review Comment:
Pushed a change
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] yeandy commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
yeandy commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958819406
##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -160,6 +175,52 @@ This writes the output to the `predictions.csv` with contents like:
```
Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.
+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:
+```sh
+python -m apache_beam.examples.inference.tensorrt_object_detection \
+ --input IMAGE_FILE_NAMES \
+ --images_dir IMAGES_DIR \
+ --output OUTPUT \
+ --engine_path TRT_ENGINE
+```
+For example:
+```sh
+python -m apache_beam.examples.inference.tensorrt_object_detection \
+ --input image_file_names.txt \
+ --output predictions.csv \
+ --model_state_dict_path ssd_mobilenet_v2_320x320_coco17_tpu-8.trt
+```
+This writes the output to the `predictions.csv` with contents like:
+```
+/absolute/path/to/000000000139.jpg;[{'ymin': '217.31875205039978' 'xmin': '295.93122482299805' 'ymax': '315.90323209762573' 'xmax': '357.8959655761719' 'score': '0.72342616' 'class': 'chair'} {'ymin': '166.81788557767868'.....
+
+/absolute/path/to/000000289594.jpg;[{'ymin': '227.25109100341797' 'xmin': '331.7402381300926' 'ymax': '476.88533782958984' 'xmax': '402.2928895354271' 'score': '0.77217317' 'class': 'person'} {'ymin': '231.8712615966797' 'xmin': '292.8590789437294'.....
+...
+```
+Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of dictionaries, each dictionary corresponds with a single detection. As a result providing: box coordinates (ymin, xmin, ymax, xmax); score and class on a per detection basis.
Review Comment:
```suggestion
Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of dictionaries, where each dictionary corresponds with a single detection. A detection contains: box coordinates (ymin, xmin, ymax, xmax); score; and class.
```
##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -160,6 +175,52 @@ This writes the output to the `predictions.csv` with contents like:
```
Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.
+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
Review Comment:
The style of instructions on how to run the examples has been modified since you first made this PR. So under the `Dataset and model for image classification` section, I've made some changes. This includes some rewording and fixing some typos. PTAL, and if ok, let's replace the old wording.
Changes starts below:
### Dataset and model for image classification
To use this transform, you need a dataset and model for image classification.
1. Create a directory named `IMAGES_DIR`. Create or download images and put them in this directory. The directory is not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths. One popular dataset is from [COCO](https://cocodataset.org/#home). The COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip). Follow their instructions to download the images.
2. Create a file named `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` that you want to use to run image classification. The path to the file can be different types of URIs such as your local file system, an AWS S3 bucket, or a GCP Cloud Storage bucket. For example:
```
/absolute/path/to/000000000139.jpg
/absolute/path/to/000000289594.jpg
```
3. Follow the [instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert a SSD MobileNet v2 320x320 model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step, you can use resulting engine as `TRT_ENGINE` input (see step 4).
- Note: Make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/tensorrt/developer-guide/index.html#compatibility-serialized-engines).
4. Create a path to a file named `TRT_ENGINE` that contains the pre-built TensorRT engine from the SSD MobileNet v2 320x320 model.
5. Note the path to the `OUTPUT` file. This file is used by the pipeline to write the predictions.
##########
sdks/python/apache_beam/examples/inference/README.md:
##########
@@ -160,6 +175,52 @@ This writes the output to the `predictions.csv` with contents like:
```
Each line has data separated by a semicolon ";". The first item is the file name. The second item is a list of predicted instances.
+---
+## Object Detection
+
+[`tensorrt_object_detection.py`](./tensorrt_object_detection.py) contains an implementation for a RunInference pipeline that performs object detection using [Tensorflow Object Detection's](https://github.com/tensorflow/models/blob/master/research/object_detection/g3doc/tf2_detection_zoo.md) SSD MobileNet v2 320x320 architecture.
+
+The pipeline reads the images, performs basic preprocessing, passes them to the TensorRT implementation of RunInference, and then writes the predictions to a text file.
+
+### Dataset and model for image classification
+
+You will need to create or download images, and place them into your `IMAGES_DIR` directory. Popular dataset for such task is [COCO dataset](https://cocodataset.org/#home). COCO validation dataset can be obtained [here](http://images.cocodataset.org/zips/val2017.zip).
+- **Required**: A path to a file called `IMAGE_FILE_NAMES` that contains the absolute paths of each of the images in `IMAGES_DIR` on which you want to run image segmentation. Paths can be different types of URIs such as your local file system, a AWS S3 bucket or GCP Cloud Storage bucket. For example:
+```
+/absolute/path/to/000000000139.jpg
+/absolute/path/to/000000289594.jpg
+```
+- **Required**: A path to a file called `TRT_ENGINE` that contains the pre-built TensorRT engine from SSD MobileNet v2 320x320 model. You will need to [follow instructions](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api) on how to download and convert this SSD model into TensorRT engine. At [Create ONNX Graph](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#create-onnx-graph) step, keep batch size at 1. As soon as you are done with [Build TensorRT Engine](https://github.com/NVIDIA/TensorRT/tree/main/samples/python/tensorflow_object_detection_api#build-tensorrt-engine) step. You can use resulted engine as `TRT_ENGINE` input. In addition, make sure that environment you use for TensorRT engine creation is the same environment you use to run TensorRT inference. It is related not only to TensorRT version, but also to a specific GPU used. Read more about it [here](https://docs.nvidia.com/deeplearning/
tensorrt/developer-guide/index.html#compatibility-serialized-engines).
+
+- **Required**: A path to a file called `OUTPUT`, to which the pipeline will write the predictions.
+- **Optional**: `IMAGES_DIR`, which is the path to the directory where images are stored. Not required if image names in the input file `IMAGE_FILE_NAMES` have absolute paths.
+
+### Running `tensorrt_object_detection.py`
+
+To run the image classification pipeline locally, use the following command:
+```sh
+python -m apache_beam.examples.inference.tensorrt_object_detection \
+ --input IMAGE_FILE_NAMES \
+ --images_dir IMAGES_DIR \
+ --output OUTPUT \
+ --engine_path TRT_ENGINE
+```
+For example:
+```sh
+python -m apache_beam.examples.inference.tensorrt_object_detection \
+ --input image_file_names.txt \
+ --output predictions.csv \
+ --model_state_dict_path ssd_mobilenet_v2_320x320_coco17_tpu-8.trt
Review Comment:
```suggestion
--engine_path ssd_mobilenet_v2_320x320_coco17_tpu-8.trt
```
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r958938153
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,285 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+from __future__ import annotations
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from apache_beam.utils.annotations import experimental
+
+LOGGER = logging.getLogger("TensorRTEngineHandlerNumPy")
+# This try/catch block allows users to submit jobs from a machine without
+# GPU and other dependencies (tensorrt, cuda, etc.) at job submission time.
+try:
+ import tensorrt as trt
+ TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+ LOGGER.info('tensorrt module successfully imported.')
+except ModuleNotFoundError:
+ TRT_LOGGER = None
+ msg = 'tensorrt module was not found. This is ok as long as the specified ' \
+ 'runner has tensorrt dependencies installed.'
+ LOGGER.warning(msg)
+
+
+def _load_engine(engine_path):
+ import tensorrt as trt
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ import tensorrt as trt
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ LOGGER.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ LOGGER.error(parser.get_error(error))
+ raise ValueError(f"Failed to load ONNX file: {onnx_path}")
+ return network, builder
+
+
+def _build_engine(network, builder):
+ import tensorrt as trt
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _assign_or_fail(args):
+ """CUDA error checking."""
+ from cuda import cuda
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ from cuda import cuda
+ import tensorrt as trt
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = _assign_or_fail(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = _assign_or_fail(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+@experimental(extra_message="No backwards-compatibility guarantees.")
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ **NOTE:** This API and its implementation are under development and
+ do not provide backward compatibility guarantees.
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
+ self,
+ batch: Sequence[np.ndarray],
+ engine: TensorRTEngine,
+ inference_args: Optional[Dict[str, Any]] = None
+ ) -> Iterable[PredictionResult]:
+ """
+ Runs inferences on a batch of Tensors and returns an Iterable of
+ TensorRT Predictions.
+
+ Args:
+ batch: A np.ndarray or a np.ndarray that represents a concatenation
+ of multiple arrays as a batch.
+ engine: A TensorRT engine.
+ inference_args: Any additional arguments for an inference
+ that are not applicable to TensorRT.
+
+ Returns:
+ An Iterable of type PredictionResult.
+ """
+ from cuda import cuda
+ (
+ engine,
+ context,
+ inputs,
+ outputs,
+ gpu_allocations,
+ cpu_allocations,
+ stream) = engine.get_engine_attrs()
+ # Process I/O and execute the network
Review Comment:
```
# Process I/O and execute the network
with context_lock:
<move the code that is using shared context and needs to be guarded by a lock here.>
return [
# PredictionResults
]
```
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] pranavm-nvidia commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
pranavm-nvidia commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930038135
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
@azhurkevich I'm not sure how multi-threading is set up in Beam, but the basic idea would be:
```py
import threading
def run_inference(context, inputs, outputs, stream):
... # Copy HtoD
context.execute_async_v2(...)
... # Copy DtoH
stream.synchronize()
engine = ...
# Engine can be shared across threads, but need 1 context per thread
context0 = engine.create_execution_context()
context1 = engine.create_execution_context()
... # Allocate I/O buffers for each thread
t0 = threading.Thread(target=run_inference, args=(context0, inputs0, outputs0, stream0))
t1 = threading.Thread(target=run_inference, args=(context1, inputs1, outputs1, stream1))
t0.start()
t1.start()
t0.join()
t1.join()
```
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930336009
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
Review Comment:
sure, I think `raise ValueError(f"Failed to load ONNX file: {onnx_path}")` would work.
The reason is there may be additional logic for handling exceptions and communicating the exceptions between sdk and the runners, which would result in a more clear message such as:
we tried to run this workitem 4 times and it failed with message X. versus, a container with an SDK process keeps crashing and restarting, and a user would need to dig further to find logs preceding the restart.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r930417691
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
So, I think the return result of the load_model (i.e. the engine) will be shared between threads: https://github.com/apache/beam/pull/22131/files#diff-145530e8e39084aed7792a4d3b8104258ea1635db466ab48a58f168bce10dde3R204
OTOH, it looks like we only create the execution context once, when we initialize the engine: https://github.com/apache/beam/pull/22131/files#diff-145530e8e39084aed7792a4d3b8104258ea1635db466ab48a58f168bce10dde3R114
in this case, the context and the engine will both be shared across threads.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r931644387
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
I was thinking something along the lines of having a dictionary[Thread ID -> execution_context], and create the context if it has not been created by this thread yet, otherwise fetch it from the dictionary.
Is it expensive in any sense to create execution contexts? As in, would it make sense to try to recycle the context between multiple non-concurrent threads (i.e. reuse the context after a thread that created it has finished)?
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] tvalentyn commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
tvalentyn commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929432419
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
Review Comment:
We should raise a ValueError instead of exiting the process.
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
Review Comment:
Consider _assign_or_fail() as the check doesn't seem to be about drivers.
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
+ """CUDA error checking."""
+ err, ret = args[0], args[1:]
+ if isinstance(err, cuda.CUresult):
+ if err != cuda.CUresult.CUDA_SUCCESS:
+ raise RuntimeError("Cuda Error: {}".format(err))
+ else:
+ raise RuntimeError("Unknown error type: {}".format(err))
+ # Special case so that no unpacking is needed at call-site.
+ if len(ret) == 1:
+ return ret[0]
+ return ret
+
+
+class TensorRTEngine:
+ def __init__(self, engine: trt.ICudaEngine):
+ """Implementation of the TensorRTEngine class which handles
+ allocations associated with TensorRT engine.
+
+ Example Usage::
+
+ TensorRTEngine(engine)
+
+ Args:
+ engine: trt.ICudaEngine object that contains TensorRT engine
+ """
+ self.engine = engine
+ self.context = engine.create_execution_context()
+ self.inputs = []
+ self.outputs = []
+ self.gpu_allocations = []
+ self.cpu_allocations = []
+ """Setup I/O bindings."""
+ for i in range(self.engine.num_bindings):
+ name = self.engine.get_binding_name(i)
+ dtype = self.engine.get_binding_dtype(i)
+ shape = self.engine.get_binding_shape(i)
+ size = trt.volume(shape) * dtype.itemsize
+ allocation = ASSERT_DRV(cuda.cuMemAlloc(size))
+ binding = {
+ 'index': i,
+ 'name': name,
+ 'dtype': np.dtype(trt.nptype(dtype)),
+ 'shape': list(shape),
+ 'allocation': allocation,
+ 'size': size
+ }
+ self.gpu_allocations.append(allocation)
+ if self.engine.binding_is_input(i):
+ self.inputs.append(binding)
+ else:
+ self.outputs.append(binding)
+
+ assert self.context
+ assert len(self.inputs) > 0
+ assert len(self.outputs) > 0
+ assert len(self.gpu_allocations) > 0
+
+ for output in self.outputs:
+ self.cpu_allocations.append(np.zeros(output['shape'], output['dtype']))
+ # Create CUDA Stream.
+ self.stream = ASSERT_DRV(cuda.cuStreamCreate(0))
+
+ def get_engine_attrs(self):
+ """Returns TensorRT engine attributes."""
+ return (
+ self.engine,
+ self.context,
+ self.inputs,
+ self.outputs,
+ self.gpu_allocations,
+ self.cpu_allocations,
+ self.stream)
+
+
+class TensorRTEngineHandlerNumPy(ModelHandler[np.ndarray,
+ PredictionResult,
+ TensorRTEngine]):
+ def __init__(self, min_batch_size: int, max_batch_size: int, **kwargs):
+ """Implementation of the ModelHandler interface for TensorRT.
+
+ Example Usage::
+
+ pcoll | RunInference(
+ TensorRTEngineHandlerNumPy(
+ min_batch_size=1,
+ max_batch_size=1,
+ engine_path="my_uri"))
+
+ Args:
+ min_batch_size: minimum accepted batch size.
+ max_batch_size: maximum accepted batch size.
+ kwargs: Additional arguments like 'engine_path' and 'onnx_path' are
+ currently supported.
+
+ See https://docs.nvidia.com/deeplearning/tensorrt/api/python_api/
+ for details
+ """
+ self.min_batch_size = min_batch_size
+ self.max_batch_size = max_batch_size
+ if 'engine_path' in kwargs:
+ self.engine_path = kwargs.get('engine_path')
+ elif 'onnx_path' in kwargs:
+ self.onnx_path = kwargs.get('onnx_path')
+
+ trt.init_libnvinfer_plugins(TRT_LOGGER, namespace="")
+
+ def batch_elements_kwargs(self):
+ """Sets min_batch_size and max_batch_size of a TensorRT engine."""
+ return {
+ 'min_batch_size': self.min_batch_size,
+ 'max_batch_size': self.max_batch_size
+ }
+
+ def load_model(self) -> TensorRTEngine:
+ """Loads and initializes a TensorRT engine for processing."""
+ engine = _load_engine(self.engine_path)
+ return TensorRTEngine(engine)
+
+ def load_onnx(self) -> Tuple[trt.INetworkDefinition, trt.Builder]:
+ """Loads and parses an onnx model for processing."""
+ return _load_onnx(self.onnx_path)
+
+ def build_engine(
+ self, network: trt.INetworkDefinition,
+ builder: trt.Builder) -> TensorRTEngine:
+ """Build an engine according to parsed/created network."""
+ engine = _build_engine(network, builder)
+ return TensorRTEngine(engine)
+
+ def run_inference(
Review Comment:
Is this implementation thread-safe?
Beam could potentially have multiple concurrent threads within a process. Are there any concerns with that from hardware or software standpoint?
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929442222
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
Review Comment:
TensorRT needs its own logger type. Regular logger was requested [here](https://github.com/apache/beam/pull/22131#discussion_r919051725).
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] azhurkevich commented on a diff in pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
azhurkevich commented on code in PR #22131:
URL: https://github.com/apache/beam/pull/22131#discussion_r929448863
##########
sdks/python/apache_beam/ml/inference/tensorrt_inference.py:
##########
@@ -0,0 +1,281 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements. See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+
+# pytype: skip-file
+
+import logging
+import sys
+from typing import Any
+from typing import Dict
+from typing import Iterable
+from typing import Optional
+from typing import Sequence
+from typing import Tuple
+
+import numpy as np
+
+import tensorrt as trt
+from apache_beam.io.filesystems import FileSystems
+from apache_beam.ml.inference.base import ModelHandler
+from apache_beam.ml.inference.base import PredictionResult
+from cuda import cuda
+
+TRT_LOGGER = trt.Logger(trt.Logger.INFO)
+
+logging.basicConfig(level=logging.INFO)
+logging.getLogger("TensorRTEngineHandlerNumPy").setLevel(logging.INFO)
+log = logging.getLogger("TensorRTEngineHandlerNumPy")
+
+
+def _load_engine(engine_path):
+ file = FileSystems.open(engine_path, 'rb')
+ runtime = trt.Runtime(TRT_LOGGER)
+ engine = runtime.deserialize_cuda_engine(file.read())
+ assert engine
+ return engine
+
+
+def _load_onnx(onnx_path):
+ builder = trt.Builder(TRT_LOGGER)
+ network = builder.create_network(
+ flags=1 << int(trt.NetworkDefinitionCreationFlag.EXPLICIT_BATCH))
+ parser = trt.OnnxParser(network, TRT_LOGGER)
+ with FileSystems.open(onnx_path) as f:
+ if not parser.parse(f.read()):
+ log.error("Failed to load ONNX file: %s", onnx_path)
+ for error in range(parser.num_errors):
+ log.error(parser.get_error(error))
+ sys.exit(1)
+ return network, builder
+
+
+def _build_engine(network, builder):
+ config = builder.create_builder_config()
+ runtime = trt.Runtime(TRT_LOGGER)
+ plan = builder.build_serialized_network(network, config)
+ engine = runtime.deserialize_cuda_engine(plan)
+ builder.reset()
+ return engine
+
+
+def _validate_inference_args(inference_args):
+ """Confirms that inference_args is None.
+
+ TensorRT engines do not need extra arguments in their execute_v2() call.
+ However, since inference_args is an argument in the RunInference interface,
+ we want to make sure it is not passed here in TensorRT's implementation of
+ RunInference.
+ """
+ if inference_args:
+ raise ValueError(
+ 'inference_args were provided, but should be None because TensorRT '
+ 'engines do not need extra arguments in their execute_v2() call.')
+
+
+def ASSERT_DRV(args):
Review Comment:
Noted, will adjust in next commit
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [beam] github-actions[bot] commented on pull request #22131: TensorRT Initial commit
Posted by GitBox <gi...@apache.org>.
github-actions[bot] commented on PR #22131:
URL: https://github.com/apache/beam/pull/22131#issuecomment-1172747672
Assigning reviewers. If you would like to opt out of this review, comment `assign to next reviewer`:
R: @ryanthompson591 for label python.
Available commands:
- `stop reviewer notifications` - opt out of the automated review tooling
- `remind me after tests pass` - tag the comment author after tests pass
- `waiting on author` - shift the attention set back to the author (any comment or push by the author will return the attention set to the reviewers)
The PR bot will only process comments in the main thread (not review comments).
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@beam.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org