You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@flink.apache.org by GitBox <gi...@apache.org> on 2020/09/07 05:09:40 UTC
[GitHub] [flink-playgrounds] shuiqiangchen opened a new pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
shuiqiangchen opened a new pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16


   This is a walkthrough for PyFlink, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.

   It contains:
   - A data generator
   - Kafka
   - ElasticSearch
   - Kibana
   - Skeleton code for a PyFlink Table application.

   For more details, please refer to the README.md.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497333562
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`, There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
+
+
+
+
+
+3. Stop the PyFlink job:
+
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.
+
+
+
+## Further Explorations
+
+If you would like to explore this example more deeply, you can edit [payment_msg_processing.py](payment_msg_proccessing.py)
+or create new PyFlink projects that perform more complex processing. You can do this locally under
+the `pyflink-walkthrough` directory, since it is mounted on the `jobmanager` docker container.
+
+Ideas:
+* Add your own Kafka source table;
+* Create new index for the Elasticsearch sink;
+* Count the number of transactions, grouped by a 1 minute tumbling windows and payPlatform.
Review comment:
```suggestion
* Count the number of transactions, grouped by a 1 minute [tumbling window](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/tableApi.html#tumble-tumbling-windows) and `payPlatform`.
```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497331693
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`, There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
Review comment:
```suggestion
2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`. There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497334150


##########
File path: pyflink-walkthrough/docker-compose.yml
##########
@@ -0,0 +1,96 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+version: '2.1'
+services:
+  jobmanager:
+    build: .
+    image: pyflink/pyflink:1.11.0-scala_2.11
+    volumes:
+      - .:/opt/pyflink-walkthrough
+    hostname: "jobmanager"
+    expose:
+      - "6123"
+    ports:
+      - "8081:8081"
+    command: jobmanager
+    environment:
+      - JOB_MANAGER_RPC_ADDRESS=jobmanager
+  taskmanager:
+    image: pyflink/pyflink:1.11.0-scala_2.11
+    volumes:
+    - .:/opt/pyflink-walkthrough
+    expose:
+      - "6121"
+      - "6122"
+    depends_on:
+      - jobmanager
+    command: taskmanager
+    links:
+      - jobmanager:jobmanager
+    environment:
+      - JOB_MANAGER_RPC_ADDRESS=jobmanager
+  zookeeper:
+    image: wurstmeister/zookeeper:3.4.6
+    ports:
+      - "2181:2181"
+  kafka:
+    image: wurstmeister/kafka:2.12-2.2.1
+    ports:
+      - "9092"
+    depends_on:
+      - zookeeper
+    environment:
+      HOSTNAME_COMMAND: "route -n | awk '/UG[ \t]/{print $$2}'"
+      KAFKA_ZOOKEEPER_CONNECT: zookeeper:2181
+      KAFKA_CREATE_TOPICS: "payment_msg:1:1"
+    volumes:
+      - /var/run/docker.sock:/var/run/docker.sock
+  generator:
+    build: generator
+    image: generator:1.0
+    depends_on:
+      - kafka
+  elasticsearch:
+    image: docker.elastic.co/elasticsearch/elasticsearch:7.8.0
+    environment:
+      - cluster.name=docker-cluster
+      - bootstrap.memory_lock=true
+      - "ES_JAVA_OPTS=-Xms512m -Xmx512m"
+      - discovery.type=single-node
+    ports:
+      - "9200:9200"
+      - "9300:9300"
+    ulimits:
+      memlock:
+        soft: -1
+        hard: -1
+      nofile:
+        soft: 65536
+        hard: 65536
+  kibana:
+    image: docker.elastic.co/kibana/kibana:7.8.0
+    ports:
+      - "5601:5601"
+    depends_on:
+      - elasticsearch
+  load-kibaba-dashboard:

Review comment:
       ```suggestion
     load-kibana-dashboard:
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-707200947


   Thank you for this contribution! Merged and closed via a0c07e99dc9c8f621dcdee8f2b8aa534dbf0f94e.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-697071304


   @alpinegizmo Thank you for polishing the doc, I have updated the PR, please have a look.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r498607377
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully. There should be a job in the running job list.
+Click the job to get more details. You should see that the `StreamGraph` of the `payment_msg_proccessing` consists of two nodes, each with a parallelism of 1.
+There is also a table in the bottom of the page that shows the metrics of every node (e.g. bytes received/sent, records received/sent).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`. There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
Review comment:
Sorry, the localhost:5061 would lead you to the home page of Kibana, then you need to open the menu list by click the menu button in the upper left corner, then choose the `Dashboard` item to the dashboard page. I will make it more clear.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r492952901
##########
File path: pyflink-walkthrough/README.md
##########
@@ -102,6 +106,24 @@ $ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/pa
3. Stop the PyFlink job:
-Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancle` on the upper right side.
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.

+
+## Extension
+
+You are able to edit the [payment_msg_processing.py](payment_msg_proccessing.py) or create new PyFlink
+projects to perform more complex processing logic locally on your operating system under the `pyflink-walkthrough`
+directory since it is mounted on the `jobmanager` docker container. Such as:
+* Creating a new Kafka source table;
+* Creating a new index for the Elasticsearch sink;
+* Calculating the amount of transactions grouped by a 1 minute tumble window and payPlatforms.
+
+After the modification, you can submit the new job by executing the same command mentioned at
+[Running the PyFlink Job](#running-the-pyflink-job)
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+Furthermore, you can also [create new kibana dashboards](https://www.elastic.co/guide/en/kibana/7.8/dashboard-create-new-dashboard.html)
+to visualize more charts of various dimension based on the persistent indexes in Elasticsearch.
Review comment:
```suggestion
## Further Explorations
If you would like to explore this example more deeply, you can edit [payment_msg_processing.py](payment_msg_proccessing.py) or create new PyFlink
projects that perform more complex processing. You can do this locally under the `pyflink-walkthrough`
directory, since it is mounted on the `jobmanager` docker container.
Ideas:
* Add your own Kafka source table;
* Create a new index for the Elasticsearch sink;
* Count the number of transactions, grouped by a 1 minute tumbling windows, and by payPlatform.
After making a modification, you can submit the new job by executing the same command mentioned at
[Running the PyFlink Job](#running-the-pyflink-job)
```bash
$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
```
Furthermore, you can also [create new kibana dashboards](https://www.elastic.co/guide/en/kibana/7.8/dashboard-create-new-dashboard.html)
that visualize other aspects of the data in the Elasticsearch.
```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r486966065


##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?

##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?

##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-707024177


   I tried this change, and then the kibana dashboard worked. It seems that this script is rather fragile.

   @@ -22,7 +22,7 @@ until curl -s http://kibana:5601/login -o /dev/null; do
    done

    # The import service may not be ready, sleep 10s more.
   -sleep 10
   +sleep 20
    curl -X POST kibana:5601/api/saved_objects/_import -H "kbn-xsrf: true" --form file=@/tmp/load/export.ndjson


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-693154194


   @alpinegizmo Thank you for pointing out the errors in english and other improvements, I have revised the errors and added an extension section to allow users to do more things beyond the built-in demo. Looking forward to your feedback :)


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497331419
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
Review comment:
Did you compile the docs to see how these look? Just asking because if there are no dimensions specified, the images might end up very out of proportion.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r493545356


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,134 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to

Review comment:
       Here I would like to use `H3` header for each component (Kafka, PyFlink, Elaticsearch, Kibana) introduction to make them more recognizable.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r492952901
##########
File path: pyflink-walkthrough/README.md
##########
@@ -102,6 +106,24 @@ $ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/pa
3. Stop the PyFlink job:
-Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancle` on the upper right side.
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.

+
+## Extension
+
+You are able to edit the [payment_msg_processing.py](payment_msg_proccessing.py) or create new PyFlink
+projects to perform more complex processing logic locally on your operating system under the `pyflink-walkthrough`
+directory since it is mounted on the `jobmanager` docker container. Such as:
+* Creating a new Kafka source table;
+* Creating a new index for the Elasticsearch sink;
+* Calculating the amount of transactions grouped by a 1 minute tumble window and payPlatforms.
+
+After the modification, you can submit the new job by executing the same command mentioned at
+[Running the PyFlink Job](#running-the-pyflink-job)
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+Furthermore, you can also [create new kibana dashboards](https://www.elastic.co/guide/en/kibana/7.8/dashboard-create-new-dashboard.html)
+to visualize more charts of various dimension based on the persistent indexes in Elasticsearch.
Review comment:
```suggestion
## Further Explorations
If you would like to explore this example more deeply, you can edit [payment_msg_processing.py](payment_msg_proccessing.py) or create new PyFlink
projects that perform more complex processing. You can do this locally under the `pyflink-walkthrough`
directory, since it is mounted on the `jobmanager` docker container.
Ideas:
* Add your own Kafka source table;
* Create a new index for the Elasticsearch sink;
* Count the number of transactions, grouped by a 1 minute tumbling windows, and by payPlatform.
After making a modification, you can submit the new job by executing the same command mentioned at
[Running the PyFlink Job](#running-the-pyflink-job)
```bash
$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
```
Furthermore, you can also [create new kibana dashboards](https://www.elastic.co/guide/en/kibana/7.8/dashboard-create-new-dashboard.html)
that visualize other aspects of the data in the Elasticsearch.
```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r485978638


##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()
+    t_env = StreamTableEnvironment.create(stream_execution_environment=env, environment_settings=env_settings)
+    t_env.get_config().get_configuration().set_boolean("python.fn-execution.memory.managed", True)
+
+    source_ddl = """
+            CREATE TABLE payment_msg(
+                createTime VARCHAR,
+                orderId BIGINT,
+                payAmount DOUBLE,
+                payPlatform INT,
+                provinceId INT
+            ) WITH (
+              'connector.type' = 'kafka',
+              'connector.version' = 'universal',
+              'connector.topic' = 'payment_msg',
+              'connector.properties.bootstrap.servers' = 'kafka:9092',
+              'connector.properties.group.id' = 'test_3',
+              'connector.startup-mode' = 'latest-offset',
+              'format.type' = 'json'
+            )
+            """
+
+    es_sink_ddl = """
+            CREATE TABLE es_sink (
+                province VARCHAR PRIMARY KEY,
+                pay_amount DOUBLE
+            ) with (
+                'connector.type' = 'elasticsearch',
+                'connector.version' = '7',
+                'connector.hosts' = 'http://elasticsearch:9200',
+                'connector.index' = 'platform_pay_amount_1',
+                'connector.document-type' = 'payment',
+                'update-mode' = 'upsert',
+                'connector.flush-on-checkpoint' = 'true',
+                'connector.key-delimiter' = '$',
+                'connector.key-null-literal' = 'n/a',
+                'connector.bulk-flush.max-size' = '42mb',
+                'connector.bulk-flush.max-actions' = '32',
+                'connector.bulk-flush.interval' = '1000',
+                'connector.bulk-flush.backoff.delay' = '1000',
+                'format.type' = 'json'
+            )
+    """
+
+    t_env.sql_update(source_ddl)
+    t_env.sql_update(es_sink_ddl)
+    t_env.register_function('province_id_to_name', province_id_to_name)
+
+    t_env.from_path("payment_msg") \
+        .select("province_id_to_name(provinceId) as province, payAmount") \
+        .group_by("province") \
+        .select("province, sum(payAmount) as pay_amount") \
+        .insert_into("es_sink")
+
+    t_env.execute("payment_demo")

Review comment:
       Use 1.11 methods instead of the deprecated ones (tested).


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r488335267


##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       This could be remove to make the code simpler.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r501192510


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```

Review comment:
       I will move this part to the later section between before starting the PyFlink job after docker compose up.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-705944280


   @alpinegizmo Thank you for your comments, I have adjusted some content order to make the README to be more well-organized. And here are the answers for you questions:

   > Do you plan to add a link to this walkthrough from the docs somewhere?

   We would like to lead users to turn to this playground to have an end to end practice for PyFlink after they have the basic knowledge of PyFlink. So we plan to add a link to walkthrough in the end of the [Flink Python API docs](https://ci.apache.org/projects/flink/flink-docs-master/dev/python/).


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r498605245


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```

Review comment:
       Yes, it should be placed in the end of the walkthrough.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r486966065


##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497344203
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
Review comment:
Yes, the width of the images would be within the markdown body and automatically scale with page size changes.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r485975110
##########
File path: pyflink-walkthrough/docker-compose.yml
##########
@@ -0,0 +1,96 @@
+################################################################################
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+version: '2.1'
+services:
+ jobmanager:
+ build: .
+ image: pyflink/pyflink:1.11.0-scala_2.11
+ volumes:
+ - .:/opt/pyflink-walkthrough
+ hostname: "jobmanager"
+ expose:
+ - "6123"
+ ports:
+ - "8081:8081"
+ command: jobmanager
+ environment:
+ - JOB_MANAGER_RPC_ADDRESS=jobmanager
+ taskmanager:
+ image: pyflink/pyflink:1.11.0-scala_2.11
+ volumes:
+ - .:/opt/pyflink-walkthrough
+ expose:
+ - "6121"
+ - "6122"
+ depends_on:
+ - jobmanager
+ command: taskmanager
+ links:
+ - jobmanager:jobmanager
+ environment:
+ - JOB_MANAGER_RPC_ADDRESS=jobmanager
+ zookeeper:
+ image: wurstmeister/zookeeper:3.4.6
+ ports:
+ - "2181:2181"
+ kafka:
+ image: wurstmeister/kafka:2.12-2.2.1
+ ports:
+ - "9092"
+ depends_on:
+ - zookeeper
+ environment:
+ HOSTNAME_COMMAND: "route -n | awk '/UG[ \t]/{print $$2}'"
+ KAFKA_ZOOKEEPER_CONNECT: zookeeper:2181
+ KAFKA_CREATE_TOPICS: "payment_msg:1:1"
+ volumes:
+ - /var/run/docker.sock:/var/run/docker.sock
+ generator:
+ build: generator
+ image: generator:1.0
+ depends_on:
+ - kafka
+ elasticsearch:
+ image: docker.elastic.co/elasticsearch/elasticsearch:7.8.0
+ environment:
+ - cluster.name=docker-cluster
+ - bootstrap.memory_lock=true
+ - "ES_JAVA_OPTS=-Xms512m -Xmx512m"
+ - discovery.type=single-node
+ ports:
+ - "9200:9200"
+ - "9300:9300"
+ ulimits:
+ memlock:
+ soft: -1
+ hard: -1
+ nofile:
+ soft: 65536
+ hard: 65536
+ kibana:
+ image: docker.elastic.co/kibana/kibana:7.8.0
+ ports:
+ - "5601:5601"
+ depends_on:
+ - elasticsearch
+ load-kibaba-dashboad:
Review comment:
```suggestion
load-kibana-dashboard:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
Review comment:
```suggestion
The transaction data will be processed with PyFlink using the Python script `[payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py)`. This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF, and then sum the transaction amount for each province using a group aggregate.
```
##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+ return provinces[id]
+
+
+def log_processing():
+ env = StreamExecutionEnvironment.get_execution_environment()
+ env_settings = EnvironmentSettings.Builder().use_blink_planner().build()
+ t_env = StreamTableEnvironment.create(stream_execution_environment=env, environment_settings=env_settings)
+ t_env.get_config().get_configuration().set_boolean("python.fn-execution.memory.managed", True)
+
+ source_ddl = """
+ CREATE TABLE payment_msg(
+ createTime VARCHAR,
+ orderId BIGINT,
+ payAmount DOUBLE,
+ payPlatform INT,
+ provinceId INT
+ ) WITH (
+ 'connector.type' = 'kafka',
+ 'connector.version' = 'universal',
+ 'connector.topic' = 'payment_msg',
+ 'connector.properties.bootstrap.servers' = 'kafka:9092',
+ 'connector.properties.group.id' = 'test_3',
+ 'connector.startup-mode' = 'latest-offset',
+ 'format.type' = 'json'
+ )
+ """
+
+ es_sink_ddl = """
+ CREATE TABLE es_sink (
+ province VARCHAR PRIMARY KEY,
+ pay_amount DOUBLE
+ ) with (
+ 'connector.type' = 'elasticsearch',
+ 'connector.version' = '7',
+ 'connector.hosts' = 'http://elasticsearch:9200',
+ 'connector.index' = 'platform_pay_amount_1',
+ 'connector.document-type' = 'payment',
+ 'update-mode' = 'upsert',
+ 'connector.flush-on-checkpoint' = 'true',
+ 'connector.key-delimiter' = '$',
+ 'connector.key-null-literal' = 'n/a',
+ 'connector.bulk-flush.max-size' = '42mb',
+ 'connector.bulk-flush.max-actions' = '32',
+ 'connector.bulk-flush.interval' = '1000',
+ 'connector.bulk-flush.backoff.delay' = '1000',
+ 'format.type' = 'json'
+ )
+ """
+
+ t_env.sql_update(source_ddl)
+ t_env.sql_update(es_sink_ddl)
+ t_env.register_function('province_id_to_name', province_id_to_name)
+
+ t_env.from_path("payment_msg") \
+ .select("province_id_to_name(provinceId) as province, payAmount") \
+ .group_by("province") \
+ .select("province, sum(payAmount) as pay_amount") \
+ .insert_into("es_sink")
+
+ t_env.execute("payment_demo")
Review comment:
```suggestion
t_env.execute_sql(source_ddl)
t_env.execute_sql(es_sink_ddl)
t_env.register_function('province_id_to_name', province_id_to_name)
t_env.from_path("payment_msg") \
.select("province_id_to_name(provinceId) as province, payAmount") \
.group_by("province") \
.select("province, sum(payAmount) as pay_amount") \
.execute_insert("es_sink")
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
Review comment:
```suggestion
In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
* Reading data from a Kafka source;
* Creating and using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
* Performing a simple aggregation over the source data;
* Writing the results to Elasticsearch and visualizing them in Kibana.
The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/) installed in your machine.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
Review comment:
```suggestion
First, build the Docker image by running:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
Review comment:
```suggestion
### Building the Docker image
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
Review comment:
```suggestion
Once the Docker image build is complete, run the following command to start the playground:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
+
+```bash
+docker-compose up -d
+```
+
+You can check if the playground was successfully started by accessing the WebUI of(You may need to wait about 1 min before all services come up.):
Review comment:
```suggestion
One way of checking if the playground was successfully started is accessing some of the services exposed:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
Review comment:
```suggestion
As mentioned, the environment for this walkthrough is based on Docker Compose; and uses a custom image to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator and Elasticsearch+Kibana containers.
You can find the [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file in the `pyflink-walkthrough` root directory.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
+
+```bash
+docker-compose up -d
+```
+
+You can check if the playground was successfully started by accessing the WebUI of(You may need to wait about 1 min before all services come up.):
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+
+### Stopping the Playground
+
+To stop the playground, run the following command
+
+```bash
+docker-compose down
+```
+
+
+## Run jobs
Review comment:
```suggestion
## Running the PyFlink Job
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
Review comment:
```suggestion
You will be using Kafka to store sample input data about payment transactions. A simple data generator `[generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py)` is provided to continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
* `createTime`: The creation time of the transaction.
* `orderId`: The ID of the current transaction.
* `payAmount`: The pay amount of the current transaction.
* `payPlatform`: The platform used to pay the order (pc or mobile).
* `provinceId`: The ID of the province the user is located in.
You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
Review comment:
```suggestion
Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize the results of your PyFlink pipeline.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
+
+```bash
+docker-compose up -d
+```
+
+You can check if the playground was successfully started by accessing the WebUI of(You may need to wait about 1 min before all services come up.):
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+
+### Stopping the Playground
+
+To stop the playground, run the following command
Review comment:
```suggestion
To stop the playground, run the following command:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
+
+```bash
+docker-compose up -d
+```
+
+You can check if the playground was successfully started by accessing the WebUI of(You may need to wait about 1 min before all services come up.):
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+
Review comment:
```suggestion
**Note:** you may need to wait around 1 minute before all the services come up.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
+
+```bash
+docker-compose up -d
+```
+
+You can check if the playground was successfully started by accessing the WebUI of(You may need to wait about 1 min before all services come up.):
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+
+### Stopping the Playground
+
+To stop the playground, run the following command
+
+```bash
+docker-compose down
+```
+
+
+## Run jobs
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+2. Open [kibana ui](http://localhost:5601) and choose the dashboard: payment_dashboard
+
+
+
+
+
+3. Stop PyFlink job:
+
+Visit [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancle`.
Review comment:
```suggestion
Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview), select the job and click `Cancel` on the upper right side.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
+
+```bash
+docker-compose up -d
+```
+
+You can check if the playground was successfully started by accessing the WebUI of(You may need to wait about 1 min before all services come up.):
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+
+### Stopping the Playground
+
+To stop the playground, run the following command
+
+```bash
+docker-compose down
+```
+
+
+## Run jobs
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+2. Open [kibana ui](http://localhost:5601) and choose the dashboard: payment_dashboard
+
+
+
+
+
+3. Stop PyFlink job:
Review comment:
```suggestion
3. Stop the PyFlink job:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,102 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana. The environment is managed by Docker so that all you need is a docker on your computer.
+
+- Kafka
+
+Kafka is used to store input data in this walkthrough. The script [generate_source_data.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/generate_source_data.py) is used to generate transaction data and writes into the payment_msg kafka topic. Each record includes 5 fields:
+```text
+{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}
+```
+```text
+createTime: The creation time of the transaction.
+orderId: The id of the current transaction.
+payAmount: The pay amount of the current transaction.
+payPlatform: The platform used to pay the order, pc or mobile.
+provinceId: The id of the province for the user.
+```
+
+- Generator
+
+A simple data generator is provided that continuously writes new records into Kafka.
+You can use the following command to read data in kafka and check whether the data is generated correctly.
+
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+- PyFlink
+
+The transaction data is processed by a PyFlink job, [payment_msg_proccessing.py](https://github.com/hequn8128/pyflink-walkthrough/blob/master/payment_msg_proccessing.py). The job maps the province id to province name for better demonstration using a Python UDF and then sums the payment for each province using a group aggregate.
+
+- ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+- Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. We use it to visualize our processing results.
+
+## Setup
+
+The pyflink-walkthrough requires a custom Docker image, as well as public images for Flink, Elasticsearch, Kafka, and ZooKeeper.
+
+The [docker-compose.yaml](https://github.com/hequn8128/pyflink-walkthrough/blob/master/docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the custom Docker image
+
+Build the Docker image by running
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once you built the Docker image, run the following command to start the playground
+
+```bash
+docker-compose up -d
+```
+
+You can check if the playground was successfully started by accessing the WebUI of(You may need to wait about 1 min before all services come up.):
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+
+### Stopping the Playground
+
+To stop the playground, run the following command
+
+```bash
+docker-compose down
+```
+
+
+## Run jobs
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+2. Open [kibana ui](http://localhost:5601) and choose the dashboard: payment_dashboard
Review comment:
```suggestion
2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`.
```
##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+ return provinces[id]
+
+
+def log_processing():
+ env = StreamExecutionEnvironment.get_execution_environment()
+ env_settings = EnvironmentSettings.Builder().use_blink_planner().build()
+ t_env = StreamTableEnvironment.create(stream_execution_environment=env, environment_settings=env_settings)
+ t_env.get_config().get_configuration().set_boolean("python.fn-execution.memory.managed", True)
+
+ source_ddl = """
+ CREATE TABLE payment_msg(
+ createTime VARCHAR,
+ orderId BIGINT,
+ payAmount DOUBLE,
+ payPlatform INT,
+ provinceId INT
+ ) WITH (
+ 'connector.type' = 'kafka',
+ 'connector.version' = 'universal',
+ 'connector.topic' = 'payment_msg',
+ 'connector.properties.bootstrap.servers' = 'kafka:9092',
+ 'connector.properties.group.id' = 'test_3',
+ 'connector.startup-mode' = 'latest-offset',
+ 'format.type' = 'json'
+ )
+ """
+
+ es_sink_ddl = """
+ CREATE TABLE es_sink (
+ province VARCHAR PRIMARY KEY,
+ pay_amount DOUBLE
+ ) with (
+ 'connector.type' = 'elasticsearch',
+ 'connector.version' = '7',
+ 'connector.hosts' = 'http://elasticsearch:9200',
+ 'connector.index' = 'platform_pay_amount_1',
+ 'connector.document-type' = 'payment',
+ 'update-mode' = 'upsert',
+ 'connector.flush-on-checkpoint' = 'true',
+ 'connector.key-delimiter' = '$',
+ 'connector.key-null-literal' = 'n/a',
+ 'connector.bulk-flush.max-size' = '42mb',
+ 'connector.bulk-flush.max-actions' = '32',
+ 'connector.bulk-flush.interval' = '1000',
+ 'connector.bulk-flush.backoff.delay' = '1000',
+ 'format.type' = 'json'
+ )
+ """
+
+ t_env.sql_update(source_ddl)
+ t_env.sql_update(es_sink_ddl)
+ t_env.register_function('province_id_to_name', province_id_to_name)
+
+ t_env.from_path("payment_msg") \
+ .select("province_id_to_name(provinceId) as province, payAmount") \
+ .group_by("province") \
+ .select("province, sum(payAmount) as pay_amount") \
+ .insert_into("es_sink")
+
+ t_env.execute("payment_demo")
Review comment:
Use 1.11 methods instead of the deprecated ones.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-689249936


   Hi @sjwiesman , could you please help review this pull request?  Thank you : )


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r486966065


##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?

##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?

##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?

##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?

##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen edited a comment on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen edited a comment on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-705944280


   @alpinegizmo Thank you for your comments, I have adjusted some content order to make the README to be more well-organized. And here are the answers for your questions:

   > Do you plan to add a link to this walkthrough from the docs somewhere?

   I would like to lead users to turn to this playground to have an end to end practice for PyFlink after they have the basic knowledge of PyFlink. So I plan to add a link to this walkthrough in the end of the [Flink Python API docs](https://ci.apache.org/projects/flink/flink-docs-master/dev/python/).


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo closed pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo closed pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-707065208


   @alpinegizmo Yes, I also checked that. It's because we start the service detachedly, when we visit the kibana home page, the `load-kibana-dashboard` service is not ready yet. We should add the readiness check logic as you mentioned above.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497332100
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`, There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
+
+
+
+
+
+3. Stop the PyFlink job:
+
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.
+
+
+
+## Further Explorations
+
+If you would like to explore this example more deeply, you can edit [payment_msg_processing.py](payment_msg_proccessing.py)
+or create new PyFlink projects that perform more complex processing. You can do this locally under
+the `pyflink-walkthrough` directory, since it is mounted on the `jobmanager` docker container.
+
+Ideas:
+* Add your own Kafka source table;
+* Create new index for the Elasticsearch sink;
Review comment:
```suggestion
* Create a new index for the Elasticsearch sink;
```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497316656


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.

Review comment:
       ```suggestion
   Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
   ```
   ```suggestion
   You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r498114079
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully. There should be a job in the running job list.
+Click the job to get more details. You should see that the `StreamGraph` of the `payment_msg_proccessing` consists of two nodes, each with a parallelism of 1.
+There is also a table in the bottom of the page that shows the metrics of every node (e.g. bytes received/sent, records received/sent).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`. There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
+
+
+
+
+
+3. Stop the PyFlink job:
+
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.
Review comment:
```suggestion
Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview), select the job, and click `Cancel Job` in the upper right corner.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
Review comment:
It is confusing to present, this early in the documentation, details of how to work with Kafka that won't actually work before having built and launched the docker image.
Some, or perhaps all, of the information in this background section needs to come later, in a "just in time" fashion, when it is needed. Readers want to make a single, linear pass through one of these walkthroughs, executing commands as they go. Presenting shell commands before they can be used will confuse some readers.
##########
File path: README.md
##########
@@ -15,6 +15,8 @@ Flink job. The playground is presented in detail in
* The **Table Walkthrough** (in the `table-walkthrough` folder) shows to use the Table API to build an analytics pipeline that reads streaming data from Kafka and writes results to MySQL, along with a real-time dashboard in Grafana. The walkthrough is presented in detail in ["Real Time Reporting with the Table API"](https://ci.apache.org/projects/flink/flink-docs-release-1.11/try-flink/table_api.html), which is part of the _Try Flink_ section of the Flink documentation.
+* The **PyFlink Walkthrough** (in the `pyflink-walkthrough` folder) provides a complete example that uses the Python API, and guides you through the steps needed to run and manage Pyflink Jobs. The pipeline used in this walkthrough reads data from Kafka, performs aggregations, and writes results to Elasticsearch that are visualized with Kibana.
Review comment:
```suggestion
* The **PyFlink Walkthrough** (in the `pyflink-walkthrough` folder) provides a complete example that uses the Python API, and guides you through the steps needed to run and manage Pyflink Jobs. The pipeline used in this walkthrough reads data from Kafka, performs aggregations, and writes results to Elasticsearch that are visualized with Kibana. This walkthrough is presented in detail in the [pyflink-walkthrough README](pyflink-walkthrough).
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
Review comment:
When I tried this, it took me a couple of minutes to realize it hadn't done the right things because I was still in the parent directory.
```suggestion
cd pyflink-walkthrough
docker-compose build
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
Review comment:
This should come later. If it is left here, some folks will blindly stop the playground at this point.
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully. There should be a job in the running job list.
+Click the job to get more details. You should see that the `StreamGraph` of the `payment_msg_proccessing` consists of two nodes, each with a parallelism of 1.
+There is also a table in the bottom of the page that shows the metrics of every node (e.g. bytes received/sent, records received/sent).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`. There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
+
+
+
+
+
+3. Stop the PyFlink job:
+
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.
+
+
+
+## Further Explorations
+
+If you would like to explore this example more deeply, you can edit [payment_msg_processing.py](payment_msg_proccessing.py)
+or create new PyFlink projects that perform more complex processing. You can do this locally under
+the `pyflink-walkthrough` directory, since it is mounted on the `jobmanager` docker container.
+
+Ideas:
+* Add your own Kafka source table;
+* Create a new index for the Elasticsearch sink;
+* Count the number of transactions, grouped by a 1 minute [tumbling window](https://ci.apache.org/projects/flink/flink-docs-stable/dev/table/tableApi.html#tumble-tumbling-windows) and `payPlatform`.
+
+After making a modification, you can submit the new job by executing the same command mentioned at
+[Running the PyFlink Job](#running-the-pyflink-job)
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+Furthermore, you can also [create new Kibana dashboards](https://www.elastic.co/guide/en/kibana/7.8/dashboard-create-new-dashboard.html)
+to visualize other aspects of the data in the Elasticsearch.
Review comment:
```suggestion
to visualize other aspects of the data in Elasticsearch.
```
##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,90 @@
+################################################################################
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+ return provinces[id]
+
+
+def log_processing():
+ env = StreamExecutionEnvironment.get_execution_environment()
+ t_env = StreamTableEnvironment.create(stream_execution_environment=env)
+ t_env.get_config().get_configuration().set_boolean("python.fn-execution.memory.managed", True)
+
+ source_ddl = """
Review comment:
```suggestion
create_kafka_source_ddl = """
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully. There should be a job in the running job list.
+Click the job to get more details. You should see that the `StreamGraph` of the `payment_msg_proccessing` consists of two nodes, each with a parallelism of 1.
+There is also a table in the bottom of the page that shows the metrics of every node (e.g. bytes received/sent, records received/sent).
Review comment:
```suggestion
There is also a table in the bottom of the page that shows some metrics for each node (e.g. bytes received/sent, records received/sent). Note that Flink's metrics only report bytes and records communicated within the Flink cluster, and so will always report 0 bytes and 0 records received by sources, and 0 bytes and 0 records sent to sinks — so don't be confused that nothing is reported as being read from Kafka, or written to Elasticsearch.
```
##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,90 @@
+################################################################################
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+ return provinces[id]
+
+
+def log_processing():
+ env = StreamExecutionEnvironment.get_execution_environment()
+ t_env = StreamTableEnvironment.create(stream_execution_environment=env)
+ t_env.get_config().get_configuration().set_boolean("python.fn-execution.memory.managed", True)
+
+ source_ddl = """
+ CREATE TABLE payment_msg(
+ createTime VARCHAR,
+ orderId BIGINT,
+ payAmount DOUBLE,
+ payPlatform INT,
+ provinceId INT
+ ) WITH (
+ 'connector.type' = 'kafka',
+ 'connector.version' = 'universal',
+ 'connector.topic' = 'payment_msg',
+ 'connector.properties.bootstrap.servers' = 'kafka:9092',
+ 'connector.properties.group.id' = 'test_3',
+ 'connector.startup-mode' = 'latest-offset',
+ 'format.type' = 'json'
+ )
+ """
+
+ es_sink_ddl = """
Review comment:
```suggestion
create_es_sink_ddl = """
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
Review comment:
This is what I see at localhost:9200
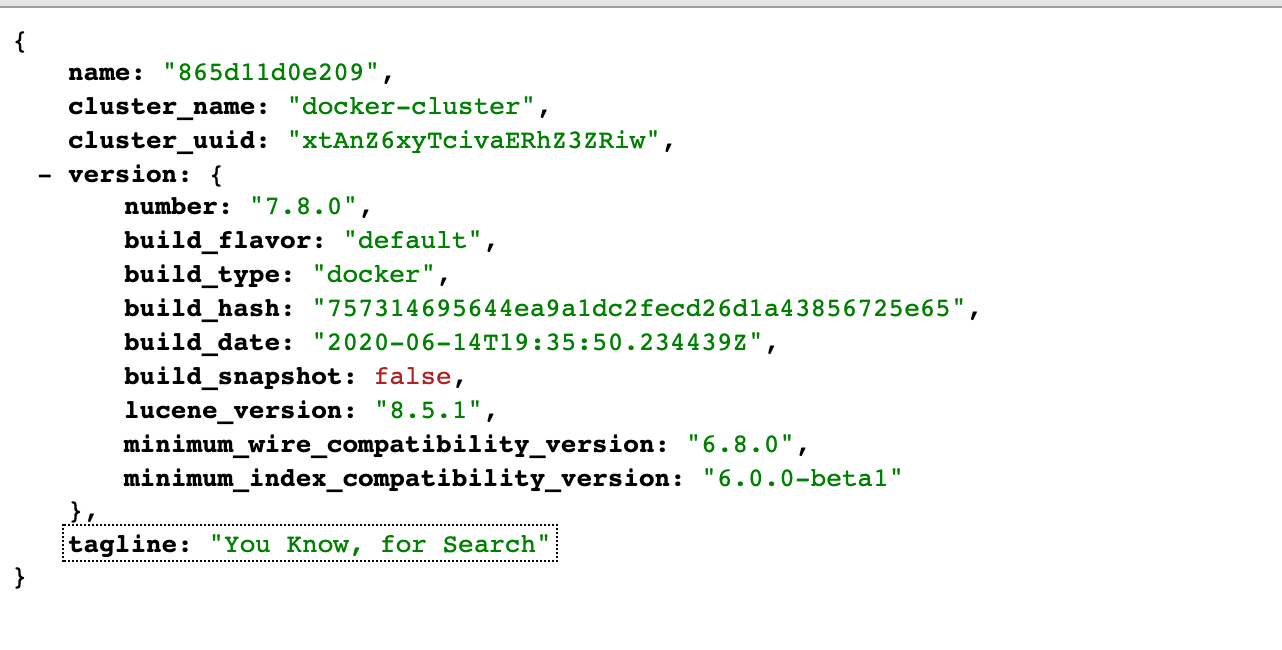
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
Review comment:
@shuiqiangchen Do you plan to add a link to this walkthrough from the docs somewhere?
##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,90 @@
+################################################################################
+# Licensed to the Apache Software Foundation (ASF) under one
+# or more contributor license agreements. See the NOTICE file
+# distributed with this work for additional information
+# regarding copyright ownership. The ASF licenses this file
+# to you under the Apache License, Version 2.0 (the
+# "License"); you may not use this file except in compliance
+# with the License. You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+ return provinces[id]
+
+
+def log_processing():
+ env = StreamExecutionEnvironment.get_execution_environment()
+ t_env = StreamTableEnvironment.create(stream_execution_environment=env)
+ t_env.get_config().get_configuration().set_boolean("python.fn-execution.memory.managed", True)
+
+ source_ddl = """
+ CREATE TABLE payment_msg(
+ createTime VARCHAR,
+ orderId BIGINT,
+ payAmount DOUBLE,
+ payPlatform INT,
+ provinceId INT
+ ) WITH (
+ 'connector.type' = 'kafka',
+ 'connector.version' = 'universal',
+ 'connector.topic' = 'payment_msg',
+ 'connector.properties.bootstrap.servers' = 'kafka:9092',
+ 'connector.properties.group.id' = 'test_3',
+ 'connector.startup-mode' = 'latest-offset',
+ 'format.type' = 'json'
+ )
+ """
+
+ es_sink_ddl = """
+ CREATE TABLE es_sink (
+ province VARCHAR PRIMARY KEY,
+ pay_amount DOUBLE
+ ) with (
+ 'connector.type' = 'elasticsearch',
+ 'connector.version' = '7',
+ 'connector.hosts' = 'http://elasticsearch:9200',
+ 'connector.index' = 'platform_pay_amount_1',
+ 'connector.document-type' = 'payment',
+ 'update-mode' = 'upsert',
+ 'connector.flush-on-checkpoint' = 'true',
+ 'connector.key-delimiter' = '$',
+ 'connector.key-null-literal' = 'n/a',
+ 'connector.bulk-flush.max-size' = '42mb',
+ 'connector.bulk-flush.max-actions' = '32',
+ 'connector.bulk-flush.interval' = '1000',
+ 'connector.bulk-flush.backoff.delay' = '1000',
+ 'format.type' = 'json'
+ )
+ """
+
+ t_env.execute_sql(source_ddl)
+ t_env.execute_sql(es_sink_ddl)
Review comment:
```suggestion
t_env.execute_sql(create_kafka_source_ddl)
t_env.execute_sql(create_es_sink_ddl)
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
Review comment:
@morsapaes FWIW, this content isn't targeted for the docs. This is intended to be a github README. I only just realized this myself. Since the other walkthroughs are in the docs, I assume this one was as planned to be as well, but it's not.
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully. There should be a job in the running job list.
+Click the job to get more details. You should see that the `StreamGraph` of the `payment_msg_proccessing` consists of two nodes, each with a parallelism of 1.
+There is also a table in the bottom of the page that shows the metrics of every node (e.g. bytes received/sent, records received/sent).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`. There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
Review comment:
This didn't work for me. localhost:5061 redirected to http://localhost:5601/app/kibana#/home where I see this:
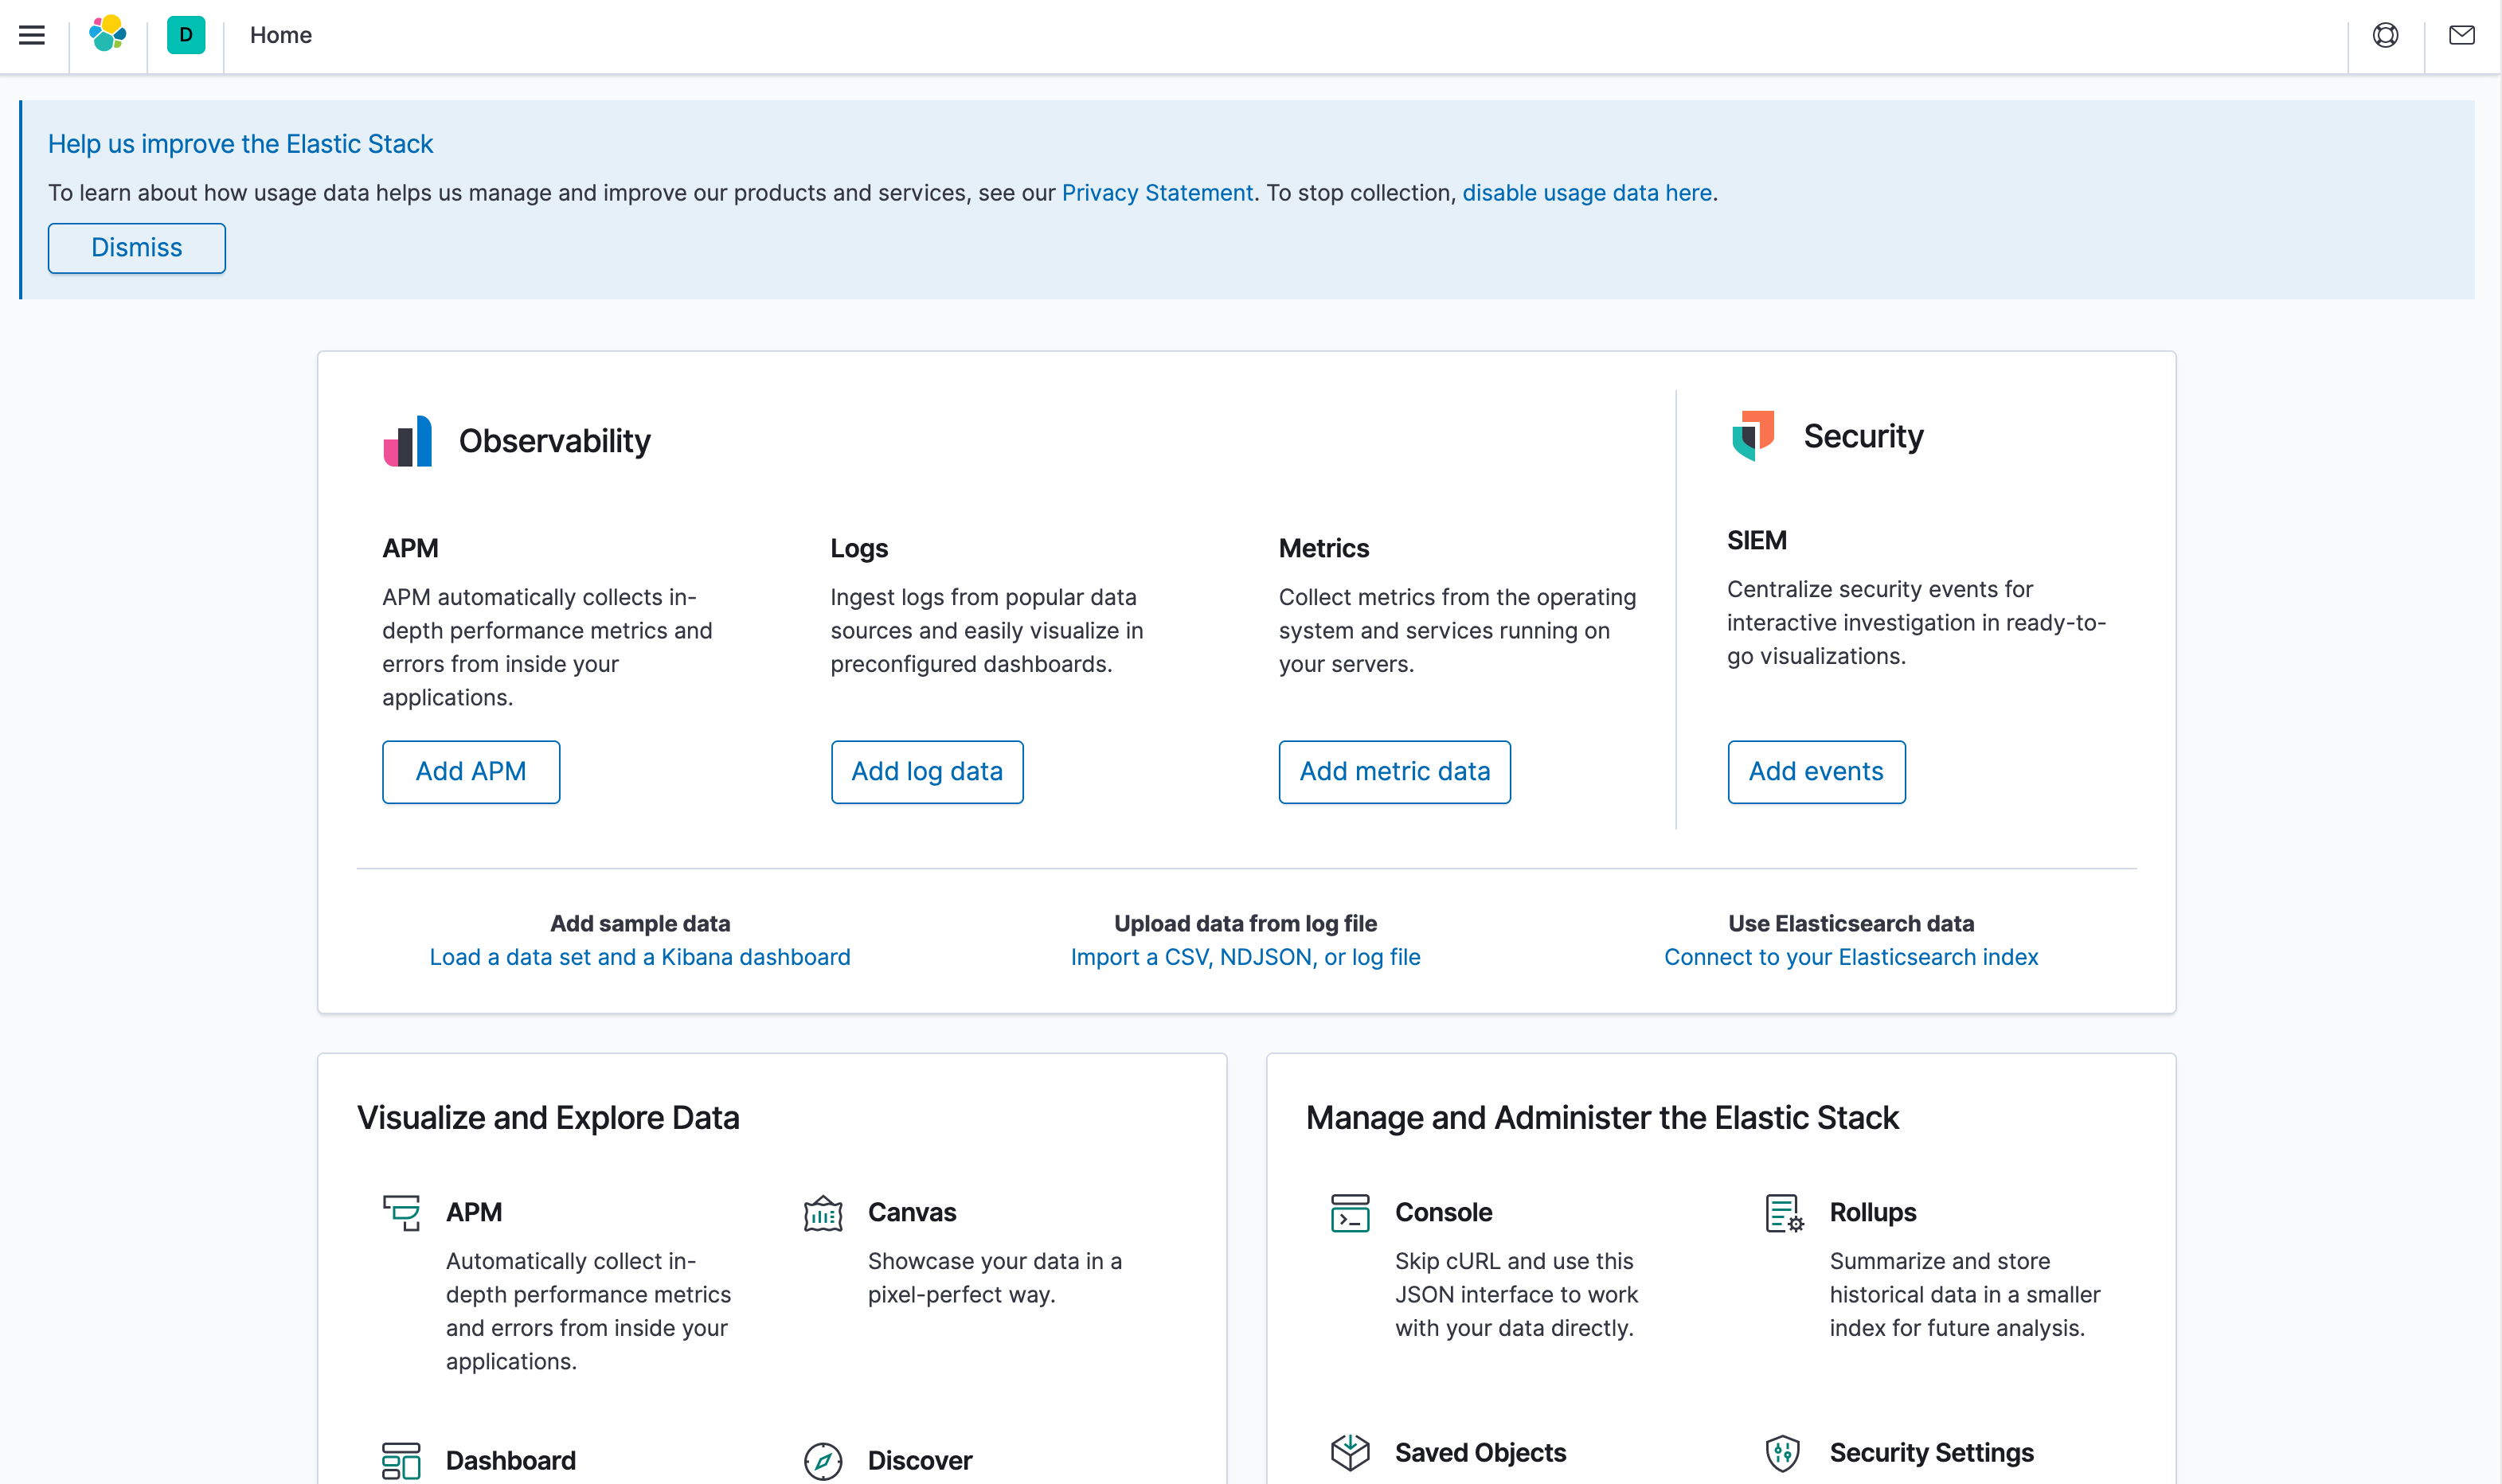
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
Review comment:
I suggest being consistent, and putting a $ prompt in front of all of the other shell commands in this README as well.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497333921
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`, There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
+
+
+
+
+
+3. Stop the PyFlink job:
+
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.
+
+
+
+## Further Explorations
+
+If you would like to explore this example more deeply, you can edit [payment_msg_processing.py](payment_msg_proccessing.py)
+or create new PyFlink projects that perform more complex processing. You can do this locally under
+the `pyflink-walkthrough` directory, since it is mounted on the `jobmanager` docker container.
+
+Ideas:
+* Add your own Kafka source table;
+* Create new index for the Elasticsearch sink;
+* Count the number of transactions, grouped by a 1 minute tumbling windows and payPlatform.
+
+After making a modification, you can submit the new job by executing the same command mentioned at
+[Running the PyFlink Job](#running-the-pyflink-job)
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+Furthermore, you can also [create new kibana dashboards](https://www.elastic.co/guide/en/kibana/7.8/dashboard-create-new-dashboard.html)
Review comment:
```suggestion
Furthermore, you can also [create new Kibana dashboards](https://www.elastic.co/guide/en/kibana/7.8/dashboard-create-new-dashboard.html)
```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497317674


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.

Review comment:
       ```suggestion
   Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully. There should be a job in the running job list.
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r498606570


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).

Review comment:
       This simply indicates that the Elasticsearch service is successfully up  when you visit this link.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen edited a comment on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen edited a comment on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-705944280


   @alpinegizmo Thank you for your comments, I have adjusted some content order to make the README to be more well-organized. And here are the answers for your questions:

   > Do you plan to add a link to this walkthrough from the docs somewhere?

   I would like to lead users to turn to this playground to have an end to end practice for PyFlink after they have the basic knowledge of PyFlink. So I plan to add a link to this walkthrough in the end of the [Flink Python API docs](https://ci.apache.org/projects/flink/flink-docs-master/dev/python/).


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-692097594


   @shuiqiangchen I would like to review this PR, but would find it easier to do that after you've responded to the excellent review from @morsapaes.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r498607377
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,140 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana containers.
+
+You can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully. There should be a job in the running job list.
+Click the job to get more details. You should see that the `StreamGraph` of the `payment_msg_proccessing` consists of two nodes, each with a parallelism of 1.
+There is also a table in the bottom of the page that shows the metrics of every node (e.g. bytes received/sent, records received/sent).
+
+
+
+
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`. There will be a vertical bar chart and a pie chart demonstrating the total amount and the proportion of each province.
Review comment:
Sorry, the localhost:5061 would lead you to the home page of Kibana, then you need to open the menu list by clicking the menu button in the upper left corner, then choose the `Dashboard` item to turn the dashboard page. I will make it more clear.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-701268849


   LGTM, @shuiqiangchen ! Thanks for working on the suggestions. 👍  And sorry that it took me so long to come back to it!


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-705944280


   @alpinegizmo Thank you for your comments, I have adjusted some content order to make the README to be more well-organized. And here are the answers for you questions:

   > Do you plan to add a link to this walkthrough from the docs somewhere?

   We would like to lead users to turn to this playground to have an end to end practice for PyFlink after they have the basic knowledge of PyFlink. So we plan to add a link to walkthrough in the end of the [Flink Python API docs](https://ci.apache.org/projects/flink/flink-docs-master/dev/python/).


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-707013640
@shuiqiangchen I not finding a pre-defined kibana dashboard. When I choose "Kibana / Dashboard" from the menu, I end up here:

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497319777


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is to access some of the services that are exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Running the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+Navigate to the [Flink Web UI](http://localhost:8081) after the job is submitted successfully, There will be a job in the running job list.
+Click the job to turn to the main page of it. You can see that the StreamGraph of the `payment_msg_proccessing` job is consist of two nodes, each of them has parallelism of 1.
+And there is a table in the bottom of the page shows the metrics of every node (bytes received/sent, records received/sent, etc).

Review comment:
       ```suggestion
   Click the job to get more details. You should see that the `StreamGraph` of the `payment_msg_proccessing` consists of two nodes, each with a parallelism of 1. There is also a table at the bottom of the page that shows some metrics for every node (e.g. bytes received/sent, records received/sent).
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen edited a comment on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen edited a comment on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-692423562


   Hi @morsapaes @alpinegizmo , sorry for the late reply, I was on vacation in the last four days. Highly appreciate for @morsapaes valuable comments and warmly welcome @alpinegizmo  to help reviewing this PR, I have updated the PR according to your suggestions, Please have a look at it.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-697071304


   @alpinegizmo Thank you for polishing the doc, I have updated the PR, please have a look.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r486966065


##########
File path: pyflink-walkthrough/payment_msg_proccessing.py
##########
@@ -0,0 +1,93 @@
+################################################################################
+#  Licensed to the Apache Software Foundation (ASF) under one
+#  or more contributor license agreements.  See the NOTICE file
+#  distributed with this work for additional information
+#  regarding copyright ownership.  The ASF licenses this file
+#  to you under the Apache License, Version 2.0 (the
+#  "License"); you may not use this file except in compliance
+#  with the License.  You may obtain a copy of the License at
+#
+#      http://www.apache.org/licenses/LICENSE-2.0
+#
+#  Unless required by applicable law or agreed to in writing, software
+#  distributed under the License is distributed on an "AS IS" BASIS,
+#  WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+#  See the License for the specific language governing permissions and
+# limitations under the License.
+################################################################################
+
+from pyflink.datastream import StreamExecutionEnvironment, TimeCharacteristic
+from pyflink.table import StreamTableEnvironment, DataTypes, EnvironmentSettings
+from pyflink.table.udf import udf
+
+
+provinces = ("Beijing", "Shanghai", "Hangzhou", "Shenzhen", "Jiangxi", "Chongqing", "Xizang")
+
+
+@udf(input_types=[DataTypes.STRING()], result_type=DataTypes.STRING())
+def province_id_to_name(id):
+    return provinces[id]
+
+
+def log_processing():
+    env = StreamExecutionEnvironment.get_execution_environment()
+    env_settings = EnvironmentSettings.Builder().use_blink_planner().build()

Review comment:
       Does this need to be set, considering that the Blink planner is the default since 1.11?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] morsapaes commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
morsapaes commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r497316656


##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,141 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+The environment is based on Docker Compose, so the only requirement is that you have [Docker](https://docs.docker.com/get-docker/)
+installed in your machine.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The amount being paid with this transaction.
+* `payPlatform`: The platform used to create this payment: pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+You can also create a new topic by executing the following command:
+```shell script
+$ docker-compose exec kafka kafka-topics.sh --bootstrap-server kafka:9092 --create --topic <YOUR-TOPIC-NAME> --partitions 8 --replication-factor 1
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name using a Python UDF,
+and then compute the sum of the transaction amounts for each province.
+
+### ElasticSearch
+
+ElasticSearch is used to store the upstream processing results and to provide an efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; It uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.

Review comment:
       ```suggestion
   Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
   ```
   ```suggestion
   Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough in the `pyflink-walkthrough` root directory.
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on a change in pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on a change in pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#discussion_r488772985
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
Review comment:
```suggestion
* `payAmount`: The amount being paid with this transaction.
```
##########
File path: README.md
##########
@@ -15,6 +15,8 @@ Flink job. The playground is presented in detail in
* The **Table Walkthrough** (in the `table-walkthrough` folder) shows to use the Table API to build an analytics pipeline that reads streaming data from Kafka and writes results to MySQL, along with a real-time dashboard in Grafana. The walkthrough is presented in detail in ["Real Time Reporting with the Table API"](https://ci.apache.org/projects/flink/flink-docs-release-1.11/try-flink/table_api.html), which is part of the _Try Flink_ section of the Flink documentation.
+* The **PyFlink Walkthrough** (int the `pyflink-walkthrough` folder) guides you to learn about how to manage and run PyFlink Jobs. The pipeline of this walkthrough reads data from Kafka, performs aggregations and writes results to Elasticsearch visualized via Kibana.
Review comment:
```suggestion
* The **PyFlink Walkthrough** (in the `pyflink-walkthrough` folder) provides a complete example that uses the Python API, and guides you through the steps needed to run and manage PyFlink jobs. The pipeline used in this walkthrough reads data from Kafka, performs aggregations, and writes results to Elasticsearch that are visualized with Kibana.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
+* `payPlatform`: The platform used to pay the order, pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name
+using a Python UDF, and them sum the transaction amount for each province using a group aggregate.
Review comment:
```suggestion
using a Python UDF, and then compute the sum of the transaction amounts for each province.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
+* `payPlatform`: The platform used to pay the order, pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name
+using a Python UDF, and them sum the transaction amount for each province using a group aggregate.
+
+### ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; and uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is accessing some of the services exposed:
Review comment:
```suggestion
One way of checking if the playground was successfully started is to access some of the services that are exposed:
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
+* `payPlatform`: The platform used to pay the order, pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name
+using a Python UDF, and them sum the transaction amount for each province using a group aggregate.
+
+### ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
Review comment:
```suggestion
ElasticSearch is used to store the results and to provide an efficient query service.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
+* `payPlatform`: The platform used to pay the order, pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name
+using a Python UDF, and them sum the transaction amount for each province using a group aggregate.
+
+### ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; and uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is accessing some of the services exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Runing the PyFlink job
+
+1. Submit the PyFlink job.
+```shell script
+$ docker-compose exec jobmanager ./bin/flink run -py /opt/pyflink-walkthrough/payment_msg_proccessing.py -d
+```
+
+2. Navigate to the [Kibana UI](http://localhost:5601) and choose the pre-created dashboard `payment_dashboard`.
+
+
+
+
+
+3. Stop the PyFlink job:
+
+Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancle` on the upper right side.
Review comment:
```suggestion
Visit the Flink Web UI at [http://localhost:8081/#/overview](http://localhost:8081/#/overview) , select the job and click `Cancel` on the upper right side.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
+* `payPlatform`: The platform used to pay the order, pc or mobile.
Review comment:
```suggestion
* `payPlatform`: The platform used to create this payment: pc or mobile.
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
+* `payPlatform`: The platform used to pay the order, pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name
+using a Python UDF, and them sum the transaction amount for each province using a group aggregate.
+
+### ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; and uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator and Elasticsearch+Kibana
+containers.
+
+Your can find the [docker-compose.yaml](docker-compose.yml) file of the pyflink-walkthrough is located in the `pyflink-walkthrough` root directory.
+
+### Building the Docker image
+
+First, build the Docker image by running:
+
+```bash
+docker-compose build
+```
+
+### Starting the Playground
+
+Once the Docker image build is complete, run the following command to start the playground:
+
+```bash
+docker-compose up -d
+```
+
+One way of checking if the playground was successfully started is accessing some of the services exposed:
+
+1. visiting Flink Web UI [http://localhost:8081](http://localhost:8081).
+2. visiting Elasticsearch [http://localhost:9200](http://localhost:9200).
+3. visiting Kibana [http://localhost:5601](http://localhost:5601).
+
+**Note:** you may need to wait around 1 minute before all the services come up.
+
+### Stopping the Playground
+
+To stop the playground, run the following command:
+
+```bash
+docker-compose down
+```
+
+
+## Runing the PyFlink job
Review comment:
```suggestion
## Running the PyFlink job
```
##########
File path: pyflink-walkthrough/README.md
##########
@@ -0,0 +1,107 @@
+# pyflink-walkthrough
+
+## Background
+
+In this playground, you will learn how to build and run an end-to-end PyFlink pipeline for data analytics, covering the following steps:
+
+* Reading data from a Kafka source;
+* Creating data using a [UDF](https://ci.apache.org/projects/flink/flink-docs-release-1.11/dev/python/table-api-users-guide/udfs/python_udfs.html);
+* Performing a simple aggregation over the source data;
+* Writing the results to Elasticsearch and visualizing them in Kibana.
+
+### Kafka
+You will be using Kafka to store sample input data about payment transactions. A simple data generator [generate_source_data.py](generator/generate_source_data.py) is provided to
+continuously write new records to the `payment_msg` Kafka topic. Each record is structured as follows:
+
+`{"createTime": "2020-08-12 06:29:02", "orderId": 1597213797, "payAmount": 28306.44976403719, "payPlatform": 0, "provinceId": 4}`
+
+* `createTime`: The creation time of the transaction.
+* `orderId`: The id of the current transaction.
+* `payAmount`: The pay amount of the current transaction.
+* `payPlatform`: The platform used to pay the order, pc or mobile.
+* `provinceId`: The id of the province for the user.
+
+You can use the following command to read data from the Kafka topic and check whether it's generated correctly:
+```shell script
+$ docker-compose exec kafka kafka-console-consumer.sh --bootstrap-server kafka:9092 --topic payment_msg
+{"createTime":"2020-07-27 09:25:32.77","orderId":1595841867217,"payAmount":7732.44,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.231","orderId":1595841867218,"payAmount":75774.05,"payPlatform":0,"provinceId":3}
+{"createTime":"2020-07-27 09:25:33.72","orderId":1595841867219,"payAmount":65908.55,"payPlatform":0,"provinceId":0}
+{"createTime":"2020-07-27 09:25:34.216","orderId":1595841867220,"payAmount":15341.11,"payPlatform":0,"provinceId":1}
+{"createTime":"2020-07-27 09:25:34.698","orderId":1595841867221,"payAmount":37504.42,"payPlatform":0,"provinceId":0}
+```
+
+### PyFlink
+
+The transaction data will be processed with PyFlink using the Python script [payment_msg_processing.py](payment_msg_proccessing.py).
+This script will first map the `provinceId` in the input records to its corresponding province name
+using a Python UDF, and them sum the transaction amount for each province using a group aggregate.
+
+### ElasticSearch
+
+ElasticSearch is used to store upstream processing results and provide efficient query service.
+
+### Kibana
+
+Kibana is an open source data visualization dashboard for ElasticSearch. You will use it to visualize
+the results of your PyFlink pipeline.
+
+## Setup
+
+As mentioned, the environment for this walkthrough is based on Docker Compose; and uses a custom image
+to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator and Elasticsearch+Kibana
+containers.
Review comment:
```suggestion
As mentioned, the environment for this walkthrough is based on Docker Compose. It uses a custom image
to spin up Flink (JobManager+TaskManager), Kafka+Zookeeper, the data generator, and Elasticsearch+Kibana
containers.
```
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-697261481


   @shuiqiangchen Thank you for applying my suggestions. I see, however, that some critical fixes from @morsapaes still need to be resolved.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] alpinegizmo commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
alpinegizmo commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-707014533
This is what I see in Elasticsearch:

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen commented on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen commented on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-692423562


   Hi @morsapaes @alpinegizmo , sorry for the late reply, I was on vacation in the last four days. Highly appreciate for @morsapaes valuable comments and warmly welcome @morsapaes to help reviewing these PR, I have updated the PR according to your suggestions, Please have a look at it.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink-playgrounds] shuiqiangchen edited a comment on pull request #16: [FLINK-19145][walkthroughs] Add PyFlink-walkthrough to Flink playground.
Posted by GitBox <gi...@apache.org>.
shuiqiangchen edited a comment on pull request #16:
URL: https://github.com/apache/flink-playgrounds/pull/16#issuecomment-692423562


   Hi @morsapaes @alpinegizmo , sorry for the late reply, I was on vacation in the last four days. Highly appreciate for @morsapaes valuable comments and warmly welcome @morsapaes to help reviewing this PR, I have updated the PR according to your suggestions, Please have a look at it.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org