You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@ozone.apache.org by GitBox <gi...@apache.org> on 2020/09/01 02:43:30 UTC
[GitHub] [hadoop-ozone] runzhiwang opened a new pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
runzhiwang opened a new pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371
## What changes were proposed in this pull request?
**What's the problem ?**
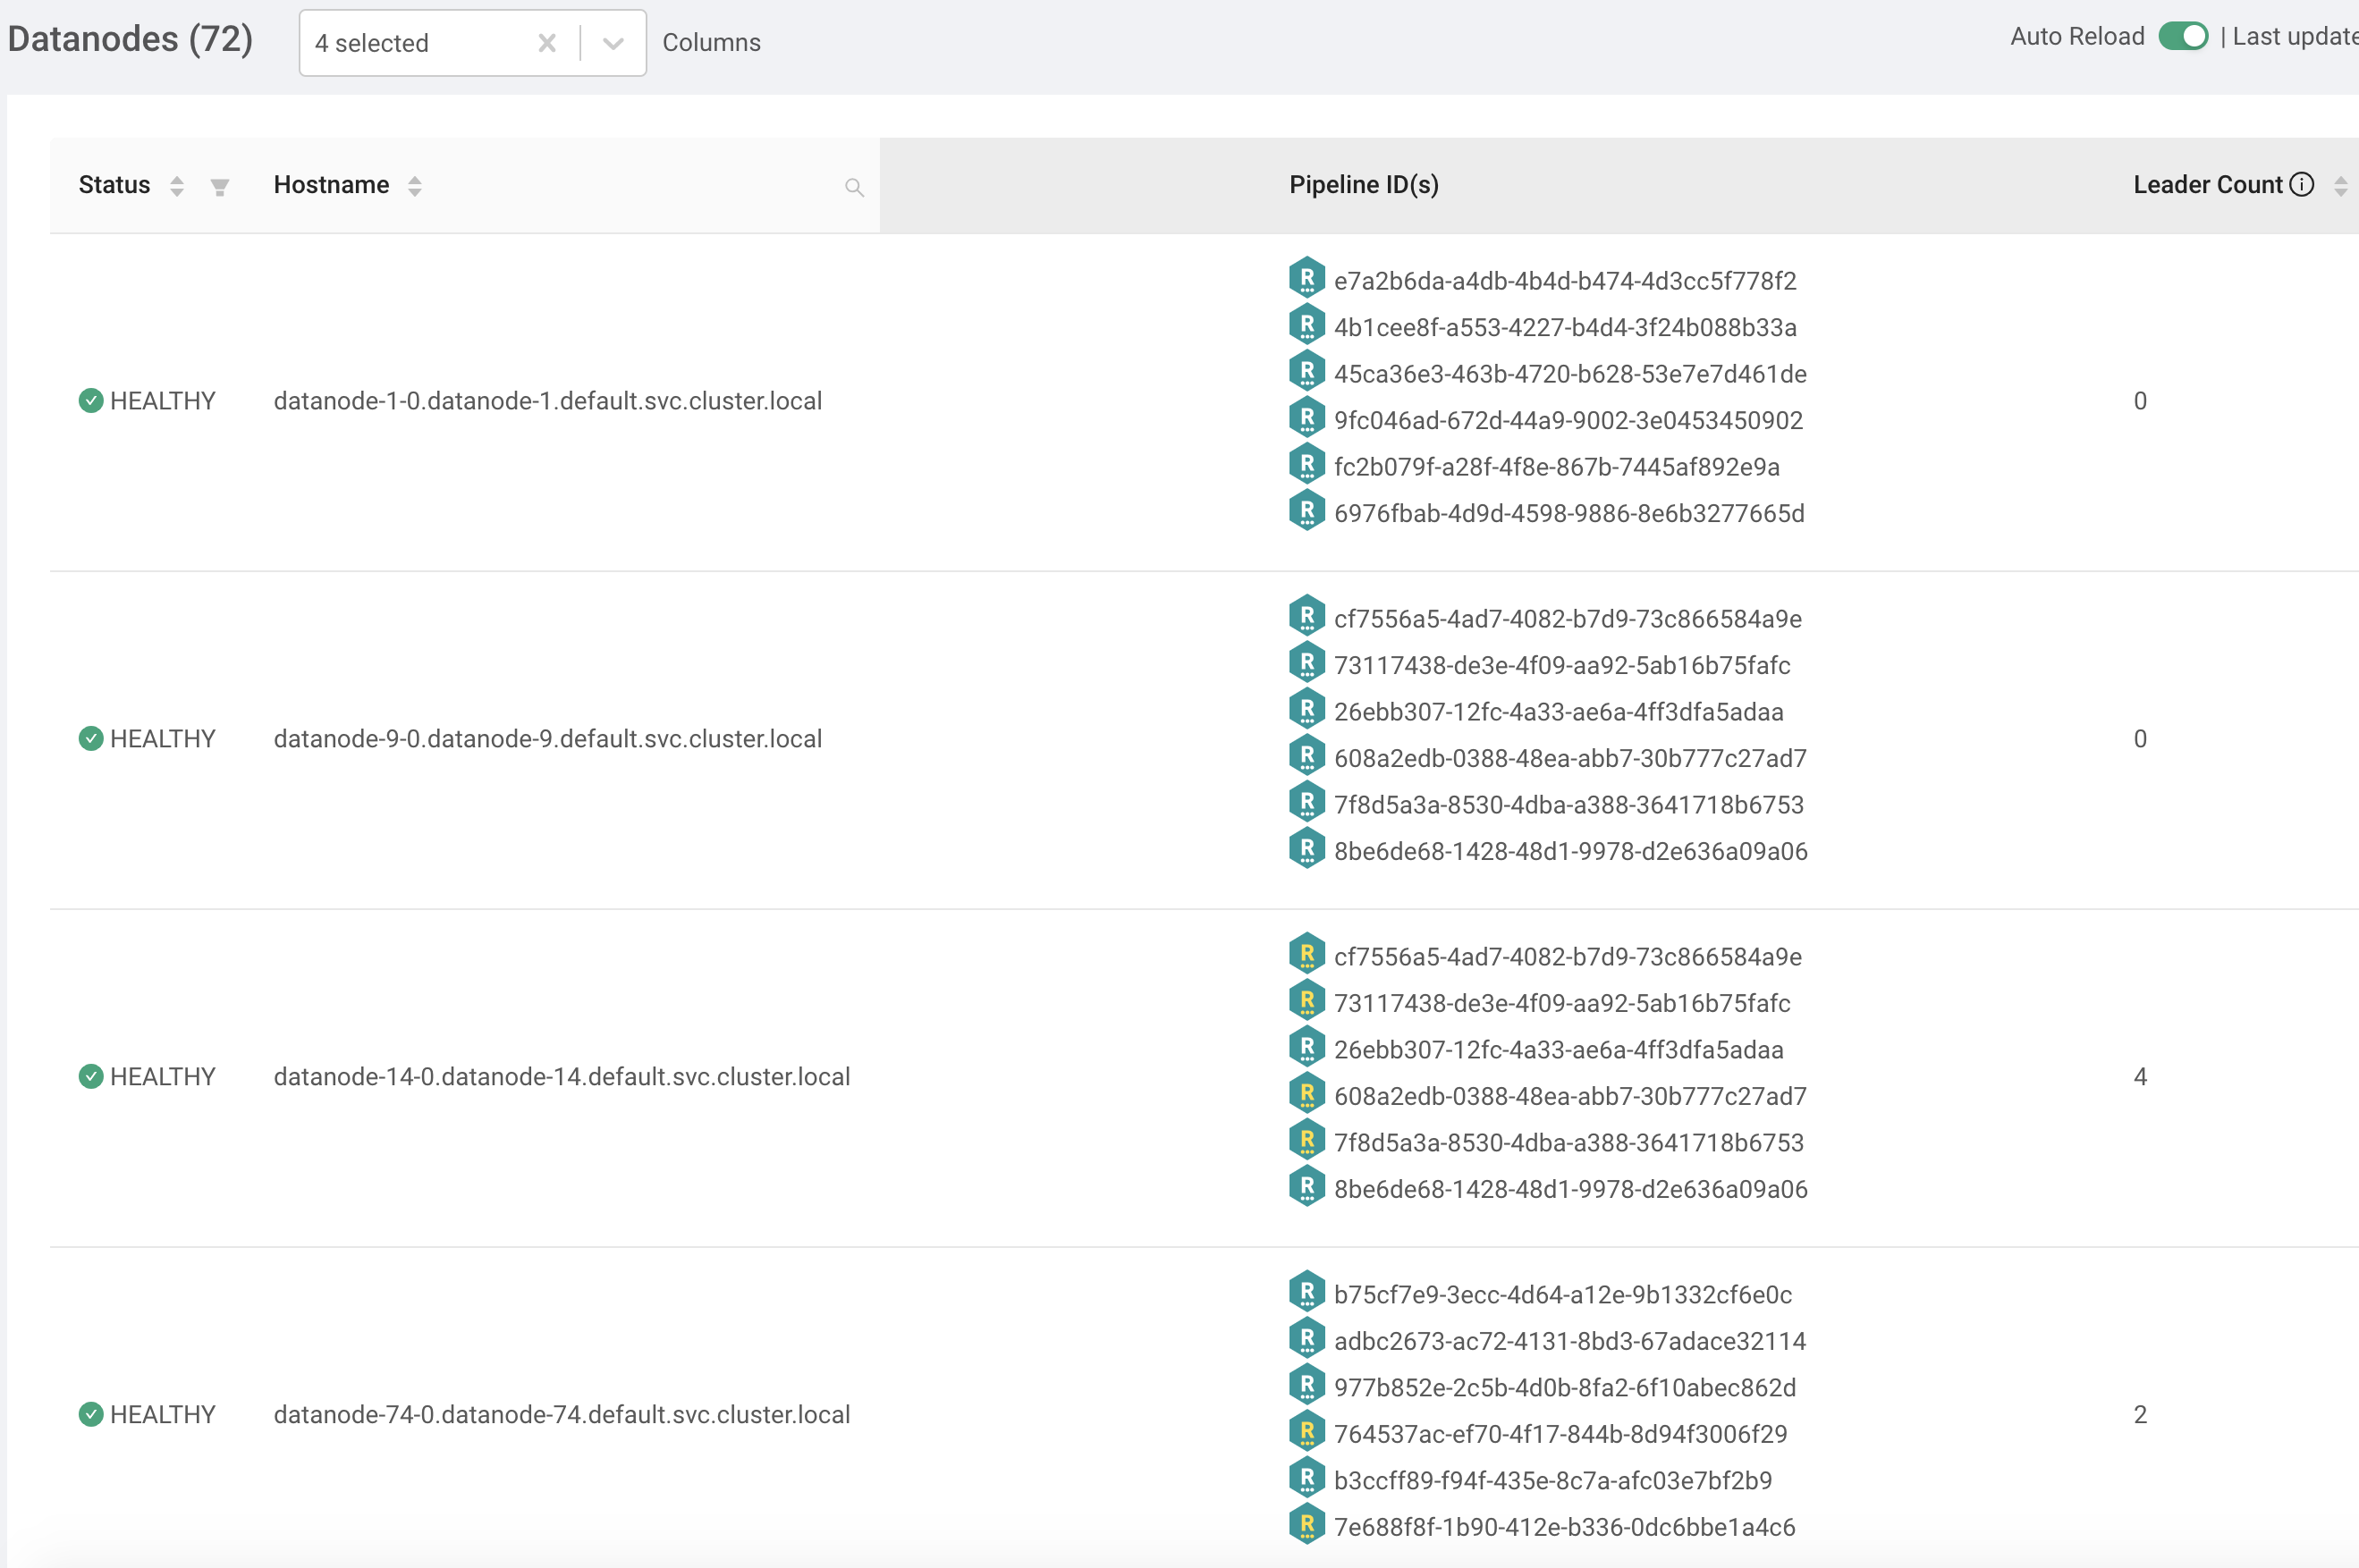
When enable multi-raft, the leader distribution in datanodes is not balance. In my test, there are 72 datanodes, each datanode
engage in 6 pipelines, so there are 144 pipelines. As the image shows, the leader number of the 4 datanodes is 0, 0, 4, 2, it's not balance. Because ratis leader not only accept client request, but also replicate log to 2 followers, and follower only replicate log from leader, so the leader's load is at least 3 times of follower. So we need to balance leader.
**How to improve ?**
With the guidance of @szetszwo , [RATIS-967](https://issues.apache.org/jira/browse/RATIS-967) not only support priority in leader election, but also support lower priority leader try to yield leadership to higher priority peer when higher priority peer's log catch up.
So in ozone
1. assign the suggested leader with higher priority, and 2 followers with lower priority, then we can achieve leader distribution's balance.
2. record the suggested leader count in DatanodeDetails, when create pipeline, choose the datanode with the smallest suggested leader count as the suggested leader.
3. to avoid we lose the suggested leader count in SCM when restart SCM, we also record it in datanode, when scm restart, datanode will report the suggested leader count to SCM.
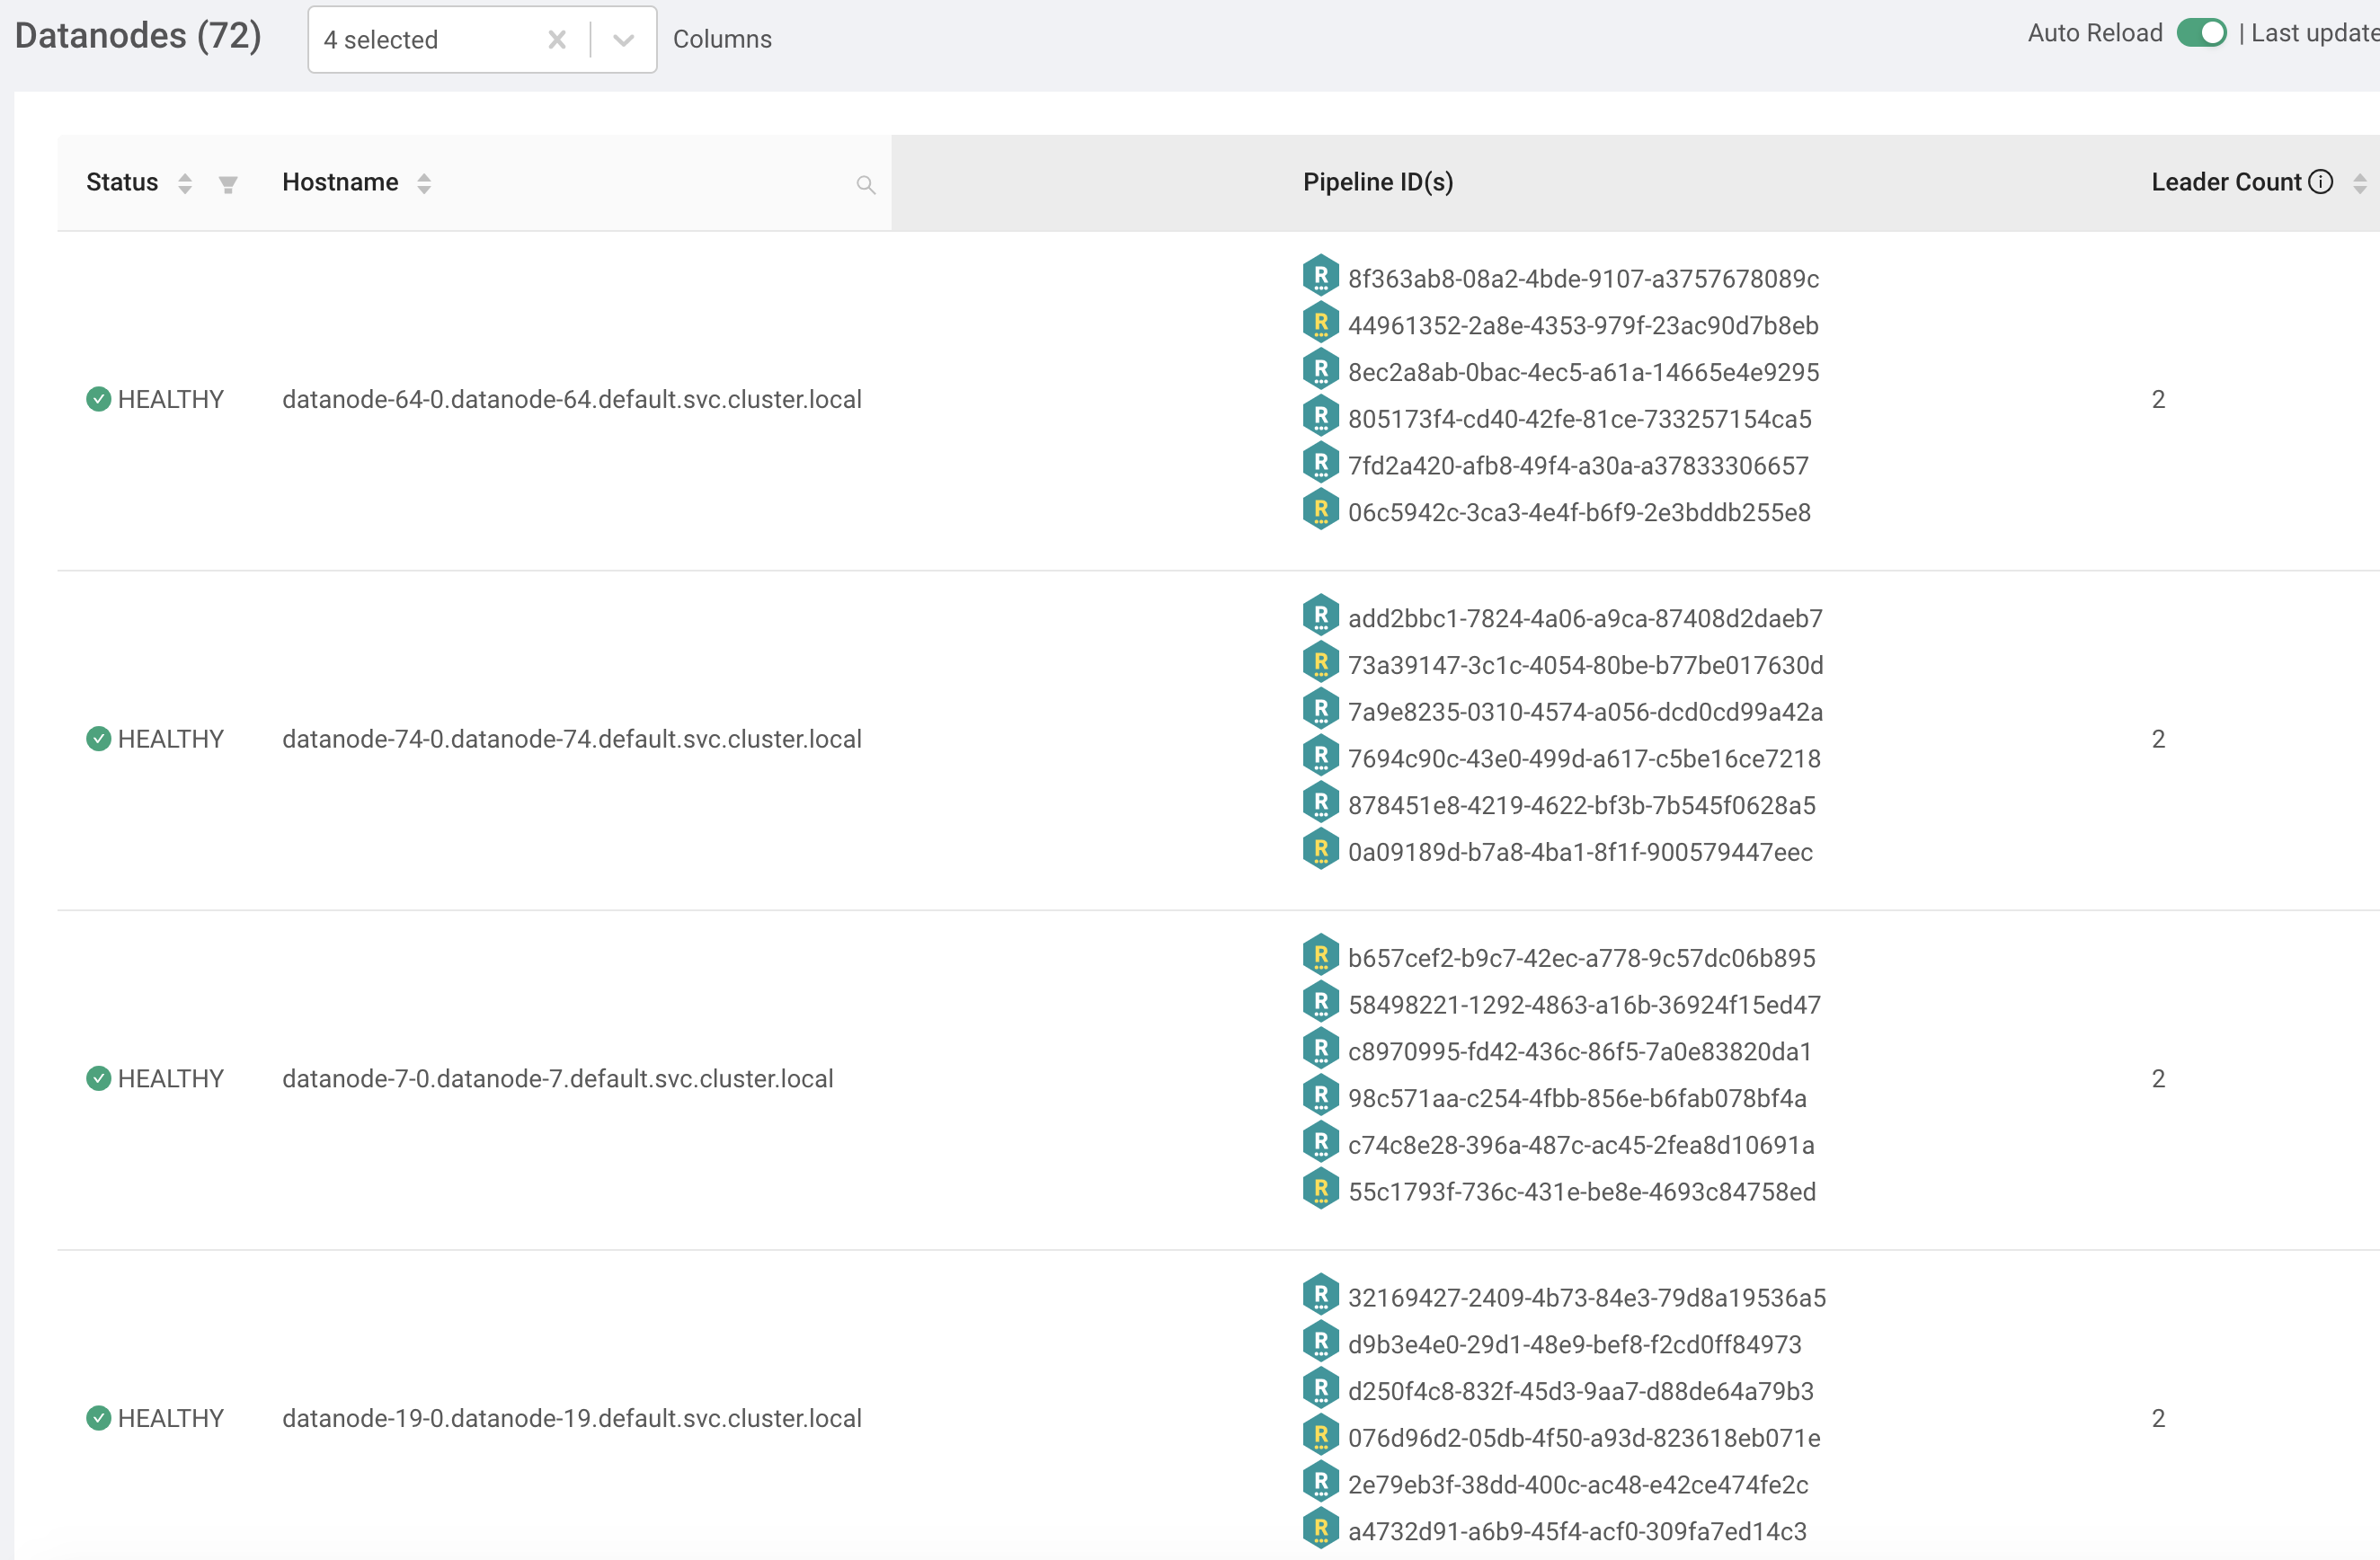
As the following image shows, there are 72 datanodes, each datanode engage in 6 pipelines, so there are 144 pipelines.
The leader count of each datanode is 2, there is no exception, we achieve the leader distribution's balance.
## What is the link to the Apache JIRA
https://issues.apache.org/jira/browse/HDDS-2922
## How was this patch tested?
add new ut.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496643970


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/SCMPipelineManager.java
##########
@@ -619,9 +619,9 @@ private void finalizePipeline(PipelineID pipelineId) throws IOException {
    * @throws IOException
    */
   protected void destroyPipeline(Pipeline pipeline) throws IOException {
-    pipelineFactory.close(pipeline.getType(), pipeline);
     // remove the pipeline from the pipeline manager
     removePipeline(pipeline.getId());
+    pipelineFactory.close(pipeline.getType(), pipeline);

Review comment:
       If did not change,  the order maybe: pipelineFactory.close(pipeline.getType(), pipeline) -> datanode close pipeline -> scm create new pipeline -> removePipeline(pipeline.getId()), then leader distribution will not be balance.
   For example, on server S1, S3, S3, there are 3 pipelines: P1, P2, P3 with leader: S1, S2, S3.
   S1 .. S2 .. S3
   P1 .. P2 .. P3

   If close P3, and order maybe: pipelineFactory.close(pipeline.getType(), P3) -> datanode close P3 -> scm create new pipeline P4 -> removePipeline(P3). When create new pipeline P4, because P3 has not been removed, P4 will choose S1 as the leader, then S1 has 2 leaders, but S3 has no leader.
   S1 .. S2 .. S3
   P1 .. P2
   P4


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] bshashikant commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
bshashikant commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r488543079


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {
+            suggestedLeaderCount.put(dn, suggestedLeaderCount.get(dn) + 1);
+          }
+        } catch (PipelineNotFoundException e) {
+          LOG.debug("Pipeline not found in pipeline state manager : {}",
+              pipelineID, e);
+        }
+      }
+    }
+
+    return suggestedLeaderCount;
+  }
+
+  private DatanodeDetails getSuggestedLeader(List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount =

Review comment:
       I think suggested leader selection can be made a policy driven change.
   1) default policy can be Min leader election count
   2) It can also be driven by factors like memory/resource availability on a datanode
   3) Can be determined by the topology as well. The node nearest to the client can be made the leader .

   Its better to make it a pluggable model like this.

##########
File path: hadoop-ozone/integration-test/src/test/java/org/apache/hadoop/hdds/scm/pipeline/TestRatisPipelineCreateAndDestroy.java
##########
@@ -92,11 +98,128 @@ public void testAutomaticPipelineCreationOnPipelineDestroy()
     waitForPipelines(2);
   }

+  private void checkLeaderBalance(int dnNum, int leaderNumOfEachDn)
+      throws Exception {
+    List<Pipeline> pipelines = pipelineManager
+        .getPipelines(HddsProtos.ReplicationType.RATIS,
+            HddsProtos.ReplicationFactor.THREE, Pipeline.PipelineState.OPEN);
+
+    for (Pipeline pipeline : pipelines) {
+      LambdaTestUtils.await(30000, 500, () ->
+          pipeline.getLeaderId().equals(pipeline.getSuggestedLeaderId()));
+    }
+
+    Map<UUID, Integer> leaderCount = new HashMap<>();
+    for (Pipeline pipeline : pipelines) {
+      UUID leader = pipeline.getLeaderId();
+      if (!leaderCount.containsKey(leader)) {
+        leaderCount.put(leader, 0);
+      }
+
+      leaderCount.put(leader, leaderCount.get(leader) + 1);
+    }
+
+    Assert.assertTrue(leaderCount.size() == dnNum);
+    for (UUID key : leaderCount.keySet()) {
+      Assert.assertTrue(leaderCount.get(key) == leaderNumOfEachDn);
+    }
+  }
+
+  @Test(timeout = 360000)
+  public void testRestoreSuggestedLeader() throws Exception {
+    conf.setBoolean(OZONE_SCM_PIPELINE_AUTO_CREATE_FACTOR_ONE, false);
+    int dnNum = 3;
+    int dnPipelineLimit = 3;
+    int leaderNumOfEachDn = dnPipelineLimit / dnNum;
+    int pipelineNum = 3;
+
+    init(dnNum, dnPipelineLimit);
+    // make sure two pipelines are created
+    waitForPipelines(pipelineNum);
+    // No Factor ONE pipeline is auto created.
+    Assert.assertEquals(0, pipelineManager.getPipelines(
+        HddsProtos.ReplicationType.RATIS,
+        HddsProtos.ReplicationFactor.ONE).size());
+
+    // pipelineNum pipelines in 3 datanodes,
+    // each datanode has leaderNumOfEachDn leaders after balance
+    checkLeaderBalance(dnNum, leaderNumOfEachDn);
+    List<Pipeline> pipelinesBeforeRestart =
+        cluster.getStorageContainerManager().getPipelineManager()
+            .getPipelines();
+
+    cluster.restartStorageContainerManager(true);
+
+    checkLeaderBalance(dnNum, leaderNumOfEachDn);
+    List<Pipeline> pipelinesAfterRestart =
+        cluster.getStorageContainerManager().getPipelineManager()
+            .getPipelines();
+
+    Assert.assertEquals(
+        pipelinesBeforeRestart.size(), pipelinesAfterRestart.size());
+
+    for (Pipeline p : pipelinesBeforeRestart) {
+      boolean equal = false;
+      for (Pipeline q : pipelinesAfterRestart) {
+        if (p.getId().equals(q.getId())
+            && p.getSuggestedLeaderId().equals(q.getSuggestedLeaderId())) {
+          equal = true;
+        }
+      }
+
+      Assert.assertTrue(equal);
+    }
+  }
+
+  @Test(timeout = 360000)
+  public void testPipelineLeaderBalance() throws Exception {
+    conf.setBoolean(OZONE_SCM_PIPELINE_AUTO_CREATE_FACTOR_ONE, false);
+    int dnNum = 3;
+    int dnPipelineLimit = 3;
+    int leaderNumOfEachDn = dnPipelineLimit / dnNum;
+    int pipelineNum = 3;
+
+    init(dnNum, dnPipelineLimit);
+    // make sure two pipelines are created
+    waitForPipelines(pipelineNum);
+    // No Factor ONE pipeline is auto created.
+    Assert.assertEquals(0, pipelineManager.getPipelines(
+        HddsProtos.ReplicationType.RATIS,
+        HddsProtos.ReplicationFactor.ONE).size());
+
+    // pipelineNum pipelines in 3 datanodes,
+    // each datanode has leaderNumOfEachDn leaders after balance
+    checkLeaderBalance(dnNum, leaderNumOfEachDn);
+
+    //cluster.restartStorageContainerManager(true);

Review comment:
       can we remove this commented out lines?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-708327004


   @xiaoyuyao Could you help merge this patch ? Thanks a lot.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] GlenGeng commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
GlenGeng commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496496531


##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java
##########
@@ -48,16 +52,37 @@ public CreatePipelineCommand(final PipelineID pipelineID,
     this.factor = factor;
     this.type = type;
     this.nodelist = datanodeList;
+    if (datanodeList.size() ==
+        XceiverServerRatis.DEFAULT_PRIORITY_LIST.size()) {

Review comment:
       just forward to the Ctor with `priorityList `.

   ```
   this(pipelineID, factor, type, datanodeList,
       new ArrayList<>(Collections.nCopies(datanodeList.size(), 0))
   ```

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +115,28 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  @VisibleForTesting
+  public LeaderChoosePolicy getLeaderChoosePolicy() {
+    return leaderChoosePolicy;
+  }
+  private List<Integer> getPriorityList(
+      List<DatanodeDetails> dns, DatanodeDetails suggestedLeader) {
+    List<Integer> priorityList = new ArrayList<>();
+
+    for (DatanodeDetails dn : dns) {
+      if (dn.getUuid().equals(suggestedLeader.getUuid())) {

Review comment:
       why not use `DatanodeDetails.equals()` ?

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/PipelineStateManager.java
##########
@@ -59,7 +59,8 @@ void addContainerToPipeline(PipelineID pipelineId, ContainerID containerID)
     pipelineStateMap.addContainerToPipeline(pipelineId, containerID);
   }

-  Pipeline getPipeline(PipelineID pipelineID) throws PipelineNotFoundException {
+  public Pipeline getPipeline(PipelineID pipelineID)

Review comment:
       revert unnecessary change.

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/SCMPipelineManager.java
##########
@@ -619,9 +619,9 @@ private void finalizePipeline(PipelineID pipelineId) throws IOException {
    * @throws IOException
    */
   protected void destroyPipeline(Pipeline pipeline) throws IOException {
-    pipelineFactory.close(pipeline.getType(), pipeline);
     // remove the pipeline from the pipeline manager
     removePipeline(pipeline.getId());
+    pipelineFactory.close(pipeline.getType(), pipeline);

Review comment:
       why need this change ?  The sequence of sending SCMCommand and removing state may affect SCM HA.

##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java
##########
@@ -39,6 +42,7 @@
   private final ReplicationFactor factor;
   private final ReplicationType type;
   private final List<DatanodeDetails> nodelist;
+  private final List<Integer> priorityList;

Review comment:
       I consider that, should move `RatisPipelineProvider.getPriorityList()`, `HIGH_PRIORITY`, `LOW_PRIORITY` here, and replace priorityList in Ctor param as suggestedLeader.
   We can minimize the existence of `priorityList`.

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -121,18 +158,24 @@ public Pipeline create(ReplicationFactor factor) throws IOException {
       throw new IllegalStateException("Unknown factor: " + factor.name());
     }

+    DatanodeDetails suggestedLeader = leaderChoosePolicy.chooseLeader(

Review comment:
       make node manager and pipeline manager be member of leaderChoosePolicy, so that leaderChoosePolicy can has it own state, which will make future extension easier.

##########
File path: hadoop-hdds/common/src/main/java/org/apache/hadoop/hdds/scm/pipeline/Pipeline.java
##########
@@ -123,6 +126,15 @@ public Instant getCreationTimestamp() {
     return creationTimestamp;
   }

+  /**
+   * Return the suggested leaderId with high priority of pipeline.

Review comment:
       Return the suggested leaderId which has a high priority among DNs of the pipeline.

##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/container/common/transport/server/ratis/XceiverServerRatis.java
##########
@@ -115,6 +116,9 @@
   private static final Logger LOG = LoggerFactory
       .getLogger(XceiverServerRatis.class);
   private static final AtomicLong CALL_ID_COUNTER = new AtomicLong();
+  public static final List<Integer> DEFAULT_PRIORITY_LIST =

Review comment:
       why we need this `DEFAULT_PRIORITY_LIST` ?
   At all the locations it appears, it dn number does not equal to it, you always create a new list.
   Suggest to remove this static var.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] bshashikant commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
bshashikant commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r488543079


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {
+            suggestedLeaderCount.put(dn, suggestedLeaderCount.get(dn) + 1);
+          }
+        } catch (PipelineNotFoundException e) {
+          LOG.debug("Pipeline not found in pipeline state manager : {}",
+              pipelineID, e);
+        }
+      }
+    }
+
+    return suggestedLeaderCount;
+  }
+
+  private DatanodeDetails getSuggestedLeader(List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount =

Review comment:
       I think suggested leader selection can be made a policy driven change.
   1) default policy can be Min leader election count
   2) It can also be driven by factors like memory/resource availability on a datanode
   3) Can be determined by the topology as well. The node nearest to the client can be made the leader .

   Its better to make it a pluggable model like this.

##########
File path: hadoop-ozone/integration-test/src/test/java/org/apache/hadoop/hdds/scm/pipeline/TestRatisPipelineCreateAndDestroy.java
##########
@@ -92,11 +98,128 @@ public void testAutomaticPipelineCreationOnPipelineDestroy()
     waitForPipelines(2);
   }

+  private void checkLeaderBalance(int dnNum, int leaderNumOfEachDn)
+      throws Exception {
+    List<Pipeline> pipelines = pipelineManager
+        .getPipelines(HddsProtos.ReplicationType.RATIS,
+            HddsProtos.ReplicationFactor.THREE, Pipeline.PipelineState.OPEN);
+
+    for (Pipeline pipeline : pipelines) {
+      LambdaTestUtils.await(30000, 500, () ->
+          pipeline.getLeaderId().equals(pipeline.getSuggestedLeaderId()));
+    }
+
+    Map<UUID, Integer> leaderCount = new HashMap<>();
+    for (Pipeline pipeline : pipelines) {
+      UUID leader = pipeline.getLeaderId();
+      if (!leaderCount.containsKey(leader)) {
+        leaderCount.put(leader, 0);
+      }
+
+      leaderCount.put(leader, leaderCount.get(leader) + 1);
+    }
+
+    Assert.assertTrue(leaderCount.size() == dnNum);
+    for (UUID key : leaderCount.keySet()) {
+      Assert.assertTrue(leaderCount.get(key) == leaderNumOfEachDn);
+    }
+  }
+
+  @Test(timeout = 360000)
+  public void testRestoreSuggestedLeader() throws Exception {
+    conf.setBoolean(OZONE_SCM_PIPELINE_AUTO_CREATE_FACTOR_ONE, false);
+    int dnNum = 3;
+    int dnPipelineLimit = 3;
+    int leaderNumOfEachDn = dnPipelineLimit / dnNum;
+    int pipelineNum = 3;
+
+    init(dnNum, dnPipelineLimit);
+    // make sure two pipelines are created
+    waitForPipelines(pipelineNum);
+    // No Factor ONE pipeline is auto created.
+    Assert.assertEquals(0, pipelineManager.getPipelines(
+        HddsProtos.ReplicationType.RATIS,
+        HddsProtos.ReplicationFactor.ONE).size());
+
+    // pipelineNum pipelines in 3 datanodes,
+    // each datanode has leaderNumOfEachDn leaders after balance
+    checkLeaderBalance(dnNum, leaderNumOfEachDn);
+    List<Pipeline> pipelinesBeforeRestart =
+        cluster.getStorageContainerManager().getPipelineManager()
+            .getPipelines();
+
+    cluster.restartStorageContainerManager(true);
+
+    checkLeaderBalance(dnNum, leaderNumOfEachDn);
+    List<Pipeline> pipelinesAfterRestart =
+        cluster.getStorageContainerManager().getPipelineManager()
+            .getPipelines();
+
+    Assert.assertEquals(
+        pipelinesBeforeRestart.size(), pipelinesAfterRestart.size());
+
+    for (Pipeline p : pipelinesBeforeRestart) {
+      boolean equal = false;
+      for (Pipeline q : pipelinesAfterRestart) {
+        if (p.getId().equals(q.getId())
+            && p.getSuggestedLeaderId().equals(q.getSuggestedLeaderId())) {
+          equal = true;
+        }
+      }
+
+      Assert.assertTrue(equal);
+    }
+  }
+
+  @Test(timeout = 360000)
+  public void testPipelineLeaderBalance() throws Exception {
+    conf.setBoolean(OZONE_SCM_PIPELINE_AUTO_CREATE_FACTOR_ONE, false);
+    int dnNum = 3;
+    int dnPipelineLimit = 3;
+    int leaderNumOfEachDn = dnPipelineLimit / dnNum;
+    int pipelineNum = 3;
+
+    init(dnNum, dnPipelineLimit);
+    // make sure two pipelines are created
+    waitForPipelines(pipelineNum);
+    // No Factor ONE pipeline is auto created.
+    Assert.assertEquals(0, pipelineManager.getPipelines(
+        HddsProtos.ReplicationType.RATIS,
+        HddsProtos.ReplicationFactor.ONE).size());
+
+    // pipelineNum pipelines in 3 datanodes,
+    // each datanode has leaderNumOfEachDn leaders after balance
+    checkLeaderBalance(dnNum, leaderNumOfEachDn);
+
+    //cluster.restartStorageContainerManager(true);

Review comment:
       can we remove this commented out lines?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704986134


   > > @bshashikant Thanks for suggestions. Actually, RandomLeaderChoosePolicy does not choose datanode, it return null in [chooseLeader](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/leader/choose/algorithms/RandomLeaderChoosePolicy.java#L40), then all the datanodes are assigned the [same priority](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java#L60), as what is currently. The name of RandomLeaderChoosePolicy seems confused, sorry for the misleading, do you have better name?
   >
   > i guess , this can be named as "DefaultLeaderChoosePolicy" and this should be made the default , until and unless we measure the performance with the minimumLeader election count policy and see the results. What do you think?

   @bshashikant I agree. I have updated the patch.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  S2  S3
   P1 P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1  S2  S3
   .....P2   P1
    ...........P3.

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496627193


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -121,18 +158,24 @@ public Pipeline create(ReplicationFactor factor) throws IOException {
       throw new IllegalStateException("Unknown factor: " + factor.name());
     }

+    DatanodeDetails suggestedLeader = leaderChoosePolicy.chooseLeader(

Review comment:
       LeaderChoosePolicy is an interface, define member in interface is not common.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  S2  S3
   P1 P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1  S2  S3
        P2   P1
               P3.

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] GlenGeng commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
GlenGeng commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r486090313


##########
File path: hadoop-hdds/common/src/main/java/org/apache/hadoop/hdds/ratis/RatisHelper.java
##########
@@ -125,6 +131,17 @@ private static RaftGroup newRaftGroup(Collection<RaftPeer> peers) {
         : RaftGroup.valueOf(DUMMY_GROUP_ID, peers);
   }

+  public static RaftGroup newRaftGroup(RaftGroupId groupId,
+      List<DatanodeDetails> peers, List<Integer> priorityList) {
+    final List<RaftPeer> newPeers = new ArrayList<>();

Review comment:
       sanity check for `peers.size() == priorityList.size()`

##########
File path: hadoop-hdds/common/src/main/java/org/apache/hadoop/hdds/protocol/DatanodeDetails.java
##########
@@ -190,6 +195,18 @@ public Port getPort(Port.Name name) {
     return null;
   }

+  public int getSuggestedLeaderCount() {

Review comment:
       miss java doc for these public method.

##########
File path: hadoop-hdds/common/src/main/java/org/apache/hadoop/hdds/scm/pipeline/Pipeline.java
##########
@@ -123,6 +124,14 @@ public Instant getCreationTimestamp() {
     return creationTimestamp;
   }

+  public void setSuggestedLeader(UUID suggestedLeader) {

Review comment:
       miss java doc for public method.

   Why not set suggestedLeader in Ctor and remove the getter/setter ? I guess, it would be final/immutable after creating, just like type/factor.

##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java
##########
@@ -48,16 +50,34 @@ public CreatePipelineCommand(final PipelineID pipelineID,
     this.factor = factor;
     this.type = type;
     this.nodelist = datanodeList;
+    this.priorityList = new ArrayList<>();
+    for (DatanodeDetails dn : datanodeList) {

Review comment:
       ditto

##########
File path: hadoop-hdds/common/src/main/java/org/apache/hadoop/hdds/scm/pipeline/Pipeline.java
##########
@@ -61,6 +61,7 @@
   private UUID leaderId;
   // Timestamp for pipeline upon creation
   private Instant creationTimestamp;
+  private UUID suggestedLeader;

Review comment:
       how about suggestedLeaderId ?

##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/container/common/statemachine/commandhandler/CreatePipelineCommandHandler.java
##########
@@ -82,18 +104,22 @@ public void handle(SCMCommand command, OzoneContainer ozoneContainer,
     final CreatePipelineCommandProto createCommand =
         ((CreatePipelineCommand)command).getProto();
     final HddsProtos.PipelineID pipelineID = createCommand.getPipelineID();
-    final Collection<DatanodeDetails> peers =
+    final List<DatanodeDetails> peers =
         createCommand.getDatanodeList().stream()
             .map(DatanodeDetails::getFromProtoBuf)
             .collect(Collectors.toList());
+    final List<Integer> priorityList = createCommand.getPriorityList();
+
+    incSuggestedLeaderCount(priorityList, peers, dn);

Review comment:
       increase the counter after successfully created the pipeline ? Might throw exception during the creation.

##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/container/common/transport/server/ratis/XceiverServerRatis.java
##########
@@ -711,10 +711,23 @@ private long calculatePipelineBytesWritten(HddsProtos.PipelineID pipelineID) {

   @Override
   public void addGroup(HddsProtos.PipelineID pipelineId,
-      Collection<DatanodeDetails> peers) throws IOException {
+      List<DatanodeDetails> peers) throws IOException {
+    List<Integer> priorityList = new ArrayList<>();

Review comment:
       ``
   List<Integer> priorityList = new ArrayList<>(peers.size());
   for (...)
   ``

   so that won't be bothered by unused var `dn`

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +102,40 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private DatanodeDetails getSuggestedLeader(List<DatanodeDetails> dns) {
+    int minLeaderCount = Integer.MAX_VALUE;
+    DatanodeDetails suggestedLeader = null;
+
+    for (int i = 0; i < dns.size(); i++) {

Review comment:
       as suggested by idea, range for
   `for (dn : dns)`


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489833136


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       [RATIS-967](https://issues.apache.org/jira/browse/RATIS-967) guarantee the highpriority node act as leader when create pipeline. In a long running cluster, the leader maybe crash, then some follower will take the leadership, but when the old leader restart and catch up with current leader's log, the old leader can grab the leadership again by [RATIS-967](https://issues.apache.org/jira/browse/RATIS-967).

   So let me suppose the following case, there are 3 servers: s1, s2, s3, there are 2 pipelines now,  the first pipeline's leader is s1, the second pipeline's leader is s2, both the 2 leaders are suggested leader with high priority. Then s1 crash, suppose s3 will take the first pipline's leader.  Then s1 restart, but has not grab leadership of the first pipeline. If we use getLeaderId() instead of getSuggestedLeaderId() to reflect the actual leader count, when we create the 3 third pipeline, we find the leader number on s1, s2, s3 is 0, 1, 1, so we will select s1 as the suggest leader,  then s1 grab the leadership of the first pipeline by [RATIS-967](https://issues.apache.org/jira/browse/RATIS-967), so the leader number on s1, s2, s3 will be 2, 1, 0, it's not balance.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489826433


##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/container/common/transport/server/ratis/XceiverServerRatis.java
##########
@@ -711,10 +712,20 @@ private long calculatePipelineBytesWritten(HddsProtos.PipelineID pipelineID) {

   @Override
   public void addGroup(HddsProtos.PipelineID pipelineId,
-      Collection<DatanodeDetails> peers) throws IOException {
+      List<DatanodeDetails> peers) throws IOException {
+    List<Integer> priorityList =

Review comment:
       Updated


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] xiaoyuyao commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
xiaoyuyao commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490666872


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       bq.  then s1 grab the leadership of the first pipeline by RATIS-967,

   Does RATIS-967 always gives up its leader when s1 is back online even the current leader works fine? I think this is more specific to RATIS-967 wrt. how the priority is enforced. Any performance impact on the pipeline of forcing leader to be the original one?

   I'm thinking of instead of forcing leader of pipeline P1, P2, P3 like
   S1   S2   S3
   P1   P2
                 P3

   In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?
   S1   S2   S3
          P2
                 P1
   P3

   Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489833136


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       [RATIS-967](https://issues.apache.org/jira/browse/RATIS-967) guarantee the highpriority node act as leader when create pipeline. In a long running cluster, the leader maybe crash, then some follower will take the leadership, but when the old leader restart and catch up with current leader's log, the old leader can grab the leadership again by [RATIS-967](https://issues.apache.org/jira/browse/RATIS-967).

   So let me suppose the following case, there are 3 servers: s1, s2, s3, there are 2 pipelines now,  the first pipeline's leader is s1, the second pipeline's leader is s2, both the 2 leaders are suggested leader with high priority. Then s1 crash, suppose s3 will take the first pipline's leader.  Then s1 restart, but has not grab leadership of the first pipeline. If we use getLeaderId() instead of getSuggestedLeaderId() to reflect the actual leader count, when we create the 3 third pipeline, we find the leader number on s1, s2, s3 is 0, 1, 1, so we will select s1 as the suggest leader,  then s1 grab the leadership of the first pipeline, so the leader number on s1, s2, s3 will be 2, 1, 0, it's not balance.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] ChenSammi commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
ChenSammi commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-711494972


   LGTM + 1.

   Thanks @runzhiwang for the contribution and @bshashikant @xiaoyuyao @GlenGeng for the review.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-693743559


   @xiaoyuyao Thanks for review. I have updated the patch.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-700470083


   @xiaoyuyao @bshashikant  I have updated the patch. Could you help review it again ? Thank you very much.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] GlenGeng commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
GlenGeng commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-707094391


   +1
   Thanks for the work! LGTM


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704131953


   @GlenGeng @bshashikant  Thanks for review. I have updated the patch.

   `Can we also make the policy configurable? Also, one policy should also be defined for no priority at all incase, this turns out to be a performance killer.`

   policy can be configured by `ozone.scm.pipeline.leader-choose.policy`. And define a policy for no priority named `RandomLeaderChoosePolicy`


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496643970


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/SCMPipelineManager.java
##########
@@ -619,9 +619,9 @@ private void finalizePipeline(PipelineID pipelineId) throws IOException {
    * @throws IOException
    */
   protected void destroyPipeline(Pipeline pipeline) throws IOException {
-    pipelineFactory.close(pipeline.getType(), pipeline);
     // remove the pipeline from the pipeline manager
     removePipeline(pipeline.getId());
+    pipelineFactory.close(pipeline.getType(), pipeline);

Review comment:
       If did not change,  the order maybe: pipelineFactory.close(pipeline.getType(), pipeline) -> datanode close pipeline -> scm create new pipeline -> removePipeline(pipeline.getId()), then leader distribution will not be balance.
   For example, on server S1, S3, S3, there are 3 pipelines: P1, P2, P3 with leader: S1, S2, S3.
   S1 .. S2 .. S3
   P1 .. P2 .. P3

   If close P3, and order maybe: pipelineFactory.close(pipeline.getType(), P3) -> datanode close P3 -> scm create new pipeline P4 -> removePipeline(P3). When create new pipeline P4, because P3 has not been removed, P4 will choose S1 as the leader, finally S1 has 2 leaders, but S3 has no leader.
   S1 .. S2 .. S3
   P1 .. P2
   P4


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] xiaoyuyao commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
xiaoyuyao commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492218302


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       Good point, planed leader distribution should work with RATIS-967. How do we scale with this. Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] bshashikant commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
bshashikant commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704702172


   > @bshashikant Thanks for suggestions. Actually, RandomLeaderChoosePolicy does not choose datanode, it return null in [chooseLeader](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/leader/choose/algorithms/RandomLeaderChoosePolicy.java#L40), then all the datanodes are assigned the [same priority](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java#L60), as what is currently. The name of RandomLeaderChoosePolicy seems confused, sorry for the misleading, do you have better name?

   i guess , this can be named as "DefaultLeaderChoosePolicy" and this should be made the default , until and unless we measure the performance with the minimumLeader election count policy and see the results.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489826760


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {
+            suggestedLeaderCount.put(dn, suggestedLeaderCount.get(dn) + 1);
+          }
+        } catch (PipelineNotFoundException e) {
+          LOG.debug("Pipeline not found in pipeline state manager : {}",
+              pipelineID, e);
+        }
+      }
+    }
+
+    return suggestedLeaderCount;
+  }
+
+  private DatanodeDetails getSuggestedLeader(List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount =
+        getSuggestedLeaderCount(dns);
+    int minLeaderCount = Integer.MAX_VALUE;
+    DatanodeDetails suggestedLeader = null;
+
+    for (Map.Entry<DatanodeDetails, Integer> entry :
+        suggestedLeaderCount.entrySet()) {
+      if (entry.getValue() < minLeaderCount) {
+        minLeaderCount = entry.getValue();
+        suggestedLeader = entry.getKey();
+      }
+    }
+
+    return suggestedLeader;
+  }
+
+  private List<Integer> getPriorityList(
+      List<DatanodeDetails> dns, DatanodeDetails suggestedLeader) {
+    List<Integer> priorityList = new ArrayList<>();
+
+    for (DatanodeDetails dn : dns) {
+      if (dn.getUuid().equals(suggestedLeader.getUuid())) {
+        priorityList.add(HIGH_PRIORITY);

Review comment:
       Yes, [RATIS-967](https://issues.apache.org/jira/browse/RATIS-967) guarantee the highpriority node act as leader


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  ..  S2 ..   S3
   P1  ..  P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1 .. S2 .. S3
   .......P2 ..  P1
   ..............P3

   It's not balance now.

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  ..  S2 ..   S3
   P1  ..  P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1 .. S2 .. S3
   .......P2 ..  P1
   ...............P3

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496628148


##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/container/common/transport/server/ratis/XceiverServerRatis.java
##########
@@ -115,6 +116,9 @@
   private static final Logger LOG = LoggerFactory
       .getLogger(XceiverServerRatis.class);
   private static final AtomicLong CALL_ID_COUNTER = new AtomicLong();
+  public static final List<Integer> DEFAULT_PRIORITY_LIST =

Review comment:
       why always create a new list ? The size of DEFAULT_PRIORITY_LIST is 3, most case the size of datanode list is 3, their size are equal.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-690911218


   @GlenGeng Thanks for review, I have updated the patch.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496628424


##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java
##########
@@ -48,16 +52,37 @@ public CreatePipelineCommand(final PipelineID pipelineID,
     this.factor = factor;
     this.type = type;
     this.nodelist = datanodeList;
+    if (datanodeList.size() ==
+        XceiverServerRatis.DEFAULT_PRIORITY_LIST.size()) {

Review comment:
       always new is a waste.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] bshashikant commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
bshashikant commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-703565884


   Can we also make the policy configurable? Also, one policy should also be defined for no priority at all incase, this turns out to be a performance killer.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  ..  S2 ..   S3
   P1  ..  P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1 .. S2 .. S3
   ........P2 ..  P1
   ...............P3

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492416925


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] GlenGeng commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
GlenGeng commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496533516


##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java
##########
@@ -39,6 +42,7 @@
   private final ReplicationFactor factor;
   private final ReplicationType type;
   private final List<DatanodeDetails> nodelist;
+  private final List<Integer> priorityList;

Review comment:
       I consider that, should move `RatisPipelineProvider.getPriorityList()`, `HIGH_PRIORITY`, `LOW_PRIORITY` here, and replace priorityList in Ctor param as suggestedLeader.
   We can minimize the existence of `priorityList`, and the calculation logic of priority in `RatisPipelineProvider` is a little bit weird.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] xiaoyuyao commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
xiaoyuyao commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489780674


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {
+            suggestedLeaderCount.put(dn, suggestedLeaderCount.get(dn) + 1);
+          }
+        } catch (PipelineNotFoundException e) {
+          LOG.debug("Pipeline not found in pipeline state manager : {}",
+              pipelineID, e);
+        }
+      }
+    }
+
+    return suggestedLeaderCount;
+  }
+
+  private DatanodeDetails getSuggestedLeader(List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount =
+        getSuggestedLeaderCount(dns);
+    int minLeaderCount = Integer.MAX_VALUE;
+    DatanodeDetails suggestedLeader = null;
+
+    for (Map.Entry<DatanodeDetails, Integer> entry :
+        suggestedLeaderCount.entrySet()) {
+      if (entry.getValue() < minLeaderCount) {
+        minLeaderCount = entry.getValue();
+        suggestedLeader = entry.getKey();
+      }
+    }
+
+    return suggestedLeader;
+  }
+
+  private List<Integer> getPriorityList(
+      List<DatanodeDetails> dns, DatanodeDetails suggestedLeader) {
+    List<Integer> priorityList = new ArrayList<>();
+
+    for (DatanodeDetails dn : dns) {
+      if (dn.getUuid().equals(suggestedLeader.getUuid())) {
+        priorityList.add(HIGH_PRIORITY);

Review comment:
       Does Ratis have guarantee to have the highpriority node act as leader?

##########
File path: hadoop-ozone/integration-test/src/test/java/org/apache/hadoop/ozone/TestMiniOzoneCluster.java
##########
@@ -102,7 +102,7 @@ public static void afterClass() {
     FileUtils.deleteQuietly(READ_TMP);
   }

-  @Test(timeout = 30000)
+  @Test(timeout = 60000)

Review comment:
       Does the new logic cause more timeout without increasing this?

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       And the method name can be changed to getLeaderCount() so that the suggest leader is determined by the actual leader count.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-711495208


   @ChenSammi Thanks for merging it, @bshashikant @xiaoyuyao @GlenGeng Thanks for review.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang edited a comment on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang edited a comment on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704242576


   @bshashikant Thanks for suggestions. Actually, RandomLeaderChoosePolicy does not choose datanode, it return null in [chooseLeader](https://github.com/apache/hadoop-ozone/pull/1371/files#diff-b180475d031c8ef84f96e7d623f11506R40), then all the datanodes are assigned the [same priority](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java#L60), as what is currently.  The name of RandomLeaderChoosePolicy seems confused, sorry for the misleading, do you have better name?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang edited a comment on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang edited a comment on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704242576


   @bshashikant Thanks for suggestions. Actually, RandomLeaderChoosePolicy does not choose datanode, it return null in [chooseLeader](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/leader/choose/algorithms/RandomLeaderChoosePolicy.java#L40), then all the datanodes are assigned the [same priority](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java#L60), as what is currently.  The name of RandomLeaderChoosePolicy seems confused, sorry for the misleading, do you have better name?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] amaliujia commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
amaliujia commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-685181887


   Thanks @runzhiwang. This is an awesome work! I will also try to help review this PR.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492416925


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now.
   If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap. We can change this if there is requirement in the future, but now it is enough to allocate the same leader number in each datanode.


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {
+            suggestedLeaderCount.put(dn, suggestedLeaderCount.get(dn) + 1);
+          }
+        } catch (PipelineNotFoundException e) {
+          LOG.debug("Pipeline not found in pipeline state manager : {}",
+              pipelineID, e);
+        }
+      }
+    }
+
+    return suggestedLeaderCount;
+  }
+
+  private DatanodeDetails getSuggestedLeader(List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount =

Review comment:
       @bshashikant I agree. @xiaoyuyao What do you think of this suggestion?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492416925


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap. We can change this if there is requirement in the future, but now it is enough to allocate the same leader number in each datanode.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  S2  S3
   P1 P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1  S2  S3
   .....P2   P1
   ..........P3.

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492416925


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now.
   If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.

##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap. We can change this if there is requirement in the future, but now it is enough to allocate the same leader number in each datanode.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang closed pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang closed pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492595294


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {
+            suggestedLeaderCount.put(dn, suggestedLeaderCount.get(dn) + 1);
+          }
+        } catch (PipelineNotFoundException e) {
+          LOG.debug("Pipeline not found in pipeline state manager : {}",
+              pipelineID, e);
+        }
+      }
+    }
+
+    return suggestedLeaderCount;
+  }
+
+  private DatanodeDetails getSuggestedLeader(List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount =

Review comment:
       @bshashikant I agree. @xiaoyuyao What do you think of this suggestion?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] bshashikant edited a comment on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
bshashikant edited a comment on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704702172


   > @bshashikant Thanks for suggestions. Actually, RandomLeaderChoosePolicy does not choose datanode, it return null in [chooseLeader](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/leader/choose/algorithms/RandomLeaderChoosePolicy.java#L40), then all the datanodes are assigned the [same priority](https://github.com/apache/hadoop-ozone/blob/f573b4a8b45f4463f0bcb95971a45789bda91d5c/hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/protocol/commands/CreatePipelineCommand.java#L60), as what is currently. The name of RandomLeaderChoosePolicy seems confused, sorry for the misleading, do you have better name?

   i guess , this can be named as "DefaultLeaderChoosePolicy" and this should be made the default , until and unless we measure the performance with the minimumLeader election count policy and see the results. What do you think?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-690911218


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  S2  S3
   P1 P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1  S2  S3
   ......P2   P1
    ............P3.

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] bshashikant commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
bshashikant commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704195949


   > @GlenGeng @bshashikant Thanks for review. I have updated the patch.
   >
   > > Can we also make the policy configurable? Also, one policy should also be defined for no priority at all incase, this turns out to be a performance killer.
   >
   > policy can be configured by `ozone.scm.pipeline.leader-choose.policy`. And define a policy for no priority named `RandomLeaderChoosePolicy`

   @runzhiwang , please correct me if i am wrong. RandomLeaderChoosePolicy still chooses a datanode randomly and this is suggested to Ratis while creating the pipeline.
   With NO_PRIORITY, i meant that, we should not have any recommendation for a leader at all (as what is currently). Usually in such cases, whoever starts the ratis leader election first initially, becomes the leader.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704242576


   @bshashikant Thanks for suggestions. Actually, RandomLeaderChoosePolicy does not choose datanode, it return null in [chooseLeader](https://github.com/apache/hadoop-ozone/pull/1371/files#diff-b180475d031c8ef84f96e7d623f11506R40), then all the datanodes are assigned the [same priority](https://github.com/apache/hadoop-ozone/pull/1371/files#diff-a9f8deba9c990cb9b148008785c8cff2R60), as what is currently.  The name of RandomLeaderChoosePolicy seems confused, sorry for the misleading, do you have better name?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496643970


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/SCMPipelineManager.java
##########
@@ -619,9 +619,9 @@ private void finalizePipeline(PipelineID pipelineId) throws IOException {
    * @throws IOException
    */
   protected void destroyPipeline(Pipeline pipeline) throws IOException {
-    pipelineFactory.close(pipeline.getType(), pipeline);
     // remove the pipeline from the pipeline manager
     removePipeline(pipeline.getId());
+    pipelineFactory.close(pipeline.getType(), pipeline);

Review comment:
       If did not change,  the order maybe: pipelineFactory.close(pipeline.getType(), pipeline) -> datanode close pipeline -> scm create new pipeline -> removePipeline(pipeline.getId()), then leader distribution will not be balance.
   For example, on server S1, S3, S3, there are 3 pipelines: P1, P2, P3 with leader: S1, S2, S3.
   S1 .. S2 .. S3
   P1 .. P2 .. P3

   If close P3, and order maybe: pipelineFactory.close(pipeline.getType(), P3) -> datanode close P3 -> scm create new pipeline P4 -> removePipeline(P3). When create new pipeline P4, because P3 has not been removed, P4 will choose S1 as the leader, finally S1 has 2 leaders, but S3 has no leader.
   S1 .. S2 .. S3
   P1 .. P2
   P4


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489827467


##########
File path: hadoop-ozone/integration-test/src/test/java/org/apache/hadoop/ozone/TestMiniOzoneCluster.java
##########
@@ -102,7 +102,7 @@ public static void afterClass() {
     FileUtils.deleteQuietly(READ_TMP);
   }

-  @Test(timeout = 30000)
+  @Test(timeout = 60000)

Review comment:
       Yes, the highpriority node act as leader will increase the time of leader election,  but almost the increased time is within 10 seconds.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] xiaoyuyao commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
xiaoyuyao commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489771893


##########
File path: hadoop-hdds/container-service/src/main/java/org/apache/hadoop/ozone/container/common/transport/server/ratis/XceiverServerRatis.java
##########
@@ -711,10 +712,20 @@ private long calculatePipelineBytesWritten(HddsProtos.PipelineID pipelineID) {

   @Override
   public void addGroup(HddsProtos.PipelineID pipelineId,
-      Collection<DatanodeDetails> peers) throws IOException {
+      List<DatanodeDetails> peers) throws IOException {
+    List<Integer> priorityList =

Review comment:
       NIT: can we have a static default priority list here?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1    S2    S3
   P1    P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1  S2  S3
   .....P2   P1
   ..........P3

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang edited a comment on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang edited a comment on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-704131953


   @GlenGeng @bshashikant  Thanks for review. I have updated the patch.

   > Can we also make the policy configurable? Also, one policy should also be defined for no priority at all incase, this turns out to be a performance killer.

   policy can be configured by `ozone.scm.pipeline.leader-choose.policy`. And define a policy for no priority named `RandomLeaderChoosePolicy`


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-684160456


   @bshashikant @lokeshj1703 @mukul1987 @elek @xiaoyuyao Could you help review this patch ? Thank you very much.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496627193


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -121,18 +158,24 @@ public Pipeline create(ReplicationFactor factor) throws IOException {
       throw new IllegalStateException("Unknown factor: " + factor.name());
     }

+    DatanodeDetails suggestedLeader = leaderChoosePolicy.chooseLeader(

Review comment:
       LeaderChoosePolicy is an interface, define member in interface is not common.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#issuecomment-690911218


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] xiaoyuyao commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
xiaoyuyao commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r489778062


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       should we use getLeaderId() instead of getSuggestedLeaderId() here to reflect the actual leader count?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492416925


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now. If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492416925


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       > Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.

   If each node has similar hardware, i.e. CPU, memory, we just plan weight as now, assign each node with same leader number, it is cheap and reasonable.

   I think the only case we need to consider is that some nodes' hardware is weaker than other nodes' obviously.  I think the weeker datanodes should engage in less pipeline than the stronger datanodes,  but ozone does not support this now.
   If we can support this, the maxum leader number of each datanode should be less or equal to ((1/3) * the pipeline number it engaged in),  and we select the datanode as the leader which has lowest value of (leader number / pipeline number it engaged in) in 3 datanodes,  this is also cheap.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] ChenSammi merged pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
ChenSammi merged pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] xiaoyuyao commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
xiaoyuyao commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r492218302


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       Good point, planed leader distribution should work with RATIS-967. How do we scale with this. Plan weight for each of node as a leader when the cluster has thousands of nodes can be difficult.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r496624353


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/PipelineStateManager.java
##########
@@ -59,7 +59,8 @@ void addContainerToPipeline(PipelineID pipelineId, ContainerID containerID)
     pipelineStateMap.addContainerToPipeline(pipelineId, containerID);
   }

-  Pipeline getPipeline(PipelineID pipelineID) throws PipelineNotFoundException {
+  public Pipeline getPipeline(PipelineID pipelineID)

Review comment:
       This is necessary, otherwise we can not call `getPipeline` in `MinLeaderCountChoosePolicy`


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  S2  S3
   P1 P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1  S2  S3
   .....P2   P1
   ..........P3

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org
[GitHub] [hadoop-ozone] runzhiwang commented on a change in pull request #1371: HDDS-2922. Balance ratis leader distribution in datanodes
Posted by GitBox <gi...@apache.org>.
runzhiwang commented on a change in pull request #1371:
URL: https://github.com/apache/hadoop-ozone/pull/1371#discussion_r490675374


##########
File path: hadoop-hdds/server-scm/src/main/java/org/apache/hadoop/hdds/scm/pipeline/RatisPipelineProvider.java
##########
@@ -98,8 +105,65 @@ private boolean exceedPipelineNumberLimit(ReplicationFactor factor) {
     return false;
   }

+  private Map<DatanodeDetails, Integer> getSuggestedLeaderCount(
+      List<DatanodeDetails> dns) {
+    Map<DatanodeDetails, Integer> suggestedLeaderCount = new HashMap<>();
+    for (DatanodeDetails dn : dns) {
+      suggestedLeaderCount.put(dn, 0);
+
+      Set<PipelineID> pipelineIDSet = getNodeManager().getPipelines(dn);
+      for (PipelineID pipelineID : pipelineIDSet) {
+        try {
+          Pipeline pipeline = getPipelineStateManager().getPipeline(pipelineID);
+          if (!pipeline.isClosed()
+              && dn.getUuid().equals(pipeline.getSuggestedLeaderId())) {

Review comment:
       @xiaoyuyao Good point, I also have thought this.

   > Any performance impact on the pipeline of forcing leader to be the original one.

   If there is performance problem, I can improve forcing leader change within 1 second. I already know how to improve it, but has not implemented it.

   > Another situation I'm thinking of is writers on pipeline with slow leader(e.g., hardware slowness) may not be able to recover by leader change.

   We can find slow leader by some metric, decrease the priority of the slow leader, select one faster datanode and increase it's priority, so the faster datanode will grab the leadership from the slow leader.


   > In the case of S1 temporarily down, why don't we keep P1 leader on S3 and create P3 with leader on S1, this gives more flexibility for higher level to choose leader?

   I want the cluster leader distribution as we planned, if the plan is not appropriate, we can adjust the plan by change priority.

   If the leader distribution totally depends on hardware rather than plan, we maybe lost control of the leader distribution. Because the leaderId in scm was reported by datanode, it maybe a delayed leaderId. For example, datanode report:

   S1  ..  S2 ..   S3
   P1  ..  P2

   then P1's leader transfer to S3, but SCM has not received this report, SCM allocate P3's leader to S3, then

   S1 .. S2 .. S3
   .......P2 ..  P1
   ............P3

   It's not balance now.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: ozone-issues-unsubscribe@hadoop.apache.org
For additional commands, e-mail: ozone-issues-help@hadoop.apache.org