You are viewing a plain text version of this content. The canonical link for it is here.
Posted to reviews@spark.apache.org by GitBox <gi...@apache.org> on 2021/05/27 02:29:00 UTC
[GitHub] [spark] ulysses-you opened a new pull request #32683: [SPARK-35282][SQL][FOLLOWUP] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
ulysses-you opened a new pull request #32683:
URL: https://github.com/apache/spark/pull/32683


   <!--
   Thanks for sending a pull request!  Here are some tips for you:
     1. If this is your first time, please read our contributor guidelines: https://spark.apache.org/contributing.html
     2. Ensure you have added or run the appropriate tests for your PR: https://spark.apache.org/developer-tools.html
     3. If the PR is unfinished, add '[WIP]' in your PR title, e.g., '[WIP][SPARK-XXXX] Your PR title ...'.
     4. Be sure to keep the PR description updated to reflect all changes.
     5. Please write your PR title to summarize what this PR proposes.
     6. If possible, provide a concise example to reproduce the issue for a faster review.
     7. If you want to add a new configuration, please read the guideline first for naming configurations in
        'core/src/main/scala/org/apache/spark/internal/config/ConfigEntry.scala'.
     8. If you want to add or modify an error message, please read the guideline first:
        https://spark.apache.org/error-message-guidelines.html
   -->

   ### What changes were proposed in this pull request?
   <!--
   Please clarify what changes you are proposing. The purpose of this section is to outline the changes and how this PR fixes the issue.
   If possible, please consider writing useful notes for better and faster reviews in your PR. See the examples below.
     1. If you refactor some codes with changing classes, showing the class hierarchy will help reviewers.
     2. If you fix some SQL features, you can provide some references of other DBMSes.
     3. If there is design documentation, please add the link.
     4. If there is a discussion in the mailing list, please add the link.
   -->
   Tune `spark.sql.adaptive.maxShuffledHashJoinLocalMapThreshold` default value.

   ### Why are the changes needed?
   <!--
   Please clarify why the changes are needed. For instance,
     1. If you propose a new API, clarify the use case for a new API.
     2. If you fix a bug, you can clarify why it is a bug.
   -->
   Make config `spark.sql.adaptive.maxShuffledHashJoinLocalMapThreshold` fallback to `spark.sql.adaptive.advisoryPartitionSizeInBytes` so that we can convert SMJ to SHJ in AQE by default.


   ### Does this PR introduce _any_ user-facing change?
   <!--
   Note that it means *any* user-facing change including all aspects such as the documentation fix.
   If yes, please clarify the previous behavior and the change this PR proposes - provide the console output, description and/or an example to show the behavior difference if possible.
   If possible, please also clarify if this is a user-facing change compared to the released Spark versions or within the unreleased branches such as master.
   If no, write 'No'.
   -->
   Yes, default value changed.

   ### How was this patch tested?
   <!--
   If tests were added, say they were added here. Please make sure to add some test cases that check the changes thoroughly including negative and positive cases if possible.
   If it was tested in a way different from regular unit tests, please clarify how you tested step by step, ideally copy and paste-able, so that other reviewers can test and check, and descendants can verify in the future.
   If tests were not added, please describe why they were not added and/or why it was difficult to add.
   -->
   Pass CI.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] monkeyboy123 commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
monkeyboy123 commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-990983566


   > At present, AQE uses the compressed size to do conditional judgment. In some extreme cases, such as when the compression ratio is relatively high, if smj is converted to shj when enable AQE, it is very likely that the oom issue will happen when building the hash table in shj.
   I think AQE is Based on metrics dataSize,and dataSize is the actually size, rather than the compressed size. Can you point this why?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] viirya commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
viirya commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850218567


   > This is a good point. We can probably hardcode the default value as 64mb

   Sounds good.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35282][SQL][FOLLOWUP] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849286869


   Kubernetes integration test unable to build dist.

   exiting with code: 1
   URL: https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder-K8s/43519/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] maropu commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
maropu commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-852119555


   > The same applies to the TPCDS result checking, and by default we probably only test the broadcast join, cc @maropu

   Yea, it would be nice to add test paths for the other join strategies in these TPCDS tests.

   > Here list some queries with obvious performance differences. Note that, seems query q72 has a perf regression .

   Do you know why the regression happens there? And, does the regression occur even if a different value (e.g., 32mb, 128mb, ...) is set?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849524131


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder-K8s/43533/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850388668


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder-K8s/43577/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850504478


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder/139056/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850388668


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder-K8s/43577/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] JkSelf commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
JkSelf commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850179735


   At present, AQE uses the compressed size to do conditional judgment. In some extreme cases, such as when the compression ratio is relatively high, if smj is converted to shj when enable AQE, it is very likely that the oom issue will happen when building the hash table in shj.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] JkSelf commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
JkSelf commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-852639372


   @ulysses-you What is the data size in your TPC-DS test ?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850352585


   Kubernetes integration test starting
   URL: https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder-K8s/43577/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849451285


   **[Test build #139016 has started](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139016/testReport)** for PR 32683 at commit [`38251d0`](https://github.com/apache/spark/commit/38251d08a62ec1819d98f4b30fca6db9801a81d5).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] cloud-fan commented on pull request #32683: [SPARK-35282][SQL][FOLLOWUP] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
cloud-fan commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849307197


   cc @hvanhovell @maryannxue @JkSelf @viirya @maropu


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins commented on pull request #32683: [SPARK-35282][SQL][FOLLOWUP] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849291964


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder-K8s/43519/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] ulysses-you commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
ulysses-you commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850280702


   >  Also this is a big changes and it is better to have a config to control this feature. So even if OOM appears, users can bypass this problem by disabling this switch.

   we can tune this config to 0 to disable the feature.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849506471


   Kubernetes integration test status success
   URL: https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder-K8s/43533/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] ulysses-you commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
ulysses-you commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849310502


   created [SPARK-35540](https://issues.apache.org/jira/browse/SPARK-35540)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849483404


   Kubernetes integration test starting
   URL: https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder-K8s/43533/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849367460


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder/139001/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849367460


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder/139001/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] ulysses-you commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
ulysses-you commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-852658058


   > @ulysses-you What is the data size in your TPC-DS test ?

   @JkSelf 100GB, as I mentioned sf100.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849639185


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder/139016/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] cloud-fan commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
cloud-fan commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850207380


   > If users don't notify that and change advisoryPartitionSizeInBytes, they might not be aware of the fact that they are changing join strategy.

   This is a good point. We can probably hardcode the default value as 64mb


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850369705


   Kubernetes integration test status success
   URL: https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder-K8s/43577/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849524131


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder-K8s/43533/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] ulysses-you commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
ulysses-you commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850210710


   And just prepare to run tpcds-sf100 to check if there has some issue or improvement with/without `smj -> shj`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850504478


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder/139056/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] cloud-fan commented on pull request #32683: [SPARK-35282][SQL][FOLLOWUP] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
cloud-fan commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849307288


   @ulysses-you can you make a new JIRA ticket? This will be a big decision.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850326846


   **[Test build #139056 has started](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139056/testReport)** for PR 32683 at commit [`ce27e6a`](https://github.com/apache/spark/commit/ce27e6ab0206778bf3bce611966dc1154bad5506).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] cloud-fan commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
cloud-fan commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850199669


   Another concern is the test coverage of shuffle hash join, as it's disabled by default.

   Can we add a testing config to forcibly apply shuffle hash join, and then test different join algorithms in golden file tests? e.g., in `outer-join.sql`, we have
   ```
   --CONFIG_DIM1 spark.sql.autoBroadcastJoinThreshold=10485760
   --CONFIG_DIM1 spark.sql.autoBroadcastJoinThreshold=-1,spark.sql.join.preferSortMergeJoin=true
   --CONFIG_DIM1 spark.sql.autoBroadcastJoinThreshold=-1,spark.sql.join.preferSortMergeJoin=false
   ```

   But `preferSortMergeJoin=false` doesn't guarantee to use shuffle hash join, as we still have conditions like streamside must be 3 times larger than build side.

   The same applies to the TPCDS result checking, and by default we probably only test the broadcast join, cc @maropu


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] ulysses-you commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
ulysses-you commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-852188051
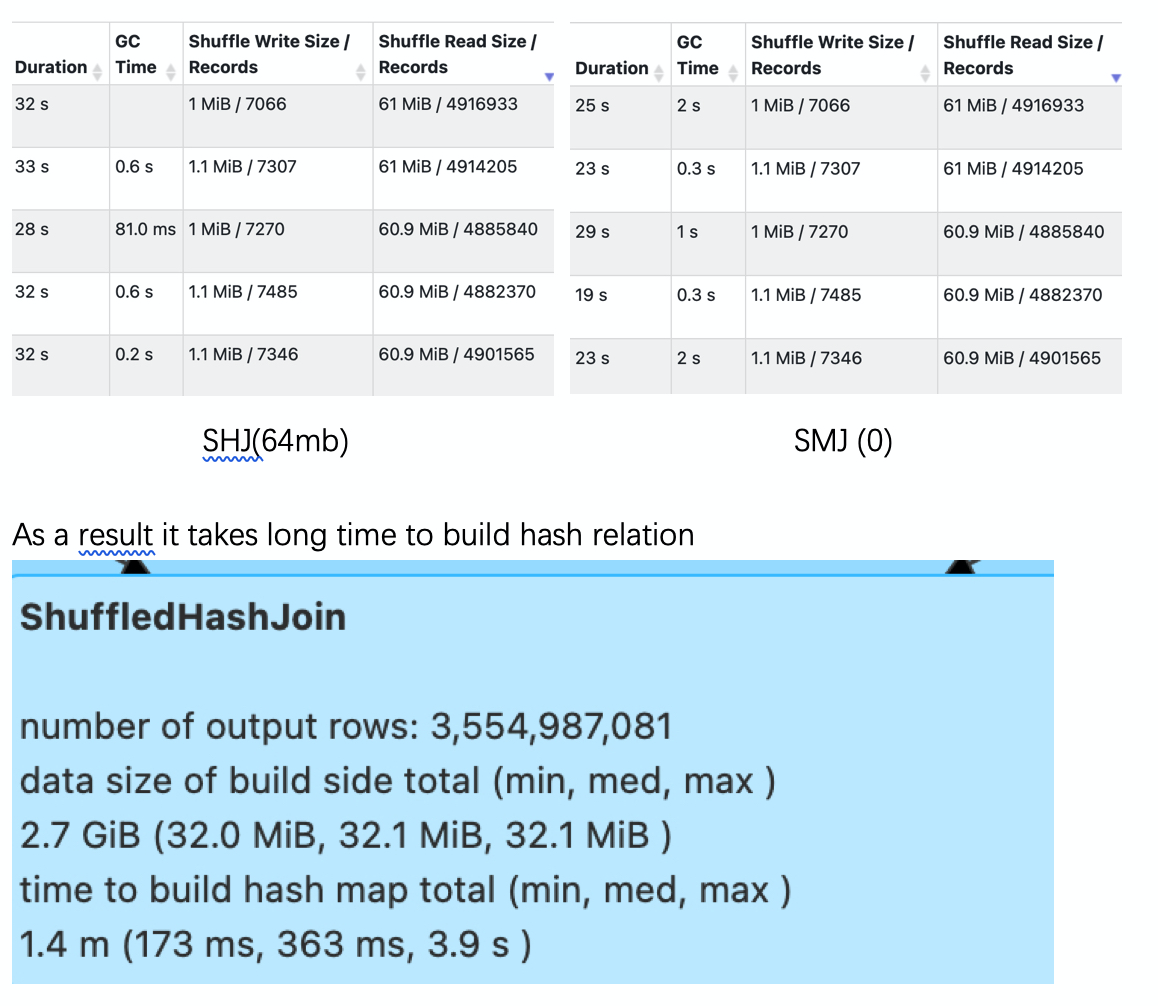
@maropu After taking a deep look, I think it's about compression ratio that the extreme case @JkSelf metioned above.
Here is some pictures of `q72`. We can see the 60MB data contains 4.9million rows.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] cloud-fan commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
cloud-fan commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-917881222


   I think the only blocker to this change is we need to track precise shuffle data size in AQE.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849270859


   **[Test build #139001 has started](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139001/testReport)** for PR 32683 at commit [`381379d`](https://github.com/apache/spark/commit/381379d01ceac033aadd81e8595c791ce68e8801).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849359434


   **[Test build #139001 has finished](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139001/testReport)** for PR 32683 at commit [`381379d`](https://github.com/apache/spark/commit/381379d01ceac033aadd81e8595c791ce68e8801).
    * This patch **fails Spark unit tests**.
    * This patch merges cleanly.
    * This patch adds no public classes.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] github-actions[bot] closed pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
github-actions[bot] closed pull request #32683:
URL: https://github.com/apache/spark/pull/32683


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] JkSelf commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
JkSelf commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850227847


   - In the production environment, we have encountered oom issue when AQE is turned on to convert smj to bhj. The reason is that the compression ratio of the data is too large, the size after compression is 16M, but the data after decompression is 2GB when building the hash table. I think this concern still exists in shj.


   - Also this is a big changes and it is better to have a config to control this feature. So even if OOM appears, users can bypass this problem by disabling this switch.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849615755


   **[Test build #139016 has finished](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139016/testReport)** for PR 32683 at commit [`38251d0`](https://github.com/apache/spark/commit/38251d08a62ec1819d98f4b30fca6db9801a81d5).
    * This patch passes all tests.
    * This patch merges cleanly.
    * This patch adds no public classes.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] github-actions[bot] commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
github-actions[bot] commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-917298569


   We're closing this PR because it hasn't been updated in a while. This isn't a judgement on the merit of the PR in any way. It's just a way of keeping the PR queue manageable.
   If you'd like to revive this PR, please reopen it and ask a committer to remove the Stale tag!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850489461


   **[Test build #139056 has finished](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139056/testReport)** for PR 32683 at commit [`ce27e6a`](https://github.com/apache/spark/commit/ce27e6ab0206778bf3bce611966dc1154bad5506).
    * This patch passes all tests.
    * This patch merges cleanly.
    * This patch adds no public classes.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins removed a comment on pull request #32683: [SPARK-35282][SQL][FOLLOWUP] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849291964


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder-K8s/43519/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849451285


   **[Test build #139016 has started](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139016/testReport)** for PR 32683 at commit [`38251d0`](https://github.com/apache/spark/commit/38251d08a62ec1819d98f4b30fca6db9801a81d5).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] AmplabJenkins removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
AmplabJenkins removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849639185


   Refer to this link for build results (access rights to CI server needed):
   https://amplab.cs.berkeley.edu/jenkins//job/SparkPullRequestBuilder/139016/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA removed a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA removed a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850326846


   **[Test build #139056 has started](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139056/testReport)** for PR 32683 at commit [`ce27e6a`](https://github.com/apache/spark/commit/ce27e6ab0206778bf3bce611966dc1154bad5506).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] SparkQA commented on pull request #32683: [SPARK-35282][SQL][FOLLOWUP] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
SparkQA commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-849270859


   **[Test build #139001 has started](https://amplab.cs.berkeley.edu/jenkins/job/SparkPullRequestBuilder/139001/testReport)** for PR 32683 at commit [`381379d`](https://github.com/apache/spark/commit/381379d01ceac033aadd81e8595c791ce68e8801).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] ulysses-you commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
ulysses-you commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-852101332


   Here list some queries with obvious performance differences. Note that, seems query `q72` has a perf regression .

   tpcds sf100 perf number(seconds) with two value of `spark.sql.adaptive.maxShuffledHashJoinLocalMapThreshold`:

   query|64mb|0|diff
   -|-|-|-
   q2|72.224|109.094|0.337965424
   q11|87.811|106.552|0.175885952
   q14a|269.834|298.432|0.095827525
   q14b|200.496|212.351|0.05582738
   q32|24.37|27.066|0.099608365
   q37|31.595|36.413|0.132315382
   q57|40.86|46.324|0.117951818
   q69|42.891|52.873|0.188792011
   q72|124.234|98.2|/


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] viirya commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
viirya commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850206214


   What I saw is `advisoryPartitionSizeInBytes` is not big (64MB), is OOM likely a concern here? What I concern is `maxShuffledHashJoinLocalMapThreshold` is silently bound to `advisoryPartitionSizeInBytes` by default. If users don't notify that and change `advisoryPartitionSizeInBytes`, they might not be aware of the fact that they are changing join strategy.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] ulysses-you commented on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
ulysses-you commented on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-850208508


   +1, I like 64mb as default instead of fallback.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] monkeyboy123 edited a comment on pull request #32683: [SPARK-35540][SQL] Make config maxShuffledHashJoinLocalMapThreshold fallback to advisoryPartitionSizeInBytes
Posted by GitBox <gi...@apache.org>.
monkeyboy123 edited a comment on pull request #32683:
URL: https://github.com/apache/spark/pull/32683#issuecomment-990983566


   > At present, AQE uses the compressed size to do conditional judgment. In some extreme cases, such as when the compression ratio is relatively high, if smj is converted to shj when enable AQE, it is very likely that the oom issue will happen when building the hash table in shj.

   @JkSelf  I think AQE is Based on metrics dataSize,and dataSize is the actually size, rather than the compressed size. Can you point this why?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org