You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2020/07/02 21:55:09 UTC
[GitHub] [hudi] srsteinmetz commented on issue #1737: [SUPPORT]spark streaming create small parquet files
srsteinmetz commented on issue #1737:
URL: https://github.com/apache/hudi/issues/1737#issuecomment-653235981
Is there any update on this issue?
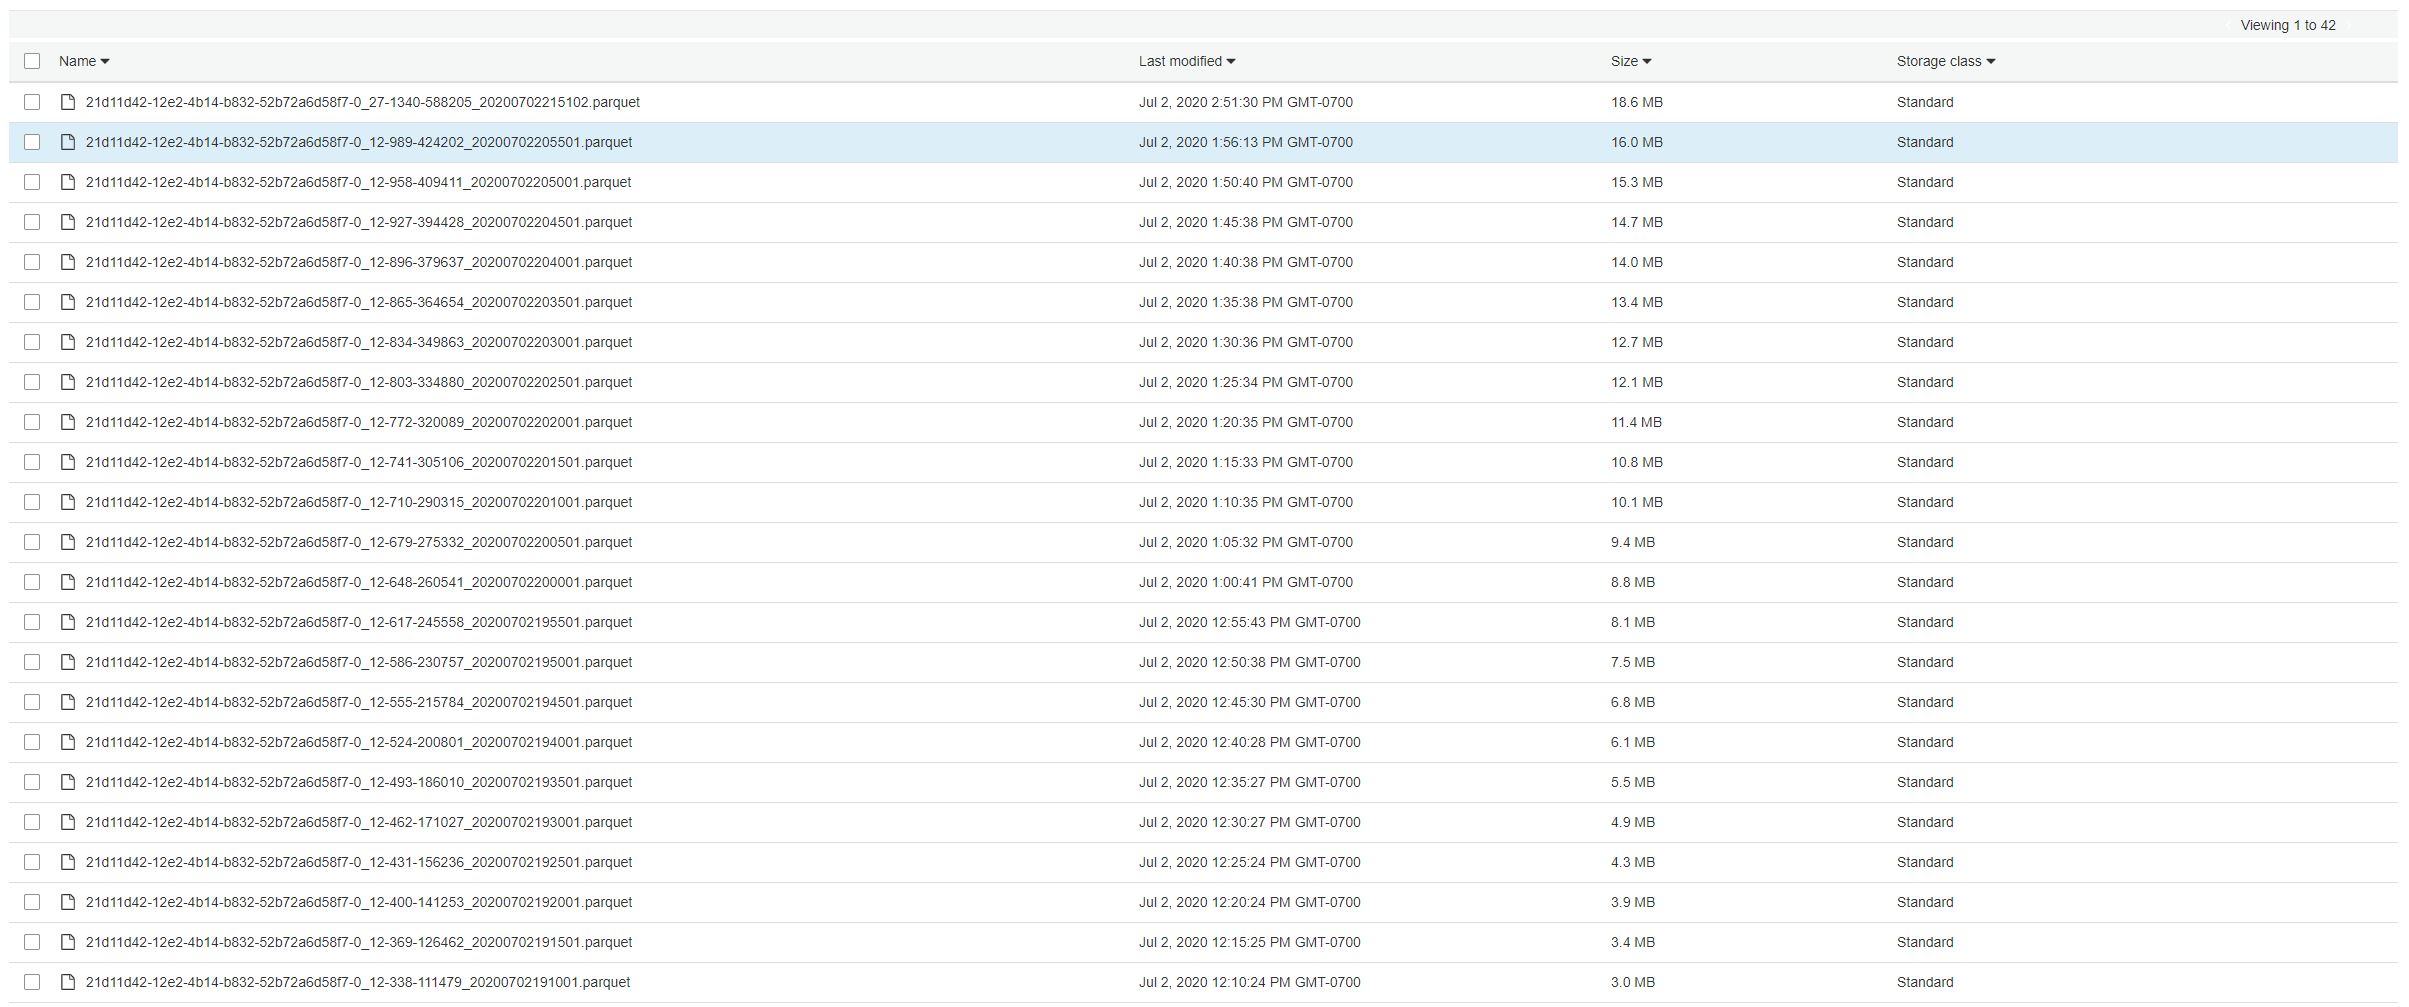
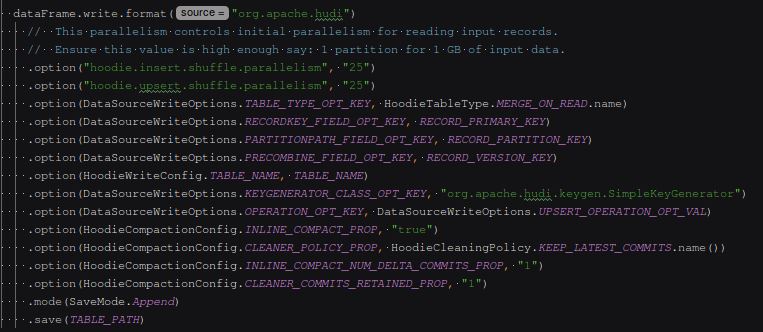
I am having the same problem where each commit is creating a new parquet file and none of the old parquet files (which are not being touched again) are being cleaned. I am also using a MOR table and have tried setting "hoodie.cleaner.commits.retained" to 1. The behavior I am expecting is that every commit would clean the parquet files created by previous commits. However, the number of parquet files in each partition continuously grows in an unbounded manner, negatively affecting ingest performance. From my understanding it seems that cleaning is never being performed on my partitions.
I've attached a screenshot from one of the partitions, along with the code I am using to write the data.
The writes happen through Spark Streaming on a 5 min batch interval.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org