You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@spark.apache.org by sr...@apache.org on 2018/09/06 14:17:40 UTC
spark git commit: [SPARK-25108][SQL] Fix the show method to display
the wide character alignment problem
Repository: spark
Updated Branches:
refs/heads/master 64c314e22 -> f5817d8bb
[SPARK-25108][SQL] Fix the show method to display the wide character alignment problem
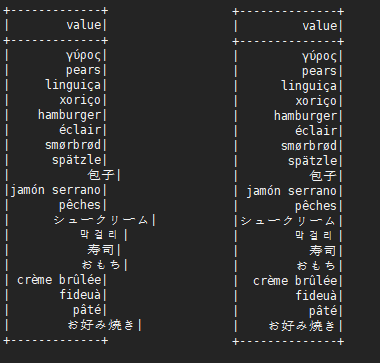
This is not a perfect solution. It is designed to minimize complexity on the basis of solving problems.
It is effective for English, Chinese characters, Japanese, Korean and so on.
```scala
before:
+---+---------------------------+-------------+
|id |中国 |s2 |
+---+---------------------------+-------------+
|1 |ab |[a] |
|2 |null |[中国, abc] |
|3 |ab1 |[hello world]|
|4 |か行 きゃ(kya) きゅ(kyu) きょ(kyo) |[“中国] |
|5 |中国(你好)a |[“中(国), 312] |
|6 |中国山(东)服务区 |[“中(国)] |
|7 |中国山东服务区 |[中(国)] |
|8 | |[中国] |
+---+---------------------------+-------------+
after:
+---+-----------------------------------+----------------+
|id |中国 |s2 |
+---+-----------------------------------+----------------+
|1 |ab |[a] |
|2 |null |[中国, abc] |
|3 |ab1 |[hello world] |
|4 |か行 きゃ(kya) きゅ(kyu) きょ(kyo) |[“中国] |
|5 |中国(你好)a |[“中(国), 312]|
|6 |中国山(东)服务区 |[“中(国)] |
|7 |中国山东服务区 |[中(国)] |
|8 | |[中国] |
+---+-----------------------------------+----------------+
```
## What changes were proposed in this pull request?
When there are wide characters such as Chinese characters or Japanese characters in the data, the show method has a alignment problem.
Try to fix this problem.
## How was this patch tested?
(Please explain how this patch was tested. E.g. unit tests, integration tests, manual tests)
Please review http://spark.apache.org/contributing.html before opening a pull request.
Closes #22048 from xuejianbest/master.
Authored-by: xuejianbest <38...@qq.com>
Signed-off-by: Sean Owen <se...@databricks.com>
Project: http://git-wip-us.apache.org/repos/asf/spark/repo
Commit: http://git-wip-us.apache.org/repos/asf/spark/commit/f5817d8b
Tree: http://git-wip-us.apache.org/repos/asf/spark/tree/f5817d8b
Diff: http://git-wip-us.apache.org/repos/asf/spark/diff/f5817d8b
Branch: refs/heads/master
Commit: f5817d8bb33b733eeca0154d1ed207c8d1e8513f
Parents: 64c314e
Author: xuejianbest <38...@qq.com>
Authored: Thu Sep 6 07:17:37 2018 -0700
Committer: Sean Owen <se...@databricks.com>
Committed: Thu Sep 6 07:17:37 2018 -0700
----------------------------------------------------------------------
.../scala/org/apache/spark/util/Utils.scala | 30 ++++++++++++
.../org/apache/spark/util/UtilsSuite.scala | 21 +++++++++
.../scala/org/apache/spark/sql/Dataset.scala | 18 +++----
.../org/apache/spark/sql/DatasetSuite.scala | 49 ++++++++++++++++++++
4 files changed, 109 insertions(+), 9 deletions(-)
----------------------------------------------------------------------
http://git-wip-us.apache.org/repos/asf/spark/blob/f5817d8b/core/src/main/scala/org/apache/spark/util/Utils.scala
----------------------------------------------------------------------
diff --git a/core/src/main/scala/org/apache/spark/util/Utils.scala b/core/src/main/scala/org/apache/spark/util/Utils.scala
index 15c958d..4593b05 100644
--- a/core/src/main/scala/org/apache/spark/util/Utils.scala
+++ b/core/src/main/scala/org/apache/spark/util/Utils.scala
@@ -2795,6 +2795,36 @@ private[spark] object Utils extends Logging {
}
}
}
+
+ /**
+ * Regular expression matching full width characters.
+ *
+ * Looked at all the 0x0000-0xFFFF characters (unicode) and showed them under Xshell.
+ * Found all the full width characters, then get the regular expression.
+ */
+ private val fullWidthRegex = ("""[""" +
+ // scalastyle:off nonascii
+ """\u1100-\u115F""" +
+ """\u2E80-\uA4CF""" +
+ """\uAC00-\uD7A3""" +
+ """\uF900-\uFAFF""" +
+ """\uFE10-\uFE19""" +
+ """\uFE30-\uFE6F""" +
+ """\uFF00-\uFF60""" +
+ """\uFFE0-\uFFE6""" +
+ // scalastyle:on nonascii
+ """]""").r
+
+ /**
+ * Return the number of half widths in a given string. Note that a full width character
+ * occupies two half widths.
+ *
+ * For a string consisting of 1 million characters, the execution of this method requires
+ * about 50ms.
+ */
+ def stringHalfWidth(str: String): Int = {
+ if (str == null) 0 else str.length + fullWidthRegex.findAllIn(str).size
+ }
}
private[util] object CallerContext extends Logging {
http://git-wip-us.apache.org/repos/asf/spark/blob/f5817d8b/core/src/test/scala/org/apache/spark/util/UtilsSuite.scala
----------------------------------------------------------------------
diff --git a/core/src/test/scala/org/apache/spark/util/UtilsSuite.scala b/core/src/test/scala/org/apache/spark/util/UtilsSuite.scala
index 418d2f9..943b535 100644
--- a/core/src/test/scala/org/apache/spark/util/UtilsSuite.scala
+++ b/core/src/test/scala/org/apache/spark/util/UtilsSuite.scala
@@ -1184,6 +1184,27 @@ class UtilsSuite extends SparkFunSuite with ResetSystemProperties with Logging {
assert(Utils.getSimpleName(classOf[MalformedClassObject.MalformedClass]) ===
"UtilsSuite$MalformedClassObject$MalformedClass")
}
+
+ test("stringHalfWidth") {
+ // scalastyle:off nonascii
+ assert(Utils.stringHalfWidth(null) == 0)
+ assert(Utils.stringHalfWidth("") == 0)
+ assert(Utils.stringHalfWidth("ab c") == 4)
+ assert(Utils.stringHalfWidth("1098") == 4)
+ assert(Utils.stringHalfWidth("mø") == 2)
+ assert(Utils.stringHalfWidth("γύρ") == 3)
+ assert(Utils.stringHalfWidth("pê") == 2)
+ assert(Utils.stringHalfWidth("ー") == 2)
+ assert(Utils.stringHalfWidth("测") == 2)
+ assert(Utils.stringHalfWidth("か") == 2)
+ assert(Utils.stringHalfWidth("걸") == 2)
+ assert(Utils.stringHalfWidth("à") == 1)
+ assert(Utils.stringHalfWidth("焼") == 2)
+ assert(Utils.stringHalfWidth("羍む") == 4)
+ assert(Utils.stringHalfWidth("뺭ᾘ") == 3)
+ assert(Utils.stringHalfWidth("\u0967\u0968\u0969") == 3)
+ // scalastyle:on nonascii
+ }
}
private class SimpleExtension
http://git-wip-us.apache.org/repos/asf/spark/blob/f5817d8b/sql/core/src/main/scala/org/apache/spark/sql/Dataset.scala
----------------------------------------------------------------------
diff --git a/sql/core/src/main/scala/org/apache/spark/sql/Dataset.scala b/sql/core/src/main/scala/org/apache/spark/sql/Dataset.scala
index db439b1..fa14aa1 100644
--- a/sql/core/src/main/scala/org/apache/spark/sql/Dataset.scala
+++ b/sql/core/src/main/scala/org/apache/spark/sql/Dataset.scala
@@ -306,16 +306,16 @@ class Dataset[T] private[sql](
// Compute the width of each column
for (row <- rows) {
for ((cell, i) <- row.zipWithIndex) {
- colWidths(i) = math.max(colWidths(i), cell.length)
+ colWidths(i) = math.max(colWidths(i), Utils.stringHalfWidth(cell))
}
}
val paddedRows = rows.map { row =>
row.zipWithIndex.map { case (cell, i) =>
if (truncate > 0) {
- StringUtils.leftPad(cell, colWidths(i))
+ StringUtils.leftPad(cell, colWidths(i) - Utils.stringHalfWidth(cell) + cell.length)
} else {
- StringUtils.rightPad(cell, colWidths(i))
+ StringUtils.rightPad(cell, colWidths(i) - Utils.stringHalfWidth(cell) + cell.length)
}
}
}
@@ -337,12 +337,10 @@ class Dataset[T] private[sql](
// Compute the width of field name and data columns
val fieldNameColWidth = fieldNames.foldLeft(minimumColWidth) { case (curMax, fieldName) =>
- math.max(curMax, fieldName.length)
+ math.max(curMax, Utils.stringHalfWidth(fieldName))
}
val dataColWidth = dataRows.foldLeft(minimumColWidth) { case (curMax, row) =>
- math.max(curMax, row.map(_.length).reduceLeftOption[Int] { case (cellMax, cell) =>
- math.max(cellMax, cell)
- }.getOrElse(0))
+ math.max(curMax, row.map(cell => Utils.stringHalfWidth(cell)).max)
}
dataRows.zipWithIndex.foreach { case (row, i) =>
@@ -351,8 +349,10 @@ class Dataset[T] private[sql](
s"-RECORD $i", fieldNameColWidth + dataColWidth + 5, "-")
sb.append(rowHeader).append("\n")
row.zipWithIndex.map { case (cell, j) =>
- val fieldName = StringUtils.rightPad(fieldNames(j), fieldNameColWidth)
- val data = StringUtils.rightPad(cell, dataColWidth)
+ val fieldName = StringUtils.rightPad(fieldNames(j),
+ fieldNameColWidth - Utils.stringHalfWidth(fieldNames(j)) + fieldNames(j).length)
+ val data = StringUtils.rightPad(cell,
+ dataColWidth - Utils.stringHalfWidth(cell) + cell.length)
s" $fieldName | $data "
}.addString(sb, "", "\n", "\n")
}
http://git-wip-us.apache.org/repos/asf/spark/blob/f5817d8b/sql/core/src/test/scala/org/apache/spark/sql/DatasetSuite.scala
----------------------------------------------------------------------
diff --git a/sql/core/src/test/scala/org/apache/spark/sql/DatasetSuite.scala b/sql/core/src/test/scala/org/apache/spark/sql/DatasetSuite.scala
index cf24eba..ca8fbc9 100644
--- a/sql/core/src/test/scala/org/apache/spark/sql/DatasetSuite.scala
+++ b/sql/core/src/test/scala/org/apache/spark/sql/DatasetSuite.scala
@@ -969,6 +969,55 @@ class DatasetSuite extends QueryTest with SharedSQLContext {
checkShowString(ds, expected)
}
+ test("SPARK-25108 Fix the show method to display the full width character alignment problem") {
+ // scalastyle:off nonascii
+ val df = Seq(
+ (0, null, 1),
+ (0, "", 1),
+ (0, "ab c", 1),
+ (0, "1098", 1),
+ (0, "mø", 1),
+ (0, "γύρ", 1),
+ (0, "pê", 1),
+ (0, "ー", 1),
+ (0, "测", 1),
+ (0, "か", 1),
+ (0, "걸", 1),
+ (0, "à", 1),
+ (0, "焼", 1),
+ (0, "羍む", 1),
+ (0, "뺭ᾘ", 1),
+ (0, "\u0967\u0968\u0969", 1)
+ ).toDF("b", "a", "c")
+ // scalastyle:on nonascii
+ val ds = df.as[ClassData]
+ val expected =
+ // scalastyle:off nonascii
+ """+---+----+---+
+ || b| a| c|
+ |+---+----+---+
+ || 0|null| 1|
+ || 0| | 1|
+ || 0|ab c| 1|
+ || 0|1098| 1|
+ || 0| mø| 1|
+ || 0| γύρ| 1|
+ || 0| pê| 1|
+ || 0| ー| 1|
+ || 0| 测| 1|
+ || 0| か| 1|
+ || 0| 걸| 1|
+ || 0| à| 1|
+ || 0| 焼| 1|
+ || 0|羍む| 1|
+ || 0| 뺭ᾘ| 1|
+ || 0| १२३| 1|
+ |+---+----+---+
+ |""".stripMargin
+ // scalastyle:on nonascii
+ checkShowString(ds, expected)
+ }
+
test(
"SPARK-15112: EmbedDeserializerInFilter should not optimize plan fragment that changes schema"
) {
---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@spark.apache.org
For additional commands, e-mail: commits-help@spark.apache.org