You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2021/03/06 04:46:26 UTC
[GitHub] [hudi] afeldman1 opened a new issue #2639: [SUPPORT] Spark upgrade cause severe increase in Hudi write time
afeldman1 opened a new issue #2639:
URL: https://github.com/apache/hudi/issues/2639
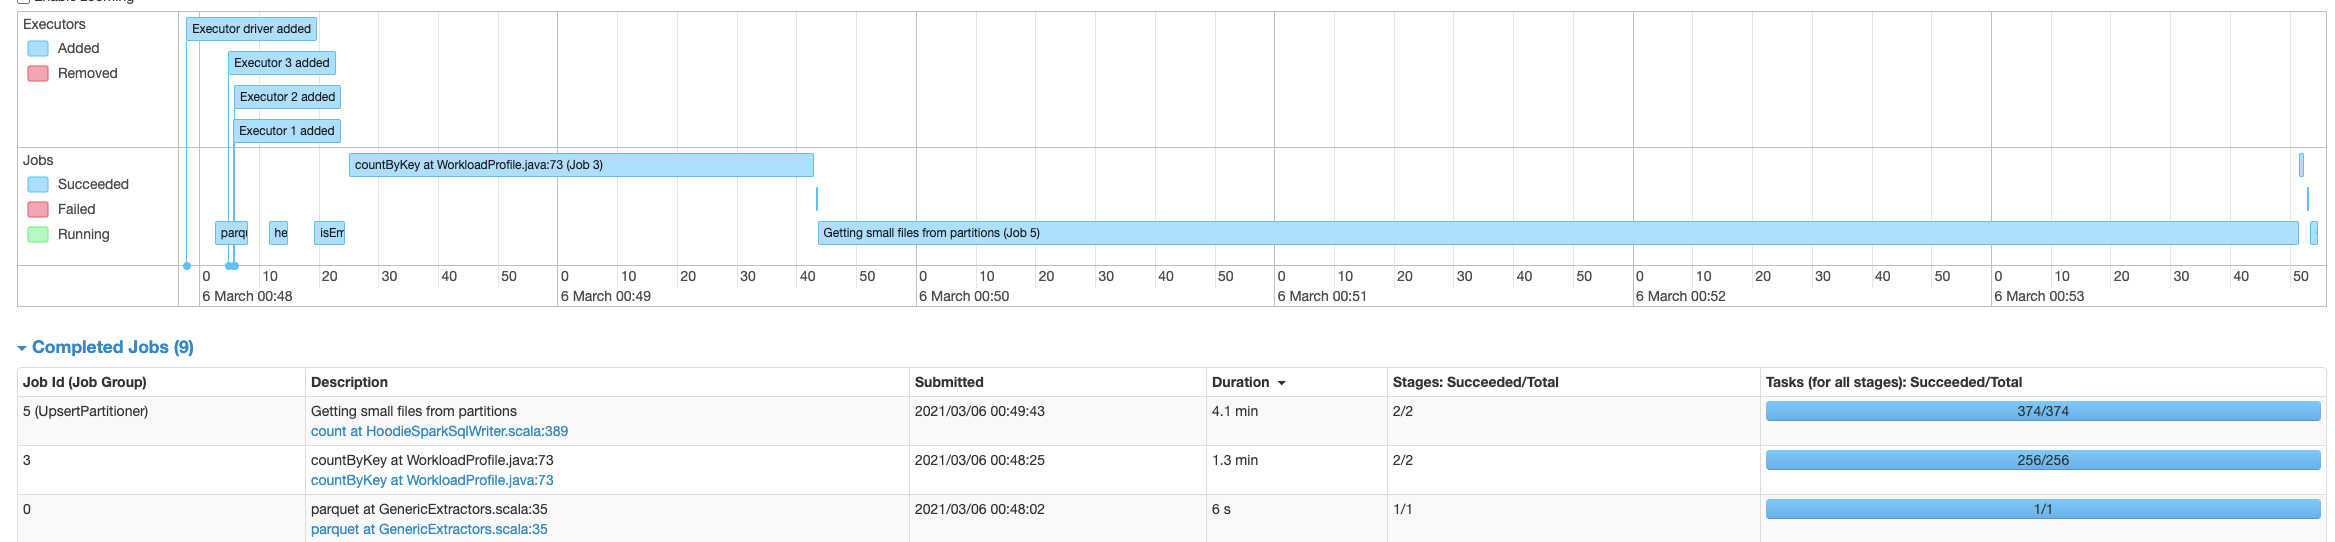
Using Hudi 0.6.0, updated from Spark 2.4.7 on EMR 5.32.0 to Spark 3.0.1 on EMR 6.2.0, there is a significant slowdown on writing into Hudi tables. With Spark 2.4.7 the process writing into the Hudi table takes about 6 minutes, while with Spark 3.0.1, the same code takes about 3.4 hours.
The table has 60073874 records.
The source Spark is reading the data from is a single un-partitioned parquet file.
Using AWS Glue as the metastore and S3 as the table file store location.
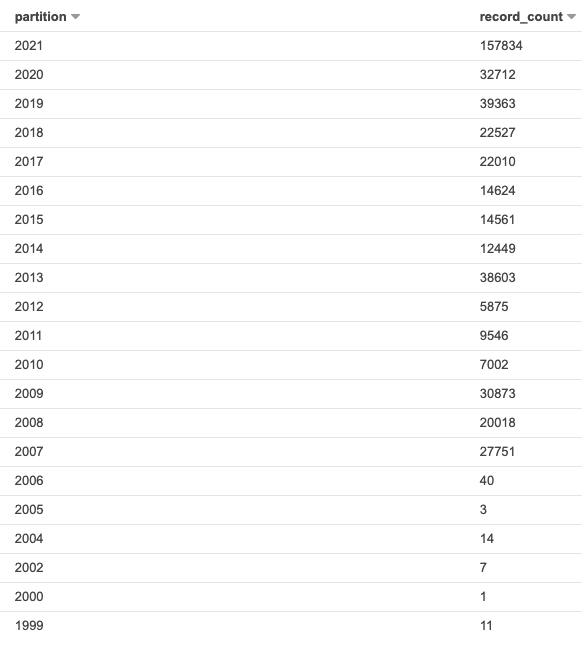
Originally it was writing into a Hudi table with a single partition, but I also attempted to break it up partitioned into groups as see below, with no significant change in performance:
The Hudi write config is the same with both Spark 2.4.7 and Spark 3.0.1:
`DataSourceWriteOptions.HIVE_DATABASE_OPT_KEY -> datalakeDbName,
HoodieWriteConfig.TABLE_NAME -> table.tableName,
DataSourceWriteOptions.TABLE_TYPE_OPT_KEY -> DataSourceWriteOptions.COW_TABLE_TYPE_OPT_VAL,
DataSourceWriteOptions.OPERATION_OPT_KEY -> DataSourceWriteOptions.BULK_INSERT_OPERATION_OPT_VAL,
DataSourceWriteOptions.KEYGENERATOR_CLASS_OPT_KEY -> classOf[ComplexKeyGenerator].getName,
DataSourceWriteOptions.RECORDKEY_FIELD_OPT_KEY -> table.keyCols.reduce(_ + "," + _),
DataSourceWriteOptions.PARTITIONPATH_FIELD_OPT_KEY -> table.partitionCols,
DataSourceWriteOptions.PRECOMBINE_FIELD_OPT_KEY -> "ts",
DataSourceWriteOptions.HIVE_SYNC_ENABLED_OPT_KEY -> "true",
DataSourceWriteOptions.HIVE_TABLE_OPT_KEY -> table.tableName,
DataSourceWriteOptions.HIVE_PARTITION_EXTRACTOR_CLASS_OPT_KEY -> classOf[MultiPartKeysValueExtractor].getCanonicalName,
DataSourceWriteOptions.HIVE_PARTITION_FIELDS_OPT_KEY -> partitionCols
DataSourceWriteOptions.HIVE_URL_OPT_KEY -> getHiveMetastoreJdbcUrl`
(also attempted to switch to `DataSourceWriteOptions.INSERT_OPERATION_OPT_VAL` for `DataSourceWriteOptions.OPERATION_OPT_KEY`, but this does not help)
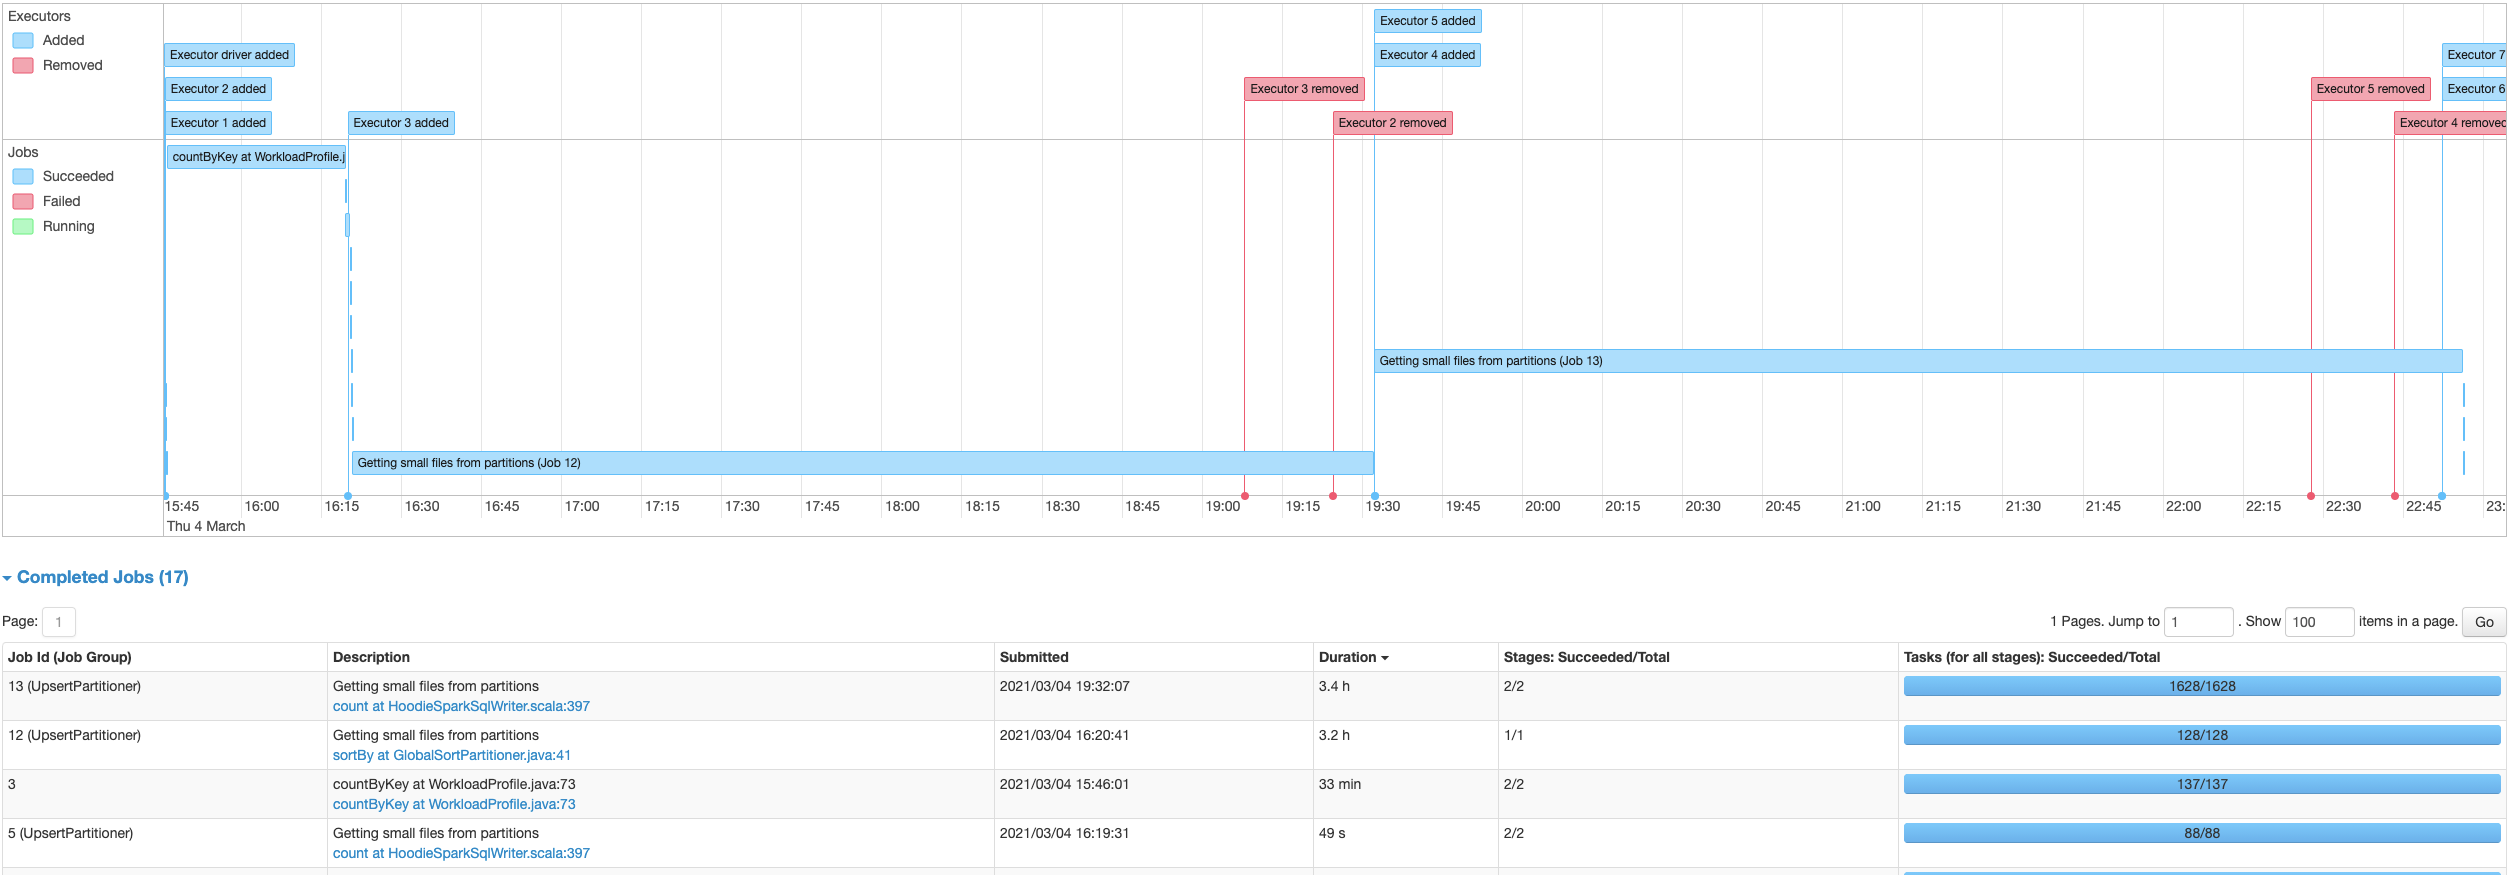
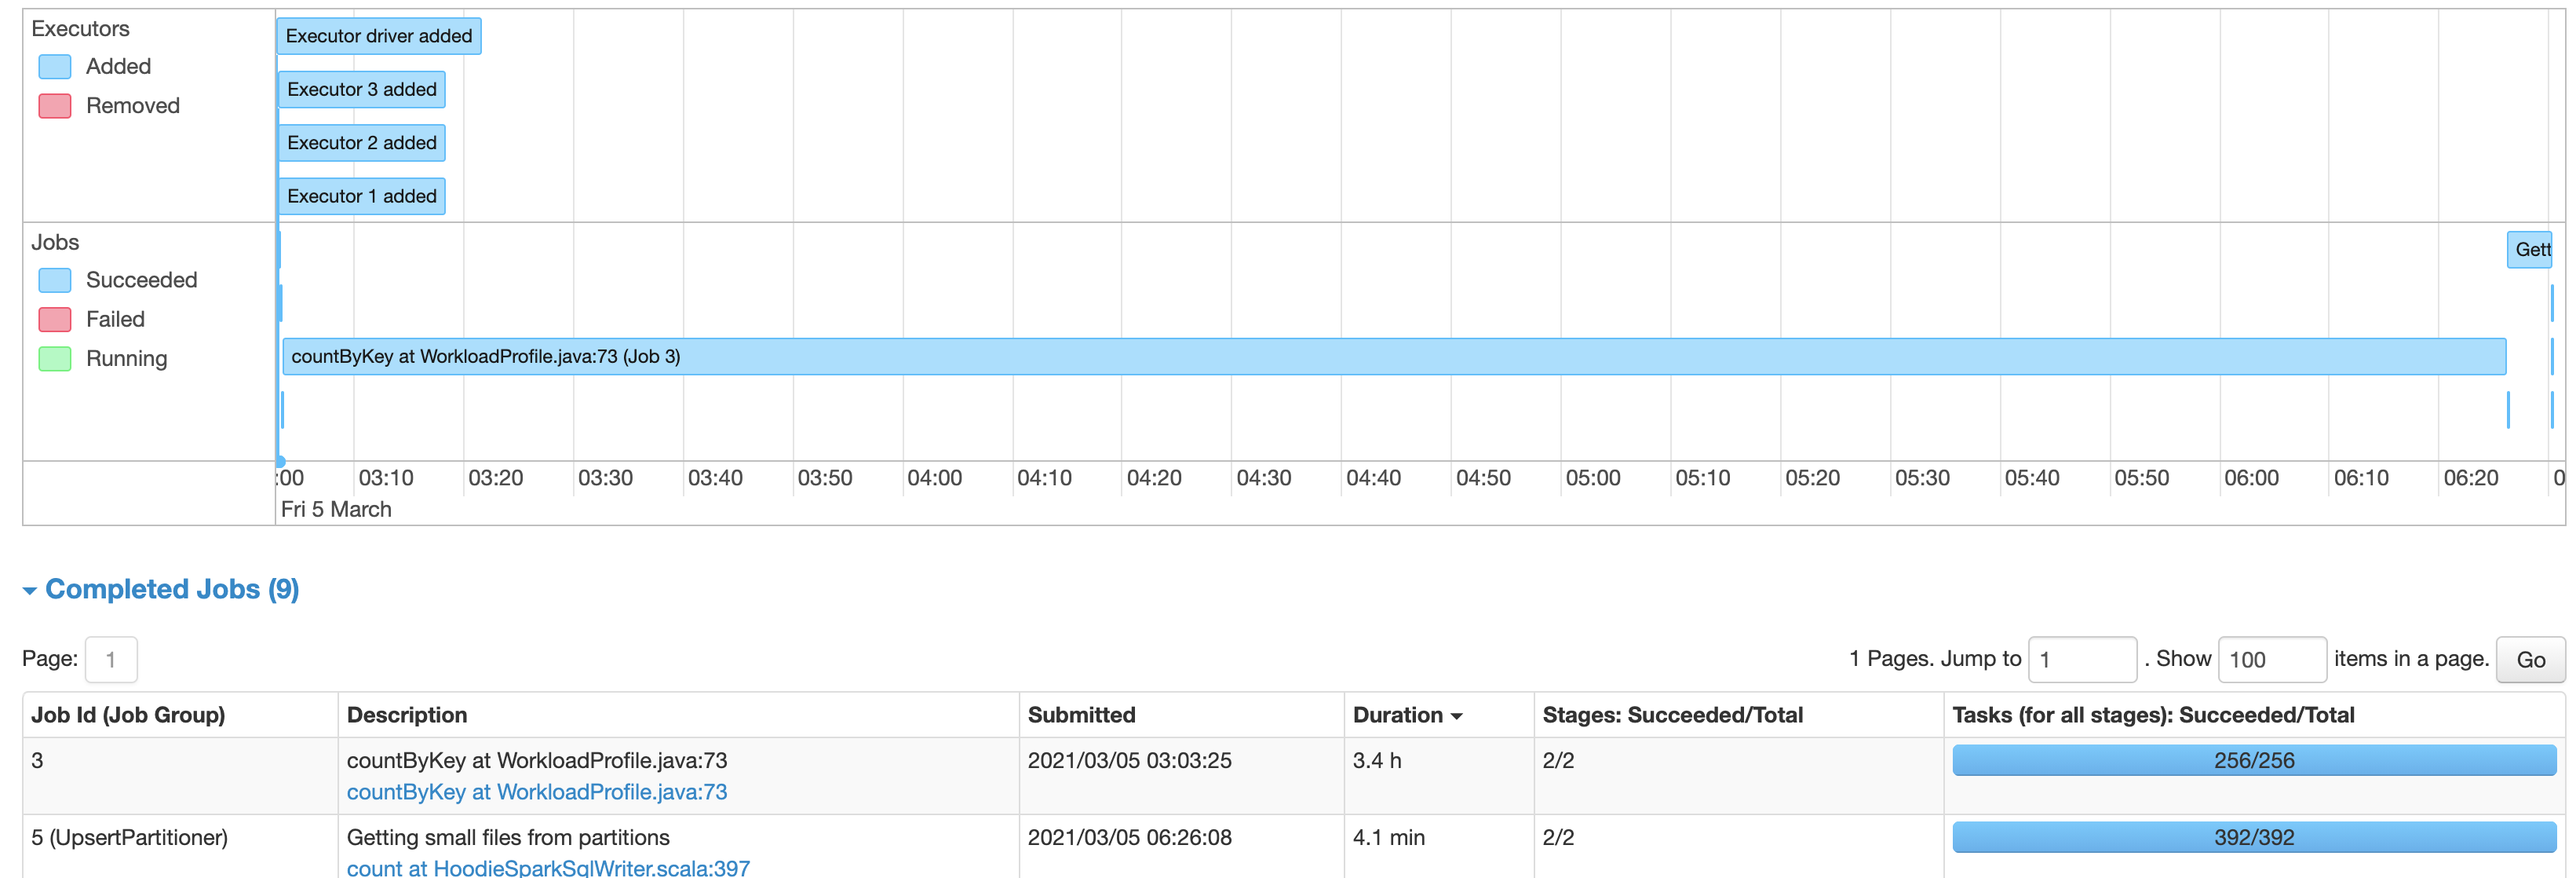
It’s spending most time time on the piece “UpsertPartitioner”, “Getting small files from partitions” with spark job “sortBy at GlobalSortPartitioner.java” and “count at HoodieSparkSqlWriter.scala"
Is there something wrong with the config, that's causing this extreme increase in hudi processing time?
With Spark 3.0.1 Using single partition:
With Spark 3.0.1 Using multiple partitions:
With Spark 2.4.7:
**Problematic Environment Description**
Hudi version : 0.6.0
Spark version : 3.0.1
Storage: AWS S3
Running on EMR
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] bvaradar commented on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
bvaradar commented on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-792869498


   @nsivabalan : Can you take an initial look at this issue ?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan edited a comment on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
nsivabalan edited a comment on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-798640139


   @afeldman1 : is it possible for you to try hudi 0.7.0 with EMR? The time increase definitely seems unacceptable.

   Can you try setting this config and let us know how it goes.
   hoodie.datasource.write.row.writer.enable -> true
   DataSourceWriteOptions.OPERATION_OPT_KEY -> DataSourceWriteOptions.BULK_INSERT_OPERATION_OPT_VAL

   Wrt difference between "insert" and "bulk_insert" operation:
   In bulk insert, you can configure different sort modes.
   GLOBAL_SORT: all incoming records are sorted globally before being partitioned and written to hudi.
   PARTITION_SORT: records are locally sorted for each RDD partition after coalesce and then written to hudi.
   NONE: if you don't prefer any ordering with bulk_insert.

   If your record keys are completely random, you might as well set this [sort mode ](https://hudi.apache.org/docs/configurations.html#withBulkInsertSortMode)to NONE.
   NONE is expected to match spark.write.parquet() in terms of number of files, overheads.

   And, can you provide spark UI for stages with spark 3.0.1 for the job that's taking hours as well.

   I have one clarification as well: If you are incrementally ingesting data, why not consider "upsert" as your operation. Or are you just trying to load data into hudi for first time and trying out different approaches.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] rubenssoto commented on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
rubenssoto commented on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-795734772


   I have the same problem with Hudi 0.6.0 EMR version on EMR 6.x, Using Hudi 0.7.0 on the same EMR version works perfectly.

   Hudi 0.6.0 doesn't have support for spark 3, so AWS made changes to make it work.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan edited a comment on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
nsivabalan edited a comment on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-798640139


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] maxiaoniu commented on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
maxiaoniu commented on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-799088028


   Might be related with this
   ```
   Important
   Amazon EMR 6.1.0 and 6.2.0 include a performance issue that can critically affect all Hudi insert, upsert, and delete operations. If you plan to use Hudi with Amazon EMR 6.1.0 or 6.2.0, you should contact AWS support to obtain a patched Hudi RPM.
   ```
   https://docs.aws.amazon.com/emr/latest/ReleaseGuide/emr-whatsnew.html


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] n3nash commented on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
n3nash commented on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-827313973


   @afeldman1 I think this issue is related to the AWS EMR changes for Hudi 0.6. As @rubenssoto described, the Hudi 0.7 works fine. Closing this ticket, feel free to re-open if issue still persists for you.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-798640139


   @afeldman1 : is it possible for you to try hudi 0.7.0 with EMR? The time increase definitely seems unacceptable. I could not spot any issues on the first look especially since you have ran it w/ spark2 and its the issue only with spark3.

   Can you try setting this config and let us know how it goes.
   hoodie.datasource.write.row.writer.enable -> true
   DataSourceWriteOptions.OPERATION_OPT_KEY -> DataSourceWriteOptions.BULK_INSERT_OPERATION_OPT_VAL

   I don't suspect this should completely solve your perf issue since your screenshots shows delays in fetching small files. But just to get more signals.

   And, can you provide spark UI for stages with spark 3.0.1 as well.

   Wrt difference between "insert" and "bulk_insert" operation:
   In bulk insert, you can configure different sort modes.
   GLOBAL_SORT: all incoming records are sorted globally before being partitioned and written to hudi.
   PARTITION_SORT: records are locally sorted for each RDD partition after coalesce and then written to hudi.
   NONE: if you don't prefer any ordering with bulk_insert.

   If your record keys are completely random, you might as well set this [sort mode ](https://hudi.apache.org/docs/configurations.html#withBulkInsertSortMode)to NONE.
   NONE is expected to match spark.write.parquet() in terms of number of files, overheads.

   I have one clarification as well: If you are incrementally ingesting data, why not consider "upsert" as your operation. Or are you just trying to load data into hudi for first time and trying out different approaches.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] n3nash closed issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
n3nash closed issue #2639:
URL: https://github.com/apache/hudi/issues/2639


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #2639: [SUPPORT] Spark 3.0.1 upgrade cause severe increase in Hudi write time
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #2639:
URL: https://github.com/apache/hudi/issues/2639#issuecomment-810344901


   @afeldman1 : gentle ping. once you respond, can you please remove "awaiting-user-response" label for the issue. If possible add "awaiting-community-help" label.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org