You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@iceberg.apache.org by GitBox <gi...@apache.org> on 2021/10/08 11:52:15 UTC
[GitHub] [iceberg] ConeyLiu opened a new pull request #3249: Optimized spark vectorized read parquet decimal
ConeyLiu opened a new pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249
Arrow use 16 bytes for all decimal vector, however, the data could be stored as int/long in parquet file for different precision decimal data. We only need to use the int/long arrow vector for int/long backed decimal data. This could improve performance a lot when we do a full table scan on the store_sales table(1TB data scale).
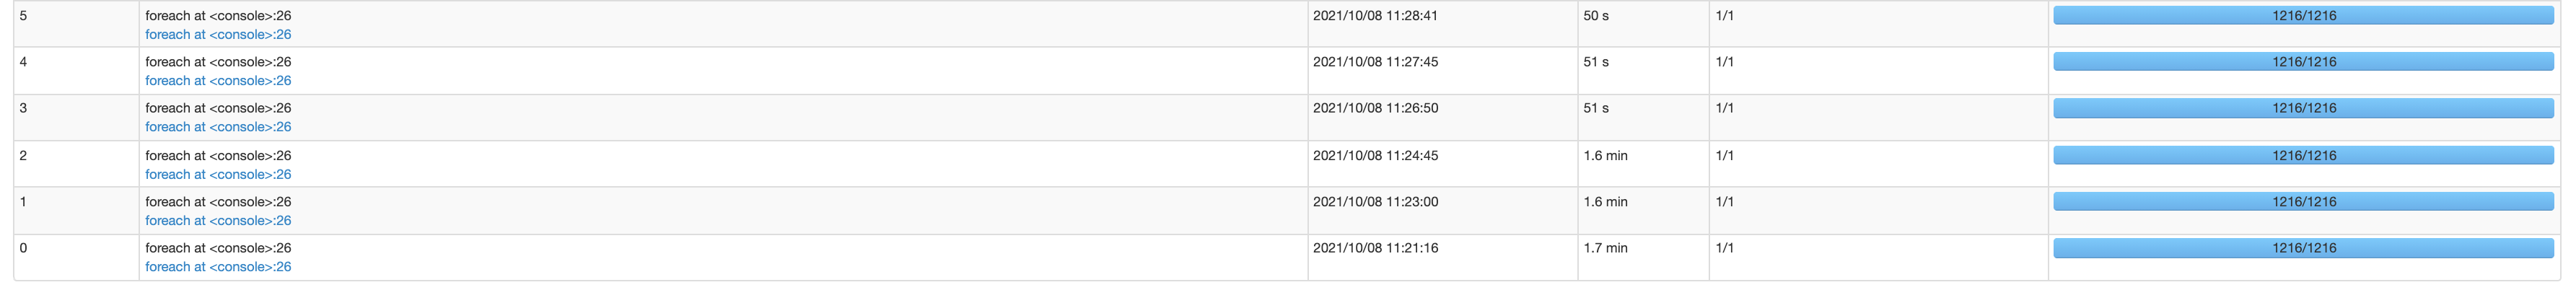
The existed UT should cover the vectorized read case. I could add the extra UTs if needed.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r725681999


##########
File path: spark/src/main/java/org/apache/iceberg/spark/data/vectorized/ArrowVectorAccessorFactory.java
##########
@@ -37,7 +37,8 @@
     super(DecimalFactoryImpl::new,
         StringFactoryImpl::new,
         StructChildFactoryImpl::new,
-        ArrayFactoryImpl::new);
+        ArrayFactoryImpl::new,
+        true, true);

Review comment:
       Good.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-940601867


   thanks @rdblue  for the review. I will do some refactoring.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-1067527102


   @ConeyLiu, could you rebase this? I'll take another look so we can get it in. Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r725681139


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/GenericArrowVectorAccessorFactory.java
##########
@@ -72,6 +73,9 @@
   private final Supplier<StructChildFactory<ChildVectorT>> structChildFactorySupplier;
   private final Supplier<ArrayFactory<ChildVectorT, ArrayT>> arrayFactorySupplier;

+  private final boolean useIntVectorForIntBackedDecimal;
+  private final boolean useLongVectorForLongBackedDecimal;

Review comment:
       Are these exposed to users? I would rather not expose them and just use the faster version in Spark.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-939258436


   before
   ```
   Benchmark                                                                 Mode  Cnt   Score   Error  Units
   VectorizedReadFlatParquetDataBenchmark.readDatesIcebergVectorized5k         ss    5   1.362 ± 0.092   s/op
   VectorizedReadFlatParquetDataBenchmark.readDatesSparkVectorized5k           ss    5   1.451 ± 0.222   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsIcebergVectorized5k      ss    5  10.508 ± 0.893   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsSparkVectorized5k        ss    5   8.165 ± 1.205   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesIcebergVectorized5k       ss    5   2.880 ± 0.241   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesSparkVectorized5k         ss    5   2.610 ± 0.152   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsIcebergVectorized5k        ss    5   2.801 ± 0.376   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsSparkVectorized5k          ss    5   2.469 ± 0.155   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersIcebergVectorized5k      ss    5   2.286 ± 0.136   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersSparkVectorized5k        ss    5   2.580 ± 0.229   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsIcebergVectorized5k         ss    5   2.684 ± 0.186   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsSparkVectorized5k           ss    5   2.526 ± 0.767   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsIcebergVectorized5k       ss    5   4.367 ± 0.207   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsSparkVectorized5k         ss    5   3.964 ± 0.334   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsIcebergVectorized5k    ss    5   1.434 ± 0.120   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsSparkVectorized5k      ss    5   2.015 ± 0.351   s/op

   ```

   after
   ```
   Benchmark                                                                 Mode  Cnt   Score   Error  Units
   VectorizedReadFlatParquetDataBenchmark.readDatesIcebergVectorized5k         ss    5   1.578 ± 0.045   s/op
   VectorizedReadFlatParquetDataBenchmark.readDatesSparkVectorized5k           ss    5   1.757 ± 0.338   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsIcebergVectorized5k      ss    5  10.965 ± 1.610   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsSparkVectorized5k        ss    5   8.143 ± 0.300   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesIcebergVectorized5k       ss    5   2.791 ± 0.078   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesSparkVectorized5k         ss    5   2.623 ± 0.171   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsIcebergVectorized5k        ss    5   2.570 ± 0.065   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsSparkVectorized5k          ss    5   2.657 ± 0.692   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersIcebergVectorized5k      ss    5   2.651 ± 0.115   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersSparkVectorized5k        ss    5   2.547 ± 0.290   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsIcebergVectorized5k         ss    5   2.305 ± 0.124   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsSparkVectorized5k           ss    5   2.540 ± 0.076   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsIcebergVectorized5k       ss    5   4.176 ± 0.222   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsSparkVectorized5k         ss    5   4.231 ± 1.574   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsIcebergVectorized5k    ss    5   1.597 ± 0.415   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsSparkVectorized5k      ss    5   1.720 ± 0.052   s/op
   ```

   I added decimal benchmark:
   before:
   ```
   Benchmark                                                                        Mode  Cnt   Score   Error  Units
   VectorizedReadParquetDecimalBenchmark.readDecimalsIcebergVectorized5k              ss    5  10.623 ± 1.204   s/op
   VectorizedReadParquetDecimalBenchmark.readDecimalsSparkVectorized5k                ss    5   8.322 ± 1.146   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsIcebergVectorized5k     ss    5   1.593 ± 0.199   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsSparkVectorized5k       ss    5   1.597 ± 0.064   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsIcebergVectorized5k    ss    5   5.836 ± 0.406   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsSparkVectorized5k      ss    5   3.285 ± 0.230   s/op
   ```

   after
   ```
   Benchmark                                                                        Mode  Cnt   Score   Error  Units
   VectorizedReadParquetDecimalBenchmark.readDecimalsIcebergVectorized5k              ss    5  10.988 ± 2.355   s/op
   VectorizedReadParquetDecimalBenchmark.readDecimalsSparkVectorized5k                ss    5   7.511 ± 0.484   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsIcebergVectorized5k     ss    5   1.748 ± 0.174   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsSparkVectorized5k       ss    5   1.631 ± 0.325   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsIcebergVectorized5k    ss    5   3.623 ± 0.557   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsSparkVectorized5k      ss    5   3.203 ± 0.209   s/op

   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] kbendick commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
kbendick commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r826560423


##########
File path: site/docs/benchmarks.md
##########
@@ -128,4 +128,8 @@ column used in the filter predicate. The performance is compared to the built-in

 ### SparkParquetWritersNestedDataBenchmark
 * A benchmark that evaluates the performance of writing nested Parquet data using Iceberg and Spark Parquet writers. To run this benchmark for either spark-2 or spark-3:
-  `./gradlew :iceberg-spark:iceberg-spark[2|3]:jmh -PjmhIncludeRegex=SparkParquetWritersNestedDataBenchmark -PjmhOutputPath=benchmark/spark-parquet-writers-nested-data-benchmark-result.txt`
+`./gradlew :iceberg-spark:iceberg-spark[2|3]:jmh -PjmhIncludeRegex=SparkParquetWritersNestedDataBenchmark -PjmhOutputPath=benchmark/spark-parquet-writers-nested-data-benchmark-result.txt`
+
+### VectorizedReadParquetDecimalBenchmark
+* A benchmark to compare performance of reading Parquet decimal data using vectorized Iceberg read path and the built-in file source in Spark.
+`./gradlew :iceberg-spark[2|3]:jmh -PjmhIncludeRegex=VectorizedReadParquetDecimalBenchmark -PjmhOutputPath=benchmark/vectorized-read-parquet-decimal-result.txt`

Review comment:
       Opened a PR with the updated commands for Spark 3.2: https://github.com/apache/iceberg/pull/4328


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] nastra commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
nastra commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r728824889


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       However, I'm not sure we can change stuff for `FIXED_LENGTH_DECIMAL`. See also https://github.com/apache/iceberg/blob/8058ec12da13b88a1724bbc493649f7b8342414e/arrow/src/main/java/org/apache/iceberg/arrow/vectorized/parquet/VectorizedPageIterator.java#L310-L316


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-941962715


   Hi @rdblue, please take a look again, thanks a lot. Update benchmark results:
   ```
   Benchmark                                                                 Mode  Cnt  Score   Error  Units
   VectorizedReadFlatParquetDataBenchmark.readDatesIcebergVectorized5k         ss    5  1.320 ± 0.045   s/op
   VectorizedReadFlatParquetDataBenchmark.readDatesSparkVectorized5k           ss    5  1.348 ± 0.044   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsIcebergVectorized5k      ss    5  8.095 ± 0.308   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsSparkVectorized5k        ss    5  8.013 ± 0.412   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesIcebergVectorized5k       ss    5  2.697 ± 0.113   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesSparkVectorized5k         ss    5  2.224 ± 0.071   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsIcebergVectorized5k        ss    5  2.135 ± 0.030   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsSparkVectorized5k          ss    5  2.233 ± 0.765   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersIcebergVectorized5k      ss    5  2.223 ± 0.043   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersSparkVectorized5k        ss    5  2.479 ± 0.096   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsIcebergVectorized5k         ss    5  2.640 ± 0.041   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsSparkVectorized5k           ss    5  2.498 ± 0.116   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsIcebergVectorized5k       ss    5  4.043 ± 0.486   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsSparkVectorized5k         ss    5  3.809 ± 0.163   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsIcebergVectorized5k    ss    5  1.504 ± 0.298   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsSparkVectorized5k      ss    5  1.856 ± 0.295   s/op
   ```

   ```
   Benchmark                                                                        Mode  Cnt  Score   Error  Units
   VectorizedReadParquetDecimalBenchmark.readDecimalsIcebergVectorized5k              ss    5  7.822 ± 0.441   s/op
   VectorizedReadParquetDecimalBenchmark.readDecimalsSparkVectorized5k                ss    5  7.916 ± 0.908   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsIcebergVectorized5k     ss    5  1.655 ± 0.130   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsSparkVectorized5k       ss    5  1.539 ± 0.104   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsIcebergVectorized5k    ss    5  3.468 ± 0.471   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsSparkVectorized5k      ss    5  3.256 ± 0.587   s/op
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r727742336


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       Here, combined the `FIXED_WIDTH_BINARY` to use `fixedSizeBinaryBatchReader` instead of `fixedWidthTypeBinaryBatchReader`. `fixedWidthTypeBinaryBatchReader` uses `VarBinaryVector`, it should use `FixedSizeBinaryVector`. Please correct me if I am wrong @nastra


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r827586493


##########
File path: site/docs/benchmarks.md
##########
@@ -128,4 +128,8 @@ column used in the filter predicate. The performance is compared to the built-in

 ### SparkParquetWritersNestedDataBenchmark
 * A benchmark that evaluates the performance of writing nested Parquet data using Iceberg and Spark Parquet writers. To run this benchmark for either spark-2 or spark-3:
-  `./gradlew :iceberg-spark:iceberg-spark[2|3]:jmh -PjmhIncludeRegex=SparkParquetWritersNestedDataBenchmark -PjmhOutputPath=benchmark/spark-parquet-writers-nested-data-benchmark-result.txt`
+`./gradlew :iceberg-spark:iceberg-spark[2|3]:jmh -PjmhIncludeRegex=SparkParquetWritersNestedDataBenchmark -PjmhOutputPath=benchmark/spark-parquet-writers-nested-data-benchmark-result.txt`
+
+### VectorizedReadParquetDecimalBenchmark
+* A benchmark to compare performance of reading Parquet decimal data using vectorized Iceberg read path and the built-in file source in Spark.
+`./gradlew :iceberg-spark[2|3]:jmh -PjmhIncludeRegex=VectorizedReadParquetDecimalBenchmark -PjmhOutputPath=benchmark/vectorized-read-parquet-decimal-result.txt`

Review comment:
       Updated


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r727742336


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       Here, combined the `FIXED_WIDTH_BINARY` to use `fixedSizeBinaryBatchReader` instead of `fixedWidthTypeBinaryBatchReader`. `fixedWidthTypeBinaryBatchReader` uses `VarBinaryVector`, it should be use `FixedSizeBinaryVector`. Please correct me if I understand wrong @nastra


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r727742336


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       Here, combined the `FIXED_WIDTH_BINARY` to use `fixedSizeBinaryBatchReader` instead of `fixedWidthTypeBinaryBatchReader`. `fixedWidthTypeBinaryBatchReader` uses `VarBinaryVector`, it should be use `FixedSizeBinaryVector`. Please correct me if I am wrong @nastra


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu edited a comment on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu edited a comment on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-941962715


   Hi @rdblue, please take a look again, thanks a lot. Also update benchmark results:
   ```
   Benchmark                                                                 Mode  Cnt  Score   Error  Units
   VectorizedReadFlatParquetDataBenchmark.readDatesIcebergVectorized5k         ss    5  1.320 ± 0.045   s/op
   VectorizedReadFlatParquetDataBenchmark.readDatesSparkVectorized5k           ss    5  1.348 ± 0.044   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsIcebergVectorized5k      ss    5  8.095 ± 0.308   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsSparkVectorized5k        ss    5  8.013 ± 0.412   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesIcebergVectorized5k       ss    5  2.697 ± 0.113   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesSparkVectorized5k         ss    5  2.224 ± 0.071   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsIcebergVectorized5k        ss    5  2.135 ± 0.030   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsSparkVectorized5k          ss    5  2.233 ± 0.765   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersIcebergVectorized5k      ss    5  2.223 ± 0.043   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersSparkVectorized5k        ss    5  2.479 ± 0.096   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsIcebergVectorized5k         ss    5  2.640 ± 0.041   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsSparkVectorized5k           ss    5  2.498 ± 0.116   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsIcebergVectorized5k       ss    5  4.043 ± 0.486   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsSparkVectorized5k         ss    5  3.809 ± 0.163   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsIcebergVectorized5k    ss    5  1.504 ± 0.298   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsSparkVectorized5k      ss    5  1.856 ± 0.295   s/op
   ```

   ```
   Benchmark                                                                        Mode  Cnt  Score   Error  Units
   VectorizedReadParquetDecimalBenchmark.readDecimalsIcebergVectorized5k              ss    5  7.822 ± 0.441   s/op
   VectorizedReadParquetDecimalBenchmark.readDecimalsSparkVectorized5k                ss    5  7.916 ± 0.908   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsIcebergVectorized5k     ss    5  1.655 ± 0.130   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsSparkVectorized5k       ss    5  1.539 ± 0.104   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsIcebergVectorized5k    ss    5  3.468 ± 0.471   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsSparkVectorized5k      ss    5  3.256 ± 0.587   s/op
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-960514963


   @rdblue @nastra @pvary @kbendick Could you help to review when you have time? Thanks a lot.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-1068690623


   Thanks, @rdblue @kbendick, code has been rebased. Please take a look when you are free.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] nastra commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
nastra commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-938588591


   @ConeyLiu I'll try to review this next week. In the meantime could you please run some [benchmarks](https://iceberg.apache.org/benchmarks/) for this PR and attach the results here?

   So in your case it would be: `./gradlew :iceberg-spark3:jmh -PjmhIncludeRegex=VectorizedReadFlatParquetDataBenchmark -PjmhOutputPath=benchmark/vectorized-read-flat-parquet-data-result.txt`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] kbendick commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
kbendick commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r826568867


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorHolder.java
##########
@@ -36,6 +36,7 @@
   private final Dictionary dictionary;
   private final NullabilityHolder nullabilityHolder;
   private final Type icebergType;
+  private final Type originalIcebergType;

Review comment:
       Not sure if this comment is up to date or not, and if you’re planning on keeping both fields.

   But would it make sense to use terms like iceberg type, logical type, and physical type?

   In your example of the parquet int backed decimal, I would call the field that is integer as `physicalType` and the decimal field as `logicalType`.

   I feel these terms are more self documenting and wouldn’t require the comment here. How you choose to name them exactly is up to you, but the terms physical / logical are much more self documenting in my opinion.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] nastra commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
nastra commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r728828579


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorHolder.java
##########
@@ -51,6 +52,25 @@ public VectorHolder(
     this.dictionary = dictionary;
     this.nullabilityHolder = holder;
     this.icebergType = type;
+    this.originalIcebergType = type;
+  }
+
+  public VectorHolder(

Review comment:
       same here, do we need to keep the other constructor or can it be removed?

##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -83,13 +84,28 @@ public VectorizedArrowReader(
       BufferAllocator ra,
       boolean setArrowValidityVector) {
     this.icebergField = icebergField;
+    this.originalIcebergField = icebergField;
+    this.columnDescriptor = desc;
+    this.rootAlloc = ra;
+    this.vectorizedColumnIterator = new VectorizedColumnIterator(desc, "", setArrowValidityVector);
+  }
+
+  public VectorizedArrowReader(
+      ColumnDescriptor desc,
+      Types.NestedField icebergField,
+      Types.NestedField originalIcebergField,

Review comment:
       @rdblue do we need to keep the original constructor without the `originalIcebergField` or could it be removed?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-938580907


   Hi @rdblue @jackye1995 @nastra, could you help to review this? thanks a lot.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-941962715


   Hi @rdblue, please take a look again, thanks a lot. Update benchmark results:
   ```
   Benchmark                                                                 Mode  Cnt  Score   Error  Units
   VectorizedReadFlatParquetDataBenchmark.readDatesIcebergVectorized5k         ss    5  1.320 ± 0.045   s/op
   VectorizedReadFlatParquetDataBenchmark.readDatesSparkVectorized5k           ss    5  1.348 ± 0.044   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsIcebergVectorized5k      ss    5  8.095 ± 0.308   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsSparkVectorized5k        ss    5  8.013 ± 0.412   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesIcebergVectorized5k       ss    5  2.697 ± 0.113   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesSparkVectorized5k         ss    5  2.224 ± 0.071   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsIcebergVectorized5k        ss    5  2.135 ± 0.030   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsSparkVectorized5k          ss    5  2.233 ± 0.765   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersIcebergVectorized5k      ss    5  2.223 ± 0.043   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersSparkVectorized5k        ss    5  2.479 ± 0.096   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsIcebergVectorized5k         ss    5  2.640 ± 0.041   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsSparkVectorized5k           ss    5  2.498 ± 0.116   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsIcebergVectorized5k       ss    5  4.043 ± 0.486   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsSparkVectorized5k         ss    5  3.809 ± 0.163   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsIcebergVectorized5k    ss    5  1.504 ± 0.298   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsSparkVectorized5k      ss    5  1.856 ± 0.295   s/op
   ```

   ```
   Benchmark                                                                        Mode  Cnt  Score   Error  Units
   VectorizedReadParquetDecimalBenchmark.readDecimalsIcebergVectorized5k              ss    5  7.822 ± 0.441   s/op
   VectorizedReadParquetDecimalBenchmark.readDecimalsSparkVectorized5k                ss    5  7.916 ± 0.908   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsIcebergVectorized5k     ss    5  1.655 ± 0.130   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsSparkVectorized5k       ss    5  1.539 ± 0.104   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsIcebergVectorized5k    ss    5  3.468 ± 0.471   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsSparkVectorized5k      ss    5  3.256 ± 0.587   s/op
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r725681381


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/GenericArrowVectorAccessorFactory.java
##########
@@ -163,12 +188,20 @@ protected GenericArrowVectorAccessorFactory(

   @SuppressWarnings("checkstyle:CyclomaticComplexity")
   private ArrowVectorAccessor<DecimalT, Utf8StringT, ArrayT, ChildVectorT>
-      getPlainVectorAccessor(FieldVector vector) {
+      getPlainVectorAccessor(FieldVector vector, PrimitiveType primitive) {
     if (vector instanceof BitVector) {
       return new BooleanAccessor<>((BitVector) vector);
     } else if (vector instanceof IntVector) {
+      if (primitive != null && OriginalType.DECIMAL.equals(primitive.getOriginalType()) &&
+          useIntVectorForIntBackedDecimal) {

Review comment:
       Why does this check the config property? If the type is a decimal and it is encoded as an `IntVector`, then  this should always use the right accessor.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r727740396


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorHolder.java
##########
@@ -36,6 +36,7 @@
   private final Dictionary dictionary;
   private final NullabilityHolder nullabilityHolder;
   private final Type icebergType;
+  private final Type originalIcebergType;

Review comment:
       `icebergType` indicates the corresponding iceberg type of the `FieldVector`, `originalIcebergType` indicates what the real type we will read from the `FieldVector`. For example, the parquet int backed decimal, the `icebergType` should be integer, `originalIcebergType` is decimal.

   I intend to only keep the `originalIcebergType`, but listening to your ideas.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu edited a comment on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu edited a comment on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-941962715


   Hi @rdblue, please take a look again, thanks a lot. Also update benchmark results:
   ```
   Benchmark                                                                 Mode  Cnt  Score   Error  Units
   VectorizedReadFlatParquetDataBenchmark.readDatesIcebergVectorized5k         ss    5  1.320 ± 0.045   s/op
   VectorizedReadFlatParquetDataBenchmark.readDatesSparkVectorized5k           ss    5  1.348 ± 0.044   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsIcebergVectorized5k      ss    5  8.095 ± 0.308   s/op
   VectorizedReadFlatParquetDataBenchmark.readDecimalsSparkVectorized5k        ss    5  8.013 ± 0.412   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesIcebergVectorized5k       ss    5  2.697 ± 0.113   s/op
   VectorizedReadFlatParquetDataBenchmark.readDoublesSparkVectorized5k         ss    5  2.224 ± 0.071   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsIcebergVectorized5k        ss    5  2.135 ± 0.030   s/op
   VectorizedReadFlatParquetDataBenchmark.readFloatsSparkVectorized5k          ss    5  2.233 ± 0.765   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersIcebergVectorized5k      ss    5  2.223 ± 0.043   s/op
   VectorizedReadFlatParquetDataBenchmark.readIntegersSparkVectorized5k        ss    5  2.479 ± 0.096   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsIcebergVectorized5k         ss    5  2.640 ± 0.041   s/op
   VectorizedReadFlatParquetDataBenchmark.readLongsSparkVectorized5k           ss    5  2.498 ± 0.116   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsIcebergVectorized5k       ss    5  4.043 ± 0.486   s/op
   VectorizedReadFlatParquetDataBenchmark.readStringsSparkVectorized5k         ss    5  3.809 ± 0.163   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsIcebergVectorized5k    ss    5  1.504 ± 0.298   s/op
   VectorizedReadFlatParquetDataBenchmark.readTimestampsSparkVectorized5k      ss    5  1.856 ± 0.295   s/op
   ```

   ```
   Benchmark                                                                        Mode  Cnt  Score   Error  Units
   VectorizedReadParquetDecimalBenchmark.readDecimalsIcebergVectorized5k              ss    5  7.822 ± 0.441   s/op
   VectorizedReadParquetDecimalBenchmark.readDecimalsSparkVectorized5k                ss    5  7.916 ± 0.908   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsIcebergVectorized5k     ss    5  1.655 ± 0.130   s/op
   VectorizedReadParquetDecimalBenchmark.readIntBackedDecimalsSparkVectorized5k       ss    5  1.539 ± 0.104   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsIcebergVectorized5k    ss    5  3.468 ± 0.471   s/op
   VectorizedReadParquetDecimalBenchmark.readLongBackedDecimalsSparkVectorized5k      ss    5  3.256 ± 0.587   s/op
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r727740396


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorHolder.java
##########
@@ -36,6 +36,7 @@
   private final Dictionary dictionary;
   private final NullabilityHolder nullabilityHolder;
   private final Type icebergType;
+  private final Type originalIcebergType;

Review comment:
       `icebergType` indicates the corresponding iceberg type of the `FieldVector`, `originalIcebergType` indicates what the real type we will read from the `FieldVector`. For example, the parquet int backed decimal, the `icebergType` should be integer, `originalIcebergType` is decimal.

   I intend to only keep the `originalIcebergType`, but listening to your ideas.

##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       Here, combined the `FIXED_WIDTH_BINARY` to use `fixedSizeBinaryBatchReader` instead of `fixedWidthTypeBinaryBatchReader`. `fixedWidthTypeBinaryBatchReader` uses `VarBinaryVector`, it should be use `FixedSizeBinaryVector`. Please correct me if I understand wrong @nastra

##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       Here, combined the `FIXED_WIDTH_BINARY` to use `fixedSizeBinaryBatchReader` instead of `fixedWidthTypeBinaryBatchReader`. `fixedWidthTypeBinaryBatchReader` uses `VarBinaryVector`, it should be use `FixedSizeBinaryVector`. Please correct me if I am wrong @nastra

##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       Here, combined the `FIXED_WIDTH_BINARY` to use `fixedSizeBinaryBatchReader` instead of `fixedWidthTypeBinaryBatchReader`. `fixedWidthTypeBinaryBatchReader` uses `VarBinaryVector`, it should use `FixedSizeBinaryVector`. Please correct me if I am wrong @nastra


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-939534012


   @ConeyLiu, this looks like an improvement, but I think that it relies too heavily on config properties that must be set the same way everywhere rather than detecting what should be done from inputs.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r827586654


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorHolder.java
##########
@@ -36,6 +36,7 @@
   private final Dictionary dictionary;
   private final NullabilityHolder nullabilityHolder;
   private final Type icebergType;
+  private final Type originalIcebergType;

Review comment:
       Updated


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] nastra commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
nastra commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r728819327


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -171,6 +177,8 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.timestampMillisBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case UUID:
+          case FIXED_WIDTH_BINARY:
+          case FIXED_LENGTH_DECIMAL:

Review comment:
       yep those changes for `FIXED_WIDTH_BINARY` are correct. Note that support for `FIXED` is being added as part of https://github.com/apache/iceberg/pull/3029

##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/GenericArrowVectorAccessorFactory.java
##########
@@ -92,19 +93,21 @@ protected GenericArrowVectorAccessorFactory(
     Dictionary dictionary = holder.dictionary();
     boolean isVectorDictEncoded = holder.isDictionaryEncoded();
     FieldVector vector = holder.vector();
+    ColumnDescriptor desc = holder.descriptor();
+    // desc could be null when the holder is PositionVectorHolder
+    PrimitiveType primitive = desc == null ? null : desc.getPrimitiveType();
     if (isVectorDictEncoded) {
-      ColumnDescriptor desc = holder.descriptor();
-      PrimitiveType primitive = desc.getPrimitiveType();
       return getDictionaryVectorAccessor(dictionary, desc, vector, primitive);
     } else {
-      return getPlainVectorAccessor(vector);
+      return getPlainVectorAccessor(vector, primitive);
     }
   }

   private ArrowVectorAccessor<DecimalT, Utf8StringT, ArrayT, ChildVectorT> getDictionaryVectorAccessor(
       Dictionary dictionary,
       ColumnDescriptor desc,
       FieldVector vector, PrimitiveType primitive) {
+    Preconditions.checkState(primitive != null, "Primitive should not be null");

Review comment:
       PrimitiveType should not be null


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#issuecomment-939532601


   Running CI


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r725681727


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -140,10 +162,18 @@ public VectorHolder read(VectorHolder reuse, int numValsToRead) {
             vectorizedColumnIterator.fixedLengthDecimalBatchReader().nextBatch(vec, typeWidth, nullabilityHolder);
             break;
           case INT_BACKED_DECIMAL:
-            vectorizedColumnIterator.intBackedDecimalBatchReader().nextBatch(vec, -1, nullabilityHolder);
+            if (useIntVectorForIntBackedDecimal) {

Review comment:
       I don't think this should check the property. It should check the destination vector's type and use the appropriate reader for the vector. That way only allocation needs to worry about this configuration.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r725682143


##########
File path: spark/src/main/java/org/apache/iceberg/spark/source/BatchDataReader.java
##########
@@ -75,7 +75,8 @@
           .project(expectedSchema)
           .split(task.start(), task.length())
           .createBatchedReaderFunc(fileSchema -> VectorizedSparkParquetReaders.buildReader(expectedSchema,
-              fileSchema, /* setArrowValidityVector */ NullCheckingForGet.NULL_CHECKING_ENABLED, idToConstant))
+              fileSchema, /* setArrowValidityVector */ NullCheckingForGet.NULL_CHECKING_ENABLED, idToConstant,
+              true, true))

Review comment:
       Why does `VectorizedSparkParquetReaders` expose boolean properties? I think it should set them internally instead.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] rdblue commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
rdblue commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r725681939


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/VectorizedArrowReader.java
##########
@@ -262,19 +292,35 @@ private void allocateVectorBasedOnOriginalType(PrimitiveType primitive, Field ar
         this.typeWidth = 8;
         break;
       case DECIMAL:
-        this.vec = arrowField.createVector(rootAlloc);
-        ((DecimalVector) vec).allocateNew(batchSize);
         switch (primitive.getPrimitiveTypeName()) {
           case BINARY:
           case FIXED_LEN_BYTE_ARRAY:
+            this.vec = arrowField.createVector(rootAlloc);
+            ((DecimalVector) vec).allocateNew(batchSize);
             this.readType = ReadType.FIXED_LENGTH_DECIMAL;
             this.typeWidth = primitive.getTypeLength();
             break;
           case INT64:
+            if (useLongVectorForLongBackedDecimal) {
+              Field field = ArrowSchemaUtil.convertToLong(icebergField);

Review comment:
       I don't think conversion should be re-done here. Can you make it so that this is handed the correct converted field in the first place? Then you'd just need to detect that the field is a long or int rather than checking the config property in so many places.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] ConeyLiu commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
ConeyLiu commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r827586584


##########
File path: arrow/src/main/java/org/apache/iceberg/arrow/vectorized/GenericArrowVectorAccessorFactory.java
##########
@@ -92,19 +93,21 @@ protected GenericArrowVectorAccessorFactory(
     Dictionary dictionary = holder.dictionary();
     boolean isVectorDictEncoded = holder.isDictionaryEncoded();
     FieldVector vector = holder.vector();
+    ColumnDescriptor desc = holder.descriptor();
+    // desc could be null when the holder is PositionVectorHolder
+    PrimitiveType primitive = desc == null ? null : desc.getPrimitiveType();
     if (isVectorDictEncoded) {
-      ColumnDescriptor desc = holder.descriptor();
-      PrimitiveType primitive = desc.getPrimitiveType();
       return getDictionaryVectorAccessor(dictionary, desc, vector, primitive);
     } else {
-      return getPlainVectorAccessor(vector);
+      return getPlainVectorAccessor(vector, primitive);
     }
   }

   private ArrowVectorAccessor<DecimalT, Utf8StringT, ArrayT, ChildVectorT> getDictionaryVectorAccessor(
       Dictionary dictionary,
       ColumnDescriptor desc,
       FieldVector vector, PrimitiveType primitive) {
+    Preconditions.checkState(primitive != null, "Primitive should not be null");

Review comment:
       Removed the checking.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org
[GitHub] [iceberg] kbendick commented on a change in pull request #3249: Optimized spark vectorized read parquet decimal
Posted by GitBox <gi...@apache.org>.
kbendick commented on a change in pull request #3249:
URL: https://github.com/apache/iceberg/pull/3249#discussion_r826553736


##########
File path: site/docs/benchmarks.md
##########
@@ -128,4 +128,8 @@ column used in the filter predicate. The performance is compared to the built-in

 ### SparkParquetWritersNestedDataBenchmark
 * A benchmark that evaluates the performance of writing nested Parquet data using Iceberg and Spark Parquet writers. To run this benchmark for either spark-2 or spark-3:
-  `./gradlew :iceberg-spark:iceberg-spark[2|3]:jmh -PjmhIncludeRegex=SparkParquetWritersNestedDataBenchmark -PjmhOutputPath=benchmark/spark-parquet-writers-nested-data-benchmark-result.txt`
+`./gradlew :iceberg-spark:iceberg-spark[2|3]:jmh -PjmhIncludeRegex=SparkParquetWritersNestedDataBenchmark -PjmhOutputPath=benchmark/spark-parquet-writers-nested-data-benchmark-result.txt`
+
+### VectorizedReadParquetDecimalBenchmark
+* A benchmark to compare performance of reading Parquet decimal data using vectorized Iceberg read path and the built-in file source in Spark.
+`./gradlew :iceberg-spark[2|3]:jmh -PjmhIncludeRegex=VectorizedReadParquetDecimalBenchmark -PjmhOutputPath=benchmark/vectorized-read-parquet-decimal-result.txt`

Review comment:
       These benchmarking commands are relatively out of date btw. I’ll open a PR to update them in the files and then you can copy from there if you’d like?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@iceberg.apache.org
For additional commands, e-mail: issues-help@iceberg.apache.org