You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@iotdb.apache.org by ha...@apache.org on 2023/03/01 10:02:39 UTC
[iotdb] branch rel/1.0 updated: [To rel/1.0]docs(site): image move to site depend on https://github.com/apache/iotdb/pull/9182 (#9186)
This is an automated email from the ASF dual-hosted git repository.
haonan pushed a commit to branch rel/1.0
in repository https://gitbox.apache.org/repos/asf/iotdb.git
The following commit(s) were added to refs/heads/rel/1.0 by this push:
new fd2649b264 [To rel/1.0]docs(site): image move to site depend on https://github.com/apache/iotdb/pull/9182 (#9186)
fd2649b264 is described below
commit fd2649b264c08095d597372b9ca9fd036b9ccc46
Author: CritasWang <cr...@outlook.com>
AuthorDate: Wed Mar 1 18:02:33 2023 +0800
[To rel/1.0]docs(site): image move to site depend on https://github.com/apache/iotdb/pull/9182 (#9186)
---
docs/UserGuide/API/InfluxDB-Protocol.md | 10 ++--
docs/UserGuide/API/Programming-JDBC.md | 2 +-
docs/UserGuide/API/Programming-MQTT.md | 4 +-
.../UserGuide/API/Programming-Python-Native-API.md | 2 +-
docs/UserGuide/Cluster/Cluster-Concept.md | 4 +-
docs/UserGuide/Cluster/Cluster-Maintenance.md | 2 +-
.../Data-Concept/Data-Model-and-Terminology.md | 4 +-
docs/UserGuide/Data-Concept/Schema-Template.md | 6 +--
docs/UserGuide/Data-Concept/Time-Partition.md | 2 +-
docs/UserGuide/Ecosystem-Integration/DBeaver.md | 16 +++---
.../Ecosystem-Integration/Grafana-Connector.md | 6 +--
.../Ecosystem-Integration/Grafana-Plugin.md | 58 +++++++++++-----------
docs/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md | 2 +-
.../UserGuide/Ecosystem-Integration/Spark-IoTDB.md | 2 +-
.../Ecosystem-Integration/Spark-TsFile.md | 4 +-
.../Ecosystem-Integration/Writing-Data-on-HDFS.md | 2 +-
.../Ecosystem-Integration/Zeppelin-IoTDB.md | 8 +--
.../Edge-Cloud-Collaboration/Sync-Tool.md | 4 +-
.../Integration-Test-refactoring-tutorial.md | 4 +-
docs/UserGuide/IoTDB-Introduction/Architecture.md | 2 +-
docs/UserGuide/IoTDB-Introduction/Scenario.md | 14 +++---
docs/UserGuide/Maintenance-Tools/JMX-Tool.md | 4 +-
docs/UserGuide/Maintenance-Tools/Log-Tool.md | 6 +--
docs/UserGuide/Monitor-Alert/Alerting.md | 2 +-
docs/UserGuide/Monitor-Alert/Metric-Tool.md | 10 ++--
.../Operate-Metadata/Auto-Create-MetaData.md | 2 +-
docs/UserGuide/Operate-Metadata/Node.md | 2 +-
docs/UserGuide/Operate-Metadata/Timeseries.md | 2 +-
.../Operators-Functions/Continuous-Interval.md | 8 +--
docs/UserGuide/Operators-Functions/Sample.md | 10 ++--
.../Operators-Functions/User-Defined-Function.md | 10 ++--
docs/UserGuide/Query-Data/Continuous-Query.md | 8 +--
docs/UserGuide/Query-Data/Group-By.md | 10 ++--
.../UserGuide/QuickStart/Command-Line-Interface.md | 28 +++++------
docs/UserGuide/QuickStart/QuickStart.md | 2 +-
docs/UserGuide/Reference/Common-Config-Manual.md | 4 +-
docs/UserGuide/Reference/SQL-Reference.md | 4 +-
docs/UserGuide/Reference/TSDB-Comparison.md | 16 +++---
docs/UserGuide/Syntax-Conventions/Identifier.md | 2 +-
docs/UserGuide/Syntax-Conventions/KeyValue-Pair.md | 4 +-
.../UserGuide/Syntax-Conventions/Literal-Values.md | 10 ++--
.../Syntax-Conventions/NodeName-In-Path.md | 12 ++---
.../Syntax-Conventions/Session-And-TsFile-API.md | 18 +++----
docs/UserGuide/UserGuideReadme.md | 5 +-
docs/zh/UserGuide/API/InfluxDB-Protocol.md | 10 ++--
docs/zh/UserGuide/API/Programming-JDBC.md | 2 +-
docs/zh/UserGuide/API/Programming-MQTT.md | 4 +-
.../UserGuide/API/Programming-Python-Native-API.md | 2 +-
docs/zh/UserGuide/Cluster/Cluster-Concept.md | 4 +-
docs/zh/UserGuide/Cluster/Cluster-Maintenance.md | 2 +-
.../Data-Concept/Data-Model-and-Terminology.md | 4 +-
docs/zh/UserGuide/Data-Concept/Schema-Template.md | 6 +--
docs/zh/UserGuide/Data-Concept/Time-Partition.md | 2 +-
docs/zh/UserGuide/Ecosystem-Integration/DBeaver.md | 16 +++---
.../Ecosystem-Integration/Grafana-Connector.md | 6 +--
.../Ecosystem-Integration/Grafana-Plugin.md | 58 +++++++++++-----------
.../UserGuide/Ecosystem-Integration/NiFi-IoTDB.md | 2 +-
.../Ecosystem-Integration/Writing-Data-on-HDFS.md | 2 +-
.../Ecosystem-Integration/Zeppelin-IoTDB.md | 8 +--
.../Edge-Cloud-Collaboration/Sync-Tool.md | 14 +++---
.../Integration-Test-refactoring-tutorial.md | 4 +-
.../UserGuide/IoTDB-Introduction/Architecture.md | 2 +-
docs/zh/UserGuide/IoTDB-Introduction/Scenario.md | 14 +++---
docs/zh/UserGuide/Maintenance-Tools/JMX-Tool.md | 4 +-
docs/zh/UserGuide/Maintenance-Tools/Log-Tool.md | 6 +--
docs/zh/UserGuide/Monitor-Alert/Alerting.md | 2 +-
docs/zh/UserGuide/Monitor-Alert/Metric-Tool.md | 10 ++--
.../Operate-Metadata/Auto-Create-MetaData.md | 2 +-
docs/zh/UserGuide/Operate-Metadata/Node.md | 2 +-
docs/zh/UserGuide/Operate-Metadata/Timeseries.md | 2 +-
.../Operators-Functions/Continuous-Interval.md | 8 +--
docs/zh/UserGuide/Operators-Functions/Overview.md | 12 ++---
docs/zh/UserGuide/Operators-Functions/Sample.md | 10 ++--
.../Operators-Functions/User-Defined-Function.md | 10 ++--
docs/zh/UserGuide/Query-Data/Continuous-Query.md | 8 +--
docs/zh/UserGuide/Query-Data/Group-By.md | 10 ++--
.../UserGuide/QuickStart/Command-Line-Interface.md | 26 +++++-----
docs/zh/UserGuide/QuickStart/QuickStart.md | 2 +-
docs/zh/UserGuide/Reference/SQL-Reference.md | 4 +-
docs/zh/UserGuide/Reference/TSDB-Comparison.md | 14 +++---
docs/zh/UserGuide/Syntax-Conventions/Identifier.md | 2 +-
.../UserGuide/Syntax-Conventions/KeyValue-Pair.md | 4 +-
.../UserGuide/Syntax-Conventions/Literal-Values.md | 14 +++---
.../Syntax-Conventions/NodeName-In-Path.md | 12 ++---
.../Syntax-Conventions/Session-And-TsFile-API.md | 18 +++----
docs/zh/UserGuide/Trigger/Implement-Trigger.md | 4 +-
docs/zh/UserGuide/UserGuideReadme.md | 7 ++-
87 files changed, 345 insertions(+), 347 deletions(-)
diff --git a/docs/UserGuide/API/InfluxDB-Protocol.md b/docs/UserGuide/API/InfluxDB-Protocol.md
index a09651d35e..9dc61fa040 100644
--- a/docs/UserGuide/API/InfluxDB-Protocol.md
+++ b/docs/UserGuide/API/InfluxDB-Protocol.md
@@ -51,9 +51,9 @@ InfluxDB influxDB = IoTDBInfluxDBFactory.connect(openurl, username, password);
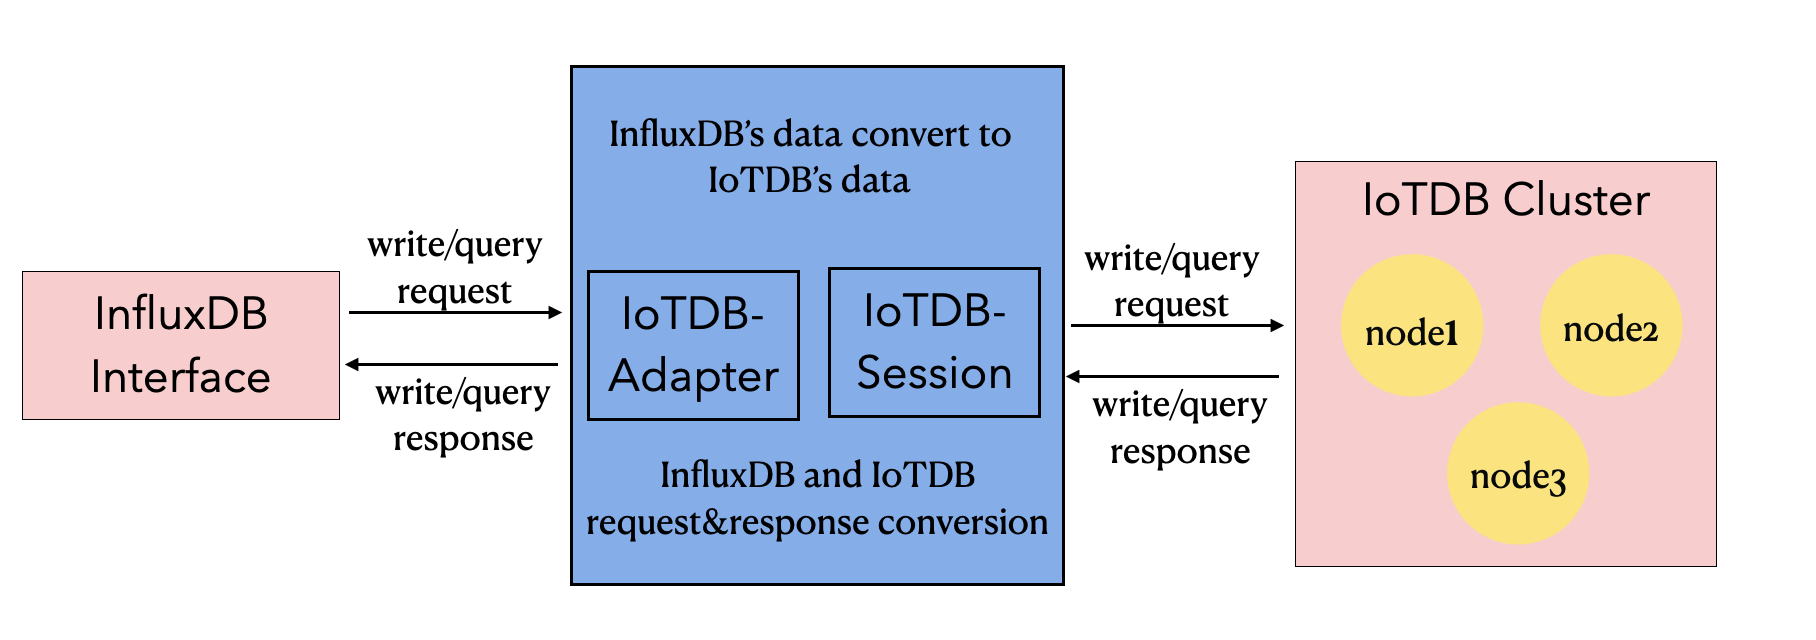
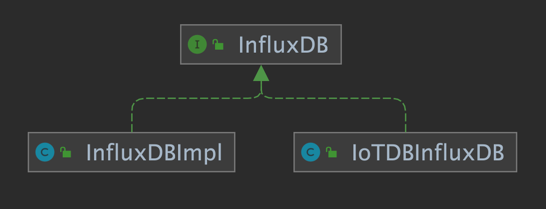
Based on the IoTDB Java ServiceProvider interface, the adapter implements the 'interface InfluxDB' of the java interface of InfluxDB, and provides users with all the interface methods of InfluxDB. End users can use the InfluxDB protocol to initiate write and read requests to IoTDB without perception.
-
+
-
+
### 2.2 Metadata Format Conversion
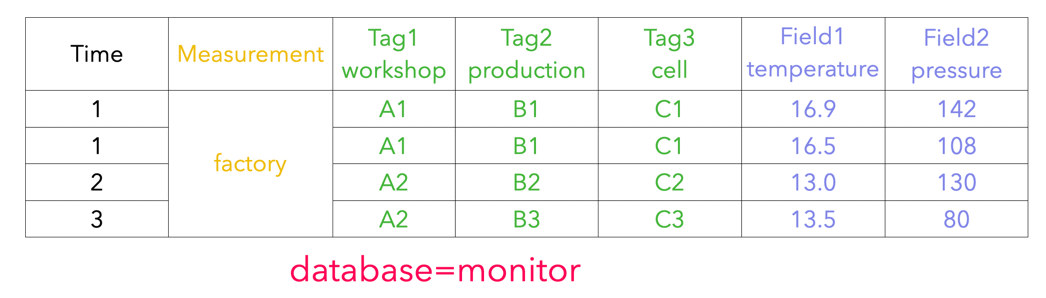
@@ -66,7 +66,7 @@ The metadata of InfluxDB is tag field model, and the metadata of IoTDB is tree m
3. tags: various indexed attributes.
4. fields: various record values(attributes without index).
-
+
#### 2.2.2 IoTDB Metadata
@@ -74,7 +74,7 @@ The metadata of InfluxDB is tag field model, and the metadata of IoTDB is tree m
2. path(time series ID): storage path.
3. measurement: physical quantity.
-
+
#### 2.2.3 Mapping relationship between the two
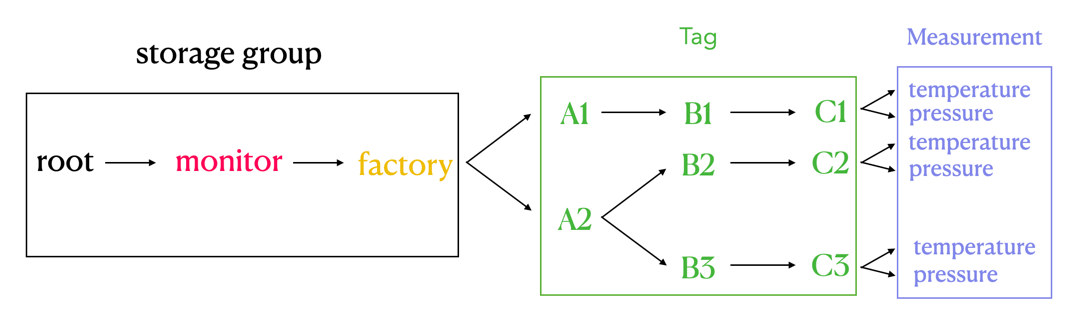
@@ -87,7 +87,7 @@ The transformation relationship from InfluxDB metadata to IoTDB metadata can be
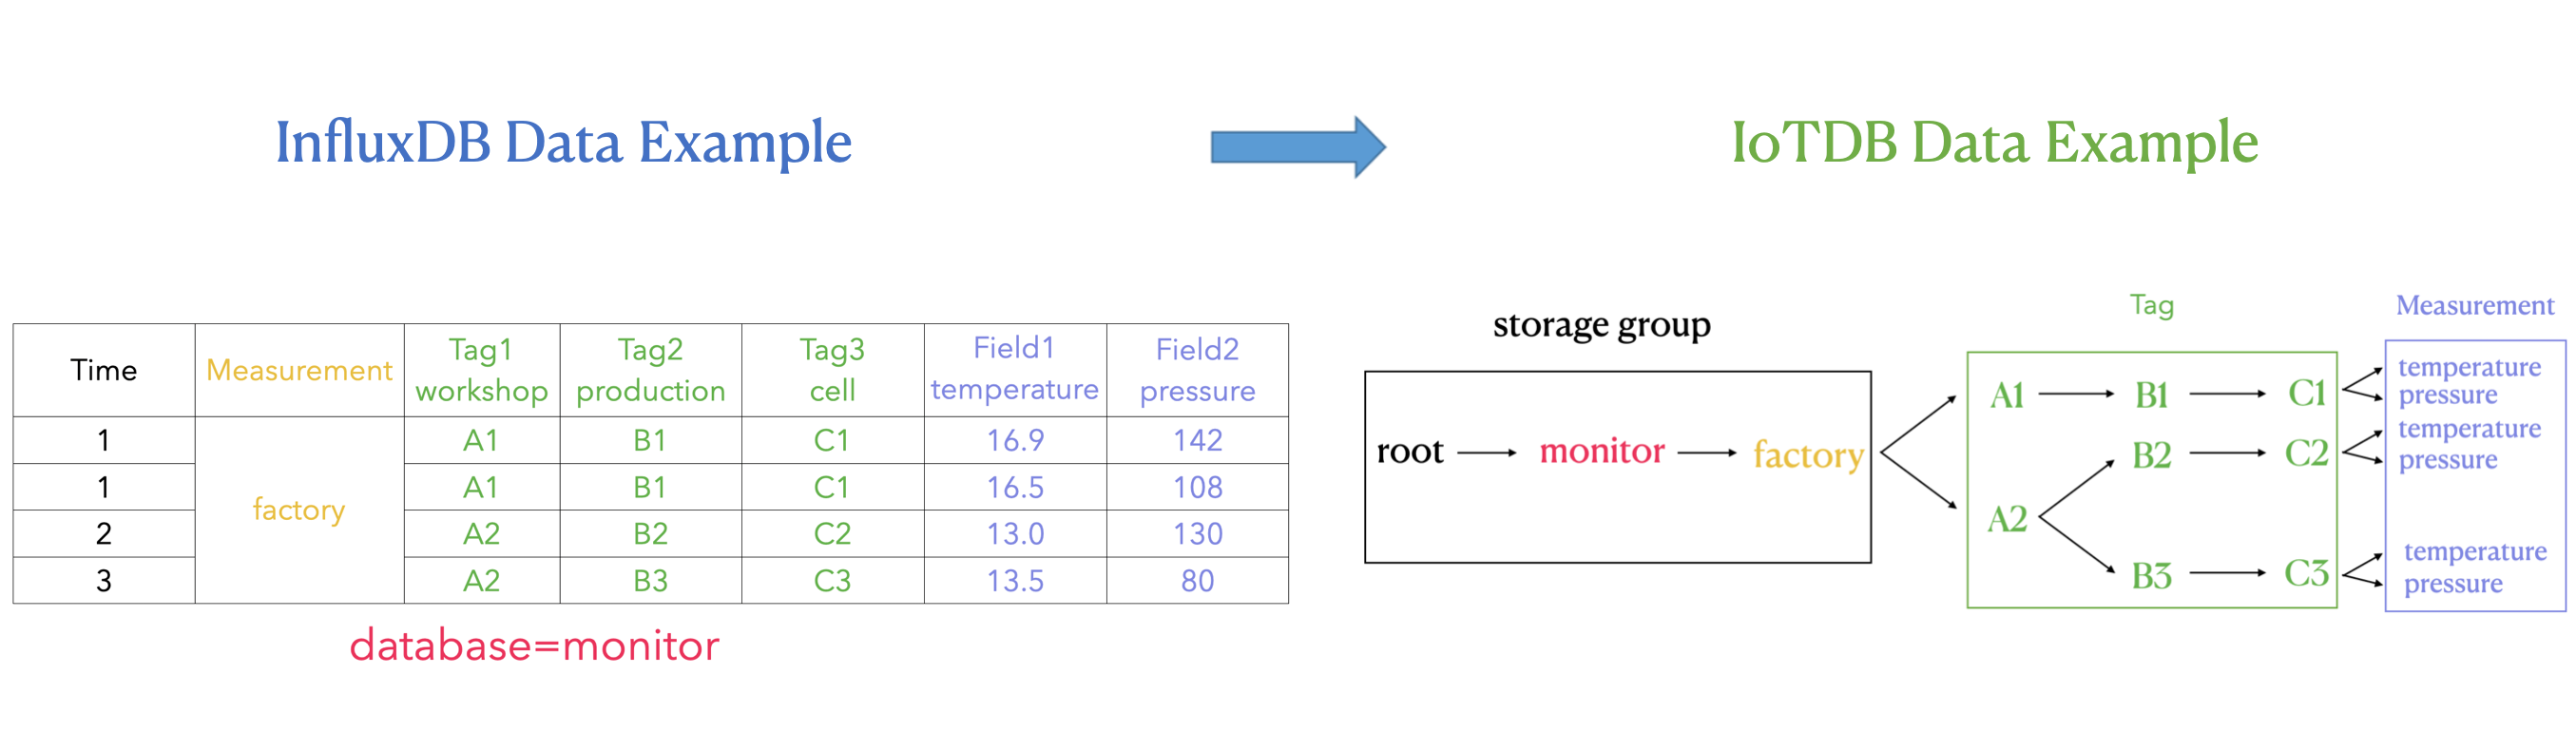
`root.{database}.{measurement}.{tag value 1}.{tag value 2}...{tag value N-1}.{tag value N}.{field key}`
-
+
As shown in the figure above, it can be seen that:
diff --git a/docs/UserGuide/API/Programming-JDBC.md b/docs/UserGuide/API/Programming-JDBC.md
index 3122634563..0329282ad1 100644
--- a/docs/UserGuide/API/Programming-JDBC.md
+++ b/docs/UserGuide/API/Programming-JDBC.md
@@ -64,7 +64,7 @@ It requires including the packages containing the JDBC classes needed for databa
**NOTE: For faster insertion, the insertTablet() in Session is recommended.**
-```Java
+```java
import java.sql.*;
import org.apache.iotdb.jdbc.IoTDBSQLException;
diff --git a/docs/UserGuide/API/Programming-MQTT.md b/docs/UserGuide/API/Programming-MQTT.md
index db3b1eb776..6104f5d78b 100644
--- a/docs/UserGuide/API/Programming-MQTT.md
+++ b/docs/UserGuide/API/Programming-MQTT.md
@@ -27,7 +27,7 @@ It is useful for connections with remote locations where a small code footprint
IoTDB supports the MQTT v3.1(an OASIS Standard) protocol.
IoTDB server includes a built-in MQTT service that allows remote devices send messages into IoTDB server directly.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/6711230/78357432-0c71cf80-75e4-11ea-98aa-c43a54d469ce.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/78357432-0c71cf80-75e4-11ea-98aa-c43a54d469ce.png">
### Built-in MQTT Service
@@ -56,7 +56,7 @@ or
```
or json array of the above two.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/6711230/78357469-1bf11880-75e4-11ea-978f-a53996667a0d.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/78357469-1bf11880-75e4-11ea-978f-a53996667a0d.png">
### MQTT Configurations
The IoTDB MQTT service load configurations from `${IOTDB_HOME}/${IOTDB_CONF}/iotdb-datanode.properties` by default.
diff --git a/docs/UserGuide/API/Programming-Python-Native-API.md b/docs/UserGuide/API/Programming-Python-Native-API.md
index 30ea146e4b..827f3ec3bd 100644
--- a/docs/UserGuide/API/Programming-Python-Native-API.md
+++ b/docs/UserGuide/API/Programming-Python-Native-API.md
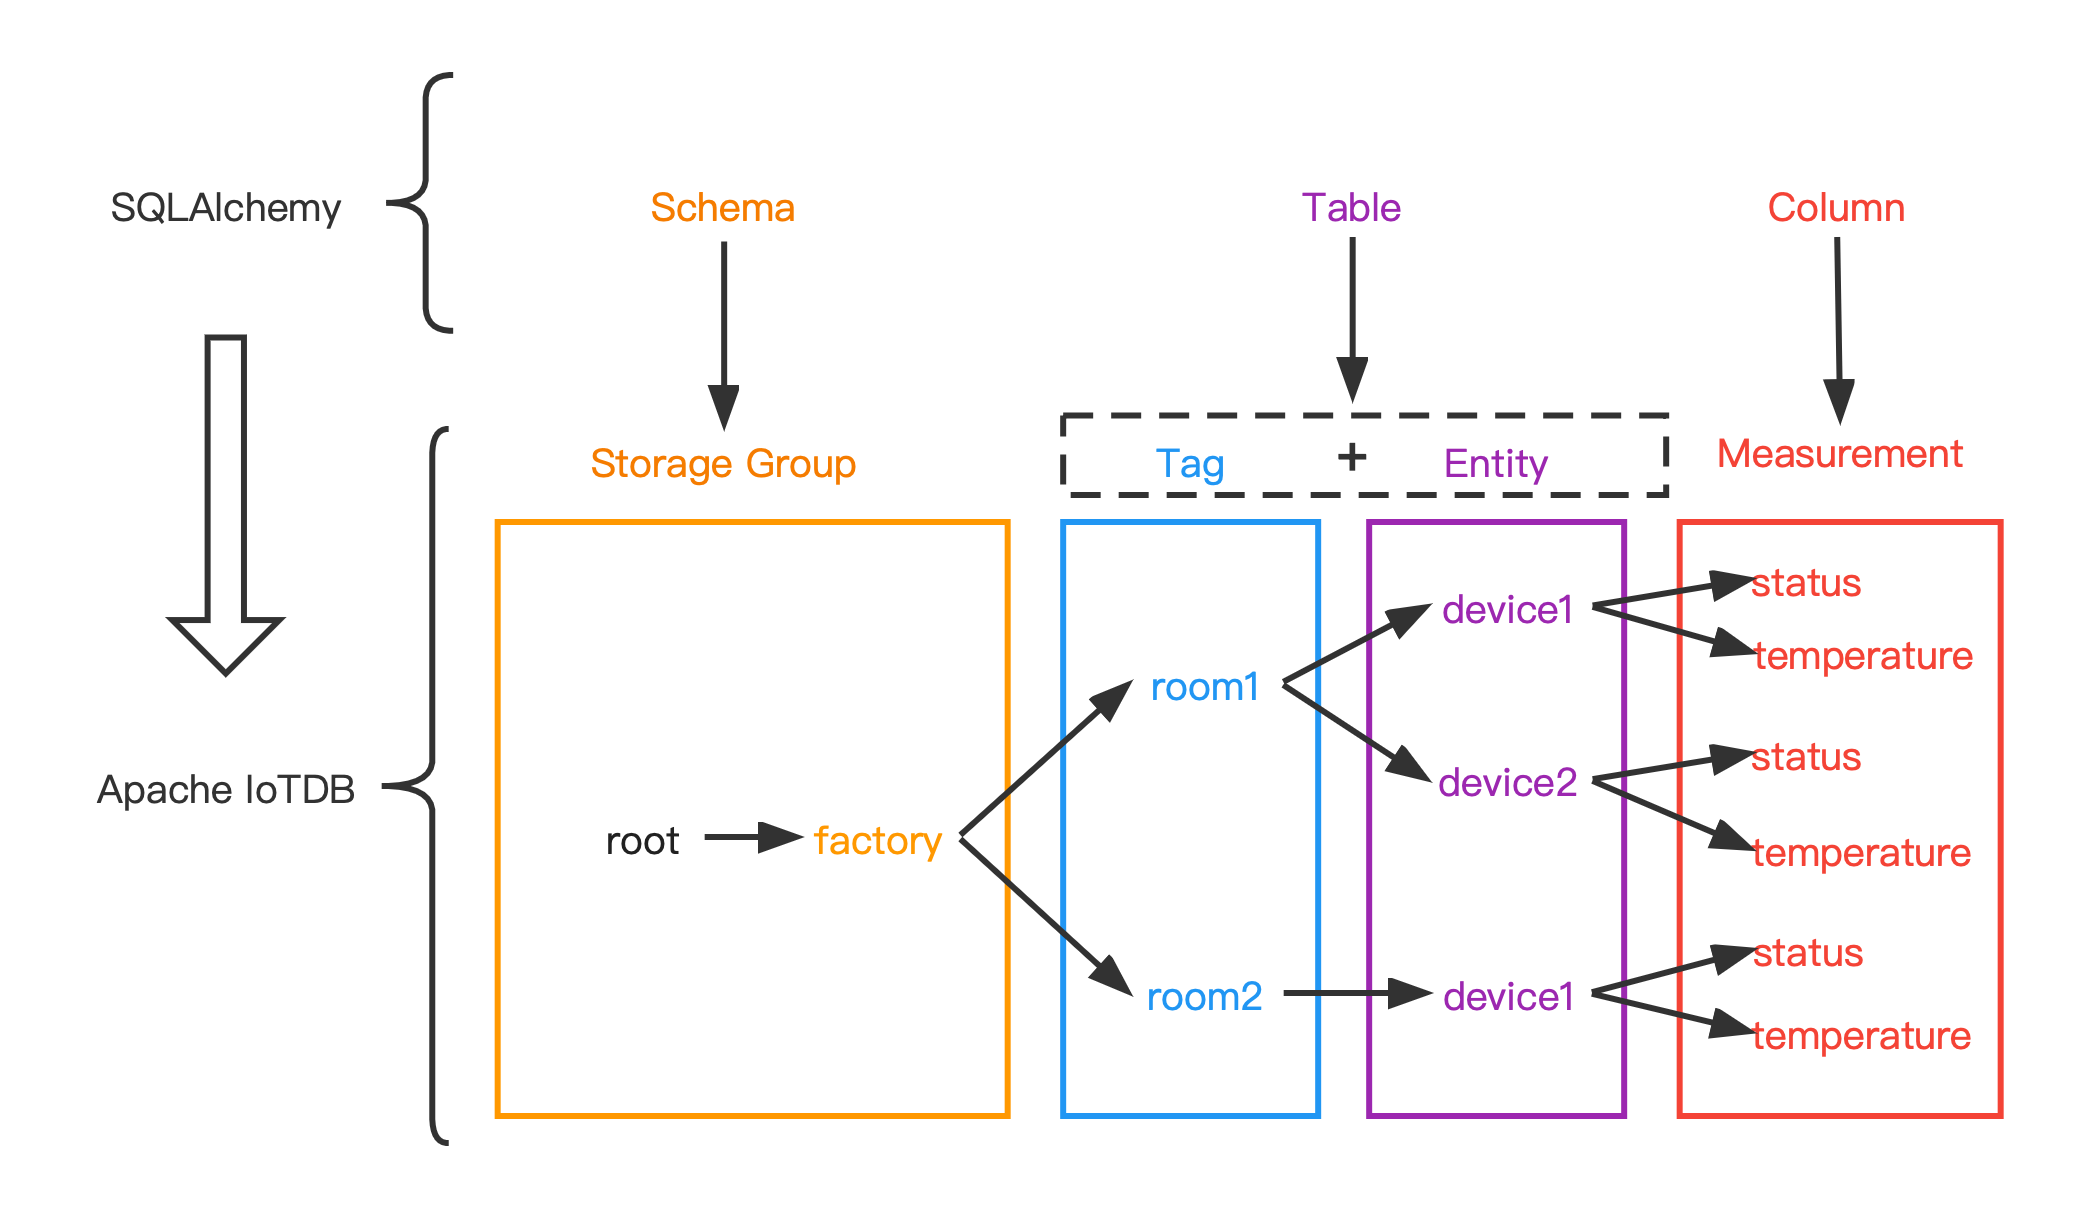
@@ -478,7 +478,7 @@ The mapping relationship between them is:
The following figure shows the relationship between the two more intuitively:
-
+
#### Data type mapping
| data type in IoTDB | data type in SQLAlchemy |
diff --git a/docs/UserGuide/Cluster/Cluster-Concept.md b/docs/UserGuide/Cluster/Cluster-Concept.md
index 25773dd10b..5131adc865 100644
--- a/docs/UserGuide/Cluster/Cluster-Concept.md
+++ b/docs/UserGuide/Cluster/Cluster-Concept.md
@@ -27,7 +27,7 @@ Apache IoTDB Cluster contains two types of nodes: ConfigNode and DataNode, each
An illustration of the cluster architecture:
-<img style="width:100%; max-width:500px; max-height:400px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Cluster/Architecture.png?raw=true">
+<img style="width:100%; max-width:500px; max-height:400px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Cluster/Architecture.png?raw=true">
ConfigNode is the control node of the cluster, which manages the cluster's node status, partition information, etc. All ConfigNodes in the cluster form a highly available group, which is fully replicated.
@@ -98,7 +98,7 @@ A region is the basic unit of replication. Multiple replicas of a region constru
An illustration of the partition allocation in cluster:
-<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Cluster/Data-Partition.png?raw=true">
+<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Cluster/Data-Partition.png?raw=true">
The figure contains 1 SchemaRegionGroup, and the schema_replication_factor is 3, so the 3 white SchemaRegion-0s form a replication group.
diff --git a/docs/UserGuide/Cluster/Cluster-Maintenance.md b/docs/UserGuide/Cluster/Cluster-Maintenance.md
index dcd8999f78..e71826afa4 100644
--- a/docs/UserGuide/Cluster/Cluster-Maintenance.md
+++ b/docs/UserGuide/Cluster/Cluster-Maintenance.md
@@ -123,7 +123,7 @@ It costs 0.006s
### DataNode status definition
The state machine of DataNode is shown in the figure below:
-<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Cluster/DataNode-StateMachine-EN.jpg?raw=true">
+<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Cluster/DataNode-StateMachine-EN.jpg?raw=true">
The DataNode statuses are defined as follows:
diff --git a/docs/UserGuide/Data-Concept/Data-Model-and-Terminology.md b/docs/UserGuide/Data-Concept/Data-Model-and-Terminology.md
index b2068a2627..d7fbb01a0c 100644
--- a/docs/UserGuide/Data-Concept/Data-Model-and-Terminology.md
+++ b/docs/UserGuide/Data-Concept/Data-Model-and-Terminology.md
@@ -25,7 +25,7 @@ A wind power IoT scenario is taken as an example to illustrate how to creat a co
According to the enterprise organization structure and equipment entity hierarchy, it is expressed as an attribute hierarchy structure, as shown below. The hierarchical from top to bottom is: power group layer - power plant layer - entity layer - measurement layer. ROOT is the root node, and each node of measurement layer is a leaf node. In the process of using IoTDB, the attributes on the path from ROOT node is directly connected to each leaf node with ".", thus forming the name of a ti [...]
-<center><img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/122668849-b1c69280-d1ec-11eb-83cb-3b73c40bdf72.png"></center>
+<center><img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/122668849-b1c69280-d1ec-11eb-83cb-3b73c40bdf72.png"></center>
Here are the basic concepts of the model involved in IoTDB.
@@ -132,7 +132,7 @@ When querying, you can query each timeseries separately.
When inserting data, it is allowed to insert null value in the aligned timeseries.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/114125919-f4850800-9929-11eb-8211-81d4c04af1ec.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/114125919-f4850800-9929-11eb-8211-81d4c04af1ec.png">
In the following chapters of data definition language, data operation language and Java Native Interface, various operations related to aligned timeseries will be introduced one by one.
diff --git a/docs/UserGuide/Data-Concept/Schema-Template.md b/docs/UserGuide/Data-Concept/Schema-Template.md
index a3d97622f1..1398a294dc 100644
--- a/docs/UserGuide/Data-Concept/Schema-Template.md
+++ b/docs/UserGuide/Data-Concept/Schema-Template.md
@@ -29,7 +29,7 @@ In order to enable different entities of the same type to share metadata, reduce
The following picture illustrates the data model of petrol vehicle scenario. The velocity, fuel amount, acceleration, and angular velocity of each petrol vehicle spread over cities will be collected. Obviously, the measurements of single petrol vehicle are the same as those of another.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Measurement%20Template/example_without_template.png?raw=true" alt="example without template">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Measurement-Template/example_without_template.png?raw=true" alt="example without template">
## Concept
@@ -45,7 +45,7 @@ In the following chapters of data definition language, data operation language a
After applying schema template, the following picture illustrates the new data model of petrol vehicle scenario. All petrol vehicles share the schemas defined in template. There are no redundancy storage of measurement schemas.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Measurement%20Template/example_with_template.png?raw=true" alt="example with template">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Measurement-Template/example_with_template.png?raw=true" alt="example with template">
### Lifetime of Schema Template
@@ -60,7 +60,7 @@ The term about lifetime of schema template may help you utilize it in a better w
It should be complemented that the distinction between SET and ACTIVATE is meant to serve an ubiquitous scenario where massive nodes with a common ancestor may need to apply the template. Under this circumstance, it is more feasible to SET the template on the common ancestor rather than all those descendant. For those who needs to apply the template, ACTIVATE is a more appropriate arrangement.
-<img style="width:100%; max-width:800px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Measurement%20Template/example_template_lifetime.png?raw=true" alt="example with template">
+<img style="width:100%; max-width:800px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Measurement-Template/example_template_lifetime.png?raw=true" alt="example with template">
## Usage
diff --git a/docs/UserGuide/Data-Concept/Time-Partition.md b/docs/UserGuide/Data-Concept/Time-Partition.md
index ddd781d4b3..f67919e1e9 100644
--- a/docs/UserGuide/Data-Concept/Time-Partition.md
+++ b/docs/UserGuide/Data-Concept/Time-Partition.md
@@ -38,7 +38,7 @@ Time partition divides data according to time, and a time partition is used to s
Enable time partition and set partition_interval to 86400000 (one day), then the data distribution is shown as the following figure:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Time-Partition/time_partition_example.png?raw=true" alt="time partition example">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Time-Partition/time_partition_example.png?raw=true" alt="time partition example">
* Insert one datapoint with timestamp 0, calculate 0/86400000 = 0, then this datapoint will be stored in TsFile under folder 0
diff --git a/docs/UserGuide/Ecosystem-Integration/DBeaver.md b/docs/UserGuide/Ecosystem-Integration/DBeaver.md
index 25159978d5..c222105717 100644
--- a/docs/UserGuide/Ecosystem-Integration/DBeaver.md
+++ b/docs/UserGuide/Ecosystem-Integration/DBeaver.md
@@ -45,11 +45,11 @@ DBeaver is a SQL client software application and a database administration tool.
2. Start DBeaver
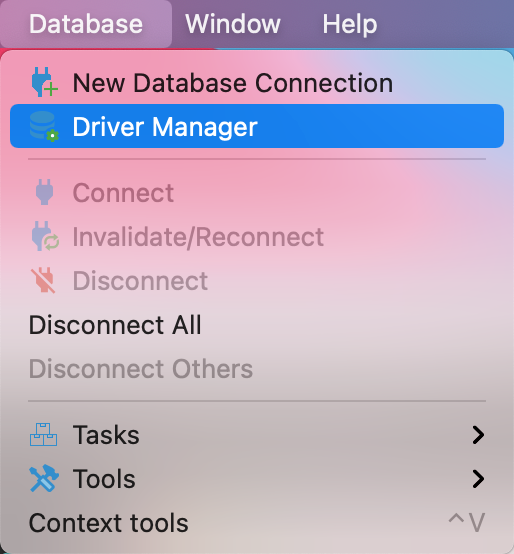
3. Open Driver Manager
- 
+ 
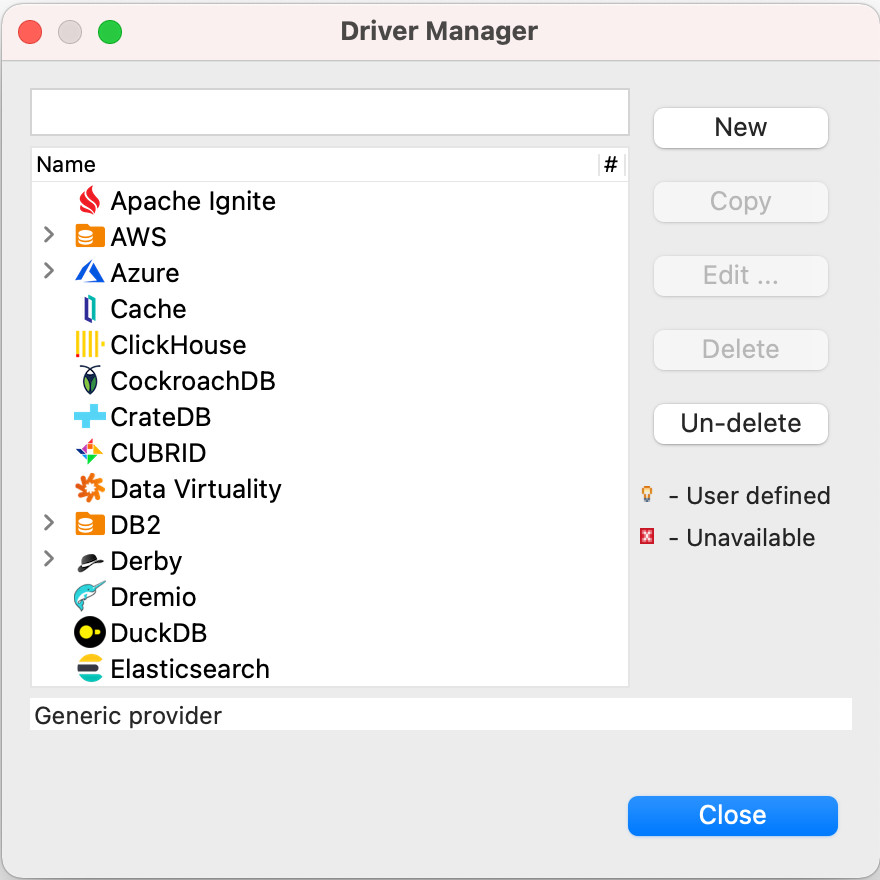
4. Create a new driver type for IoTDB
- 
+ 
5. Download [Sources](https://iotdb.apache.org/Download/),unzip it and compile jdbc driver by the following command
@@ -58,15 +58,15 @@ DBeaver is a SQL client software application and a database administration tool.
```
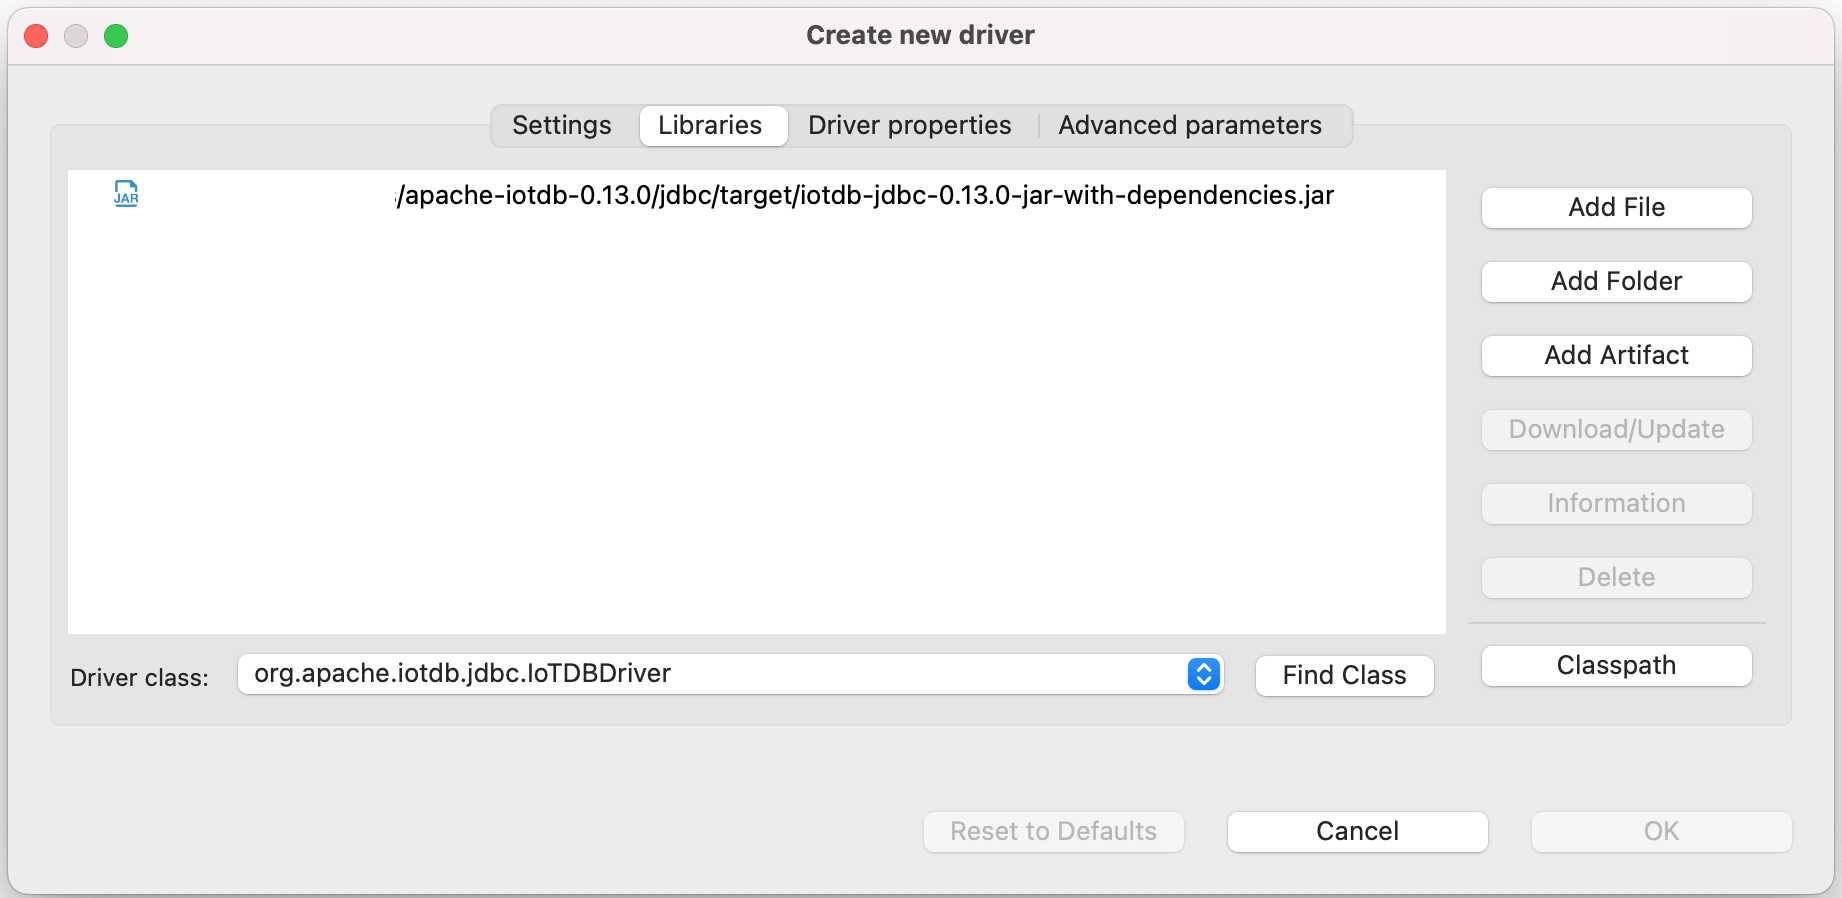
6. Find and add a lib named `apache-iotdb-jdbc-{version}-jar-with-dependencies.jar`, which should be under `jdbc/target/`, then select `Find Class`.
- 
+ 
8. Edit the driver Settings
- 
+ 
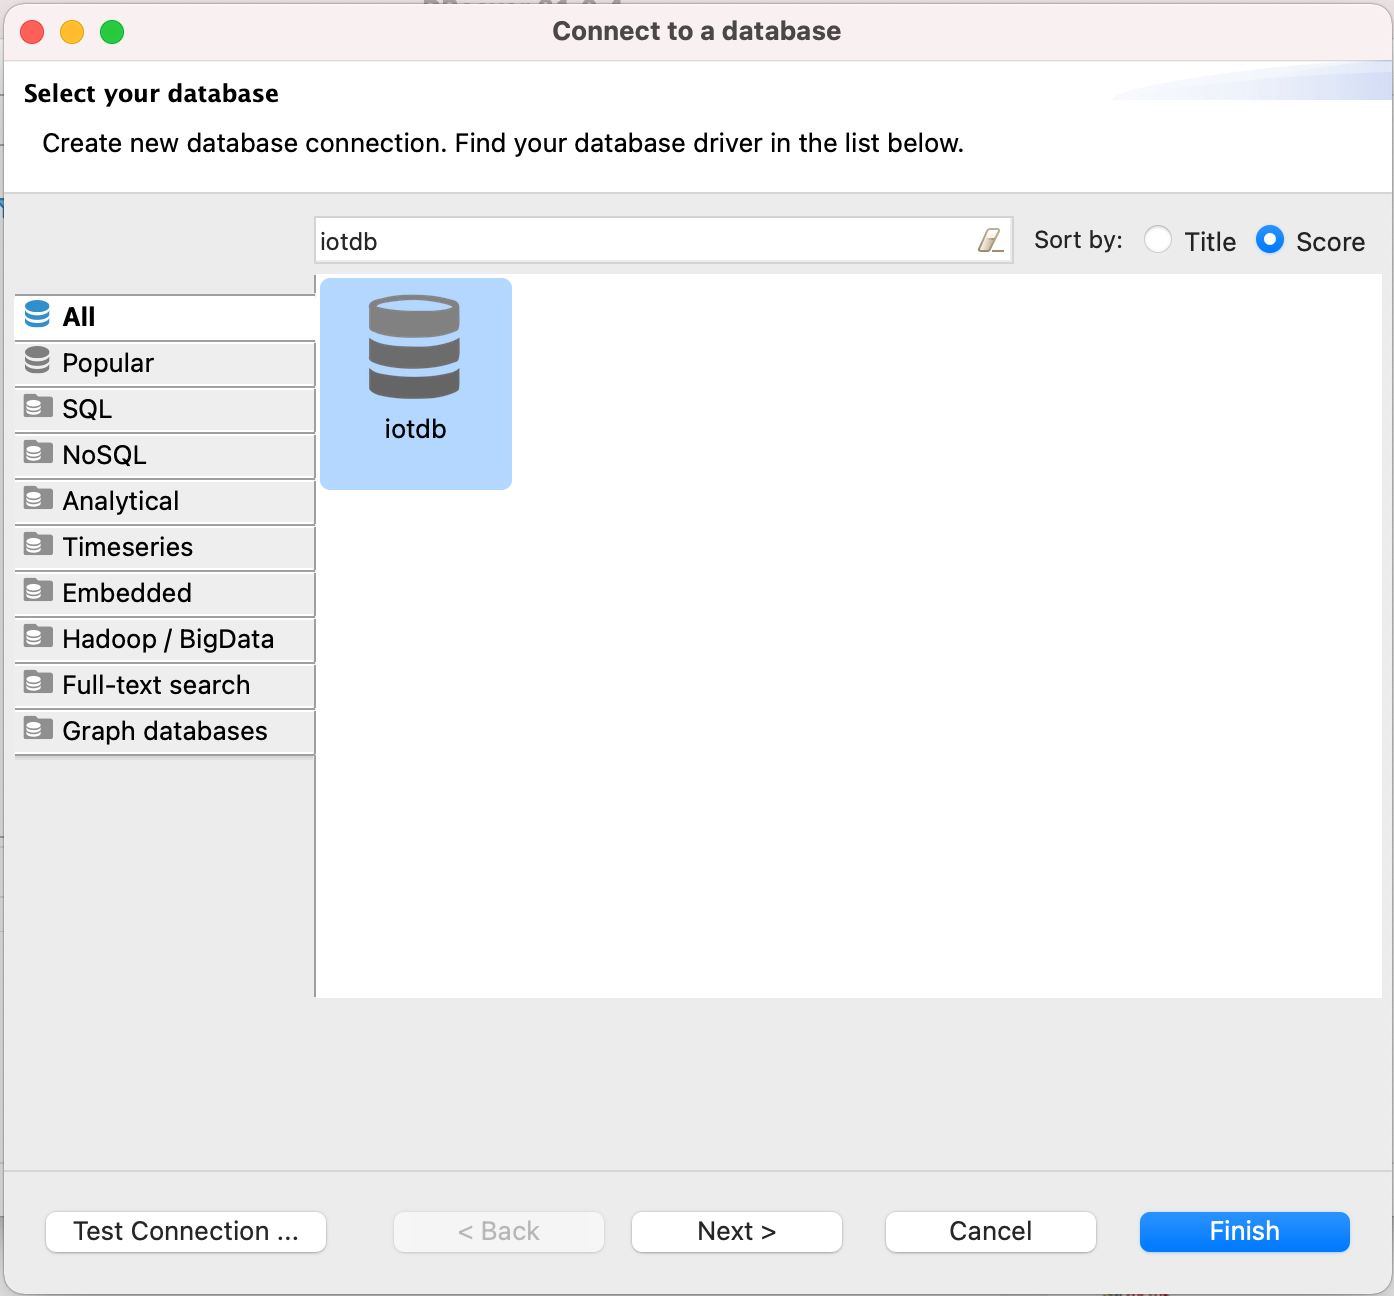
9. Open New DataBase Connection and select iotdb
- 
+ 
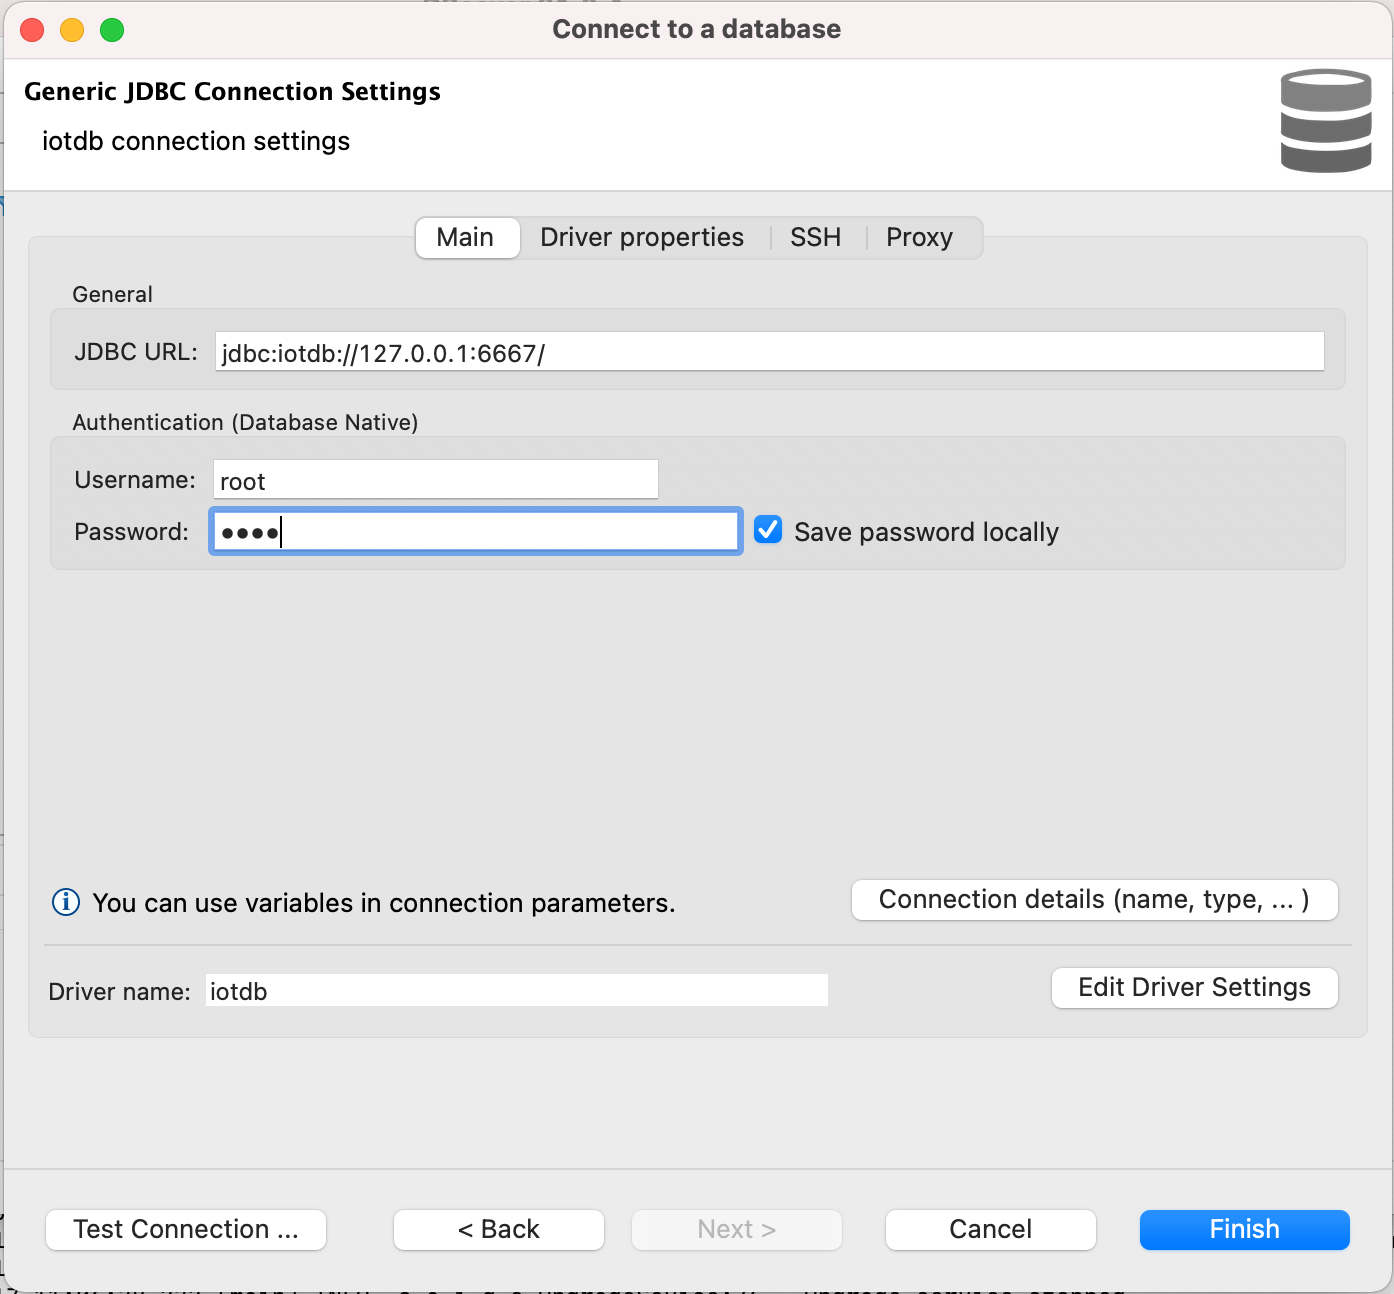
10. Edit JDBC Connection Settings
@@ -75,12 +75,12 @@ DBeaver is a SQL client software application and a database administration tool.
Username: root
Password: root
```
- 
+ 
11. Test Connection
- 
+ 
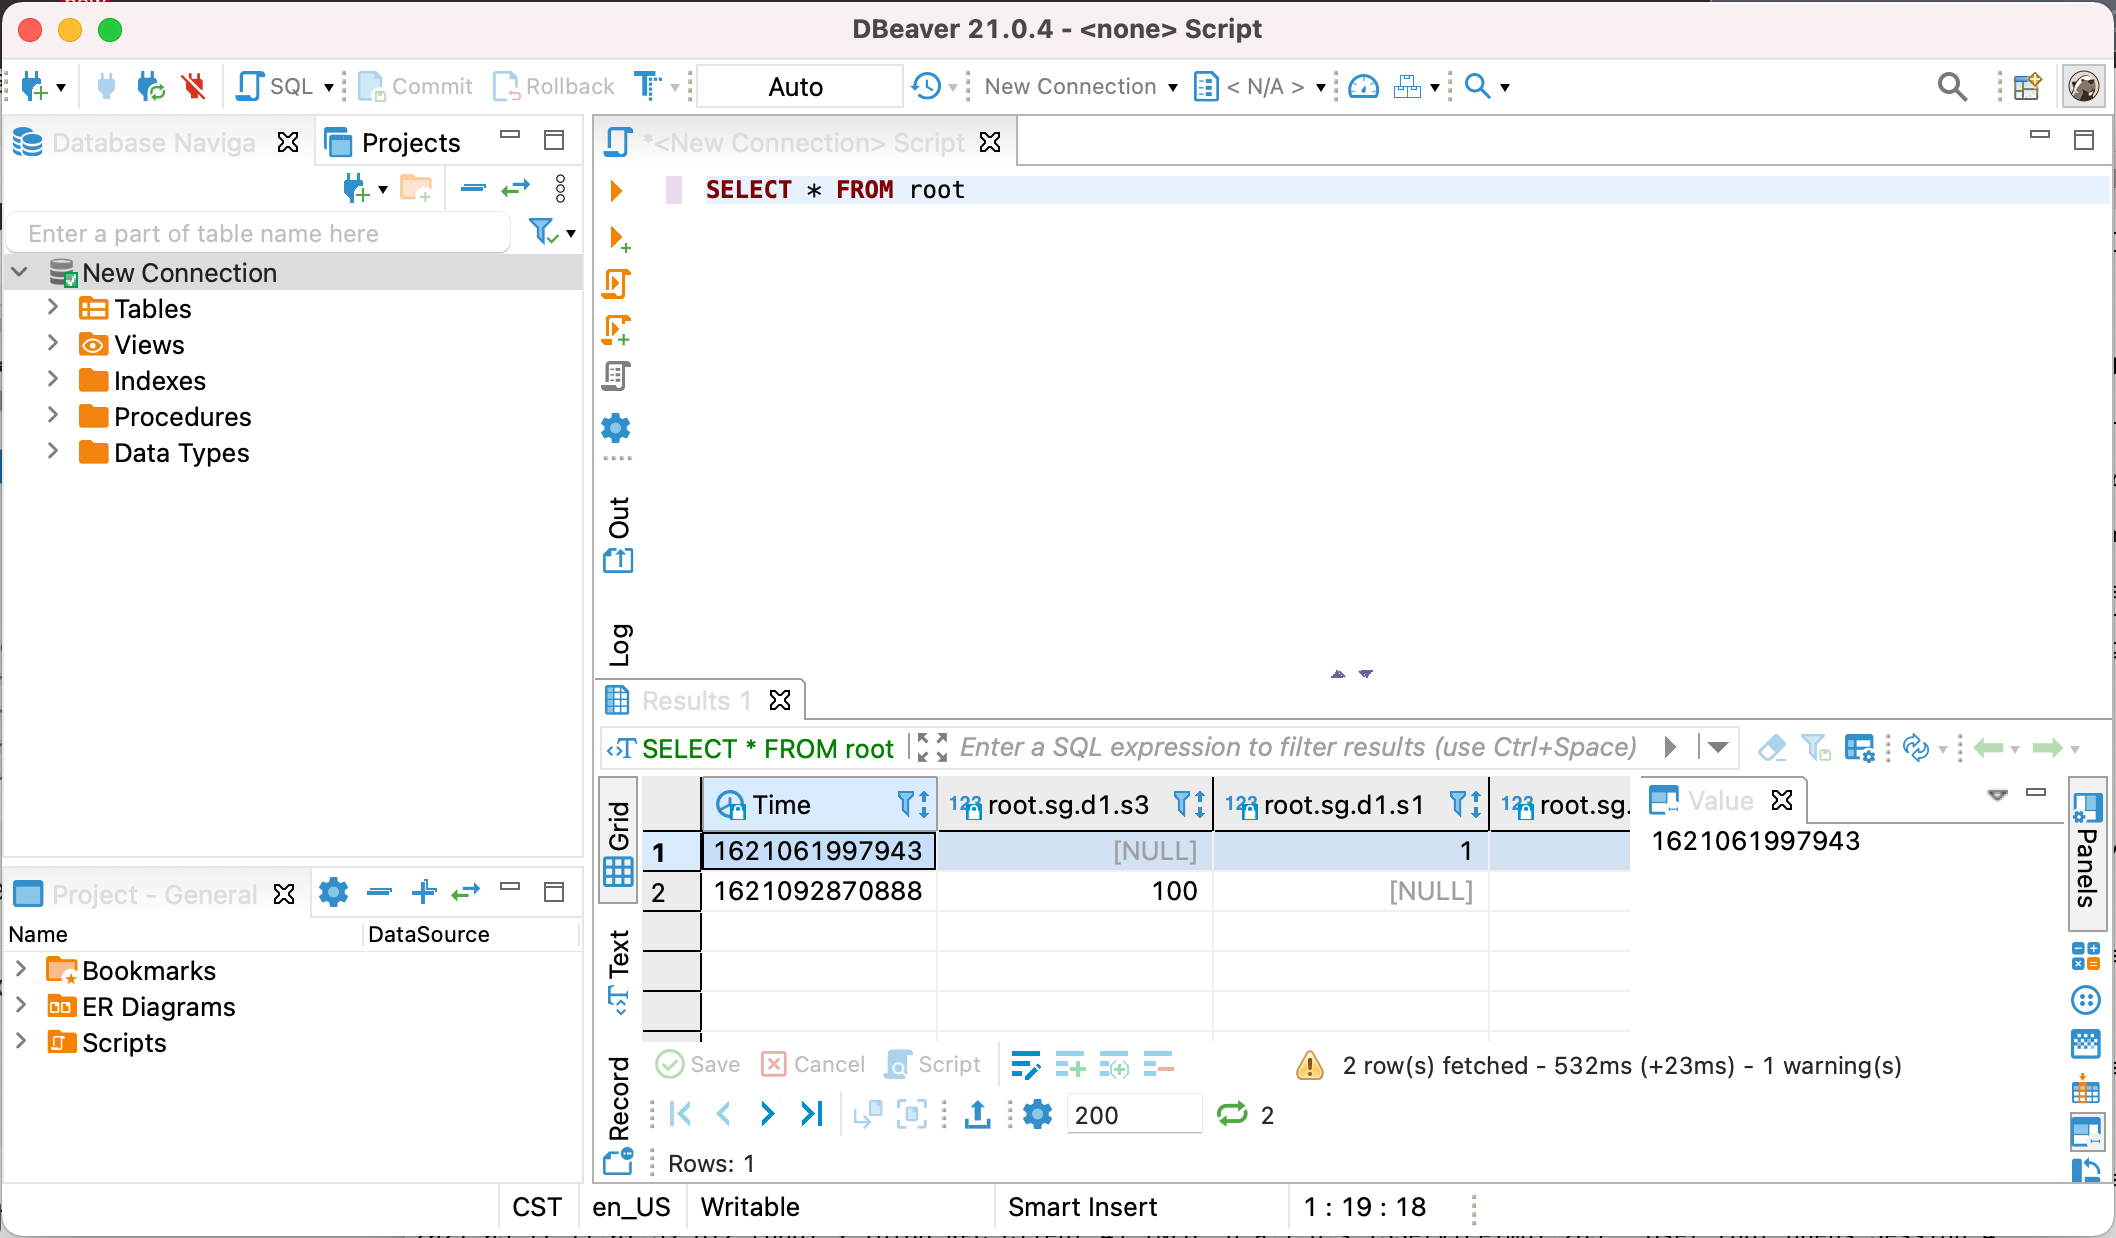
12. Enjoy IoTDB with DBeaver
- 
+ 
diff --git a/docs/UserGuide/Ecosystem-Integration/Grafana-Connector.md b/docs/UserGuide/Ecosystem-Integration/Grafana-Connector.md
index 1c9b12227b..72d26ca401 100644
--- a/docs/UserGuide/Ecosystem-Integration/Grafana-Connector.md
+++ b/docs/UserGuide/Ecosystem-Integration/Grafana-Connector.md
@@ -128,15 +128,15 @@ Username and password are both "admin" by default.
Select `Data Sources` and then `Add data source`, select `SimpleJson` in `Type` and `URL` is http://localhost:8888.
After that, make sure IoTDB has been started, click "Save & Test", and "Data Source is working" will be shown to indicate successful configuration.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51664777-2766ae00-1ff5-11e9-9d2f-7489f8ccbfc2.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51664777-2766ae00-1ff5-11e9-9d2f-7489f8ccbfc2.png">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51664842-554bf280-1ff5-11e9-97d2-54eebe0b2ca1.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51664842-554bf280-1ff5-11e9-97d2-54eebe0b2ca1.png">
#### Design in dashboard
Add diagrams in dashboard and customize your query. See http://docs.grafana.org/guides/getting_started/
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51664878-6e54a380-1ff5-11e9-9718-4d0e24627fa8.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51664878-6e54a380-1ff5-11e9-9718-4d0e24627fa8.png">
### config grafana
diff --git a/docs/UserGuide/Ecosystem-Integration/Grafana-Plugin.md b/docs/UserGuide/Ecosystem-Integration/Grafana-Plugin.md
index abe2bf6537..1b63767f9e 100644
--- a/docs/UserGuide/Ecosystem-Integration/Grafana-Plugin.md
+++ b/docs/UserGuide/Ecosystem-Integration/Grafana-Plugin.md
@@ -80,7 +80,7 @@ go get: module github.com/grafana/grafana-plugin-sdk-go: Get "https://proxy.gola
If compiling successful, you can see the `dist` directory , which contains the compiled Grafana-Plugin:
-<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana-plugin-build.png?raw=true">
+<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana-plugin-build.png?raw=true">
##### Method 3: The distribution package of IoTDB is fully compiled
@@ -94,7 +94,7 @@ Execute following command in the IoTDB root directory:
If compiling successful, you can see that the `distribution/target` directory contains the compiled Grafana-Plugin:
-<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/distribution.png?raw=true">
+<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/distribution.png?raw=true">
#### Install Grafana-Plugin
@@ -171,9 +171,9 @@ Grafana displays data in a web page dashboard. Please open your browser and visi
Click the `Settings` icon on the left, select the `Data Source` option, and then click `Add data source`.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/datasource_1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/datasource_1.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/datasource_2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/datasource_2.png?raw=true">
Select the `Apache IoTDB` data source.
@@ -184,22 +184,22 @@ Select the `Apache IoTDB` data source.
Click `Save & Test`, and `Success` will appear.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/datasource_3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/datasource_3.png?raw=true">
#### Create a new Panel
Click the `Dashboards` icon on the left, and select `Manage` option.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/manage.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/manage.png?raw=true">
Click the `New Dashboard` icon on the top right, and select `Add an empty panel` option.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/add%20empty%20panel.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/add-empty-panel.png?raw=true">
Grafana plugin supports SQL: Full Customized mode and SQL: Drop-down List mode, and the default mode is SQL: Full Customized mode.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana_input_style.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana_input_style.png?raw=true">
##### SQL: Full Customized input method
@@ -207,7 +207,7 @@ Enter content in the SELECT, FROM , WHERE and CONTROL input box, where the WHERE
If a query involves multiple expressions, we can click `+` on the right side of the SELECT input box to add expressions in the SELECT clause, or click `+` on the right side of the FROM input box to add a path prefix:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana_input.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana_input.png?raw=true">
SELECT input box: contents can be the time series suffix, function, udf, arithmetic expression, or nested expressions. You can also use the as clause to rename the result.
@@ -245,7 +245,7 @@ Tip: Statements like `select * from root.xx.**` are not recommended because thos
Select a time series in the TIME-SERIES selection box, select a function in the FUNCTION option, and enter the contents in the SAMPLING INTERVAL、SLIDING STEP、LEVEL、FILL input boxes, where TIME-SERIES is a required item and the rest are non required items.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana_input2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana_input2.png?raw=true">
#### Support for variables and template functions
@@ -253,34 +253,34 @@ Both SQL: Full Customized and SQL: Drop-down List input methods support the vari
After creating a new Panel, click the Settings button in the upper right corner:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/setconf.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/setconf.png?raw=true">
Select `Variables`, click `Add variable`:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/addvaribles.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/addvaribles.png?raw=true">
Example 1:Enter `Name`, `Label`, and `Query`, and then click the `Update` button:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput.png?raw=true">
Apply Variables, enter the variable in the `grafana panel` and click the `save` button:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/applyvariables.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/applyvariables.png?raw=true">
Example 2: Nested use of variables:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput2.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput2-1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput2-1.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput2-2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput2-2.png?raw=true">
Example 3: using function variables
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variablesinput3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variablesinput3.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variablesinput3-1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variablesinput3-1.png?raw=true">
The Name in the above figure is the variable name and the variable name we will use in the panel in the future. Label is the display name of the variable. If it is empty, the variable of Name will be displayed. Otherwise, the name of the Label will be displayed.
There are Query, Custom, Text box, Constant, DataSource, Interval, Ad hoc filters, etc. in the Type drop-down, all of which can be used in IoTDB's Grafana Plugin
@@ -304,30 +304,30 @@ This plugin supports Grafana alert function.
1. In the Grafana sidebar, hover over the `Alerting` icon and click `Notification channels`.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting1.png?raw=true">
2. Click Add Channel.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting2.png?raw=true">
3. Fill in the fields described below or select options. There are many types of Type, including DingDing, Email, Slack, WebHook, Prometheus Alertmanager, etc.
This sample Type uses `Prometheus Alertmanager`. Prometheus Alertmanager needs to be installed in advance. For more detailed configuration and parameter introduction, please refer to the official documentation: https://grafana.com/docs/grafana/v8.0/alerting/old- alerting/notifications/.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting3.png?raw=true">
4. Click the `Test` button, the `Test notification sent` appears, click the `Save` button to save
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting4.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting4.png?raw=true">
5. After creating a new Panel, enter the query parameters and click Save, then select `Alert` and click `Create Alert`, as shown in the following figure:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanle1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanle1.png?raw=true">
6、Fill out the fields described below or select an option, `Name`- Enter a descriptive name. The name will be displayed in the Alert Rules list. This field supports templating.
`Evaluate every` - Specify how often the scheduler should evaluate the alert rule. This is referred to as the evaluation interval.
`For` - Specify how long the query needs to violate the configured thresholds before the alert notification triggers.。`Conditions`- Represents query criteria. Multiple combined query criteria can be configured.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanle2.jpg?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanle2.jpg?raw=true">
Query conditions in the figure:avg() OF query(A,5m,now) IS ABOVE -1
@@ -344,19 +344,19 @@ More details can be found in the official documents:https://grafana.com/docs/gra
7、Click the `Test rule` button and the `firing: true` appears, the configuration is successful, click the `save` button
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanel3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanel3.png?raw=true">
8、The following figure shows the alarm displayed in the grafana panel
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanel4.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanel4.png?raw=true">
9、View alert rules
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertPanel5.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertPanel5.png?raw=true">
10、View alert records in promehthus alertmanager
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanel6.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanel6.png?raw=true">
### More Details about Grafana
diff --git a/docs/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md b/docs/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md
index 4f973a4fd9..7f5dd94ec7 100644
--- a/docs/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md
+++ b/docs/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md
@@ -129,7 +129,7 @@ This is a processor that reads the sql query from the incoming FlowFile and usin
| Username | Username to access the IoTDB. | null | true |
| Password | Password to access the IoTDB. | null | true |
| Record Writer | Specifies the Controller Service to use for writing results to a FlowFile. The Record Writer may use Inherit Schema to emulate the inferred schema behavior, i.e. An explicit schema need not be defined in the writer, and will be supplied by the same logic used to infer the schema from the column types. | null | true |
-| iotdb-query | The IoTDB query to execute. <bbr> Note: If there are incoming connections, then the query is created from incoming FlowFile's content otherwise"it is created from this property. | null | false |
+| iotdb-query | The IoTDB query to execute. <br> Note: If there are incoming connections, then the query is created from incoming FlowFile's content otherwise"it is created from this property. | null | false |
| iotdb-query-chunk-size | Chunking can be used to return results in a stream of smaller batches (each has a partial results up to a chunk size) rather than as a single response. Chunking queries can return an unlimited number of rows. Note: Chunking is enable when result chunk size is greater than 0 | 0 | false |
diff --git a/docs/UserGuide/Ecosystem-Integration/Spark-IoTDB.md b/docs/UserGuide/Ecosystem-Integration/Spark-IoTDB.md
index f53319b102..f7c987e178 100644
--- a/docs/UserGuide/Ecosystem-Integration/Spark-IoTDB.md
+++ b/docs/UserGuide/Ecosystem-Integration/Spark-IoTDB.md
@@ -93,7 +93,7 @@ Take the following TsFile structure as an example: There are three Measurements
The existing data in the TsFile is as follows:
-<img width="517" alt="SI " src="https://user-images.githubusercontent.com/69114052/98197835-99a64980-1f62-11eb-84af-8301b8a6aad5.png">
+<img width="517" alt="SI " src="/img/github/98197835-99a64980-1f62-11eb-84af-8301b8a6aad5.png">
The wide(default) table form is as follows:
diff --git a/docs/UserGuide/Ecosystem-Integration/Spark-TsFile.md b/docs/UserGuide/Ecosystem-Integration/Spark-TsFile.md
index 02fa7dea2c..2d0becf7f9 100644
--- a/docs/UserGuide/Ecosystem-Integration/Spark-TsFile.md
+++ b/docs/UserGuide/Ecosystem-Integration/Spark-TsFile.md
@@ -94,7 +94,7 @@ The way to display TsFile is dependent on the schema. Take the following TsFile
The existing data in the TsFile are:
-<img width="519" alt="ST 1" src="https://user-images.githubusercontent.com/69114052/98197920-be9abc80-1f62-11eb-9efb-027f0590031c.png">
+<img width="519" alt="ST 1" src="/img/github/98197920-be9abc80-1f62-11eb-9efb-027f0590031c.png">
The corresponding SparkSQL table is:
@@ -239,7 +239,7 @@ The way to display TsFile is related to TsFile Schema. Take the following TsFile
The existing data in the file are:
-<img width="817" alt="ST 2" src="https://user-images.githubusercontent.com/69114052/98197948-cf4b3280-1f62-11eb-9c8c-c97d1adf032c.png">
+<img width="817" alt="ST 2" src="/img/github/98197948-cf4b3280-1f62-11eb-9c8c-c97d1adf032c.png">
A set of time-series data
diff --git a/docs/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md b/docs/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md
index 9d0cffb1ca..646aae78f1 100644
--- a/docs/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md
+++ b/docs/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md
@@ -29,7 +29,7 @@ Currently, TsFiles(including both TsFile and related data files) are supported t
When you config to store TSFile on HDFS, your data files will be in distributed storage. The system architecture is as below:
-<img style="width:100%; max-width:700px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/66922722-35180400-f05a-11e9-8ff0-7dd51716e4a8.png">
+<img style="width:100%; max-width:700px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/66922722-35180400-f05a-11e9-8ff0-7dd51716e4a8.png">
#### Config and usage
diff --git a/docs/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md b/docs/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md
index b218b3ed2c..c5f509f3e7 100644
--- a/docs/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md
+++ b/docs/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md
@@ -25,7 +25,7 @@
Zeppelin is a web-based notebook that enables interactive data analytics. You can connect to data sources and perform interactive operations with SQL, Scala, etc. The operations can be saved as documents, just like Jupyter. Zeppelin has already supported many data sources, including Spark, ElasticSearch, Cassandra, and InfluxDB. Now, we have enabled Zeppelin to operate IoTDB via SQL.
-
+
@@ -113,7 +113,7 @@ In the interpreter page:
Now you are ready to use your interpreter.
-
+
We provide some simple SQL to show the use of Zeppelin-IoTDB interpreter:
@@ -147,7 +147,7 @@ We provide some simple SQL to show the use of Zeppelin-IoTDB interpreter:
The screenshot is as follows:
-
+
You can also design more fantasy documents referring to [[1]](https://zeppelin.apache.org/docs/0.9.0/usage/display_system/basic.html) and others.
@@ -159,7 +159,7 @@ The above demo notebook can be found at `$IoTDB_HOME/zeppelin-interpreter/Zeppe
You can configure the connection parameters in http://127.0.0.1:8080/#/interpreter :
-
+
The parameters you can configure are as follows:
diff --git a/docs/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md b/docs/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md
index 2214646b59..4aa356db73 100644
--- a/docs/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md
+++ b/docs/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md
@@ -31,7 +31,7 @@ You can use SQL commands to start or close a synchronization task at the sender,
## 2.Model definition
-
+
Two machines A and B, which are installed with iotdb, we want to continuously synchronize the data from A to B. To better describe this process, we introduce the following concepts.
@@ -131,7 +131,7 @@ All parameters are in `$IOTDB_ HOME$/conf/iotdb-common.properties`, after all mo
- Show all PipeSink types supported by IoTDB.
-```Plain%20Text
+```
IoTDB> SHOW PIPESINKTYPE
IoTDB>
+-----+
diff --git a/docs/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md b/docs/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md
index 136b06116d..3fc6c6749e 100644
--- a/docs/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md
+++ b/docs/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md
@@ -51,7 +51,7 @@ Generally, there are three steps to finish the integration test, (1) constructin
#### 1. Integration Test Class (IT Class) and Annotations
-When writing new IT classes, the developers are encouraged to create the new ones in the [integration-test](https://github.com/apache/iotdb/tree/master/integration-test) module. Except for the classes serving the other test cases, the classes containing integration tests to evaluate the functionality of IoTDB should be named "function"+"IT". For example, the test for auto-registration metadata in IoTDB is named “<font color=green>IoTDBAutoCreateSchema</font><font color=red>IT</font>”.
+When writing new IT classes, the developers are encouraged to create the new ones in the [integration-test](https://github.com/apache/iotdb/tree/master/integration-test) module. Except for the classes serving the other test cases, the classes containing integration tests to evaluate the functionality of IoTDB should be named "function"+"IT". For example, the test for auto-registration metadata in IoTDB is named “<span style="color:green">IoTDBAutoCreateSchema</span><span style="color:red [...]
- Category`` Annotation. **When creating new IT classes, the ```@Category``` should be introduced explicitly**, and the test environment should be specified by ```LocalStandaloneIT.class```, ```ClusterIT.class```, and ```RemoteIT.class```, which corresponds to the Local Standalone, Cluster and Remote environment respectively. **In general, ```LocalStandaloneIT.class``` and ```ClusterIT.class``` should both be included**. Only in the case when some functionalities are only supported in t [...]
- RunWith Annotation. The ```@RunWith(IoTDBTestRunner.class)``` annotation should be included in every IT class.
@@ -108,7 +108,7 @@ public static void tearDown() throws Exception {
#### 3. Implementing the logic of IT
-IT of Apache IoTDB should be implemented as black-box testing. Please name the method as "functionality"+"Test", e.g., "<font color=green>selectWithAlias</font><font color=red>Test</font>". The interaction should be implemented through JDBC or Session API.
+IT of Apache IoTDB should be implemented as black-box testing. Please name the method as "functionality"+"Test", e.g., "<span style="color:green">selectWithAlias</span><span style="color:red">Test</span>". The interaction should be implemented through JDBC or Session API.
1 With JDBC
diff --git a/docs/UserGuide/IoTDB-Introduction/Architecture.md b/docs/UserGuide/IoTDB-Introduction/Architecture.md
index b6b581cb4a..bff327c3b2 100644
--- a/docs/UserGuide/IoTDB-Introduction/Architecture.md
+++ b/docs/UserGuide/IoTDB-Introduction/Architecture.md
@@ -25,7 +25,7 @@ Besides IoTDB engine, we also developed several components to provide better IoT
IoTDB suite can provide a series of functions in the real situation such as data collection, data writing, data storage, data query, data visualization and data analysis. Figure 1.1 shows the overall application architecture brought by all the components of the IoTDB suite.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/IoTDB-Introduction/Architecture/Structure%20of%20Apache%20IoTDB.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/IoTDB-Introduction/Architecture/Structure-of-Apache-IoTDB.png?raw=true">
As shown in Figure 1.1, users can use JDBC to import timeseries data collected by sensor on the device to local/remote IoTDB. These timeseries data may be system state data (such as server load and CPU memory, etc.), message queue data, timeseries data from applications, or other timeseries data in the database. Users can also write the data directly to the TsFile (local or on HDFS).
diff --git a/docs/UserGuide/IoTDB-Introduction/Scenario.md b/docs/UserGuide/IoTDB-Introduction/Scenario.md
index 3709ba5b5a..c3e0e72ec0 100644
--- a/docs/UserGuide/IoTDB-Introduction/Scenario.md
+++ b/docs/UserGuide/IoTDB-Introduction/Scenario.md
@@ -31,11 +31,11 @@ In order to improve the quality of the printing, it is necessary for the company
At this point, the data can be stored using TsFile component, TsFileSync tool, and Hadoop/Spark integration component in the IoTDB suite.That is, each time a new chip is printed, a data is written on the SPI device using the SDK, which ultimately forms a TsFile. Through the TsFileSync tool, the generated TsFile will be synchronized to the data center according to certain rules (such as daily) and analyzed by data analysts tools.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579014-695ef980-1efa-11e9-8cbc-e9e7ee4fa0d8.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579014-695ef980-1efa-11e9-8cbc-e9e7ee4fa0d8.png">
In this scenario, only TsFile and TsFileSync are required to be deployed on a PC, and a Hadoop/Spark cluster is required. Figure below shows the architecture at this time.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/25913899/81768490-bf034f00-950d-11ea-9b56-fef3edca0958.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81768490-bf034f00-950d-11ea-9b56-fef3edca0958.png">
* Scenario 2
@@ -43,11 +43,11 @@ A company has several wind turbines which are installed hundreds of sensors on e
In order to ensure the normal operation of the turbines and timely monitoring and analysis of the turbines, the company needs to collect these sensor data, perform partial calculation and analysis in the turbines working environment, and upload the original data collected to the data center.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579033-7ed42380-1efa-11e9-889f-fb4180291a9e.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579033-7ed42380-1efa-11e9-889f-fb4180291a9e.png">
In this situation, IoTDB, TsFileSync tools, and Hadoop/Spark integration components in the IoTDB suite can be used. A PC needs to be deployed with IoTDB and TsFileSync tools installed to support reading and writing data, local computing and analysis, and uploading data to the data center. In addition, Hadoop/Spark clusters need to be deployed for data storage and analysis on the data center side. Figure below shows the architecture at this time.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579064-8f849980-1efa-11e9-8cd6-a7339cd0540f.jpg">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579064-8f849980-1efa-11e9-8cd6-a7339cd0540f.jpg">
* Scenario 3
@@ -57,11 +57,11 @@ A variety of sensors are installed on each robotic device to monitor the robot's
In order to ensure that the data of the robot can be monitored and analyzed in time, the company needs to collect the information of these robot sensors, send them to the server that can connect to the external network, and then upload the original data information to the data center for complex calculation and analysis.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579080-96aba780-1efa-11e9-87ac-940c45b19dd7.jpg">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579080-96aba780-1efa-11e9-87ac-940c45b19dd7.jpg">
At this point, IoTDB, IoTDB-Client tools, TsFileSync tools, and Hadoop/Spark integration components in the IoTDB suite can be used. IoTDB-Client tool is installed on the robot and each of them is connected to the LAN of the factory. When sensors generate real-time data, the data will be uploaded to the server in the factory. The IoTDB server and TsFileSync is installed on the server connected to the external network. Once triggered, the data on the server will be upload to the data cente [...]
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/25913899/81768477-b874d780-950d-11ea-80ca-8807b9bd0970.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81768477-b874d780-950d-11ea-80ca-8807b9bd0970.png">
* Scenario 4
@@ -73,4 +73,4 @@ At this point, IoTDB, IoTDB-Client, and Hadoop/Spark integration components in t
In addition, Hadoop/Spark clusters need to be deployed for data storage and analysis on the data center side. As shown in Figure below.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579095-a4f9c380-1efa-11e9-9f95-17165ec55568.jpg">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579095-a4f9c380-1efa-11e9-9f95-17165ec55568.jpg">
diff --git a/docs/UserGuide/Maintenance-Tools/JMX-Tool.md b/docs/UserGuide/Maintenance-Tools/JMX-Tool.md
index 58f41b4489..3ac1eb645b 100644
--- a/docs/UserGuide/Maintenance-Tools/JMX-Tool.md
+++ b/docs/UserGuide/Maintenance-Tools/JMX-Tool.md
@@ -48,12 +48,12 @@ Step 4: Use jvisualvm
1. Make sure jdk 8 is installed. For versions later than jdk 8, you need to [download visualvm](https://visualvm.github.io/download.html)
2. Open jvisualvm
3. Right-click at the left navigation area -> Add JMX connection
-<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/81464569-725e0200-91f5-11ea-9ff9-49745f4c9ef2.png">
+<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81464569-725e0200-91f5-11ea-9ff9-49745f4c9ef2.png">
4. Fill in information and log in as below. Remember to check "Do not require SSL connection".
An example is:
Connection:192.168.130.15:31999
Username:iotdb
Password:passw!d
-<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/81464639-ed271d00-91f5-11ea-91a0-b4fe9cb8204e.png">
+<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81464639-ed271d00-91f5-11ea-91a0-b4fe9cb8204e.png">
diff --git a/docs/UserGuide/Maintenance-Tools/Log-Tool.md b/docs/UserGuide/Maintenance-Tools/Log-Tool.md
index 5395274642..0ce3c0512e 100644
--- a/docs/UserGuide/Maintenance-Tools/Log-Tool.md
+++ b/docs/UserGuide/Maintenance-Tools/Log-Tool.md
@@ -35,14 +35,14 @@ Here we use JConsole to connect with JMX.
Start the JConsole, establish a new JMX connection with the IoTDB Server (you can select the local process or input the IP and PORT for remote connection, the default operation port of the IoTDB JMX service is 31999). Fig 4.1 shows the connection GUI of JConsole.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51577195-f94d7500-1ef3-11e9-999a-b4f67055d80e.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51577195-f94d7500-1ef3-11e9-999a-b4f67055d80e.png">
After connected, click `MBean` and find `ch.qos.logback.classic.default.ch.qos.logback.classic.jmx.JMXConfigurator`(As shown in fig 4.2).
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51577204-fe122900-1ef3-11e9-9e89-2eb1d46e24b8.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51577204-fe122900-1ef3-11e9-9e89-2eb1d46e24b8.png">
In the JMXConfigurator Window, there are 6 operations provided, as shown in fig 4.3. You can use these interfaces to perform operation.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51577216-09fdeb00-1ef4-11e9-9005-542ad7d9e9e0.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51577216-09fdeb00-1ef4-11e9-9005-542ad7d9e9e0.png">
#### Interface Instruction
diff --git a/docs/UserGuide/Monitor-Alert/Alerting.md b/docs/UserGuide/Monitor-Alert/Alerting.md
index 6f81bfede4..e9b98a2f20 100644
--- a/docs/UserGuide/Monitor-Alert/Alerting.md
+++ b/docs/UserGuide/Monitor-Alert/Alerting.md
@@ -396,6 +396,6 @@ makes alerts of `critical` severity inhibit those of `warning` severity,
the alerting email we receive only contains the alert triggered
by the writing of `(5, 120)`.
-<img width="669" alt="alerting" src="https://user-images.githubusercontent.com/34649843/115957896-a9791080-a537-11eb-9962-541412bdcee6.png">
+<img width="669" alt="alerting" src="/img/github/115957896-a9791080-a537-11eb-9962-541412bdcee6.png">
diff --git a/docs/UserGuide/Monitor-Alert/Metric-Tool.md b/docs/UserGuide/Monitor-Alert/Metric-Tool.md
index ed288c5b0e..78f30f2603 100644
--- a/docs/UserGuide/Monitor-Alert/Metric-Tool.md
+++ b/docs/UserGuide/Monitor-Alert/Metric-Tool.md
@@ -337,18 +337,18 @@ thread information, class information, and the server's CPU usage.
After connecting to JMX, you can find the "MBean" named "org.apache.iotdb.metrics" through the "MBeans" tab, and you can
view the specific values of all monitoring metrics in the sidebar.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" alt="metric-jmx" src="https://user-images.githubusercontent.com/46039728/204018765-6fda9391-ebcf-4c80-98c5-26f34bd74df0.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" alt="metric-jmx" src="/img/github/204018765-6fda9391-ebcf-4c80-98c5-26f34bd74df0.png">
#### 5.1.2. Get other relevant data
After connecting to JMX, you can find the "MBean" named "org.apache.iotdb.service" through the "MBeans" tab, as shown in
the image below, to understand the basic status of the service
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/46039728/149951720-707f1ee8-32ee-4fde-9252-048caebd232e.png"> <br>
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/149951720-707f1ee8-32ee-4fde-9252-048caebd232e.png"> <br>
In order to improve query performance, IOTDB caches ChunkMetaData and TsFileMetaData. Users can use MXBean and expand the sidebar `org.apache.iotdb.db.service` to view the cache hit ratio:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/112426760-73e3da80-8d73-11eb-9a8f-9232d1f2033b.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/112426760-73e3da80-8d73-11eb-9a8f-9232d1f2033b.png">
### 5.2. Prometheus
@@ -398,7 +398,7 @@ As shown above, IoTDB exposes monitoring metrics data in the standard Prometheus
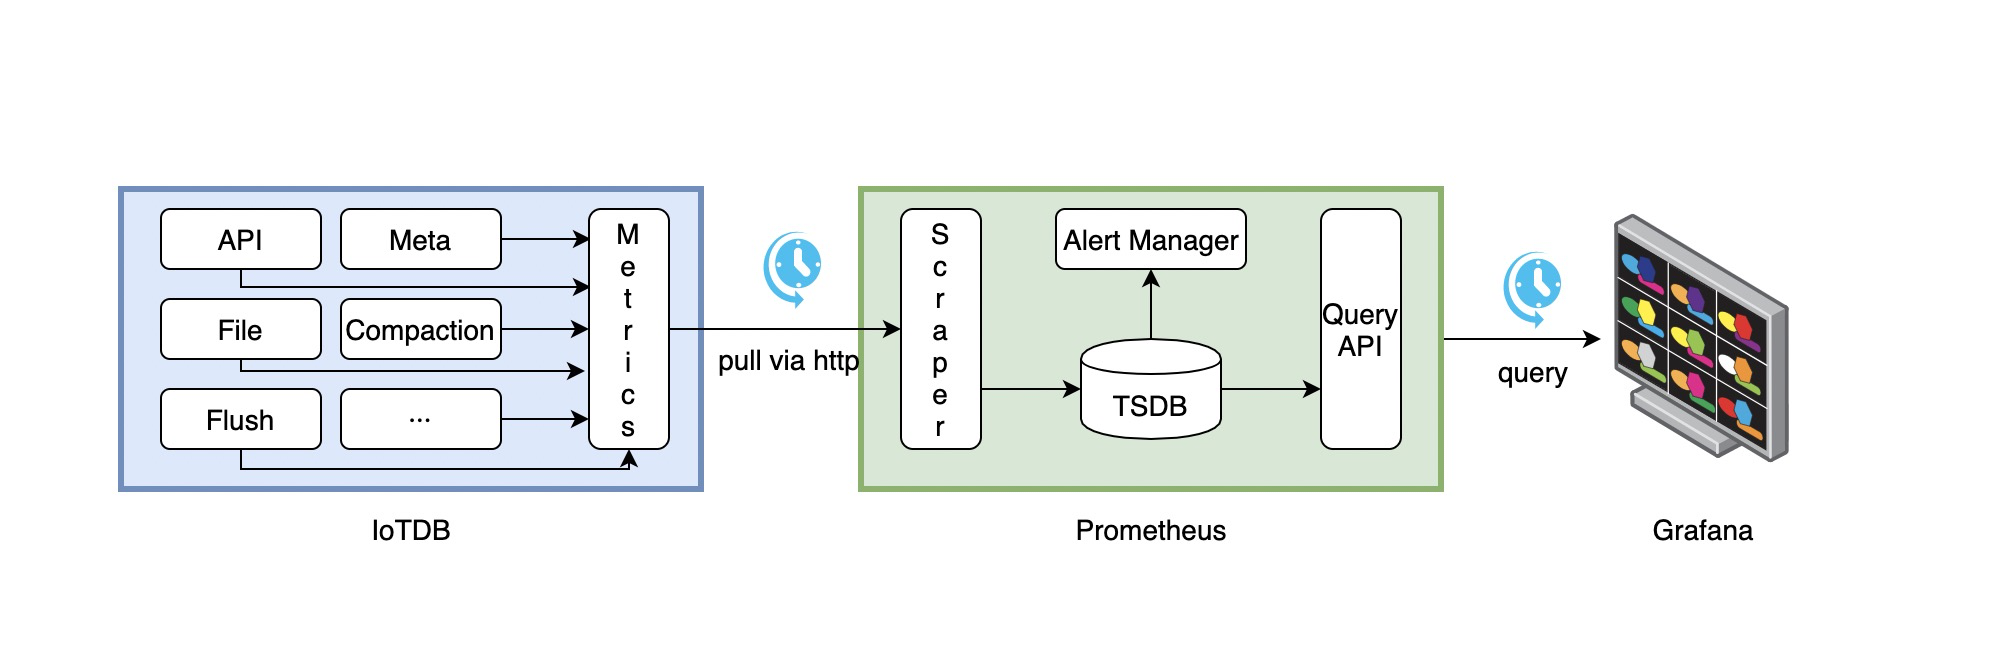
The following picture describes the relationships among IoTDB, Prometheus and Grafana
-
+
1. Along with running, IoTDB will collect its metrics continuously.
2. Prometheus scrapes metrics from IoTDB at a constant interval (can be configured).
@@ -437,7 +437,7 @@ The following documents may help you have a good journey with Prometheus and Gra
We provide the Apache IoTDB Dashboard, and the rendering shown in Grafana is as follows:
-
+
##### 5.2.4.1. How to get Apache IoTDB Dashboard
diff --git a/docs/UserGuide/Operate-Metadata/Auto-Create-MetaData.md b/docs/UserGuide/Operate-Metadata/Auto-Create-MetaData.md
index 131ce07248..f8a2439427 100644
--- a/docs/UserGuide/Operate-Metadata/Auto-Create-MetaData.md
+++ b/docs/UserGuide/Operate-Metadata/Auto-Create-MetaData.md
@@ -51,7 +51,7 @@ Illustrated as the following figure:
* When default_storage_group_level=2, root.turbine1.d1, root.turbine1.d2, root.turbine2.d1 and root.turbine2.d2 will be created as database.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Auto-Create-MetaData/auto_create_sg_example.png?raw=true" alt="auto create database example">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Auto-Create-MetaData/auto_create_sg_example.png?raw=true" alt="auto create database example">
## Auto create time series metadata(specify data type in the frontend)
diff --git a/docs/UserGuide/Operate-Metadata/Node.md b/docs/UserGuide/Operate-Metadata/Node.md
index 3fda6a31bb..e2dfe09323 100644
--- a/docs/UserGuide/Operate-Metadata/Node.md
+++ b/docs/UserGuide/Operate-Metadata/Node.md
@@ -213,7 +213,7 @@ It costs 0.001s
## Count Devices
-* COUNT DEVICES <PathPattern>
+* COUNT DEVICES \<PathPattern\>
The above statement is used to count the number of devices. At the same time, it is allowed to specify `PathPattern` to count the number of devices matching the `PathPattern`.
diff --git a/docs/UserGuide/Operate-Metadata/Timeseries.md b/docs/UserGuide/Operate-Metadata/Timeseries.md
index 07ee8d6fb6..12c482e2ca 100644
--- a/docs/UserGuide/Operate-Metadata/Timeseries.md
+++ b/docs/UserGuide/Operate-Metadata/Timeseries.md
@@ -181,7 +181,7 @@ It costs 0.004s
Then the Metadata Tree will be as below:
-<center><img style="width:100%; max-width:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/69792176-1718f400-1201-11ea-861a-1a83c07ca144.jpg"></center>
+<center><img style="width:100%; max-width:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/69792176-1718f400-1201-11ea-861a-1a83c07ca144.jpg"></center>
As can be seen, `root` is considered as `LEVEL=0`. So when you enter statements such as:
```
diff --git a/docs/UserGuide/Operators-Functions/Continuous-Interval.md b/docs/UserGuide/Operators-Functions/Continuous-Interval.md
index b8d7d8ba5a..d1f6528650 100644
--- a/docs/UserGuide/Operators-Functions/Continuous-Interval.md
+++ b/docs/UserGuide/Operators-Functions/Continuous-Interval.md
@@ -28,10 +28,10 @@ They can be divided into two categories according to return value:
| Function Name | Input TSDatatype | Parameters | Output TSDatatype | Function Description |
|-------------------|--------------------------------------|-----------------------------------------------------------------------------------------------|-------------------|------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
-| ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `0L`</br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and duration times in which the value is always 0(false), and the duration time `t` satisfy `t >= min && t <= max`. The unit of `t` is ms |
-| NON_ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `0L`</br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and duration times in which the value is always not 0, and the duration time `t` satisfy `t >= min && t <= max`. The unit of `t` is ms |
-| ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `1L`</br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and the number of data points in the interval in which the value is always 0(false). Data points number `n` satisfy `n >= min && n <= max` |
-| NON_ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `1L`</br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and the number of data points in the interval in which the value is always not 0(false). Data points number `n` satisfy `n >= min && n <= max` |
+| ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `0L`<br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and duration times in which the value is always 0(false), and the duration time `t` satisfy `t >= min && t <= max`. The unit of `t` is ms |
+| NON_ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `0L`<br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and duration times in which the value is always not 0, and the duration time `t` satisfy `t >= min && t <= max`. The unit of `t` is ms |
+| ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `1L`<br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and the number of data points in the interval in which the value is always 0(false). Data points number `n` satisfy `n >= min && n <= max` |
+| NON_ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:Optional with default value `1L`<br>`max`:Optional with default value `Long.MAX_VALUE` | Long | Return intervals' start times and the number of data points in the interval in which the value is always not 0(false). Data points number `n` satisfy `n >= min && n <= max` |
##### Demonstrate
Example data:
diff --git a/docs/UserGuide/Operators-Functions/Sample.md b/docs/UserGuide/Operators-Functions/Sample.md
index c638fbf88d..95f8301f34 100644
--- a/docs/UserGuide/Operators-Functions/Sample.md
+++ b/docs/UserGuide/Operators-Functions/Sample.md
@@ -100,7 +100,7 @@ The timestamp of the sampling output of each bucket is the timestamp of the firs
| Function Name | Allowed Input Series Data Types | Required Attributes | Output Series Data Type | Series Data Type Description |
|----------|--------------------------------|---------------------------------------|------------|--------------------------------------------------|
-| EQUAL_SIZE_BUCKET_AGG_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion` The value range is `(0, 1]`, the default is `0.1`</br>`type`: The value types are `avg`, `max`, `min`, `sum`, `extreme`, `variance`, the default is `avg` | INT32 / INT64 / FLOAT / DOUBLE | Returns equal bucket aggregation samples that match the sampling ratio |
+| EQUAL_SIZE_BUCKET_AGG_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion` The value range is `(0, 1]`, the default is `0.1`<br>`type`: The value types are `avg`, `max`, `min`, `sum`, `extreme`, `variance`, the default is `avg` | INT32 / INT64 / FLOAT / DOUBLE | Returns equal bucket aggregation samples that match the sampling ratio |
Example data: `root.ln.wf01.wt01.temperature` has a total of `100` ordered data from `0.0-99.0`, and the test data is randomly sampled in equal buckets.
@@ -170,7 +170,7 @@ This function samples the input sequence with equal number of bucket outliers, t
| Function Name | Allowed Input Series Data Types | Required Attributes | Output Series Data Type | Series Data Type Description |
|----------|--------------------------------|---------------------------------------|------------|--------------------------------------------------|
-| EQUAL_SIZE_BUCKET_OUTLIER_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | The value range of `proportion` is `(0, 1]`, the default is `0.1`</br> The value of `type` is `avg` or `stendis` or `cos` or `prenextdis`, the default is `avg` </br>The value of `number` should be greater than 0, the default is `3`| INT32 / INT64 / FLOAT / DOUBLE | Returns outlier samples in equal buckets that match the sampling ratio and the number of samples in the bucket |
+| EQUAL_SIZE_BUCKET_OUTLIER_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | The value range of `proportion` is `(0, 1]`, the default is `0.1`<br> The value of `type` is `avg` or `stendis` or `cos` or `prenextdis`, the default is `avg` <br>The value of `number` should be greater than 0, the default is `3`| INT32 / INT64 / FLOAT / DOUBLE | Returns outlier samples in equal buckets that match the sampling ratio and the number of samples in the bucket |
Parameter Description
- `proportion`: sampling ratio
@@ -248,7 +248,7 @@ M4 is used to sample the `first, last, bottom, top` points for each sliding wind
- the bottom point is the point with the **m**inimal value (if there are multiple such points, M4 returns one of them);
- the top point is the point with the **m**aximal value (if there are multiple such points, M4 returns one of them).
-<img src="https://user-images.githubusercontent.com/33376433/198178733-a0919d17-0663-4672-9c4f-1efad6f463c2.png" alt="image" style="zoom:50%;" />
+<img src="/img/github/198178733-a0919d17-0663-4672-9c4f-1efad6f463c2.png" alt="image" style="zoom:50%;" />
| Function Name | Allowed Input Series Data Types | Attributes | Output Series Data Type | Series Data Type Description |
| ------------- | ------------------------------- | ------------------------------------------------------------ | ------------------------------ | ------------------------------------------------------------ |
@@ -261,7 +261,7 @@ M4 is used to sample the `first, last, bottom, top` points for each sliding wind
+ `windowSize`: The number of points in a window. Int data type. **Required**.
+ `slidingStep`: Slide a window by the number of points. Int data type. Optional. If not set, default to the same as `windowSize`.
-<img src="https://user-images.githubusercontent.com/33376433/198181449-00d563c8-7bce-4ecd-a031-ec120ca42c3f.png" alt="image" style="zoom: 50%;" />
+<img src="/img/github/198181449-00d563c8-7bce-4ecd-a031-ec120ca42c3f.png" alt="image" style="zoom: 50%;" />
*(image source: https://iotdb.apache.org/UserGuide/Master/Process-Data/UDF-User-Defined-Function.html#udtf-user-defined-timeseries-generating-function)*
@@ -272,7 +272,7 @@ M4 is used to sample the `first, last, bottom, top` points for each sliding wind
+ `displayWindowBegin`: The starting position of the window (included). Long data type. Optional. If not set, default to Long.MIN_VALUE, meaning using the time of the first data point of the input time series as the starting position of the window.
+ `displayWindowEnd`: End time limit (excluded, essentially playing the same role as `WHERE time < displayWindowEnd`). Long data type. Optional. If not set, default to Long.MAX_VALUE, meaning there is no additional end time limit other than the end of the input time series itself.
-<img src="https://user-images.githubusercontent.com/33376433/198183015-93b56644-3330-4acf-ae9e-d718a02b5f4c.png" alt="groupBy window" style="zoom: 67%;" />
+<img src="/img/github/198183015-93b56644-3330-4acf-ae9e-d718a02b5f4c.png" alt="groupBy window" style="zoom: 67%;" />
*(image source: https://iotdb.apache.org/UserGuide/Master/Query-Data/Aggregate-Query.html#downsampling-aggregate-query)*
diff --git a/docs/UserGuide/Operators-Functions/User-Defined-Function.md b/docs/UserGuide/Operators-Functions/User-Defined-Function.md
index a5c49cef34..bf933e81cd 100644
--- a/docs/UserGuide/Operators-Functions/User-Defined-Function.md
+++ b/docs/UserGuide/Operators-Functions/User-Defined-Function.md
@@ -171,7 +171,7 @@ The following are the strategies you can set:
`RowByRowAccessStrategy`: The construction of `RowByRowAccessStrategy` does not require any parameters.
The `SlidingTimeWindowAccessStrategy` is shown schematically below.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/timeWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/timeWindow.png">
`SlidingTimeWindowAccessStrategy`: `SlidingTimeWindowAccessStrategy` has many constructors, you can pass 3 types of parameters to them:
@@ -185,12 +185,12 @@ The sliding step parameter is also optional. If the parameter is not provided, t
The relationship between the three types of parameters can be seen in the figure below. Please see the Javadoc for more details.
-<div style="text-align: center;"><img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/30497621/99787878-47b51480-2b5b-11eb-8ed3-84088c5c30f7.png"></div>
+<div style="text-align: center;"><img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/99787878-47b51480-2b5b-11eb-8ed3-84088c5c30f7.png"></div>
Note that the actual time interval of some of the last time windows may be less than the specified time interval parameter. In addition, there may be cases where the number of data rows in some time windows is 0. In these cases, the framework will also call the `transform` method for the empty windows.
The `SlidingSizeWindowAccessStrategy` is shown schematically below.
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/countWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/countWindow.png">
`SlidingSizeWindowAccessStrategy`: `SlidingSizeWindowAccessStrategy` has many constructors, you can pass 2 types of parameters to them:
@@ -200,7 +200,7 @@ The `SlidingSizeWindowAccessStrategy` is shown schematically below.
The sliding step parameter is optional. If the parameter is not provided, the sliding step will be set to the same as the window size.
The `SessionTimeWindowAccessStrategy` is shown schematically below. **Time intervals less than or equal to the given minimum time interval `sessionGap` are assigned in one group**
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/sessionWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/sessionWindow.png">
`SessionTimeWindowAccessStrategy`: `SessionTimeWindowAccessStrategy` has many constructors, you can pass 2 types of parameters to them:
- Parameter 1: The display window on the time axis.
@@ -208,7 +208,7 @@ The `SessionTimeWindowAccessStrategy` is shown schematically below. **Time inter
The `StateWindowAccessStrategy` is shown schematically below. **For numerical data, if the state difference is less than or equal to the given threshold `delta`, it will be assigned in one group. **
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/stateWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/stateWindow.png">
`StateWindowAccessStrategy` has four constructors.
- Constructor 1: For numerical data, there are 3 parameters: the time axis can display the start and end time of the time window and the threshold `delta` for the allowable change within a single window.
diff --git a/docs/UserGuide/Query-Data/Continuous-Query.md b/docs/UserGuide/Query-Data/Continuous-Query.md
index 4f744c7c8b..e536480d1b 100644
--- a/docs/UserGuide/Query-Data/Continuous-Query.md
+++ b/docs/UserGuide/Query-Data/Continuous-Query.md
@@ -75,19 +75,19 @@ END
#### `<start_time_offset>` == `<every_interval>`
-
+
#### `<start_time_offset>` > `<every_interval>`
-
+
#### `<start_time_offset>` < `<every_interval>`
-
+
#### `<every_interval>` is not zero
-
+
- `TIMEOUT POLICY` specify how we deal with the cq task whose previous time interval execution is not finished while the next execution time has reached. The default value is `BLOCKED`.
diff --git a/docs/UserGuide/Query-Data/Group-By.md b/docs/UserGuide/Query-Data/Group-By.md
index 41d14a4f4c..de71bee3de 100644
--- a/docs/UserGuide/Query-Data/Group-By.md
+++ b/docs/UserGuide/Query-Data/Group-By.md
@@ -135,7 +135,7 @@ The GROUP BY statement provides users with three types of specified parameters:
The actual meanings of the three types of parameters are shown in Figure below.
Among them, the parameter 3 is optional.
-<center><img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/16079446/69109512-f808bc80-0ab2-11ea-9e4d-b2b2f58fb474.png">
+<center><img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/69109512-f808bc80-0ab2-11ea-9e4d-b2b2f58fb474.png">
</center>
There are three typical examples of frequency reduction aggregation:
@@ -426,7 +426,7 @@ The devices `d1` and `d2` belong to the workshop `d1` in `Beijing`.
`d8` and `d9` are under maintenance, and don't belong to any workshops, so they have no tags.
-```SQL
+```sql
CREATE DATABASE root.factory1;
create timeseries root.factory1.d1.temperature with datatype=FLOAT tags(city=Beijing, workshop=w1);
create timeseries root.factory1.d2.temperature with datatype=FLOAT tags(city=Beijing, workshop=w1);
@@ -483,7 +483,7 @@ insert into root.factory1.d9(time, temperature) values(3000, 52.1);
If the user wants to know the average temperature of each workshop, he can query like this
-```SQL
+```sql
SELECT AVG(temperature) FROM root.factory1.** GROUP BY TAGS(city);
```
@@ -517,7 +517,7 @@ So the aggregation by the tag `city` should be done first, and then by the tag `
SQL
-```SQL
+```sql
SELECT avg(temperature) FROM root.factory1.** GROUP BY TAGS(city, workshop);
```
@@ -547,7 +547,7 @@ For example, a user wants to know the average temperature of the devices in each
SQL
-```SQL
+```sql
SELECT avg(temperature) FROM root.factory1.** GROUP BY ([1000, 10000), 5s), TAGS(city, workshop);
```
diff --git a/docs/UserGuide/QuickStart/Command-Line-Interface.md b/docs/UserGuide/QuickStart/Command-Line-Interface.md
index 996958c75b..b1b5bc60e1 100644
--- a/docs/UserGuide/QuickStart/Command-Line-Interface.md
+++ b/docs/UserGuide/QuickStart/Command-Line-Interface.md
@@ -46,9 +46,9 @@ After installation, there is a default user in IoTDB: `root`, and the
default password is `root`. Users can use this username to try IoTDB Cli/Shell tool. The cli startup script is the `start-cli` file under the \$IOTDB\_HOME/bin folder. When starting the script, you need to specify the IP and PORT. (Make sure the IoTDB cluster is running properly when you use Cli/Shell tool to connect to it.)
Here is an example where the cluster is started locally and the user has not changed the running port. The default rpc port is
-6667 </br>
+6667 <br>
If you need to connect to the remote DataNode or changes
-the rpc port number of the DataNode running, set the specific IP and RPC PORT at -h and -p.</br>
+the rpc port number of the DataNode running, set the specific IP and RPC PORT at -h and -p.<br>
You also can set your own environment variable at the front of the start script ("/sbin/start-cli.sh" for linux and "/sbin/start-cli.bat" for windows)
The Linux and MacOS system startup commands are as follows:
@@ -145,48 +145,48 @@ Shell >cd bin
Shell >bash ./standalone.sh
```
2、use url(https://ip:port/auth) login keycloack, the first login needs to create a user
-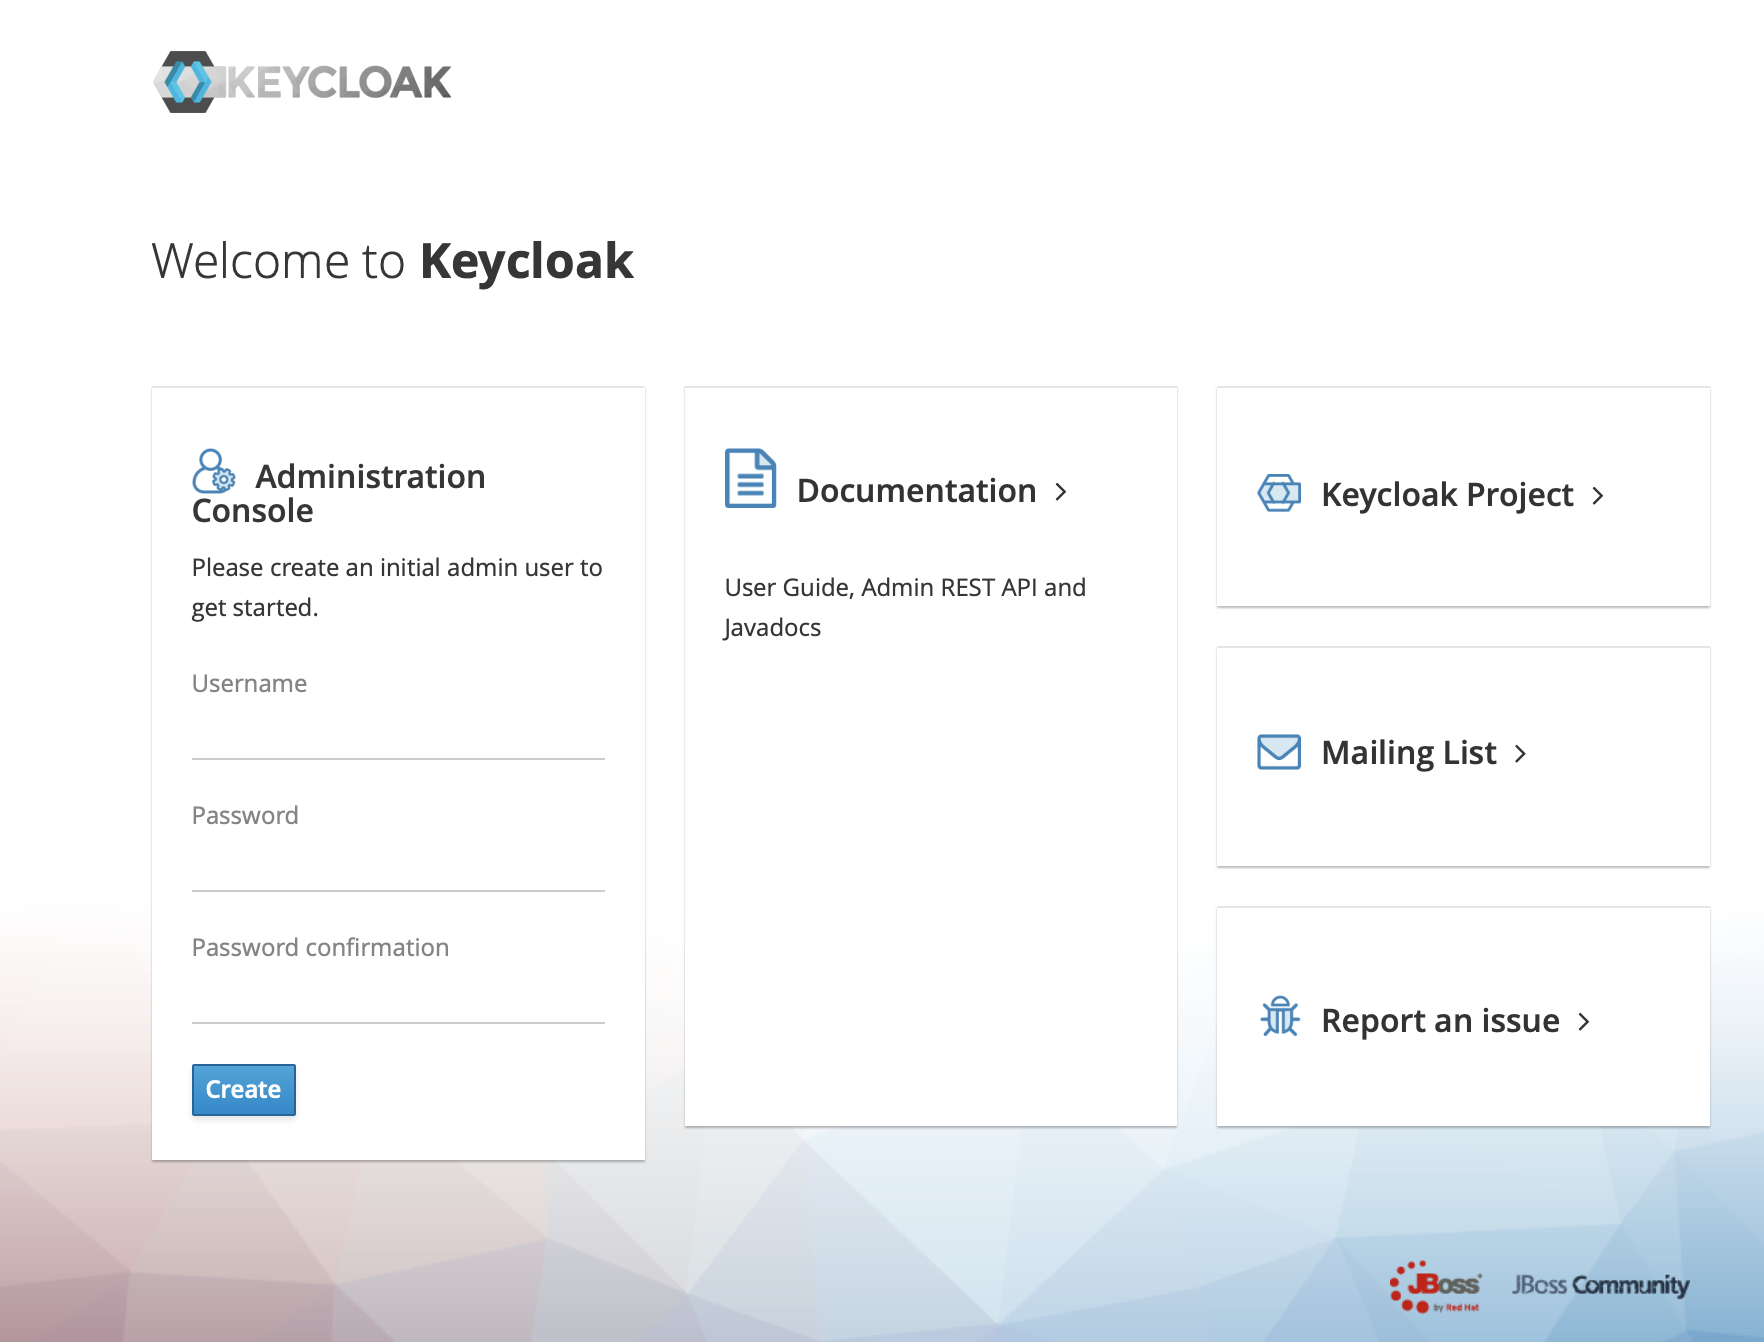
+
3、Click administration console
-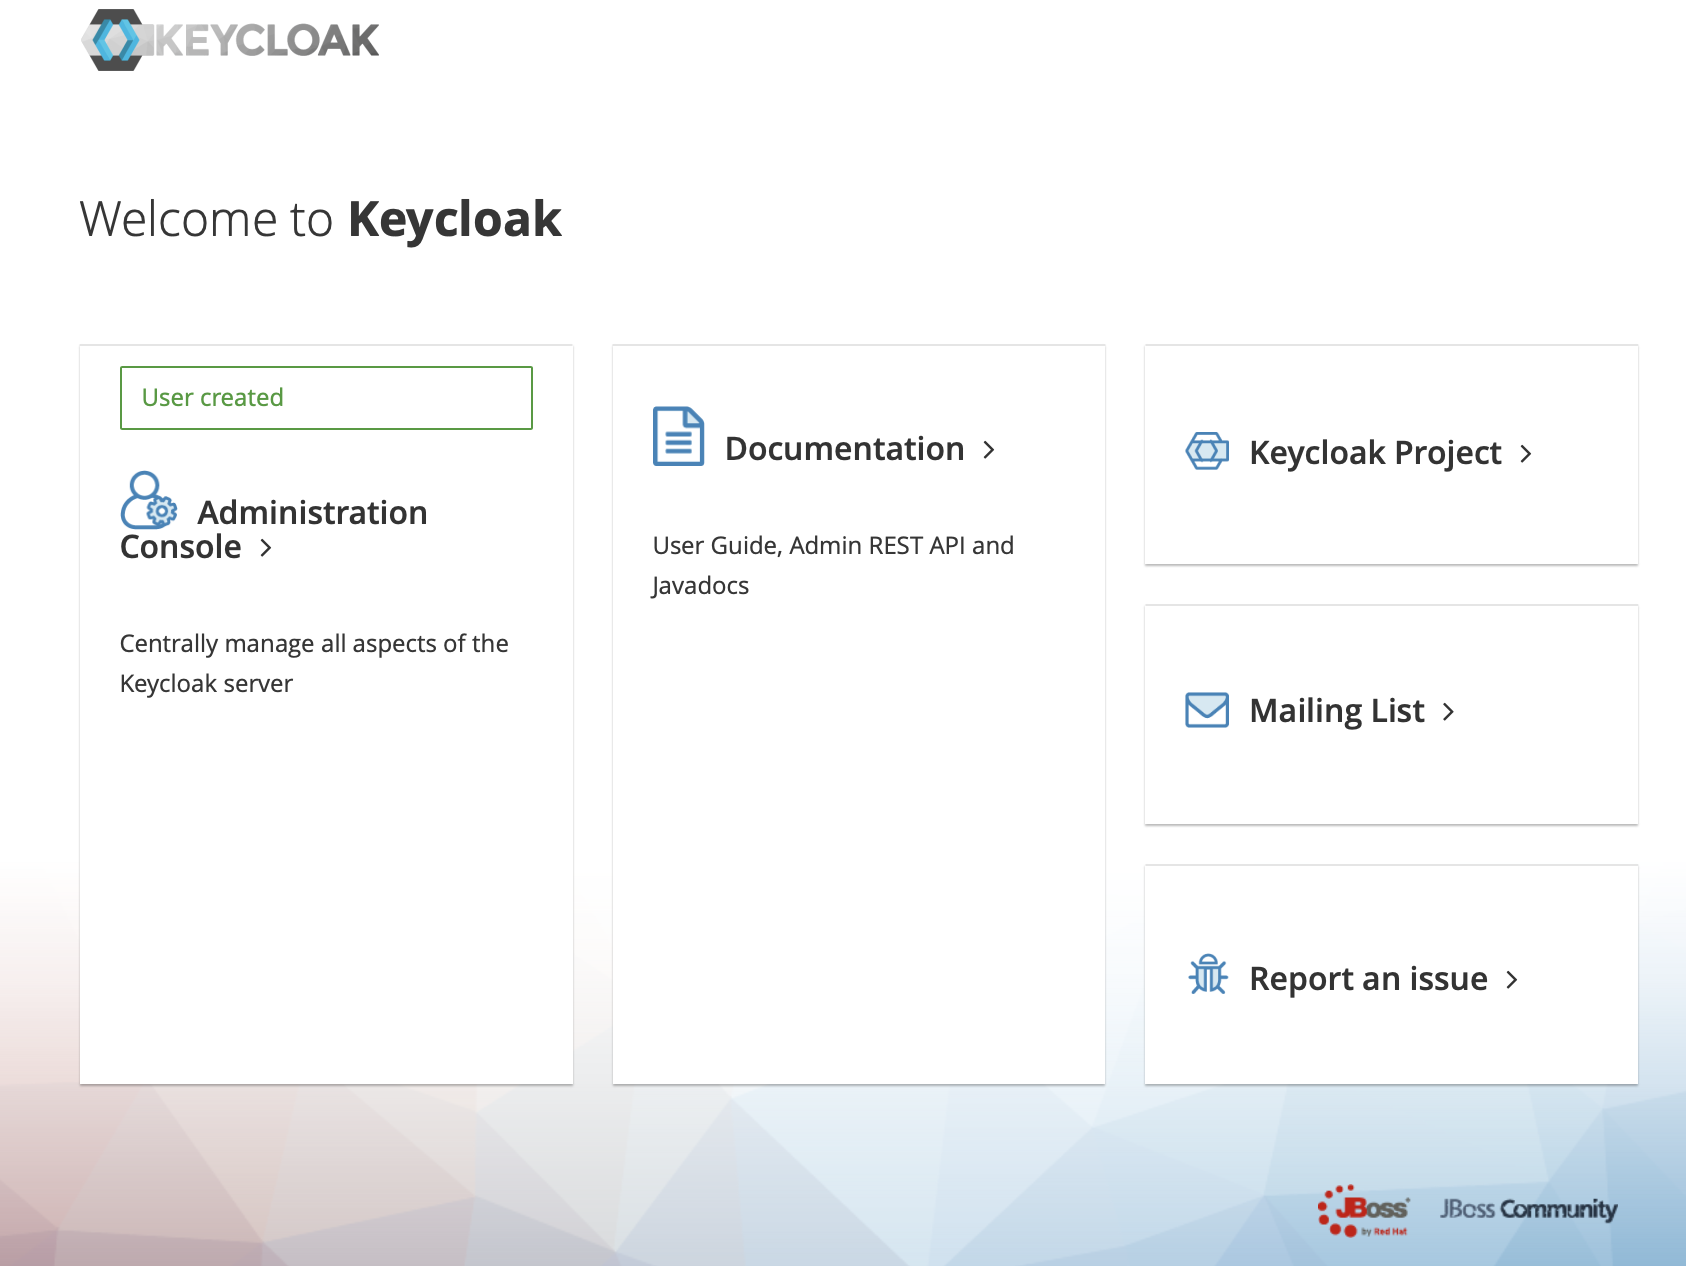
+
4、In the master menu on the left, click Add realm and enter name to create a new realm
-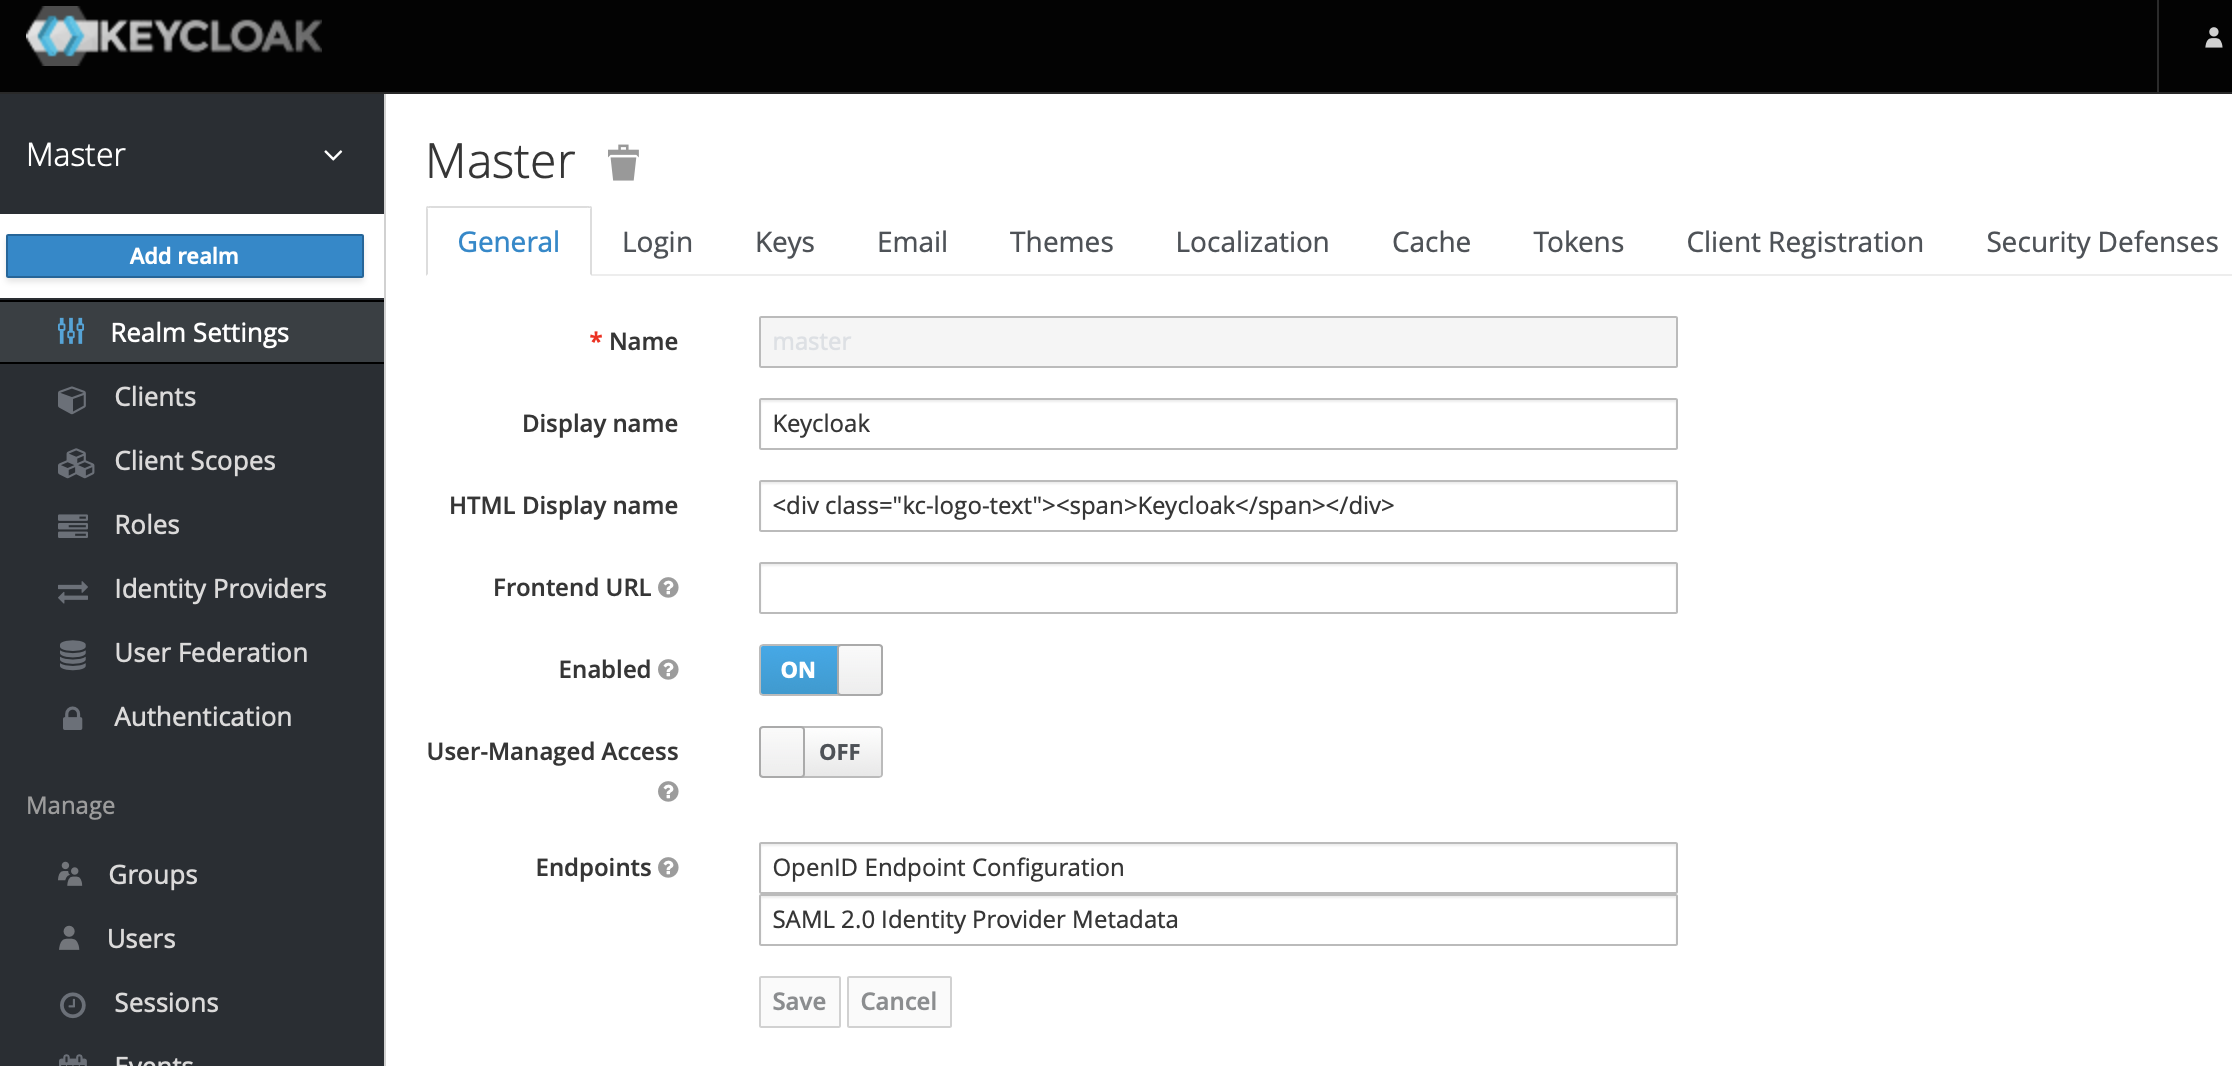
+
-
+
5、Click the menu clients on the left to create clients
-
+
6、Click user on the left menu to create user
-
+
7、Click the newly created user ID, click the credentials navigation, enter the password and close the temporary option. The configuration of keycloud is completed
-
+
8、To create a role, click Roles on the left menu and then click the Add Role button to add a role
-
+
9、 Enter `iotdb_admin` in the Role Name and click the save button. Tip: `iotdb_admin` here cannot be any other name, otherwise even after successful login, you will not have permission to use iotdb's query, insert, create database, add users, roles and other functions
-
+
10、Click the User menu on the left and click the Edit button in the user list to add the `iotdb_admin` role we just created for this user
-
+
11、 Select Role Mappings, select the `iotdb_admin` role in Available Role and click the Add selected button to add the role
-
+
12. If the `iotdb_admin` role is in Assigned Roles and the `Success Role mappings updated` prompt appears, it proves that the role was added successfully
-
+
Tip: If the user role is adjusted, you need to regenerate the token and log in to iotdb again to take effect
diff --git a/docs/UserGuide/QuickStart/QuickStart.md b/docs/UserGuide/QuickStart/QuickStart.md
index 56cd9349a2..e53716b45b 100644
--- a/docs/UserGuide/QuickStart/QuickStart.md
+++ b/docs/UserGuide/QuickStart/QuickStart.md
@@ -36,7 +36,7 @@ IoTDB provides you three installation methods, you can refer to the following su
* Installation from source code. If you need to modify the code yourself, you can use this method.
* Installation from binary files. Download the binary files from the official website. This is the recommended method, in which you will get a binary released package which is out-of-the-box.
-* Using Docker:The path to the dockerfile is https://github.com/apache/iotdb/blob/master/docker/src/main
+* Using Docker:The path to the dockerfile is [github](https://github.com/apache/iotdb/blob/master/docker/src/main)
## Download
diff --git a/docs/UserGuide/Reference/Common-Config-Manual.md b/docs/UserGuide/Reference/Common-Config-Manual.md
index e2c79e093e..fdeb08dc26 100644
--- a/docs/UserGuide/Reference/Common-Config-Manual.md
+++ b/docs/UserGuide/Reference/Common-Config-Manual.md
@@ -265,7 +265,7 @@ Different configuration parameters take effect in the following three ways:
|Name| concurrent\_writing\_time\_partition |
|:---:|:---|
-|Description| This config decides how many time partitions in a database can be inserted concurrently </br> For example, your partitionInterval is 86400 and you want to insert data in 5 different days, |
+|Description| This config decides how many time partitions in a database can be inserted concurrently <br> For example, your partitionInterval is 86400 and you want to insert data in 5 different days, |
|Type|int32|
|Default| 1 |
|Effective|After restarting system|
@@ -478,7 +478,7 @@ Different configuration parameters take effect in the following three ways:
| Name | mpp\_data\_exchange\_core\_pool\_size |
|:-----------:|:---------------------------------------------|
-| Description | The read consistency level, </br>1. strong(Default, read from the leader replica) </br>2. weak(Read from a random replica) |
+| Description | The read consistency level, <br>1. strong(Default, read from the leader replica) <br>2. weak(Read from a random replica) |
| Type | string |
| Default | strong |
| Effective | After restarting system |
diff --git a/docs/UserGuide/Reference/SQL-Reference.md b/docs/UserGuide/Reference/SQL-Reference.md
index 11276cb433..5bc5baaa32 100644
--- a/docs/UserGuide/Reference/SQL-Reference.md
+++ b/docs/UserGuide/Reference/SQL-Reference.md
@@ -1236,7 +1236,7 @@ Note: DateTime Type can support several types, see Chapter 3 Datetime section fo
PrecedenceEqualOperator : EQUAL | NOTEQUAL | LESSTHANOREQUALTO | LESSTHAN | GREATERTHANOREQUALTO | GREATERTHAN
```
```
-Timeseries : ROOT [DOT <LayerName>]* DOT <SensorName>
+Timeseries : ROOT [DOT \<LayerName\>]* DOT \<SensorName\>
LayerName : Identifier
SensorName : Identifier
eg. root.ln.wf01.wt01.status
@@ -1245,7 +1245,7 @@ Note: Timeseries must be start with `root`(case insensitive) and end with sensor
```
```
-PrefixPath : ROOT (DOT <LayerName>)*
+PrefixPath : ROOT (DOT \<LayerName\>)*
LayerName : Identifier | STAR
eg. root.sgcc
eg. root.*
diff --git a/docs/UserGuide/Reference/TSDB-Comparison.md b/docs/UserGuide/Reference/TSDB-Comparison.md
index 30d0ec449c..aaa0bf1789 100644
--- a/docs/UserGuide/Reference/TSDB-Comparison.md
+++ b/docs/UserGuide/Reference/TSDB-Comparison.md
@@ -23,7 +23,7 @@
## Overview
-
+
@@ -320,7 +320,7 @@ IoTDB uses batch insertion API and the batch size is distributed from 0 to 6000
The write throughput (points/second) is:
-
+
<span id = "exp1"> <center>Figure 1. Batch Size with Write throughput (points/second) IoTDB v0.11.1</center></span>
* client num:
@@ -330,24 +330,24 @@ IoTDB uses batch insertion API and the batch size is 100 (write 100 data points
The write throughput (points/second) is:
-
+
<center>Figure 3. Client Num with Write Throughput (points/second) IoTDB v0.11.1</center>
**Query performance**
-
+
<center>Figure 4. Raw data query 1 col time cost(ms) IoTDB v0.11.1</center>
-
+
<center>Figure 5. Aggregation query time cost(ms) IoTDB v0.11.1</center>
-
+
<center>Figure 6. Downsampling query time cost(ms) IoTDB v0.11.1</center>
-
+
<center>Figure 7. Latest query time cost(ms) IoTDB v0.11.1</center>
-
+
<center>Figure 8. Data compression IoTDB v0.11.1</center>
We can see that IoTDB outperforms others.
diff --git a/docs/UserGuide/Syntax-Conventions/Identifier.md b/docs/UserGuide/Syntax-Conventions/Identifier.md
index 9fee4778ef..659c513522 100644
--- a/docs/UserGuide/Syntax-Conventions/Identifier.md
+++ b/docs/UserGuide/Syntax-Conventions/Identifier.md
@@ -47,7 +47,7 @@ Below are basic constraints of identifiers, specific identifiers may have other
` may be written as `` in quoted identifiers. See the example below:
-```SQL
+```sql
# create template t1't"t
create schema template `t1't"t`
(temperature FLOAT encoding=RLE, status BOOLEAN encoding=PLAIN compression=SNAPPY)
diff --git a/docs/UserGuide/Syntax-Conventions/KeyValue-Pair.md b/docs/UserGuide/Syntax-Conventions/KeyValue-Pair.md
index c59efcbc3c..3041b1b81a 100644
--- a/docs/UserGuide/Syntax-Conventions/KeyValue-Pair.md
+++ b/docs/UserGuide/Syntax-Conventions/KeyValue-Pair.md
@@ -27,7 +27,7 @@ Below are usage scenarios of key-value pair:
- Attributes fields of trigger. See the attributes after `With` clause in the example below:
-```SQL
+```sql
# 以字符串形式表示键值对
CREATE TRIGGER `alert-listener-sg1d1s1`
AFTER INSERT
@@ -109,7 +109,7 @@ SHOW timeseries root.ln.** WHRER unit = c
- Attributes fields of Pipe and PipeSink.
-```SQL
+```sql
# PipeSink example
CREATE PIPESINK my_iotdb AS IoTDB ('ip' = '输入你的IP')
diff --git a/docs/UserGuide/Syntax-Conventions/Literal-Values.md b/docs/UserGuide/Syntax-Conventions/Literal-Values.md
index 52326d3bfa..48e608b279 100644
--- a/docs/UserGuide/Syntax-Conventions/Literal-Values.md
+++ b/docs/UserGuide/Syntax-Conventions/Literal-Values.md
@@ -38,7 +38,7 @@ Usages of string literals:
- Values of `TEXT` type data in `INSERT` or `SELECT` statements
- ```SQL
+ ```sql
# insert
insert into root.ln.wf02.wt02(timestamp,hardware) values(1, 'v1')
insert into root.ln.wf02.wt02(timestamp,hardware) values(2, '\\')
@@ -57,7 +57,7 @@ Usages of string literals:
- Used in`LOAD` / `REMOVE` / `SETTLE` instructions to represent file path.
- ```SQL
+ ```sql
# load
LOAD 'examplePath'
@@ -70,14 +70,14 @@ Usages of string literals:
- Password fields in user management statements
- ```SQL
+ ```sql
# write_pwd is the password
CREATE USER ln_write_user 'write_pwd'
```
- Full Java class names in UDF and trigger management statements
- ```SQL
+ ```sql
# Trigger example. Full java class names after 'AS' should be string literals.
CREATE TRIGGER `alert-listener-sg1d1s1`
AFTER INSERT
@@ -94,7 +94,7 @@ Usages of string literals:
- `AS` function provided by IoTDB can assign an alias to time series selected in query. Alias can be constant(including string) or identifier.
- ```SQL
+ ```sql
select s1 as 'temperature', s2 as 'speed' from root.ln.wf01.wt01;
# Header of dataset
diff --git a/docs/UserGuide/Syntax-Conventions/NodeName-In-Path.md b/docs/UserGuide/Syntax-Conventions/NodeName-In-Path.md
index ea1c55791e..19dc1b4331 100644
--- a/docs/UserGuide/Syntax-Conventions/NodeName-In-Path.md
+++ b/docs/UserGuide/Syntax-Conventions/NodeName-In-Path.md
@@ -31,7 +31,7 @@ Node name is a special identifier, it can also be wildcard `*` and `**`. When cr
As `*` can also be used in expressions of select clause to represent multiplication, below are examples to help you better understand the usage of `* `:
-```SQL
+```sql
# create timeseries root.sg.`a*b`
create timeseries root.sg.`a*b` with datatype=FLOAT,encoding=PLAIN;
@@ -61,7 +61,7 @@ When node name is not wildcard, it is a identifier, which means the constraints
- Create timeseries statement:
-```SQL
+```sql
# Node name contains special characters like ` and .,all nodes of this timeseries are: ["root","sg","www.`baidu.com"]
create timeseries root.sg.`www.``baidu.com`.a with datatype=FLOAT,encoding=PLAIN;
@@ -71,7 +71,7 @@ create timeseries root.sg.`111` with datatype=FLOAT,encoding=PLAIN;
After executing above statments, execute "show timeseries",below is the result:
-```SQL
+```sql
+---------------------------+-----+-------------+--------+--------+-----------+----+----------+
| timeseries|alias|database|dataType|encoding|compression|tags|attributes|
+---------------------------+-----+-------------+--------+--------+-----------+----+----------+
@@ -82,7 +82,7 @@ After executing above statments, execute "show timeseries",below is the result
- Insert statment:
-```SQL
+```sql
# Node name contains special characters like . and `
insert into root.sg.`www.``baidu.com`(timestamp, a) values(1, 2);
@@ -92,7 +92,7 @@ insert into root.sg(timestamp, `111`) values (1, 2);
- Query statement:
-```SQL
+```sql
# Node name contains special characters like . and `
select a from root.sg.`www.``baidu.com`;
@@ -102,7 +102,7 @@ select `111` from root.sg
Results:
-```SQL
+```sql
# select a from root.sg.`www.``baidu.com`
+-----------------------------+---------------------------+
| Time|root.sg.`www.``baidu.com`.a|
diff --git a/docs/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md b/docs/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md
index 7f085e4e80..6d0c171fac 100644
--- a/docs/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md
+++ b/docs/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md
@@ -25,7 +25,7 @@ When using the Session and TsFile APIs, if the method you call requires paramete
1. Take creating a time series createTimeseries as an example:
-```Java
+```java
public void createTimeseries(
String path,
TSDataType dataType,
@@ -36,7 +36,7 @@ public void createTimeseries(
If you wish to create the time series root.sg.a, root.sg.\`a.\`\`"b\`, root.sg.\`111\`, the SQL statement you use should look like this:
-```SQL
+```sql
create timeseries root.sg.a with datatype=FLOAT,encoding=PLAIN,compressor=SNAPPY;
# node names contain special characters, each node in the time series is ["root","sg","a.`\"b"]
@@ -48,7 +48,7 @@ create timeseries root.sg.`111` with datatype=FLOAT,encoding=PLAIN,compressor=SN
When you call the createTimeseries method, you should assign the path string as follows to ensure that the content of the path string is the same as when using SQL:
-```Java
+```java
// timeseries root.sg.a
String path = "root.sg.a";
@@ -61,7 +61,7 @@ String path = "root.sg.`111`";
2. Take inserting data insertRecord as an example:
-```Java
+```java
public void insertRecord(
String deviceId,
long time,
@@ -73,13 +73,13 @@ public void insertRecord(
If you want to insert data into the time series root.sg.a, root.sg.\`a.\`\`"b\`, root.sg.\`111\`, the SQL statement you use should be as follows:
-```SQL
+```sql
insert into root.sg(timestamp, a, `a.``"b`, `111`) values (1, 2, 2, 2);
```
When you call the insertRecord method, you should assign deviceId and measurements as follows:
-```Java
+```java
// deviceId is root.sg
String deviceId = "root.sg";
@@ -90,7 +90,7 @@ List<String> measurementList = Arrays.asList(measurements);
3. Take executeRawDataQuery as an example:
-```Java
+```java
public SessionDataSet executeRawDataQuery(
List<String> paths,
long startTime,
@@ -100,7 +100,7 @@ public SessionDataSet executeRawDataQuery(
If you wish to query the data of the time series root.sg.a, root.sg.\`a.\`\`"b\`, root.sg.\`111\`, the SQL statement you use should be as follows :
-```SQL
+```sql
select a from root.sg
# node name contains special characters
@@ -112,7 +112,7 @@ select `111` from root.sg
When you call the executeRawDataQuery method, you should assign paths as follows:
-```Java
+```java
// paths
String[] paths = new String[]{"root.sg.a", "root.sg.`a.``\"b`", "root.sg.`111`"};
List<String> pathList = Arrays.asList(paths);
diff --git a/docs/UserGuide/UserGuideReadme.md b/docs/UserGuide/UserGuideReadme.md
index 4c6c9d4cb7..e5201f0297 100644
--- a/docs/UserGuide/UserGuideReadme.md
+++ b/docs/UserGuide/UserGuideReadme.md
@@ -26,7 +26,6 @@ The "In Progress Version" is for matching the master branch of IOTDB's source co
Other documents are for IoTDB previous released versions.
- [In progress version](https://iotdb.apache.org/UserGuide/Master/QuickStart/QuickStart.html)
-- [Version 0.10.x](https://iotdb.apache.org/UserGuide/V0.10.x/Get%20Started/QuickStart.html)
-- [Version 0.9.x](https://iotdb.apache.org/UserGuide/V0.9.x/0-Get%20Started/1-QuickStart.html)
-- [Version 0.8.x](https://iotdb.apache.org/UserGuide/V0.8.x/0-Get%20Started/1-QuickStart.html)
+- [Version 1.0.x](https://iotdb.apache.org/UserGuide/V1.0.x/QuickStart/QuickStart.html)
+- [Version 0.13.x](https://iotdb.apache.org/UserGuide/V0.13.x/QuickStart/QuickStart.html)
diff --git a/docs/zh/UserGuide/API/InfluxDB-Protocol.md b/docs/zh/UserGuide/API/InfluxDB-Protocol.md
index 772e195613..2f195950b9 100644
--- a/docs/zh/UserGuide/API/InfluxDB-Protocol.md
+++ b/docs/zh/UserGuide/API/InfluxDB-Protocol.md
@@ -52,9 +52,9 @@ InfluxDB influxDB = IoTDBInfluxDBFactory.connect(openurl, username, password);
该适配器以 IoTDB Java ServiceProvider 接口为底层基础,实现了 InfluxDB 的 Java 接口 `interface InfluxDB`,对用户提供了所有 InfluxDB 的接口方法,最终用户可以无感知地使用 InfluxDB 协议向 IoTDB 发起写入和读取请求。
-
+
-
+
### 2.2 元数据格式转换
@@ -68,7 +68,7 @@ InfluxDB 的元数据是 tag-field 模型,IoTDB 的元数据是树形模型。
3. tags : 各种有索引的属性。
4. fields : 各种记录值(没有索引的属性)。
-
+
#### 2.2.2 IoTDB 元数据
@@ -76,7 +76,7 @@ InfluxDB 的元数据是 tag-field 模型,IoTDB 的元数据是树形模型。
2. path(time series ID):存储路径。
3. measurement: 物理量。
-
+
#### 2.2.3 两者映射关系
@@ -89,7 +89,7 @@ InfluxDB 元数据向 IoTDB 元数据的转换关系可以由下面的公示表
`root.{database}.{measurement}.{tag value 1}.{tag value 2}...{tag value N-1}.{tag value N}.{field key}`
-
+
如上图所示,可以看出:
diff --git a/docs/zh/UserGuide/API/Programming-JDBC.md b/docs/zh/UserGuide/API/Programming-JDBC.md
index f0c0b5de19..f335274f8d 100644
--- a/docs/zh/UserGuide/API/Programming-JDBC.md
+++ b/docs/zh/UserGuide/API/Programming-JDBC.md
@@ -56,7 +56,7 @@ mvn clean install -pl jdbc -am -Dmaven.test.skip=true
**注意:为了更快地插入,建议使用 executeBatch()**
-```Java
+```java
import java.sql.*;
import org.apache.iotdb.jdbc.IoTDBSQLException;
diff --git a/docs/zh/UserGuide/API/Programming-MQTT.md b/docs/zh/UserGuide/API/Programming-MQTT.md
index 97d018966f..d7db5d695c 100644
--- a/docs/zh/UserGuide/API/Programming-MQTT.md
+++ b/docs/zh/UserGuide/API/Programming-MQTT.md
@@ -30,7 +30,7 @@
IoTDB 支持 MQTT v3.1(OASIS 标准)协议。
IoTDB 服务器包括内置的 MQTT 服务,该服务允许远程设备将消息直接发送到 IoTDB 服务器。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/6711230/78357432-0c71cf80-75e4-11ea-98aa-c43a54d469ce.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/78357432-0c71cf80-75e4-11ea-98aa-c43a54d469ce.png">
### 内置 MQTT 服务
内置的 MQTT 服务提供了通过 MQTT 直接连接到 IoTDB 的能力。 它侦听来自 MQTT 客户端的发布消息,然后立即将数据写入存储。
@@ -57,7 +57,7 @@ MQTT 主题与 IoTDB 时间序列相对应。
```
或者以上两者的JSON数组形式。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/6711230/78357469-1bf11880-75e4-11ea-978f-a53996667a0d.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/78357469-1bf11880-75e4-11ea-978f-a53996667a0d.png">
### MQTT 配置
默认情况下,IoTDB MQTT 服务从`${IOTDB_HOME}/${IOTDB_CONF}/iotdb-datanode.properties`加载配置。
diff --git a/docs/zh/UserGuide/API/Programming-Python-Native-API.md b/docs/zh/UserGuide/API/Programming-Python-Native-API.md
index 115488b729..8e65c90c6b 100644
--- a/docs/zh/UserGuide/API/Programming-Python-Native-API.md
+++ b/docs/zh/UserGuide/API/Programming-Python-Native-API.md
@@ -471,7 +471,7 @@ SQLAlchemy 中的元数据有:
下图更加清晰的展示了二者的映射关系:
-
+
#### 数据类型映射
| IoTDB 中的数据类型 | SQLAlchemy 中的数据类型 |
diff --git a/docs/zh/UserGuide/Cluster/Cluster-Concept.md b/docs/zh/UserGuide/Cluster/Cluster-Concept.md
index 5e16fc2ea6..b8efedbfdc 100644
--- a/docs/zh/UserGuide/Cluster/Cluster-Concept.md
+++ b/docs/zh/UserGuide/Cluster/Cluster-Concept.md
@@ -27,7 +27,7 @@ Apache IoTDB 集群版包含两种角色的节点,ConfigNode 和 DataNode,
集群架构示例如下图:
-<img style="width:100%; max-width:500px; max-height:400px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Cluster/Architecture.png?raw=true">
+<img style="width:100%; max-width:500px; max-height:400px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Cluster/Architecture.png?raw=true">
ConfigNode 是集群的控制节点,管理集群的节点状态、分区信息等,集群所有 ConfigNode 组成一个高可用组,数据全量备份。
@@ -100,7 +100,7 @@ Region 是数据复制的基本单位,一个 Region 的多个副本构成了
完整的集群分区复制的示意图如下:
-<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Cluster/Data-Partition.png?raw=true">
+<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Cluster/Data-Partition.png?raw=true">
图中包含 1 个 SchemaRegionGroup,元数据采用 3 副本,因此 3 个白色的 SchemaRegion-0 组成了一个副本组。
diff --git a/docs/zh/UserGuide/Cluster/Cluster-Maintenance.md b/docs/zh/UserGuide/Cluster/Cluster-Maintenance.md
index a69785d586..b25364af56 100644
--- a/docs/zh/UserGuide/Cluster/Cluster-Maintenance.md
+++ b/docs/zh/UserGuide/Cluster/Cluster-Maintenance.md
@@ -124,7 +124,7 @@ It costs 0.006s
### DataNode 状态定义
DataNode 的状态机如下图所示:
-<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Cluster/DataNode-StateMachine-ZH.jpg?raw=true">
+<img style="width:100%; max-width:500px; max-height:500px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Cluster/DataNode-StateMachine-ZH.jpg?raw=true">
对 DataNode 各状态定义如下:
diff --git a/docs/zh/UserGuide/Data-Concept/Data-Model-and-Terminology.md b/docs/zh/UserGuide/Data-Concept/Data-Model-and-Terminology.md
index 59f313ad1b..398918bc6b 100644
--- a/docs/zh/UserGuide/Data-Concept/Data-Model-and-Terminology.md
+++ b/docs/zh/UserGuide/Data-Concept/Data-Model-and-Terminology.md
@@ -25,7 +25,7 @@
根据企业组织结构和设备实体层次结构,我们将其物联网数据模型表示为如下图所示的属性层级组织结构,即电力集团层-风电场层-实体层-物理量层。其中 ROOT 为根节点,物理量层的每一个节点为叶子节点。IoTDB 采用树形结构定义数据模式,以从 ROOT 节点到叶子节点的路径来命名一个时间序列,层次间以“.”连接。例如,下图最左侧路径对应的时间序列名称为`ROOT.ln.wf01.wt01.status`。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/123542457-5f511d00-d77c-11eb-8006-562d83069baa.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/123542457-5f511d00-d77c-11eb-8006-562d83069baa.png">
在上图所描述的实际场景中,有许多实体所采集的物理量相同,即具有相同的工况名称和类型,因此,可以声明一个**元数据模板**来定义可采集的物理量集合。在实践中,元数据模板的使用可帮助减少元数据的资源占用,详细内容参见 [元数据模板文档](./Schema-Template.md)。
@@ -135,6 +135,6 @@ wildcard
插入数据时,对齐的时间序列中某列的某些行允许有空值。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/114125919-f4850800-9929-11eb-8211-81d4c04af1ec.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/114125919-f4850800-9929-11eb-8211-81d4c04af1ec.png">
在后续数据定义语言、数据操作语言和 Java 原生接口章节,将对涉及到对齐时间序列的各种操作进行逐一介绍。
diff --git a/docs/zh/UserGuide/Data-Concept/Schema-Template.md b/docs/zh/UserGuide/Data-Concept/Schema-Template.md
index 34a7967e35..e3b8d98249 100644
--- a/docs/zh/UserGuide/Data-Concept/Schema-Template.md
+++ b/docs/zh/UserGuide/Data-Concept/Schema-Template.md
@@ -29,7 +29,7 @@
下图展示了一个燃油车场景的数据模型,各地区的多台燃油车的速度、油量、加速度、角速度四个物理量将会被采集,显然这些燃油车实体具备相同的物理量。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Measurement%20Template/example_without_template.png?raw=true" alt="example without template">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Measurement-Template/example_without_template.png?raw=true" alt="example without template">
## 概念定义
@@ -45,7 +45,7 @@
使用元数据模板后,问题背景中示例的燃油车数据模型将会转变至下图所示的形式。所有的物理量元数据仅在模板中保存一份,所有的实体共享模板中的元数据。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Measurement%20Template/example_with_template.png?raw=true" alt="example with template">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Measurement-Template/example_with_template.png?raw=true" alt="example with template">
### 生命周期
@@ -60,7 +60,7 @@
最后需要补充的是,**对挂载模板与激活模板进行区分,是为了服务一种常见的场景**:在 Apache IoTDB 元数据模型 MTree 中,经常需要在数量众多的节点上“应用”元数据模板,而这些节点一般拥有共同的祖先节点。因此,可以在其共同祖先节点**挂载**模板,而不必对其大量的孩子节点进行挂载操作。对于需要“应用”模板的节点,则应该使用**激活模板**的操作。
-<img style="width:100%; max-width:800px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Measurement%20Template/example_template_lifetime_zh.png?raw=true" alt="example with template">
+<img style="width:100%; max-width:800px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Measurement-Template/example_template_lifetime_zh.png?raw=true" alt="example with template">
## 使用
diff --git a/docs/zh/UserGuide/Data-Concept/Time-Partition.md b/docs/zh/UserGuide/Data-Concept/Time-Partition.md
index b2f65b06bf..c1b8fd3073 100644
--- a/docs/zh/UserGuide/Data-Concept/Time-Partition.md
+++ b/docs/zh/UserGuide/Data-Concept/Time-Partition.md
@@ -38,7 +38,7 @@
开启时间分区功能,并设置 partition_interval 为 86400000(一天),则数据的分布情况如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Time-Partition/time_partition_example.png?raw=true" alt="time partition example">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Time-Partition/time_partition_example.png?raw=true" alt="time partition example">
* 插入一条时间戳为 0 的数据,计算 0 / 86400000 = 0,则该数据会被存储到 0 号文件夹下的TsFile中
diff --git a/docs/zh/UserGuide/Ecosystem-Integration/DBeaver.md b/docs/zh/UserGuide/Ecosystem-Integration/DBeaver.md
index 26b198dd47..65cd7799a9 100644
--- a/docs/zh/UserGuide/Ecosystem-Integration/DBeaver.md
+++ b/docs/zh/UserGuide/Ecosystem-Integration/DBeaver.md
@@ -46,10 +46,10 @@ DBeaver 是一个 SQL 客户端和数据库管理工具。DBeaver 可以使用 I
3. 打开 Driver Manager
- 
+ 
4. 为 IoTDB 新建一个驱动类型
- 
+ 
5. 下载[源代码](https://iotdb.apache.org/zh/Download/),解压并运行下面的命令编译 jdbc 驱动
@@ -58,15 +58,15 @@ DBeaver 是一个 SQL 客户端和数据库管理工具。DBeaver 可以使用 I
```
7. 在`jdbc/target/`下找到并添加名为`apache-iotdb-jdbc-{version}-jar-with-dependencies.jar`的库,点击 `Find Class`。
- 
+ 
8. 编辑驱动设置
- 
+ 
9. 新建 DataBase Connection, 选择 iotdb
- 
+ 
10. 编辑 JDBC 连接设置
@@ -75,12 +75,12 @@ DBeaver 是一个 SQL 客户端和数据库管理工具。DBeaver 可以使用 I
Username: root
Password: root
```
- 
+ 
11. 测试连接
- 
+ 
12. 可以开始通过 DBeaver 使用 IoTDB
- 
+ 
diff --git a/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Connector.md b/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Connector.md
index 3b60f231b2..c18f9d6d85 100644
--- a/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Connector.md
+++ b/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Connector.md
@@ -131,16 +131,16 @@ Grafana 以网页的 dashboard 形式为您展示数据,在使用时请您打
#### 添加 IoTDB 数据源
点击左上角的“Grafana”图标,选择`Data Source`选项,然后再点击`Add data source`。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51664777-2766ae00-1ff5-11e9-9d2f-7489f8ccbfc2.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51664777-2766ae00-1ff5-11e9-9d2f-7489f8ccbfc2.png">
在编辑数据源的时候,`Type`一栏选择`Simplejson`,`URL`一栏填写 http://\<ip\>:\<port\>,IP 为您的 IoTDB-Grafana-Connector 连接器所在的服务器 IP,Port 为运行端口(默认 8888)。之后确保 IoTDB 已经启动,点击“Save & Test”,出现“Data Source is working”提示表示配置成功。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51664842-554bf280-1ff5-11e9-97d2-54eebe0b2ca1.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51664842-554bf280-1ff5-11e9-97d2-54eebe0b2ca1.png">
#### 操作 Grafana
进入 Grafana 可视化页面后,可以选择添加时间序列,如下图。您也可以按照 Grafana 官方文档进行相应的操作,详情可参看 Grafana 官方文档:http://docs.grafana.org/guides/getting_started/。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51664878-6e54a380-1ff5-11e9-9718-4d0e24627fa8.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51664878-6e54a380-1ff5-11e9-9718-4d0e24627fa8.png">
### 配置 grafana
diff --git a/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Plugin.md b/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Plugin.md
index c816dc35f1..dd7154179e 100644
--- a/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Plugin.md
+++ b/docs/zh/UserGuide/Ecosystem-Integration/Grafana-Plugin.md
@@ -83,7 +83,7 @@ go get: module github.com/grafana/grafana-plugin-sdk-go: Get "https://proxy.gola
如果编译成功,我们将看到生成的目标文件夹 `dist`,它包含了编译好的 Grafana 前端插件:
-<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana-plugin-build.png?raw=true">
+<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana-plugin-build.png?raw=true">
##### 方案三 IoTDB 的分发包完整编译
@@ -108,7 +108,7 @@ git clone https://github.com/apache/iotdb.git
如果编译成功,我们将看到 `distribution/target` 路径下包含了编译好的 Grafana 前端插件:
-<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/distribution.png?raw=true">
+<img style="width:100%; max-width:333px; max-height:545px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/distribution.png?raw=true">
@@ -187,9 +187,9 @@ Grafana 以网页的 dashboard 形式为您展示数据,在使用时请您打
点击左侧的 `设置` 图标,选择 `Data Source` 选项,然后再点击 `Add data source`。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/datasource_1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/datasource_1.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/datasource_2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/datasource_2.png?raw=true">
选择 `Apache IoTDB` 数据源,`URL` 一栏填写 `http://<ip>:<port>`。
@@ -197,7 +197,7 @@ Ip 为您的 IoTDB 服务器所在的宿主机 IP,port 为 REST 服务的运
输入 IoTDB 服务器的 username 和 password,点击 `Save & Test`,出现 `Success` 则提示配置成功。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/datasource_3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/datasource_3.png?raw=true">
@@ -205,15 +205,15 @@ Ip 为您的 IoTDB 服务器所在的宿主机 IP,port 为 REST 服务的运
点击左侧的 `Dashboards` 图标,选择 `Manage`,如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/manage.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/manage.png?raw=true">
点击右上方的 `New Dashboard` 图标,选择 `Add an empty panel`,如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/add%20empty%20panel.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/add-empty-panel.png?raw=true">
Grafana Plugin 支持SQL: Full Customized和SQL: Drop-down List 两种方式,默认是SQL: Full Customized方式。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana_input_style.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana_input_style.png?raw=true">
##### SQL: Full Customized 输入方式
@@ -221,7 +221,7 @@ Grafana Plugin 支持SQL: Full Customized和SQL: Drop-down List 两种方式,
如果一个查询涉及多个表达式,我们可以点击 SELECT 输入框右侧的 `+` 来添加 SELECT 子句中的表达式,也可以点击 FROM 输入框右侧的 `+` 来添加路径前缀,如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana_input.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana_input.png?raw=true">
SELECT 输入框中的内容可以是时间序列的后缀,可以是函数或自定义函数,可以是算数表达式,也可以是它们的嵌套表达式。您还可以使用 as 子句来重命名需要显示的结果序列名字。
@@ -254,7 +254,7 @@ CONTROL 输入框为非必须填写项目,填写内容应当是控制查询类
##### SQL: Drop-down List 输入方式
在 TIME-SERIES 选择框中选择一条时间序列、FUNCTION 选择一个函数、SAMPLING INTERVAL、SLIDING STEP、LEVEL、FILL 输入框中输入内容,其中 TIME-SERIESL 为必填项其余为非必填项。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/grafana_input2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/grafana_input2.png?raw=true">
#### 变量与模板功能的支持
@@ -262,32 +262,32 @@ SQL: Full Customized和SQL: Drop-down List两种输入方式都支持 Grafana
创建一个新的 Panel 后,点击右上角的设置按钮,如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/setconf.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/setconf.png?raw=true">
选择 `Variables`,点击 `Add variable` ,如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/addvaribles.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/addvaribles.png?raw=true">
示例一:输入 `Name`,`Label`,选择Type的`Query`、在Query 中输入show child paths xx , 点击 `Update` 按钮,如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput.png?raw=true">
应用 Variables,在 `grafana panel` 中输入变量点击 `save` 按钮,如下图所示
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/applyvariables.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/applyvariables.png?raw=true">
示例二:变量嵌套使用,如下图所示
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput2.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput2-1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput2-1.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variblesinput2-2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variblesinput2-2.png?raw=true">
示例三:函数变量使用,如下图所示
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variablesinput3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variablesinput3.png?raw=true">
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/variablesinput3-1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/variablesinput3-1.png?raw=true">
上图中Name 是变量名称也是将来我们在panel中使用的变量名称,Label是变量的展示名称如果为空就显示Name的变量反之则显示Label的名称,
Type下拉中有Query、Custom、Text box、Constant、DataSource、Interval、Ad hoc filters等这些都可以在IoTDB的Grafana Plugin 中使用
@@ -309,29 +309,29 @@ Type下拉中有Query、Custom、Text box、Constant、DataSource、Interval、A
1、在 Grafana 侧栏中,将光标悬停在`Alerting`图标上,然后单击`Notification channels`。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting1.png?raw=true">
2、单击添加频道。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting2.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting2.png?raw=true">
3、填写下面描述的字段或选择选项,Type有好多种类型包括DingDing、Email、Slack、WebHook、Prometheus Alertmanager等。
本次示例Type使用`Prometheus Alertmanager`,需要提前安装好Prometheus Alertmanager,更多详细的配置及参数介绍请参考官方文档:https://grafana.com/docs/grafana/v8.0/alerting/old-alerting/notifications/。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting3.png?raw=true">
4、点击`Test`按钮,出现`Test notification sent`点击`Save`按钮保存
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alerting4.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alerting4.png?raw=true">
5、创建一个新的 Panel 后,输入查询参数后点击保存然后选择`Alert`点击`Create Alert`,如下图所示:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanle1.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanle1.png?raw=true">
6、填写下面描述的字段或选择选项, 其中`Name`是规则名称,`Evaluate every` 指定调度程序评估警报规则的频率,称为评估间隔,
`FOR` 指定在触发警报通知之前查询需要在多长时间内违反配置的阈值。`Conditions` 表示查询条件,可以配置多个组合查询条件。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanle2.jpg?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanle2.jpg?raw=true">
图中的查询条件:avg() OF query(A,5m,now) IS ABOVE -1
@@ -346,19 +346,19 @@ IS ABOVE -1 定义阈值的类型和阈值。IS ABOVE表示在-1之上,可以
7、点击`Test rule` 按钮出现`firing: true`则配置成功,点击`save` 按钮
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanel3.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanel3.png?raw=true">
8、下图为grafana panel 中显示告警
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanel4.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanel4.png?raw=true">
9、查看告警规则
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertPanel5.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertPanel5.png?raw=true">
10、在promehthus alertmanager 中查看告警记录
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Ecosystem%20Integration/Grafana-plugin/alertpanel6.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Ecosystem-Integration/Grafana-plugin/alertpanel6.png?raw=true">
### 更多
diff --git a/docs/zh/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md b/docs/zh/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md
index 686aa96a8c..cdc73cbb1b 100644
--- a/docs/zh/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md
+++ b/docs/zh/UserGuide/Ecosystem-Integration/NiFi-IoTDB.md
@@ -128,7 +128,7 @@ Apache NiFi 包含以下功能:
| Username | IoTDB 的用户名 | null | true |
| Password | IoTDB 的密码 | null | true |
| Record Writer | 指定一个 Record Writer controller service 来写入数据。 | null | true |
-| iotdb-query | 需要执行的IoTDB query <bbr>。 Note: 如果有连入侧的连接那么查询会从FlowFile的内容中提取,否则使用当前配置的属性 | null | false |
+| iotdb-query | 需要执行的IoTDB query <br>。 Note: 如果有连入侧的连接那么查询会从FlowFile的内容中提取,否则使用当前配置的属性 | null | false |
| iotdb-query-chunk-size | 返回的结果可以进行分块,数据流中会返回一批按设置大小切分的数据,而不是一个单一的响应. 分块查询可以返回无限量的行。 注意: 数据分块只有在设置不为0时启用 | 0 | false |
diff --git a/docs/zh/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md b/docs/zh/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md
index 44dc57341f..65a71e1331 100644
--- a/docs/zh/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md
+++ b/docs/zh/UserGuide/Ecosystem-Integration/Writing-Data-on-HDFS.md
@@ -29,7 +29,7 @@
当你配置使用 HDFS 存储 TSFile 之后,你的数据文件将会被分布式存储。系统架构如下:
-<img style="width:100%; max-width:700px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/66922722-35180400-f05a-11e9-8ff0-7dd51716e4a8.png">
+<img style="width:100%; max-width:700px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/66922722-35180400-f05a-11e9-8ff0-7dd51716e4a8.png">
#### Config and usage
diff --git a/docs/zh/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md b/docs/zh/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md
index b319cd2dd8..46a0fb015e 100644
--- a/docs/zh/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md
+++ b/docs/zh/UserGuide/Ecosystem-Integration/Zeppelin-IoTDB.md
@@ -25,7 +25,7 @@
Apache Zeppelin 是一个基于网页的交互式数据分析系统。用户可以通过 Zeppelin 连接数据源并使用 SQL、Scala 等进行交互式操作。操作可以保存为文档(类似于 Jupyter)。Zeppelin 支持多种数据源,包括 Spark、ElasticSearch、Cassandra 和 InfluxDB 等等。现在,IoTDB 已经支持使用 Zeppelin 进行操作。样例如下:
-
+
### Zeppelin-IoTDB 解释器
@@ -105,7 +105,7 @@ or
现在可以开始使用 Zeppelin 操作 IoTDB 了。
-
+
我们提供了一些简单的 SQL 来展示 Zeppelin-IoTDB 解释器的使用:
@@ -138,7 +138,7 @@ WHERE time >= 1
样例如下:
-
+
用户也可以参考 [[1]](https://zeppelin.apache.org/docs/0.9.0/usage/display_system/basic.html) 编写更丰富多彩的文档。
@@ -148,7 +148,7 @@ WHERE time >= 1
进入页面 [http://127.0.0.1:8080/#/interpreter](http://127.0.0.1:8080/#/interpreter) 并配置 IoTDB 的连接参数:
-
+
可配置参数默认值和解释如下:
diff --git a/docs/zh/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md b/docs/zh/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md
index 38e3977c6d..7b97d7cc23 100644
--- a/docs/zh/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md
+++ b/docs/zh/UserGuide/Edge-Cloud-Collaboration/Sync-Tool.md
@@ -31,7 +31,7 @@ IoTDB 同步工具内嵌于 IoTDB 引擎,与下游接收端相连,下游支
## 2.模型定义
-
+
TsFile 同步工具实现了数据从 "流入-> IoTDB ->流出" 的闭环。假设目前有两台机器A和B都安装了IoTDB,希望将 A 上的数据不断同步至 B 中。为了更好地描述这个过程,我们引入以下概念。
@@ -124,7 +124,7 @@ IoTDB> DROP PIPE my_pipe
- 显示当前所能支持的 PipeSink 类型。
-```Plain%20Text
+```
IoTDB> SHOW PIPESINKTYPE
IoTDB>
+-----+
@@ -170,7 +170,7 @@ IoTDB>
- 创建同步任务
- 其中 select 语句目前仅支持`**`(即所有序列中的数据),from 语句目前仅支持`root`,where语句仅支持指定 time 的起始时间。起始时间的指定形式可以是 yyyy-mm-dd HH:MM:SS或时间戳。
-```Plain%20Text
+```
IoTDB> CREATE PIPE my_pipe TO my_iotdb [FROM (select ** from root WHERE time>=yyyy-mm-dd HH:MM:SS)]
```
@@ -227,7 +227,7 @@ IoTDB> DROP PIPE <PipeName>
- ERROR 状态,这表明出现了网络连接正常但数据无法传输的问题,例如发送端 IP 不在接收端白名单中,或是发送端与接收端版本不兼容
- 当出现 ERROR 状态时,建议 STOP PIPE 后查看 DataNode 日志,检查接收端配置或网络情况后重新 START PIPE
-```Plain%20Text
+```
IoTDB> SHOW PIPES
IoTDB>
+-----------------------+--------+--------+-------------+---------+------------------------------------+-------+
@@ -287,7 +287,7 @@ IoTDB> CREATE PIPE p TO my_iotdb FROM (select ** from root where time>= 16485696
启动Pipe
-```Plain%20Text
+```
IoTDB> START PIPE p
```
@@ -301,7 +301,7 @@ IoTDB> SHOW PIPE p
在发送端执行以下 SQL
-```SQL
+```sql
CREATE DATABASE root.vehicle;
CREATE TIMESERIES root.vehicle.d0.s0 WITH DATATYPE=INT32, ENCODING=RLE;
CREATE TIMESERIES root.vehicle.d0.s1 WITH DATATYPE=TEXT, ENCODING=PLAIN;
@@ -318,7 +318,7 @@ flush;
在发送端和接受端执行查询,可查询到相同的结果
-```Plain%20Text
+```
IoTDB> select ** from root.vehicle
+-----------------------------+------------------+------------------+------------------+------------------+
| Time|root.vehicle.d0.s0|root.vehicle.d0.s1|root.vehicle.d1.s3|root.vehicle.d1.s2|
diff --git a/docs/zh/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md b/docs/zh/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md
index 21e94d6eeb..88a34222f6 100644
--- a/docs/zh/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md
+++ b/docs/zh/UserGuide/Integration-Test/Integration-Test-refactoring-tutorial.md
@@ -46,7 +46,7 @@ Apache IoTDB 集成测试的环境一共有3种,分别为**本地单机测试
#### 1. 集成测试类和注解
-构建的集成测试类时,开发者需要在 Apache IoTDB 的 [integration-test](https://github.com/apache/iotdb/tree/master/integration-test) 模块中创建测试类。类名应当能够精简准确地表述该集成测试的目的。除用于服务其他测试用例的类外,含集成测试用例用于测试 Apache IoTDB 功能的类,应当命名为“功能+IT”。例如,用于测试IoTDB自动注册元数据功能的集成测试命名为“<font color=green>IoTDBAutoCreateSchema</font><font color=red>IT</font>”。
+构建的集成测试类时,开发者需要在 Apache IoTDB 的 [integration-test](https://github.com/apache/iotdb/tree/master/integration-test) 模块中创建测试类。类名应当能够精简准确地表述该集成测试的目的。除用于服务其他测试用例的类外,含集成测试用例用于测试 Apache IoTDB 功能的类,应当命名为“功能+IT”。例如,用于测试IoTDB自动注册元数据功能的集成测试命名为“<span style="color:green">IoTDBAutoCreateSchema</span><span style="color:red">IT</span>”。
- Category 注解:**在构建集成测试类时,需要显式地通过引入```@Category```注明测试环境** ,测试环境用```LocalStandaloneIT.class```、```ClusterIT.class``` 和 ```RemoteIT.class```来表示,分别与“Apache IoTDB 集成测试的环境”中的本地单机测试环境、本地集群测试环境和远程测试环境对应。标签内是测试环境的集合,可以包含多个元素,表示在多种环境下分别测试。**一般情况下,标签```LocalStandaloneIT.class``` 和 ```ClusterIT.class``` 是必须添加的。** 当某些功能仅支持单机版 IoTDB 时可以只保留```LocalStandaloneIT.class```。
- RunWith 注解: 每一个集成测试类上都需要添加 ```@RunWith(IoTDBTestRunner.class)``` 标签。
@@ -99,7 +99,7 @@ public static void tearDown() throws Exception {
#### 3. 实现集成测试逻辑
-Apache IoTDB 的集成测试以黑盒测试的方式进行,测试方法的名称为“测试的功能点+Test”,例如“<font color=green>selectWithAlias</font><font color=red>Test</font>”。测试通过 JDBC 或 Session API 的接口来完成。
+Apache IoTDB 的集成测试以黑盒测试的方式进行,测试方法的名称为“测试的功能点+Test”,例如“<span style="color:green">selectWithAlias</span><span style="color:red">Test</span>”。测试通过 JDBC 或 Session API 的接口来完成。
1、使用JDBC接口
diff --git a/docs/zh/UserGuide/IoTDB-Introduction/Architecture.md b/docs/zh/UserGuide/IoTDB-Introduction/Architecture.md
index 3cca9ceb76..406908fc52 100644
--- a/docs/zh/UserGuide/IoTDB-Introduction/Architecture.md
+++ b/docs/zh/UserGuide/IoTDB-Introduction/Architecture.md
@@ -25,7 +25,7 @@ IoTDB 套件由若干个组件构成,共同形成“数据收集-数据写入-
如下图展示了使用 IoTDB 套件全部组件后形成的整体应用架构。下文称所有组件形成 IoTDB 套件,而 IoTDB 特指其中的时间序列数据库组件。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/IoTDB-Introduction/Architecture/Structure%20of%20Apache%20IoTDB%20cn.png?raw=true">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/IoTDB-Introduction/Architecture/Structure-of-Apache-IoTDB-cn.png?raw=true">
在上图中,用户可以通过 JDBC 将来自设备上传感器采集的时序数据、服务器负载和 CPU 内存等系统状态数据、消息队列中的时序数据、应用程序的时序数据或者其他数据库中的时序数据导入到本地或者远程的 IoTDB 中。用户还可以将上述数据直接写成本地(或位于 HDFS 上)的 TsFile 文件。
diff --git a/docs/zh/UserGuide/IoTDB-Introduction/Scenario.md b/docs/zh/UserGuide/IoTDB-Introduction/Scenario.md
index f6d5c23a4c..2eda6e8990 100644
--- a/docs/zh/UserGuide/IoTDB-Introduction/Scenario.md
+++ b/docs/zh/UserGuide/IoTDB-Introduction/Scenario.md
@@ -29,11 +29,11 @@
此时可以采用 IoTDB 套件中的 TsFile 组件、TsFileSync 工具和 Hadoop/Spark 集成组件对数据进行存储:每新印刷一个芯片,就在 SPI 设备上使用 SDK 写一条数据,这些数据最终形成一个 TsFile 文件。通过 TsFileSync 工具,生成的 TsFile 文件将按一定规则(如每天)被同步到 Hadoop 数据中心,并由数据分析人员对其进行分析。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579014-695ef980-1efa-11e9-8cbc-e9e7ee4fa0d8.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579014-695ef980-1efa-11e9-8cbc-e9e7ee4fa0d8.png">
在场景 1 中,仅需要 TsFile、TsFileSync 部署在一台 PC 上,此外还需要部署 Hadoop/Spark 连接器用于数据中心端 Hadoop/Spark 集群的数据存储和分析。其示意图如上图所示。下图展示了此时的应用架构。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/25913899/81768490-bf034f00-950d-11ea-9b56-fef3edca0958.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81768490-bf034f00-950d-11ea-9b56-fef3edca0958.png">
* 场景 2
@@ -43,11 +43,11 @@
此时可以采用 IoTDB 套件中的 IoTDB、TsFileSync 工具和 Hadoop/Spark 集成组件等。需要部署一个场控 PC 机,其上安装 IoTDB 和 TsFileSync 工具,用于支持读写数据、本地计算和分析以及上传数据到数据中心。此外还需要部署 Hadoop/Spark 连接器用于数据中心端 Hadoop/Spark 集群的数据存储和分析。如下图所示。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579033-7ed42380-1efa-11e9-889f-fb4180291a9e.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579033-7ed42380-1efa-11e9-889f-fb4180291a9e.png">
下图给出了此时的应用架构。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579064-8f849980-1efa-11e9-8cd6-a7339cd0540f.jpg">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579064-8f849980-1efa-11e9-8cd6-a7339cd0540f.jpg">
* 场景 3
@@ -57,11 +57,11 @@
此时,可以采用 IoTDB 套件中的 IoTDB、IoTDB-Client 工具、TsFileSync 工具和 Hadoop/Spark 集成组件等。将 IoTDB 服务器安装在工厂连接外网的服务器上,用户接收机械手传输的数据并将数据上传到数据中心。将 IoTDB-Client 工具安装在每一个连接工厂内网的机械手上,用于将传感器产生的实时数据上传到工厂内部服务器。再使用 TsFileSync 工具将原始数据上传到数据中心。此外还需要部署 Hadoop/Spark 连接器用于数据中心端 Hadoop/Spark 集群的数据存储和分析。如下图中间场景所示。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579080-96aba780-1efa-11e9-87ac-940c45b19dd7.jpg">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579080-96aba780-1efa-11e9-87ac-940c45b19dd7.jpg">
下图给出了此时的应用架构。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/25913899/81768477-b874d780-950d-11ea-80ca-8807b9bd0970.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81768477-b874d780-950d-11ea-80ca-8807b9bd0970.png">
* 场景 4
@@ -73,4 +73,4 @@
此外还需要部署 Hadoop/Spark 集群用于数据中心端的数据存储和分析。如下图所示。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51579095-a4f9c380-1efa-11e9-9f95-17165ec55568.jpg">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51579095-a4f9c380-1efa-11e9-9f95-17165ec55568.jpg">
diff --git a/docs/zh/UserGuide/Maintenance-Tools/JMX-Tool.md b/docs/zh/UserGuide/Maintenance-Tools/JMX-Tool.md
index b360f6e672..15d07801cf 100644
--- a/docs/zh/UserGuide/Maintenance-Tools/JMX-Tool.md
+++ b/docs/zh/UserGuide/Maintenance-Tools/JMX-Tool.md
@@ -49,11 +49,11 @@ JMX_IP="the_real_iotdb_server_ip" # 填写实际 IoTDB 的 IP 地址
1. 确保安装 jdk 8。jdk 8 以上需要 [下载 visualvm](https://visualvm.github.io/download.html)
2. 打开 jvisualvm
3. 在左侧导航栏空白处右键 -> 添加 JMX 连接
-<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/81462914-5738c580-91e8-11ea-94d1-4ff6607e7e2c.png">
+<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81462914-5738c580-91e8-11ea-94d1-4ff6607e7e2c.png">
4. 填写信息进行登录,按下图分别填写,注意需要勾选”不要求 SSL 连接”。
例如:
连接:192.168.130.15:31999
用户名:iotdb
口令:passw!d
-<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/81462909-53a53e80-91e8-11ea-98df-0012380da0b2.png">
+<img style="width:100%; max-width:300px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/81462909-53a53e80-91e8-11ea-98df-0012380da0b2.png">
diff --git a/docs/zh/UserGuide/Maintenance-Tools/Log-Tool.md b/docs/zh/UserGuide/Maintenance-Tools/Log-Tool.md
index 6da846968e..ca905e4f11 100644
--- a/docs/zh/UserGuide/Maintenance-Tools/Log-Tool.md
+++ b/docs/zh/UserGuide/Maintenance-Tools/Log-Tool.md
@@ -33,15 +33,15 @@ IoTDB 支持用户通过修改日志配置文件的方式对 IoTDB 系统日志
本节以 Jconsole 为例介绍连接 JMX 并进入动态系统日志配置模块的方法。启动 Jconsole 控制页面,在新建连接处建立与 IoTDB Server 的 JMX 连接(可以选择本地进程或给定 IoTDB 的 IP 及 PORT 进行远程连接,IoTDB 的 JMX 服务默认运行端口为 31999),如下图使用远程进程连接 Localhost 下运行在 31999 端口的 IoTDB JMX 服务。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51577195-f94d7500-1ef3-11e9-999a-b4f67055d80e.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51577195-f94d7500-1ef3-11e9-999a-b4f67055d80e.png">
连接到 JMX 后,您可以通过 MBean 选项卡找到名为`ch.qos.logback.classic`的`MBean`,如下图所示。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51577204-fe122900-1ef3-11e9-9e89-2eb1d46e24b8.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51577204-fe122900-1ef3-11e9-9e89-2eb1d46e24b8.png">
在`ch.qos.logback.classic`的 MBean 操作(Operations)选项中,可以看到当前动态系统日志配置支持的 6 种接口,您可以通过使用相应的方法,来执行相应的操作,操作页面如图。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/13203019/51577216-09fdeb00-1ef4-11e9-9005-542ad7d9e9e0.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/51577216-09fdeb00-1ef4-11e9-9005-542ad7d9e9e0.png">
#### 动态系统日志接口说明
diff --git a/docs/zh/UserGuide/Monitor-Alert/Alerting.md b/docs/zh/UserGuide/Monitor-Alert/Alerting.md
index 9aa5de937d..7bfd0c1053 100644
--- a/docs/zh/UserGuide/Monitor-Alert/Alerting.md
+++ b/docs/zh/UserGuide/Monitor-Alert/Alerting.md
@@ -367,4 +367,4 @@ INSERT INTO root.ln.wf01.wt01(timestamp, temperature) VALUES (5, 120);
会抑制 `severity` 为 `warning` 的告警,我们收到的告警邮件中只包含写入
`(5, 120)` 后触发的告警。
-<img alt="alerting" src="https://user-images.githubusercontent.com/34649843/115957896-a9791080-a537-11eb-9962-541412bdcee6.png">
+<img alt="alerting" src="/img/github/115957896-a9791080-a537-11eb-9962-541412bdcee6.png">
diff --git a/docs/zh/UserGuide/Monitor-Alert/Metric-Tool.md b/docs/zh/UserGuide/Monitor-Alert/Metric-Tool.md
index 939c622f01..c38350c4ef 100644
--- a/docs/zh/UserGuide/Monitor-Alert/Metric-Tool.md
+++ b/docs/zh/UserGuide/Monitor-Alert/Metric-Tool.md
@@ -320,18 +320,18 @@ Core 级别的监控指标在系统运行中默认开启,每一个 Core 级别
连接到 JMX 后,您可以通过 "MBeans" 标签找到名为 "org.apache.iotdb.metrics" 的 "MBean",可以在侧边栏中查看所有监控指标的具体值。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" alt="metric-jmx" src="https://user-images.githubusercontent.com/46039728/204018765-6fda9391-ebcf-4c80-98c5-26f34bd74df0.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" alt="metric-jmx" src="/img/github/204018765-6fda9391-ebcf-4c80-98c5-26f34bd74df0.png">
#### 5.1.2. 获取其他相关数据
连接到 JMX 后,您可以通过 "MBeans" 标签找到名为 "org.apache.iotdb.service" 的 "MBean",如下图所示,了解服务的基本状态
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/46039728/149951720-707f1ee8-32ee-4fde-9252-048caebd232e.png"> <br>
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/149951720-707f1ee8-32ee-4fde-9252-048caebd232e.png"> <br>
为了提高查询性能,IOTDB 对 ChunkMetaData 和 TsFileMetaData 进行了缓存。用户可以使用 MXBean
,展开侧边栏`org.apache.iotdb.db.service`查看缓存命中率:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/112426760-73e3da80-8d73-11eb-9a8f-9232d1f2033b.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/112426760-73e3da80-8d73-11eb-9a8f-9232d1f2033b.png">
### 5.2. 使用 Prometheus 方式
@@ -378,7 +378,7 @@ file_count{name="seq",} 2.0
IoTDB、Prometheus、Grafana三者的关系如下图所示:
-
+
1. IoTDB在运行过程中持续收集监控指标数据。
2. Prometheus以固定的间隔(可配置)从IoTDB的HTTP接口拉取监控指标数据。
@@ -417,7 +417,7 @@ static_configs:
我们提供了Apache IoTDB Dashboard,在Grafana中显示的效果图如下所示:
-
+
##### 5.2.4.1. 如何获取 Apache IoTDB Dashboard?
diff --git a/docs/zh/UserGuide/Operate-Metadata/Auto-Create-MetaData.md b/docs/zh/UserGuide/Operate-Metadata/Auto-Create-MetaData.md
index f83ba2b50c..a7d29f84b8 100644
--- a/docs/zh/UserGuide/Operate-Metadata/Auto-Create-MetaData.md
+++ b/docs/zh/UserGuide/Operate-Metadata/Auto-Create-MetaData.md
@@ -50,7 +50,7 @@
* 当 default_storage_group_level=2 时,将使用 root.turbine1.d1、root.turbine1.d2、root.turbine2.d1 和 root.turbine2.d2 作为 database。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Data%20Concept/Auto-Create-MetaData/auto_create_sg_example.png?raw=true" alt="auto create database example">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Data-Concept/Auto-Create-MetaData/auto_create_sg_example.png?raw=true" alt="auto create database example">
## 自动创建序列的元数据(前端指定数据类型)
diff --git a/docs/zh/UserGuide/Operate-Metadata/Node.md b/docs/zh/UserGuide/Operate-Metadata/Node.md
index dfc7d4edb7..e198f3fc6e 100644
--- a/docs/zh/UserGuide/Operate-Metadata/Node.md
+++ b/docs/zh/UserGuide/Operate-Metadata/Node.md
@@ -218,7 +218,7 @@ It costs 0.001s
## 统计设备数量
-* COUNT DEVICES <PathPattern>
+* COUNT DEVICES \<PathPattern\>
上述语句用于统计设备的数量,同时允许指定`PathPattern` 用于统计匹配该`PathPattern` 的设备数量
diff --git a/docs/zh/UserGuide/Operate-Metadata/Timeseries.md b/docs/zh/UserGuide/Operate-Metadata/Timeseries.md
index 6417c1f3d2..4e6f6d4a92 100644
--- a/docs/zh/UserGuide/Operate-Metadata/Timeseries.md
+++ b/docs/zh/UserGuide/Operate-Metadata/Timeseries.md
@@ -175,7 +175,7 @@ It costs 0.004s
那么 Metadata Tree 如下所示:
-<img style="width:100%; max-width:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/19167280/69792176-1718f400-1201-11ea-861a-1a83c07ca144.jpg">
+<img style="width:100%; max-width:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/69792176-1718f400-1201-11ea-861a-1a83c07ca144.jpg">
可以看到,`root`被定义为`LEVEL=0`。那么当你输入如下语句时:
diff --git a/docs/zh/UserGuide/Operators-Functions/Continuous-Interval.md b/docs/zh/UserGuide/Operators-Functions/Continuous-Interval.md
index 29cd01b8c5..c704a7e3ef 100644
--- a/docs/zh/UserGuide/Operators-Functions/Continuous-Interval.md
+++ b/docs/zh/UserGuide/Operators-Functions/Continuous-Interval.md
@@ -31,10 +31,10 @@
| 函数名 | 输入序列类型 | 属性参数 | 输出序列类型 | 功能描述 |
|-------------------|--------------------------------------|------------------------------------------------|-------|------------------------------------------------------------------|
-| ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` |
-| NON_ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` | |
-| ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
-| NON_ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
+| ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` |
+| NON_ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` | |
+| ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
+| NON_ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
测试数据:
```
diff --git a/docs/zh/UserGuide/Operators-Functions/Overview.md b/docs/zh/UserGuide/Operators-Functions/Overview.md
index bbcbf0fee1..cdd0842688 100644
--- a/docs/zh/UserGuide/Operators-Functions/Overview.md
+++ b/docs/zh/UserGuide/Operators-Functions/Overview.md
@@ -199,10 +199,10 @@ OR, |, ||
| 函数名 | 输入序列类型 | 属性参数 | 输出序列类型 | 功能描述 |
|-------------------|--------------------------------------|------------------------------------------------|-------|------------------------------------------------------------------|
-| ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` |
-| NON_ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` | |
-| ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
-| NON_ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1</br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
+| ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` |
+| NON_ZERO_DURATION | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值0<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与持续时间,持续时间t(单位ms)满足`t >= min && t <= max` | |
+| ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
+| NON_ZERO_COUNT | INT32/ INT64/ FLOAT/ DOUBLE/ BOOLEAN | `min`:可选,默认值1<br>`max`:可选,默认值`Long.MAX_VALUE` | Long | 返回时间序列连续不为0(false)的开始时间与其后数据点的个数,数据点个数n满足`n >= min && n <= max` | |
详细说明及示例见文档 [区间查询函数](./Continuous-Interval.md)。
@@ -223,9 +223,9 @@ OR, |, ||
| 函数名 | 可接收的输入序列类型 | 必要的属性参数 | 输出序列类型 | 功能类型 |
|----------|--------------------------------|---------------------------------------|------------|--------------------------------------------------|
| EQUAL_SIZE_BUCKET_RANDOM_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | 降采样比例 `proportion`,取值范围为`(0, 1]`,默认为`0.1` | INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例的等分桶随机采样 |
-| EQUAL_SIZE_BUCKET_AGG_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`</br>`type`:取值类型有`avg`, `max`, `min`, `sum`, `extreme`, `variance`, 默认为`avg` | INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例的等分桶聚合采样 |
+| EQUAL_SIZE_BUCKET_AGG_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`<br>`type`:取值类型有`avg`, `max`, `min`, `sum`, `extreme`, `variance`, 默认为`avg` | INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例的等分桶聚合采样 |
| EQUAL_SIZE_BUCKET_M4_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`| INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例的等分桶M4采样 |
-| EQUAL_SIZE_BUCKET_OUTLIER_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`</br>`type`取值为`avg`或`stendis`或`cos`或`prenextdis`,默认为`avg`</br>`number`取值应大于0,默认`3`| INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例和桶内采样个数的等分桶离群值采样 |
+| EQUAL_SIZE_BUCKET_OUTLIER_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`<br>`type`取值为`avg`或`stendis`或`cos`或`prenextdis`,默认为`avg`<br>`number`取值应大于0,默认`3`| INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例和桶内采样个数的等分桶离群值采样 |
| M4 | INT32 / INT64 / FLOAT / DOUBLE | 包含固定点数的窗口和滑动时间窗口使用不同的属性参数。包含固定点数的窗口使用属性`windowSize`和`slidingStep`。滑动时间窗口使用属性`timeInterval`、`slidingStep`、`displayWindowBegin`和`displayWindowEnd`。更多细节见下文。 | INT32 / INT64 / FLOAT / DOUBLE | 返回每个窗口内的第一个点(`first`)、最后一个点(`last`)、最小值点(`bottom`)、最大值点(`top`)。在一个窗口内的聚合点输出之前,M4会将它们按照时间戳递增排序并且去重。 |
## 数据质量函数库
diff --git a/docs/zh/UserGuide/Operators-Functions/Sample.md b/docs/zh/UserGuide/Operators-Functions/Sample.md
index 9c18f989f4..0680de753c 100644
--- a/docs/zh/UserGuide/Operators-Functions/Sample.md
+++ b/docs/zh/UserGuide/Operators-Functions/Sample.md
@@ -107,7 +107,7 @@ It costs 0.024s
| 函数名 | 可接收的输入序列类型 | 必要的属性参数 | 输出序列类型 | 功能类型 |
|----------|--------------------------------|---------------------------------------|------------|--------------------------------------------------|
-| EQUAL_SIZE_BUCKET_AGG_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`</br>`type`:取值类型有`avg`, `max`, `min`, `sum`, `extreme`, `variance`, 默认为`avg` | INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例的等分桶聚合采样 |
+| EQUAL_SIZE_BUCKET_AGG_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`<br>`type`:取值类型有`avg`, `max`, `min`, `sum`, `extreme`, `variance`, 默认为`avg` | INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例的等分桶聚合采样 |
#### 使用示例
@@ -185,7 +185,7 @@ It costs 0.065s
| 函数名 | 可接收的输入序列类型 | 必要的属性参数 | 输出序列类型 | 功能类型 |
|----------|--------------------------------|---------------------------------------|------------|--------------------------------------------------|
-| EQUAL_SIZE_BUCKET_OUTLIER_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`</br>`type`取值为`avg`或`stendis`或`cos`或`prenextdis`,默认为`avg`</br>`number`取值应大于0,默认`3`| INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例和桶内采样个数的等分桶离群值采样 |
+| EQUAL_SIZE_BUCKET_OUTLIER_SAMPLE | INT32 / INT64 / FLOAT / DOUBLE | `proportion`取值范围为`(0, 1]`,默认为`0.1`<br>`type`取值为`avg`或`stendis`或`cos`或`prenextdis`,默认为`avg`<br>`number`取值应大于0,默认`3`| INT32 / INT64 / FLOAT / DOUBLE | 返回符合采样比例和桶内采样个数的等分桶离群值采样 |
参数说明
- `proportion`: 采样比例
@@ -267,7 +267,7 @@ M4用于在窗口内采样第一个点(`first`)、最后一个点(`last`
- 最小值点是拥有这个窗口内最小值的点(如果有多个这样的点,M4只返回其中一个);
- 最大值点是拥有这个窗口内最大值的点(如果有多个这样的点,M4只返回其中一个)。
-<img src="https://user-images.githubusercontent.com/33376433/198178733-a0919d17-0663-4672-9c4f-1efad6f463c2.png" alt="image" style="zoom:50%;" />
+<img src="/img/github/198178733-a0919d17-0663-4672-9c4f-1efad6f463c2.png" alt="image" style="zoom:50%;" />
| 函数名 | 可接收的输入序列类型 | 属性参数 | 输出序列类型 | 功能类型 |
| ------ | ------------------------------ | ------------------------------------------------------------ | ------------------------------ | ------------------------------------------------------------ |
@@ -280,7 +280,7 @@ M4用于在窗口内采样第一个点(`first`)、最后一个点(`last`
+ `windowSize`: 一个窗口内的点数。Int数据类型。必需的属性参数。
+ `slidingStep`: 按照设定的点数来滑动窗口。Int数据类型。可选的属性参数;如果没有设置,默认取值和`windowSize`一样。
-<img src="https://user-images.githubusercontent.com/33376433/198181449-00d563c8-7bce-4ecd-a031-ec120ca42c3f.png" alt="image" style="zoom: 50%;" />
+<img src="/img/github/198181449-00d563c8-7bce-4ecd-a031-ec120ca42c3f.png" alt="image" style="zoom: 50%;" />
*(图片来源: https://iotdb.apache.org/UserGuide/Master/Process-Data/UDF-User-Defined-Function.html#udtf-user-defined-timeseries-generating-function)*
@@ -291,7 +291,7 @@ M4用于在窗口内采样第一个点(`first`)、最后一个点(`last`
+ `displayWindowBegin`: 窗口滑动的起始时间戳位置(包含在内)。Long数据类型。可选的属性参数;如果没有设置,默认取值为Long.MIN_VALUE,意为使用输入的时间序列的第一个点的时间戳作为窗口滑动的起始时间戳位置。
+ `displayWindowEnd`: 结束时间限制(不包含在内;本质上和`WHERE time < displayWindowEnd`起的效果是一样的)。Long数据类型。可选的属性参数;如果没有设置,默认取值为Long.MAX_VALUE,意为除了输入的时间序列自身数据读取完毕之外没有增加额外的结束时间过滤条件限制。
-<img src="https://user-images.githubusercontent.com/33376433/198183015-93b56644-3330-4acf-ae9e-d718a02b5f4c.png" alt="groupBy window" style="zoom: 67%;" />
+<img src="/img/github/198183015-93b56644-3330-4acf-ae9e-d718a02b5f4c.png" alt="groupBy window" style="zoom: 67%;" />
*(图片来源: https://iotdb.apache.org/UserGuide/Master/Query-Data/Aggregate-Query.html#downsampling-aggregate-query)*
diff --git a/docs/zh/UserGuide/Operators-Functions/User-Defined-Function.md b/docs/zh/UserGuide/Operators-Functions/User-Defined-Function.md
index 1347874778..2717362325 100644
--- a/docs/zh/UserGuide/Operators-Functions/User-Defined-Function.md
+++ b/docs/zh/UserGuide/Operators-Functions/User-Defined-Function.md
@@ -152,7 +152,7 @@ void beforeStart(UDFParameters parameters, UDTFConfigurations configurations) th
`RowByRowAccessStrategy`的构造不需要任何参数。
如图是`SlidingTimeWindowAccessStrategy`的开窗示意图。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/timeWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/timeWindow.png">
`SlidingTimeWindowAccessStrategy`有多种构造方法,您可以向构造方法提供 3 类参数:
@@ -166,12 +166,12 @@ void beforeStart(UDFParameters parameters, UDTFConfigurations configurations) th
3 类参数的关系可见下图。策略的构造方法详见 Javadoc。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/30497621/99787878-47b51480-2b5b-11eb-8ed3-84088c5c30f7.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/99787878-47b51480-2b5b-11eb-8ed3-84088c5c30f7.png">
注意,最后的一些时间窗口的实际时间间隔可能小于规定的时间间隔参数。另外,可能存在某些时间窗口内数据行数量为 0 的情况,这种情况框架也会为该窗口调用一次`transform`方法。
如图是`SlidingSizeWindowAccessStrategy`的开窗示意图。
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/countWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/countWindow.png">
`SlidingSizeWindowAccessStrategy`有多种构造方法,您可以向构造方法提供 2 个参数:
@@ -181,7 +181,7 @@ void beforeStart(UDFParameters parameters, UDTFConfigurations configurations) th
滑动步长参数不是必须的。当您不提供滑动步长参数时,滑动步长会被设定为窗口大小。
如图是`SessionTimeWindowAccessStrategy`的开窗示意图。**时间间隔小于等于给定的最小时间间隔 sessionGap 则分为一组。**
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/sessionWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/sessionWindow.png">
`SessionTimeWindowAccessStrategy`有多种构造方法,您可以向构造方法提供 2 类参数:
1. 时间轴显示时间窗开始和结束时间。
@@ -189,7 +189,7 @@ void beforeStart(UDFParameters parameters, UDTFConfigurations configurations) th
如图是`StateWindowAccessStrategy`的开窗示意图。**对于数值型数据,状态差值小于等于给定的阈值 delta 则分为一组。**
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://raw.githubusercontent.com/apache/iotdb-bin-resources/main/docs/UserGuide/Process-Data/UDF-User-Defined-Function/stateWindow.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/UserGuide/Process-Data/UDF-User-Defined-Function/stateWindow.png">
`StateWindowAccessStrategy`有四种构造方法。
1. 针对数值型数据,可以提供时间轴显示时间窗开始和结束时间以及对于单个窗口内部允许变化的阈值delta。
diff --git a/docs/zh/UserGuide/Query-Data/Continuous-Query.md b/docs/zh/UserGuide/Query-Data/Continuous-Query.md
index a9101fde7d..59e4f199fc 100644
--- a/docs/zh/UserGuide/Query-Data/Continuous-Query.md
+++ b/docs/zh/UserGuide/Query-Data/Continuous-Query.md
@@ -76,19 +76,19 @@ END
#### `<start_time_offset>`等于`<every_interval>`
-
+
#### `<start_time_offset>`大于`<every_interval>`
-
+
#### `<start_time_offset>`小于`<every_interval>`
-
+
#### `<every_interval>`不为0
-
+
- `TIMEOUT POLICY` 指定了我们如何处理“前一个时间窗口还未执行完时,下一个窗口的执行时间已经到达的场景,默认值是`BLOCKED`.
- `BLOCKED`意味着即使下一个窗口的执行时间已经到达,我们依旧需要阻塞等待前一个时间窗口的查询执行完再开始执行下一个窗口。如果使用`BLOCKED`策略,所有的时间窗口都将会被依此执行,但是如果遇到执行查询的时间长于周期性间隔时,连续查询的结果会迟于最新的时间窗口范围。
diff --git a/docs/zh/UserGuide/Query-Data/Group-By.md b/docs/zh/UserGuide/Query-Data/Group-By.md
index 2061098553..507bbf4e3f 100644
--- a/docs/zh/UserGuide/Query-Data/Group-By.md
+++ b/docs/zh/UserGuide/Query-Data/Group-By.md
@@ -33,7 +33,7 @@
下图中指出了这三个参数的含义:
-<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="https://user-images.githubusercontent.com/16079446/69109512-f808bc80-0ab2-11ea-9e4d-b2b2f58fb474.png">
+<img style="width:100%; max-width:800px; max-height:600px; margin-left:auto; margin-right:auto; display:block;" src="/img/github/69109512-f808bc80-0ab2-11ea-9e4d-b2b2f58fb474.png">
接下来,我们给出几个典型例子:
@@ -416,7 +416,7 @@ IoTDB 支持通过 `GROUP BY TAGS` 语句根据时间序列中定义的标签的
其中,设备 `d1`、`d2` 在 `Beijing` 的 `w1` 车间, `d3`、`d4` 在 `Beijing` 的 `w2` 车间,`d5`、`d6` 在 `Shanghai` 的 `w1` 车间,`d7` 在 `Shanghai` 的 `w2` 车间。
`d8` 和 `d9` 设备目前处于调试阶段,还未被分配到具体的城市和车间,所以其相应的标签值为空值。
-```SQL
+```sql
create database root.factory1;
create timeseries root.factory1.d1.temperature with datatype=FLOAT tags(city=Beijing, workshop=w1);
create timeseries root.factory1.d2.temperature with datatype=FLOAT tags(city=Beijing, workshop=w1);
@@ -473,7 +473,7 @@ insert into root.factory1.d9(time, temperature) values(3000, 52.1);
用户想统计该工厂每个地区的设备的温度的平均值,可以使用如下查询语句
-```SQL
+```sql
SELECT AVG(temperature) FROM root.factory1.** GROUP BY TAGS(city);
```
@@ -504,7 +504,7 @@ It costs 0.231s
SQL 语句如下
-```SQL
+```sql
SELECT avg(temperature) FROM root.factory1.** GROUP BY TAGS(city, workshop);
```
@@ -534,7 +534,7 @@ It costs 0.027s
SQL 语句如下
-```SQL
+```sql
SELECT AVG(temperature) FROM root.factory1.** GROUP BY ([1000, 10000), 5s), TAGS(city, workshop);
```
diff --git a/docs/zh/UserGuide/QuickStart/Command-Line-Interface.md b/docs/zh/UserGuide/QuickStart/Command-Line-Interface.md
index 07c386ff15..d5c1dfb80a 100644
--- a/docs/zh/UserGuide/QuickStart/Command-Line-Interface.md
+++ b/docs/zh/UserGuide/QuickStart/Command-Line-Interface.md
@@ -38,7 +38,7 @@ IOTDB 为用户提供 cli/Shell 工具用于启动客户端和服务端程序。
## 运行
### Cli 运行方式
-安装后的 IoTDB 中有一个默认用户:`root`,默认密码为`root`。用户可以使用该用户尝试运行 IoTDB 客户端以测试服务器是否正常启动。客户端启动脚本为$IOTDB_HOME/sbin 文件夹下的`start-cli`脚本。启动脚本时需要指定运行 IP 和 RPC PORT。以下为服务器在本机启动,且用户未更改运行端口号的示例,默认端口为 6667。若用户尝试连接远程服务器或更改了服务器运行的端口号,请在-h 和-p 项处使用服务器的 IP 和 RPC PORT。</br>
+安装后的 IoTDB 中有一个默认用户:`root`,默认密码为`root`。用户可以使用该用户尝试运行 IoTDB 客户端以测试服务器是否正常启动。客户端启动脚本为$IOTDB_HOME/sbin 文件夹下的`start-cli`脚本。启动脚本时需要指定运行 IP 和 RPC PORT。以下为服务器在本机启动,且用户未更改运行端口号的示例,默认端口为 6667。若用户尝试连接远程服务器或更改了服务器运行的端口号,请在-h 和-p 项处使用服务器的 IP 和 RPC PORT。<br>
用户也可以在启动脚本的最前方设置自己的环境变量,如 JAVA_HOME 等 (对于 linux 用户,脚本路径为:"/sbin/start-cli.sh"; 对于 windows 用户,脚本路径为:"/sbin/start-cli.bat")
Linux 系统与 MacOS 系统启动命令如下:
@@ -132,49 +132,49 @@ Shell > bash ./standalone.sh
```
2、使用 https://ip:port/auth 登陆 keycloack, 首次登陆需要创建用户
-
+
3、点击 Administration Console 进入管理端
-
+
4、在左侧的 Master 菜单点击 add Realm, 输入 Name 创建一个新的 Realm
-
+
-
+
5、点击左侧菜单 Clients,创建 client
-
+
6、点击左侧菜单 User,创建 user
-
+
7、点击新创建的用户 id,点击 Credentials 导航输入密码和关闭 Temporary 选项,至此 keyclork 配置完成
-
+
8、创建角色,点击左侧菜单的 Roles然后点击Add Role 按钮添加角色
-
+
9、在Role Name 中输入`iotdb_admin`,点击save 按钮。提示:这里的`iotdb_admin`不能为其他名称否则即使登陆成功后也将无权限使用iotdb的查询、插入、创建 database、添加用户、角色等功能
-
+
10、点击左侧的User 菜单然后点击用户列表中的Edit的按钮为该用户添加我们刚创建的`iotdb_admin`角色
-
+
11、选择Role Mappings ,在Available Role选择`iotdb_admin`角色然后点Add selected 按钮添加角色
-
+
12、如果`iotdb_admin`角色在Assigned Roles中并且出现`Success Role mappings updated`提示,证明角色添加成功
-
+
提示:如果用户角色有调整需要重新生成token并且重新登陆iotdb才会生效
diff --git a/docs/zh/UserGuide/QuickStart/QuickStart.md b/docs/zh/UserGuide/QuickStart/QuickStart.md
index 5c550ecad1..373580695f 100644
--- a/docs/zh/UserGuide/QuickStart/QuickStart.md
+++ b/docs/zh/UserGuide/QuickStart/QuickStart.md
@@ -37,7 +37,7 @@ IoTDB 支持多种安装途径。用户可以使用三种方式对 IoTDB 进行
* 二进制可运行程序:请从 [下载](https://iotdb.apache.org/Download/) 页面下载最新的安装包,解压后即完成安装。
-* 使用 Docker 镜像:dockerfile 文件位于 https://github.com/apache/iotdb/blob/master/docker/src/main
+* 使用 Docker 镜像:dockerfile 文件位于 [github](https://github.com/apache/iotdb/blob/master/docker/src/main)
## 软件目录结构
diff --git a/docs/zh/UserGuide/Reference/SQL-Reference.md b/docs/zh/UserGuide/Reference/SQL-Reference.md
index aaff8ee919..8e52cbc9bf 100644
--- a/docs/zh/UserGuide/Reference/SQL-Reference.md
+++ b/docs/zh/UserGuide/Reference/SQL-Reference.md
@@ -1197,7 +1197,7 @@ Note: DateTime Type can support several types, see Chapter 3 Datetime section fo
```
PrecedenceEqualOperator : EQUAL | NOTEQUAL | LESSTHANOREQUALTO | LESSTHAN | GREATERTHANOREQUALTO | GREATERTHAN
```
-Timeseries : ROOT [DOT <LayerName>]* DOT <SensorName>
+Timeseries : ROOT [DOT \<LayerName\>]* DOT \<SensorName\>
LayerName : Identifier
SensorName : Identifier
eg. root.ln.wf01.wt01.status
@@ -1206,7 +1206,7 @@ Note: Timeseries must be start with `root`(case insensitive) and end with sensor
```
```
-PrefixPath : ROOT (DOT <LayerName>)*
+PrefixPath : ROOT (DOT \<LayerName\>)*
LayerName : Identifier | STAR
eg. root.sgcc
eg. root.*
diff --git a/docs/zh/UserGuide/Reference/TSDB-Comparison.md b/docs/zh/UserGuide/Reference/TSDB-Comparison.md
index 6bee5662f4..2520ead848 100644
--- a/docs/zh/UserGuide/Reference/TSDB-Comparison.md
+++ b/docs/zh/UserGuide/Reference/TSDB-Comparison.md
@@ -23,7 +23,7 @@
## Overview
-
+
**表格外观启发自 [Andriy Zabavskyy: How to Select Time Series DB](https://towardsdatascience.com/how-to-select-time-series-db-123b0eb4ab82)*
@@ -282,7 +282,7 @@ IoTDB 拥有许多其它时间序列数据库不支持的强大功能。
写入吞吐率(points/second)如下图所示:
-<img src="https://user-images.githubusercontent.com/24886743/106254214-6cacbe80-6253-11eb-8532-d6a1829f8f66.png" alt="Batch Size with Write Throughput (points/second)" />
+<img src="/img/github/106254214-6cacbe80-6253-11eb-8532-d6a1829f8f66.png" alt="Batch Size with Write Throughput (points/second)" />
<center>Figure 1. Batch Size with Write throughput (points/second) IoTDB v0.11.1</center>
@@ -292,7 +292,7 @@ client num 从 1 到 50 变化。IoTDB 使用 batch insertion API,batch size
写入吞吐率(points/second)如下图所示:
-
+
<center>Figure 3. Client Num with Write Throughput (points/second) IoTDB v0.11.1</center>
@@ -306,19 +306,19 @@ client num 从 1 到 50 变化。IoTDB 使用 batch insertion API,batch size
测试结果如下图所示:
-
+
<center>Figure 4. Raw data query 1 col time cost(ms) IoTDB v0.11.1</center>
-
+
<center>Figure 5. Aggregation query time cost(ms) IoTDB v0.11.1</center>
-
+
<center>Figure 6. Downsampling query time cost(ms) IoTDB v0.11.1</center>
-
+
<center>Figure 7. Latest query time cost(ms) IoTDB v0.11.1</center>
diff --git a/docs/zh/UserGuide/Syntax-Conventions/Identifier.md b/docs/zh/UserGuide/Syntax-Conventions/Identifier.md
index 59f036454b..8bf400f4e6 100644
--- a/docs/zh/UserGuide/Syntax-Conventions/Identifier.md
+++ b/docs/zh/UserGuide/Syntax-Conventions/Identifier.md
@@ -52,7 +52,7 @@
**在用反引号引用的标识符中,可以通过双写反引号的方式使用反引号,即 ` 可以表示为 ``**,示例如下:
-```SQL
+```sql
# 创建模板 t1`t
create schema template `t1``t`
(temperature FLOAT encoding=RLE, status BOOLEAN encoding=PLAIN compression=SNAPPY)
diff --git a/docs/zh/UserGuide/Syntax-Conventions/KeyValue-Pair.md b/docs/zh/UserGuide/Syntax-Conventions/KeyValue-Pair.md
index 604bd76ed1..ccdf533fc3 100644
--- a/docs/zh/UserGuide/Syntax-Conventions/KeyValue-Pair.md
+++ b/docs/zh/UserGuide/Syntax-Conventions/KeyValue-Pair.md
@@ -27,7 +27,7 @@
- 触发器中表示触发器属性的键值对。参考示例语句中 WITH 后的属性键值对。
-```SQL
+```sql
# 以字符串形式表示键值对
CREATE TRIGGER `alert-listener-sg1d1s1`
AFTER INSERT
@@ -109,7 +109,7 @@ SHOW timeseries root.ln.** WHRER unit = c
- 创建 Pipe 以及 PipeSink 时表示属性的键值对。
-```SQL
+```sql
# 创建 PipeSink 时表示属性
CREATE PIPESINK my_iotdb AS IoTDB ('ip' = '输入你的IP')
diff --git a/docs/zh/UserGuide/Syntax-Conventions/Literal-Values.md b/docs/zh/UserGuide/Syntax-Conventions/Literal-Values.md
index f620f1788b..ace6258e78 100644
--- a/docs/zh/UserGuide/Syntax-Conventions/Literal-Values.md
+++ b/docs/zh/UserGuide/Syntax-Conventions/Literal-Values.md
@@ -27,7 +27,7 @@
在 IoTDB 中,字符串是由**单引号(`'`)或双引号(`"`)字符括起来的字符序列**。示例如下:
-```Plain%20Text
+```
'a string'
"another string"
```
@@ -36,7 +36,7 @@
- `INSERT` 或者 `SELECT` 中用于表达 `TEXT` 类型数据的场景。
- ```SQL
+ ```sql
# insert 示例
insert into root.ln.wf02.wt02(timestamp,hardware) values(1, 'v1')
insert into root.ln.wf02.wt02(timestamp,hardware) values(2, '\\')
@@ -55,7 +55,7 @@
- `LOAD` / `REMOVE` / `SETTLE` 指令中的文件路径。
- ```SQL
+ ```sql
# load 示例
LOAD 'examplePath'
@@ -68,14 +68,14 @@
- 用户密码。
- ```SQL
+ ```sql
# 示例,write_pwd 即为用户密码
CREATE USER ln_write_user 'write_pwd'
```
- 触发器和 UDF 中的类全类名,示例如下:
- ```SQL
+ ```sql
# 触发器示例,AS 后使用字符串表示类全类名
CREATE TRIGGER `alert-listener-sg1d1s1`
AFTER INSERT
@@ -92,7 +92,7 @@
- Select 子句中可以为结果集中的值指定别名,别名可以被定义为字符串或者标识符,示例如下:
- ```SQL
+ ```sql
select s1 as 'temperature', s2 as 'speed' from root.ln.wf01.wt01;
# 表头如下所示
@@ -111,7 +111,7 @@
字符串内使用引号的示例如下:
-```Plain%20Text
+```
'string' // string
'"string"' // "string"
'""string""' // ""string""
diff --git a/docs/zh/UserGuide/Syntax-Conventions/NodeName-In-Path.md b/docs/zh/UserGuide/Syntax-Conventions/NodeName-In-Path.md
index 2b03d056a4..232476f031 100644
--- a/docs/zh/UserGuide/Syntax-Conventions/NodeName-In-Path.md
+++ b/docs/zh/UserGuide/Syntax-Conventions/NodeName-In-Path.md
@@ -31,7 +31,7 @@
由于通配符 * 在查询表达式中也可以表示乘法符号,下述例子用于帮助您区分两种情况:
-```SQL
+```sql
# 创建时间序列 root.sg.`a*b`
create timeseries root.sg.`a*b` with datatype=FLOAT,encoding=PLAIN;
# 请注意,如标识符部分所述,a*b包含特殊字符,需要用``括起来使用
@@ -62,7 +62,7 @@ select a*b from root.sg
- 创建时间序列时,如下情况需要使用反引号对特殊节点名进行引用:
-```SQL
+```sql
# 路径结点名中包含特殊字符,时间序列各结点为["root","sg","www.`baidu.com"]
create timeseries root.sg.`www.``baidu.com`.a with datatype=FLOAT,encoding=PLAIN;
@@ -72,7 +72,7 @@ create timeseries root.sg.`111` with datatype=FLOAT,encoding=PLAIN;
依次执行示例中语句后,执行 show timeseries,结果如下:
-```SQL
+```sql
+---------------------------+-----+-------------+--------+--------+-----------+----+----------+
| timeseries|alias|database|dataType|encoding|compression|tags|attributes|
+---------------------------+-----+-------------+--------+--------+-----------+----+----------+
@@ -83,7 +83,7 @@ create timeseries root.sg.`111` with datatype=FLOAT,encoding=PLAIN;
- 插入数据时,如下情况需要使用反引号对特殊节点名进行引用:
-```SQL
+```sql
# 路径结点名中包含特殊字符
insert into root.sg.`www.``baidu.com`(timestamp, a) values(1, 2);
@@ -93,7 +93,7 @@ insert into root.sg(timestamp, `111`) values (1, 2);
- 查询数据时,如下情况需要使用反引号对特殊节点名进行引用:
-```SQL
+```sql
# 路径结点名中包含特殊字符
select a from root.sg.`www.``baidu.com`;
@@ -103,7 +103,7 @@ select `111` from root.sg
结果集分别为:
-```SQL
+```sql
# select a from root.sg.`www.``baidu.com` 结果集
+-----------------------------+---------------------------+
| Time|root.sg.`www.``baidu.com`.a|
diff --git a/docs/zh/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md b/docs/zh/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md
index cfecc02831..7f1a69cf50 100644
--- a/docs/zh/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md
+++ b/docs/zh/UserGuide/Syntax-Conventions/Session-And-TsFile-API.md
@@ -25,7 +25,7 @@
1. 以创建时间序列 createTimeseries 为例:
-```Java
+```java
public void createTimeseries(
String path,
TSDataType dataType,
@@ -36,7 +36,7 @@ public void createTimeseries(
如果您希望创建时间序列 root.sg.a,root.sg.\`a.\`\`"b\`,root.sg.\`111\`,您使用的 SQL 语句应该如下所示:
-```SQL
+```sql
create timeseries root.sg.a with datatype=FLOAT,encoding=PLAIN,compressor=SNAPPY;
# 路径结点名中包含特殊字符,时间序列各结点为["root","sg","a.`\"b"]
@@ -48,7 +48,7 @@ create timeseries root.sg.`111` with datatype=FLOAT,encoding=PLAIN,compressor=SN
您在调用 createTimeseries 方法时,应该按照如下方法赋值 path 字符串,保证 path 字符串内容与使用 SQL 时一致:
-```Java
+```java
// 时间序列 root.sg.a
String path = "root.sg.a";
@@ -61,7 +61,7 @@ String path = "root.sg.`111`";
2. 以插入数据 insertRecord 为例:
-```Java
+```java
public void insertRecord(
String deviceId,
long time,
@@ -73,13 +73,13 @@ public void insertRecord(
如果您希望向时间序列 root.sg.a,root.sg.\`a.\`\`"b\`,root.sg.\`111\`中插入数据,您使用的 SQL 语句应该如下所示:
-```SQL
+```sql
insert into root.sg(timestamp, a, `a.``"b`, `111`) values (1, 2, 2, 2);
```
您在调用 insertRecord 方法时,应该按照如下方法赋值 deviceId 和 measurements:
-```Java
+```java
// deviceId 为 root.sg
String deviceId = "root.sg";
@@ -90,7 +90,7 @@ List<String> measurementList = Arrays.asList(measurements);
3. 以查询数据 executeRawDataQuery 为例:
-```Java
+```java
public SessionDataSet executeRawDataQuery(
List<String> paths,
long startTime,
@@ -100,7 +100,7 @@ public SessionDataSet executeRawDataQuery(
如果您希望查询时间序列 root.sg.a,root.sg.\`a.\`\`"b\`,root.sg.\`111\`的数据,您使用的 SQL 语句应该如下所示:
-```SQL
+```sql
select a from root.sg
# 路径结点名中包含特殊字符
@@ -112,7 +112,7 @@ select `111` from root.sg
您在调用 executeRawDataQuery 方法时,应该按照如下方法赋值 paths:
-```Java
+```java
// paths
String[] paths = new String[]{"root.sg.a", "root.sg.`a.``\"b`", "root.sg.`111`"};
List<String> pathList = Arrays.asList(paths);
diff --git a/docs/zh/UserGuide/Trigger/Implement-Trigger.md b/docs/zh/UserGuide/Trigger/Implement-Trigger.md
index 4d1f6ab1f7..4ed2648b90 100644
--- a/docs/zh/UserGuide/Trigger/Implement-Trigger.md
+++ b/docs/zh/UserGuide/Trigger/Implement-Trigger.md
@@ -183,9 +183,9 @@ insert into root.sg(time, a, b) values (1, 1, 1);
您可以参考下图辅助理解,其中 Trigger1 配置采用乐观策略,Trigger2 配置采用悲观策略。Trigger1 和 Trigger2 的触发时机是 BEFORE INSERT,Trigger3 和 Trigger4 的触发时机是 AFTER INSERT。 正常执行流程如下:
-<img src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Process-Data/Triggers/Trigger_Process_Flow.jpg?raw=true">
+<img src="/img/UserGuide/Process-Data/Triggers/Trigger_Process_Flow.jpg?raw=true">
-<img src="https://github.com/apache/iotdb-bin-resources/blob/main/docs/UserGuide/Process-Data/Triggers/Trigger_Process_Strategy.jpg?raw=true">
+<img src="/img/UserGuide/Process-Data/Triggers/Trigger_Process_Strategy.jpg?raw=true">
## 示例
diff --git a/docs/zh/UserGuide/UserGuideReadme.md b/docs/zh/UserGuide/UserGuideReadme.md
index 5282fe926d..739e32ae41 100644
--- a/docs/zh/UserGuide/UserGuideReadme.md
+++ b/docs/zh/UserGuide/UserGuideReadme.md
@@ -25,7 +25,6 @@
"In Progress Version" 用于匹配 IOTDB 源代码存储库的 master 分支。
其他文档用于匹配 IoTDB 发布的版本。
-- [In progress version](https://iotdb.apache.org/UserGuide/Master/Get%20Started/QuickStart.html)
-- [Version 0.10.x](https://iotdb.apache.org/UserGuide/V0.10.x/Get%20Started/QuickStart.html)
-- [Version 0.9.x](https://iotdb.apache.org/UserGuide/V0.9.x/0-Get%20Started/1-QuickStart.html)
-- [Version 0.8.x](https://iotdb.apache.org/UserGuide/V0.8.x/0-Get%20Started/1-QuickStart.html)
+- [In progress version](https://iotdb.apache.org/UserGuide/Master/QuickStart/QuickStart.html)
+- [Version 1.0.x](https://iotdb.apache.org/UserGuide/V1.0.x/QuickStart/QuickStart.html)
+- [Version 0.13.x](https://iotdb.apache.org/UserGuide/V0.13.x/QuickStart/QuickStart.html)