You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@dolphinscheduler.apache.org by zh...@apache.org on 2022/10/31 12:36:56 UTC
[dolphinscheduler-website] branch master updated: Add Blog News (#836)
This is an automated email from the ASF dual-hosted git repository.
zhongjiajie pushed a commit to branch master
in repository https://gitbox.apache.org/repos/asf/dolphinscheduler-website.git
The following commit(s) were added to refs/heads/master by this push:
new d5ee1624d3 Add Blog News (#836)
d5ee1624d3 is described below
commit d5ee1624d3bb21aaa906040fbdd66bffad476509
Author: lifeng <53...@users.noreply.github.com>
AuthorDate: Mon Oct 31 20:36:50 2022 +0800
Add Blog News (#836)
* Add Blog News
* Update How_did_Yili_explore_a_path_for_digital_transformation_based_on_DolphinScheduler.md
Co-authored-by: Jiajie Zhong <zh...@gmail.com>
---
blog/en-us/Apache_DolphinScheduler_2.0.7.md | 60 ++++++
.../How_can_more_people_benefit_from_big_data.md | 210 +++++++++++++++++++++
...tal_transformation_based_on_DolphinScheduler.md | 137 ++++++++++++++
site_config/blog.js | 21 +++
site_config/home.jsx | 15 +-
5 files changed, 435 insertions(+), 8 deletions(-)
diff --git a/blog/en-us/Apache_DolphinScheduler_2.0.7.md b/blog/en-us/Apache_DolphinScheduler_2.0.7.md
new file mode 100644
index 0000000000..bbfb2e68af
--- /dev/null
+++ b/blog/en-us/Apache_DolphinScheduler_2.0.7.md
@@ -0,0 +1,60 @@
+---
+title:# Apache DolphinScheduler 2.0.7 released, fixes complement and fault tolerance
+keywords: Apache,DolphinScheduler,scheduler,big data,ETL,airflow,hadoop,orchestration,dataops,Meetup
+description: Recently, Apache DolphinScheduler version 2.0.7 was officially released...
+---
+# Apache DolphinScheduler 2.0.7 released, fixes complement and fault tolerance
+
+
+
+Recently, Apache DolphinScheduler version 2.0.7 was officially released. The new version fixes some complement and fault tolerance bugs and solves problems such as inconsistent batch data.
+
+# Major bug fixes
+
+## №1 The problem of continued detection of dependent while the dependent node contains tasks that are prohibited from running
+* In version 2.0.6, when a dependent node has a task that is forbidden to run, the dependent node will continue to detect the task instance for unable to find the task instance, since the forbidden task does not generate a task instance, resulting in the post-task of the dependent node not being submitted. This issue has been fixed in version 2.0.7.
+* PR: https://github.com/apache/dolphinscheduler/pull/10952
+
+## №2 The problem of +1 day to the complement time by default
+* In the previous version, when October 1, 2022 was selected as the complement time, for the time parameter $[yyyy-MM-dd], the output date was 2022–10–02, which is not the expected date. To solve this problem, the new version subtracts one day from the complement date to correct the output date.
+* Corresponding PR: https://github.com/apache/dolphinscheduler/pull/12376
+## №3 The problem that the task cannot be resubmitted when it is fault-tolerant
+
+* In the previous version, if there are 2 Worker nodes, each Worker is running 10 tasks and 10 internally -queued tasks. When Worker 1 hangs up, the state will turn to a fault-tolerant state because the status of all the running tasks and the tasks waiting to be run needs to be fault-tolerant. However, due to a bug, the fault-tolerant task will not be resubmitted, which will cause the running task background to show that the running is completed, while the task waiting to be run does not [...]
+* Corresponding to PR https://github.com/apache/dolphinscheduler/pull/12423
+
+# Bug fix
+
+* Fix the problem that the disk monitoring in the monitoring interface is not displayed
+* Fixed the problem of transferring parameters for tasks that failed to restore
+* Fix the problem that the dependency node contains forbidden tasks and the dependency continues to detect
+* Fix HTTP alert including content field in Post
+* Fix the problem that the complement time is +1 day by default
+* Fixed an issue where the retry time of failed tasks in the workflow did not work in some cases
+* Fix the problem that the interface of workflow task relationship creation has no dependency detection
+* Fix the problem that the task cannot be resubmitted when it is fault-tolerant
+* Fix the problem that the prompt information is not clear when the tenant’s name is too long
+
+# Modify records
+https://github.com/apache/dolphinscheduler/releases/tag/2.0.7
+
+# Download
+https://dolphinscheduler.apache.org/en-us/download/download.html
+
+# Acknowledgement
+This version, like version 2.0.6, is also tempered on the scheduling practice of 8000+ daily cumulative scheduling jobs in the production environment of Zhengcai Cloud and fixes the problems feed backed by the community. Special thanks to the Zhengcai Cloud Data Platform Department for their support of this release, and to all those who contributed to the release of Apache DolphinScheduler 2.0.7. It is your unremitting efforts to make the community progress!
+
+| danielfree | edward-yang | hstdream |
+|------------|--------------|------------|
+| lordk911 | retime123 | zwZjut |
+| Jekong-hao | JinyLeeChina | liqingwang |
+
+How to contribute:
+
+* GitHub Code Repository: https://github.com/apache/dolphinscheduler
+
+* Official Website:https://dolphinscheduler.apache.org/
+
+* Mail List:dev@dolphinscheduler@apache.org
+
+* Twitter:@DolphinSchedule
diff --git a/blog/en-us/How_can_more_people_benefit_from_big_data.md b/blog/en-us/How_can_more_people_benefit_from_big_data.md
new file mode 100644
index 0000000000..4dd6a0eca1
--- /dev/null
+++ b/blog/en-us/How_can_more_people_benefit_from_big_data.md
@@ -0,0 +1,210 @@
+---
+title:# How can more people benefit from big data?
+keywords: Apache,DolphinScheduler,scheduler,big data,ETL,airflow,hadoop,orchestration,dataops,Meetup
+description:During the ApacheCon Asia 2022, Chen Wei, who has more than 10 years of experience in Big Data...
+---
+# How can more people benefit from big data?
+
+<u>During the ApacheCon Asia 2022, Chen Wei, who has more than 10 years of experience in Big Data development and is head of an offline data factory development tool from a bank, delivered a keynote speech on how to enable more people to benefit from Big Data.
+
+Many thanks to volunteer Guan Bo for your text editing work, your contribution to Apache DolphinScheduler is what keeps the community moving forward!</u>
+
+This presentation focused on the following four key elements.
+
+# Background Information
+Business managers would like access to reliable data to help them make better business decisions.
+
+End-users want to get their data quickly within a few minutes or hours. They don’t want to go through the traditional process where they need to submit requirements to colleagues to the data department and wait weeks to get the data about requirement changes, development, and online implementation.
+
+Data development teams are getting bigger and more sophisticated to manage than ever before. Everyone who works with data wants immediate access to business data to help them make decisions.
+
+Data sources are becoming more complex, such as databases, web pages, logs, files, ERP, external data, etc.
+
+## User Needs
+Advanced users are looking for limited self-service, with easy, analytical access to data through self-service.
+
+Application developers only care about the business logic, not the specific underlying technology, they also don’t want to go deeper into the configuration associated with platform operations and maintenance.
+
+Hiding as much technical detail as possible, allows business developers as well as business users to focus more on the business logic and achieving business goals.
+
+More user-friendly for system administrators, allowing them to quickly and easily manage the data platform effectively.
+
+Based on the above user requirements, we believe that DataOps is the way to go, and DataOps built on top of DevOps is the best way to achieve data agility.
+
+## What is DataOps?
+
+DataOps is a collaborative data management practice focused on improving the communication, integration, and automation of data flows between data administrators, data consumers, and data developers within an organization.
+
+The goal of DataOps is to deliver value quicker by establishing predictable delivery as well as managing change to data, data models, and related artifacts.
+
+DataOps uses technology to automate the design, deployment, and management of data delivery through suitable levels of governance and uses metadata to improve the availability and value of data in a dynamic environment.
+
+DataOps helps us achieve rapid data innovation, deliver insights to the business customer at a faster rate, and provide data quality to support data personnel.
+
+In 2018, DataOps was included in the Technology Maturity Curve for Data Management, marking the official adoption and rollout of DataOps by the wider industry. Although DataOps can lower the barriers to data analytics, it does not make data analytics a simple task.
+
+## Focus of DataOps
+* Rapid innovation and experimentation to deliver better value to customers at an ever-increasing rate
+* Delivering extremely high-quality data with very low error rates.
+* Delivers interactive value through collaboration between complex arrays of people as well as technologies and environments.
+* Clarity of measurement and monitoring and transparency of results.
+
+
+## DataOps Core Component
+
+### Job Scheduler
+Provides scheduling of workflows, and offline data development and enables data developers to focus on the implementation of business logic and improve development efficiency.
+
+### DevTools
+Mainly provides development tools such as traditional scripting languages SQL, Python, etc. for quick and easy integration with the scheduling platform.
+
+### Migration and Deployment tools
+Data migration and deployment management tools. Aimed towards industries where the development and testing environment is network isolated, it requires effective import and export functions for proper deployment to the production environment.
+
+### Management and monitoring tools
+Administrator-friendly management, monitoring, and alert tools for offline tasks related to operations and maintenance.
+
+# Job Scheduler
+Next, we will compare different job schedulers together with you.
+
+## Advantages and disadvantages of mainstream job scheduler
+* **Oozie**
+Oozie is an open-source workflow engine-based framework that provides job scheduling and coordination for Hadoop MapReduce, and Pig Jobs. Oozie needs to be deployed to the Java Servlet container to function. It is mainly used for scheduling tasks at regular intervals and multiple tasks can be scheduled in sequential logical order of execution.
+
+* **Airflow**
+Airflow is an open-source project for Airbnb’s Workflow, Python-based task management, job scheduling, and monitoring workflow platform. Airflow is a DAG (directed acyclic graph) based job scheduling system, which can be interpreted as an advanced version of crontab, but it solves the task dependency problem that Crontab cannot handle. Compared to Crontab, Airflow makes it easy to monitor the status of tasks (if they were executed successfully or not, time of execution, execution depende [...]
+
+* **Apache Dolphinscheduler**
+DolphinScheduler is a decentralized, scalable and easily visualized DAG workflow job scheduling platform. Dedicated to solving the complex dependencies in the data processing process and enabling scheduling systems to be used right out of the box in the data processing process.
+
+* **Control-M**
+Control-M is a commercial version of a cross-platform job scheduling management software with powerful features but a lesser degree of programmability.
+
+* **Azkaban**
+Azkaban is a bulk workflow job scheduler released by Linkedin to execute a set of jobs and processes within a workflow in a specific order. Azkaban uses job profiles to establish dependencies between jobs and provides an easy-to-use web user interface to maintain and track your workflows. Azkaban requires all nodes to be deployed on a peer-to-peer basis, but under certain circumstances does not require full node peering as long as it supports high availability.
+
+## Scheduler Services
+* **Timer Service**
+
+Provides a scheduled service of Crontab expressions to execute workflows on a scheduled cycle.
+
+* **DAG Computation**
+DAG computing often refers to the internal division of a computational job into several smaller jobs, which are logically related or sequentially constructed into a DAG (directed acyclic graph) structure.
+
+* **Task Execution**
+Task Execution is run by the scheduling system’s execution engine according to the type of task, parameters, environment, referenced data source, etc.
+
+* **Environment Manage**
+ Targeting distributed scheduling engines, need to provide node management capabilities to facilitate task execution at different nodes. This enables tasks to run at a scale well beyond the limits of a single machine.
+
+* **Alert Service**
+Notify users and system administrators when tasks fail, time out, or are not completed within a specified time.
+
+* **What’s more?**
+
+In addition to the above, we hope that the scheduler can provide environment and data source management functions. After the workflow has been configured with an environment parameter, all tasks can then directly refer to it. Data sources can be made available for other tasks in an injection method, depending on the type of task.
+
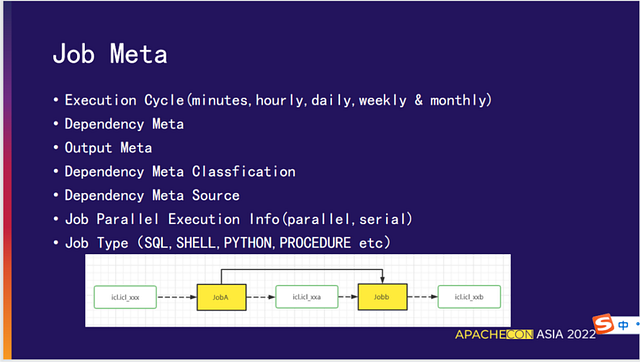
+## Job Meta
+
+
+* **Task Execution Cycle**
+
+(minutes, hourly, daily, weekly & monthly)
+
+* **Dependency Meta**
+
+Upstream metadata information (files, tables, etc.) depending on the task.
+
+* **Output Meta**
+
+Downstream metadata information (files, tables, etc.) depends on the task.
+
+* **Dependency Meta Classification**
+
+Classify and differentiate the sources of dependent metadata.
+
+* **Dependency Meta Source**
+
+Reverse processing of task-dependent metadata to obtain upstream and downstream tasks, providing a logical basis for automatic workflow scheduling and initiation.
+
+* **Job Parallel Execution Info(parallel, serial)**
+
+Controls the parallel execution status of jobs (parallel, serial).
+
+* **Job Type**
+
+Type of job (SQL, SHELL, PYTHON, PROCEDURE, etc.)
+
+## Job Development
+Integration IDE(script language,shell,SQL,python etc)
+
+Integrated IDE development environment (Script language, Shell, SQL, Python tasks, etc.)
+
+configurable resource file(jar,spark, etc)
+
+Configurable resource files(jar, spark, tasks that cannot be edited using text, etc.)
+
+custom components
+
+Customizable components, such as off-line data platforms where data synchronization is a specific component, require only a simple configuration of data synchronization to implement the synchronization process.
+
+# Third-Party Job
+Third-party job, where a specific application generates a custom script to accomplish the job goal.
+
+Third-Party Job Integration
+
+There are two methods of integration with third-party jobs, with the second method being the primary method used.
+
+**First method: pull**
+
+* The job scheduler provides an interface that can be accessed by the third-party system.
+* Development within the system and configuring the scheduler in the scheduler system. Configure the job in the third-party system, configure the scheduler in the scheduling system and execute the job.
+* Single-point of failure and bottleneck for job execution.
+**Disadvantages**: Requires multiple developments in third-party systems and configuration of the scheduler in the scheduling system.
+
+**Second method: push**
+* The scheduling system provides a programmable API.
+* Third-party systems create jobs and push them to the scheduling system, where they are automatically configured and scheduled.
+
+## Job Execution And Notification
+
+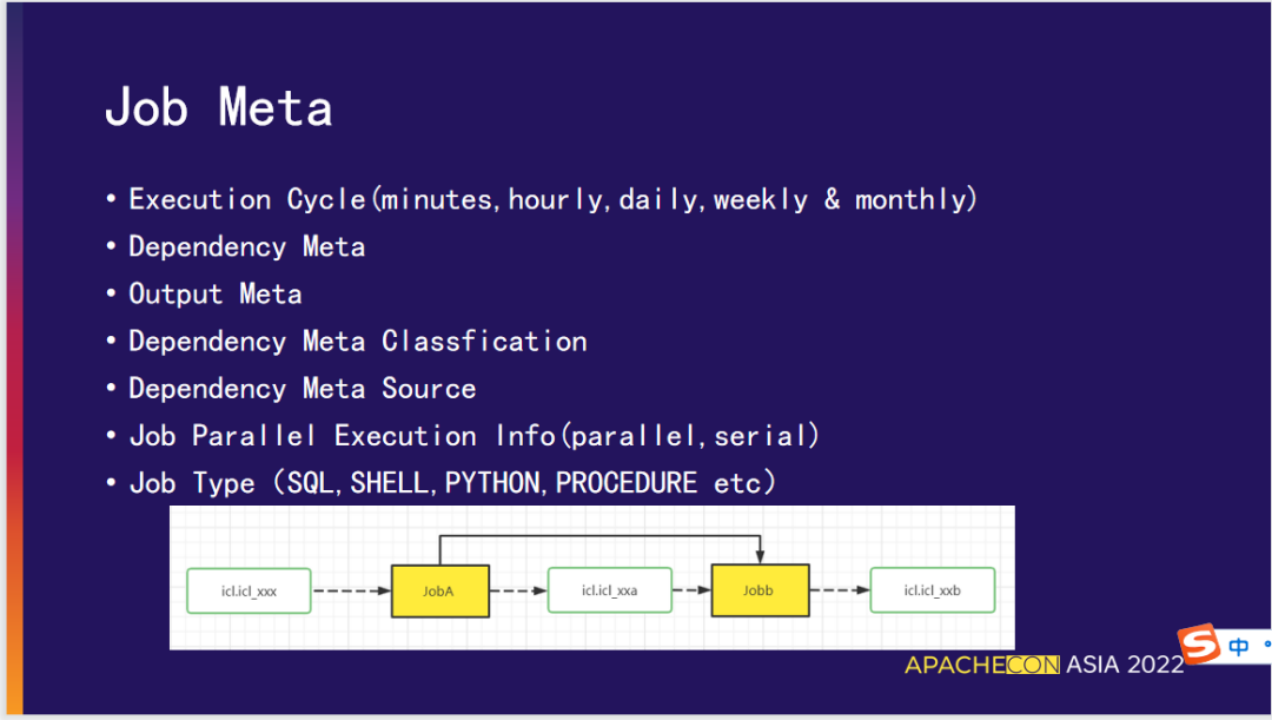
+**Job execution**: automatically triggered, based on conditions, upstream task dependencies
+
+**Job notifications**: progress and status of job execution sent to third-party systems as a push message
+
+## Sample Configuration For Data Integration
+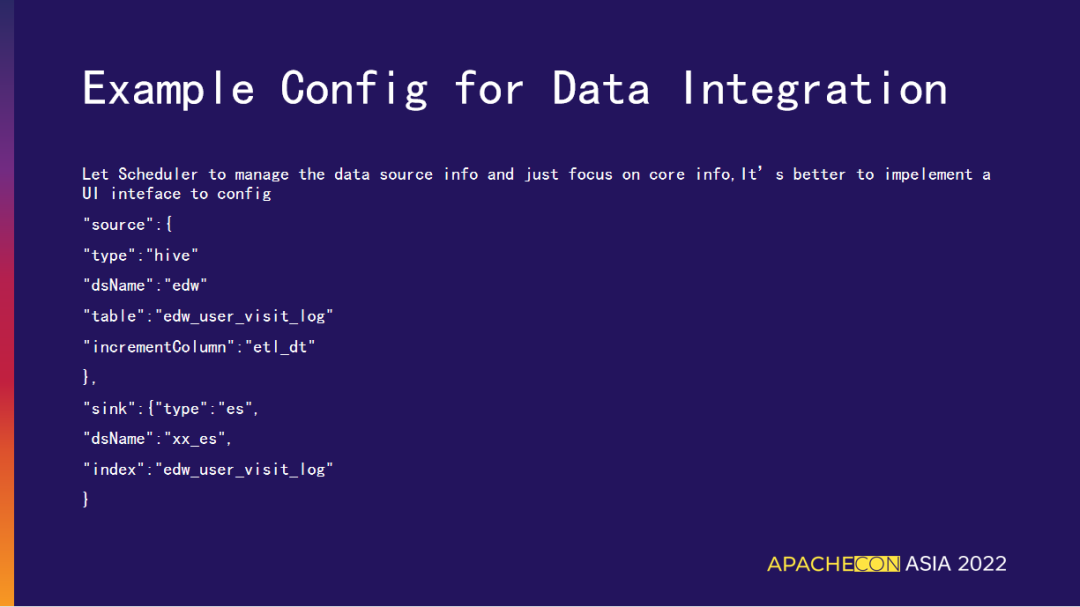
+**Sample configurations for third-party system integration are listed above.**
+
+The job scheduling system provides a programmable interface to enable the injection of environmental information. You only need to specify the different types of data sources in the third-party system, you do not need to configure the details of each data source e.g. (IP, port, username, password, etc.), this part is configured in the scheduling system and the data source and environment information are injected to the job. The job then parses the data source and environment from the par [...]
+
+## Job Assignments
+Traditional job scheduling was implemented by users dragging and connecting links, but we have improved the process by:
+
+* Integrating job scheduling into the workflow.
+* The configuration of upstream and downstream jobs is achieved through job-dependent metadata information.
+* Some of the tables (some dimension tables) in ETL jobs are immutable and can be added to a whitelist. The workflow eliminates the need to look for business logic upstream of the corresponding table in the whitelist when making automatic changes and resolving dependencies.
+* Views are an important factor affecting workflow automation. Views do not have ETL jobs, so we need to consider the view as a virtual job and import the view data into the scheduling platform so that the scheduling system is aware that the jobs that depend on the view are fundamentally dependent on the tasks corresponding to the underlying tables in the view.
+
+## Job Impact Analysis
+Thanks to the existence of metadata information, analysis of the impact of jobs is very straightforward.
+
+* The dependencies of the upstream and downstream metadata are used to resolve the upstream jobs which are job-dependent, avoiding the use of the manual configuration to reduce the probability of errors.
+* The calculation of some of the latest impacts, e.g. job suspension, failure, and impact of downstream jobs.
+
+## Low Code Platform
+* For general situations, it is a good choice to build template jobs that can be reused to calculate processes for a large number of job configurations, requiring only a single configuration of the core process to set up the parameters.
+* Support of specific systems, such as metrics management systems, tagging systems, data desensitization systems, etc.
+* Coding friendly, able to perform coding when required.
+* User friendly, under certain circumstances, the system coding is used rather than through user coding, the user can obtain the required data to assemble a specific data model without having to re-code it, e.g. the user can assemble a derivative tag based on the base tag by simple click configuration.
+
+# How to contribute:
+
+* GitHub Code Repository: https://github.com/apache/dolphinscheduler
+
+* Official Website:https://dolphinscheduler.apache.org/
+
+* Mail List:dev@dolphinscheduler@apache.org
+
+* Twitter:@DolphinSchedule
\ No newline at end of file
diff --git a/blog/en-us/How_did_Yili_explore_a_path_for_digital_transformation_based_on_DolphinScheduler.md b/blog/en-us/How_did_Yili_explore_a_path_for_digital_transformation_based_on_DolphinScheduler.md
new file mode 100644
index 0000000000..828dbea9d5
--- /dev/null
+++ b/blog/en-us/How_did_Yili_explore_a_path_for_digital_transformation_based_on_DolphinScheduler.md
@@ -0,0 +1,137 @@
+---
+title:# How did Yili explore a “path” for digital transformation based on DolphinScheduler?
+keywords: Apache,DolphinScheduler,scheduler,big data,ETL,airflow,hadoop,orchestration,dataops,Meetup
+description:People in general know about Yili. Every year, 1.3 billion...
+---
+# How did Yili explore a “path” for digital transformation based on DolphinScheduler?
+
+
+# Background and introduction of application
+
+## Introduction of Yili
+People in general know about Yili. Every year, 1.3 billion national consumers consume an average of 100 million packs of Yili products every day. The starting point of Yili’s business can be traced back to the cultivation of grass, the breeding of a cow, the production of a cup of milk, and finally delivered to consumers through a complex supply chain system, which involves the primary, secondary and tertiary industries.
+
+## Background of the application
+
+There is a complex application matrix behind the huge business volume, which poses a great challenge to our technical architecture.
+
+**· The current multi-cloud distribution of applications makes cross-cloud data migration and multi-cloud unified scheduling a rigid requirement**
+Currently, in the process of cooperation with cloud service providers, Yili does not only consider the IaaS and PaaS abilities supported by cloud service providers, but also the ecology behind them, including private domain ecology, e-commerce, logistics, etc. Therefore, our applications are more distributed on multiple clouds, and the data generated by these applications are also found on multiple clouds. The current centralized data structure requires a large amount of physical data re [...]
+
+· Unified technical architecture to combat entropy increase, reduce cost and increase efficiency
+
+The first challenge we faced was the ease of use, stability, and scalability of data integration and scheduling abilities due to massive relocation requirements. The second one came from the effect of entropy increase brought by the landing of a large number of applications. In the case of limited technical resources, it was difficult for us to effectively control our costs and improve our efficiency, especially in the face of data integration. We were facing the following core issues:
+
+• Duplicate construction of similar tools and products: Due to a lack of unified planning, duplicate construction of similar functional products exists.
+
+• Miscellaneous technology selection: AirFlow, Azkaban, Oozie, self-developed scheduling, etc.
+
+• High construction and derivative costs: costs such as personnel resource reserves, operation and maintenance, and operation training for multiple technology stacks.
+
+• Extensibility issues: extensive support for localized individual requirements.
+
+Before the introduction of Apache DolphinScheduler, our overall technical architecture was not unified in scheduling and data integration. To meet our internal rigid requirements, and with the consideration of scalability and stability, we planned to build a unified scheduling & data integration service system. After researching a large number of scheduling products, we decided to use Apache DolphinScheduler as our core engine and make localized transformations on top of it.
+
+## The positioning and application of the status of the Yili Big Data Scheduling System
+With limited technical resources, it is challenging to initiate the development of a tool. We must be clear about who our core users are, what the core positioning of this product is, and in what circumstances is this product used.
+
+After sufficient research, we have clarified the core positioning of this tool. It is not a scheduling platform for simple workflow, but a development platform of integrated data that suits the multi-cloud business of Yili. Application developers support the integration of internal and external data, scheduling requirements of the application, visual orchestration, and scheduling of data tasks.
+
+Judging from the current application of Yili, the number of daily scheduling tasks has reached 13,000, there are 15 nodes of clusters and more than 8000 tables are relocated every day.
+
+We have built a unified data platform for data integration, development, scheduling, operation, and maintenance on the multi-cloud infrastructure for big data. Through this platform, we can hide the differences between multi-cloud big data platforms and provide users with a unified development experience.
+
+**· System Overview of the Data Scheduling Service Platform of Yili
+**
+We have re-abstracted the 2.0.2 version of the entire model of DolphinScheduler, with the project as the top model, abstracting the three concepts of resources, roles, and tools, and bound them to the project. Among them, the toolset is the most important. All the tools used in the data development process would be expanded here. Users can complete data integration, development, operation and maintenance, asset management, and other tasks by authorizing projects in the platform. We have [...]
+
+# Practice & Exploration
+We have upgraded three times based on Apache DolphinScheduler 2.0.2 version with many function optimization, but there is a logic that runs through our product design and development process, that is, to meet the core needs of users to build new functions, improve user experience and to optimize the old functions. We aim to make the product easy to use, easy to get used to, user-friendly, and with reasonable moving lines.
+
+## Scenario-oriented data integration
+What is scenario-oriented data integration? Our products are completely open to users. When developers do data integration, they have a very clear context, such as synchronizing Mysql data to Hive, ES data to StarRocks, etc. Therefore, we provide a large number of integration components, which can complete the integration based on the configuration method. In the whole process, no code is needed. This improves the efficiency of data integration development.
+
+Before planning the core functions of data integration, we had the following main problems:
+
+1. Multiple data integration components or technologies make it difficult for users to choose
+
+2. An inconsistent technical structure that leads to increased maintenance costs
+
+3. The configuration of data integration is troublesome
+
+4. Poor scalability for secondary development
+
+We implemented the following strategies for these four problems :
+
+1. We only gave users the best choice — there are often no choices to choose from, so we will just provide the best one.
+
+2. Based on the structure of DataX unified data integration, we solved problems related to resources and reduced operation and maintenance costs
+
+3. For business applications, we used the template generator to generate task templates to simplify operations
+
+4. We implemented a reasonable code design
+
+## A lightened asset management
+The core requirement corresponding to this function is as follows: when applying the native big data capability to build a lightened data warehouse, it is necessary to gain a clear insight into the technical metadata information, including library, table, field, and basic attributes. We listed some business tag information, including subject domains, topics, etc., to facilitate the use of data by analysts. Based on such demands, we extended this lightened asset management function on the [...]
+
+**Forward and reverse table building are the core functions**. Forward table building refers to supporting users to create table models on the platform and materialize the table models on the big data platform. Reverse table building is used more often. In many cases, users still use traditional development methods to write scripts on the ETL server and submit them to the big data platform for calculation. At this time, the table already exists in advance, rather than being created visua [...]
+
+Asset retrieval provides asset retrieval functions for development and business analysis. It can perform lightweight retrieval based on subject domains, tags, field names, etc., and display asset cards, and upstream and downstream bloodline information.
+
+## Scheduling of multi-cloud tasks
+Scheduling of multi-cloud tasks is to solve the integrated scheduling problem of multi-cloud platforms. As mentioned above, Yili’s applications are distributed in multiple clouds, and this function can complete cross-cloud task scheduling based on a canvas. We made some extensions and transformations based on Apache DolphinScheduler. The binding relationship between the environment and the worker group is flexibly used, and the big data infrastructure is used to solve the problem of Kerb [...]
+
+We can separately trigger data integration tasks, including data processing tasks on different clouds. After the processing is completed, data calculation and business application-oriented planning are triggered on another cloud, and data services are provided finally. In this way, multi-cloud scheduling is done.
+
+## Optimization of monitoring dashboard
+Based on the original Apache DolphinScheduler dashboard, we did some optimization and upgrade. By focusing on operation and maintenance, we built the core indicators that the operation and maintenance work focuses on and displayed the indicators visually.
+
+The entire monitoring board is divided into task monitoring and cluster service monitoring.
+
+For task monitoring, we design key indicators like the number of projects, workflow (online/offline), the number of tasks to be scheduled, the number of tasks that have been successfully scheduled, an overview of the hourly operation, the TOP5 statistics on running failures, and the TOP5 statistics on running time.
+
+For service monitoring, key indicators include CPU, memory, average load, worker load in each cloud environment, and hourly worker operation overview.
+
+## Upgrade and optimization of users’ experience
+
+We also upgraded and optimized the user experience, such as the optimization of users’ timed configuration and the overall layout, which aims to optimize the user experience and make it easier to use.
+
+# Plans
+Lastly, these are the plans for DolphinScheduler.
+
+## Long-term planning
+In the long run, both the community and our company need to have a clear positioning for DolphinScheduler. It is not a scheduling platform for simple workflow, but a one-stop intelligent data development platform. There are at least three important characteristics of this platform:
+
+1. Multi-cloud unification: It can perfectly fit with the new decentralized data structure, which is a very important direction;
+
+2. Low-code: From the user’s point of view, it can support one-stop visual modeling, development, and analysis experience for the whole link;
+
+3. Intelligent management: The current data structure is based on reducing the complexity of data management, metadata-driven governance, and realizing intelligent data quality management will also be an important proposition.
+
+## Short and mid-range plans:
+Three important points will be focused on in the short term :
+
+1. The combination of cloud-native: The DolphinScheduler community has provided deployment services based on k8S, so our master, worker, and other services will be transformed based on containerization;
+
+2. Introduce the testing and online process: add roles such as developers and reviewers in the project, and control the online actions, and the metadata will be automatically synchronized after getting online;
+
+3. Quality module: DolphinScheduler 3.0 has added the data quality module. We will integrate this part and carry out the localized expansion, including pre-defining data quality, auditing, introducing data blood relationships, etc.
+
+# Reflects on open-source
+During the process of introducing DolphinScheduler, Yili was driven and inspired by some thoughts on collaboration. That is it’s very important to build a good collaboration between the company and open-source.
+
+Internally, we will assign specific personnel to follow up on the dynamics of open-source communities. The R&D team will proactively find bugs and submit them to the community, and submit PRs after they are fixed.
+
+At the same time, we will also actively interact with the community and check the trends through weekly and monthly meetings. Companies with limited technical research and development resources should find an open-source product that fits the actual use, and truly understand and implement the meaning of open-source. It is a powerful tool, as it can solve many problems internally, and notice issues that were never noticed before. Therefore, companies need to implement a suitable process f [...]
+
+That’s all of my talks. Thank you!
+
+# How to contribute:
+
+* GitHub Code Repository: https://github.com/apache/dolphinscheduler
+
+* Official Website:https://dolphinscheduler.apache.org/
+
+* Mail List:dev@dolphinscheduler@apache.org
+
+* Twitter:@DolphinSchedule
\ No newline at end of file
diff --git a/site_config/blog.js b/site_config/blog.js
index 37b6a1764d..1da032fe22 100644
--- a/site_config/blog.js
+++ b/site_config/blog.js
@@ -3,6 +3,27 @@ export default {
barText: 'Blog',
postsTitle: 'All posts',
list: [
+ {
+ title: 'How did Yili explore a “path” for digital transformation based on DolphinScheduler?,
+ author: 'Debra Chen',
+ dateStr: '2022-10-31',
+ desc: 'People in general know about Yili. Every year, 1.3 billion... ',
+ link: '/en-us/blog/How_did_Yili_explore_a_path_for_digital_transformation_based_on_DolphinScheduler.html',
+ },
+ {
+ title: 'How can more people benefit from big data?',
+ author: 'Debra Chen',
+ dateStr: '2022-10-29',
+ desc: 'During the ApacheCon Asia 2022, Chen Wei, who has more than 10 years... ',
+ link: '/en-us/blog/How_can_more_people_benefit_from_big_data.html',
+ },
+ {
+ title: 'Apache DolphinScheduler 2.0.7 released, fixes complement and fault tolerance',
+ author: 'Debra Chen',
+ dateStr: '2022-10-28',
+ desc: 'Recently, Apache DolphinScheduler version 2.0.7 was officially released...... ',
+ link: '/en-us/blog/Apache_DolphinScheduler_2.0.7.html',
+ },
{
title: 'Apache DolphinScheduler 3.0.1 released, with the scheduling kernel and UI optimized',
author: 'Debra Chen',
diff --git a/site_config/home.jsx b/site_config/home.jsx
index 9517747d87..5a7c619b45 100644
--- a/site_config/home.jsx
+++ b/site_config/home.jsx
@@ -558,6 +558,13 @@ export default {
events: {
title: 'Events & News',
list: [
+ {
+ img: 'https://miro.medium.com/max/630/0*Ep9rZFSTviU8SjmP',
+ title: 'Apache DolphinScheduler 2.0.7 released, fixes complement and fault tolerance',
+ content: 'Recently, Apache DolphinScheduler version 2.0.7 was officially released...',
+ dateStr: '2022-9-28',
+ link: '/en-us/blog/Apache_DolphinScheduler_2.0.7.html',
+ },
{
img: 'https://miro.medium.com/max/1400/1*zgkZk3lhn3UhLAKkHM9wzQ.png',
title: 'ApacheCon Asia 2022 Review | Application of DolphinScheduler in T3Go One-stop Platform',
@@ -574,14 +581,6 @@ export default {
link: '/en-us/blog/Apache_dolphinScheduler_3.0.0.html',
},
- {
- img: 'https://miro.medium.com/max/630/0*Ep9rZFSTviU8SjmP',
- title: 'Apache DolphinScheduler Extends Capabilities Through Python API and AWS Support',
- content: 'In the ever-changing world of technology, data is abundant. In fact,....',
- dateStr: '2022-8-26',
- link: '/en-us/blog/Python_API_and_AWS_Support.html',
- },
-
],
},
userreview: {