You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@flink.apache.org by GitBox <gi...@apache.org> on 2021/03/22 07:09:17 UTC
[GitHub] [flink] Thesharing opened a new pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Thesharing opened a new pull request #15310:
URL: https://github.com/apache/flink/pull/15310


   ## What is the purpose of the change

   *This pull request introduces the optimization of the initialization of PipelinedRegionSchedulingStrategy.*

   *PipelinedRegionSchedulingStrategy is used for task scheduling. The bottleneck of initializing PipelinedRegionSchedulingStrategy mainly lies in the procedure of calculating the consumed result partitions of the pipelined region, as well as the consumer pipelined region of the result partitions.*

   *For a batch job fulfilled with all-to-all blocking edges, each region consists of one vertex. The time complexity and space complexity both degrades to O(N^2).*

   *Based on FLINK-21328, the consumedResults in DefaultSchedulingPipelinedRegion can be replaced with ConsumedPartitionGroup in DefaultExecutionVertex.*

   *The complexity of initializing PipelinedRegionSchedulingStrategy decreases from O(N^2) to O(N).*

   *For more details, please check FLINK-21330.*


   ## Brief change log

     - *Add partitionNum for TestingSchedulingResultPartition*
     - *Add getConsumedPartitionGroups for SchedulingPipelinedRegion*
     - *Optimize the initialization of PipelinedRegionSchedulingStrategy*
     - *Optimize PipelinedRegionSchedulingStrategy#maybeScheduleRegion*


   ## Verifying this change

   *Since this optimization does not change the original logic of the initialization of PipelinedRegionSchedulingStrategy, we believe that this change is already covered by existing tests, such as PipelinedRegionSchedulingStrategyTest, DefaultExecutionTopologyTest, and etc.*

   ## Does this pull request potentially affect one of the following parts:

     - Dependencies (does it add or upgrade a dependency): (yes / **no**)
     - The public API, i.e., is any changed class annotated with `@Public(Evolving)`: (yes / **no**)
     - The serializers: (yes / **no** / don't know)
     - The runtime per-record code paths (performance sensitive): (yes / **no** / don't know)
     - Anything that affects deployment or recovery: JobManager (and its components), Checkpointing, Kubernetes/Yarn/Mesos, ZooKeeper: (**yes** / no / don't know)
     - The S3 file system connector: (yes / **no** / don't know)

   ## Documentation

     - Does this pull request introduce a new feature? (yes / **no**)
     - If yes, how is the feature documented? (**not applicable** / docs / JavaDocs / not documented)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk commented on a change in pull request #15310: [FLINK-21330] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r600155822


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -175,9 +184,24 @@ private void maybeScheduleRegion(final SchedulingPipelinedRegion region) {
         schedulerOperations.allocateSlotsAndDeploy(vertexDeploymentOptions);
     }

-    private boolean areRegionInputsAllConsumable(final SchedulingPipelinedRegion region) {
-        for (SchedulingResultPartition partition : region.getConsumedResults()) {
-            if (partition.getState() != ResultPartitionState.CONSUMABLE) {
+    private boolean areRegionInputsAllConsumable(
+            final SchedulingPipelinedRegion region,
+            final Map<ConsumedPartitionGroup, Boolean> consumableStatusCache) {
+        for (ConsumedPartitionGroup consumedPartitionGroup : region.getConsumedPartitionGroups()) {
+            if (!consumableStatusCache.computeIfAbsent(
+                    consumedPartitionGroup, this::isConsumedPartitionGroupConsumable)) {
+                return false;
+            }
+        }
+        return true;
+    }
+
+    private boolean isConsumedPartitionGroupConsumable(
+            final ConsumedPartitionGroup consumedPartitionGroup) {
+        // For grouped pipelined result partitions, they may not be consumable at the same time

Review comment:
       I did not quite understand this comment, would you explain it?

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -62,21 +85,34 @@ public DefaultExecutionVertex getVertex(final ExecutionVertexID vertexId) {

     @Override
     public Iterable<DefaultResultPartition> getConsumedResults() {
-        if (consumedResults == null) {
+        if (consumedPartitionGroups == null) {
             initializeConsumedResults();
         }
-        return consumedResults;
+        return () -> flatMap(consumedPartitionGroups, resultPartitionRetriever);
     }

     private void initializeConsumedResults() {
-        final Set<DefaultResultPartition> consumedResults = new HashSet<>();
+        final Set<ConsumedPartitionGroup> consumedResultGroupSet = new HashSet<>();
         for (DefaultExecutionVertex executionVertex : executionVertices.values()) {
-            for (DefaultResultPartition resultPartition : executionVertex.getConsumedResults()) {
+            for (ConsumedPartitionGroup consumedResultGroup :
+                    executionVertex.getConsumedPartitionGroups()) {
+                SchedulingResultPartition resultPartition =
+                        resultPartitionRetriever.apply(consumedResultGroup.getFirst());

Review comment:
       this is not correct because `consumedResultGroup` can be across multiple regions. And it is also a problem if a `ConsumedPartitionGroup` contains both intra-region consumed partition and inter-region one.
   I think we need to have a clear to avoid this case or solve it before we continue with this PR.

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingResultPartition.java
##########
@@ -48,11 +48,15 @@
     private ResultPartitionState state;

     TestingSchedulingResultPartition(

Review comment:
       This method can be private

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -96,7 +101,7 @@ private void init() {
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(region -> !region.getConsumedPartitionGroups().iterator().hasNext())

Review comment:
       We need to take care of it if `region.getConsumedPartitionGroups()` can contain intra-region partitions.

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingResultPartition.java
##########
@@ -115,6 +119,7 @@ void setState(ResultPartitionState state) {
     /** Builder for {@link TestingSchedulingResultPartition}. */
     public static final class Builder {
         private IntermediateDataSetID intermediateDataSetId = new IntermediateDataSetID();
+        private int partitionNum = -1;

Review comment:
       I would use a valid value 0 as the default `partitionNum`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "FAILURE",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 6a135eef1fd9441748be8446fad28ef2eec23a95 Azure: [FAILURE](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     }, {
       "hash" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617",
       "triggerID" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "triggerType" : "PUSH"
     }, {
       "hash" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "triggerType" : "PUSH"
     }, {
       "hash" : "86a9297e50f050579d4a956fc4cef3253d1d87c6",
       "status" : "PENDING",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15677",
       "triggerID" : "86a9297e50f050579d4a956fc4cef3253d1d87c6",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 64018c1e754c5f5754395491d6731b7e8893fb25 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617)
   * 0139fa9c34a9ab8d821096668ac2bae9243ea7b2 UNKNOWN
   * 86a9297e50f050579d4a956fc4cef3253d1d87c6 Azure: [PENDING](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15677)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] Thesharing commented on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
Thesharing commented on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-806018417
> Thanks for opening this PR @Thesharing
> I noticed a critical problem of this PR that it assumes the `ConsumedPartitionGroup` can either be consumed all intra-region or inter-region. However, it can happen that a ConsumedPartitionGroup contains both intra-region consumed partition and inter-region one. e.g. A(4) -- pointwise pipelined --> B(3), A(4) -- pointwise pipelined --> C(2), B(3) -- pointwise blocking --> C(2).
> I think we need to have a clear idea about how to avoid this case or solve it before we continue with this PR.
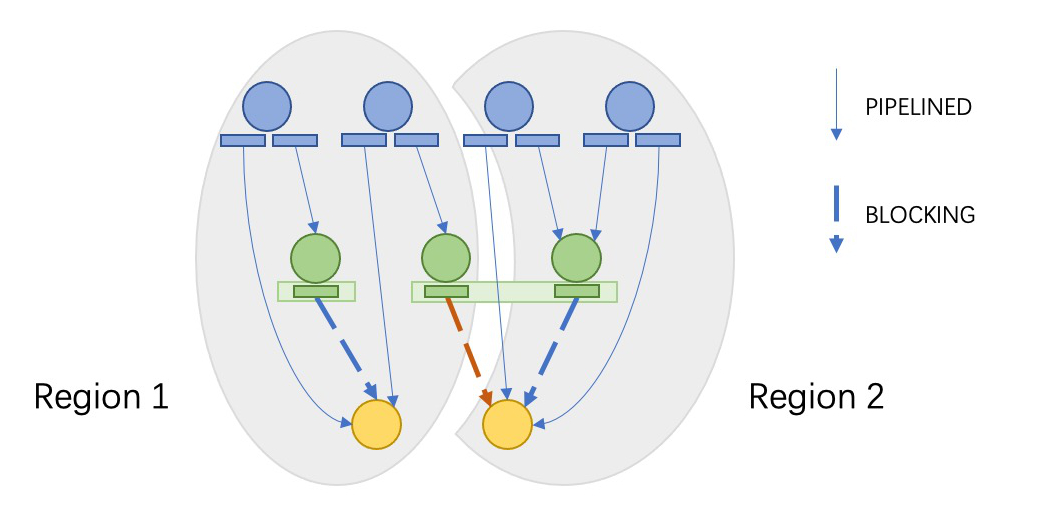
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk commented on a change in pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r603174108


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);
+                        }
+                    }
+                }
+            }
+        }
+    }
+
+    private SchedulingPipelinedRegion getProducerRegion(IntermediateResultPartitionID partitionId) {
+        return schedulingTopology.getPipelinedRegionOfVertex(
+                schedulingTopology.getResultPartition(partitionId).getProducer().getId());
+    }
+
+    private void initPartitionGroupConsumerRegions() {
+        for (SchedulingPipelinedRegion region : schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    region.getAllBlockingConsumedPartitionGroups()) {
+                if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)
+                        || isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                    partitionGroupConsumerRegions
+                            .computeIfAbsent(consumedPartitionGroup, group -> new HashSet<>())
+                            .add(region);
+                }
+            }
+        }
+    }
+
+    private void initCorrelatedResultPartitionGroups() {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                partitionGroupConsumerRegions.keySet()) {
+            for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                correlatedResultPartitionGroups
+                        .computeIfAbsent(
+                                partitionId.getIntermediateDataSetID(), id -> new HashSet<>())
+                        .add(consumedPartitionGroup);
+            }
+        }
+    }
+
     @Override
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(this::noExternalBlockingConsumedPartitions)
                         .collect(Collectors.toSet());
         maybeScheduleRegions(sourceRegions);
     }

+    private boolean noExternalBlockingConsumedPartitions(SchedulingPipelinedRegion region) {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                region.getAllBlockingConsumedPartitionGroups()) {
+            if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)

Review comment:
       Thanks for reporting this problem. Go ahead to open a new JIRA for it.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     }, {
       "hash" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617",
       "triggerID" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "triggerType" : "PUSH"
     }, {
       "hash" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 64018c1e754c5f5754395491d6731b7e8893fb25 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617)
   * 0139fa9c34a9ab8d821096668ac2bae9243ea7b2 UNKNOWN

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     }, {
       "hash" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "status" : "PENDING",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617",
       "triggerID" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * dcbc4d6f9efcd5e5d70f224862be38963e1fab63 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233)
   * 64018c1e754c5f5754395491d6731b7e8893fb25 Azure: [PENDING](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "PENDING",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 6a135eef1fd9441748be8446fad28ef2eec23a95 Azure: [PENDING](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot commented on pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot commented on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803821275


   Thanks a lot for your contribution to the Apache Flink project. I'm the @flinkbot. I help the community
   to review your pull request. We will use this comment to track the progress of the review.


   ## Automated Checks
   Last check on commit 6a135eef1fd9441748be8446fad28ef2eec23a95 (Mon Mar 22 07:13:07 UTC 2021)

   **Warnings:**
    * No documentation files were touched! Remember to keep the Flink docs up to date!


   <sub>Mention the bot in a comment to re-run the automated checks.</sub>
   ## Review Progress

   * ❓ 1. The [description] looks good.
   * ❓ 2. There is [consensus] that the contribution should go into to Flink.
   * ❓ 3. Needs [attention] from.
   * ❓ 4. The change fits into the overall [architecture].
   * ❓ 5. Overall code [quality] is good.

   Please see the [Pull Request Review Guide](https://flink.apache.org/contributing/reviewing-prs.html) for a full explanation of the review process.<details>
    The Bot is tracking the review progress through labels. Labels are applied according to the order of the review items. For consensus, approval by a Flink committer of PMC member is required <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot approve description` to approve one or more aspects (aspects: `description`, `consensus`, `architecture` and `quality`)
    - `@flinkbot approve all` to approve all aspects
    - `@flinkbot approve-until architecture` to approve everything until `architecture`
    - `@flinkbot attention @username1 [@username2 ..]` to require somebody's attention
    - `@flinkbot disapprove architecture` to remove an approval you gave earlier
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] Thesharing commented on pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
Thesharing commented on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803884629


   @zhuzhurk Considering `Set<SchedulingPipelinedRegion>` is used frequently in `RegionPartitionReleaseStrategy` after the optimization, should we add a class `PipelinedRegionSet` or not?
   Please refer to https://github.com/apache/flink/pull/15314/commits/3764ec2edda2138751e0a3f61ad5e4077894d8f8 .


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk commented on a change in pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r602884482


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -19,30 +19,51 @@

 package org.apache.flink.runtime.scheduler.adapter;

+import org.apache.flink.annotation.VisibleForTesting;
+import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
+import org.apache.flink.runtime.scheduler.strategy.ConsumedPartitionGroup;
 import org.apache.flink.runtime.scheduler.strategy.ExecutionVertexID;
 import org.apache.flink.runtime.scheduler.strategy.SchedulingPipelinedRegion;
+import org.apache.flink.runtime.scheduler.strategy.SchedulingResultPartition;
 import org.apache.flink.util.Preconditions;

+import java.util.ArrayList;
 import java.util.Collections;
 import java.util.HashMap;
 import java.util.HashSet;
+import java.util.List;
 import java.util.Map;
 import java.util.Set;
+import java.util.function.Function;

 /** Default implementation of {@link SchedulingPipelinedRegion}. */
 public class DefaultSchedulingPipelinedRegion implements SchedulingPipelinedRegion {

     private final Map<ExecutionVertexID, DefaultExecutionVertex> executionVertices;

-    private Set<DefaultResultPartition> consumedResults;
+    private List<ConsumedPartitionGroup> blockingConsumedPartitionGroups;
+
+    private final Function<IntermediateResultPartitionID, DefaultResultPartition>
+            resultPartitionRetriever;
+
+    public DefaultSchedulingPipelinedRegion(
+            Set<DefaultExecutionVertex> defaultExecutionVertices,
+            Function<IntermediateResultPartitionID, DefaultResultPartition>
+                    resultPartitionRetriever) {

-    public DefaultSchedulingPipelinedRegion(Set<DefaultExecutionVertex> defaultExecutionVertices) {
         Preconditions.checkNotNull(defaultExecutionVertices);

         this.executionVertices = new HashMap<>();
         for (DefaultExecutionVertex executionVertex : defaultExecutionVertices) {
             this.executionVertices.put(executionVertex.getId(), executionVertex);
         }
+
+        this.resultPartitionRetriever = resultPartitionRetriever;
+    }
+
+    @VisibleForTesting
+    public DefaultSchedulingPipelinedRegion(Set<DefaultExecutionVertex> defaultExecutionVertices) {

Review comment:
       Can we avoid introducing such a testing method? I also think `resultPartitionRetriever` should never be `null`

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingResultPartition.java
##########
@@ -47,12 +47,16 @@

     private ResultPartitionState state;

-    TestingSchedulingResultPartition(
-            IntermediateDataSetID dataSetID, ResultPartitionType type, ResultPartitionState state) {
+    private TestingSchedulingResultPartition(
+            IntermediateDataSetID dataSetID,
+            int partitionNum,

Review comment:
       Which tests will be broken if not doing this change?

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -49,16 +50,21 @@

     private final DeploymentOption deploymentOption = new DeploymentOption(false);

-    /** Result partitions are correlated if they have the same result id. */
-    private final Map<IntermediateDataSetID, Set<SchedulingResultPartition>>
-            correlatedResultPartitions = new HashMap<>();
+    /** ConsumedPartitionGroups are correlated if they have the same result id. */
+    private final Map<IntermediateDataSetID, Set<ConsumedPartitionGroup>>
+            correlatedResultPartitionGroups = new HashMap<>();

-    private final Map<IntermediateResultPartitionID, Set<SchedulingPipelinedRegion>>
-            partitionConsumerRegions = new HashMap<>();
+    /** External consumer regions of each ConsumedPartitionGroup. */
+    private final Map<ConsumedPartitionGroup, Set<SchedulingPipelinedRegion>>
+            partitionGroupConsumerRegions = new HashMap<>();

Review comment:
       better to use `IdentityHashMap`

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/executiongraph/failover/flip1/partitionrelease/RegionPartitionReleaseStrategy.java
##########
@@ -74,7 +74,10 @@ private void initRegionExecutionViewByVertex() {
         if (regionExecutionView.isFinished()) {
             final SchedulingPipelinedRegion pipelinedRegion =
                     schedulingTopology.getPipelinedRegionOfVertex(finishedVertex);
-            return filterReleasablePartitions(pipelinedRegion.getConsumedResults());
+            return filterReleasablePartitions(

Review comment:
       I think the input of `filterReleasablePartitions` should be changed to a `Set` to ensure there is no duplicated element. Or at least we should add a `unique()` filter in the implementation of `filterReleasablePartitions`.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -49,16 +50,21 @@

     private final DeploymentOption deploymentOption = new DeploymentOption(false);

-    /** Result partitions are correlated if they have the same result id. */
-    private final Map<IntermediateDataSetID, Set<SchedulingResultPartition>>
-            correlatedResultPartitions = new HashMap<>();
+    /** ConsumedPartitionGroups are correlated if they have the same result id. */
+    private final Map<IntermediateDataSetID, Set<ConsumedPartitionGroup>>
+            correlatedResultPartitionGroups = new HashMap<>();

-    private final Map<IntermediateResultPartitionID, Set<SchedulingPipelinedRegion>>
-            partitionConsumerRegions = new HashMap<>();
+    /** External consumer regions of each ConsumedPartitionGroup. */
+    private final Map<ConsumedPartitionGroup, Set<SchedulingPipelinedRegion>>
+            partitionGroupConsumerRegions = new HashMap<>();

     private final Map<SchedulingPipelinedRegion, List<ExecutionVertexID>> regionVerticesSorted =
             new IdentityHashMap<>();

+    /** The ConsumedPartitionGroups which have inter-region producers and inter-region producers. */
+    private final Set<ConsumedPartitionGroup> crossRegionConsumerPartitionGroups =

Review comment:
       `crossRegionConsumerPartitionGroups` -> `crossRegionConsumedPartitionGroups `

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);

Review comment:
       break;

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);
+                        }
+                    }
+                }
+            }
+        }
+    }
+
+    private SchedulingPipelinedRegion getProducerRegion(IntermediateResultPartitionID partitionId) {
+        return schedulingTopology.getPipelinedRegionOfVertex(
+                schedulingTopology.getResultPartition(partitionId).getProducer().getId());
+    }
+
+    private void initPartitionGroupConsumerRegions() {
+        for (SchedulingPipelinedRegion region : schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    region.getAllBlockingConsumedPartitionGroups()) {
+                if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)
+                        || isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                    partitionGroupConsumerRegions
+                            .computeIfAbsent(consumedPartitionGroup, group -> new HashSet<>())
+                            .add(region);
+                }
+            }
+        }
+    }
+
+    private void initCorrelatedResultPartitionGroups() {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                partitionGroupConsumerRegions.keySet()) {
+            for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                correlatedResultPartitionGroups
+                        .computeIfAbsent(
+                                partitionId.getIntermediateDataSetID(), id -> new HashSet<>())
+                        .add(consumedPartitionGroup);
+            }
+        }
+    }
+
     @Override
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(this::noExternalBlockingConsumedPartitions)
                         .collect(Collectors.toSet());
         maybeScheduleRegions(sourceRegions);
     }

+    private boolean noExternalBlockingConsumedPartitions(SchedulingPipelinedRegion region) {

Review comment:
       I would prefer this method to be `isSourceRegion`

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/SchedulingPipelinedRegion.java
##########
@@ -23,10 +23,19 @@
 import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
 import org.apache.flink.runtime.topology.PipelinedRegion;

+import java.util.List;
+
 /** Pipelined region on execution level, i.e., {@link ExecutionGraph} level. */
 public interface SchedulingPipelinedRegion
         extends PipelinedRegion<
                 ExecutionVertexID,
                 IntermediateResultPartitionID,
                 SchedulingExecutionVertex,
-                SchedulingResultPartition> {}
+                SchedulingResultPartition> {
+    /**
+     * Get all blocking {@link ConsumedPartitionGroup}s.
+     *
+     * @return list of {@link ConsumedPartitionGroup}s
+     */
+    List<ConsumedPartitionGroup> getAllBlockingConsumedPartitionGroups();

Review comment:
       I would suggest this to be an `Iterable`

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {

Review comment:
       `initCrossRegionConsumerPartitionGroups` -> `initCrossRegionConsumedPartitionGroups `

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -49,16 +50,21 @@

     private final DeploymentOption deploymentOption = new DeploymentOption(false);

-    /** Result partitions are correlated if they have the same result id. */
-    private final Map<IntermediateDataSetID, Set<SchedulingResultPartition>>
-            correlatedResultPartitions = new HashMap<>();
+    /** ConsumedPartitionGroups are correlated if they have the same result id. */
+    private final Map<IntermediateDataSetID, Set<ConsumedPartitionGroup>>
+            correlatedResultPartitionGroups = new HashMap<>();

-    private final Map<IntermediateResultPartitionID, Set<SchedulingPipelinedRegion>>
-            partitionConsumerRegions = new HashMap<>();
+    /** External consumer regions of each ConsumedPartitionGroup. */
+    private final Map<ConsumedPartitionGroup, Set<SchedulingPipelinedRegion>>
+            partitionGroupConsumerRegions = new HashMap<>();

     private final Map<SchedulingPipelinedRegion, List<ExecutionVertexID>> regionVerticesSorted =
             new IdentityHashMap<>();

+    /** The ConsumedPartitionGroups which have inter-region producers and inter-region producers. */

Review comment:
       `which have inter-region producers and inter-region producers.` -> `which are produced by multiple regions.`

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -19,30 +19,51 @@

 package org.apache.flink.runtime.scheduler.adapter;

+import org.apache.flink.annotation.VisibleForTesting;
+import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
+import org.apache.flink.runtime.scheduler.strategy.ConsumedPartitionGroup;
 import org.apache.flink.runtime.scheduler.strategy.ExecutionVertexID;
 import org.apache.flink.runtime.scheduler.strategy.SchedulingPipelinedRegion;
+import org.apache.flink.runtime.scheduler.strategy.SchedulingResultPartition;
 import org.apache.flink.util.Preconditions;

+import java.util.ArrayList;
 import java.util.Collections;
 import java.util.HashMap;
 import java.util.HashSet;
+import java.util.List;
 import java.util.Map;
 import java.util.Set;
+import java.util.function.Function;

 /** Default implementation of {@link SchedulingPipelinedRegion}. */
 public class DefaultSchedulingPipelinedRegion implements SchedulingPipelinedRegion {

     private final Map<ExecutionVertexID, DefaultExecutionVertex> executionVertices;

-    private Set<DefaultResultPartition> consumedResults;
+    private List<ConsumedPartitionGroup> blockingConsumedPartitionGroups;
+
+    private final Function<IntermediateResultPartitionID, DefaultResultPartition>
+            resultPartitionRetriever;
+
+    public DefaultSchedulingPipelinedRegion(
+            Set<DefaultExecutionVertex> defaultExecutionVertices,
+            Function<IntermediateResultPartitionID, DefaultResultPartition>
+                    resultPartitionRetriever) {

-    public DefaultSchedulingPipelinedRegion(Set<DefaultExecutionVertex> defaultExecutionVertices) {
         Preconditions.checkNotNull(defaultExecutionVertices);

         this.executionVertices = new HashMap<>();
         for (DefaultExecutionVertex executionVertex : defaultExecutionVertices) {
             this.executionVertices.put(executionVertex.getId(), executionVertex);
         }
+
+        this.resultPartitionRetriever = resultPartitionRetriever;

Review comment:
       checkNotNull

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingPipelinedRegion.java
##########
@@ -30,15 +33,24 @@
     private final Map<ExecutionVertexID, TestingSchedulingExecutionVertex> regionVertices =
             new HashMap<>();

-    private final Set<TestingSchedulingResultPartition> consumedPartitions = new HashSet<>();
+    private final List<ConsumedPartitionGroup> consumedPartitionGroups = new ArrayList<>();
+
+    private final Map<IntermediateResultPartitionID, TestingSchedulingResultPartition>

Review comment:
       Is it needed as a field?

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingPipelinedRegion.java
##########
@@ -30,15 +33,24 @@
     private final Map<ExecutionVertexID, TestingSchedulingExecutionVertex> regionVertices =
             new HashMap<>();

-    private final Set<TestingSchedulingResultPartition> consumedPartitions = new HashSet<>();
+    private final List<ConsumedPartitionGroup> consumedPartitionGroups = new ArrayList<>();

Review comment:
       Could we make it a `Set` instead of a `List`?

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -60,23 +81,33 @@ public DefaultExecutionVertex getVertex(final ExecutionVertexID vertexId) {
         return executionVertex;
     }

-    @Override
-    public Iterable<DefaultResultPartition> getConsumedResults() {
-        if (consumedResults == null) {
-            initializeConsumedResults();
-        }
-        return consumedResults;
-    }
-
-    private void initializeConsumedResults() {
-        final Set<DefaultResultPartition> consumedResults = new HashSet<>();
+    private void initializeAllBlockingConsumedPartitionGroups() {
+        final Set<ConsumedPartitionGroup> consumedResultGroupSet = new HashSet<>();
         for (DefaultExecutionVertex executionVertex : executionVertices.values()) {
-            for (DefaultResultPartition resultPartition : executionVertex.getConsumedResults()) {
-                if (!executionVertices.containsKey(resultPartition.getProducer().getId())) {
-                    consumedResults.add(resultPartition);
+            for (ConsumedPartitionGroup consumedResultGroup :
+                    executionVertex.getConsumedPartitionGroups()) {
+                SchedulingResultPartition resultPartition =
+                        resultPartitionRetriever.apply(consumedResultGroup.getFirst());
+                if (resultPartition.getResultType().isBlocking()) {
+                    consumedResultGroupSet.add(consumedResultGroup);
                 }
             }
         }
-        this.consumedResults = Collections.unmodifiableSet(consumedResults);
+
+        this.blockingConsumedPartitionGroups =

Review comment:
       There is no need to convert the `Set` to a `List`. I think `blockingConsumedPartitionGroups` should just be a `Set`.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/SchedulingStrategyUtils.java
##########
@@ -31,7 +31,7 @@
 import java.util.stream.Collectors;

 /** Utils for {@link SchedulingStrategy}. */
-class SchedulingStrategyUtils {
+public class SchedulingStrategyUtils {

Review comment:
       There is no need to do this change

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -175,15 +246,50 @@ private void maybeScheduleRegion(final SchedulingPipelinedRegion region) {
         schedulerOperations.allocateSlotsAndDeploy(vertexDeploymentOptions);
     }

-    private boolean areRegionInputsAllConsumable(final SchedulingPipelinedRegion region) {
-        for (SchedulingResultPartition partition : region.getConsumedResults()) {
-            if (partition.getState() != ResultPartitionState.CONSUMABLE) {
+    private boolean areRegionInputsAllConsumable(
+            final SchedulingPipelinedRegion region,
+            final Map<ConsumedPartitionGroup, Boolean> consumableStatusCache) {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                region.getAllBlockingConsumedPartitionGroups()) {
+            if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)) {
+                if (!isCrossRegionConsumedPartitionConsumable(consumedPartitionGroup, region)) {
+                    return false;
+                }
+            } else if (isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                if (!consumableStatusCache.computeIfAbsent(
+                        consumedPartitionGroup, this::isConsumedPartitionGroupConsumable)) {
+                    return false;
+                }
+            }
+        }
+        return true;
+    }
+
+    private boolean isConsumedPartitionGroupConsumable(
+            final ConsumedPartitionGroup consumedPartitionGroup) {
+        for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+            if (schedulingTopology.getResultPartition(partitionId).getState()
+                    != ResultPartitionState.CONSUMABLE) {
                 return false;
             }
         }
         return true;
     }

+    private boolean isCrossRegionConsumedPartitionConsumable(
+            final ConsumedPartitionGroup consumedPartitionGroup,
+            final SchedulingPipelinedRegion pipelinedRegion) {
+        for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+            if (isExternalConsumedPartition(partitionId, pipelinedRegion)) {

Review comment:
       It's better to merge the two nested `if`s into one.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);
+                        }
+                    }
+                }
+            }
+        }
+    }
+
+    private SchedulingPipelinedRegion getProducerRegion(IntermediateResultPartitionID partitionId) {
+        return schedulingTopology.getPipelinedRegionOfVertex(
+                schedulingTopology.getResultPartition(partitionId).getProducer().getId());
+    }
+
+    private void initPartitionGroupConsumerRegions() {
+        for (SchedulingPipelinedRegion region : schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    region.getAllBlockingConsumedPartitionGroups()) {
+                if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)
+                        || isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                    partitionGroupConsumerRegions
+                            .computeIfAbsent(consumedPartitionGroup, group -> new HashSet<>())
+                            .add(region);
+                }
+            }
+        }
+    }
+
+    private void initCorrelatedResultPartitionGroups() {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                partitionGroupConsumerRegions.keySet()) {
+            for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                correlatedResultPartitionGroups
+                        .computeIfAbsent(
+                                partitionId.getIntermediateDataSetID(), id -> new HashSet<>())
+                        .add(consumedPartitionGroup);
+            }
+        }
+    }
+
     @Override
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(this::noExternalBlockingConsumedPartitions)
                         .collect(Collectors.toSet());
         maybeScheduleRegions(sourceRegions);
     }

+    private boolean noExternalBlockingConsumedPartitions(SchedulingPipelinedRegion region) {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                region.getAllBlockingConsumedPartitionGroups()) {
+            if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)

Review comment:
       It is no correct here. If a region has cross-region `ConsumerPartitionGroups` but has no external `ConsumerPartitionGroup`, it should also be treated as a source region.
   I think we need to add a test case for it.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     }, {
       "hash" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617",
       "triggerID" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "triggerType" : "PUSH"
     }, {
       "hash" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "triggerType" : "PUSH"
     }, {
       "hash" : "86a9297e50f050579d4a956fc4cef3253d1d87c6",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15677",
       "triggerID" : "86a9297e50f050579d4a956fc4cef3253d1d87c6",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 0139fa9c34a9ab8d821096668ac2bae9243ea7b2 UNKNOWN
   * 86a9297e50f050579d4a956fc4cef3253d1d87c6 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15677)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "FAILURE",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 6a135eef1fd9441748be8446fad28ef2eec23a95 Azure: [FAILURE](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152)
   * dcbc4d6f9efcd5e5d70f224862be38963e1fab63 UNKNOWN

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk commented on a change in pull request #15310: [FLINK-21330] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r599350956


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -62,21 +85,34 @@ public DefaultExecutionVertex getVertex(final ExecutionVertexID vertexId) {

     @Override
     public Iterable<DefaultResultPartition> getConsumedResults() {
-        if (consumedResults == null) {
+        if (consumedPartitionGroups == null) {
             initializeConsumedResults();
         }
-        return consumedResults;
+        return () -> flatMap(consumedPartitionGroups, resultPartitionRetriever);
     }

     private void initializeConsumedResults() {
-        final Set<DefaultResultPartition> consumedResults = new HashSet<>();
+        final Set<ConsumedPartitionGroup> consumedResultGroupSet = new HashSet<>();
         for (DefaultExecutionVertex executionVertex : executionVertices.values()) {
-            for (DefaultResultPartition resultPartition : executionVertex.getConsumedResults()) {
+            for (ConsumedPartitionGroup consumedResultGroup :
+                    executionVertex.getConsumedPartitionGroups()) {
+                SchedulingResultPartition resultPartition =
+                        resultPartitionRetriever.apply(consumedResultGroup.getFirst());

Review comment:
       this is not correct because `consumedResultGroup` can be across multiple regions. And it is also a problem if a `ConsumedPartitionGroup` contains both intra-region consumed partition and inter-region one.
   I think we need to have a clear idea to avoid this case or solve it before we continue with this PR.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     }, {
       "hash" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617",
       "triggerID" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 64018c1e754c5f5754395491d6731b7e8893fb25 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "FAILURE",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "PENDING",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 6a135eef1fd9441748be8446fad28ef2eec23a95 Azure: [FAILURE](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152)
   * dcbc4d6f9efcd5e5d70f224862be38963e1fab63 Azure: [PENDING](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk commented on a change in pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r603082091


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -96,7 +101,7 @@ private void init() {
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(region -> !region.getConsumedPartitionGroups().iterator().hasNext())

Review comment:
       outdated.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -175,9 +184,24 @@ private void maybeScheduleRegion(final SchedulingPipelinedRegion region) {
         schedulerOperations.allocateSlotsAndDeploy(vertexDeploymentOptions);
     }

-    private boolean areRegionInputsAllConsumable(final SchedulingPipelinedRegion region) {
-        for (SchedulingResultPartition partition : region.getConsumedResults()) {
-            if (partition.getState() != ResultPartitionState.CONSUMABLE) {
+    private boolean areRegionInputsAllConsumable(
+            final SchedulingPipelinedRegion region,
+            final Map<ConsumedPartitionGroup, Boolean> consumableStatusCache) {
+        for (ConsumedPartitionGroup consumedPartitionGroup : region.getConsumedPartitionGroups()) {
+            if (!consumableStatusCache.computeIfAbsent(
+                    consumedPartitionGroup, this::isConsumedPartitionGroupConsumable)) {
+                return false;
+            }
+        }
+        return true;
+    }
+
+    private boolean isConsumedPartitionGroupConsumable(
+            final ConsumedPartitionGroup consumedPartitionGroup) {
+        // For grouped pipelined result partitions, they may not be consumable at the same time

Review comment:
       outdated.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803821275


   Thanks a lot for your contribution to the Apache Flink project. I'm the @flinkbot. I help the community
   to review your pull request. We will use this comment to track the progress of the review.


   ## Automated Checks
   Last check on commit 86a9297e50f050579d4a956fc4cef3253d1d87c6 (Sat Aug 28 10:34:42 UTC 2021)

   **Warnings:**
    * No documentation files were touched! Remember to keep the Flink docs up to date!


   <sub>Mention the bot in a comment to re-run the automated checks.</sub>
   ## Review Progress

   * ❓ 1. The [description] looks good.
   * ❓ 2. There is [consensus] that the contribution should go into to Flink.
   * ❓ 3. Needs [attention] from.
   * ❓ 4. The change fits into the overall [architecture].
   * ❓ 5. Overall code [quality] is good.

   Please see the [Pull Request Review Guide](https://flink.apache.org/contributing/reviewing-prs.html) for a full explanation of the review process.<details>
    The Bot is tracking the review progress through labels. Labels are applied according to the order of the review items. For consensus, approval by a Flink committer of PMC member is required <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot approve description` to approve one or more aspects (aspects: `description`, `consensus`, `architecture` and `quality`)
    - `@flinkbot approve all` to approve all aspects
    - `@flinkbot approve-until architecture` to approve everything until `architecture`
    - `@flinkbot attention @username1 [@username2 ..]` to require somebody's attention
    - `@flinkbot disapprove architecture` to remove an approval you gave earlier
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@flink.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk commented on a change in pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r603166896


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/SchedulingPipelinedRegion.java
##########
@@ -23,10 +23,19 @@
 import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
 import org.apache.flink.runtime.topology.PipelinedRegion;

+import java.util.List;
+
 /** Pipelined region on execution level, i.e., {@link ExecutionGraph} level. */
 public interface SchedulingPipelinedRegion
         extends PipelinedRegion<
                 ExecutionVertexID,
                 IntermediateResultPartitionID,
                 SchedulingExecutionVertex,
-                SchedulingResultPartition> {}
+                SchedulingResultPartition> {
+    /**
+     * Get all blocking {@link ConsumedPartitionGroup}s.
+     *
+     * @return list of {@link ConsumedPartitionGroup}s
+     */
+    List<ConsumedPartitionGroup> getAllBlockingConsumedPartitionGroups();

Review comment:
       >> I'm wondering should we change SchedulingExecutionVertex#getConsumedPartitionGroups and SchedulingResultPartition#getConsumerVertexGroups into Iterable
   As long as it is not causing problems, I think it's fine to keep them as is. `getAllBlockingConsumedPartitionGroups ()` should not return a list because it is just complicating things (one have to convert a set to a list).

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/SchedulingPipelinedRegion.java
##########
@@ -23,10 +23,19 @@
 import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
 import org.apache.flink.runtime.topology.PipelinedRegion;

+import java.util.List;
+
 /** Pipelined region on execution level, i.e., {@link ExecutionGraph} level. */
 public interface SchedulingPipelinedRegion
         extends PipelinedRegion<
                 ExecutionVertexID,
                 IntermediateResultPartitionID,
                 SchedulingExecutionVertex,
-                SchedulingResultPartition> {}
+                SchedulingResultPartition> {
+    /**
+     * Get all blocking {@link ConsumedPartitionGroup}s.
+     *
+     * @return list of {@link ConsumedPartitionGroup}s
+     */
+    List<ConsumedPartitionGroup> getAllBlockingConsumedPartitionGroups();

Review comment:
       >> I'm wondering should we change SchedulingExecutionVertex#getConsumedPartitionGroups and SchedulingResultPartition#getConsumerVertexGroups into Iterable

   As long as it is not causing problems, I think it's fine to keep them as is. `getAllBlockingConsumedPartitionGroups ()` should not return a list because it is just complicating things (one have to convert a set to a list).


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] Thesharing commented on a change in pull request #15310: [FLINK-21330] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
Thesharing commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r600139119


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -62,21 +85,34 @@ public DefaultExecutionVertex getVertex(final ExecutionVertexID vertexId) {

     @Override
     public Iterable<DefaultResultPartition> getConsumedResults() {
-        if (consumedResults == null) {
+        if (consumedPartitionGroups == null) {
             initializeConsumedResults();
         }
-        return consumedResults;
+        return () -> flatMap(consumedPartitionGroups, resultPartitionRetriever);
     }

     private void initializeConsumedResults() {
-        final Set<DefaultResultPartition> consumedResults = new HashSet<>();
+        final Set<ConsumedPartitionGroup> consumedResultGroupSet = new HashSet<>();

Review comment:
       consumedResultGroupSet --> consumedPartitionGroupSet


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] Thesharing commented on a change in pull request #15310: [FLINK-21330] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
Thesharing commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r600139542


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -49,12 +51,12 @@

     private final DeploymentOption deploymentOption = new DeploymentOption(false);

-    /** Result partitions are correlated if they have the same result id. */
-    private final Map<IntermediateDataSetID, Set<SchedulingResultPartition>>
-            correlatedResultPartitions = new HashMap<>();
+    /** ConsumedPartitionGroups are correlated if they have the same result id. */
+    private final Map<IntermediateDataSetID, Set<ConsumedPartitionGroup>>
+            correlatedResultPartitionGroups = new HashMap<>();

Review comment:
       correlatedResultPartitionGroups --> correlatedConsumedPartitionGroups


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     }, {
       "hash" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * dcbc4d6f9efcd5e5d70f224862be38963e1fab63 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233)
   * 64018c1e754c5f5754395491d6731b7e8893fb25 UNKNOWN

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk closed pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk closed pull request #15310:
URL: https://github.com/apache/flink/pull/15310


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] Thesharing commented on a change in pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
Thesharing commented on a change in pull request #15310:
URL: https://github.com/apache/flink/pull/15310#discussion_r602992946


##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/SchedulingPipelinedRegion.java
##########
@@ -23,10 +23,19 @@
 import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
 import org.apache.flink.runtime.topology.PipelinedRegion;

+import java.util.List;
+
 /** Pipelined region on execution level, i.e., {@link ExecutionGraph} level. */
 public interface SchedulingPipelinedRegion
         extends PipelinedRegion<
                 ExecutionVertexID,
                 IntermediateResultPartitionID,
                 SchedulingExecutionVertex,
-                SchedulingResultPartition> {}
+                SchedulingResultPartition> {
+    /**
+     * Get all blocking {@link ConsumedPartitionGroup}s.
+     *
+     * @return list of {@link ConsumedPartitionGroup}s
+     */
+    List<ConsumedPartitionGroup> getAllBlockingConsumedPartitionGroups();

Review comment:
       Resolved. I'm wondering should we change `SchedulingExecutionVertex#getConsumedPartitionGroups` and `SchedulingResultPartition#getConsumerVertexGroups` into `Iterable`, too?

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -19,30 +19,51 @@

 package org.apache.flink.runtime.scheduler.adapter;

+import org.apache.flink.annotation.VisibleForTesting;
+import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
+import org.apache.flink.runtime.scheduler.strategy.ConsumedPartitionGroup;
 import org.apache.flink.runtime.scheduler.strategy.ExecutionVertexID;
 import org.apache.flink.runtime.scheduler.strategy.SchedulingPipelinedRegion;
+import org.apache.flink.runtime.scheduler.strategy.SchedulingResultPartition;
 import org.apache.flink.util.Preconditions;

+import java.util.ArrayList;
 import java.util.Collections;
 import java.util.HashMap;
 import java.util.HashSet;
+import java.util.List;
 import java.util.Map;
 import java.util.Set;
+import java.util.function.Function;

 /** Default implementation of {@link SchedulingPipelinedRegion}. */
 public class DefaultSchedulingPipelinedRegion implements SchedulingPipelinedRegion {

     private final Map<ExecutionVertexID, DefaultExecutionVertex> executionVertices;

-    private Set<DefaultResultPartition> consumedResults;
+    private List<ConsumedPartitionGroup> blockingConsumedPartitionGroups;
+
+    private final Function<IntermediateResultPartitionID, DefaultResultPartition>
+            resultPartitionRetriever;
+
+    public DefaultSchedulingPipelinedRegion(
+            Set<DefaultExecutionVertex> defaultExecutionVertices,
+            Function<IntermediateResultPartitionID, DefaultResultPartition>
+                    resultPartitionRetriever) {

-    public DefaultSchedulingPipelinedRegion(Set<DefaultExecutionVertex> defaultExecutionVertices) {
         Preconditions.checkNotNull(defaultExecutionVertices);

         this.executionVertices = new HashMap<>();
         for (DefaultExecutionVertex executionVertex : defaultExecutionVertices) {
             this.executionVertices.put(executionVertex.getId(), executionVertex);
         }
+
+        this.resultPartitionRetriever = resultPartitionRetriever;

Review comment:
       Thanks for reminding. Added.

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingPipelinedRegion.java
##########
@@ -30,15 +33,24 @@
     private final Map<ExecutionVertexID, TestingSchedulingExecutionVertex> regionVertices =
             new HashMap<>();

-    private final Set<TestingSchedulingResultPartition> consumedPartitions = new HashSet<>();
+    private final List<ConsumedPartitionGroup> consumedPartitionGroups = new ArrayList<>();

Review comment:
       Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/SchedulingStrategyUtils.java
##########
@@ -31,7 +31,7 @@
 import java.util.stream.Collectors;

 /** Utils for {@link SchedulingStrategy}. */
-class SchedulingStrategyUtils {
+public class SchedulingStrategyUtils {

Review comment:
       Sorry that I forget to remove it since I removed the methods added in the previous commits. Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {

Review comment:
       Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -19,30 +19,51 @@

 package org.apache.flink.runtime.scheduler.adapter;

+import org.apache.flink.annotation.VisibleForTesting;
+import org.apache.flink.runtime.jobgraph.IntermediateResultPartitionID;
+import org.apache.flink.runtime.scheduler.strategy.ConsumedPartitionGroup;
 import org.apache.flink.runtime.scheduler.strategy.ExecutionVertexID;
 import org.apache.flink.runtime.scheduler.strategy.SchedulingPipelinedRegion;
+import org.apache.flink.runtime.scheduler.strategy.SchedulingResultPartition;
 import org.apache.flink.util.Preconditions;

+import java.util.ArrayList;
 import java.util.Collections;
 import java.util.HashMap;
 import java.util.HashSet;
+import java.util.List;
 import java.util.Map;
 import java.util.Set;
+import java.util.function.Function;

 /** Default implementation of {@link SchedulingPipelinedRegion}. */
 public class DefaultSchedulingPipelinedRegion implements SchedulingPipelinedRegion {

     private final Map<ExecutionVertexID, DefaultExecutionVertex> executionVertices;

-    private Set<DefaultResultPartition> consumedResults;
+    private List<ConsumedPartitionGroup> blockingConsumedPartitionGroups;
+
+    private final Function<IntermediateResultPartitionID, DefaultResultPartition>
+            resultPartitionRetriever;
+
+    public DefaultSchedulingPipelinedRegion(
+            Set<DefaultExecutionVertex> defaultExecutionVertices,
+            Function<IntermediateResultPartitionID, DefaultResultPartition>
+                    resultPartitionRetriever) {

-    public DefaultSchedulingPipelinedRegion(Set<DefaultExecutionVertex> defaultExecutionVertices) {
         Preconditions.checkNotNull(defaultExecutionVertices);

         this.executionVertices = new HashMap<>();
         for (DefaultExecutionVertex executionVertex : defaultExecutionVertices) {
             this.executionVertices.put(executionVertex.getId(), executionVertex);
         }
+
+        this.resultPartitionRetriever = resultPartitionRetriever;
+    }
+
+    @VisibleForTesting
+    public DefaultSchedulingPipelinedRegion(Set<DefaultExecutionVertex> defaultExecutionVertices) {

Review comment:
       Agreed. Removed.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/adapter/DefaultSchedulingPipelinedRegion.java
##########
@@ -60,23 +81,33 @@ public DefaultExecutionVertex getVertex(final ExecutionVertexID vertexId) {
         return executionVertex;
     }

-    @Override
-    public Iterable<DefaultResultPartition> getConsumedResults() {
-        if (consumedResults == null) {
-            initializeConsumedResults();
-        }
-        return consumedResults;
-    }
-
-    private void initializeConsumedResults() {
-        final Set<DefaultResultPartition> consumedResults = new HashSet<>();
+    private void initializeAllBlockingConsumedPartitionGroups() {
+        final Set<ConsumedPartitionGroup> consumedResultGroupSet = new HashSet<>();
         for (DefaultExecutionVertex executionVertex : executionVertices.values()) {
-            for (DefaultResultPartition resultPartition : executionVertex.getConsumedResults()) {
-                if (!executionVertices.containsKey(resultPartition.getProducer().getId())) {
-                    consumedResults.add(resultPartition);
+            for (ConsumedPartitionGroup consumedResultGroup :
+                    executionVertex.getConsumedPartitionGroups()) {
+                SchedulingResultPartition resultPartition =
+                        resultPartitionRetriever.apply(consumedResultGroup.getFirst());
+                if (resultPartition.getResultType().isBlocking()) {
+                    consumedResultGroupSet.add(consumedResultGroup);
                 }
             }
         }
-        this.consumedResults = Collections.unmodifiableSet(consumedResults);
+
+        this.blockingConsumedPartitionGroups =

Review comment:
       Agreed. Resolved.

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingResultPartition.java
##########
@@ -47,12 +47,16 @@

     private ResultPartitionState state;

-    TestingSchedulingResultPartition(
-            IntermediateDataSetID dataSetID, ResultPartitionType type, ResultPartitionState state) {
+    private TestingSchedulingResultPartition(
+            IntermediateDataSetID dataSetID,
+            int partitionNum,

Review comment:
       `testNotifyingBlockingResultPartitionProducerFinished` and `testFinishedBlockingResultPartitionProducerDoNotScheduleNonCreatedRegions` in `PipelinedRegionSchedulingStrategyTest`.

   I prefer this should be changed since the `correlatedResultPartitionGroups`  in `PipelinedRegionSchedulingStrategy` use `IntermediateDataSetID` as key. It's more reasonable to make `IntermediateResultPartitionID` has the same `IntermediateDataSetID`.

##########
File path: flink-runtime/src/test/java/org/apache/flink/runtime/scheduler/strategy/TestingSchedulingPipelinedRegion.java
##########
@@ -30,15 +33,24 @@
     private final Map<ExecutionVertexID, TestingSchedulingExecutionVertex> regionVertices =
             new HashMap<>();

-    private final Set<TestingSchedulingResultPartition> consumedPartitions = new HashSet<>();
+    private final List<ConsumedPartitionGroup> consumedPartitionGroups = new ArrayList<>();
+
+    private final Map<IntermediateResultPartitionID, TestingSchedulingResultPartition>

Review comment:
       Changed this field into a local variable.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -49,16 +50,21 @@

     private final DeploymentOption deploymentOption = new DeploymentOption(false);

-    /** Result partitions are correlated if they have the same result id. */
-    private final Map<IntermediateDataSetID, Set<SchedulingResultPartition>>
-            correlatedResultPartitions = new HashMap<>();
+    /** ConsumedPartitionGroups are correlated if they have the same result id. */
+    private final Map<IntermediateDataSetID, Set<ConsumedPartitionGroup>>
+            correlatedResultPartitionGroups = new HashMap<>();

-    private final Map<IntermediateResultPartitionID, Set<SchedulingPipelinedRegion>>
-            partitionConsumerRegions = new HashMap<>();
+    /** External consumer regions of each ConsumedPartitionGroup. */
+    private final Map<ConsumedPartitionGroup, Set<SchedulingPipelinedRegion>>
+            partitionGroupConsumerRegions = new HashMap<>();

     private final Map<SchedulingPipelinedRegion, List<ExecutionVertexID>> regionVerticesSorted =
             new IdentityHashMap<>();

+    /** The ConsumedPartitionGroups which have inter-region producers and inter-region producers. */
+    private final Set<ConsumedPartitionGroup> crossRegionConsumerPartitionGroups =

Review comment:
       Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/executiongraph/failover/flip1/partitionrelease/RegionPartitionReleaseStrategy.java
##########
@@ -74,7 +74,10 @@ private void initRegionExecutionViewByVertex() {
         if (regionExecutionView.isFinished()) {
             final SchedulingPipelinedRegion pipelinedRegion =
                     schedulingTopology.getPipelinedRegionOfVertex(finishedVertex);
-            return filterReleasablePartitions(pipelinedRegion.getConsumedResults());
+            return filterReleasablePartitions(

Review comment:
       This part will be improved by FLINK-21331 later. But in this PR, first, I'll make sure `getAllBlockingConsumedPartitionGroups` return `Set`. Also I'll add a `distinct()` in `filterReleasablePartitions`.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);
+                        }
+                    }
+                }
+            }
+        }
+    }
+
+    private SchedulingPipelinedRegion getProducerRegion(IntermediateResultPartitionID partitionId) {
+        return schedulingTopology.getPipelinedRegionOfVertex(
+                schedulingTopology.getResultPartition(partitionId).getProducer().getId());
+    }
+
+    private void initPartitionGroupConsumerRegions() {
+        for (SchedulingPipelinedRegion region : schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    region.getAllBlockingConsumedPartitionGroups()) {
+                if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)
+                        || isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                    partitionGroupConsumerRegions
+                            .computeIfAbsent(consumedPartitionGroup, group -> new HashSet<>())
+                            .add(region);
+                }
+            }
+        }
+    }
+
+    private void initCorrelatedResultPartitionGroups() {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                partitionGroupConsumerRegions.keySet()) {
+            for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                correlatedResultPartitionGroups
+                        .computeIfAbsent(
+                                partitionId.getIntermediateDataSetID(), id -> new HashSet<>())
+                        .add(consumedPartitionGroup);
+            }
+        }
+    }
+
     @Override
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(this::noExternalBlockingConsumedPartitions)
                         .collect(Collectors.toSet());
         maybeScheduleRegions(sourceRegions);
     }

+    private boolean noExternalBlockingConsumedPartitions(SchedulingPipelinedRegion region) {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                region.getAllBlockingConsumedPartitionGroups()) {
+            if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)

Review comment:
       I'd prefer that the region with cross-region partitions should not be scheduled like a source region. A test case has been added.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -49,16 +50,21 @@

     private final DeploymentOption deploymentOption = new DeploymentOption(false);

-    /** Result partitions are correlated if they have the same result id. */
-    private final Map<IntermediateDataSetID, Set<SchedulingResultPartition>>
-            correlatedResultPartitions = new HashMap<>();
+    /** ConsumedPartitionGroups are correlated if they have the same result id. */
+    private final Map<IntermediateDataSetID, Set<ConsumedPartitionGroup>>
+            correlatedResultPartitionGroups = new HashMap<>();

-    private final Map<IntermediateResultPartitionID, Set<SchedulingPipelinedRegion>>
-            partitionConsumerRegions = new HashMap<>();
+    /** External consumer regions of each ConsumedPartitionGroup. */
+    private final Map<ConsumedPartitionGroup, Set<SchedulingPipelinedRegion>>
+            partitionGroupConsumerRegions = new HashMap<>();

     private final Map<SchedulingPipelinedRegion, List<ExecutionVertexID>> regionVerticesSorted =
             new IdentityHashMap<>();

+    /** The ConsumedPartitionGroups which have inter-region producers and inter-region producers. */

Review comment:
       Thanks for pointing this out. Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);
+                        }
+                    }
+                }
+            }
+        }
+    }
+
+    private SchedulingPipelinedRegion getProducerRegion(IntermediateResultPartitionID partitionId) {
+        return schedulingTopology.getPipelinedRegionOfVertex(
+                schedulingTopology.getResultPartition(partitionId).getProducer().getId());
+    }
+
+    private void initPartitionGroupConsumerRegions() {
+        for (SchedulingPipelinedRegion region : schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    region.getAllBlockingConsumedPartitionGroups()) {
+                if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)
+                        || isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                    partitionGroupConsumerRegions
+                            .computeIfAbsent(consumedPartitionGroup, group -> new HashSet<>())
+                            .add(region);
+                }
+            }
+        }
+    }
+
+    private void initCorrelatedResultPartitionGroups() {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                partitionGroupConsumerRegions.keySet()) {
+            for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                correlatedResultPartitionGroups
+                        .computeIfAbsent(
+                                partitionId.getIntermediateDataSetID(), id -> new HashSet<>())
+                        .add(consumedPartitionGroup);
+            }
+        }
+    }
+
     @Override
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(this::noExternalBlockingConsumedPartitions)
                         .collect(Collectors.toSet());
         maybeScheduleRegions(sourceRegions);
     }

+    private boolean noExternalBlockingConsumedPartitions(SchedulingPipelinedRegion region) {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                region.getAllBlockingConsumedPartitionGroups()) {
+            if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)

Review comment:
       Furthermore, @zhuzhurk and I find that for the case illustrated in https://github.com/apache/flink/pull/15310#issuecomment-806018417, the region 2 won't be scheduled, even if we don't have this PR. It's because the result partition produced by the third vertex in layer 2 is not consumable since it locates in region 2. This leading to that the IntermediateDataSet it belongs to will never be consumable. And region 2 will never be scheduled. We are going to discuss this issue in a new JIRA.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);

Review comment:
       Yes. Sorry for being careless. Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -92,15 +92,82 @@ private void init() {
         }
     }

+    private void initCrossRegionConsumerPartitionGroups() {
+        Set<ConsumedPartitionGroup> visitedPartitionGroups =
+                Collections.newSetFromMap(new IdentityHashMap<>());
+
+        for (SchedulingPipelinedRegion pipelinedRegion :
+                schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    pipelinedRegion.getAllBlockingConsumedPartitionGroups()) {
+                if (!visitedPartitionGroups.contains(consumedPartitionGroup)) {
+                    visitedPartitionGroups.add(consumedPartitionGroup);
+
+                    SchedulingPipelinedRegion producerRegion = null;
+                    for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                        SchedulingPipelinedRegion region = getProducerRegion(partitionId);
+                        if (producerRegion == null) {
+                            producerRegion = region;
+                        } else if (producerRegion != region) {
+                            crossRegionConsumerPartitionGroups.add(consumedPartitionGroup);
+                        }
+                    }
+                }
+            }
+        }
+    }
+
+    private SchedulingPipelinedRegion getProducerRegion(IntermediateResultPartitionID partitionId) {
+        return schedulingTopology.getPipelinedRegionOfVertex(
+                schedulingTopology.getResultPartition(partitionId).getProducer().getId());
+    }
+
+    private void initPartitionGroupConsumerRegions() {
+        for (SchedulingPipelinedRegion region : schedulingTopology.getAllPipelinedRegions()) {
+            for (ConsumedPartitionGroup consumedPartitionGroup :
+                    region.getAllBlockingConsumedPartitionGroups()) {
+                if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)
+                        || isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                    partitionGroupConsumerRegions
+                            .computeIfAbsent(consumedPartitionGroup, group -> new HashSet<>())
+                            .add(region);
+                }
+            }
+        }
+    }
+
+    private void initCorrelatedResultPartitionGroups() {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                partitionGroupConsumerRegions.keySet()) {
+            for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+                correlatedResultPartitionGroups
+                        .computeIfAbsent(
+                                partitionId.getIntermediateDataSetID(), id -> new HashSet<>())
+                        .add(consumedPartitionGroup);
+            }
+        }
+    }
+
     @Override
     public void startScheduling() {
         final Set<SchedulingPipelinedRegion> sourceRegions =
                 IterableUtils.toStream(schedulingTopology.getAllPipelinedRegions())
-                        .filter(region -> !region.getConsumedResults().iterator().hasNext())
+                        .filter(this::noExternalBlockingConsumedPartitions)
                         .collect(Collectors.toSet());
         maybeScheduleRegions(sourceRegions);
     }

+    private boolean noExternalBlockingConsumedPartitions(SchedulingPipelinedRegion region) {

Review comment:
       Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -175,15 +246,50 @@ private void maybeScheduleRegion(final SchedulingPipelinedRegion region) {
         schedulerOperations.allocateSlotsAndDeploy(vertexDeploymentOptions);
     }

-    private boolean areRegionInputsAllConsumable(final SchedulingPipelinedRegion region) {
-        for (SchedulingResultPartition partition : region.getConsumedResults()) {
-            if (partition.getState() != ResultPartitionState.CONSUMABLE) {
+    private boolean areRegionInputsAllConsumable(
+            final SchedulingPipelinedRegion region,
+            final Map<ConsumedPartitionGroup, Boolean> consumableStatusCache) {
+        for (ConsumedPartitionGroup consumedPartitionGroup :
+                region.getAllBlockingConsumedPartitionGroups()) {
+            if (crossRegionConsumerPartitionGroups.contains(consumedPartitionGroup)) {
+                if (!isCrossRegionConsumedPartitionConsumable(consumedPartitionGroup, region)) {
+                    return false;
+                }
+            } else if (isExternalConsumedPartitionGroup(consumedPartitionGroup, region)) {
+                if (!consumableStatusCache.computeIfAbsent(
+                        consumedPartitionGroup, this::isConsumedPartitionGroupConsumable)) {
+                    return false;
+                }
+            }
+        }
+        return true;
+    }
+
+    private boolean isConsumedPartitionGroupConsumable(
+            final ConsumedPartitionGroup consumedPartitionGroup) {
+        for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+            if (schedulingTopology.getResultPartition(partitionId).getState()
+                    != ResultPartitionState.CONSUMABLE) {
                 return false;
             }
         }
         return true;
     }

+    private boolean isCrossRegionConsumedPartitionConsumable(
+            final ConsumedPartitionGroup consumedPartitionGroup,
+            final SchedulingPipelinedRegion pipelinedRegion) {
+        for (IntermediateResultPartitionID partitionId : consumedPartitionGroup) {
+            if (isExternalConsumedPartition(partitionId, pipelinedRegion)) {

Review comment:
       Thanks for pointing this out. Resolved.

##########
File path: flink-runtime/src/main/java/org/apache/flink/runtime/scheduler/strategy/PipelinedRegionSchedulingStrategy.java
##########
@@ -49,16 +50,21 @@

     private final DeploymentOption deploymentOption = new DeploymentOption(false);

-    /** Result partitions are correlated if they have the same result id. */
-    private final Map<IntermediateDataSetID, Set<SchedulingResultPartition>>
-            correlatedResultPartitions = new HashMap<>();
+    /** ConsumedPartitionGroups are correlated if they have the same result id. */
+    private final Map<IntermediateDataSetID, Set<ConsumedPartitionGroup>>
+            correlatedResultPartitionGroups = new HashMap<>();

-    private final Map<IntermediateResultPartitionID, Set<SchedulingPipelinedRegion>>
-            partitionConsumerRegions = new HashMap<>();
+    /** External consumer regions of each ConsumedPartitionGroup. */
+    private final Map<ConsumedPartitionGroup, Set<SchedulingPipelinedRegion>>
+            partitionGroupConsumerRegions = new HashMap<>();

Review comment:
       Resolved.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot commented on pull request #15310: [FLINK-21330] Optimize the initialization of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot commented on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 6a135eef1fd9441748be8446fad28ef2eec23a95 UNKNOWN

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] zhuzhurk commented on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
zhuzhurk commented on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-809569511


   Merging.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330][runtime] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     }, {
       "hash" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617",
       "triggerID" : "64018c1e754c5f5754395491d6731b7e8893fb25",
       "triggerType" : "PUSH"
     }, {
       "hash" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "0139fa9c34a9ab8d821096668ac2bae9243ea7b2",
       "triggerType" : "PUSH"
     }, {
       "hash" : "86a9297e50f050579d4a956fc4cef3253d1d87c6",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "86a9297e50f050579d4a956fc4cef3253d1d87c6",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * 64018c1e754c5f5754395491d6731b7e8893fb25 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15617)
   * 0139fa9c34a9ab8d821096668ac2bae9243ea7b2 UNKNOWN
   * 86a9297e50f050579d4a956fc4cef3253d1d87c6 UNKNOWN

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [flink] flinkbot edited a comment on pull request #15310: [FLINK-21330] Optimize the performance of PipelinedRegionSchedulingStrategy
Posted by GitBox <gi...@apache.org>.
flinkbot edited a comment on pull request #15310:
URL: https://github.com/apache/flink/pull/15310#issuecomment-803836704


   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15152",
       "triggerID" : "6a135eef1fd9441748be8446fad28ef2eec23a95",
       "triggerType" : "PUSH"
     }, {
       "hash" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233",
       "triggerID" : "dcbc4d6f9efcd5e5d70f224862be38963e1fab63",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * dcbc4d6f9efcd5e5d70f224862be38963e1fab63 Azure: [SUCCESS](https://dev.azure.com/apache-flink/98463496-1af2-4620-8eab-a2ecc1a2e6fe/_build/results?buildId=15233)

   <details>
   <summary>Bot commands</summary>
     The @flinkbot bot supports the following commands:

    - `@flinkbot run travis` re-run the last Travis build
    - `@flinkbot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org