You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@maka.apache.org by "liugddx (via GitHub)" <gi...@apache.org> on 2026/09/26 11:20:11 UTC
[PR] fix(runtime): send no output-token limit to the OpenAI Codex subscription backend [maka]
liugddx opened a new pull request, #5738:
URL: https://github.com/apache/maka/pull/5738
## Summary
The ChatGPT Codex backend rejects `max_output_tokens` with `HTTP 400 {"detail":"Unsupported parameter: max_output_tokens"}`. Two paths on `main` still send it on an `openai-codex` connection:
1. **A per-model output limit.** `modelOverrides[model].maxOutputTokens` is set from the connection's model settings. Every main turn on that model fails, and the settings page accepts and saves the value without a word (#5736).
2. **Context-overflow recovery.** After a recovery fold, the retried request is capped at `min(limit ?? 8K, 8K)`. So on Codex, even with no limit configured, a turn that reaches overflow recovery sends `max_output_tokens: 8000` and fails with the same 400.
The fix states the fact once and lets both Runtime and settings read it:
- **`providerAcceptsOutputTokenLimit`** (`core/provider-registry.ts`). It is false for the `openai-codex` runtime adapter.
- **`ModelAdapter.acceptsOutputTokenLimit()`**. When it is false, `maxOutputTokens()` returns `undefined`, so neither a configured limit nor the capacity-derived one is sent. Overflow recovery also no longer adds its 8K cap.
- **Settings.** On such a connection the model's "Maximum output" field is read-only and says why ("The ChatGPT subscription (Codex) does not accept an output limit, so Maka does not send this setting."). A value saved earlier stays visible with a warning, so the user can see that it is not applied. The same applies in the add-model dialog. Copy is in zh-CN, zh-TW and en.
A limit cannot be honoured on this backend at all, so sending it only turns a working turn into a failed one. The explicit part is in settings, where the user sees that the field does not apply, rather than in a request that the backend rejects.
Fixes #5736
## Verification
- **Real backend.** I ran a Runtime Host on a copy of a Desktop workspace with a ChatGPT-subscription connection, set `modelOverrides['gpt-6-astra'] = { maxOutputTokens: 4096 }`, and ran one streamed main turn:
| build | turn |
|---|---|
| `main` (`87fc9f69c`) | `failed`, `request_rejected`: `HTTP 400 {"detail":"Unsupported parameter: max_output_tokens"}` |
| same turn, no limit configured | `completed` |
| this branch, limit 4096 | **not yet verified.** My network route to chatgpt.com kept resetting TLS handshakes, so the patched run never reached the backend. |
With this branch, a capped Codex turn sends the same request body as the uncapped turn that completed: no `max_output_tokens`. The `model-adapter` test pins that. I'll post the real-backend result here once the route is stable.
- **Tests.** Each fails without the change:
- `provider-catalog-contract`: `providerAcceptsOutputTokenLimit` is false only for `openai-codex`, and true for an unknown provider.
- `model-adapter`: a Codex connection with a configured 4096 limit yields no limit (`maxOutputTokens()` and `maxOutputTokensForInput()` both return `undefined`), while the same override on `openai` still yields 4096.
- `overflow-reactive-recovery`: on a Codex connection with a 128K-capacity model, none of the three requests (including the post-recovery retry) carries `maxOutputTokens`. I checked that this case fails with the old recovery line restored.
- Results: core 12/12, `model-adapter` 37/37, `overflow-reactive-recovery` 60/60.
- Checks: `tsc --noEmit` for `@maka/runtime` and `apps/desktop`, `biome check` on the changed files, and `check-locale-hygiene --base upstream/main` all pass.
- **UI.** Storybook `Product/Settings/Providers › O Auth Connections Disambiguated`, Codex connection → *Configure model parameters: GPT-6 Astra*, with the field hovered.
| Before | After |
|---|---|
| 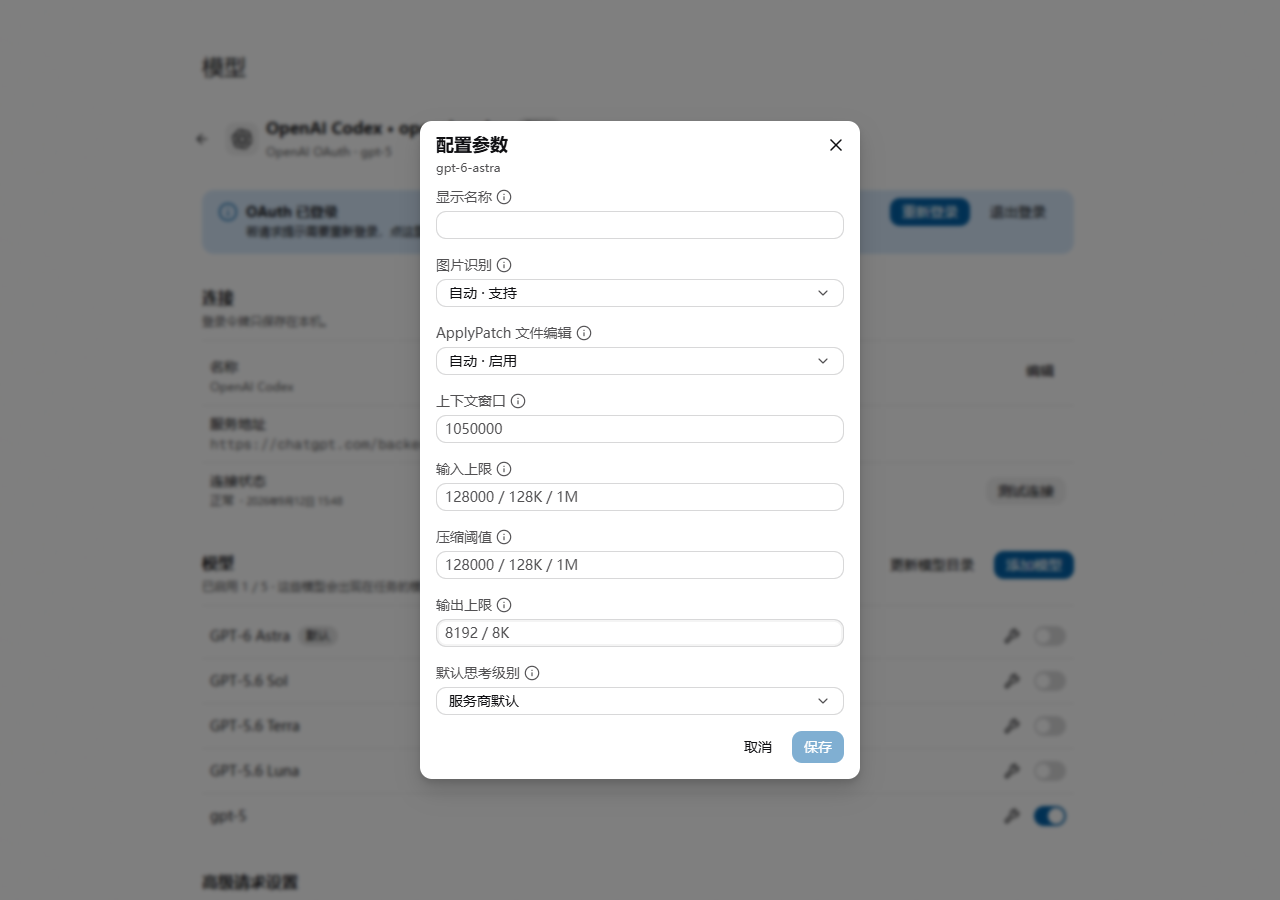 | 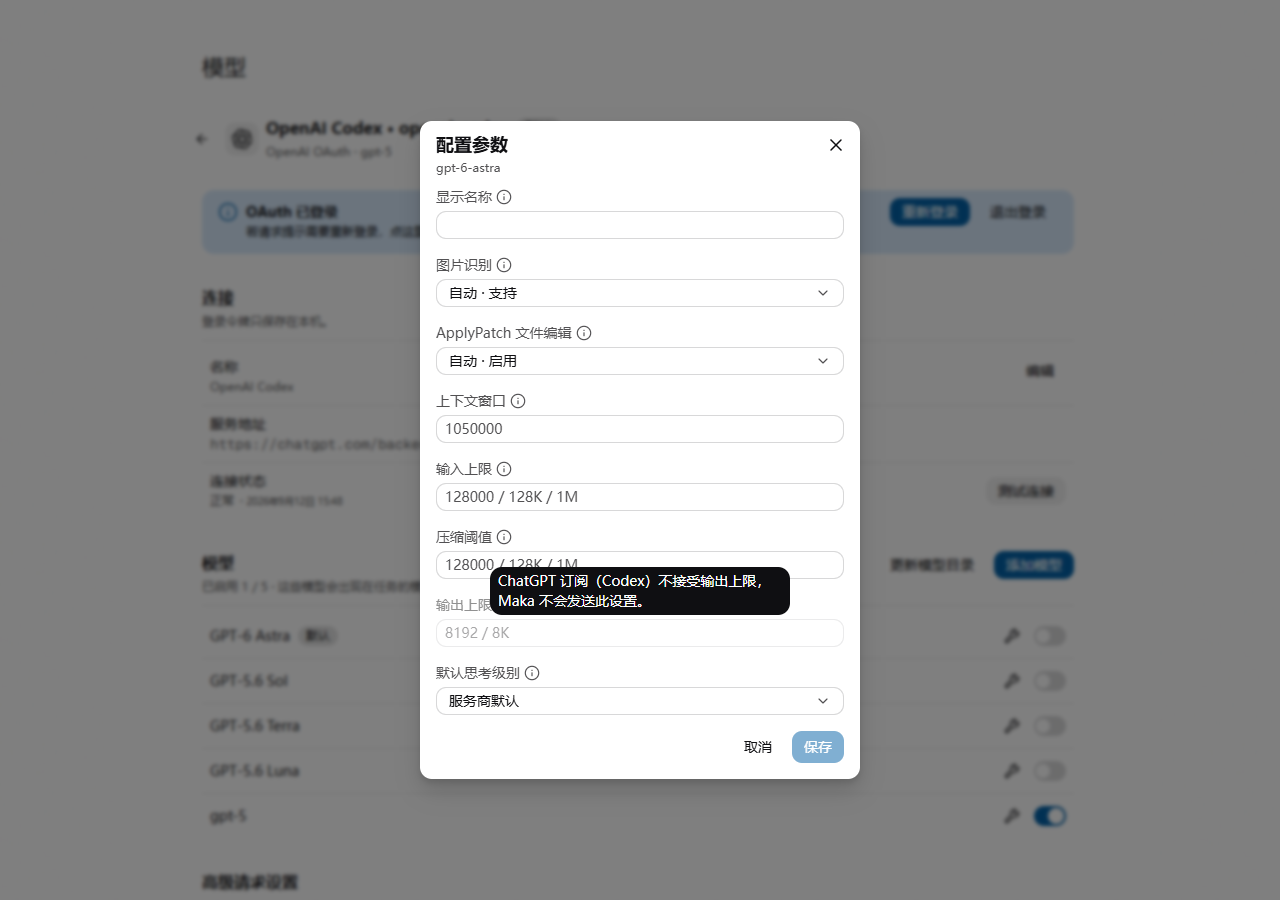 |
- The pre-commit hook cannot run on this Windows machine: `biome.cmd` fails under `spawnSync` with `EINVAL`. I ran its steps manually.
## Review focus
- **Relation to #5723.** #5723 drops `max_output_tokens` inside the Codex fetch adapter, but only for auxiliary (`generateText`) calls. Those calls pass their cap directly rather than through `ModelAdapter`. It forwards main turns unchanged. This PR stops main turns from producing the cap at all. The two do not overlap. Once both land, auxiliary calls could read `providerAcceptsOutputTokenLimit` too, so the rule has a single site. I've left that as a follow-up rather than coupling the two PRs.
## AI use
- [ ] No generative tool made a substantive contribution
- [x] Generative tooling made a substantive contribution
Tool(s) and scope: Claude Code (Claude Opus) reproduced the failure against the real backend, implemented the change and tests, and ran the verification above; liugddx reviewed. The commit carries a `Generated-by` trailer.
## Checklist
- [x] Tests cover the change and fail without it
- [x] Lint, format, typecheck and the affected suites pass locally
Does this PR entail a change in behavior?
- [x] Yes — described under Summary above
- [ ] No
🤖 Generated with [Claude Code](https://claude.com/claude-code)
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org
Re: [PR] fix(runtime): send no output-token limit to the OpenAI Codex subscription backend [maka]
Posted by "liugddx (via GitHub)" <gi...@apache.org>.
liugddx commented on code in PR #5738:
URL: https://github.com/apache/maka/pull/5738#discussion_r4111679235


##########
packages/runtime/src/model-adapter.ts:
##########
@@ -217,7 +218,17 @@ export class ModelAdapter {
     });
   }

+  /**
+   * Whether a request to this connection may carry an output-token limit at
+   * all. When it may not, no limit is sent: neither a configured per-model
+   * limit nor the context-recovery cap.
+   */
+  acceptsOutputTokenLimit(): boolean {
+    return providerAcceptsOutputTokenLimit(this.input.connection.providerType);
+  }
+
   maxOutputTokens(): number | undefined {
+    if (!this.acceptsOutputTokenLimit()) return undefined;

Review Comment:
   Confirmed, thanks. When its caller passed no limit, `ModelAdapter.startStream` fell back to `selectedModelMaxOutputTokens(...)` directly. The guard in `maxOutputTokens()` / `maxOutputTokensForInput()` never saw that path, so a Codex turn still sent the configured 4096.

   Fixed in cad717b58. The check now sits at the one place a main-turn limit reaches the wire: `startStream` sends no `maxOutputTokens` when `acceptsOutputTokenLimit()` is false, whether the value came from the caller or from the model configuration. Because of that, overflow recovery needs no special case, so I reverted the `ai-sdk-turn.ts` change; this PR no longer touches that file.

   Tests:
   - New `model-adapter` case that goes through `startStream` into a `MockLanguageModelV4`. It asserts what reaches `doStream`: on `openai-codex` with a 4096 override, nothing, both with no caller limit and with a caller-supplied 8000. On `openai`, 4096 and 8000 respectively.
   - The existing Codex overflow-recovery case now passes through the adapter alone.
   - Both fail when the gate is removed, and pass with it.
   - `model-adapter` 38/38, `overflow-reactive-recovery` 60/60, `mid-turn-capacity-backend` 68/68; runtime `tsc` passes.

   On the red CI: I can't read the job log from here (the log download is blocked on my network), so thanks for naming `opencli-chrome.test.js`. That test covers the Windows Chrome Web Store launch path, which this PR does not touch. Other unrelated PRs went red around the same time, so I'll see whether it reproduces on this push.

   On #5723: agreed with your reading. Neither PR alone fixes both call paths.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org
Re: [PR] fix(runtime): send no output-token limit to the OpenAI Codex subscription backend [maka]
Posted by "liugddx (via GitHub)" <gi...@apache.org>.
liugddx merged PR #5738:
URL: https://github.com/apache/maka/pull/5738


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org
Re: [PR] fix(runtime): send no output-token limit to the OpenAI Codex subscription backend [maka]
Posted by "hqhq1025 (via GitHub)" <gi...@apache.org>.
hqhq1025 commented on code in PR #5738:
URL: https://github.com/apache/maka/pull/5738#discussion_r4111469030


##########
packages/runtime/src/model-adapter.ts:
##########
@@ -217,7 +218,17 @@ export class ModelAdapter {
     });
   }

+  /**
+   * Whether a request to this connection may carry an output-token limit at
+   * all. When it may not, no limit is sent: neither a configured per-model
+   * limit nor the context-recovery cap.
+   */
+  acceptsOutputTokenLimit(): boolean {
+    return providerAcceptsOutputTokenLimit(this.input.connection.providerType);
+  }
+
   maxOutputTokens(): number | undefined {
+    if (!this.acceptsOutputTokenLimit()) return undefined;

Review Comment:
   P1: This guard does not protect the actual streamed request. `startStream()` at lines 288-295 uses `input.maxOutputTokens ?? selectedModelMaxOutputTokens(...)` instead of this guarded method. When `AiSdkTurn` omits the limit for `openai-codex`, that fallback recalculates the configured override and passes it to `streamText` (line 382). On this head, a Codex adapter with a 4096 override reports `maxOutputTokensForInput() === undefined`, but a direct `startStream()` probe observes `doStream.maxOutputTokens === 4096`. The streamed Codex request therefore still carries the backend-rejected limit. Gate this fallback as well, and test the final `doStream`/wire request rather than only the helper return value.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org