You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@druid.apache.org by GitBox <gi...@apache.org> on 2021/12/21 11:43:31 UTC
[GitHub] [druid] yannuokiss opened a new issue #12086: ingest data from s3
yannuokiss opened a new issue #12086:
URL: https://github.com/apache/druid/issues/12086


   Please provide a detailed title (e.g. "Broker crashes when using TopN query with Bound filter" instead of just "Broker crashes").

   ### Affected Version

   The Druid version is 0.22.1

   ### Description
   api druid/indexer/v1/task
   {
       "type": "index_hadoop",
       "spec": {
           "dataSchema": {
               "metricsSpec": [
                   {
                       "type": "count",
                       "name": "count"
                   }
               ],
               "granularitySpec": {
                   "queryGranularity": "day",
                   "segmentGranularity": "day",
                   "type": "uniform",
                   "intervals": [
                       "2021-01-01T00:00:00+00:00/2022-01-01T00:00:00+00:00"
                   ]
               },
               "parser": {
                   "parseSpec": {
                       "dimensionsSpec": {
                           "dimensions": [
                               dimensions
                           ]
                       },
                       "timestampSpec": {
                           "column": "startDate",
                           "format": "millis"
                       },
                       "columns": [
                           columns
                       ],
                       "format": "csv"
                   },
                   "type": "hadoopyString"
               },
               "dataSource": "test"
           },
           "tuningConfig": {
               "jobProperties": {
                   "fs.s3.impl": "com.amazon.ws.emr.hadoop.fs.EmrFileSystem",
                   "fs.s3n.awsSecretAccessKey": "xxx",
                   "fs.s3.awsAccessKeyId": "xxx",
                   "mapreduce.reduce.shuffle.memory.limit.percent": "0.1",
                   "io.compression.codecs": "org.apache.hadoop.io.compress.GzipCodec,org.apache.hadoop.io.compress.DefaultCodec,org.apache.hadoop.io.compress.BZip2Codec,org.apache.hadoop.io.compress.SnappyCodec",
                   "fs.s3.awsSecretAccessKey": "xxx",
                   "fs.s3n.awsAccessKeyId": "xxx",
                   "fs.s3n.impl": "com.amazon.ws.emr.hadoop.fs.EmrFileSystem",
                   "mapreduce.job.classloader": "true"
               },
               "type": "hadoop",
               "partitionsSpec": {
                   "type": "hashed",
                   "targetPartitionSize": 5000000
               }
           },
           "ioConfig": {
               "inputSpec": {
                   "paths": "s3:///data//druiddatasource//*.csv",
                   "type": "static"
               },
               "type": "hadoop"
           }
       },
       "hadoopDependencyCoordinates": [
           "org.apache.hadoop:hadoop-client:2.8.5",
           "org.apache.hadoop:hadoop-aws:2.8.5"
       ]
   }

   log
   {
     "ingestionState": "DETERMINE_PARTITIONS",
     "unparseableEvents": null,
     "rowStats": {},
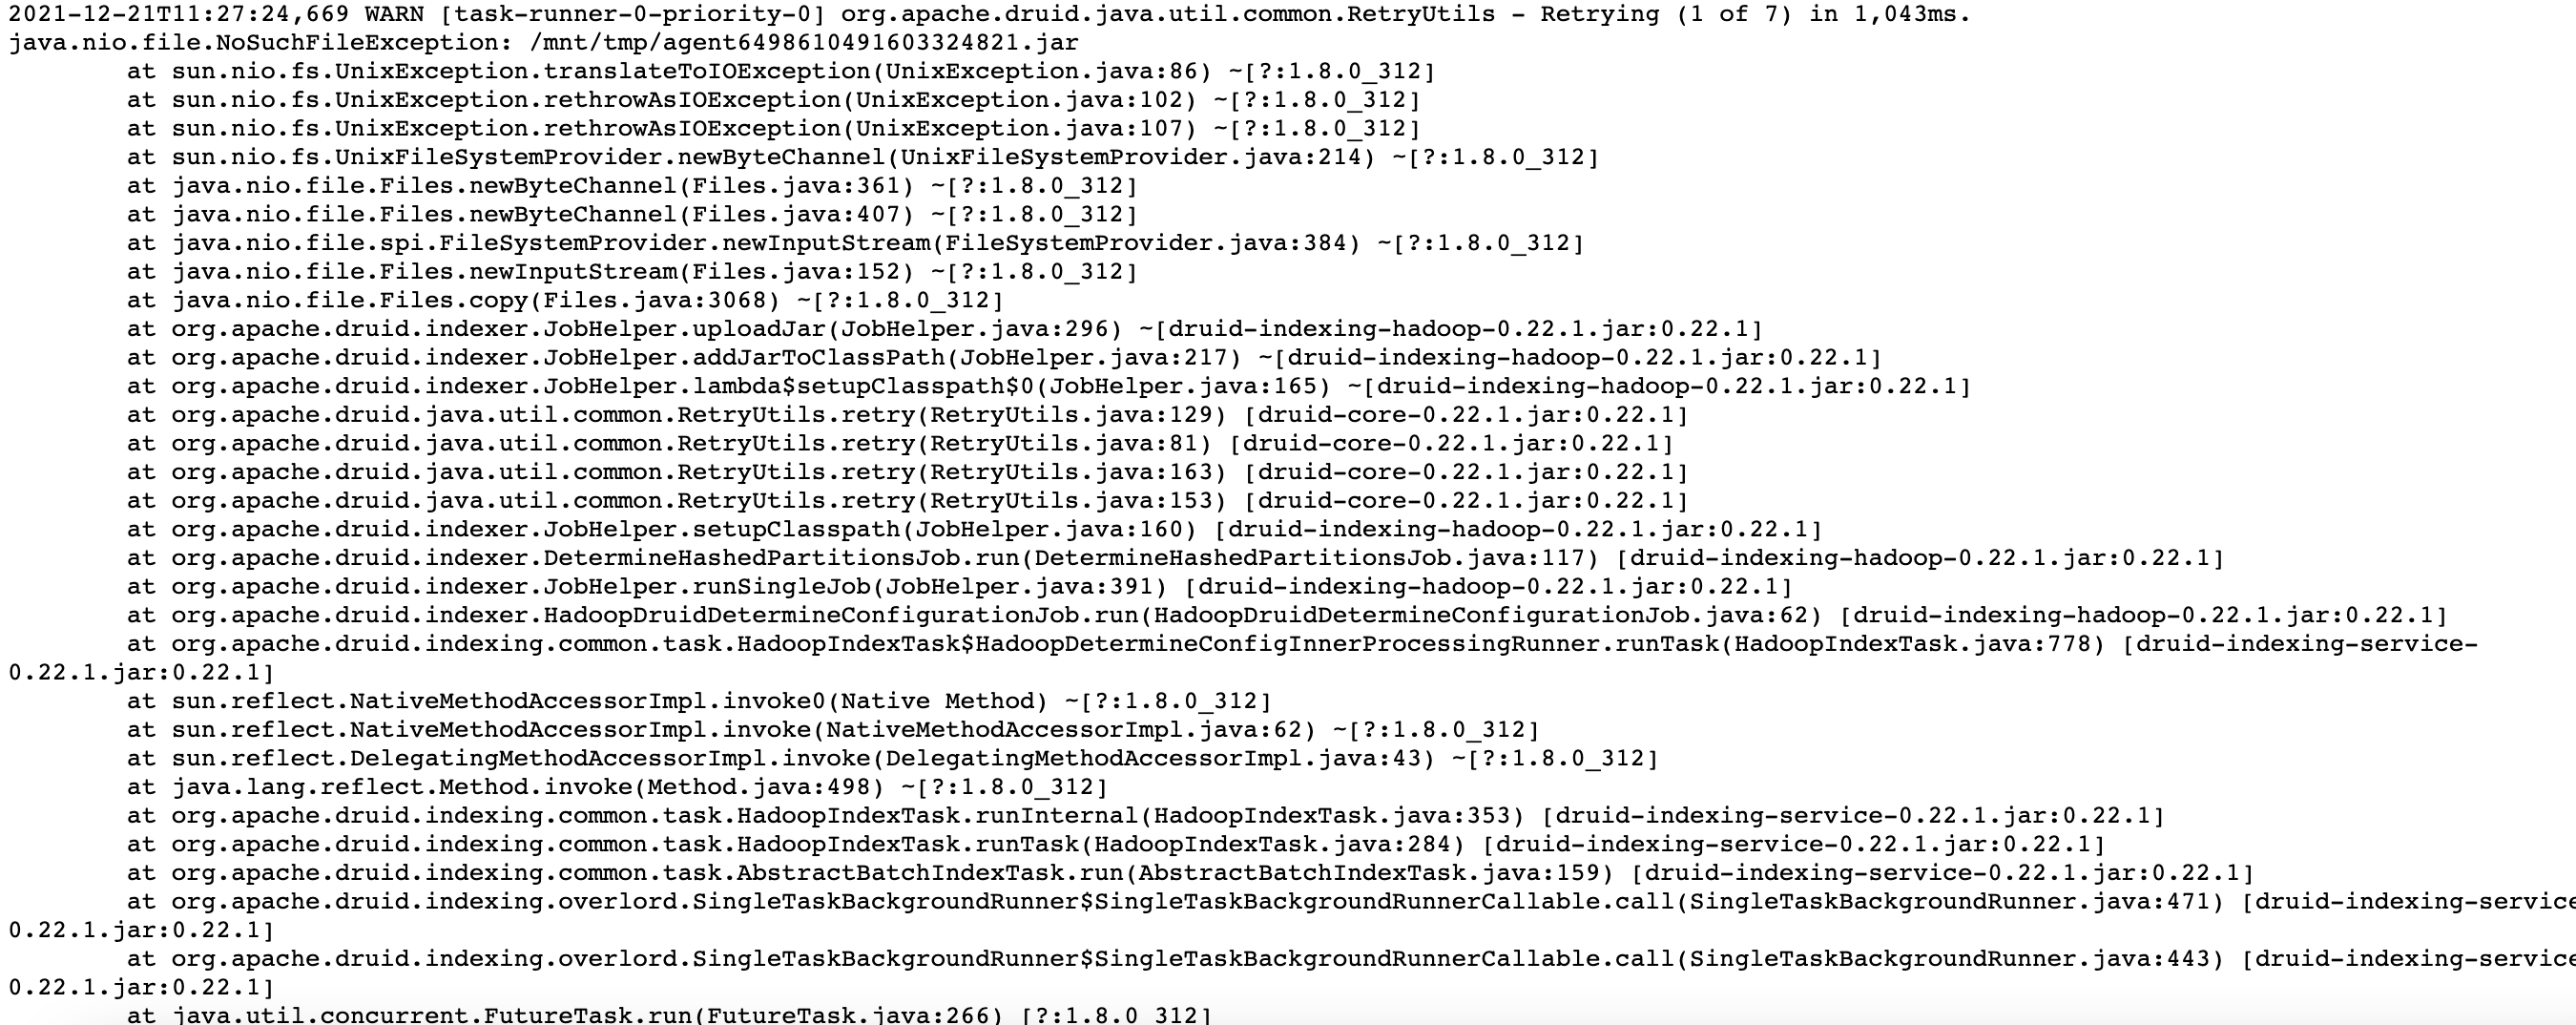
     "errorMsg": "java.lang.RuntimeException: java.lang.RuntimeException: java.nio.file.NoSuchFileException: /mnt/tmp/agent6498610491603324821.jar\n\tat org.apache.druid.indexer.DetermineHashedPartitionsJob.run(DetermineHashedPartitionsJob.java:241)\n\tat org.apache.druid.indexer.JobHelper.runSingleJob(JobHelper.java:391)\n\tat org.apache.druid.indexer.HadoopDruidDetermineConfigurationJob.run(HadoopDruidDetermineConfigurationJob.java:62)\n\tat org.apache.druid.indexing.common.task.HadoopIndexTask$HadoopDetermineConfigInnerProcessingRunner.runTask(HadoopIndexTask.java:778)\n\tat sun.reflect.NativeMethodAccessorImpl.invoke0(Native Method)\n\tat sun.reflect.NativeMethodAccessorImpl.invoke(NativeMethodAccessorImpl.java:62)\n\tat sun.reflect.DelegatingMethodAccessorImpl.invoke(DelegatingMethodAccessorImpl.java:43)\n\tat java.lang.reflect.Method.invoke(Method.java:498)\n\tat org.apache.druid.indexing.common.task.HadoopIndexTask.runInternal(HadoopIndexTask.java:353)\n\tat org.apache.druid.i
 ndexing.common.task.HadoopIndexTask.runTask(HadoopIndexTask.java:284)\n\tat org.apache.druid.indexing.common.task.AbstractBatchIndexTask.run(AbstractBatchIndexTask.java:159)\n\tat org.apache.druid.indexing.overlord.SingleTaskBackgroundRunner$SingleTaskBackgroundRunnerCallable.call(SingleTaskBackgroundRunner.java:471)\n\tat org.apache.druid.indexing.overlord.SingleTaskBackgroundRunner$SingleTaskBackgroundRunnerCallable.call(SingleTaskBackgroundRunner.java:443)\n\tat java.util.concurrent.FutureTask.run(FutureTask.java:266)\n\tat java.util.concurrent.ThreadPoolExecutor.runWorker(ThreadPoolExecutor.java:1149)\n\tat java.util.concurrent.ThreadPoolExecutor$Worker.run(ThreadPoolExecutor.java:624)\n\tat java.lang.Thread.run(Thread.java:748)\nCaused by: java.lang.RuntimeException: java.nio.file.NoSuchFileException: /mnt/tmp/agent6498610491603324821.jar\n\tat org.apache.druid.indexer.JobHelper.setupClasspath(JobHelper.java:174)\n\tat org.apache.druid.indexer.DetermineHashedPartitionsJob.run(D
 etermineHashedPartitionsJob.java:117)\n\t... 16 more\nCaused by: java.nio.file.NoSuchFileException: /mnt/tmp/agent6498610491603324821.jar\n\tat sun.nio.fs.UnixException.translateToIOException(UnixException.java:86)\n\tat sun.nio.fs.UnixException.rethrowAsIOException(UnixException.java:102)\n\tat sun.nio.fs.UnixException.rethrowAsIOException(UnixException.java:107)\n\tat sun.nio.fs.UnixFileSystemProvider.newByteChannel(UnixFileSystemProvider.java:214)\n\tat java.nio.file.Files.newByteChannel(Files.java:361)\n\tat java.nio.file.Files.newByteChannel(Files.java:407)\n\tat java.nio.file.spi.FileSystemProvider.newInputStream(FileSystemProvider.java:384)\n\tat java.nio.file.Files.newInputStream(Files.java:152)\n\tat java.nio.file.Files.copy(Files.java:3068)\n\tat org.apache.druid.indexer.JobHelper.uploadJar(JobHelper.java:296)\n\tat org.apache.druid.indexer.JobHelper.addJarToClassPath(JobHelper.java:217)\n\tat org.apache.druid.indexer.JobHelper.lambda$setupClasspath$0(JobHelper.java:165)\n
 \tat org.apache.druid.java.util.common.RetryUtils.retry(RetryUtils.java:129)\n\tat org.apache.druid.java.util.common.RetryUtils.retry(RetryUtils.java:81)\n\tat org.apache.druid.java.util.common.RetryUtils.retry(RetryUtils.java:163)\n\tat org.apache.druid.java.util.common.RetryUtils.retry(RetryUtils.java:153)\n\tat org.apache.druid.indexer.JobHelper.setupClasspath(JobHelper.java:160)\n\t... 17 more\n",
     "segmentAvailabilityConfirmed": false
   }


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org
For additional commands, e-mail: commits-help@druid.apache.org
[GitHub] [druid] yannuokiss closed issue #12086: ingest data from s3
Posted by GitBox <gi...@apache.org>.
yannuokiss closed issue #12086:
URL: https://github.com/apache/druid/issues/12086


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org
For additional commands, e-mail: commits-help@druid.apache.org
[GitHub] [druid] yannuokiss commented on issue #12086: ingest data from s3
Posted by GitBox <gi...@apache.org>.
yannuokiss commented on issue #12086:
URL: https://github.com/apache/druid/issues/12086#issuecomment-998712599


   why loading agent.jar?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org
For additional commands, e-mail: commits-help@druid.apache.org
[GitHub] [druid] yannuokiss commented on issue #12086: ingest data from s3
Posted by GitBox <gi...@apache.org>.
yannuokiss commented on issue #12086:
URL: https://github.com/apache/druid/issues/12086#issuecomment-998712167
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@druid.apache.org
For additional commands, e-mail: commits-help@druid.apache.org