You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2022/05/09 15:57:34 UTC
[GitHub] [hudi] yangdafish opened a new issue, #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
yangdafish opened a new issue, #5541:
URL: https://github.com/apache/hudi/issues/5541
**Describe the problem you faced**
Recently, we upgraded our environment from Hudi 0.8.0 to Hudi 0.9.0, and after the upgrade we noticed that upsert jobs for some of our existing tables run much slower compared to how they ran in Hudi 0.8.0.
For our Hudi tables, we ran one bulk_insert job to ingest snapshot, and schedule an upsert job every 10 mins to ingest incremental updates after the completion of bulk_insert job.
To reproduce the issue, we ran upsert job on a table with the size around 1.8T. The job took in 11 tsv files (< 150 MB in total) containing both new records and updates.
In Hudi 0.8.0, the job took 8.5 mins to complete whereas in Hudi 0.9.0, the job took 25+ mins consistently. And we notice that the main difference seemed to come from the steps "Getting small files from partitions".
We don't upgrade to Hudi 0.10 because it is not yet supported by Redshift for our customer purposes
0.8
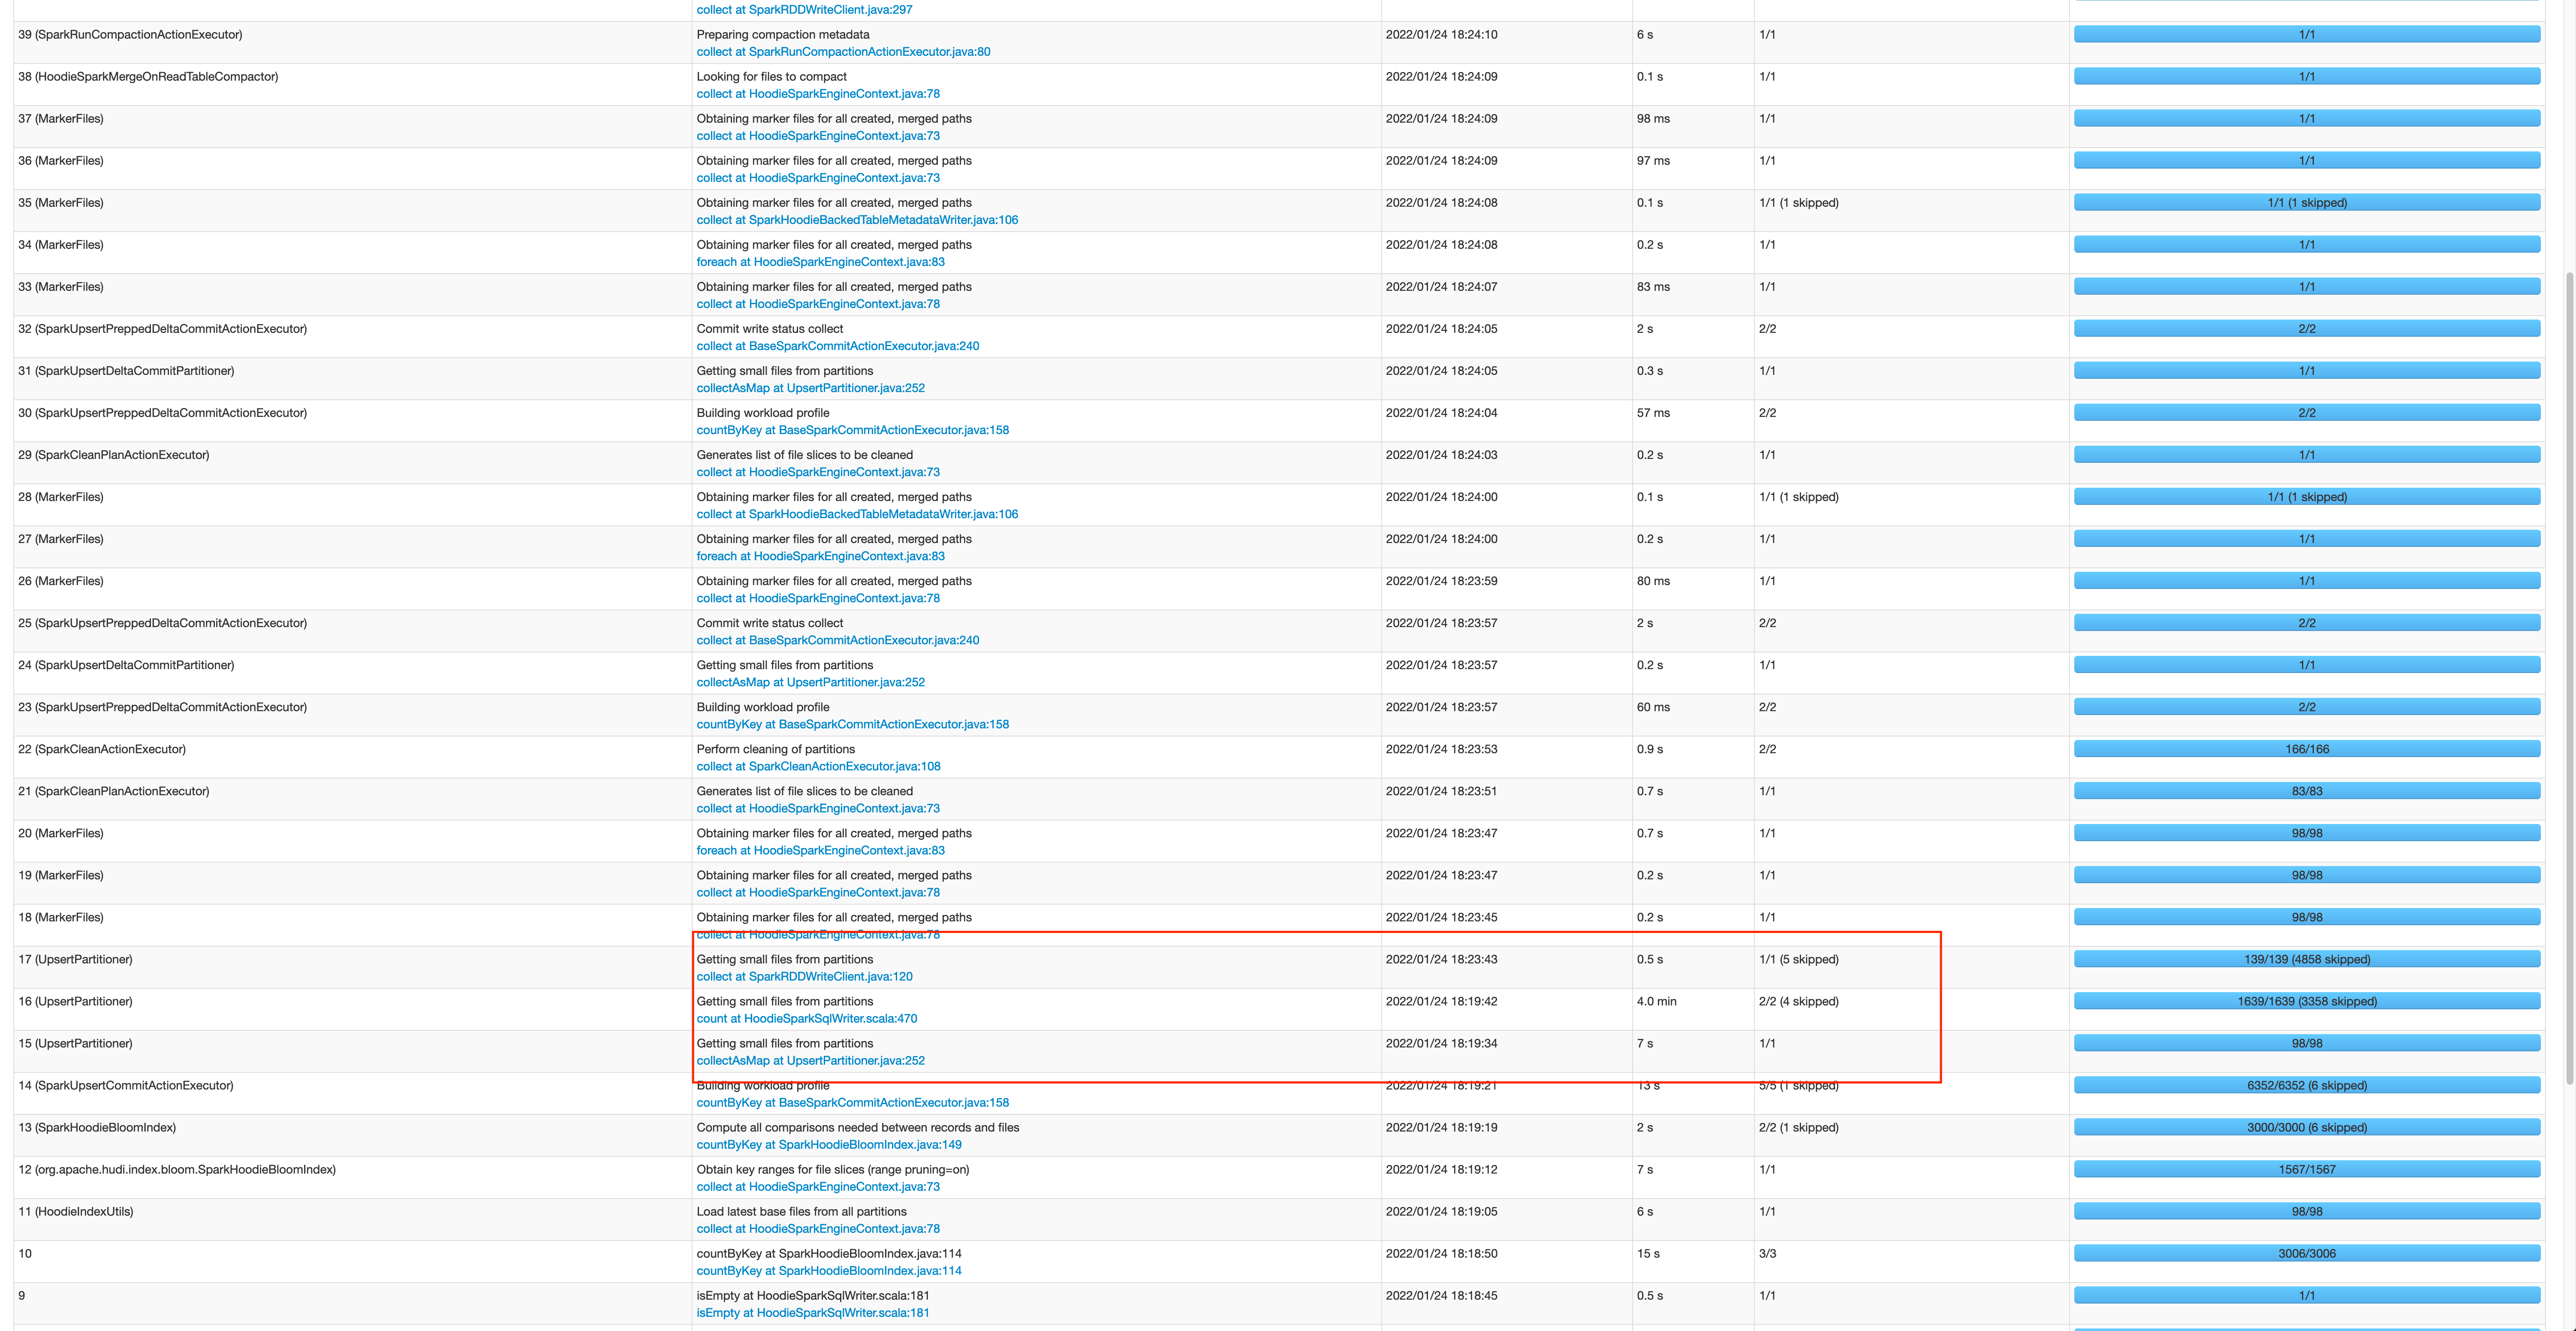
0.9
<img width="1782" alt="Screen Shot 2022-05-03 at 2 28 43 PM" src="https://user-images.githubusercontent.com/32607057/167448363-51dbdf36-44ec-4d7b-ac80-d166f8b6f656.png">
**Environment Description**
* Hudi version : 0.9.0
* Spark version : 3.1.2
* Scala version: 2.12
* Hadoop version : 2.10.1
* Storage (HDFS/S3/GCS..) : S3
* Running on Docker? (yes/no) : no
* AWS EMR: 6.55.0, 1 master(r6g.16xlarge) with 30 cores(r6g.16xlarge)
**Additional context**
Spark configs:
--deploy-mode cluster
--executor-memory 43g
--driver-memory 43g
--executor-cores 6
--conf spark.serializer=org.apache.spark.serializer.KryoSerializer
--conf spark.sql.hive.convertMetastoreParquet=false
--conf spark.hadoop.fs.s3.maxRetries=30
--conf spark.yarn.executor.memoryOverhead=5g
Hudi configs:
hoodie.consistency.check.enabled -> true
hoodie.datasource.write.table.type -> "COPY_ON_WRITE"
hoodie.datasource.write.keygenerator.class -> "org.apache.hudi.keygen.ComplexKeyGenerator"
hoodie.upsert.shuffle.parallelism -> 1500
hoodie.bulkinsert.shuffle.parallelism -> 1800
hoodie.parquet.max.file.size -> 500 * 1024 * 1024
hoodie.datasource.write.operation -> "upsert"
hoodie.metadata.enable -> true
hoodie.metadata.validate -> true
hoodie.fail.on.timeline.archiving -> false
hoodie.clean.automatic -> true
hoodie.cleaner.commits.retained: 72
hoodie.keep.min.commits: 100
hoodie.keep.max.commits: 150
hoodie.write.markers.type: timeline_server_based
**Stacktrace**
Getting small files from partitions isEmpty at HoodieSparkSqlWriter.scala:609 +details
org.apache.spark.rdd.RDD.isEmpty(RDD.scala:1557)
org.apache.hudi.HoodieSparkSqlWriter$.commitAndPerformPostOperations(HoodieSparkSqlWriter.scala:609)
org.apache.hudi.HoodieSparkSqlWriter$.write(HoodieSparkSqlWriter.scala:274)
org.apache.hudi.DefaultSource.createRelation(DefaultSource.scala:164)
org.apache.spark.sql.execution.datasources.SaveIntoDataSourceCommand.run(SaveIntoDataSourceCommand.scala:46)
org.apache.spark.sql.execution.command.ExecutedCommandExec.sideEffectResult$lzycompute(commands.scala:70)
org.apache.spark.sql.execution.command.ExecutedCommandExec.sideEffectResult(commands.scala:68)
org.apache.spark.sql.execution.command.ExecutedCommandExec.doExecute(commands.scala:90)
org.apache.spark.sql.execution.SparkPlan.$anonfun$execute$1(SparkPlan.scala:194)
org.apache.spark.sql.execution.SparkPlan.$anonfun$executeQuery$1(SparkPlan.scala:232)
org.apache.spark.rdd.RDDOperationScope$.withScope(RDDOperationScope.scala:151)
org.apache.spark.sql.execution.SparkPlan.executeQuery(SparkPlan.scala:229)
org.apache.spark.sql.execution.SparkPlan.execute(SparkPlan.scala:190)
org.apache.spark.sql.execution.QueryExecution.toRdd$lzycompute(QueryExecution.scala:134)
org.apache.spark.sql.execution.QueryExecution.toRdd(QueryExecution.scala:133)
org.apache.spark.sql.DataFrameWriter.$anonfun$runCommand$1(DataFrameWriter.scala:989)
org.apache.spark.sql.catalyst.QueryPlanningTracker$.withTracker(QueryPlanningTracker.scala:107)
org.apache.spark.sql.execution.SQLExecution$.withTracker(SQLExecution.scala:232)
org.apache.spark.sql.execution.SQLExecution$.executeQuery$1(SQLExecution.scala:110)
org.apache.spark.sql.execution.SQLExecution$.$anonfun$withNewExecutionId$6(SQLExecution.scala:135)
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] codope commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
codope commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1160587714

   @yangdafish As suggested above, could you please upgrade to latest Hudi release 0.11.1 and see if issue is still there?
   @YuweiXiao if you can share the patch which fixed this issue, that would be great.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] xushiyan commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
xushiyan commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1129882521

   @yangdafish please let us know if this suggestion works

   > Maybe related to this PR #4012
   >
   > Could you try adding this patch and test again? The issue is introduced in 0.9.0 and fixed in 0.11.0.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] YuweiXiao commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
YuweiXiao commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1149374796

   @yangdafish Hi, looking at the new spark UI you posted, the issue of 'one task being executed in multiple jobs' has actually been resolved (compared to job 15-19 in the 0.9.0 spark ui).

   And in the new spark ui, if we exclude the time used by job 0 (which seems not part of Hudi write), the total costs is around 1.5min.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] YuweiXiao commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
YuweiXiao commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1181369576

   > @yangdafish As suggested above, could you please upgrade to latest Hudi release 0.11.1 and see if issue is still there? @YuweiXiao if you can share the patch which fixed this issue, that would be great.

   Sorry for the late reply. The patch is posted above, PR #4012


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] yangdafish commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
yangdafish commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1149059891

   Hi, have upgraded our Hudi to 0.11.0 as suggested, using Maven bundle

   Performance issue still persists for larger datasets. Upsert job every 10 mins now takes longer than 10 minutes with the same Hudi settings.

   Executing Hudi 0.11.0 on AWS EMR 0.66 with Spark 3.2

   Included the following documentation suggested Hudi flags, but all other settings remained the same:
   --conf spark.sql.avro.datetimeRebaseModeInWrite=CORRECTED
   --conf spark.sql.catalog.spark_catalog=org.apache.spark.sql.hudi.catalog.HoodieCatalog
   --conf spark.sql.hive.convertMetastoreParquet=false

   Attaching EMR Spark History server snapshot as reference

   <img width="1789" alt="Screen Shot 2022-06-07 at 12 05 22 PM" src="https://user-images.githubusercontent.com/32607057/172462410-3cbcd5f8-66ab-4010-8c81-4fae843354a1.png">

   <img width="1786" alt="Screen Shot 2022-06-07 at 12 05 36 PM" src="https://user-images.githubusercontent.com/32607057/172462401-ca9e063e-5d3e-411e-ad27-f7a84551018f.png">


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan closed issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
nsivabalan closed issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
URL: https://github.com/apache/hudi/issues/5541


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] nsivabalan commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
nsivabalan commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1299684429

   Hey looks like we got the perf fix in https://github.com/apache/hudi/pull/5187
   Can you try it out w/ 0.11.1 or above and let us know if you are still seeing the issue.
   Closing the github issue for now. but feel free to reopen if you are still facing issues.
   would be glad to assist.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] yangdafish commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
yangdafish commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1149062702

   Also attempted to add the following Hudi flags for performance optimization, but was still unable to see same performance as pre-upgrade 0.8 Hudi with Spark 2

   ```
   "hoodie.metadata.enable" -> "true",
   "spark.memory.storageFraction" -> "0.2",
   "spark.yarn.driver.memoryOverhead" -> "1024",
   "spark.yarn.executor.memoryOverhead" -> "3072",
   "spark.yarn.max.executor.failures" -> "100"
    ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] YuweiXiao commented on issue #5541: [SUPPORT] Upgrade from 0.8.0 to 0.9.0 decreases Upsert performance
Posted by GitBox <gi...@apache.org>.
YuweiXiao commented on issue #5541:
URL: https://github.com/apache/hudi/issues/5541#issuecomment-1121939354

   Maybe related to this PR https://github.com/apache/hudi/pull/4012

   Could you try adding this patch and test again? The issue is introduced in 0.9.0 and fixed in 0.11.0.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org