You are viewing a plain text version of this content. The canonical link for it is here.
Posted to reviews@spark.apache.org by GitBox <gi...@apache.org> on 2022/04/04 13:49:33 UTC
[GitHub] [spark] zhengruifeng opened a new pull request, #36063: [SPARK-38785][PYTHON][WIP] impl EWM in the SQL side
zhengruifeng opened a new pull request, #36063:
URL: https://github.com/apache/spark/pull/36063

   <!--
   Thanks for sending a pull request!  Here are some tips for you:
     1. If this is your first time, please read our contributor guidelines: https://spark.apache.org/contributing.html
     2. Ensure you have added or run the appropriate tests for your PR: https://spark.apache.org/developer-tools.html
     3. If the PR is unfinished, add '[WIP]' in your PR title, e.g., '[WIP][SPARK-XXXX] Your PR title ...'.
     4. Be sure to keep the PR description updated to reflect all changes.
     5. Please write your PR title to summarize what this PR proposes.
     6. If possible, provide a concise example to reproduce the issue for a faster review.
     7. If you want to add a new configuration, please read the guideline first for naming configurations in
        'core/src/main/scala/org/apache/spark/internal/config/ConfigEntry.scala'.
     8. If you want to add or modify an error type or message, please read the guideline first in
        'core/src/main/resources/error/README.md'.
   -->

   ### What changes were proposed in this pull request?
   <!--
   Please clarify what changes you are proposing. The purpose of this section is to outline the changes and how this PR fixes the issue.
   If possible, please consider writing useful notes for better and faster reviews in your PR. See the examples below.
     1. If you refactor some codes with changing classes, showing the class hierarchy will help reviewers.
     2. If you fix some SQL features, you can provide some references of other DBMSes.
     3. If there is design documentation, please add the link.
     4. If there is a discussion in the mailing list, please add the link.
   -->


   ### Why are the changes needed?
   <!--
   Please clarify why the changes are needed. For instance,
     1. If you propose a new API, clarify the use case for a new API.
     2. If you fix a bug, you can clarify why it is a bug.
   -->


   ### Does this PR introduce _any_ user-facing change?
   <!--
   Note that it means *any* user-facing change including all aspects such as the documentation fix.
   If yes, please clarify the previous behavior and the change this PR proposes - provide the console output, description and/or an example to show the behavior difference if possible.
   If possible, please also clarify if this is a user-facing change compared to the released Spark versions or within the unreleased branches such as master.
   If no, write 'No'.
   -->


   ### How was this patch tested?
   <!--
   If tests were added, say they were added here. Please make sure to add some test cases that check the changes thoroughly including negative and positive cases if possible.
   If it was tested in a way different from regular unit tests, please clarify how you tested step by step, ideally copy and paste-able, so that other reviewers can test and check, and descendants can verify in the future.
   If tests were not added, please describe why they were not added and/or why it was difficult to add.
   If benchmark tests were added, please run the benchmarks in GitHub Actions for the consistent environment, and the instructions could accord to: https://spark.apache.org/developer-tools.html#github-workflow-benchmarks.
   -->


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845796322


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,188 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+        self._min_periods = min_periods
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+
+        if (com is not None) and (not com >= 0):

Review Comment:
   I found that using `(not com >= 0)` instead of `com < 0` can also check whether `com` is `np.nan`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on pull request #36063: [SPARK-38785][PYTHON][SQL] Implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1097522196

   all tests passed  https://github.com/zhengruifeng/spark/actions/runs/2158560305


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] Implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846943785


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,188 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+        self._min_periods = min_periods
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(

Review Comment:
   Likewise, this is actually pretty critical that we can't specify partitions while I don't have other better ideas. We should better document it somewhere that the performance is expected to be slow, and OOM can happen.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846945089


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   It's copied from pandas' right? Let's leave it as is for now.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] itholic commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
itholic commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r847817635


##########
python/pyspark/pandas/missing/window.py:
##########
@@ -124,3 +142,16 @@ class MissingPandasLikeRollingGroupby:
     is_datetimelike = _unsupported_property_rolling("is_datetimelike")
     is_freq_type = _unsupported_property_rolling("is_freq_type")
     ndim = _unsupported_property_rolling("ndim")
+
+
+class MissingPandasLikeExponentialMoving:

Review Comment:
   Maybe you could refer to https://github.com/apache/spark/pull/36034/files when adding the missing test.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1096007253

   retest this please


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on pull request #36063: [SPARK-38785][PYTHON][SQL] Implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1097522434

   Merged to master.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845760765


##########
python/pyspark/pandas/tests/test_ewm.py:
##########
@@ -0,0 +1,126 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+import numpy as np
+import pandas as pd
+
+import pyspark.pandas as ps
+from pyspark.testing.pandasutils import PandasOnSparkTestCase, TestUtils
+from pyspark.pandas.window import ExponentialMoving
+
+
+class EWMTest(PandasOnSparkTestCase, TestUtils):
+    def test_ewm_error(self):
+        with self.assertRaisesRegex(
+            TypeError, "psdf_or_psser must be a series or dataframe; however, got:.*int"
+        ):
+            ExponentialMoving(1, 2)
+
+        with self.assertRaisesRegex(ValueError, "min_periods must be >= 0"):
+            ps.range(10).ewm(min_periods=-1, alpha=0.5)

Review Comment:
   nice, will update it.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] itholic commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
itholic commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846938732


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.

Review Comment:
   Oh, I see.

   Then let's just keep it as is for now.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on pull request #36063: [SPARK-38785][PYTHON][WIP] impl EWM in the SQL side
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1089929408
this PR is still WIP, but a basic funcation was implemented.
I personaly thought it is not feasible to efficiently compute `ewm` for each x_t with existing window functions
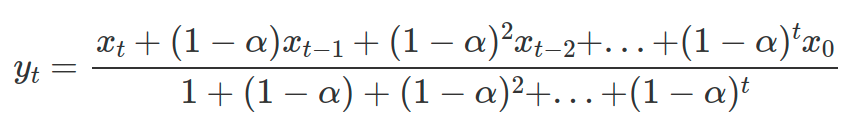
so a new window function is added to compute ewm.mean.
However, I found that I should add a `public` api in the SQL side, otherwise, the PySpark side can not find it. Are there some methods to work around it? I think we should not expose it to end users of SparkSQL.
@HyukjinKwon @ueshin could you please take a glance? Am I on the right way? Thanks
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845760545


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   `(otherwise result is NA)` this line was copid from `rolling` and `expanding` in `generic.py`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1096268487

   all tests passed:  https://github.com/zhengruifeng/spark/actions/runs/2152271171


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon closed pull request #36063: [SPARK-38785][PYTHON][SQL] Implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon closed pull request #36063: [SPARK-38785][PYTHON][SQL] Implement ExponentialMovingWindow
URL: https://github.com/apache/spark/pull/36063


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] itholic commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
itholic commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845680041


##########
python/pyspark/pandas/tests/test_ewm.py:
##########
@@ -0,0 +1,126 @@
+#
+# Licensed to the Apache Software Foundation (ASF) under one or more
+# contributor license agreements.  See the NOTICE file distributed with
+# this work for additional information regarding copyright ownership.
+# The ASF licenses this file to You under the Apache License, Version 2.0
+# (the "License"); you may not use this file except in compliance with
+# the License.  You may obtain a copy of the License at
+#
+#    http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+#
+import numpy as np
+import pandas as pd
+
+import pyspark.pandas as ps
+from pyspark.testing.pandasutils import PandasOnSparkTestCase, TestUtils
+from pyspark.pandas.window import ExponentialMoving
+
+
+class EWMTest(PandasOnSparkTestCase, TestUtils):
+    def test_ewm_error(self):
+        with self.assertRaisesRegex(
+            TypeError, "psdf_or_psser must be a series or dataframe; however, got:.*int"
+        ):
+            ExponentialMoving(1, 2)
+
+        with self.assertRaisesRegex(ValueError, "min_periods must be >= 0"):
+            ps.range(10).ewm(min_periods=-1, alpha=0.5)

Review Comment:
   Can we create one DataFrame and reuse it here and there instead of creating same DataFrame for every test?

   e.g.

   ```python
   ...
           psdf = ps.range(10)

           with self.assertRaisesRegex(ValueError, "min_periods must be >= 0"):
               psdf.ewm(min_periods=-1, alpha=0.5)

           with self.assertRaisesRegex(ValueError, "com must be >= 0"):
               psdf.ewm(com=-0.1)

           with self.assertRaisesRegex(ValueError, "span must be >= 1"):
               psdf.ewm(span=0.7)
   ...
   ```


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.

Review Comment:
   nit: It's not a big deal, just FYI, we usually use pandas-on-Spark when it's used before a noun.

   e.g. `pandas-on-Spark DataFrame`, `pandas-on-Spark docs` ...

   otherwise use full-name pandas API on Spark.


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,177 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+        self._min_periods = min_periods
+
+        opt_count = 0
+
+        if com is not None:
+            if com < 0:
+                raise ValueError("com must be >= 0")
+            self._alpha = 1.0 / (1 + com)
+            opt_count += 1
+
+        if span is not None:
+            if span < 1:
+                raise ValueError("span must be >= 1")
+            self._alpha = 2.0 / (1 + span)
+            opt_count += 1
+
+        if halflife is not None:
+            if halflife <= 0:
+                raise ValueError("halflife must be > 0")
+            self._alpha = 1.0 - np.exp(-np.log(2) / halflife)
+            opt_count += 1
+
+        if alpha is not None:
+            if alpha <= 0 or alpha > 1:

Review Comment:
   nit: Maybe `if 0 < alpha <= 1:` for better readability ? Not strong felling, though


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   Does it mean that we return `pd.NA` instead of `np.nan` ? (I think pandas returns `np.nan`)


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,177 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+        self._min_periods = min_periods
+
+        opt_count = 0
+
+        if com is not None:
+            if com < 0:
+                raise ValueError("com must be >= 0")
+            self._alpha = 1.0 / (1 + com)
+            opt_count += 1
+
+        if span is not None:
+            if span < 1:
+                raise ValueError("span must be >= 1")
+            self._alpha = 2.0 / (1 + span)
+            opt_count += 1
+
+        if halflife is not None:
+            if halflife <= 0:
+                raise ValueError("halflife must be > 0")
+            self._alpha = 1.0 - np.exp(-np.log(2) / halflife)
+            opt_count += 1
+
+        if alpha is not None:
+            if alpha <= 0 or alpha > 1:
+                raise ValueError("alpha must be in (0, 1]")
+            self._alpha = alpha
+            opt_count += 1
+
+        if opt_count == 0:
+            raise ValueError("Must pass one of comass, span, halflife, or alpha")
+
+        if opt_count != 1:
+            raise ValueError("comass, span, halflife, and alpha are mutually exclusive")
+
+    @abstractmethod
+    def _apply_as_series_or_frame(self, func: Callable[[Column], Column]) -> FrameLike:
+        """
+        Wraps a function that handles Spark column in order
+        to support it in both pandas-on-Spark Series and DataFrame.
+        Note that the given `func` name should be same as the API's method name.
+        """
+        pass
+
+    def mean(self) -> FrameLike:
+        def mean(scol: Column) -> Column:
+            jf = SparkContext._active_spark_context._jvm.PythonSQLUtils.ewm
+            return F.when(
+                F.row_number().over(self._unbounded_window) >= self._min_periods,
+                Column(jf(scol._jc, self._alpha)).over(self._window),
+            ).otherwise(SF.lit(None))
+
+        return self._apply_as_series_or_frame(mean)
+
+
+class ExponentialMoving(ExponentialMovingLike[FrameLike]):
+    def __init__(
+        self,
+        psdf_or_psser: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        from pyspark.pandas.frame import DataFrame
+        from pyspark.pandas.series import Series
+
+        if not isinstance(psdf_or_psser, (DataFrame, Series)):
+            raise TypeError(
+                "psdf_or_psser must be a series or dataframe; however, got: %s"
+                % type(psdf_or_psser)
+            )
+        self._psdf_or_psser = psdf_or_psser
+
+        window_spec = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+
+        super().__init__(window_spec, com, span, halflife, alpha, min_periods)
+
+    def __getattr__(self, item: str) -> Any:
+        if hasattr(MissingPandasLikeExponentialMoving, item):
+            property_or_func = getattr(MissingPandasLikeExponentialMoving, item)
+            if isinstance(property_or_func, property):
+                return property_or_func.fget(self)
+            else:
+                return partial(property_or_func, self)
+        raise AttributeError(item)
+
+    _apply_as_series_or_frame = Rolling._apply_as_series_or_frame
+
+    def mean(self) -> FrameLike:
+        """
+        Calculate an online exponentially weighted mean.
+
+        Notes
+        -----
+        There are behavior differences between pandas-on-Spark and pandas.
+
+        * the data should not contain NaNs. pandas-on-Spark will return an error.
+        * the current implementation of this API uses Spark's Window without
+          specifying partition specification. This leads to move all data into
+          single partition in single machine and could cause serious
+          performance degradation. Avoid this method against very large dataset.
+
+        Returns
+        -------
+        Series or DataFrame
+            Returned object type is determined by the caller of the exponentially
+            calculation.
+
+        See Also
+        --------
+        Series.expanding : Calling object with Series data.
+        DataFrame.expanding : Calling object with DataFrames.
+        Series.mean : Equivalent method for Series.
+        DataFrame.mean : Equivalent method for DataFrame.
+
+        Examples
+        --------
+        The below examples will show expanding mean calculations with window sizes of
+        two and three, respectively.

Review Comment:
   Maybe those are mistakenly from `expanding.mean` ?


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,177 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+        self._min_periods = min_periods
+
+        opt_count = 0
+
+        if com is not None:
+            if com < 0:
+                raise ValueError("com must be >= 0")
+            self._alpha = 1.0 / (1 + com)
+            opt_count += 1
+
+        if span is not None:
+            if span < 1:
+                raise ValueError("span must be >= 1")
+            self._alpha = 2.0 / (1 + span)
+            opt_count += 1
+
+        if halflife is not None:
+            if halflife <= 0:
+                raise ValueError("halflife must be > 0")
+            self._alpha = 1.0 - np.exp(-np.log(2) / halflife)
+            opt_count += 1
+
+        if alpha is not None:
+            if alpha <= 0 or alpha > 1:
+                raise ValueError("alpha must be in (0, 1]")
+            self._alpha = alpha
+            opt_count += 1
+
+        if opt_count == 0:
+            raise ValueError("Must pass one of comass, span, halflife, or alpha")

Review Comment:
   Maybe `comass` -> `com` ?? I think it's a typo in pandas.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845759363


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,177 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+        self._min_periods = min_periods
+
+        opt_count = 0
+
+        if com is not None:
+            if com < 0:
+                raise ValueError("com must be >= 0")
+            self._alpha = 1.0 / (1 + com)
+            opt_count += 1
+
+        if span is not None:
+            if span < 1:
+                raise ValueError("span must be >= 1")
+            self._alpha = 2.0 / (1 + span)
+            opt_count += 1
+
+        if halflife is not None:
+            if halflife <= 0:
+                raise ValueError("halflife must be > 0")
+            self._alpha = 1.0 - np.exp(-np.log(2) / halflife)
+            opt_count += 1
+
+        if alpha is not None:
+            if alpha <= 0 or alpha > 1:
+                raise ValueError("alpha must be in (0, 1]")
+            self._alpha = alpha
+            opt_count += 1
+
+        if opt_count == 0:
+            raise ValueError("Must pass one of comass, span, halflife, or alpha")
+
+        if opt_count != 1:
+            raise ValueError("comass, span, halflife, and alpha are mutually exclusive")
+
+    @abstractmethod
+    def _apply_as_series_or_frame(self, func: Callable[[Column], Column]) -> FrameLike:
+        """
+        Wraps a function that handles Spark column in order
+        to support it in both pandas-on-Spark Series and DataFrame.
+        Note that the given `func` name should be same as the API's method name.
+        """
+        pass
+
+    def mean(self) -> FrameLike:
+        def mean(scol: Column) -> Column:
+            jf = SparkContext._active_spark_context._jvm.PythonSQLUtils.ewm
+            return F.when(
+                F.row_number().over(self._unbounded_window) >= self._min_periods,
+                Column(jf(scol._jc, self._alpha)).over(self._window),
+            ).otherwise(SF.lit(None))
+
+        return self._apply_as_series_or_frame(mean)
+
+
+class ExponentialMoving(ExponentialMovingLike[FrameLike]):
+    def __init__(
+        self,
+        psdf_or_psser: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        from pyspark.pandas.frame import DataFrame
+        from pyspark.pandas.series import Series
+
+        if not isinstance(psdf_or_psser, (DataFrame, Series)):
+            raise TypeError(
+                "psdf_or_psser must be a series or dataframe; however, got: %s"
+                % type(psdf_or_psser)
+            )
+        self._psdf_or_psser = psdf_or_psser
+
+        window_spec = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+
+        super().__init__(window_spec, com, span, halflife, alpha, min_periods)
+
+    def __getattr__(self, item: str) -> Any:
+        if hasattr(MissingPandasLikeExponentialMoving, item):
+            property_or_func = getattr(MissingPandasLikeExponentialMoving, item)
+            if isinstance(property_or_func, property):
+                return property_or_func.fget(self)
+            else:
+                return partial(property_or_func, self)
+        raise AttributeError(item)
+
+    _apply_as_series_or_frame = Rolling._apply_as_series_or_frame
+
+    def mean(self) -> FrameLike:
+        """
+        Calculate an online exponentially weighted mean.
+
+        Notes
+        -----
+        There are behavior differences between pandas-on-Spark and pandas.
+
+        * the data should not contain NaNs. pandas-on-Spark will return an error.
+        * the current implementation of this API uses Spark's Window without
+          specifying partition specification. This leads to move all data into
+          single partition in single machine and could cause serious
+          performance degradation. Avoid this method against very large dataset.
+
+        Returns
+        -------
+        Series or DataFrame
+            Returned object type is determined by the caller of the exponentially
+            calculation.
+
+        See Also
+        --------
+        Series.expanding : Calling object with Series data.
+        DataFrame.expanding : Calling object with DataFrames.
+        Series.mean : Equivalent method for Series.
+        DataFrame.mean : Equivalent method for DataFrame.
+
+        Examples
+        --------
+        The below examples will show expanding mean calculations with window sizes of
+        two and three, respectively.

Review Comment:
   yes, good catch.  Will update those doc soon. Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846944064


##########
python/pyspark/pandas/window.py:
##########
@@ -18,16 +18,19 @@
 from functools import partial
 from typing import Any, Callable, Generic, List, Optional

Review Comment:
   ```suggestion
   from typing import Any, Callable, Generic, List, Optional

   import numpy as np
   ```


##########
python/pyspark/pandas/window.py:
##########
@@ -18,16 +18,19 @@
 from functools import partial
 from typing import Any, Callable, Generic, List, Optional

+from pyspark import SparkContext
 from pyspark.sql import Window
 from pyspark.sql import functions as F
 from pyspark.pandas.missing.window import (
     MissingPandasLikeRolling,
     MissingPandasLikeRollingGroupby,
     MissingPandasLikeExpanding,
     MissingPandasLikeExpandingGroupby,
+    MissingPandasLikeExponentialMoving,
 )

 # For running doctests and reference resolution in PyCharm.
+import numpy as np

Review Comment:
   ```suggestion
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] itholic commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
itholic commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r847817635


##########
python/pyspark/pandas/missing/window.py:
##########
@@ -124,3 +142,16 @@ class MissingPandasLikeRollingGroupby:
     is_datetimelike = _unsupported_property_rolling("is_datetimelike")
     is_freq_type = _unsupported_property_rolling("is_freq_type")
     ndim = _unsupported_property_rolling("ndim")
+
+
+class MissingPandasLikeExponentialMoving:

Review Comment:
   Maybe you could refer to https://github.com/apache/spark/pull/36034 when adding the missing test.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1092354627

   cc @ueshin, @itholic and @xinrong-databricks if you guys find some time to review.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846942722


##########
sql/catalyst/src/main/scala/org/apache/spark/sql/catalyst/expressions/windowExpressions.scala:
##########
@@ -1014,3 +1014,54 @@ case class PercentRank(children: Seq[Expression]) extends RankLike with SizeBase
   override protected def withNewChildrenInternal(newChildren: IndexedSeq[Expression]): PercentRank =
     copy(children = newChildren)
 }
+
+/**
+ * The Exponentially Weighted Window, MUST only be used in the Pandas API on Pyspark.
+ * An exponentially weighted window is similar to an expanding window but with each prior point
+ * being exponentially weighted down relative to the current point.
+ * In general, a weighted moving average is calculated as
+ *    y_t = \frac{\sum_{i=0}^t w_i x_{t-i}}{\sum_{i=0}^t w_i},
+ * where x_t is the input, y_t is the result and the w_i are the weights.
+ * See https://pandas.pydata.org/docs/user_guide/window.html#exponentially-weighted-window
+ * for details.
+ * For now, only function mean is supported. Other functions like sum/var will be added
+ * in the future.
+ */
+private[sql] case class EWM(input: Expression, alpha: Double)

Review Comment:
   We can remove this per SPARK-16813

   ```suggestion
   case class EWM(input: Expression, alpha: Double)
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846944521


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(

Review Comment:
   Would have to list it in https://github.com/apache/spark/blob/master/python/docs/source/reference/pyspark.pandas/window.rst so it's documented.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r847866649


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,188 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+        self._min_periods = min_periods
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(

Review Comment:
   currently it is documented in the Note part of `ExponentialMoving.mean`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] itholic commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
itholic commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846953442


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   It's not copied pandas but copied from:

   https://github.com/apache/spark/blob/2f122ba6d13ea26411fa4bf3e636ced449a8a205/python/pyspark/pandas/generic.py#L2584-L2586

   and:

   https://github.com/apache/spark/blob/2f122ba6d13ea26411fa4bf3e636ced449a8a205/python/pyspark/pandas/generic.py#L2610-L2612

   In our code base.

   pandas says "otherwise, result is `np.nan`." as beolw:

   <img width="633" alt="Screen Shot 2022-04-11 at 2 15 34 PM" src="https://user-images.githubusercontent.com/44108233/162669417-3fb30a27-8d29-45af-9af5-06681a24ff86.png">


   Maybe we should document as `np.nan` and also fix the document at `rolling` and `expanding` ??


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   It's not copied from pandas but copied from:

   https://github.com/apache/spark/blob/2f122ba6d13ea26411fa4bf3e636ced449a8a205/python/pyspark/pandas/generic.py#L2584-L2586

   and:

   https://github.com/apache/spark/blob/2f122ba6d13ea26411fa4bf3e636ced449a8a205/python/pyspark/pandas/generic.py#L2610-L2612

   In our code base.

   pandas says "otherwise, result is `np.nan`." as beolw:

   <img width="633" alt="Screen Shot 2022-04-11 at 2 15 34 PM" src="https://user-images.githubusercontent.com/44108233/162669417-3fb30a27-8d29-45af-9af5-06681a24ff86.png">


   Maybe we should document as `np.nan` and also fix the document at `rolling` and `expanding` ??


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846943785


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,188 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+        self._min_periods = min_periods
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(

Review Comment:
   Likewise, this is actually pretty critical that we can't specify partitions while I have other better ideas. We should better document it somewhere that the performance is expected to be slow, and OOM can happen.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r847876438


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   what about refining the documnet in another PR? then they can be changed in a batch


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r848995606


##########
sql/catalyst/src/main/scala/org/apache/spark/sql/catalyst/expressions/windowExpressions.scala:
##########
@@ -1014,3 +1015,51 @@ case class PercentRank(children: Seq[Expression]) extends RankLike with SizeBase
   override protected def withNewChildrenInternal(newChildren: IndexedSeq[Expression]): PercentRank =
     copy(children = newChildren)
 }
+
+/**
+ * Exponential Weighted Moment. This expression is dedicated only for Pandas API on Spark.
+ * An exponentially weighted window is similar to an expanding window but with each prior point
+ * being exponentially weighted down relative to the current point.
+ * See https://pandas.pydata.org/docs/user_guide/window.html#exponentially-weighted-window
+ * for details.
+ * Currently, only weighted moving average is supported. In general, it is calculated as
+ *    y_t = \frac{\sum_{i=0}^t w_i x_{t-i}}{\sum_{i=0}^t w_i},
+ * where x_t is the input, y_t is the result and the w_i are the weights.
+ */
+@DeveloperApi
+@Experimental
+@Unstable
+case class EWM(input: Expression, alpha: Double)
+  extends AggregateWindowFunction with UnaryLike[Expression] {
+  assert(0 < alpha && alpha <= 1)
+
+  override def dataType: DataType = DoubleType
+
+  private val numerator = AttributeReference("numerator", DoubleType, nullable = false)()
+  private val denominator = AttributeReference("denominator", DoubleType, nullable = false)()
+  override def aggBufferAttributes: Seq[AttributeReference] = numerator :: denominator :: Nil
+
+  override val initialValues: Seq[Expression] = Seq(Literal(0.0), Literal(0.0))
+
+  override val updateExpressions: Seq[Expression] = {
+    val beta = Literal(1.0 - alpha)
+    val casted = input.cast(DoubleType)
+    // TODO: after adding param ignore_na, we can remove this check
+    val error = RaiseError(Literal("Input values Must not be Null or NaN")).cast(DoubleType)

Review Comment:
   ```suggestion
       val error = RaiseError(Literal("Input values must not be null or NaN")).cast(DoubleType)
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][WIP] impl EWM in the SQL side
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r843586884


##########
sql/core/src/main/scala/org/apache/spark/sql/functions.scala:
##########
@@ -1178,6 +1178,8 @@ object functions {
    */
   def row_number(): Column = withExpr { RowNumber() }

+  def ewm(e: Column, alpha: Double): Column = withExpr { EWM(e.expr, alpha) }

Review Comment:
   can we make it only visiable to pyspark in some way?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] Implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r848999529


##########
sql/catalyst/src/main/scala/org/apache/spark/sql/catalyst/expressions/windowExpressions.scala:
##########
@@ -1014,3 +1015,51 @@ case class PercentRank(children: Seq[Expression]) extends RankLike with SizeBase
   override protected def withNewChildrenInternal(newChildren: IndexedSeq[Expression]): PercentRank =
     copy(children = newChildren)
 }
+
+/**
+ * Exponential Weighted Moment. This expression is dedicated only for Pandas API on Spark.
+ * An exponentially weighted window is similar to an expanding window but with each prior point
+ * being exponentially weighted down relative to the current point.
+ * See https://pandas.pydata.org/docs/user_guide/window.html#exponentially-weighted-window
+ * for details.
+ * Currently, only weighted moving average is supported. In general, it is calculated as
+ *    y_t = \frac{\sum_{i=0}^t w_i x_{t-i}}{\sum_{i=0}^t w_i},
+ * where x_t is the input, y_t is the result and the w_i are the weights.
+ */
+@DeveloperApi
+@Experimental
+@Unstable

Review Comment:
   ok


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845761513


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.

Review Comment:
   this usage of `pandas-on-Spark` was also copied from `rolling` and `expanding` in `generic.py`. I am netural on it.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846944295


##########
python/pyspark/pandas/missing/window.py:
##########
@@ -124,3 +142,16 @@ class MissingPandasLikeRollingGroupby:
     is_datetimelike = _unsupported_property_rolling("is_datetimelike")
     is_freq_type = _unsupported_property_rolling("is_freq_type")
     ndim = _unsupported_property_rolling("ndim")
+
+
+class MissingPandasLikeExponentialMoving:

Review Comment:
   We will have to test it at `python/pyspark/pandas/tests/test_window.py`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][WIP] impl EWM in the SQL side
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r843586884


##########
sql/core/src/main/scala/org/apache/spark/sql/functions.scala:
##########
@@ -1178,6 +1178,8 @@ object functions {
    */
   def row_number(): Column = withExpr { RowNumber() }

+  def ewm(e: Column, alpha: Double): Column = withExpr { EWM(e.expr, alpha) }

Review Comment:
   ~~can we make it only visiable to pyspark in some way?~~


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845759689


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,177 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+        self._min_periods = min_periods
+
+        opt_count = 0
+
+        if com is not None:
+            if com < 0:
+                raise ValueError("com must be >= 0")
+            self._alpha = 1.0 / (1 + com)
+            opt_count += 1
+
+        if span is not None:
+            if span < 1:
+                raise ValueError("span must be >= 1")
+            self._alpha = 2.0 / (1 + span)
+            opt_count += 1
+
+        if halflife is not None:
+            if halflife <= 0:
+                raise ValueError("halflife must be > 0")
+            self._alpha = 1.0 - np.exp(-np.log(2) / halflife)
+            opt_count += 1
+
+        if alpha is not None:
+            if alpha <= 0 or alpha > 1:
+                raise ValueError("alpha must be in (0, 1]")
+            self._alpha = alpha
+            opt_count += 1
+
+        if opt_count == 0:
+            raise ValueError("Must pass one of comass, span, halflife, or alpha")

Review Comment:
   yep. I copied this error msg from pandas, it should be a typo in pandas.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846944967


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.

Review Comment:
   I think it's fine for now.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r845793746


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   let's wait for others feedbacks.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on pull request #36063: [SPARK-38785][PYTHON][WIP] impl EWM in the SQL side
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1087582310

   ```
   scala> spark.sql(""" SELECT a, b, c, ewm(c, 0.1) OVER (PARTITION BY b ORDER BY a) FROM VALUES ('A', 0, 2), ('B', 1, 1), ('C', 0, 3), ('D', 1, 1) tab(a, b, c); """).show

   +---+---+---+--------------------------------------------------------------------------------------------------------+
   |  a|  b|  c|ewm(c) OVER (PARTITION BY b ORDER BY a ASC NULLS FIRST ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW)|
   +---+---+---+--------------------------------------------------------------------------------------------------------+
   |  A|  0|  2|                                                                                                     2.0|
   |  C|  0|  3|                                                                                       2.526315789473684|
   |  B|  1|  1|                                                                                                     1.0|
   |  D|  1|  1|                                                                                                     1.0|
   +---+---+---+--------------------------------------------------------------------------------------------------------+
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] itholic commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
itholic commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r846953442


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   Seems like it's not copied from pandas but copied from:

   https://github.com/apache/spark/blob/2f122ba6d13ea26411fa4bf3e636ced449a8a205/python/pyspark/pandas/generic.py#L2584-L2586

   and:

   https://github.com/apache/spark/blob/2f122ba6d13ea26411fa4bf3e636ced449a8a205/python/pyspark/pandas/generic.py#L2610-L2612

   In our code base.

   pandas says "otherwise, result is `np.nan`." as beolw:

   <img width="633" alt="Screen Shot 2022-04-11 at 2 15 34 PM" src="https://user-images.githubusercontent.com/44108233/162669417-3fb30a27-8d29-45af-9af5-06681a24ff86.png">


   Maybe we should document as `np.nan` and also fix the document at `rolling` and `expanding` ??


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] xinrong-databricks commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
xinrong-databricks commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r847786718


##########
python/pyspark/pandas/window.py:
##########
@@ -1749,6 +1752,188 @@ def var(self) -> FrameLike:
         return super().var()


+class ExponentialMovingLike(Generic[FrameLike], metaclass=ABCMeta):
+    def __init__(
+        self,
+        window: WindowSpec,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ):
+        if (min_periods is not None) and (min_periods < 0):
+            raise ValueError("min_periods must be >= 0")
+        if min_periods is None:
+            min_periods = 0
+        self._min_periods = min_periods
+
+        self._window = window
+        # This unbounded Window is later used to handle 'min_periods' for now.
+        self._unbounded_window = Window.orderBy(NATURAL_ORDER_COLUMN_NAME).rowsBetween(
+            Window.unboundedPreceding, Window.currentRow
+        )
+
+        if (com is not None) and (not com >= 0):

Review Comment:
   Good finding!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1095825025

   retest this please


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r848994888


##########
python/pyspark/pandas/generic.py:
##########
@@ -2619,6 +2619,56 @@ def expanding(self: FrameLike, min_periods: int = 1) -> "Expanding[FrameLike]":

         return Expanding(self, min_periods=min_periods)

+    # TODO: 'adjust', 'ignore_na', 'axis', 'method' parameter should be implemented.
+    def ewm(
+        self: FrameLike,
+        com: Optional[float] = None,
+        span: Optional[float] = None,
+        halflife: Optional[float] = None,
+        alpha: Optional[float] = None,
+        min_periods: Optional[int] = None,
+    ) -> "ExponentialMoving[FrameLike]":
+        """
+        Provide exponentially weighted window transformations.
+
+        .. note:: 'min_periods' in pandas-on-Spark works as a fixed window size unlike pandas.
+            Unlike pandas, NA is also counted as the period. This might be changed
+            in the near future.
+
+        .. versionadded:: 3.4.0
+
+        Parameters
+        ----------
+        com : float, optional
+            Specify decay in terms of center of mass.
+            alpha = 1 / (1 + com), for com >= 0.
+
+        span : float, optional
+            Specify decay in terms of span.
+            alpha = 2 / (span + 1), for span >= 1.
+
+        halflife : float, optional
+            Specify decay in terms of half-life.
+            alpha = 1 - exp(-ln(2) / halflife), for halflife > 0.
+
+        alpha : float, optional
+            Specify smoothing factor alpha directly.
+            0 < alpha <= 1.
+
+        min_periods : int, default 0
+            Minimum number of observations in window required to have a value
+            (otherwise result is NA).

Review Comment:
   Yeah let's do that


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] HyukjinKwon commented on a diff in pull request #36063: [SPARK-38785][PYTHON][SQL] implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
HyukjinKwon commented on code in PR #36063:
URL: https://github.com/apache/spark/pull/36063#discussion_r848995326


##########
sql/catalyst/src/main/scala/org/apache/spark/sql/catalyst/expressions/windowExpressions.scala:
##########
@@ -1014,3 +1015,51 @@ case class PercentRank(children: Seq[Expression]) extends RankLike with SizeBase
   override protected def withNewChildrenInternal(newChildren: IndexedSeq[Expression]): PercentRank =
     copy(children = newChildren)
 }
+
+/**
+ * Exponential Weighted Moment. This expression is dedicated only for Pandas API on Spark.
+ * An exponentially weighted window is similar to an expanding window but with each prior point
+ * being exponentially weighted down relative to the current point.
+ * See https://pandas.pydata.org/docs/user_guide/window.html#exponentially-weighted-window
+ * for details.
+ * Currently, only weighted moving average is supported. In general, it is calculated as
+ *    y_t = \frac{\sum_{i=0}^t w_i x_{t-i}}{\sum_{i=0}^t w_i},
+ * where x_t is the input, y_t is the result and the w_i are the weights.
+ */
+@DeveloperApi
+@Experimental
+@Unstable

Review Comment:
   Let's remove these since this class itself isn't exposed as an API.

   ```suggestion
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] [spark] zhengruifeng commented on pull request #36063: [SPARK-38785][PYTHON][SQL] Implement ExponentialMovingWindow
Posted by GitBox <gi...@apache.org>.
zhengruifeng commented on PR #36063:
URL: https://github.com/apache/spark/pull/36063#issuecomment-1097524280

   Thanks all!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org