You are viewing a plain text version of this content. The canonical link for it is here.
Posted to github@arrow.apache.org by GitBox <gi...@apache.org> on 2022/10/09 01:33:19 UTC
[GitHub] [arrow] zhixingheyi-tian opened a new pull request, #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
zhixingheyi-tian opened a new pull request, #14353:
URL: https://github.com/apache/arrow/pull/14353

   Improve parquet reading performance for String/Binary type based on Buffer operations instead of BinaryArrayBuilder


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1339045263

   Hi @pitrou ,

   Recently,have fixed  remaining failed 7 UTs, and  this patch is ready for reviw.

   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1067902165


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      hasCal_average_len_ = true;
+    }
+    offset_ = AllocateBuffer(this->pool_);
+    bianry_length_ = 0;
+    return result;
+  }
+  void ResetValues() {
+    if (values_written_ > 0) {
+      // Resize to 0, but do not shrink to fit
+      PARQUET_THROW_NOT_OK(valid_bits_->Resize(0, false));

Review Comment:
   >

   Just follow here: https://github.com/apache/arrow/blob/fc53ff8c5e2797c1a5a99db7f3aece80dd0b9f3e/cpp/src/parquet/column_reader.cc#L1846-L1851


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051808643


##########
cpp/src/parquet/column_reader.h:
##########
@@ -291,6 +293,8 @@ class PARQUET_EXPORT RecordReader {
   /// \brief Pre-allocate space for data. Results in better flat read performance
   virtual void Reserve(int64_t num_values) = 0;

+  virtual void ReserveValues(int64_t capacity) {}

Review Comment:
   Isn't it just a helper function specific to implementation?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051561605


##########
cpp/src/parquet/column_reader.h:
##########
@@ -291,6 +293,8 @@ class PARQUET_EXPORT RecordReader {
   /// \brief Pre-allocate space for data. Results in better flat read performance
   virtual void Reserve(int64_t num_values) = 0;

+  virtual void ReserveValues(int64_t capacity) {}

Review Comment:
   A new interface? Are these added data members and functions necessary for this base class? I suppose they are only for the new reader implementation.


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {

Review Comment:
   Are all these cases covered by UT?


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {

Review Comment:
   Stick to snake_case for variables.


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   Duplicates `ByteArrayChunkedRecordReader`? This doesn't look right.


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {
+        uses_opt_ = true;
+      }
+      hasSet_uses_opt_ = true;
+    }
   }

   int64_t available_values_current_page() const {
     return num_buffered_values_ - num_decoded_values_;
   }

+  bool hasSet_uses_opt_ = false;
+  bool uses_opt_ = false;

Review Comment:
   Are these two flags really necessary?
   Looks to me a trivial helper function is better.


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   I saw many dummy implementations like this in the PR. Probably they can be eliminated.


##########
cpp/src/parquet/encoding.cc:
##########
@@ -1948,6 +2026,79 @@ class DictByteArrayDecoderImpl : public DictDecoderImpl<ByteArrayType>,
     return Status::OK();
   }

+  Status DecodeArrowDense_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int* out_num_values,
+                              int32_t* bianry_length) {
+    constexpr int32_t kBufferSize = 1024;
+    int32_t indices[kBufferSize];
+    auto dst_value = values->mutable_data() + (*bianry_length);
+
+    ::arrow::internal::BitmapReader bit_reader(valid_bits, valid_bits_offset, num_values);

Review Comment:
   Do we have benchmark result of this bitmap reader based implementation?
   Is it better than original code (bitblock counter)?


##########
cpp/src/parquet/encoding.cc:
##########
@@ -1360,6 +1360,17 @@ class PlainByteArrayDecoder : public PlainDecoder<ByteArrayType>,
     return result;
   }

+  int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,

Review Comment:
   Please stick to CamelCase for function names, snake_case for variables.


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow_opt(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow_opt(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      // std::cout << "binary_per_row_length_:" << binary_per_row_length_ << std::endl;

Review Comment:
   Please remove debug code.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wgtmac commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wgtmac (via GitHub)" <gi...@apache.org>.
wgtmac commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1085376681


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   > @wgtmac I'm not sure if you are objecting to my proposal above. A separate `BufferBuilder` for the string data allows to presize for the computed total length, so it should address your concern.

   Sorry I didn't make it clear. I'm not objecting your proposal. Instead I just summarized another optimization we have done before if reusing `arrow::RecordBatch` on the same reader is possible. Internal experiment reveals that repeated buffer allocation and resize operation are non-negligible overhead, especially for wide columns (e.g. 1000+ columns).  @pitrou


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1346170702

   HI @jorisvandenbossche @wjones127 @pitrou @iajoiner

   This PR is ready to review, please have a look.
   Thanks,


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051757896


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow_opt(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow_opt(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      // std::cout << "binary_per_row_length_:" << binary_per_row_length_ << std::endl;

Review Comment:
   Done


##########
cpp/src/parquet/encoding.cc:
##########
@@ -1360,6 +1360,17 @@ class PlainByteArrayDecoder : public PlainDecoder<ByteArrayType>,
     return result;
   }

+  int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,

Review Comment:
   Done


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051820407


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   This probably means it's not good to create a new class for this optimized reader.

   That said, I don't have deep knowlege of parquet code and lack bandwidth recently to investigate, someone else might comment.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wjones127 (via GitHub)" <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1084345582


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   Thanks Antoine. I guess I'm just catching to up your understanding 😄


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1319127123

   Hi @zhixingheyi-tian, sorry this hasn't gotten reviewer attention for a while. Are you still interested in working on this?

   Would you mind rebasing and cleaning up any commented code?

   In addition, I noticed there aren't any benchmarks for binary or string types in either of these two benchmark files:

    * `src/parquet/arrow/reader_writer_benchmark.cc`
    * `src/parquet/parquet_encoding_benchmark.cc`

   We'll want some benchmarks in order to evaluate the changes. If you add those, then you can compare benchmarks locally like so:

   ```sh
   BUILD_DIR=cpp/path/to/build

   archery benchmark run $BUILD_DIR \
     --suite-filter=parquet-arrow-reader-writer-benchmark \
     --output=contender.json

   git checkout master # Or some ref that has benchmarks but not your changes

   archery benchmark run $BUILD_DIR \
     --suite-filter=parquet-arrow-reader-writer-benchmark \
     --output=baseline.json

   archery benchmark diff contender.json baseline.json
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wgtmac commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wgtmac (via GitHub)" <gi...@apache.org>.
wgtmac commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1492211046

   @zhixingheyi-tian Do you plan to update this?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
pitrou commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1346596650

   > [](https://github.com/apache/arrow/blame/6cfe24633b9fe3c474137571940eca35d7a475dc/cpp/src/parquet/column_reader_test.cc#L1181-L1185)
   >
   > And this performance PR is avoiding this interface. So it failed.
   >
   > Any suggestions to fix this UT?

   I'm not sure I understand your question. It's your job to make sure that your changes don't break the existing test suite...


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1354835587

   cc @pitrou @jorisvandenbossche @wjones127 @cyb70289 @iajoiner ,

   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1067896370


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      hasCal_average_len_ = true;
+    }
+    offset_ = AllocateBuffer(this->pool_);
+    bianry_length_ = 0;
+    return result;
+  }
+  void ResetValues() {
+    if (values_written_ > 0) {
+      // Resize to 0, but do not shrink to fit
+      PARQUET_THROW_NOT_OK(valid_bits_->Resize(0, false));

Review Comment:
   > @zhixingheyi-tian Once you've fixed the issues mentioned, could you also rebase on the latest master branch? Once you do that we can run the benchmark.

   Have rebased. Performance can refer to https://github.com/apache/arrow/pull/14353#issue-1402114514


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1380057306

   > @zhixingheyi-tian Once you've fixed the issues mentioned, could you also rebase on the latest master branch? Once you do that we can run the benchmark.

   Have rebased. Performance can refer to https://github.com/apache/arrow/pull/14353#issue-1402114514


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1357120390

   > But how to add Binary/String benchmark in *benchmark.cc? I noticed currently Arrow benchmark testings had not support generating random binary data. Would you please give some help or advices about adding String/binary in micro benchmarks, thanks!

   There are many examples you can reference. `cpp/src/arrow/testing/random.h` defines functions to generate different kinds of random test set.

   Please note it can be a separate PR to add new benchmarks, which can be reviewed and merged before this one.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1330609070

   @wjones127 ,
   Will focus on this patch recently.
   Welcome review!

   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1066405371


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      hasCal_average_len_ = true;
+    }
+    offset_ = AllocateBuffer(this->pool_);
+    bianry_length_ = 0;
+    return result;
+  }
+  void ResetValues() {
+    if (values_written_ > 0) {
+      // Resize to 0, but do not shrink to fit
+      PARQUET_THROW_NOT_OK(valid_bits_->Resize(0, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize(0, false));
+      PARQUET_THROW_NOT_OK(values_->Resize(0, false));
+
+      values_written_ = 0;
+      values_capacity_ = 0;
+      null_count_ = 0;
+      bianry_length_ = 0;
+    }
+  }
+
+ private:
+  // Helper data structure for accumulating builder chunks
+  typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
+
+  int32_t bianry_length_ = 0;

Review Comment:
   It's a prexisting issue, but could you fix this variable name?

   ```suggestion
     int32_t binary_length_ = 0;
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] ursabot commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
ursabot commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1377925913

   Benchmark runs are scheduled for baseline = f82501e763ff48af610077f9525ae83cc3ab2e95 and contender = 19e2ba3b4bf6aca344cfa179f194163d6c3ef089. Results will be available as each benchmark for each run completes.
   Conbench compare runs links:
   [Skipped :warning: Only ['lang', 'name'] filters are supported on ec2-t3-xlarge-us-east-2] [ec2-t3-xlarge-us-east-2](https://conbench.ursa.dev/compare/runs/56e34f8d30294230be86ebb3e8dd1a1f...a73fbfc0bb194b5e9b145f88fbf2fedb/)
   [Skipped :warning: Only ['lang', 'name'] filters are supported on test-mac-arm] [test-mac-arm](https://conbench.ursa.dev/compare/runs/4f60b9764d724af9acc102d714e0f637...b34bfa6f62db41e093886e38cbde56aa/)
   [Skipped :warning: Only ['lang', 'name'] filters are supported on ursa-i9-9960x] [ursa-i9-9960x](https://conbench.ursa.dev/compare/runs/cb6fb733aa0247c0bf22f9714509095b...8b931da537a94212a0228ecbd20c0f1f/)
   [Scheduled] [ursa-thinkcentre-m75q](https://conbench.ursa.dev/compare/runs/8acf7ba49e8d40718d5ac8c2b4a1c5cd...1efcfa20fe6645928bbe63902e7af6f6/)
   Buildkite builds:
   [Scheduled] [`19e2ba3b` ursa-thinkcentre-m75q](https://buildkite.com/apache-arrow/arrow-bci-benchmark-on-ursa-thinkcentre-m75q/builds/2159)
   [Finished] [`f82501e7` ec2-t3-xlarge-us-east-2](https://buildkite.com/apache-arrow/arrow-bci-benchmark-on-ec2-t3-xlarge-us-east-2/builds/2034)
   [Failed] [`f82501e7` test-mac-arm](https://buildkite.com/apache-arrow/arrow-bci-benchmark-on-test-mac-arm/builds/2056)
   [Finished] [`f82501e7` ursa-i9-9960x](https://buildkite.com/apache-arrow/arrow-bci-benchmark-on-ursa-i9-9960x/builds/2026)
   [Finished] [`f82501e7` ursa-thinkcentre-m75q](https://buildkite.com/apache-arrow/arrow-bci-benchmark-on-ursa-thinkcentre-m75q/builds/2048)
   Supported benchmarks:
   ec2-t3-xlarge-us-east-2: Supported benchmark langs: Python, R. Runs only benchmarks with cloud = True
   test-mac-arm: Supported benchmark langs: C++, Python, R
   ursa-i9-9960x: Supported benchmark langs: Python, R, JavaScript
   ursa-thinkcentre-m75q: Supported benchmark langs: C++, Java


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] github-actions[bot] commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
github-actions[bot] commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1272428186

   :warning: Ticket **has not been started in JIRA**, please click 'Start Progress'.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
pitrou commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1351823261

   Instead of defining entire separate classes for this, why not change `EncodingTraits::Accumulator` to the following:
   ```c++
   template <>
   struct EncodingTraits<ByteArrayType> {
     // ...
     struct Accumulator {
       std::unique_ptr<::arrow::Int32Builder> offsets_builder;
       std::unique_ptr<::arrow::BufferBuilder> data_builder;
       std::vector<std::shared_ptr<::arrow::Array>> chunks;
     };
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1350262966

   Would you fix the CI failures?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] amol- closed pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "amol- (via GitHub)" <gi...@apache.org>.
amol- closed pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
URL: https://github.com/apache/arrow/pull/14353


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1370500077

   @cyb70289 @wjones127
   During the last two weeks, was suffering high fever.  Sorry!
   Now, Will continue to support this patch!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1348098925

   > > And this performance PR is avoiding this interface. So it failed.
   > > Any suggestions to fix this UT?
   >
   > I'm not sure I understand your question. It's your job to make sure that your changes don't break the existing test suite...

   Hi @pitrou ,
   Have fixed this UT , today.
   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1353179807

   > Instead of defining entire separate classes for this, why not change `EncodingTraits::Accumulator` to the following:
   >
   > ```c++
   > template <>
   > struct EncodingTraits<ByteArrayType> {
   >   // ...
   >   struct Accumulator {
   >     std::unique_ptr<::arrow::Int32Builder> offsets_builder;
   >     std::unique_ptr<::arrow::BufferBuilder> data_builder;
   >     std::vector<std::shared_ptr<::arrow::Array>> chunks;
   >   };
   > ```

   If use *Builder, may  add extra data copy when accumulating element.
   Can refer to fixed width usage : https://github.com/apache/arrow/blob/5ce8d79d7ae4b3864226cc3c5480fa8eba2e571d/cpp/src/parquet/encoding.cc#L1062-L1070

   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1350315565

   >
   > I am in fixing errors in github CI. For "TestArrowReadDeltaEncoding.DeltaByteArray", why is skipped in my local testing? But showed failure on CI.
   >

   Don't know the details. But it should be easy to find in the source code.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1380068795

   > The failures in the continuous-integration/appveyor/pr seem relevant. This test is failing:
   >
   > https://github.com/apache/arrow/blob/85b167c05c2f93a95b23e8ac4fd4da576ea5b899/python/pyarrow/tests/parquet/test_basic.py#L715-L742
   >
   > Perhaps we need to make sure that if there are null values that we don't copy those parts of the buffer?

   I haven't touched pyarrow before. pyarrow underlayer is arrow-cpp, right?
   How to reproduce the issue easily in cpp?
   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1377942896

   The failures in the continuous-integration/appveyor/pr seem relevant. This test is failing:

   https://github.com/apache/arrow/blob/85b167c05c2f93a95b23e8ac4fd4da576ea5b899/python/pyarrow/tests/parquet/test_basic.py#L715-L742

   Perhaps we need to make sure that if there are null values that we don't copy those parts of the buffer?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "pitrou (via GitHub)" <gi...@apache.org>.
pitrou commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1085290017


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   @wgtmac I'm not sure if you are objecting to my proposal above. A separate `BufferBuilder` for the string data allows to presize for the computed total length, so it should address your concern.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wjones127 (via GitHub)" <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1082987506


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   Here is the changeset that allows the `parquet-arrow-test` and `parquet-arrow-internals-test` to pass. https://github.com/zhixingheyi-tian/arrow/pull/2

   Could you incorporate those changes?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wjones127 (via GitHub)" <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1083109332


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   It seems like we are adding this because the other methods are based on builders (in the accumulator), and builder don't provide a way to transfer multiple values in one `memcpy`. Does that sound right?

   I wonder if we could add such a method on builders, and that might be a cleaner solution. Something like:

   ```cpp
   class BaseBinaryBuilder {
   ...
     Status UnsafeAppendValues(const uint8_t* values, int64_t length, const uint8_t* valid_bytes = NULL_PTR) { ... }
   };
   ```

   The reason getting back to builders might be good is that I don't think these changes handle the case where there are more values than can fit into a StringArray. The current implementation will split it up into chunks if it reaches capacity, and I think we need to keep that behavior.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051754661


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {

Review Comment:
   Yes,
   This patch is from one customer's case. They want to boost String scan performance.
   So this patch is just for parquet general encodings: PLAIN , RLE_DICTIONARY, PLAIN_DICTIONARY.

   Other encodings will skip this optimization.

   Existed UTs will cover all encodings cases.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051755967


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   Just  follow previous  DecodeArrow() function call stack usages.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1377925815

   @ursabot please benchmark command=cpp-micro --suite-filter=parquet-arrow-reader-writer-benchmark


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1066401043


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   I agree, would shouldn't create another class. I don't see any reason this can't be used for the Decimal case.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1357033150

   > Good idea to show performance.
   >
   > But how to add Binary/String benchmark in *benchmark.cc? I noticed currently Arrow benchmark testings had not support generating random binary data. Would you please give some help or advices about adding String/binary in micro benchmarks, thanks!

   Hi @cyb70289 ,
   Thanks your kind review very much!

   Good idea to show performance.

   But how to add Binary/String benchmark in *benchmark.cc?
   I noticed currently Arrow benchmark testings had not support generating random binary data.
   Would you please give some help or advices about adding String/binary in micro benchmarks, thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1353172452

   > > I am in fixing errors in github CI. For "TestArrowReadDeltaEncoding.DeltaByteArray", why is skipped in my local testing? But showed failure on CI.
   >
   > Don't know the details. But it should be easy to find in the source code.

   New commits should fix all UTs. Please give a review!
   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wgtmac commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wgtmac (via GitHub)" <gi...@apache.org>.
wgtmac commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1085225401


##########
cpp/src/parquet/encoding.cc:
##########
@@ -1412,6 +1423,57 @@ class PlainByteArrayDecoder : public PlainDecoder<ByteArrayType>,
     return Status::OK();
   }

+  Status DecodeArrowDenseZeroCopy(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int* out_values_decoded,
+                              int32_t* bianry_length) {

Review Comment:
   ```suggestion
                                 int32_t* binary_length) {
   ```


##########
cpp/src/parquet/encoding.cc:
##########
@@ -1977,6 +2128,48 @@ class DictByteArrayDecoderImpl : public DictDecoderImpl<ByteArrayType>,
     return Status::OK();
   }

+  Status DecodeArrowDenseNonNull_opt(int num_values, int32_t* offset,

Review Comment:
   Can we avoid this kind of name and give a meaningful one instead?


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1959,6 +1972,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());

Review Comment:
   Is `::arrow::binary()` correct? Will it cause type mismatch if actual type is `::arrow::utf8()`? For example, when checking equality with a StringArray, the type identity may be broken if one side is binary and the other is utf8.


##########
cpp/src/parquet/encoding.cc:
##########
@@ -1977,6 +2128,48 @@ class DictByteArrayDecoderImpl : public DictDecoderImpl<ByteArrayType>,
     return Status::OK();
   }

+  Status DecodeArrowDenseNonNull_opt(int num_values, int32_t* offset,
+                                     std::shared_ptr<::arrow::ResizableBuffer>& values,
+                                     int* out_num_values, int32_t* bianry_length) {
+    constexpr int32_t kBufferSize = 2048;
+    int32_t indices[kBufferSize];
+    int values_decoded = 0;
+    uint64_t capacity = values->size();
+
+    // ArrowBinaryHelper helper(out);
+    auto dict_values = reinterpret_cast<const ByteArray*>(dictionary_->data());
+
+    auto dst_value = values->mutable_data() + (*bianry_length);
+    int num_appended = 0;
+
+    while (values_decoded < num_values) {
+      int32_t batch_size = std::min<int32_t>(kBufferSize, num_values - values_decoded);
+      int num_indices = idx_decoder_.GetBatch(indices, batch_size);
+      if (num_indices == 0) ParquetException::EofException();

Review Comment:
   It would be helpful to provide some concrete error message.


##########
cpp/src/parquet/column_reader.h:
##########
@@ -291,6 +293,8 @@ class PARQUET_EXPORT RecordReader {
   /// \brief Pre-allocate space for data. Results in better flat read performance
   virtual void Reserve(int64_t num_values) = 0;

+  virtual void ReserveValues(int64_t capacity) {}

Review Comment:
   Is it better to make it pure virtual? In addition, it helps to add a comment for public function.


##########
cpp/src/parquet/column_reader.h:
##########
@@ -55,6 +55,8 @@ static constexpr uint32_t kDefaultMaxPageHeaderSize = 16 * 1024 * 1024;
 // 16 KB is the default expected page header size
 static constexpr uint32_t kDefaultPageHeaderSize = 16 * 1024;

+static constexpr int32_t kDefaultBinaryPerRowSize = 20;

Review Comment:
   It would be better to add a comment here.


##########
cpp/src/parquet/column_reader.h:
##########
@@ -299,6 +303,8 @@ class PARQUET_EXPORT RecordReader {
   /// allocated in subsequent ReadRecords calls
   virtual std::shared_ptr<ResizableBuffer> ReleaseValues() = 0;

+  virtual std::shared_ptr<ResizableBuffer> ReleaseOffsets() = 0;
+

Review Comment:
   Same here for a comment.


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {

Review Comment:
   Just curious, why other encodings are not supported?


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   +1 for not adding a separate class. This would be difficult to maintain if more optimization will be added. It would be better if an option can be added so that user can manually turn it off when something goes wrong with the new feature.


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   When I was at previous employer, we have implemented mutable arrow::Array to address similar issue of ORC reader. The idea is that we can know in advance the total length of all string/binary values in a single batch. Therefore we can pre-allocate the data buffer at once or even reuse previous buffer if it has enough capacity. The overhead of buffer allocation and resize operation are non-negligible.

   @pitrou We have discussed the idea in  https://issues.apache.org/jira/browse/ARROW-15289


##########
cpp/src/parquet/encoding.cc:
##########
@@ -1412,6 +1423,57 @@ class PlainByteArrayDecoder : public PlainDecoder<ByteArrayType>,
     return Status::OK();
   }

+  Status DecodeArrowDenseZeroCopy(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int* out_values_decoded,
+                              int32_t* bianry_length) {

Review Comment:
   There are similar typos below.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1376878141

   > Sorry to hear you were sick @zhixingheyi-tian. I'll soon have a benchmark merged (#15100), and that will give us relevant results in [Conbench](https://github.com/voltrondata-labs/benchmarks) that will help the evaluate these changes.

   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wjones127 (via GitHub)" <gi...@apache.org>.
wjones127 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1398800527

   > How to reproduce the issue easily in cpp?

   I looked at it a bit more, and I'm actually not sure. It seems to be verifying the offsets buffer is all zeros when the array is composed only of empty string and nulls, which I can't get to fail in C++. I can help look at that further once other feedback is addressed in this PR.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1066405693


##########
cpp/src/parquet/column_reader.h:
##########
@@ -55,6 +55,8 @@ static constexpr uint32_t kDefaultMaxPageHeaderSize = 16 * 1024 * 1024;
 // 16 KB is the default expected page header size
 static constexpr uint32_t kDefaultPageHeaderSize = 16 * 1024;

+static constexpr int32_t kDefaultBinaryPerRowSzie = 20;

Review Comment:
   ```suggestion
   static constexpr int32_t kDefaultBinaryPerRowSize = 20;
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1377989081

   @zhixingheyi-tian Once you've fixed the issues mentioned, could you also rebase on the latest master branch? Once you do that we can run the benchmark.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1066409132


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   I've found locally that if I merge the implementations, the unit tests pass. Could you please merge them in the PR?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1067894864


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      hasCal_average_len_ = true;
+    }
+    offset_ = AllocateBuffer(this->pool_);
+    bianry_length_ = 0;
+    return result;
+  }
+  void ResetValues() {
+    if (values_written_ > 0) {
+      // Resize to 0, but do not shrink to fit
+      PARQUET_THROW_NOT_OK(valid_bits_->Resize(0, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize(0, false));
+      PARQUET_THROW_NOT_OK(values_->Resize(0, false));
+
+      values_written_ = 0;
+      values_capacity_ = 0;
+      null_count_ = 0;
+      bianry_length_ = 0;
+    }
+  }
+
+ private:
+  // Helper data structure for accumulating builder chunks
+  typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
+
+  int32_t bianry_length_ = 0;

Review Comment:
   done


##########
cpp/src/parquet/column_reader.h:
##########
@@ -55,6 +55,8 @@ static constexpr uint32_t kDefaultMaxPageHeaderSize = 16 * 1024 * 1024;
 // 16 KB is the default expected page header size
 static constexpr uint32_t kDefaultPageHeaderSize = 16 * 1024;

+static constexpr int32_t kDefaultBinaryPerRowSzie = 20;

Review Comment:
   done


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1067912170


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   @wjones127
   Do you merge the two class: ByteArrayChunkedRecordReader and ByteArrayChunkedOptRecordReader, ,  all unit tests passed?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "pitrou (via GitHub)" <gi...@apache.org>.
pitrou commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1084320045


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {
+        uses_opt_ = true;
+      }
+      hasSet_uses_opt_ = true;
+    }
   }

   int64_t available_values_current_page() const {
     return num_buffered_values_ - num_decoded_values_;
   }

+  bool hasSet_uses_opt_ = false;
+  bool uses_opt_ = false;

Review Comment:
   Hmm, also please find a more descriptive name than "uses optimization". (which optimization?)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wjones127 (via GitHub)" <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1083003326


##########
cpp/src/parquet/column_reader.h:
##########
@@ -370,6 +376,9 @@ class PARQUET_EXPORT RecordReader {
   int64_t values_capacity_;
   int64_t null_count_;

+  bool hasCal_average_len_ = false;
+  int64_t binary_per_row_length_ = kDefaultBinaryPerRowSize;

Review Comment:
   First, I think this would be clearer as a `std::optional`, rather than a boolean on the side.
   Second, please document the purpose of these fields in the header file.
   ```suggestion
     /// \brief Typical size of single binary value, used for pre-allocating value buffer.
     ///
     /// Before this is set, kDefaultBinaryPerRowSize is used. After the first
     /// batch of values, this is set to the size of the values buffer divided by
     /// the number of values.
     std::optional<int64_t> binary_per_row_length_ = std::nullopt;
   ```


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1959,6 +1972,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &binary_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &binary_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));

Review Comment:
   if we make this an option:
   ```suggestion
         int64_t per_row_length = binary_per_row_length_.value_or(kDefaultBinaryPerRowSize);
         PARQUET_THROW_NOT_OK(
             values_->Resize(new_values_capacity * per_row_length, false));
   ```


##########
cpp/src/parquet/column_reader.h:
##########
@@ -55,6 +55,8 @@ static constexpr uint32_t kDefaultMaxPageHeaderSize = 16 * 1024 * 1024;
 // 16 KB is the default expected page header size
 static constexpr uint32_t kDefaultPageHeaderSize = 16 * 1024;

+static constexpr int32_t kDefaultBinaryPerRowSize = 20;

Review Comment:
   Since this corresponds to `binary_per_row_length_`, could we make the names match? I'm thinking "bytes per row" is the best description here:

   ```suggestion
   static constexpr int32_t kDefaultBinaryBytesPerRow = 20;
   ```
   (Also change `binary_per_row_length_` to `binary_bytes_per_row_`)


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1959,6 +1972,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &binary_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &binary_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {

Review Comment:
   if we make it an optional:
   ```suggestion
       if (ARROW_PREDICT_FALSE(!binary_per_row_length_.has_value())) {
   ```


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1594,6 +1605,8 @@ class TypedRecordReader : public TypedColumnReaderImpl<DType>,
     }
   }

+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override { return nullptr; }

Review Comment:
   ```suggestion
     virtual std::shared_ptr<ResizableBuffer> ReleaseOffsets() { return nullptr; }
   ```


##########
cpp/src/parquet/column_reader.h:
##########
@@ -299,6 +303,8 @@ class PARQUET_EXPORT RecordReader {
   /// allocated in subsequent ReadRecords calls
   virtual std::shared_ptr<ResizableBuffer> ReleaseValues() = 0;

+  virtual std::shared_ptr<ResizableBuffer> ReleaseOffsets() = 0;
+

Review Comment:
   ```suggestion
   ```


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1697,7 +1710,7 @@ class TypedRecordReader : public TypedColumnReaderImpl<DType>,
     }
   }

-  void ReserveValues(int64_t extra_values) {
+  void ReserveValues(int64_t extra_values) override {

Review Comment:
   ```suggestion
     virtual void ReserveValues(int64_t extra_values) {
   ```


##########
cpp/src/parquet/column_reader.h:
##########
@@ -291,6 +293,8 @@ class PARQUET_EXPORT RecordReader {
   /// \brief Pre-allocate space for data. Results in better flat read performance
   virtual void Reserve(int64_t num_values) = 0;

+  virtual void ReserveValues(int64_t capacity) {}

Review Comment:
   Since these are coming from `TypeRecordReader`, which is private, could you mark it's methods as virtual instead?

   ```suggestion
   ```


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {
+        uses_opt_ = true;
+      }
+      hasSet_uses_opt_ = true;
+    }
   }

   int64_t available_values_current_page() const {
     return num_buffered_values_ - num_decoded_values_;
   }

+  bool hasSet_uses_opt_ = false;
+  bool uses_opt_ = false;

Review Comment:
   Could you create a separate function for that, as Yibo suggested? If you do measure a meaningful performance difference, could you share your results then?

   In addition, could you add a comment explaining why the optimization is only applicable to those those three encodings?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051752451


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {

Review Comment:
   Just follow https://github.com/apache/arrow/blob/f82501e763ff48af610077f9525ae83cc3ab2e95/cpp/src/parquet/column_reader.cc#L1271,

   Why different  renaming ways  for variables?

   Thank!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1348102047

   HI  @cyb70289 @jorisvandenbossche
   would you please give a review,
   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051823182


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   My gut feeling is still that they are not necessary. Though it might be wrong.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] github-actions[bot] commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
github-actions[bot] commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1272428180

   https://issues.apache.org/jira/browse/ARROW-17735


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1067902932


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      hasCal_average_len_ = true;
+    }
+    offset_ = AllocateBuffer(this->pool_);
+    bianry_length_ = 0;
+    return result;
+  }
+  void ResetValues() {
+    if (values_written_ > 0) {
+      // Resize to 0, but do not shrink to fit
+      PARQUET_THROW_NOT_OK(valid_bits_->Resize(0, false));

Review Comment:
   Just follow here: https://github.com/apache/arrow/blob/fc53ff8c5e2797c1a5a99db7f3aece80dd0b9f3e/cpp/src/parquet/column_reader.cc#L1846-L1851


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051755382


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   The optimized RecordReader implementation is ByteArrayChunkedOptRecordReader

    https://github.com/zhixingheyi-tian/arrow/blob/8d611c673d3ed23abfa32f50da3cc4c4e4feb807/cpp/src/parquet/column_reader.cc#L2203-L2206

   And is just for  Binary/String/LargeBinary/LargeString types.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051755382


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   The optimized RecordReader implementation is ByteArrayChunkedRecordReader

    https://github.com/zhixingheyi-tian/arrow/blob/8d611c673d3ed23abfa32f50da3cc4c4e4feb807/cpp/src/parquet/column_reader.cc#L2203-L2206

   And is just for  Binary/String/LargeBinary/LargeString types.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051809898


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {

Review Comment:
   Don't mix camel and snake case.
   `has_set_uses_opt`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1371316158

   Sorry to hear you were sick @zhixingheyi-tian. I'll soon have a benchmark merged (#15100), and that will give us relevant results in [Conbench](https://github.com/voltrondata-labs/benchmarks) that will help the evaluate these changes.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1346176669

   New failed UT "RecordReaderByteArrayTest.SkipByteArray" , came from newly commit #14142. This UT used the GetBuilderChunks() interface : https://github.com/apache/arrow/blame/6cfe24633b9fe3c474137571940eca35d7a475dc/cpp/src/parquet/column_reader_test.cc#L1181-L1185


   And this performance PR is avoiding this interface. So it failed.

   Any suggestions to fix this UT? Or change this UT?

   Thanks!


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051753030


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {
+        uses_opt_ = true;
+      }
+      hasSet_uses_opt_ = true;
+    }
   }

   int64_t available_values_current_page() const {
     return num_buffered_values_ - num_decoded_values_;
   }

+  bool hasSet_uses_opt_ = false;
+  bool uses_opt_ = false;

Review Comment:
   These two flags is for
   ` if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
             current_encoding_ == Encoding::PLAIN ||
             current_encoding_ == Encoding::RLE_DICTIONARY)`

   Just avoid comparing every time.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051746939


##########
cpp/src/parquet/column_reader.h:
##########
@@ -291,6 +293,8 @@ class PARQUET_EXPORT RecordReader {
   /// \brief Pre-allocate space for data. Results in better flat read performance
   virtual void Reserve(int64_t num_values) = 0;

+  virtual void ReserveValues(int64_t capacity) {}

Review Comment:
   Previously. it's TypedRecordReader internal interface, https://github.com/apache/arrow/blob/f82501e763ff48af610077f9525ae83cc3ab2e95/cpp/src/parquet/column_reader.cc#L1698-L1720.

   And ByteArrayChunkedOptRecordReader extends from TypedRecordReader, so extract it as public interface.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051812686


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow_opt(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow_opt(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      // std::cout << "binary_per_row_length_:" << binary_per_row_length_ << std::endl;

Review Comment:
   Looks there are other debug code not removed. Do remove all of them.
   `// RETURN_NOT_OK(IndexInBounds(idx));`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] cyb70289 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
cyb70289 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1051815984


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -850,12 +850,23 @@ class ColumnReaderImplBase {
     current_encoding_ = encoding;
     current_decoder_->SetData(static_cast<int>(num_buffered_values_), buffer,
                               static_cast<int>(data_size));
+    if (!hasSet_uses_opt_) {
+      if (current_encoding_ == Encoding::PLAIN_DICTIONARY ||
+          current_encoding_ == Encoding::PLAIN ||
+          current_encoding_ == Encoding::RLE_DICTIONARY) {
+        uses_opt_ = true;
+      }
+      hasSet_uses_opt_ = true;
+    }
   }

   int64_t available_values_current_page() const {
     return num_buffered_values_ - num_decoded_values_;
   }

+  bool hasSet_uses_opt_ = false;
+  bool uses_opt_ = false;

Review Comment:
   Try to make it simple. I don't think there's any performance consideration here.
   E.g., define a helper function
   `bool UsesOpt() const { return (current_encoding == xxx || ....; }`


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1350299053

   > Would you fix the CI failures?
   Thanks @cyb70289

   I am in fixing errors in github CI.
   For  "TestArrowReadDeltaEncoding.DeltaByteArray", why is skipped in my local testing? But showed failure on CI.
   ```
   # ./parquet-arrow-test --gtest_filter=TestArrowReadDeltaEncoding.DeltaByteArray
   Running main() from /home/shen/software/googletest/googletest/src/gtest_main.cc
   Note: Google Test filter = TestArrowReadDeltaEncoding.DeltaByteArray
   [==========] Running 1 test from 1 test suite.
   [----------] Global test environment set-up.
   [----------] 1 test from TestArrowReadDeltaEncoding
   [ RUN      ] TestArrowReadDeltaEncoding.DeltaByteArray
   [  SKIPPED ] TestArrowReadDeltaEncoding.DeltaByteArray (0 ms)
   [----------] 1 test from TestArrowReadDeltaEncoding (0 ms total)

   [----------] Global test environment tear-down
   [==========] 1 test from 1 test suite ran. (0 ms total)
   [  PASSED  ] 0 tests.
   [  SKIPPED ] 1 test, listed below:
   [  SKIPPED ] TestArrowReadDeltaEncoding.DeltaByteArray
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] amol- commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "amol- (via GitHub)" <gi...@apache.org>.
amol- commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1490648276

   Closing because it has been untouched for a while, in case it's still relevant feel free to reopen and move it forward 👍


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "wjones127 (via GitHub)" <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1082913149


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,139 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;

Review Comment:
   Yes, those are the two classes I merged.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] pitrou commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by "pitrou (via GitHub)" <gi...@apache.org>.
pitrou commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1084323975


##########
cpp/src/parquet/encoding.h:
##########
@@ -317,6 +317,13 @@ class TypedDecoder : virtual public Decoder {
                           int64_t valid_bits_offset,
                           typename EncodingTraits<DType>::Accumulator* out) = 0;

+  virtual int DecodeArrow_opt(int num_values, int null_count, const uint8_t* valid_bits,
+                              int32_t* offset,
+                              std::shared_ptr<::arrow::ResizableBuffer>& values,
+                              int64_t valid_bits_offset, int32_t* bianry_length) {
+    return 0;

Review Comment:
   Also, I'll say it again, but another possibility is to change the definition of `EncodingTraits<ByteArrayType>::Accumulator` from:
   ```c++
   template <>
   struct EncodingTraits<ByteArrayType> {
     using Encoder = ByteArrayEncoder;
     using Decoder = ByteArrayDecoder;

     /// \brief Internal helper class for decoding BYTE_ARRAY data where we can
     /// overflow the capacity of a single arrow::BinaryArray
     struct Accumulator {
       std::unique_ptr<::arrow::BinaryBuilder> builder;
       std::vector<std::shared_ptr<::arrow::Array>> chunks;
     };
     using ArrowType = ::arrow::BinaryType;
     using DictAccumulator = ::arrow::Dictionary32Builder<::arrow::BinaryType>;
   };
   ```
   to:
   ```c++
   template <>
   struct EncodingTraits<ByteArrayType> {
     using Encoder = ByteArrayEncoder;
     using Decoder = ByteArrayDecoder;

     /// \brief Internal helper class for decoding BYTE_ARRAY data where we can
     /// overflow the capacity of a single arrow::Int32Array
     struct Accumulator {
       std::unique_ptr<::arrow::Int32Builder> offsets_builder;
       std::unique_ptr<::arrow::BufferBuilder> data_builder;
       std::vector<std::shared_ptr<::arrow::Array>> chunks;
     };
     using ArrowType = ::arrow::BinaryType;
     using DictAccumulator = ::arrow::Dictionary32Builder<::arrow::BinaryType>;
   };
   ```

   Either this or @wjones127 's suggestion would be better than adding a specialized method, IMHO.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] wjones127 commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
wjones127 commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1066414394


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      hasCal_average_len_ = true;
+    }
+    offset_ = AllocateBuffer(this->pool_);
+    bianry_length_ = 0;
+    return result;
+  }
+  void ResetValues() {
+    if (values_written_ > 0) {
+      // Resize to 0, but do not shrink to fit
+      PARQUET_THROW_NOT_OK(valid_bits_->Resize(0, false));

Review Comment:
   I ran the unit tests (parquet-arrow-test) with a debugger, and found this branch was never hit. Does that seem right? Could you add a test that validates this branch?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on a diff in pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on code in PR #14353:
URL: https://github.com/apache/arrow/pull/14353#discussion_r1067896370


##########
cpp/src/parquet/column_reader.cc:
##########
@@ -1957,6 +1970,138 @@ class ByteArrayChunkedRecordReader : public TypedRecordReader<ByteArrayType>,
   typename EncodingTraits<ByteArrayType>::Accumulator accumulator_;
 };

+class ByteArrayChunkedOptRecordReader : public TypedRecordReader<ByteArrayType>,
+                                        virtual public BinaryRecordReader {
+ public:
+  ByteArrayChunkedOptRecordReader(const ColumnDescriptor* descr, LevelInfo leaf_info,
+                                  ::arrow::MemoryPool* pool)
+      : TypedRecordReader<ByteArrayType>(descr, leaf_info, pool) {
+    DCHECK_EQ(descr_->physical_type(), Type::BYTE_ARRAY);
+    accumulator_.builder.reset(new ::arrow::BinaryBuilder(pool));
+    values_ = AllocateBuffer(pool);
+    offset_ = AllocateBuffer(pool);
+  }
+
+  ::arrow::ArrayVector GetBuilderChunks() override {
+    if (uses_opt_) {
+      std::vector<std::shared_ptr<Buffer>> buffers = {ReleaseIsValid(), ReleaseOffsets(),
+                                                      ReleaseValues()};
+      auto data = std::make_shared<::arrow::ArrayData>(
+          ::arrow::binary(), values_written(), buffers, null_count());
+
+      auto chunks = ::arrow::ArrayVector({::arrow::MakeArray(data)});
+      return chunks;
+    } else {
+      ::arrow::ArrayVector result = accumulator_.chunks;
+      if (result.size() == 0 || accumulator_.builder->length() > 0) {
+        std::shared_ptr<::arrow::Array> last_chunk;
+        PARQUET_THROW_NOT_OK(accumulator_.builder->Finish(&last_chunk));
+        result.push_back(std::move(last_chunk));
+      }
+      accumulator_.chunks = {};
+      return result;
+    }
+  }
+
+  void ReadValuesDense(int64_t values_to_read) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), 0, NULLPTR,
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, 0, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowNonNull(
+          static_cast<int>(values_to_read), &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read);
+      ResetValues();
+    }
+  }
+
+  void ReadValuesSpaced(int64_t values_to_read, int64_t null_count) override {
+    if (uses_opt_) {
+      int64_t num_decoded = this->current_decoder_->DecodeArrowZeroCopy(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(),
+          (reinterpret_cast<int32_t*>(offset_->mutable_data()) + values_written_),
+          values_, values_written_, &bianry_length_);
+      DCHECK_EQ(num_decoded, values_to_read - null_count);
+    } else {
+      int64_t num_decoded = this->current_decoder_->DecodeArrow(
+          static_cast<int>(values_to_read), static_cast<int>(null_count),
+          valid_bits_->mutable_data(), values_written_, &accumulator_);
+      CheckNumberDecoded(num_decoded, values_to_read - null_count);
+      ResetValues();
+    }
+  }
+
+  void ReserveValues(int64_t extra_values) override {
+    const int64_t new_values_capacity =
+        UpdateCapacity(values_capacity_, values_written_, extra_values);
+    if (new_values_capacity > values_capacity_) {
+      PARQUET_THROW_NOT_OK(
+          values_->Resize(new_values_capacity * binary_per_row_length_, false));
+      PARQUET_THROW_NOT_OK(offset_->Resize((new_values_capacity + 1) * 4, false));
+
+      auto offset = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      offset[0] = 0;
+
+      values_capacity_ = new_values_capacity;
+    }
+    if (leaf_info_.HasNullableValues()) {
+      int64_t valid_bytes_new = bit_util::BytesForBits(values_capacity_);
+      if (valid_bits_->size() < valid_bytes_new) {
+        int64_t valid_bytes_old = bit_util::BytesForBits(values_written_);
+        PARQUET_THROW_NOT_OK(valid_bits_->Resize(valid_bytes_new, false));
+        // Avoid valgrind warnings
+        memset(valid_bits_->mutable_data() + valid_bytes_old, 0,
+               valid_bytes_new - valid_bytes_old);
+      }
+    }
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseValues() override {
+    auto result = values_;
+    values_ = AllocateBuffer(this->pool_);
+    values_capacity_ = 0;
+    return result;
+  }
+  std::shared_ptr<ResizableBuffer> ReleaseOffsets() override {
+    auto result = offset_;
+    if (ARROW_PREDICT_FALSE(!hasCal_average_len_)) {
+      auto offsetArr = reinterpret_cast<int32_t*>(offset_->mutable_data());
+      const auto first_offset = offsetArr[0];
+      const auto last_offset = offsetArr[values_written_];
+      int64_t binary_length = last_offset - first_offset;
+      binary_per_row_length_ = binary_length / values_written_ + 1;
+      hasCal_average_len_ = true;
+    }
+    offset_ = AllocateBuffer(this->pool_);
+    bianry_length_ = 0;
+    return result;
+  }
+  void ResetValues() {
+    if (values_written_ > 0) {
+      // Resize to 0, but do not shrink to fit
+      PARQUET_THROW_NOT_OK(valid_bits_->Resize(0, false));

Review Comment:
   > @zhixingheyi-tian Once you've fixed the issues mentioned, could you also rebase on the latest master branch? Once you do that we can run the benchmark.

   Have rebased. Performance can refer to https://github.com/apache/arrow/pull/14353#issue-1402114514


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1356149240

   cc @raulcd


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [arrow] zhixingheyi-tian commented on pull request #14353: ARROW-17735: [C++][Parquet] Optimize parquet reading for String/Binary type
Posted by GitBox <gi...@apache.org>.
zhixingheyi-tian commented on PR #14353:
URL: https://github.com/apache/arrow/pull/14353#issuecomment-1346200212
> Hi @zhixingheyi-tian, sorry this hasn't gotten reviewer attention for a while. Are you still interested in working on this?
>
> Would you mind rebasing and cleaning up any commented code?
>
> In addition, I noticed there aren't any benchmarks for binary or string types in either of these two benchmark files:
>
> * `src/parquet/arrow/reader_writer_benchmark.cc`
> * `src/parquet/parquet_encoding_benchmark.cc`
>
> We'll want some benchmarks in order to evaluate the changes. If you add those, then you can compare benchmarks locally like so:
>
> ```shell
> BUILD_DIR=cpp/path/to/build
>
> archery benchmark run $BUILD_DIR \
> --suite-filter=parquet-arrow-reader-writer-benchmark \
> --output=contender.json
>
> git checkout master # Or some ref that has benchmarks but not your changes
>
> archery benchmark run $BUILD_DIR \
> --suite-filter=parquet-arrow-reader-writer-benchmark \
> --output=baseline.json
>
> archery benchmark diff contender.json baseline.json
> ```
Hi @wjones127
Good idea to show performance.
How to add Binary/String benchmark in *benchmark.cc,
I noticed currently Arrow benchmark testing had not support generating random binary data.
In my local server end-2-end performance testing:
`Generate one parquet file with dictionary-encoding (100M rows, 10 Cols)
Run parquet with one thread on CentOS 7.6`
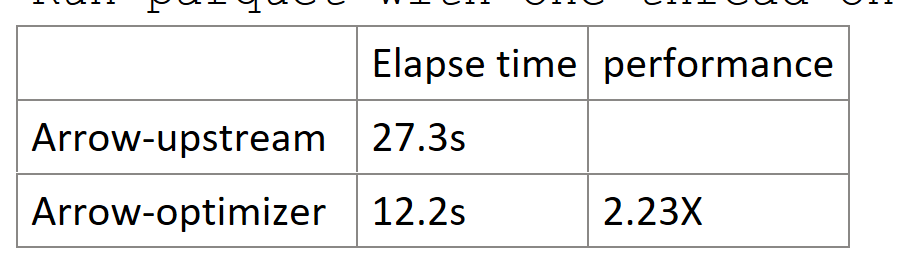
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: github-unsubscribe@arrow.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org