You are viewing a plain text version of this content. The canonical link for it is here.
Posted to reviews@spark.apache.org by cfangplus <gi...@git.apache.org> on 2018/09/05 05:10:28 UTC
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
GitHub user cfangplus opened a pull request:
https://github.com/apache/spark/pull/22335
[SPARK-25091][SQL] reduce the storage memory in Executor Tab when …
…unpersist rdd
@zsxwing
@vanzin
@attilapiros
## What changes were proposed in this pull request?
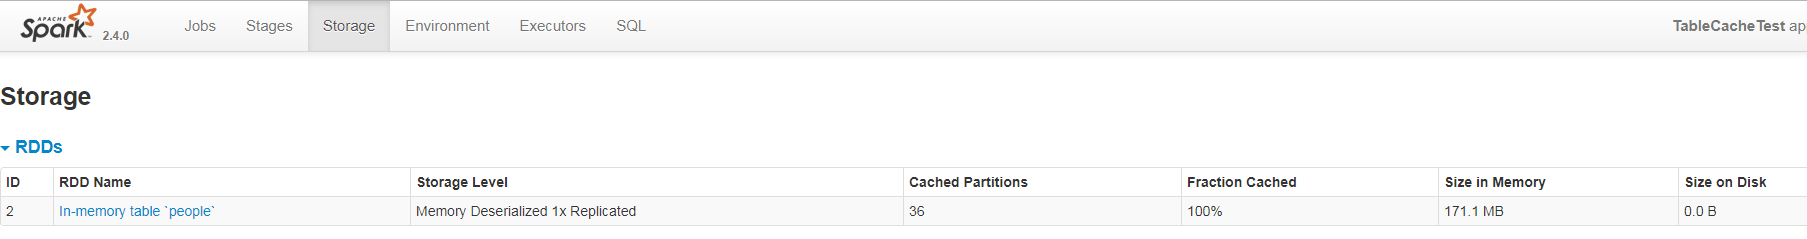
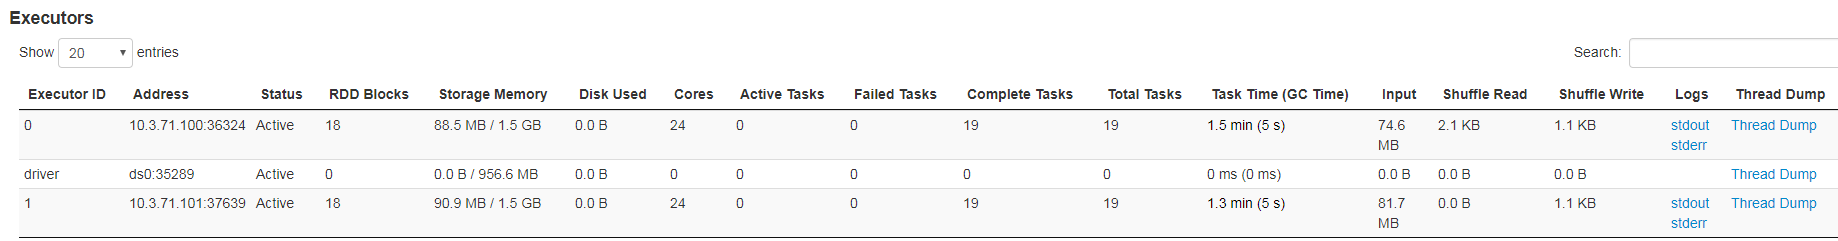
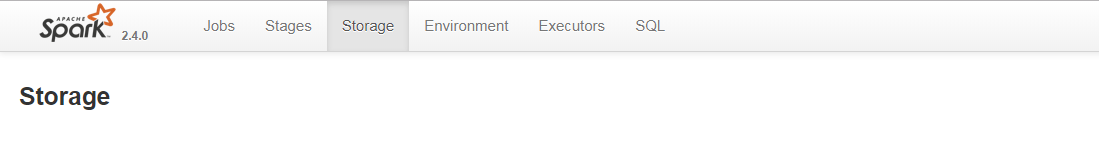
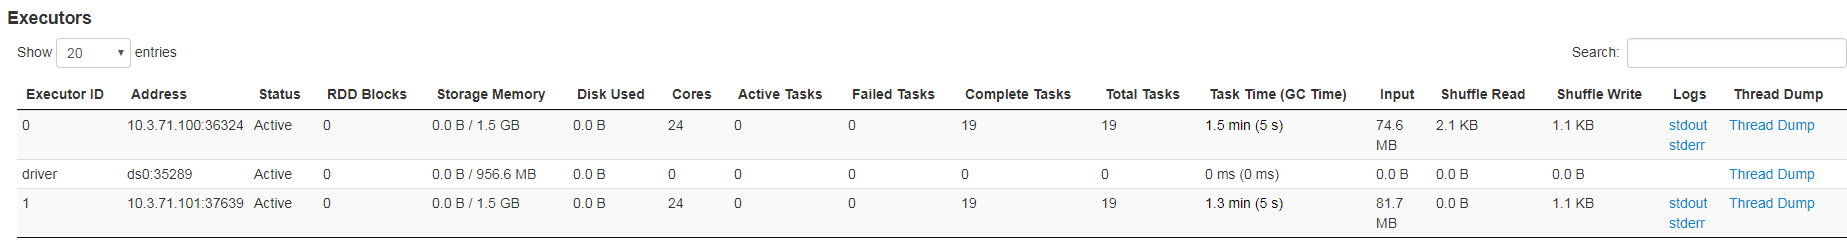
This issue is a UI issue. When we unpersist rdd or UNCACHE TABLE,the storage memory size in Executor tab could not be reduced. So I modify code as follow:
1,BlockManager send block status to BlockManagerMaster after it removed the block
2,AppStatusListener receive block remove status and modify LiveRDD and LiveExecutor info, so the storage memory size and rdd blocks in Executor Tab could change when we unpersist rdd.
## How was this patch tested?
cache table and then unpersist table. Watch the WebUI for both storage and executor tab.
You can merge this pull request into a Git repository by running:
$ git pull https://github.com/cfangplus/spark master
Alternatively you can review and apply these changes as the patch at:
https://github.com/apache/spark/pull/22335.patch
To close this pull request, make a commit to your master/trunk branch
with (at least) the following in the commit message:
This closes #22335
----
commit 5955fa6c6daa3d345046fc1e1fdc6e7eb73cd5e2
Author: cfangplus <cf...@...>
Date: 2018-09-04T13:14:12Z
[SPARK-25091][WEB UI] reduce the storage memory in Executor Tab when unpersist rdd
----
---
---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][Core] reduce the storage memory in Executo...
Posted by cfangplus <gi...@git.apache.org>.
Github user cfangplus commented on the issue:

    https://github.com/apache/spark/pull/22335

    viirya did a great job, seems this pr should be closed.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][Core] reduce the storage memory in Executo...
Posted by viirya <gi...@git.apache.org>.
Github user viirya commented on the issue:

    https://github.com/apache/spark/pull/22335

    Yea, looks like this is duplicate to #22341.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by cfangplus <gi...@git.apache.org>.
Github user cfangplus commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r216123864

    --- Diff: core/src/main/scala/org/apache/spark/status/AppStatusListener.scala ---
    @@ -646,8 +646,17 @@ private[spark] class AppStatusListener(
       }

       override def onUnpersistRDD(event: SparkListenerUnpersistRDD): Unit = {
    -    liveRDDs.remove(event.rddId)
    -    kvstore.delete(classOf[RDDStorageInfoWrapper], event.rddId)
    +    while (true) {
    --- End diff --

    hi kiszk, thank you for your thread safe remind.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][SQL] reduce the storage memory in Executor...
Posted by AmplabJenkins <gi...@git.apache.org>.
Github user AmplabJenkins commented on the issue:

    https://github.com/apache/spark/pull/22335

    Can one of the admins verify this patch?


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by vanzin <gi...@git.apache.org>.
Github user vanzin commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215359589

    --- Diff: core/src/main/scala/org/apache/spark/status/LiveEntity.scala ---
    @@ -509,6 +507,10 @@ private class LiveRDD(val info: RDDInfo) extends LiveEntity {

       private val distributions = new HashMap[String, LiveRDDDistribution]()

    +  def isEmpty(): Boolean = {
    +    memoryUsed == 0L && diskUsed == 0L && partitions.isEmpty && distributions.isEmpty
    --- End diff --

    Shouldn't this be the equivalent of `storageLevel == None` instead? That's what 2.2 does:

    https://github.com/apache/spark/blob/branch-2.2/core/src/main/scala/org/apache/spark/storage/StorageStatusListener.scala#L52


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by vanzin <gi...@git.apache.org>.
Github user vanzin commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215360659

    --- Diff: core/src/main/scala/org/apache/spark/status/AppStatusListener.scala ---
    @@ -710,9 +719,21 @@ private[spark] class AppStatusListener(
         val executorId = event.blockUpdatedInfo.blockManagerId.executorId

         // Whether values are being added to or removed from the existing accounting.
    +    // BlockManager always send empty block status message when user try to remove rdd block,
    +    // so we try to get this removed block size from rdd partition to get accurate memory/disk storage size.
         val storageLevel = event.blockUpdatedInfo.storageLevel
    -    val diskDelta = event.blockUpdatedInfo.diskSize * (if (storageLevel.useDisk) 1 else -1)
    -    val memoryDelta = event.blockUpdatedInfo.memSize * (if (storageLevel.useMemory) 1 else -1)
    +    val diskDelta: Long = storageLevel != StorageLevel.NONE match {
    --- End diff --

    A simple `if` is much clearer (and probably faster) here. But see later comment. I believe it's better for this code to be in the "unpersist" callback, and leave the block manager code unchanged.

    This code is also wrong the way it is. Because if you're changing the storage level of an RDD (e.g. if it was cached on disk, but after the update, it's not) then this is doing the wrong thing now.

    (So, another argument for treating the "unpersist" event differently, and in the appropriate callback.)


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][Core] reduce the storage memory in Executo...
Posted by kiszk <gi...@git.apache.org>.
Github user kiszk commented on the issue:

    https://github.com/apache/spark/pull/22335

    @cfangplus just for your information, #22341 is modifying the similar parts in `AppStatusListener.scala`.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][SQL] reduce the storage memory in Executor...
Posted by vanzin <gi...@git.apache.org>.
Github user vanzin commented on the issue:

    https://github.com/apache/spark/pull/22335

    Also, this should be `[core]` not `[sql]`.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][Core] reduce the storage memory in ...
Posted by cfangplus <gi...@git.apache.org>.
Github user cfangplus closed the pull request at:

    https://github.com/apache/spark/pull/22335


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by vanzin <gi...@git.apache.org>.
Github user vanzin commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215360036

    --- Diff: core/src/main/scala/org/apache/spark/storage/BlockManager.scala ---
    @@ -1549,7 +1549,7 @@ private[spark] class BlockManager(
         // TODO: Avoid a linear scan by creating another mapping of RDD.id to blocks.
         logInfo(s"Removing RDD $rddId")
         val blocksToRemove = blockInfoManager.entries.flatMap(_._1.asRDDId).filter(_.rddId == rddId)
    -    blocksToRemove.foreach { blockId => removeBlock(blockId, tellMaster = false) }
    --- End diff --

    I don't think this should be changing. Instead, the `onUnpersistRDD` callback in the listener should be updating the executor data it's tracking when the RDD is being unpersisted. That's similar to what I understand was being done in 2.2.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by vanzin <gi...@git.apache.org>.
Github user vanzin commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215359111

    --- Diff: core/src/main/scala/org/apache/spark/status/LiveEntity.scala ---
    @@ -120,7 +118,7 @@ private class LiveTask(
         stageAttemptId: Int,
         lastUpdateTime: Option[Long]) extends LiveEntity {

    -  import LiveEntityHelpers._
    --- End diff --

    None of these import changes are necessary...


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by kiszk <gi...@git.apache.org>.
Github user kiszk commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215452975

    --- Diff: core/src/main/scala/org/apache/spark/status/AppStatusListener.scala ---
    @@ -646,8 +646,17 @@ private[spark] class AppStatusListener(
       }

       override def onUnpersistRDD(event: SparkListenerUnpersistRDD): Unit = {
    -    liveRDDs.remove(event.rddId)
    -    kvstore.delete(classOf[RDDStorageInfoWrapper], event.rddId)
    +    while (true) {
    --- End diff --

    Thank you for letting me know about a single thread.

    I agree with your point. As you pointed out, when `rdd.isEmpty()` continues to return `false`, it will get into an infinite loop. Thus, I imagine that this works under multithread.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by vanzin <gi...@git.apache.org>.
Github user vanzin commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215358096

    --- Diff: core/src/main/scala/org/apache/spark/status/AppStatusListener.scala ---
    @@ -646,8 +646,17 @@ private[spark] class AppStatusListener(
       }

       override def onUnpersistRDD(event: SparkListenerUnpersistRDD): Unit = {
    -    liveRDDs.remove(event.rddId)
    -    kvstore.delete(classOf[RDDStorageInfoWrapper], event.rddId)
    +    while (true) {
    --- End diff --

    There's a single thread that calls this method (or any other listener method in this class). But I'm kinda wondering what's the point of the loop in the first place...

    It seems you'll get into an infinite loop if for some reason `rdd.isEmpty()` returns false.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by cfangplus <gi...@git.apache.org>.
Github user cfangplus commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r216123919

    --- Diff: core/src/main/scala/org/apache/spark/status/LiveEntity.scala ---
    @@ -33,7 +29,9 @@ import org.apache.spark.storage.RDDInfo
     import org.apache.spark.ui.SparkUI
     import org.apache.spark.util.AccumulatorContext
     import org.apache.spark.util.collection.OpenHashSet
    -import org.apache.spark.util.kvstore.KVStore
    +
    +import scala.collection.immutable.{HashSet, TreeSet}
    +import scala.collection.mutable.HashMap

    --- End diff --

    My IDE automatically changed that order, I think we import classes in order is ok, so remained that.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][SQL] reduce the storage memory in Executor...
Posted by felixcheung <gi...@git.apache.org>.
Github user felixcheung commented on the issue:

    https://github.com/apache/spark/pull/22335

    please fix the description for this PR - the top part contains the truncated title


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][SQL] reduce the storage memory in Executor...
Posted by AmplabJenkins <gi...@git.apache.org>.
Github user AmplabJenkins commented on the issue:

    https://github.com/apache/spark/pull/22335

    Can one of the admins verify this patch?


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by kiszk <gi...@git.apache.org>.
Github user kiszk commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215147974

    --- Diff: core/src/main/scala/org/apache/spark/status/LiveEntity.scala ---
    @@ -33,7 +29,9 @@ import org.apache.spark.storage.RDDInfo
     import org.apache.spark.ui.SparkUI
     import org.apache.spark.util.AccumulatorContext
     import org.apache.spark.util.collection.OpenHashSet
    -import org.apache.spark.util.kvstore.KVStore
    +
    +import scala.collection.immutable.{HashSet, TreeSet}
    +import scala.collection.mutable.HashMap

    --- End diff --

    nit: Is it necessary to change order of `import`?


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by kiszk <gi...@git.apache.org>.
Github user kiszk commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r215149786

    --- Diff: core/src/main/scala/org/apache/spark/status/AppStatusListener.scala ---
    @@ -646,8 +646,17 @@ private[spark] class AppStatusListener(
       }

       override def onUnpersistRDD(event: SparkListenerUnpersistRDD): Unit = {
    -    liveRDDs.remove(event.rddId)
    -    kvstore.delete(classOf[RDDStorageInfoWrapper], event.rddId)
    +    while (true) {
    --- End diff --

    This code may never cause infinite loop.
    Since `liveRDDs` is just a `HashMap` (not a `concurrentHashMap` or others), update by other threads may not be visible in this loop.


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #22335: [SPARK-25091][SQL] reduce the storage memory in E...
Posted by cfangplus <gi...@git.apache.org>.
Github user cfangplus commented on a diff in the pull request:

    https://github.com/apache/spark/pull/22335#discussion_r216123775

    --- Diff: core/src/main/scala/org/apache/spark/status/AppStatusListener.scala ---
    @@ -710,9 +719,21 @@ private[spark] class AppStatusListener(
         val executorId = event.blockUpdatedInfo.blockManagerId.executorId

         // Whether values are being added to or removed from the existing accounting.
    +    // BlockManager always send empty block status message when user try to remove rdd block,
    +    // so we try to get this removed block size from rdd partition to get accurate memory/disk storage size.
         val storageLevel = event.blockUpdatedInfo.storageLevel
    -    val diskDelta = event.blockUpdatedInfo.diskSize * (if (storageLevel.useDisk) 1 else -1)
    -    val memoryDelta = event.blockUpdatedInfo.memSize * (if (storageLevel.useMemory) 1 else -1)
    +    val diskDelta: Long = storageLevel != StorageLevel.NONE match {
    --- End diff --

    hi vanzin, Great thanks for you advice. Now I will try to modify code only in unpersist method in AppStatusListener class. I still have some quesions, could you help to explain,
    1, As I know a spark task is executed with a rdd partition in one Executor process. So why does LiveRDDPartition class has a seq executors not just an executor?
    2, I believe that we also need to reduce rdd block number in executor tab when we unpersist rdd, but now rdd blocks info is only held by LiveExecutor which in fact held rdd blocks number for all of the rdds. So as you can see the 842 line in AppStatusListener as follow, https://github.com/apache/spark/blob/master/core/src/main/scala/org/apache/spark/status/AppStatusListener.scala#L842
    I think the condition 'exec.rddBlocks + rddBlocksDelta > 0' in if block needs to be modified as 'LiveRDDDistribution.rddBlocks + rddBlocksDelta > 0' which means we use LiveRDDDistribution to hold rdd blocks info for paticular rdd in particular executor. Is that OK?


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #22335: [SPARK-25091][SQL] reduce the storage memory in Executor...
Posted by AmplabJenkins <gi...@git.apache.org>.
Github user AmplabJenkins commented on the issue:

    https://github.com/apache/spark/pull/22335

    Can one of the admins verify this patch?


---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org