You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@daffodil.apache.org by GitBox <gi...@apache.org> on 2021/03/09 14:20:43 UTC
[GitHub] [daffodil] regetom commented on pull request #481: ADD test for "%%" to bypass existing test for "%NL"
regetom commented on pull request #481:
URL: https://github.com/apache/daffodil/pull/481#issuecomment-793960178
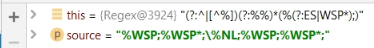
With some help from John Wass I have been attempting to fix the problems causing the unit test failures. The failure of testLengthKindDelimited2 in daffodil-core/src/test//scala/general/testPrimitives.scala has me stumped. The test defines an element name "e1" that contains a complex type with <xs:sequence dfdl:separator="%WSP;%WSP*;\%NL;%WSP;%WSP*;" dfdl:separatorPosition="infix">. After the complex type definition it calls TestUtils.testString(sch, "abcd \\\n efgh"). .TestUtils.testString calls runSchemaOnData(testSchema, Misc.stringToReadableByteChannel(data), areTracing).. runSchemaOnData calls Compiler.compileNode(testSchema). Eventually evDelimiters.DelimiterEvlMixin.evalAndConvert calls converter.convertConstant(expressionResult, ci, false) with expressionResult = "%WSP;%WSP*;\%NL;%WSP;%WSP*;". This results in a call to testRaw in DelimiterCookerNoES class of EntityReplacer.scal with raw = "%WSP;%WSP*;\%NL;%WSP;%WSP*;". This is where the error message "Property dfd
l:separator contains disallowed character classes: %WSP;, %WSP;" is coming from. When match Iterator is called it seems like the values to match are correct, but the returned result is "%WSP, %WSP".
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org