You are viewing a plain text version of this content. The canonical link for it is here.
Posted to reviews@spark.apache.org by rishabhbhardwaj <gi...@git.apache.org> on 2017/06/10 18:44:54 UTC
[GitHub] spark pull request #18263: [SPARK-21039] [Spark Core] Use treeAggregate inst...
GitHub user rishabhbhardwaj opened a pull request:

    https://github.com/apache/spark/pull/18263

    [SPARK-21039] [Spark Core] Use treeAggregate instead of aggregate in DataFrame.stat.bloomFilter

    ## What changes were proposed in this pull request?
    To use treeAggregate instead of aggregate in DataFrame.stat.bloomFilter to parallelize the operation of merging the bloom filters
    (Please fill in changes proposed in this fix)

    ## How was this patch tested?
    unit tests passed
    (Please explain how this patch was tested. E.g. unit tests, integration tests, manual tests)
    (If this patch involves UI changes, please attach a screenshot; otherwise, remove this)

    Please review http://spark.apache.org/contributing.html before opening a pull request.


You can merge this pull request into a Git repository by running:

    $ git pull https://github.com/rishabhbhardwaj/spark SPARK-21039

Alternatively you can review and apply these changes as the patch at:

    https://github.com/apache/spark/pull/18263.patch

To close this pull request, make a commit to your master/trunk branch
with (at least) the following in the commit message:

    This closes #18263

----

----


---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #18263: [SPARK-21039] [Spark Core] Use treeAggregate instead of ...
Posted by SparkQA <gi...@git.apache.org>.
Github user SparkQA commented on the issue:

    https://github.com/apache/spark/pull/18263

    **[Test build #3796 has started](https://amplab.cs.berkeley.edu/jenkins/job/NewSparkPullRequestBuilder/3796/testReport)** for PR 18263 at commit [`61bb509`](https://github.com/apache/spark/commit/61bb509e33614e63cbb8908593c88d424b635430).


---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #18263: [SPARK-21039] [Spark Core] Use treeAggregate instead of ...
Posted by lovasoa <gi...@git.apache.org>.
Github user lovasoa commented on the issue:
https://github.com/apache/spark/pull/18263
## Smaller data
You might be wondering: what about smaller data ?
Adding a stage to the computation of course adds some overhead.
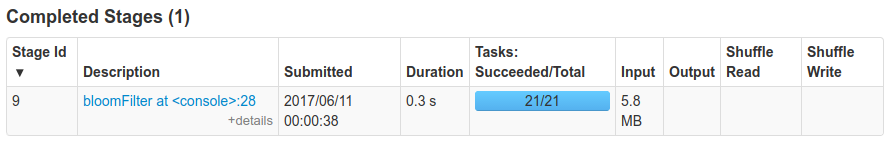
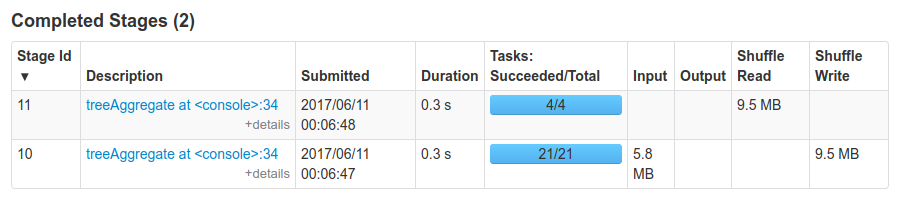
I repeated the same experiment as mentioned above, but with a scale factor of 1, (and 1.5M elements in the bloom filter).
### With `RDD.aggregate`
### With `RDD.treeAggregate`
## conclusion
There is indeed an overhead, but it is quite small. For the creation of a small bloom filter, the old method (with `aggregate`) takes 0.3 seconds, and the new one (with `treeAggregate`) 0.6 seconds.
---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---
---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #18263: [SPARK-21039] [Spark Core] Use treeAggregate instead of ...
Posted by AmplabJenkins <gi...@git.apache.org>.
Github user AmplabJenkins commented on the issue:

    https://github.com/apache/spark/pull/18263

    Can one of the admins verify this patch?


---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark pull request #18263: [SPARK-21039] [Spark Core] Use treeAggregate inst...
Posted by asfgit <gi...@git.apache.org>.
Github user asfgit closed the pull request at:

    https://github.com/apache/spark/pull/18263


---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #18263: [SPARK-21039] [Spark Core] Use treeAggregate instead of ...
Posted by srowen <gi...@git.apache.org>.
Github user srowen commented on the issue:

    https://github.com/apache/spark/pull/18263

    Merged to master


---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #18263: [SPARK-21039] [Spark Core] Use treeAggregate instead of ...
Posted by HyukjinKwon <gi...@git.apache.org>.
Github user HyukjinKwon commented on the issue:

    https://github.com/apache/spark/pull/18263

    I think we need some figures here. Would you test before/after and share some figures?


---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #18263: [SPARK-21039] [Spark Core] Use treeAggregate instead of ...
Posted by lovasoa <gi...@git.apache.org>.
Github user lovasoa commented on the issue:
https://github.com/apache/spark/pull/18263
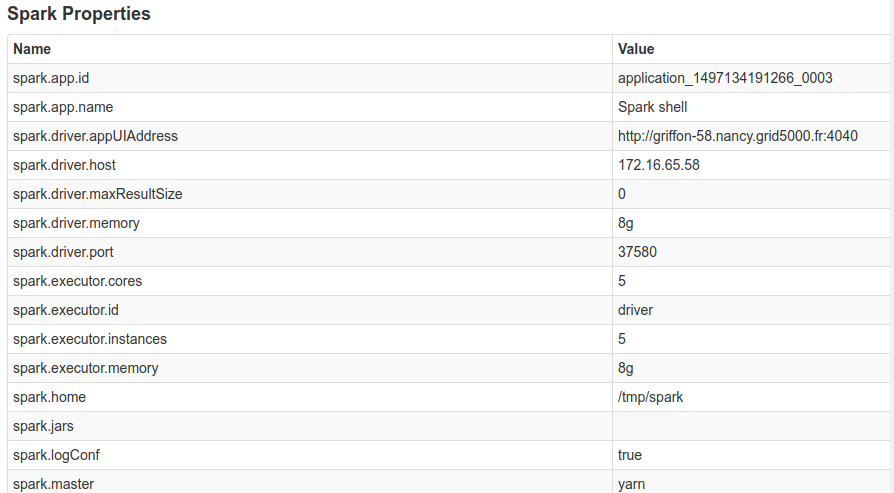
I ran some tests on a cluster with 5 nodes, creating a bloomfilter (with an fpp of 10%) of the column `o_orderkey` of the table `ORDERS` of TPC-H with a scale factor of 100.
## The cluster
## Results
### Using `RDD.aggregate`
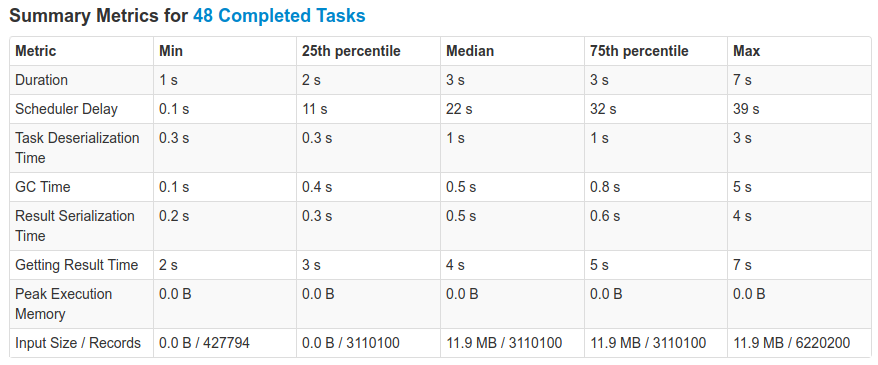
Notice the huge scheduler delay.
** total time: 52 seconds**
### Using `RDD.treeAggregate`
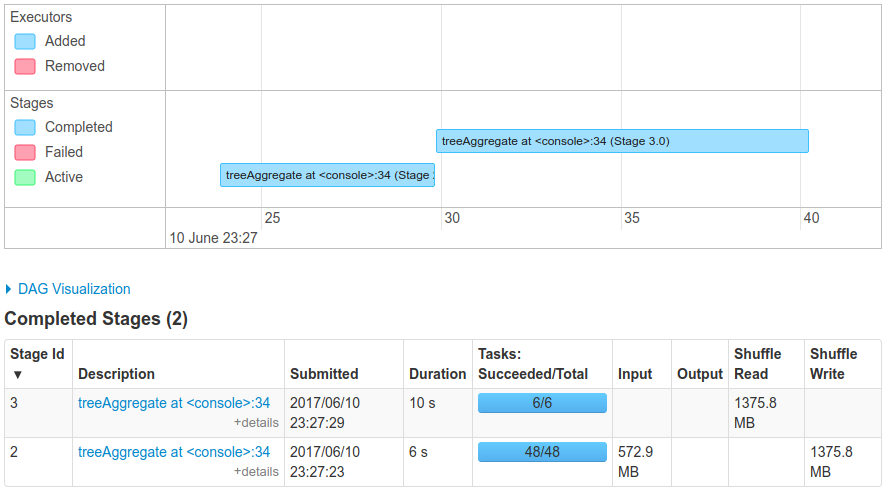
#### first stage
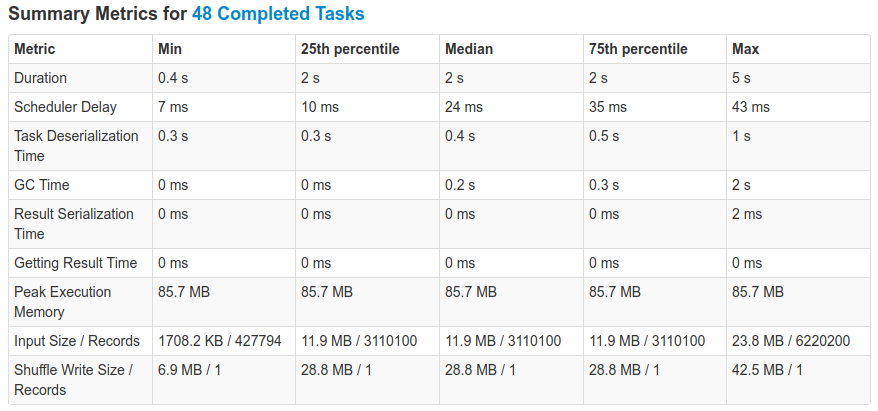
#### second stage
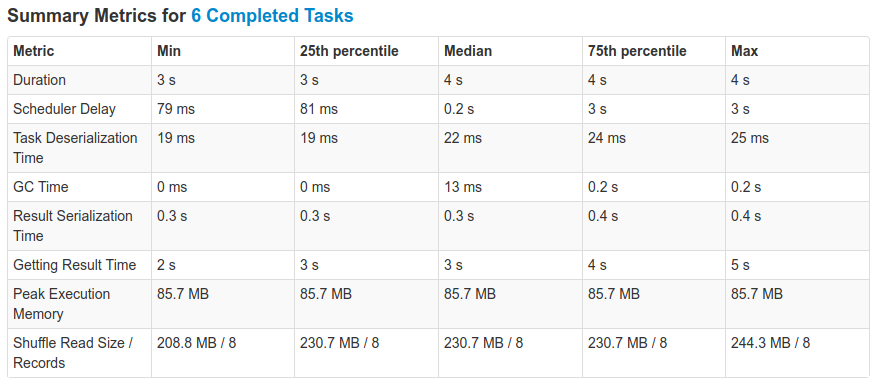
** total time: 17 seconds**
---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---
---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org
[GitHub] spark issue #18263: [SPARK-21039] [Spark Core] Use treeAggregate instead of ...
Posted by SparkQA <gi...@git.apache.org>.
Github user SparkQA commented on the issue:

    https://github.com/apache/spark/pull/18263

    **[Test build #3796 has finished](https://amplab.cs.berkeley.edu/jenkins/job/NewSparkPullRequestBuilder/3796/testReport)** for PR 18263 at commit [`61bb509`](https://github.com/apache/spark/commit/61bb509e33614e63cbb8908593c88d424b635430).
     * This patch passes all tests.
     * This patch merges cleanly.
     * This patch adds no public classes.


---
If your project is set up for it, you can reply to this email and have your
reply appear on GitHub as well. If your project does not have this feature
enabled and wishes so, or if the feature is enabled but not working, please
contact infrastructure at infrastructure@apache.org or file a JIRA ticket
with INFRA.
---

---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org