You are viewing a plain text version of this content. The canonical link for it is here.
Posted to notifications@shardingsphere.apache.org by pa...@apache.org on 2020/08/21 08:26:05 UTC
[shardingsphere] branch master updated: Update proxy.en.md
This is an automated email from the ASF dual-hosted git repository.
panjuan pushed a commit to branch master
in repository https://gitbox.apache.org/repos/asf/shardingsphere.git
The following commit(s) were added to refs/heads/master by this push:
new 1314b07 Update proxy.en.md
new db1334f Merge pull request #6965 from yang-7777/patch-1
1314b07 is described below
commit 1314b07348ac0af36d1e8fe62535b15b849b6a18
Author: yang-7777 <67...@users.noreply.github.com>
AuthorDate: Fri Aug 21 14:53:57 2020 +0800
Update proxy.en.md
---
docs/blog/content/material/proxy.en.md | 71 +++++++++++++++++-----------------
1 file changed, 36 insertions(+), 35 deletions(-)
diff --git a/docs/blog/content/material/proxy.en.md b/docs/blog/content/material/proxy.en.md
index 1907a7e..4d2e91e 100644
--- a/docs/blog/content/material/proxy.en.md
+++ b/docs/blog/content/material/proxy.en.md
@@ -10,11 +10,11 @@ chapter = true
**Yonglun Zhang**: Senior software engineer of operation and maintenance department at JD Finance
-He has been working on software development for years engaged in traditional Industry. Afterwards he was involved in Internet and started his crawler career at JD Finance, sigh at the huge amount of Internet data since then. It's great honor to join Sharding-Sphere this year and be able to do what he is interested in, he hopes to improve himself and contribute to the community.
+He has been working on software development for years engaged in traditional Industry. Afterwards he was involved in Internet and started his web crawler career at JD Finance, sigh at the huge amount of Internet data since then. It's great honor to join ShardingSphere this year and be able to do what he is interested in, he hopes to improve himself and contribute to the community.
-Hello everyone, I'm so glad to show you Sharding-Proxy, which is the second product of Sharding-Sphere.
+Hello everyone, I'm so glad to show you Sharding-Proxy, which is the second product of ShardingSphere.
-It was first released with Sharding-Sphere 3.0.0.M1 last month. I hope you can have visualize of overall view for Sharding-Proxy through several optimizing practices. With regard to topics of MySQL protocol, IO, Netty, etc. I'll share related themes when having an opportunity.
+It was first released with ShardingSphere 3.0.0.M1 last month. I hope you can have visualize of overall view for Sharding-Proxy through several optimizing practices. With regard to topics of MySQL protocol, IO, Netty, etc. I'll share related themes next time.
### 01 Sharding-Proxy Introduction
@@ -48,20 +48,20 @@ The whole architecture can be divided into three components: Frontend, Core-modu
* Frontend: It's responsible for communication with client, based on NIO client/server framework. It adopts to NIO on Windows and Mac, adaptive to Epoll automatically on Linux, and completes to the encoding/decoding of MySQL protocol in the process of communication.
-* Core-module: After getting decoded command of MySQL, it starts to parse/rewrite/route/conflate sql through Sharding-Core.
+* Core-module: After getting decoded command of MySQL, it starts to parse/rewrite/route/conflate SQL through Sharding-Core.
-* Backend: it's interacted with real database by Hikari pool of BIO. Its performance declines on condition of one master more slaves or large scale to database cluser in the way of BIO, so we will provide way of NIO to connect real database in the future.
+* Backend: it's interacted with real database by Hikari pool of BIO. Its performance declines on condition of one master more slaves or large scale to database cluster in the way of BIO, so we will provide way of NIO to connect real database in the future.
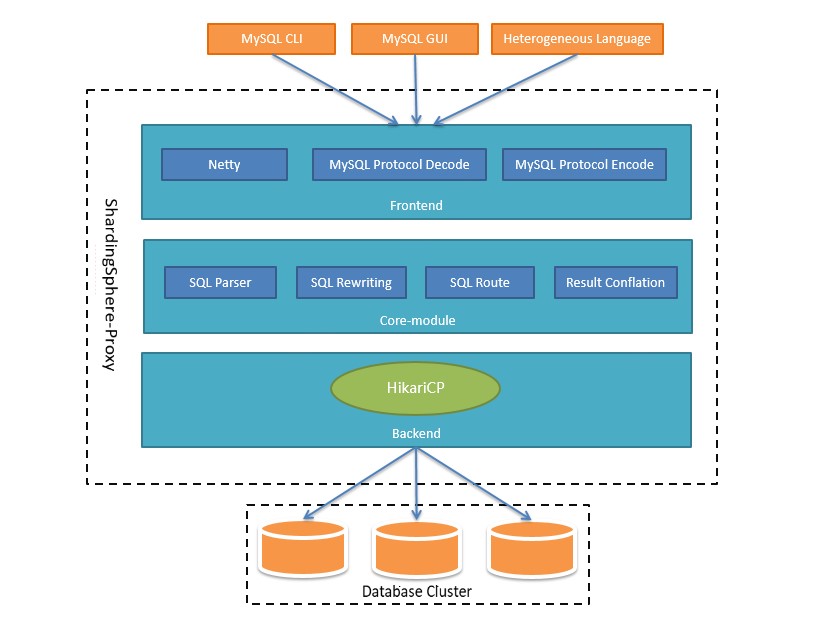
-The throughput of proxy will be greatly improved, which can effectively cope with large-scale database cluser in this way.
+The throughput of proxy will be greatly improved, which can effectively cope with large-scale database cluster in this way.
### 02 PreparedStatement Achievement
#### 1. PreparedStatement Achievement
-My first assignment at Sharding-Sphere is to achieve PreparedStatement of Proxy. It's said to be a flawless functionality that is precompile SQL to improve query speed and prevent SQL injection attacks. It sounds great that one precompilation and more queries reduces SQL compilation cost and lifts efficiency, but it turns out to be very slow to execute SQL, even it is slower than the original statement.
+My first assignment at Sharding-Sphere is to achieve PreparedStatement of Proxy. It's said to be a flawless functionality that is precompile SQL to improve query speed and prevent SQL injection attacks. It sounds great that one precompiled and more queries reduces SQL compilation cost and lifts efficiency, but it turns out to be very slow to execute SQL, even it is slower than the original statement.
Neglect Proxy, let's see how MySQL protocol works when running PreparedStatement by wireshark.
@@ -69,13 +69,13 @@ Code sample as below:
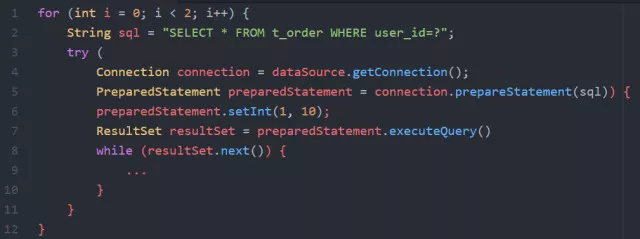
-It's clear that perform query twice by PreparedStatement and set param user_id=10 each time. Through analysis of caught packets, protocol messages between JDBC and MySQL are as follows:
+It's clear that perform query twice by PreparedStatement and set parameter user_id=10 each time. Through analysis of caught packets, protocol messages between JDBC and MySQL are as follows:
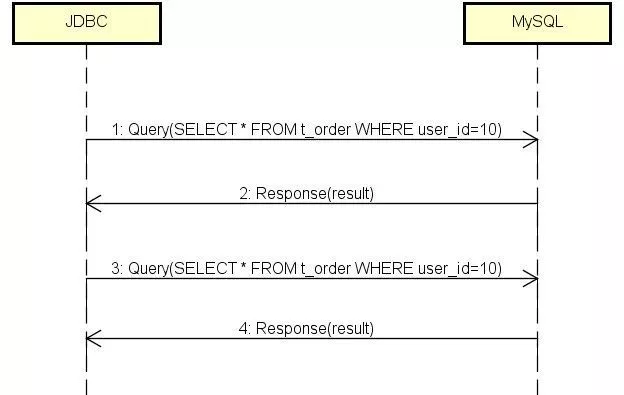
JDBC executes query two times towards MySQL and MySQL returns results with the same times. We don't expect first message for PreparedStatement because of no question mark. It implies no effect to prepare, doesn't work for MySQL at least.
-For the issue I think everyone makes sense without setting useServerPrepStmts=true to JDBC url. MySQL do prepare through the param. It's pointless if you don't set it although JDBC wants to perform preparation, because it is insensible to MySQL. Let's set the param in the url next:
+For the issue I think everyone makes sense without setting useServerPrepStmts=true to JDBC url. MySQL do prepare through the parameter. It's pointless if you don't set it although JDBC wants to perform preparation, because it is insensible to MySQL. Let's set the parameter in the url next:
```
jdbc:mysql://127.0.0.1:3306/demo_ds?useServerPrepStmts=true
@@ -85,13 +85,13 @@ Here is the new interaction:
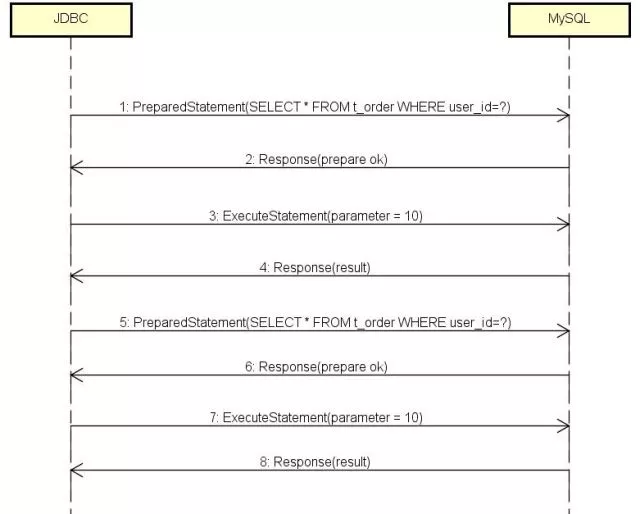
-It's a correct procedure at the first sight: for the first message, it's PreparedStatement which has question mark within SELECT; for the second message, MySQL points out to get ready for JDBC; for the third message, JDBC sets user_id=10; for the fourth message, MySQL returns query result; for the fifth messge, why does JDBC send PreparedStatement once more?
+It's a correct procedure at the first sight: for the first message, it's PreparedStatement which has question mark within SELECT; for the second message, MySQL points out to get ready for JDBC; for the third message, JDBC sets user_id=10; for the fourth message, MySQL returns query result; for the fifth message, why does JDBC send PreparedStatement once more?
-Each query should transfers its value of param through ExecuteStatement in expectation, then it takes effect of one precompilation and more performation.
+Each query should transfers its value of parameter through ExecuteStatement in expectation, then it takes effect of one precompiled and more preformation.
-If "precompiling" every time, there is no difference with normal query in addition to cost of two passing message: Response(prepareok) and ExecuteStatement(parameter=10). Here is the performance issue.
+If "precompiled" every time, there is no difference with normal query in addition to cost of two passing message: Response(prepareok) and ExecuteStatement(parameter=10). Here is the performance issue.
-It shoud be something wrong if precompilation doesn't work. I read source code of JDBC in order to work it out, and find a important settting - cachePrepStmts. What will happen to set it:
+It should be something wrong if precompiled doesn't work. I read source code of JDBC in order to work it out, and find an important settting - cachePrepStmts. What will happen to set it:
```
jdbc:mysql://127.0.0.1:3306/demo_ds?
@@ -102,24 +102,25 @@ We get the expected message flow. The speed is much faster than normal query aft
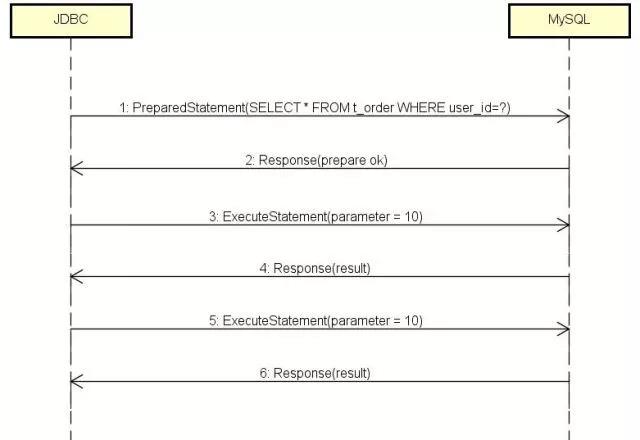
-At the beginning of fifth message, it's enough to transfers value of param for each query. We reach the goal of one precompilation and more performation in the final, MySQL efficiency improves a lot. Due to shorter length of message, network IO efficiency is much better.
+At the beginning of fifth message, it's enough to transfers value of parameter for each query. We reach the goal of one precompiled and more preformation in the final, MySQL efficiency improves a lot. Due to shorter length of message, network IO efficiency is much better.
That is how "cachePrepStmts=true" works: JDBC cache needs prepared SQL. Here is an example of "SELECT*FROMt_orderWHEREuser_id=?", after running once, it skips PreparedStatement next time and make use of ExecuteStatement to set param value.
-when making it clear, you will know how to optimize Proxy. Proxy adops Hikari as database connecting pool. In time of initialization, it will set two params above.
+when making it clear, you will know how to optimize Proxy. Proxy is using Hikari as database connecting pool. In time of initialization, it will set two parameters above.
```
config.addDataSourceProperty("useServerPrepStmts","true");
config.addDataSourceProperty("cachePrepStmts","true");
```
-These settings ensoure performance between Proxy and MySQL, but how does Proxy guarantee capability with Client?
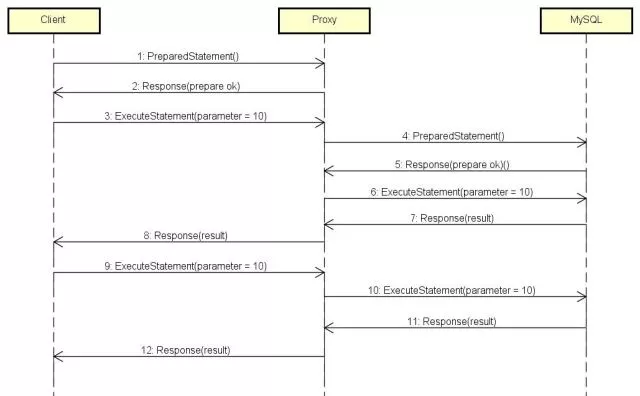
+This guarantees the performance between Proxy and MySQL services. So how is the performance between Proxy AND Client guaranteed.
-When getting PreparedStatement from Client, Proxy doesn't send the message to MySQL due to question mark of sharding key in SQL, it has no idea which physical database to route to. It caches SQL only after getting those messages and makes StatementId stored into Map of SQL. It sends requests in the end when getting ExecuteStatement.
+Proxy does not forward this message to MySQL when it receives the Client’s PreparedStatement because the fragmentation key in SQL is a question mark and Proxy does not know which real database to route to. Proxy simply catches the SQL upon receiving this message, storing it in a Statementld to the inside of the SQL map, the database is not actually requested until the ExecuteStatement is received.
-Before optimization, the logic works correctly. On account of each query, a new PreparedStatement cames into being and ExecuteStatement passes the type and value of param to Client.
+This logic wad fine before optimization because each query is a new PreparedStatement process, and ExecuteStatement tells the client the parameter type and the parameter value.
+
+With the addition of two parameters, the content of the message changes, and when ExecuteStatement send it a second time, the message body only has the parameter value but not the parameter type, and Proxy can’t retrieve the value correctly without knowing the type. So the optimization that Proxy needs to do is to cache the argument types at the beginning of the PreparedStatement.
-It's different in message content afer adding two params above, there is no type but value for param when ExecuteStatement sends message second time, Proxy can't get param value without its type. So what to do for Proxy is that cache the type in the beginning.
@@ -127,7 +128,7 @@ The image above shows interaction between Client and Proxy-MySQL when finishing
#### 2. Configuration optimization of Hikari
-During initialization, Proxy will configure a Hariki pool for each pythsical database. According to sharding rule, SQL is route to real database, and get results through Hikari connection, Proxy conflates result and return it to client in the end. What's the size of database pool? As opinions vary, i'll give the final conclusion today.
+During initialization, Proxy will configure a Hikari pool for each pythsical database. According to sharding rule, SQL is route to real database, and get results through Hikari connection, Proxy conflates result and return it to client in the end. What's the size of database pool? As opinions vary, i'll give the final conclusion today.
Out of expectation, you will find it's not question about maximum in the opposite of minimum! Will you feel surprise that serial is faster than parallel when triggering a task?
@@ -141,7 +142,7 @@ http://www.dailymotion.com/video/x2s8uec
Pool size is decreased from 2048 to 96, TPS is up to 20702 from 16163, average of response is decreased from 110ms to 3ms.
-It's not easy to make counts of connection equal with CPU, we have to take IO of network/disk into consideration. When IO occurs and thread is blocked, operation system will assign free cpu to other threads. If thread is always blocked at I/O , we could set a little more of connection than CPU, then perform more tasks within the same time, but what shoud value be? PostgreSQL does a benchmark test:
+It's not easy to make counts of connection equal with CPU, we have to take IO of network/disk into consideration. When IO occurs and thread is blocked, operation system will assign free CPU to other threads. If thread is always blocked at I/O, we could set a little more of connection than CPU, then perform more tasks within the same time, but what should value be? PostgreSQL does a benchmark test:
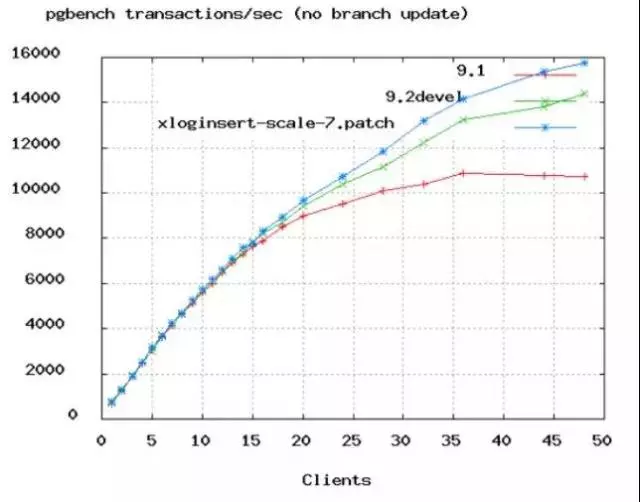
@@ -151,7 +152,7 @@ Increased speed of TPS starts to be slow from 50. According to the result, Postg
connections=((core_count*2)+effective_spindle_count)
```
-connection count = ((cores*2)+ count disk). 60 connections is enough at a 32 core machine. so there is no need to set hundreds of connections for Proxy, it's not only wastes resources, but also slows down the speed.
+connection count = ((cores*2) + count disk). 60 connections are enough at a 32 core machine. so there is no need to set hundreds of connections for Proxy, it's not only wastes resources, but also slows down the speed.
#### 3. Optimization of resultset conflation
@@ -164,12 +165,12 @@ Let's see how it behaves before optimization. 5 clients link to Proxy, each one
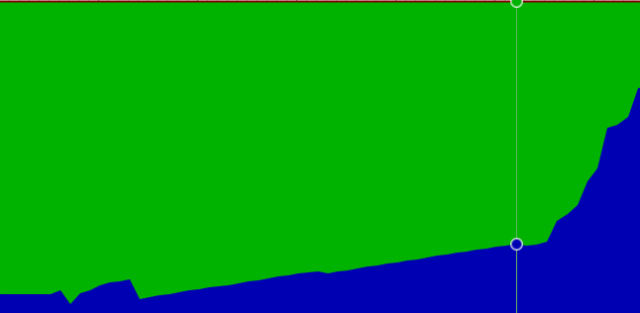
-Memory of Proxy increases all the time, although GC is triggered. The reason is that ResultSet will be blocked next() until all the quering datas storing into memory. It's default way for ResultSet to retrieve data.
+Memory of Proxy increases all the time, although GC is triggered. The reason is that ResultSet will be blocked next() until all the querying datas storing into memory. It's default way for ResultSet to retrieve data.
Is there any way to consume data immediately when ResultSet getting an item? Here is description in the Connector/J document:
```
-If you are working with ResultSets that have a large number of rows or large values and cannot allocate heap space in your JVM for the memory required , you can tell the driver to stream the results back one row at a time.
+If you are working with ResultSets that have a large number of rows or large values and cannot allocate heap space in your JVM for the memory required, you can tell the driver to stream the results back one row at a time.
```
@@ -185,7 +186,7 @@ To activate the ability, you only need to set a parameter when creating the stat
stmt.setFetchSize(Integer.MIN_VALUE);
```
-You make it. Proxy consumes data at once by next() after querying the instruction, these data will be clean up at next GC. During resultset conflation, we also need to merge data in time, there is need to merge after retrieving them all, Sharding-Core provieds the interface. Here is the optimized result, figure1 below:
+You make it. Proxy consumes data at once by next() after querying the instruction, these data will be clean up at next GC. During resultset conflation, we also need to merge data in time, there is need to merge after retrieving them all, Sharding-Core provides the interface. Here is the optimized result, figure1 below:
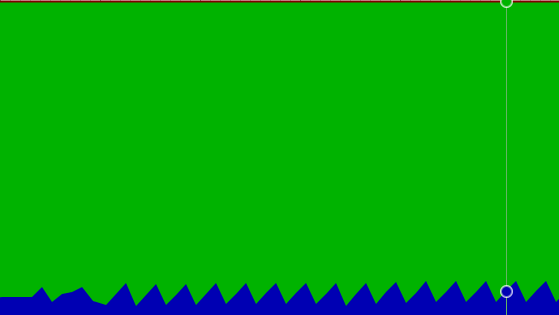
@@ -195,9 +196,9 @@ Data in the memory stays shorter, GC recycles data each time, memory efficiency

-What happens for Proxy to consumps data slower or not to work? From my test, memory usage increases linearly, stronger than figure1, Proxy is KO finally when it runs out of memory.
+What happens for Proxy to consumes data slower or not to work? From my test, memory usage increases linearly, stronger than figure1, Proxy is KO finally when it runs out of memory.
-Let's analyze the reason, and then i'll introduce second optimization: Current limiting
+Let's analyze the reason, and then I'll introduce second optimization: Current limiting
Main settings about cache as follows::
@@ -208,7 +209,7 @@ Main settings about cache as follows::
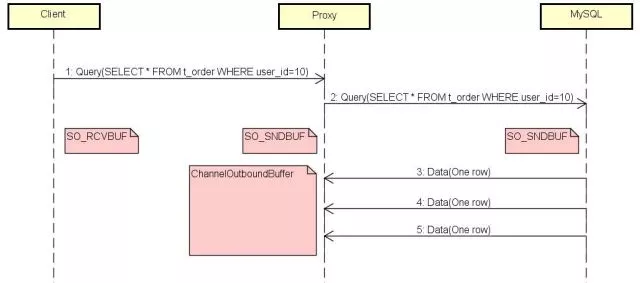
-When Client is blocked, its SO_RCVBUF runs out instantly, then it notifies Proxy not to send data any more by slide window, SO_SNDBUF of Proxy is filled by Netty immediatelly at the same time.
+When Client is blocked, its SO_RCVBUF runs out instantly, then it notifies Proxy not to send data any more by slide window, SO_SNDBUF of Proxy is filled by Netty immediately at the same time.
ChannelOutboundBuffer of Netty swallows all the data from MySQL when SO_SNDBUF is up to top value, because it is unbounded by default.
@@ -216,7 +217,7 @@ SO_RCVBUF of Proxy has free memory due to Netty consumption, it causes MySQL sen
When making it clear, our purpose is that Proxy will not accept MySQL data if Client is blocked.
-Netty controls writting cache through WRITE_BUFFER_WATER_MARK param:
+Netty controls writing cache through WRITE_BUFFER_WATER_MARK parameter:
* when Buffer size is up to high watermark, Netty will not produce data any more, unless it's under low watermark;
@@ -230,7 +231,7 @@ There will be two agent modes configuration in the upcoming version of sharding-
* MEMORY_STRICTLY: Proxy keeps all connections of database routed to, it's a good way to make use of ResultSet flow to conserve memory.
-* CONNECTION_STRICTLY: Agent releases connections when getting all of data from ResultSet, then its memory increases more then before.
+* CONNECTION_STRICTLY: Agent releases connections when getting all of data from ResultSet, then its memory increases more than before.
Let's make it simple, set MEMORY_STRICTLY mode if you want less consumption of memory; set CONNECTION_STRICTLY mode if you want less consumption of connections.
@@ -241,12 +242,12 @@ Suppose that a database is set to max_user_connections=80, and it is routed to 1
In order to resolve the problem above, CONNECTION_STRICTLY comes out, it doesn't make use of ResultSet flow which causes memory increasing. CONNECTION_STRICTLY doesn't need to keep in touch with database, it will release connection after retrieving all the data in ResultSet.
-We use the same setting max_user_connections=80 as example, the database is routed to 100 tables. Proxy create 80 connection for quering data at first, the other 20 connections will be cached into pool. These 20 connections will be created successfully one after another within quering completion before.
+We use the same setting max_user_connections=80 as example, the database is routed to 100 tables. Proxy create 80 connections for querying data at first, the other 20 connections will be cached into pool. These 20 connections will be created successfully one after another within querying completion before.
-If you feel confused, please keep it in mind CONNECTION_STRICTLY is a scenario that max_user_connections is less than maximums of tables routed to.
+If you feel confused, please keep it in mind CONNECTION_STRICTLY is a scenario that max_user_connections are less than maximums of tables routed to.
### 03 Summary
-Sharding-Sphere has been continuous improvement and development since 2016. A growing number of componies and individuals adaop it, and they provide many successful cases for us. We will move forward to impove current features, achieve soft transaction, data governance and so on in succession. If someone has good ideas or wants to do proposals, welcome to join Sharding-Sphere open source project.
+Sharding-Sphere has been continuous improvement and development since 2016. A growing number of companies and individuals uses it, and they provide many successful cases for us. We will move forward to improve current features, achieve soft transaction, data governance and so on in succession. If someone has good ideas or wants to do proposals, welcome to join Sharding-Sphere open source project.
* https://github.com/sharding-sphere/sharding-sphere/
@@ -271,13 +272,13 @@ A2: CONNECTION_STRICTLY is for decreasing connections. It's small for max_user_c
-Q3: Within the "stmt.setFetchSize(custom_size)" scenario, it's similar with ORM framworks like Mybatis to query a amount of datas into memory, these data are stored into list in general to handle them. They still occupy memory.
+Q3: Within the "stmt.setFetchSize(custom_size)" scenario, it's similar with ORM frameworks like Mybatis to query an amount of data into memory, these data are stored into list in general to handle them. They still occupy memory.
A3: It's client memory in this situation, it is no influence of Proxy.
-Q4: If we have lots of data in memory, is it only one way to use native JDBC to query/handle datas every time without putting them into memory?
+Q4: If we have lots of data in memory, is it only one way to use native JDBC to query/handle data every time without putting them into memory?
A4: Client takes control of Mybatis, it has nothing to do with Proxy.