You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2020/02/12 20:30:42 UTC
[GitHub] [incubator-hudi] bwu2 opened a new issue #1328: Hudi upsert hangs
bwu2 opened a new issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328


   **Describe the problem you faced**
   When we upsert data into Hudi, we're finding that the job just hangs in some cases. Specifically, we have an ETL pipeline where we re-ingest a lot of data (i.e. we upsert data that already exists in the Hudi table). When the proportion of data that is not new is very high, the Hudi spark job seems to hang before writing out the updated table.

   Note that this currently affects 2 of the 80 tables in our ETL pipeline and the rest run fine.

   **To Reproduce**
   See gist at: https://gist.github.com/bwu2/89f98e0926374f71c80e4b2fa5089f18

   The code there creates a Hudi table with 4m rows. It then upserts another 4m rows, 3.5m of which are the same as the original 4m.

   Note that bulk parallelism of the initial load is deliberately set to 1 to ensure we avoid lots of small files.

   Running this code on an EMR cluster (either interactively in a PySpark shell or spark-submit) causes the upsert job never to finish, being stuck somewhere in the Spark job with description (from the Spark history server):
   `count at HoodieSparkSqlWriter.scala:255` (after the stage `mapToPair at HoodieWriteClient.java:492` and before/during the stage `count at HoodieSparkSqlWriter.scala:255`).

   For a table this small, it shouldn't matter about cores/memory/executors/instance type but we have varied these too with no success.

   **Expected behavior**
   Expected the upsert job to succeed and the total number of rows in the table to be 4.5m.

   **Environment Description
   Running on EMR 5.29.0
   * Hudi version : tested on 0.5.0, 0.5.1 and latest build off master

   * Spark version : 2.4.4

   * Hive version : N/A

   * Hadoop version : 2.8.5 (Amazon)

   * Storage (HDFS/S3/GCS..) : S3

   * Running on Docker? (yes/no) : NO


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586451527


   Even #800 is a reasonable workload.. I don't understand what's going on here .. Its just a single file being versioned.. same as the next two commits, which seems to be faster.. Is there a way you can give me a reproducible snippet of code? (I think you mentioned this is synthetic data)

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-588341138


   I ported your code to scala and looking into the issue now.. Will keep you posted.

   ```
   val HUDI_FORMAT = "org.apache.hudi"
   val TABLE_NAME = "hoodie.table.name"
   val RECORDKEY_FIELD_OPT_KEY = "hoodie.datasource.write.recordkey.field"
   val PRECOMBINE_FIELD_OPT_KEY = "hoodie.datasource.write.precombine.field"
   val OPERATION_OPT_KEY = "hoodie.datasource.write.operation"
   val BULK_INSERT_OPERATION_OPT_VAL = "bulk_insert"
   val UPSERT_OPERATION_OPT_VAL = "upsert"
   val BULK_INSERT_PARALLELISM = "hoodie.bulkinsert.shuffle.parallelism"
   val UPSERT_PARALLELISM = "hoodie.upsert.shuffle.parallelism"
   val config = Map(
   "table_name" -> "example_table",
   "target" -> "file:///tmp/example_table/",
   "primary_key" ->  "id",
   "sort_key" -> "id"
   )
   val readPath = config("target") + "/*"

   val json_data = (1 to 4000000).map(i => "{\"id\":" + i + "}")
   val jsonRDD = spark.sparkContext.parallelize(json_data, 2)
   val df1 = spark.read.json(jsonRDD)
   println(s"${df1.count()} records in source 1")

   df1.printSchema

   // Runs quick
   df1.write.format(HUDI_FORMAT)
         .option(PRECOMBINE_FIELD_OPT_KEY, config("sort_key"))
         .option(RECORDKEY_FIELD_OPT_KEY, config("primary_key"))
         .option(TABLE_NAME, config("table_name"))
         .option(OPERATION_OPT_KEY, BULK_INSERT_OPERATION_OPT_VAL)
         .option(BULK_INSERT_PARALLELISM, 1)
         .mode("Overwrite")
         .save(config("target"))


   println(s"${spark.read.format(HUDI_FORMAT).load(readPath).count()} records in Hudi table")

   // Runs quick
   df1.limit(3000000).write.format(HUDI_FORMAT)
       .option(PRECOMBINE_FIELD_OPT_KEY, config("sort_key"))
       .option(RECORDKEY_FIELD_OPT_KEY, config("primary_key"))
       .option(TABLE_NAME, config("table_name"))
       .option(OPERATION_OPT_KEY, UPSERT_OPERATION_OPT_VAL)
       .option(UPSERT_PARALLELISM, 20)
       .mode("Append")
       .save(config("target"))

   println(s"${spark.read.format(HUDI_FORMAT).load(readPath).count()} records in Hudi table")

   // Runs very slow
   df1.write.format(HUDI_FORMAT)
     .option(PRECOMBINE_FIELD_OPT_KEY, config("sort_key"))
     .option(RECORDKEY_FIELD_OPT_KEY, config("primary_key"))
     .option(TABLE_NAME, config("table_name"))
     .option(OPERATION_OPT_KEY, UPSERT_OPERATION_OPT_VAL)
     .option(UPSERT_PARALLELISM, 20)
     .mode("Append")
     .save(config("target"))

   println(s"${spark.read.format(HUDI_FORMAT).load(readPath).count()} records in Hudi table")

   ```

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 commented on issue #1328: Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
bwu2 commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586457085


   See: https://gist.github.com/bwu2/e432a42f51519f27197f4785af3e1abf

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586108720


   Ok, after reading https://github.com/apache/incubator-hudi/issues/800 (which is similar), I think this is a memory issue (even though GC seems to be a small proportion of the total time, according to the Spark history server & we're not getting any OOME).

   When I double the `spark.executor.memory` the job runs much faster. I'm sure there are maybe other optimizations and/or tuning I can consider also.

   Is it normal/expected that an upsert with mostly updates would require more memory than an upsert with mostly inserts?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 commented on issue #1328: Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
bwu2 commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586071719


   Ok, thanks for this.

   I have run the jobs again. First, insert 4m records, then upsert 3m of them, then upsert 4m, then upsert 4m. The two jobs upserting 3m records work fine and quickly, but the one where upsert 4m takes >200 times as long.

   My results (from a synthetic dataset) are:
   `hudi:json_data->commits show --limit 4
   ╔════════════════╤═════════════════════╤═══════════════════╤═════════════════════╤══════════════════════════╤═══════════════════════╤══════════════════════════════╤══════════════╗
   ║ CommitTime     │ Total Bytes Written │ Total Files Added │ Total Files Updated │ Total Partitions Written │ Total Records Written │ Total Update Records Written │ Total Errors ║
   ╠════════════════╪═════════════════════╪═══════════════════╪═════════════════════╪══════════════════════════╪═══════════════════════╪══════════════════════════════╪══════════════╣
   ║ 20200214013937 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224532 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 4000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224325 │ 25.6 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224218 │ 25.5 MB             │ 1                 │ 0                   │ 1                        │ 4000000               │ 0                            │ 0            ║
   ╚════════════════╧═════════════════════╧═══════════════════╧═════════════════════╧══════════════════════════╧═══════════════════════╧══════════════════════════════╧══════════════╝
   `

   and the times:
   `
   grep -n -e totalCreateTime -e totalUpsertTime  *.commit
   20200213224218.commit:36:  "totalCreateTime" : 30012,
   20200213224218.commit:37:  "totalUpsertTime" : 0,
   20200213224325.commit:36:  "totalCreateTime" : 0,
   20200213224325.commit:37:  "totalUpsertTime" : 46879,
   20200213224532.commit:36:  "totalCreateTime" : 0,
   20200213224532.commit:37:  "totalUpsertTime" : 10347280,
   20200214013937.commit:36:  "totalCreateTime" : 0,
   20200214013937.commit:37:  "totalUpsertTime" : 44598,
   `

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585512613


   @vinothchandar Thanks for taking the time to reply!

   Let me describe the simplest example of this problem on a tiny COW data set: Create a data frame with 4m rows and one column with values 1, 2, 3....4m in that column. Bulk insert that into Hudi (using the one column as the `recordkey`). This takes ~1 minute to run and the data size is about 30MB. Now upsert the same data frame into the table a second time. This take >2 hours to run.

   Alternatively, if we upsert a new data frame with values 4000001...8m (still 4m rows upserted), this takes ~1 minute to run.

   To answer your other queries:
   * almost all of the time is spent in the  `HoodieSparkSqlWriter` job (and within that job, the `count at HoodieSparkSqlWriter.scala` stage (the `HoodieBloomIndex` jobs run quickly).
   * it seems highly unlikely to be resource constraint issue with such a small example.

   Shall i raise a JIRA for this? Or is this the expected behavior for such a workload?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585512613


   @vinothchandar Thanks for taking the time to reply!

   Let me describe the simplest example of this problem on a tiny COW data set: Create a data frame with 4m rows and one column with values 1, 2, 3....4m in that column. Bulk insert that into Hudi (using the one column as the `recordkey`). This takes ~1 minute to run and the data size is about 30MB. Now upsert the same data frame into the table a second time. This take >2 hours to run.

   Alternatively, if we upsert a new data frame with values 4000001...8m (still 4m rows upserted), this takes ~1 minute to run.

   To answer your other queries:
   * almost all of the time is spent in the  {{HoodieSparkSqlWriter}} job (and within that job, the {{count at HoodieSparkSqlWriter.scala}} stage (the BloomIndex parts run quickly).
   * it seems highly unlikely to be resource constraint issue with such a small example.

   Shall i raise a Jira for this? Or is this the expected behavior for such a workload?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585471970


   An update on this: the job did eventually complete. But took 2.4 hours (other similar jobs ran more than 9 hours before we had to kill them). This doesn't seem reasonable for such a small table.

   Also, i changed the bulk insert parallelism from 1 to 2 (and doubled the data size) and the problem still existed.

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 commented on issue #1328: Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
bwu2 commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585512613


   @vinothchandar Thanks for taking the time to reply!

   Let me describe the simplest example of this problem on a tiny COW data set: Create a data frame with 4m rows and one column with values 1, 2, 3....4m in that column. Bulk insert that into Hudi (using the one column as the {{recordkey}}). This takes ~1 minute to run and the data size is about 30MB. Now upsert the same data frame into the table a second time. This take >2 hours to run.

   Alternatively, if we upsert a new data frame with values 4000001...8m (still 4m rows upserted), this takes ~1 minute to run.

   To answer your other queries:
   * almost all of the time is spent in the  {{HoodieSparkSqlWriter}} job (and within that job, the {{count at HoodieSparkSqlWriter.scala}} stage (the BloomIndex parts run quickly).
   * it seems highly unlikely to be resource constraint issue with such a small example.

   Shall i raise a Jira for this? Or is this the expected behavior for such a workload?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] lamber-ken commented on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
lamber-ken commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-588969473
Hi @vinothchandar, follow your steps
**Analysis**:
Upsert (4000000 entries)
```
WARN HoodieMergeHandle:
Number of entries in MemoryBasedMap => 150875
Total size in bytes of MemoryBasedMap => 83886580
Number of entries in DiskBasedMap => 3849125
Size of file spilled to disk => 1443046132
```
Hang stackstrace (DiskBasedMap#get)
```
"pool-21-thread-2" Id=696 cpuUsage=98% RUNNABLE
at java.util.zip.ZipFile.getEntry(Native Method)
at java.util.zip.ZipFile.getEntry(ZipFile.java:310)
- locked java.util.jar.JarFile@1fc27ed4
at java.util.jar.JarFile.getEntry(JarFile.java:240)
at java.util.jar.JarFile.getJarEntry(JarFile.java:223)
at sun.misc.URLClassPath$JarLoader.getResource(URLClassPath.java:1005)
at sun.misc.URLClassPath.getResource(URLClassPath.java:212)
at java.net.URLClassLoader$1.run(URLClassLoader.java:365)
at java.net.URLClassLoader$1.run(URLClassLoader.java:362)
at java.security.AccessController.doPrivileged(Native Method)
at java.net.URLClassLoader.findClass(URLClassLoader.java:361)
at java.lang.ClassLoader.loadClass(ClassLoader.java:424)
- locked java.lang.Object@28f65251
at sun.misc.Launcher$AppClassLoader.loadClass(Launcher.java:331)
at java.lang.ClassLoader.loadClass(ClassLoader.java:411)
- locked scala.reflect.internal.util.ScalaClassLoader$URLClassLoader@a353dff
at java.lang.ClassLoader.loadClass(ClassLoader.java:411)
- locked com.esotericsoftware.reflectasm.AccessClassLoader@2c7122e2
at com.esotericsoftware.reflectasm.AccessClassLoader.loadClass(AccessClassLoader.java:92)
at java.lang.ClassLoader.loadClass(ClassLoader.java:357)
at com.esotericsoftware.reflectasm.ConstructorAccess.get(ConstructorAccess.java:59)
- locked com.esotericsoftware.reflectasm.AccessClassLoader@2c7122e2
at org.apache.hudi.common.util.SerializationUtils$KryoInstantiator$KryoBase.lambda$newInstantiator$0(SerializationUtils.java:151)
at org.apache.hudi.common.util.SerializationUtils$KryoInstantiator$KryoBase$$Lambda$265/1458915834.newInstance(Unknown Source)
at com.esotericsoftware.kryo.Kryo.newInstance(Kryo.java:1139)
at com.esotericsoftware.kryo.serializers.FieldSerializer.create(FieldSerializer.java:562)
at com.esotericsoftware.kryo.serializers.FieldSerializer.read(FieldSerializer.java:538)
at com.esotericsoftware.kryo.Kryo.readObject(Kryo.java:731)
at com.esotericsoftware.kryo.serializers.ObjectField.read(ObjectField.java:125)
at com.esotericsoftware.kryo.serializers.FieldSerializer.read(FieldSerializer.java:543)
at com.esotericsoftware.kryo.Kryo.readClassAndObject(Kryo.java:813)
at org.apache.hudi.common.util.SerializationUtils$KryoSerializerInstance.deserialize(SerializationUtils.java:112)
at org.apache.hudi.common.util.SerializationUtils.deserialize(SerializationUtils.java:86)
at org.apache.hudi.common.util.collection.DiskBasedMap.get(DiskBasedMap.java:217)
at org.apache.hudi.common.util.collection.DiskBasedMap.get(DiskBasedMap.java:211)
at org.apache.hudi.common.util.collection.DiskBasedMap.get(DiskBasedMap.java:207)
at org.apache.hudi.common.util.collection.ExternalSpillableMap.get(ExternalSpillableMap.java:173)
at org.apache.hudi.common.util.collection.ExternalSpillableMap.get(ExternalSpillableMap.java:55)
at org.apache.hudi.io.HoodieMergeHandle.write(HoodieMergeHandle.java:280)
at org.apache.hudi.table.HoodieCopyOnWriteTable$UpdateHandler.consumeOneRecord(HoodieCopyOnWriteTable.java:434)
at org.apache.hudi.table.HoodieCopyOnWriteTable$UpdateHandler.consumeOneRecord(HoodieCopyOnWriteTable.java:424)
at org.apache.hudi.common.util.queue.BoundedInMemoryQueueConsumer.consume(BoundedInMemoryQueueConsumer.java:37)
at org.apache.hudi.common.util.queue.BoundedInMemoryExecutor.lambda$null$2(BoundedInMemoryExecutor.java:121)
at org.apache.hudi.common.util.queue.BoundedInMemoryExecutor$$Lambda$76/1412692041.call(Unknown Source)
at java.util.concurrent.FutureTask.run(FutureTask.java:266)
at java.util.concurrent.ThreadPoolExecutor.runWorker(ThreadPoolExecutor.java:1142)
at java.util.concurrent.ThreadPoolExecutor$Worker.run(ThreadPoolExecutor.java:617)
at java.lang.Thread.run(Thread.java:745)
```
Average time of `DiskBasedMap#get`
```
$ monitor *DiskBasedMap get -c 12
Affect(class-cnt:1 , method-cnt:4) cost in 221 ms.
timestamp class method total success fail avg-rt(ms) fail-rate
----------------------------------------------------------------------------------------
2020-02-20 18:13:36 DiskBasedMap get 5814 5814 0 6.12 0.00%
timestamp class method total success fail avg-rt(ms) fail-rate
----------------------------------------------------------------------------------------
2020-02-20 18:13:48 DiskBasedMap get 9117 9117 0 3.89 0.00%
timestamp class method total success fail avg-rt(ms) fail-rate
----------------------------------------------------------------------------------------
2020-02-20 18:14:16 DiskBasedMap get 8490 8490 0 4.10 0.00%
```
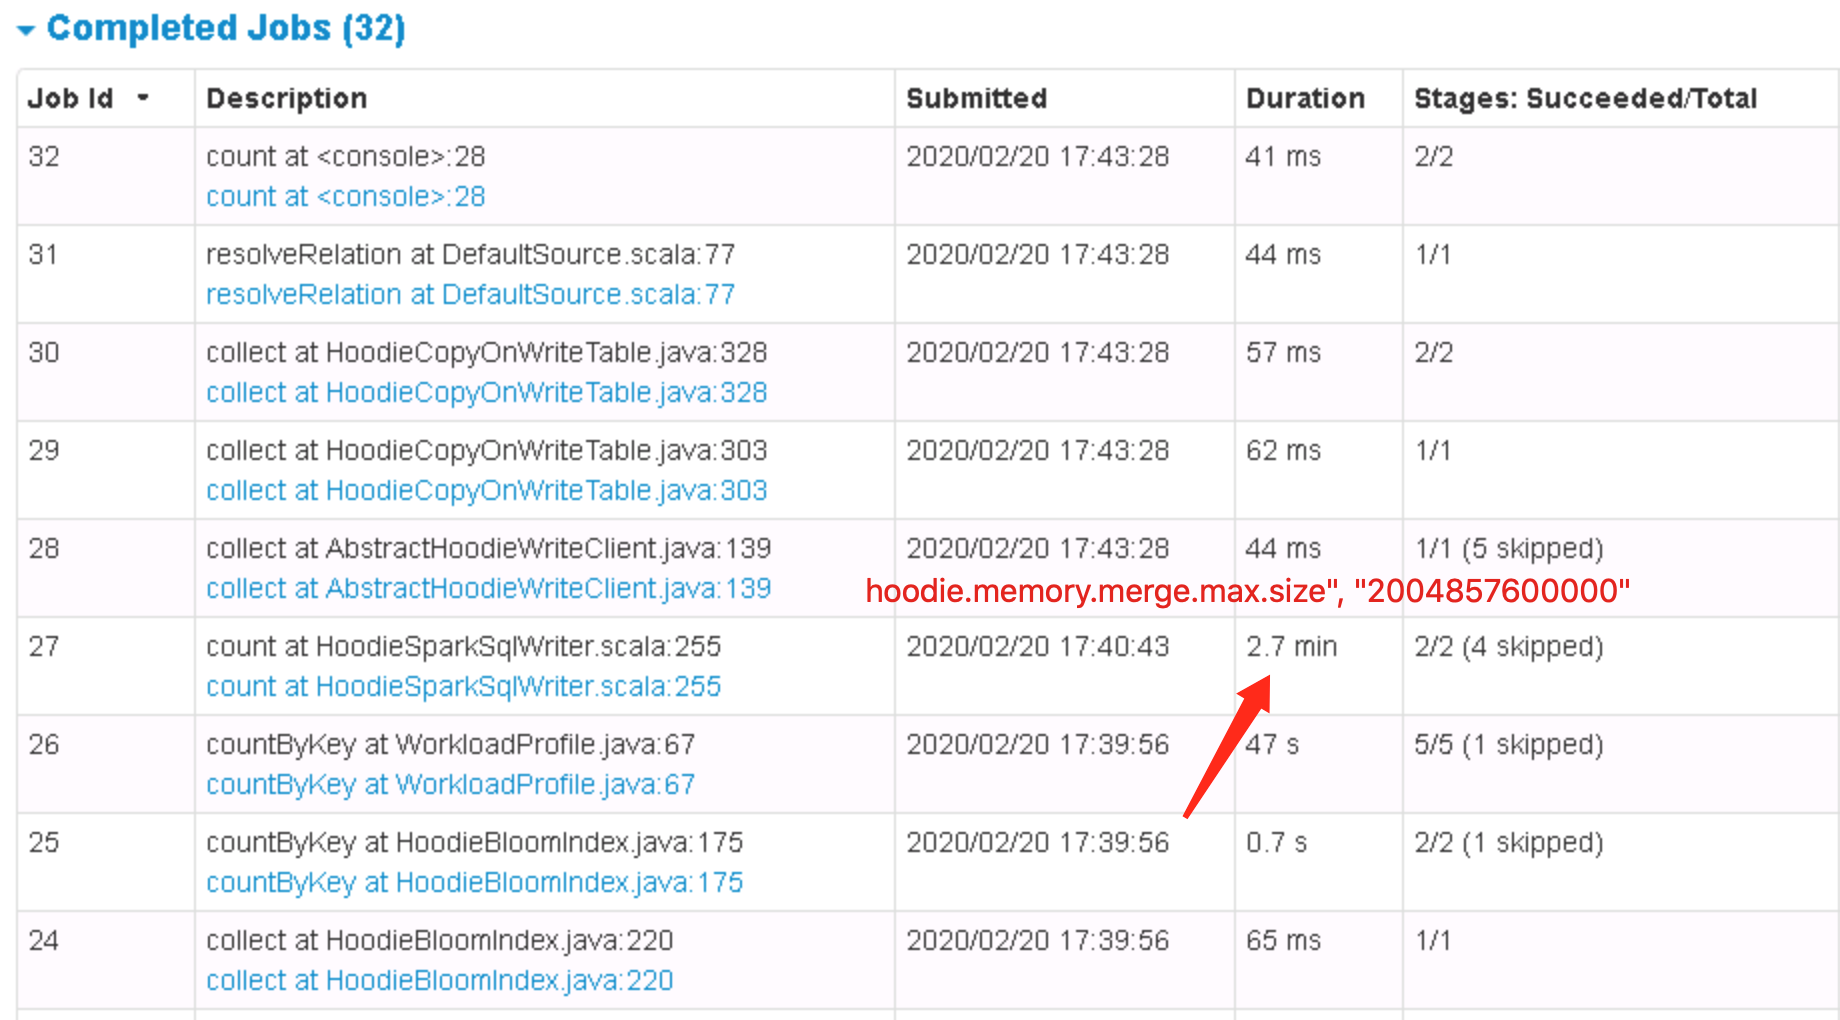
So, when write data to parquet file, needs 3849125(entries) * 4ms(avg) = 15396s.
It takes a long time.
More, add option `option("hoodie.memory.merge.max.size", "2004857600000")`, just need about 2.7min
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
With regards,
Apache Git Services
[GitHub] [incubator-hudi] lamber-ken commented on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
lamber-ken commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-588971355


   Hi @bwu2, add option when upsert `option("hoodie.memory.merge.max.size", "2004857600000")`, let's try again : )

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585991857


   There must be something else going on.. just used my own benchmark jobs to generate a pattern where the records are fully overwritten in a second (and a third) batch and it actually finishes fine..

   ```
   hudi:hoodie_benchmark->connect --path file:///tmp/hudi-benchmark/output/org.apache.hudi
   35394 [Spring Shell] INFO  org.apache.hudi.common.table.HoodieTableMetaClient  - Loading HoodieTableMetaClient from file:///tmp/hudi-benchmark/output/org.apache.hudi
   35415 [Spring Shell] INFO  org.apache.hudi.common.util.FSUtils  - Hadoop Configuration: fs.defaultFS: [file:///], Config:[Configuration: core-default.xml, core-site.xml, mapred-default.xml, mapred-site.xml, yarn-default.xml, yarn-site.xml, hdfs-default.xml, hdfs-site.xml], FileSystem: [org.apache.hadoop.fs.LocalFileSystem@6851d345]
   35416 [Spring Shell] INFO  org.apache.hudi.common.table.HoodieTableConfig  - Loading table properties from file:/tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/hoodie.properties
   35416 [Spring Shell] INFO  org.apache.hudi.common.table.HoodieTableMetaClient  - Finished Loading Table of type COPY_ON_WRITE(version=1) from file:///tmp/hudi-benchmark/output/org.apache.hudi
   Metadata for table hoodie_benchmark loaded
   hudi:hoodie_benchmark->commits show
   36774 [Spring Shell] INFO  org.apache.hudi.common.table.timeline.HoodieActiveTimeline  - Loaded instants [[20200213134159__clean__COMPLETED], [20200213134159__commit__COMPLETED], [20200213134410__clean__COMPLETED], [20200213134410__commit__COMPLETED], [20200213134548__clean__COMPLETED], [20200213134548__commit__COMPLETED]]
   ╔════════════════╤═════════════════════╤═══════════════════╤═════════════════════╤══════════════════════════╤═══════════════════════╤══════════════════════════════╤══════════════╗
   ║ CommitTime     │ Total Bytes Written │ Total Files Added │ Total Files Updated │ Total Partitions Written │ Total Records Written │ Total Update Records Written │ Total Errors ║
   ╠════════════════╪═════════════════════╪═══════════════════╪═════════════════════╪══════════════════════════╪═══════════════════════╪══════════════════════════════╪══════════════╣
   ║ 20200213134548 │ 384.8 MB            │ 0                 │ 34                  │ 3                        │ 4080024               │ 1211376                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213134410 │ 379.9 MB            │ 0                 │ 34                  │ 3                        │ 4040016               │ 1199234                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213134159 │ 374.8 MB            │ 34                │ 0                   │ 3                        │ 4000008               │ 0                            │ 0            ║
   ╚════════════════╧═════════════════════╧═══════════════════╧═════════════════════╧══════════════════════════╧═══════════════════════╧══════════════════════════════╧══════════════╝

   hudi:hoodie_benchmark->
   ```

   and the times below in ms

   ```
    grep -n -e totalCreateTime -e totalUpsertTime  /tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/*.commit
   /tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/20200213134159.commit:697:  "totalCreateTime" : 195060,
   /tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/20200213134159.commit:698:  "totalUpsertTime" : 0,
   /tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/20200213134410.commit:697:  "totalCreateTime" : 0,
   /tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/20200213134410.commit:698:  "totalUpsertTime" : 193693,
   /tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/20200213134548.commit:697:  "totalCreateTime" : 0,
   /tmp/hudi-benchmark/output/org.apache.hudi/.hoodie/20200213134548.commit:698:  "totalUpsertTime" : 182277,
   ```


   Can we drill into your dataset?  are you generating tons of files due to granular partitionining? can you share the spark UI and the hudi cli output like above?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585512613


   @vinothchandar Thanks for taking the time to reply!

   Let me describe the simplest example of this problem on a tiny COW data set: Create a data frame with 4m rows and one column with values 1, 2, 3....4m in that column. Bulk insert that into Hudi (using the one column as the `recordkey`). This takes ~1 minute to run and the data size is about 30MB. Now upsert the same data frame into the table a second time. This take >2 hours to run.

   Alternatively, if we upsert a new data frame with values 4000001...8m (still 4m rows upserted), this takes ~1 minute to run.

   To answer your other queries:
   * almost all of the time is spent in the  `HoodieSparkSqlWriter`}} job (and within that job, the {{`count at HoodieSparkSqlWriter.scala`}} stage (the `HoodieBloomIndex` jobs run quickly).
   * it seems highly unlikely to be resource constraint issue with such a small example.

   Shall i raise a JIRA for this? Or is this the expected behavior for such a workload?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585512613


   @vinothchandar Thanks for taking the time to reply!

   Let me describe the simplest example of this problem on a tiny COW data set: Create a data frame with 4m rows and one column with values 1, 2, 3....4m in that column. Bulk insert that into Hudi (using the one column as the `recordkey`). This takes ~1 minute to run and the data size is about 30MB. Now upsert the same data frame into the existing table. This take >2 hours to run.

   Alternatively, if we upsert a new data frame into the existing table with values 4000001...8m (still 4m rows upserted), this takes ~1 minute to run.

   To answer your other queries:
   * almost all of the time is spent in the  `HoodieSparkSqlWriter` job (and within that job, the `count at HoodieSparkSqlWriter.scala` stage (the `HoodieBloomIndex` jobs run quickly).
   * it seems highly unlikely to be resource constraint issue with such a small example.

   Shall i raise a JIRA for this? Or is this the expected behavior for such a workload?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar closed issue #1328: Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar closed issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-589195840


   https://issues.apache.org/jira/browse/HUDI-625 filed this to look into this scenario..

   @bwu2 In the meantime, could you run your benchmark against a real dataset with more fields so number of files spread out and record sizes are larger.

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar edited a comment on issue #1328:
Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585503340


   Reposting my response here..

   There seems to be a lot of common concerns here.. https://cwiki.apache.org/confluence/display/HUDI/Tuning+Guide is an useful resource, that hopefully can benefit here..

   Few high level thoughts:
   - It would be good to layout if the most time spent is on the indexing stages (ones tagged with HoodieBloomIndex) or the actual writing..
   - Hudi does keep the input in memory to compute the stats it needs to size files. So if you don't provide sufficient executore/rdd storage memory, it will spill and can cause slowdowns.. (covered in tuning guide & have seen this happen with users often)
   - On workload pattern itself, BloomIndex range pruning can be turned off https://hudi.apache.org/docs/configurations.html#bloomIndexPruneByRanges if the keys ranges are random anyway.. Generally speaking, unless we have RFC-8 (record level indexing), cases of random write/upserting majority of the rows in a table, may give bloom index overhead, since the bloom filters/ranges are not at all useful in pruning out files . We have an interim solution coming out in the next release.. falling back to plain old join to implement the indexing.
   - In terms or MOR and COW, MOR will help only if you have lots of updates and bottleneck is on the writing..
   - If listing is an issue, please turn the following so the table is listed once and we re-use the filesytem metadata hoodie.embed.timeline.server=true

   I would appreciate a JIRA, so that I can break each into sub-task and tackle/resolve independently..


   I am personally focussing on performance now and want to make it lot faster in 0.6.0 release. So all this help would be deeply appreciated

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 commented on issue #1328: Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
bwu2 commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-589446887


   Thanks for your replies!

    @lamber-ken I will try again with that setting. Does increasing the memory available by setting `option("hoodie.memory.merge.max.size", "2004857600000")` work better than increasing executor memory or`hoodie.memory.merge.fraction`? Will it not result in an OOME?

   @vinothchandar Yes, we are re-running against real datasets in the next couple of days. I will report back. But do note that the original problem actually arose on a real dataset not a degenerate or artificial workload: it was not a particularly wide table (with 6 or 7 fields), with about 4m rows bulk inserted and then another 4m upserted (of which most were the same rows).


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-589152895


   @lamber-ken is right.. I am looking into why the DiskBasedMap is so slow (there was a recent change.. wondering if its a regression.. ) Will raise a JIRA nonetheless..


   So bit more explanation..The big difference is that all 4M entries go to one file and its a degenerate workload (i.e a single field record) where the metadata to data overhead is lot.. We have a spilling mechanism to handle large number keys merging into a single file (like the spill map you will see in spark shuffle) and that seems to be performing poorly..

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586071719


   Ok, thanks for this.

   I have run the jobs again. First, insert 4m records, then upsert 3m of them, then upsert 4m, then upsert 4m. The two jobs upserting 3m records work fine and quickly, but the one where upsert 4m takes >200 times as long.

   My results (from a synthetic dataset) are:
   `
   hudi:json_data->commits show --limit 4
   ╔════════════════╤═════════════════════╤═══════════════════╤═════════════════════╤══════════════════════════╤═══════════════════════╤══════════════════════════════╤══════════════╗
   ║ CommitTime     │ Total Bytes Written │ Total Files Added │ Total Files Updated │ Total Partitions Written │ Total Records Written │ Total Update Records Written │ Total Errors ║
   ╠════════════════╪═════════════════════╪═══════════════════╪═════════════════════╪══════════════════════════╪═══════════════════════╪══════════════════════════════╪══════════════╣
   ║ 20200214013937 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224532 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 4000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224325 │ 25.6 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224218 │ 25.5 MB             │ 1                 │ 0                   │ 1                        │ 4000000               │ 0                            │ 0            ║
   ╚════════════════╧═════════════════════╧═══════════════════╧═════════════════════╧══════════════════════════╧═══════════════════════╧══════════════════════════════╧══════════════╝
   `

   and the times:
   `
   grep -n -e totalCreateTime -e totalUpsertTime  *.commit
   20200213224218.commit:36:  "totalCreateTime" : 30012,
   20200213224218.commit:37:  "totalUpsertTime" : 0,
   20200213224325.commit:36:  "totalCreateTime" : 0,
   20200213224325.commit:37:  "totalUpsertTime" : 46879,
   20200213224532.commit:36:  "totalCreateTime" : 0,
   20200213224532.commit:37:  "totalUpsertTime" : 10347280,
   20200214013937.commit:36:  "totalCreateTime" : 0,
   20200214013937.commit:37:  "totalUpsertTime" : 44598,
   `

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586071719


   Ok, thanks for this.

   I have run the jobs again. First, insert 4m records, then upsert 3m of them, then upsert 4m, then upsert 4m. The two jobs upserting 3m records work fine and quickly, but the one where upsert 4m takes >200 times as long.

   My results (from a synthetic dataset) are:
   ```bash
   hudi:json_data->commits show --limit 4
   ╔════════════════╤═════════════════════╤═══════════════════╤═════════════════════╤══════════════════════════╤═══════════════════════╤══════════════════════════════╤══════════════╗
   ║ CommitTime     │ Total Bytes Written │ Total Files Added │ Total Files Updated │ Total Partitions Written │ Total Records Written │ Total Update Records Written │ Total Errors ║
   ╠════════════════╪═════════════════════╪═══════════════════╪═════════════════════╪══════════════════════════╪═══════════════════════╪══════════════════════════════╪══════════════╣
   ║ 20200214013937 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224532 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 4000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224325 │ 25.6 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224218 │ 25.5 MB             │ 1                 │ 0                   │ 1                        │ 4000000               │ 0                            │ 0            ║
   ╚════════════════╧═════════════════════╧═══════════════════╧═════════════════════╧══════════════════════════╧═══════════════════════╧══════════════════════════════╧══════════════╝
   ```

   and the times:
   ```bash
   grep -n -e totalCreateTime -e totalUpsertTime  *.commit
   20200213224218.commit:36:  "totalCreateTime" : 30012,
   20200213224218.commit:37:  "totalUpsertTime" : 0,
   20200213224325.commit:36:  "totalCreateTime" : 0,
   20200213224325.commit:37:  "totalUpsertTime" : 46879,
   20200213224532.commit:36:  "totalCreateTime" : 0,
   20200213224532.commit:37:  "totalUpsertTime" : 10347280,
   20200214013937.commit:36:  "totalCreateTime" : 0,
   20200214013937.commit:37:  "totalUpsertTime" : 44598,
   ```

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585503340


   Reposting my response here..

   There seems to be a lot of common concerns here.. https://cwiki.apache.org/confluence/display/HUDI/Tuning+Guide is an useful resource, that hopefully can benefit here..

   Few high level thoughts:
   It would be good to layout if the most time spent is on the indexing stages (ones tagged with HoodieBloomIndex) or the actual writing..
   Hudi does keep the input in memory to compute the stats it needs to size files. So if you don't provide sufficient executore/rdd storage memory, it will spill and can cause slowdowns.. (covered in tuning guide & have seen this happen with users often)
   On workload pattern itself, BloomIndex range pruning can be turned off https://hudi.apache.org/docs/configurations.html#bloomIndexPruneByRanges if the keys ranges are random anyway.. Generally speaking, unless we have RFC-8 (record level indexing), cases of random write/upserting majority of the rows in a table, may give bloom index overhead, since the bloom filters/ranges are not at all useful in pruning out files . We have an interim solution coming out in the next release.. falling back to plain old join to implement the indexing.
   In terms or MOR and COW, MOR will help only if you have lots of updates and bottleneck is on the writing..
   If listing is an issue, please turn the following so the table is listed once and we re-use the filesytem metadata hoodie.embed.timeline.server=true
   I would appreciate a JIRA, so that I can break each into sub-task and tackle/resolve independently..

   I am personally focussing on performance now and want to make it lot faster in 0.6.0 release. So all this help would be deeply appreciated

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586071719


   Ok, thanks for this.

   I have run the jobs again. First, insert 4m records, then upsert 3m of them, then upsert 4m, then upsert 4m. The two jobs upserting 3m records work fine and quickly, but the one where upsert 4m takes >200 times as long. There is no partitioning and only one (small) output file.

   My results (from a synthetic dataset) are:
   ```bash
   hudi:json_data->commits show --limit 4
   ╔════════════════╤═════════════════════╤═══════════════════╤═════════════════════╤══════════════════════════╤═══════════════════════╤══════════════════════════════╤══════════════╗
   ║ CommitTime     │ Total Bytes Written │ Total Files Added │ Total Files Updated │ Total Partitions Written │ Total Records Written │ Total Update Records Written │ Total Errors ║
   ╠════════════════╪═════════════════════╪═══════════════════╪═════════════════════╪══════════════════════════╪═══════════════════════╪══════════════════════════════╪══════════════╣
   ║ 20200214013937 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224532 │ 25.5 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 4000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224325 │ 25.6 MB             │ 0                 │ 1                   │ 1                        │ 4000000               │ 3000000                      │ 0            ║
   ╟────────────────┼─────────────────────┼───────────────────┼─────────────────────┼──────────────────────────┼───────────────────────┼──────────────────────────────┼──────────────╢
   ║ 20200213224218 │ 25.5 MB             │ 1                 │ 0                   │ 1                        │ 4000000               │ 0                            │ 0            ║
   ╚════════════════╧═════════════════════╧═══════════════════╧═════════════════════╧══════════════════════════╧═══════════════════════╧══════════════════════════════╧══════════════╝
   ```

   and the times:
   ```bash
   grep -n -e totalCreateTime -e totalUpsertTime  *.commit
   20200213224218.commit:36:  "totalCreateTime" : 30012,
   20200213224218.commit:37:  "totalUpsertTime" : 0,
   20200213224325.commit:36:  "totalCreateTime" : 0,
   20200213224325.commit:37:  "totalUpsertTime" : 46879,
   20200213224532.commit:36:  "totalCreateTime" : 0,
   20200213224532.commit:37:  "totalUpsertTime" : 10347280,
   20200214013937.commit:36:  "totalCreateTime" : 0,
   20200214013937.commit:37:  "totalUpsertTime" : 44598,
   ```

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 commented on issue #1328: Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
bwu2 commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-586108720


   Ok, after reading https://github.com/apache/incubator-hudi/issues/800 (which is simialr), I think this is a memory issue (even though GC seems to be a small proportion of the total time, according to the Spark history server & we're not getting any OOME).

   When I double the `spark.executor.memory` the job runs much faster. I'm sure there are maybe other optimizations and/or tuning I can consider also.

   Is it normal/expected that an upsert with mostly updates would require more memory than an upsert with mostly inserts?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 commented on issue #1328: Hudi upsert hangs
Posted by GitBox <gi...@apache.org>.
bwu2 commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585471970


   An update on this: the job did eventually complete. But took 2.4 hours (other similar jobs ran more than 9 hours before we had to kill them). This doesn't seem reasonable for such a small table.

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] bwu2 edited a comment on issue #1328: Hudi upsert
hangs
Posted by GitBox <gi...@apache.org>.
bwu2 edited a comment on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-585512613


   @vinothchandar Thanks for taking the time to reply!

   Let me describe the simplest example of this problem on a tiny COW data set: Create a data frame with 4m rows and one column with values 1, 2, 3....4m in that column. Bulk insert that into Hudi (using the one column as the `recordkey`). This takes ~1 minute to run and the data size is about 30MB. Now upsert the same data frame into the table a second time. This take >2 hours to run.

   Alternatively, if we upsert a new data frame with values 4000001...8m (still 4m rows upserted), this takes ~1 minute to run.

   To answer your other queries:
   * almost all of the time is spent in the  `HoodieSparkSqlWriter`}} job (and within that job, the `count at HoodieSparkSqlWriter.scala` stage (the `HoodieBloomIndex` jobs run quickly).
   * it seems highly unlikely to be resource constraint issue with such a small example.

   Shall i raise a JIRA for this? Or is this the expected behavior for such a workload?

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-594114291


   Fix landed on master

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-589452198


   @bwu2 Got it.. I think the root issue is that the map is spilling more than needed. I am trying to understand why.. Will update the JIRA as I uncover stuff. if its easy, we can target a fix in the next 0.5.2 release itself.

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services
[GitHub] [incubator-hudi] vinothchandar commented on issue #1328: Hudi
upsert hangs
Posted by GitBox <gi...@apache.org>.
vinothchandar commented on issue #1328: Hudi upsert hangs
URL: https://github.com/apache/incubator-hudi/issues/1328#issuecomment-587663160


   Started on this.. Was trying to port to scala, since I am not super familiar with pySpark. Will resume today and circle back. :)

----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


With regards,
Apache Git Services