You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by "DavidZ1 (via GitHub)" <gi...@apache.org> on 2023/02/28 04:01:26 UTC
[GitHub] [hudi] DavidZ1 opened a new issue, #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
DavidZ1 opened a new issue, #8071:
URL: https://github.com/apache/hudi/issues/8071
**_Tips before filing an issue_**
- Have you gone through our [FAQs](https://hudi.apache.org/learn/faq/)?
- Join the mailing list to engage in conversations and get faster support at dev-subscribe@hudi.apache.org.
- If you have triaged this as a bug, then file an [issue](https://issues.apache.org/jira/projects/HUDI/issues) directly.
**Describe the problem you faced**
We currently have a car cloud business that consumes in real time through flink tasks and writes it into hudi. The source is kafka, and the messages of json in kafka are parsed. There are about **3600 fields** for hudi, 90% of which are of double type. However, our test found that flink writes to hudi at a faster speed It is relatively slow and cannot keep up with the speed of Kafka message production. We can't find the reason at present?
A clear and concise description of the problem.
**To Reproduce**
Steps to reproduce the behavior:
1.
2.
3.
4.
**Expected behavior**
A clear and concise description of what you expected to happen.
**Environment Description**
* Hudi version :0.12.2 and 0.13.0
* Spark version : 3.2.2
* Hive version : 3.2.1
* Hadoop version : 3.2.2
* Storage (HDFS/S3/GCS..) : COS (cloud cloud )
* Running on Docker? (yes/no) : yes
**Additional context**
1.Hudi config
`checkpoint.interval=300
checkpoint.timeout=600
compaction.max_memory=1024
payload.class.name=org.apache.hudi.common.model.OverwriteNonDefaultsWithLatestAvroPayload
compaction.delta_commits=20
compaction.trigger.strategy=num_or_time
compaction.delta_seconds=3600
clean.policy=KEEP_LATEST_COMMITS
clean.retain_commits=2
hoodie.bucket.index.num.buckets=40
archive.max_commits=50
archive.min_commits=40
table.type=MERGE_ON_READ
hoodie.datasource.write.hive_style_partitioning=true
index.type=BUCKET write.operation=upsert
compaction.schedule.enabled=true
compaction.async.enabled=true
`
2.kafka
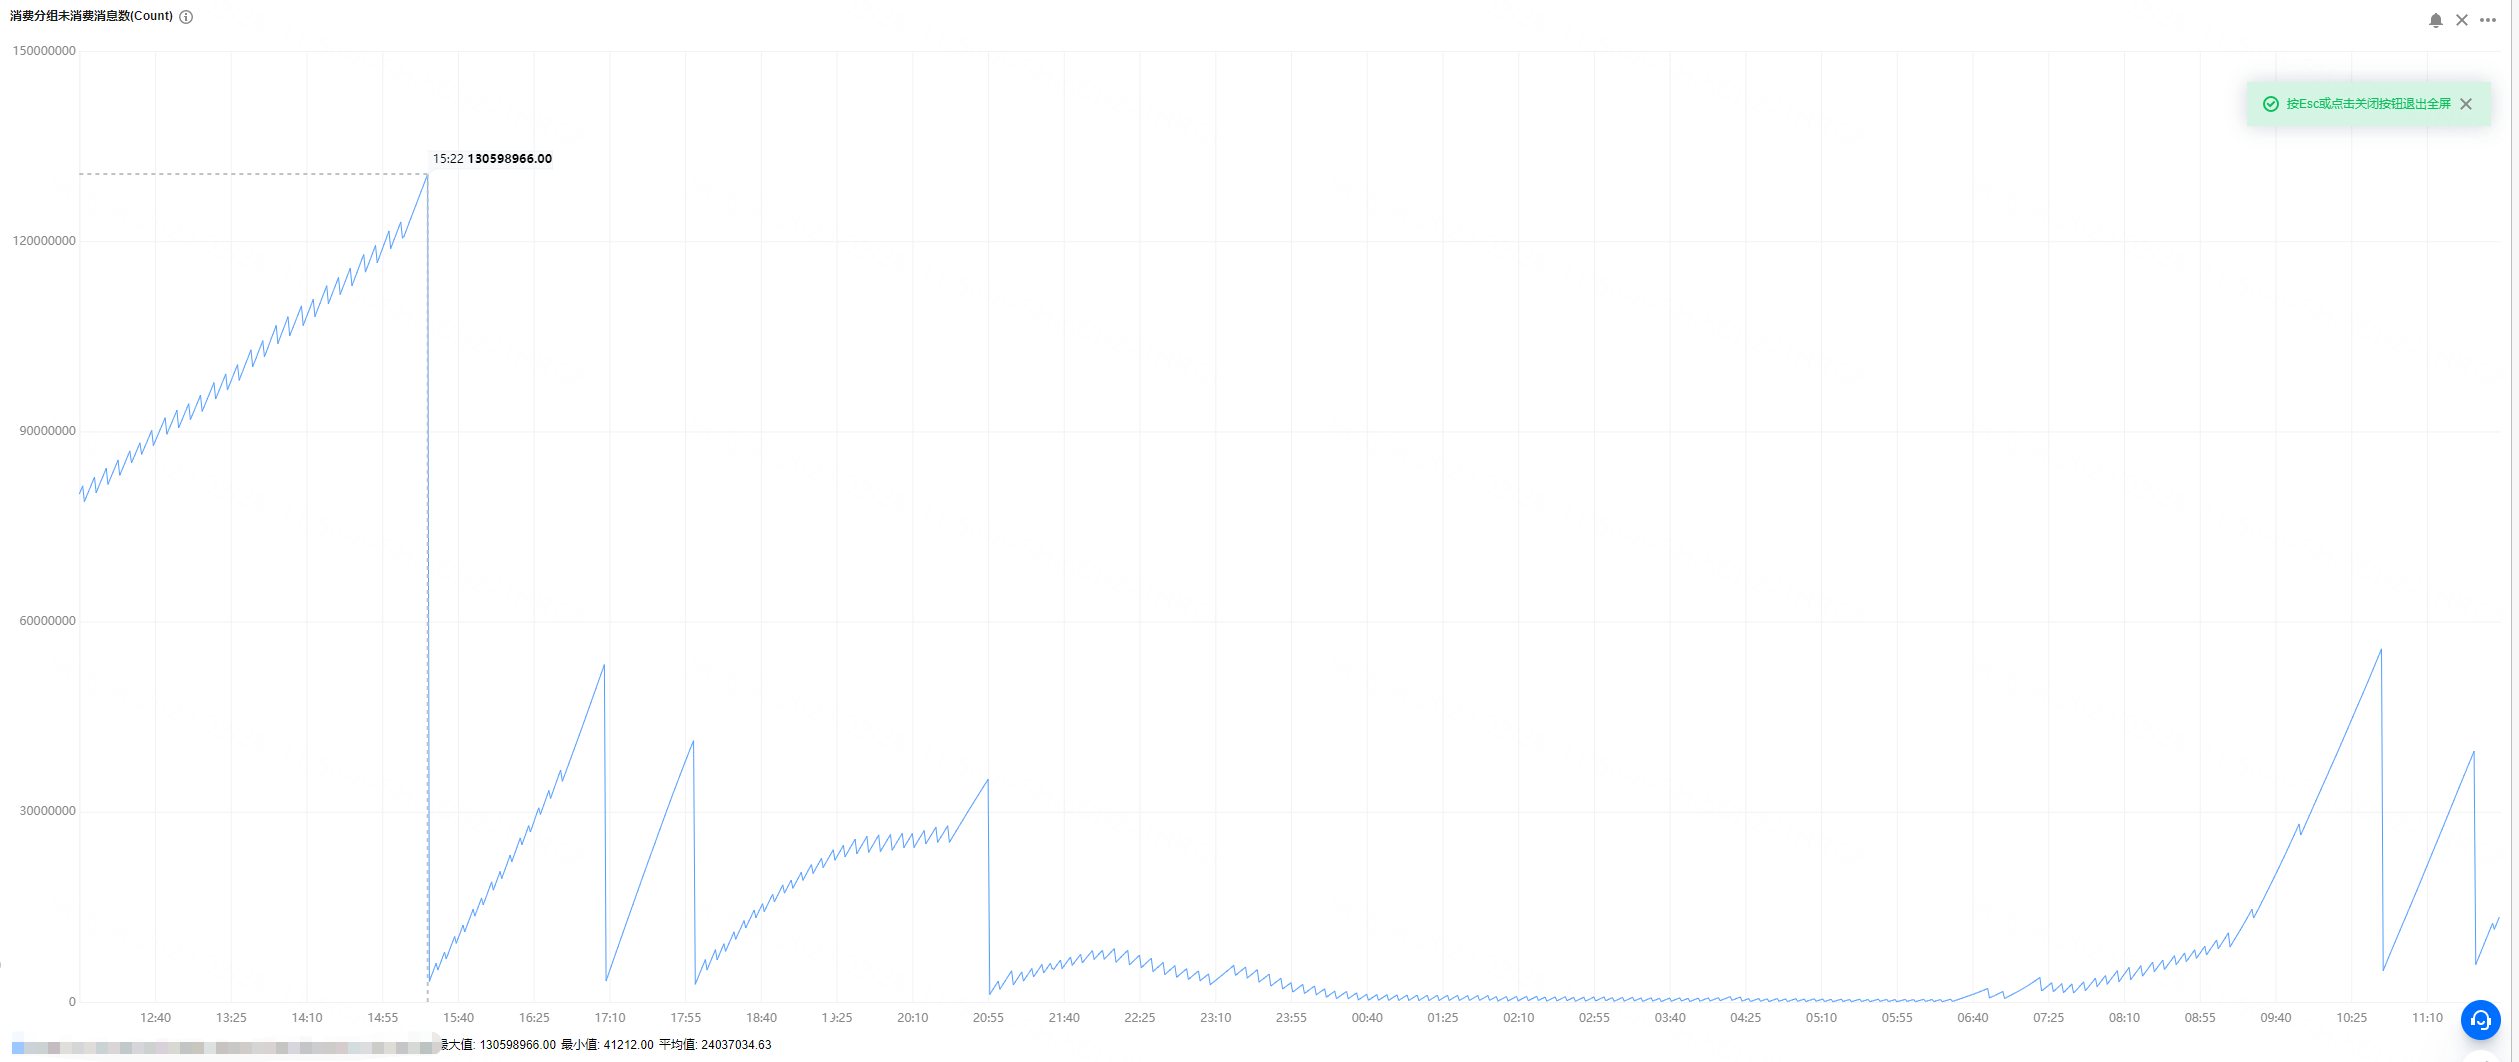
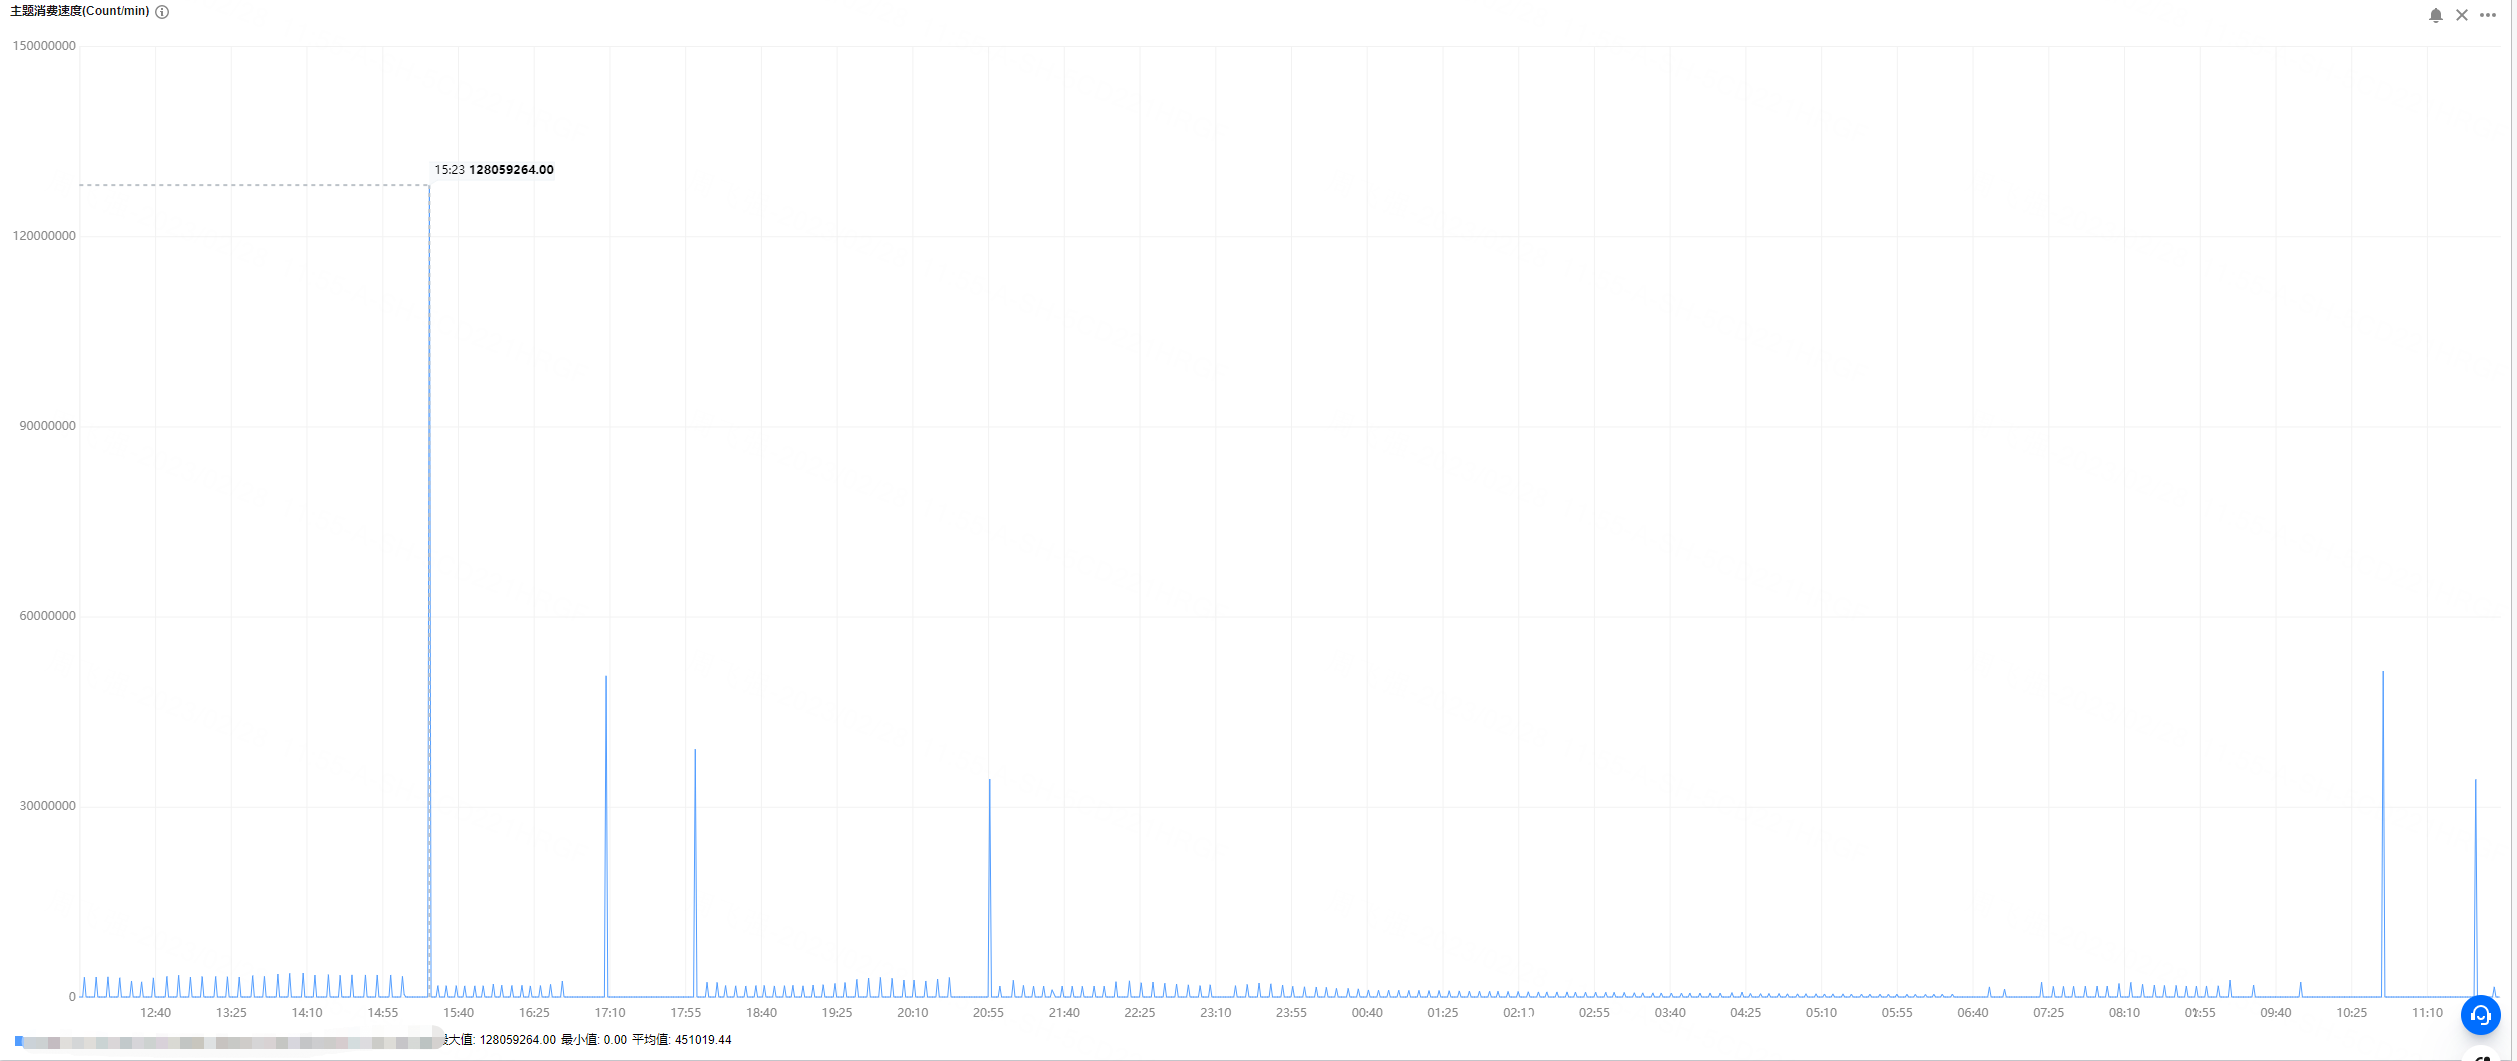
24 partitions, 200G messages per hour, each message is a JSON format, flink obtains about 3600 signal field data (double) from the JSON message
3.flink
We used 20 tasks (each task 2 core and 8gb memory) or 48 tasks (each task 1 core and 4gb memory) for the flink task. After running for an hour, we found that the speed of consumption could not keep up with the speed of message production.
We use Tencent Cloud's streaming computing platform Oceanus: 1 computing CU includes 1 core CPU and 4GB memory. According to the difference between upstream and downstream and processing logic, the processing capacity of 1CU is about 5000 pieces/second to 50000 pieces/second. The computing performance of simple services is about 30,000 entries/second/core to 50,000 entries/second/core, and the computing performance of complex services is about 5,000 entries/second/core to 10,000 entries/second/core.
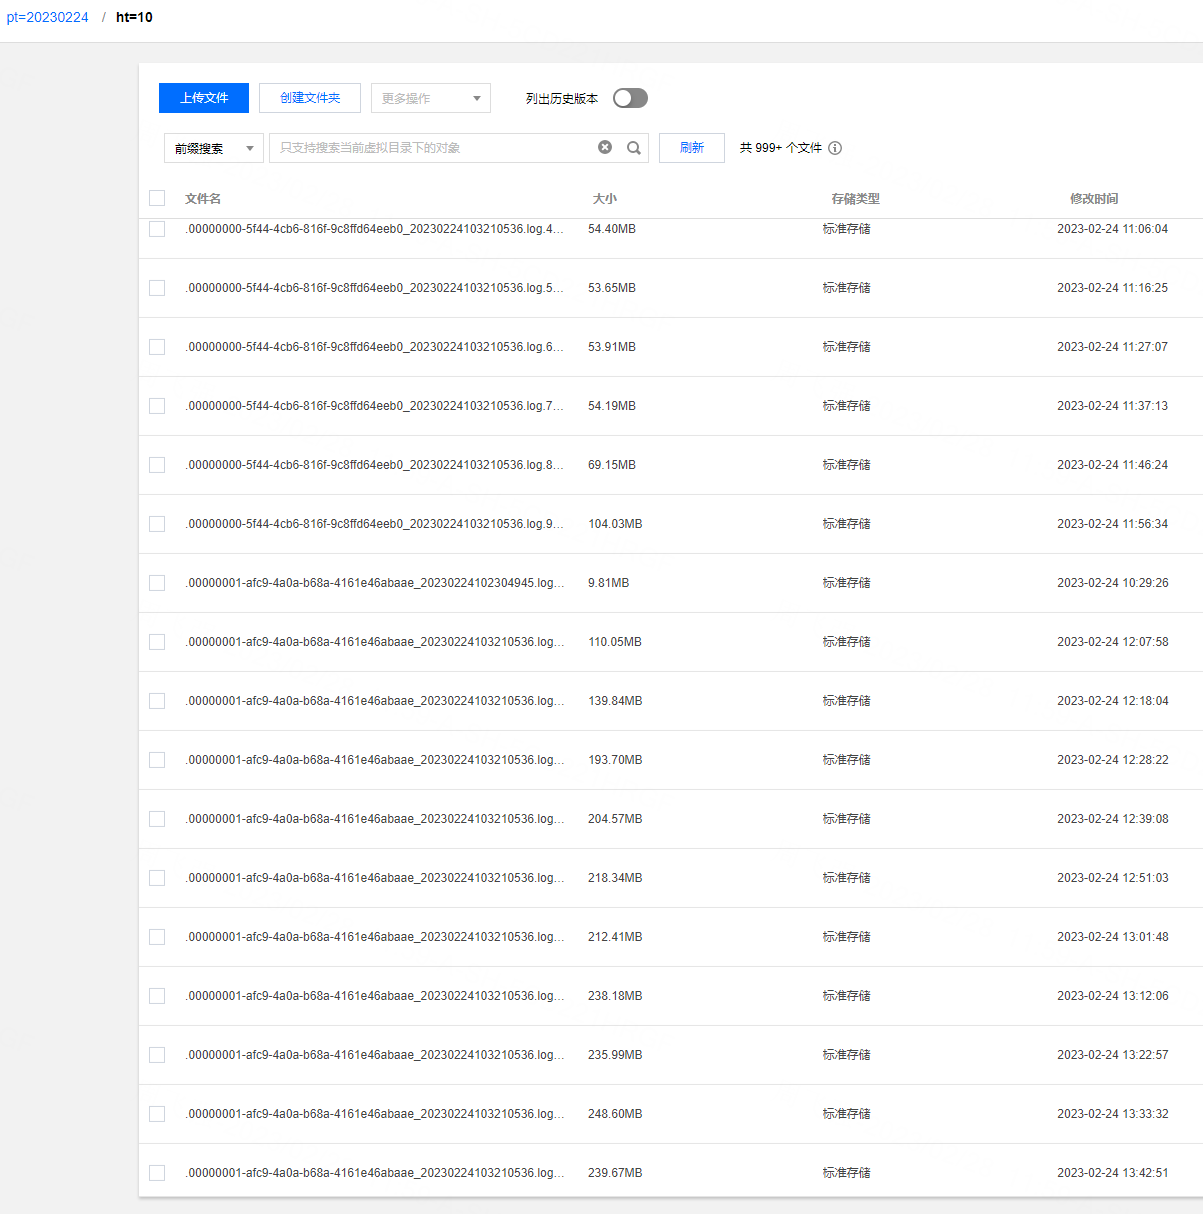
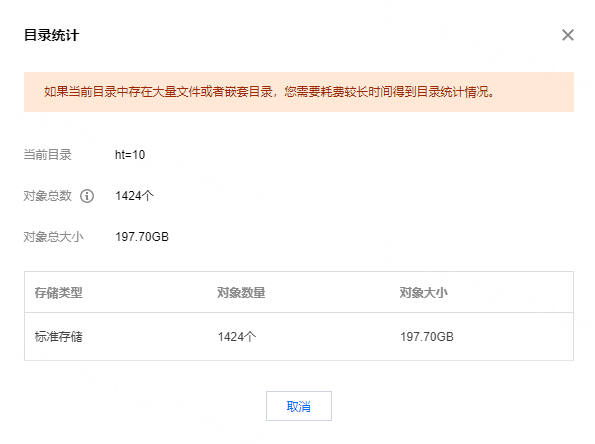
When writing cos at the same time, there will be many small files, the maximum can reach 4000+.
Add any other context about the problem here.
**Stacktrace**
```Add the stacktrace of the error.```
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1451852694

   > @DavidZ1 If you are running it under append-only `[INSERT mode + COPY_ON_WRITE]`, you can improve write throughput by changing the default compression codec from gzip to SNAPPY / LZ4.
   >
   > Snappy should be supported out of the box, but you will be trading off storage space for write throughput.
   >
   > I would recommend LZ4 if you have the appropriate bundles included in your environment.

   Thx, we use the flink jar method to write to hudi, but I can't find the relevant setting data compression format parameters in `FlinkOptions` class.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1467208193

   Maybe you can just take a reference of this doc: https://www.yuque.com/yuzhao-my9fz/kb/flqll8?#cJu7y


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1451293882

   Do you wanna update? If not, you can just set the operation type as `INSERT` and table type as `COPY_ON_WRITE`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1447909237

   Yes,we try to increase the  `write.tasks `  to 40,can not improve the write throughput.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1463363633

   Thanks, for COW table with insert operation, Flink does not use any index, so the bucket index does not work here, the write throughput should be high, and for UPSERTs with bucket index, if you use the COW, yes, the performance is bad because the whole table/partition is almot rewritten each ckp.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1590315146

   Guess you are a chinese, here is a chinese doc for bucket index: https://www.yuque.com/yuzhao-my9fz/kb/flqll8?#g3rZq


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1447927592

   Which step is the boottleneck, bucket stream write?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1461365835

   You timeout threshold is 10min, it should be fine, why it task 5min to ckp, the append mode only flush new Parquets.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1457405997

   What version of Hudi did you use, previously we resolved a bug for append mode partial failover: https://github.com/apache/hudi/pull/7208/files,

   The phenomenon is that when partial failover happens, the task would hang out there until the timeout happens. The bug was not resolved until release 0.12.2.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1453167727

   We switched the encoding format and started to use the lz4 format to compress, but found that the platform does not support it, and the exception is as follows:
   `
   java.io.IOException: java.io.IOException: Exception happened when bulk insert.
   	at org.apache.hudi.sink.bulk.BulkInsertWriterHelper.write(BulkInsertWriterHelper.java:117)
   	at org.apache.hudi.sink.append.AppendWriteFunction.processElement(AppendWriteFunction.java:86)
   	at org.apache.flink.streaming.api.operators.ProcessOperator.processElement(ProcessOperator.java:66)
   	at org.apache.flink.streaming.runtime.tasks.OneInputStreamTask$StreamTaskNetworkOutput.emitRecord(OneInputStreamTask.java:205)
   	at org.apache.flink.streaming.runtime.io.AbstractStreamTaskNetworkInput.processElement(AbstractStreamTaskNetworkInput.java:134)
   	at org.apache.flink.streaming.runtime.io.AbstractStreamTaskNetworkInput.emitNext(AbstractStreamTaskNetworkInput.java:105)
   	at org.apache.flink.streaming.runtime.io.StreamOneInputProcessor.processInput(StreamOneInputProcessor.java:66)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.processInput(StreamTask.java:423)
   	at org.apache.flink.streaming.runtime.tasks.mailbox.MailboxProcessor.runMailboxLoop(MailboxProcessor.java:204)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.runMailboxLoop(StreamTask.java:684)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.executeInvoke(StreamTask.java:639)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.runWithCleanUpOnFail(StreamTask.java:650)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.invoke(StreamTask.java:623)
   	at org.apache.flink.runtime.taskmanager.Task.doRun(Task.java:779)
   	at org.apache.flink.runtime.taskmanager.Task.run(Task.java:566)
   	at java.lang.Thread.run(Thread.java:750)
   Caused by: java.io.IOException: Exception happened when bulk insert.
   	at org.apache.hudi.sink.bulk.BulkInsertWriterHelper.write(BulkInsertWriterHelper.java:115)
   	... 15 more
   Caused by: java.lang.RuntimeException: native lz4 library not available
   	at org.apache.hadoop.io.compress.Lz4Codec.getCompressorType(Lz4Codec.java:125)
   	at org.apache.hadoop.io.compress.CodecPool.getCompressor(CodecPool.java:150)
   	at org.apache.hadoop.io.compress.CodecPool.getCompressor(CodecPool.java:168)
   	at org.apache.parquet.hadoop.CodecFactory$HeapBytesCompressor.<init>(CodecFactory.java:146)
   	at org.apache.parquet.hadoop.CodecFactory.createCompressor(CodecFactory.java:208)
   	at org.apache.parquet.hadoop.CodecFactory.getCompressor(CodecFactory.java:191)
   	at org.apache.parquet.hadoop.ParquetWriter.<init>(ParquetWriter.java:296)
   	at org.apache.parquet.hadoop.ParquetWriter.<init>(ParquetWriter.java:228)
   	at org.apache.hudi.io.storage.row.HoodieRowDataParquetWriter.<init>(HoodieRowDataParquetWriter.java:45)
   	at org.apache.hudi.io.storage.row.HoodieRowDataFileWriterFactory.newParquetInternalRowFileWriter(HoodieRowDataFileWriterFactory.java:79)
   	at org.apache.hudi.io.storage.row.HoodieRowDataFileWriterFactory.getRowDataFileWriter(HoodieRowDataFileWriterFactory.java:55)
   	at org.apache.hudi.io.storage.row.HoodieRowDataCreateHandle.createNewFileWriter(HoodieRowDataCreateHandle.java:211)
   	at org.apache.hudi.io.storage.row.HoodieRowDataCreateHandle.<init>(HoodieRowDataCreateHandle.java:103)
   	at org.apache.hudi.sink.bulk.BulkInsertWriterHelper.getRowCreateHandle(BulkInsertWriterHelper.java:134)
   	at org.apache.hudi.sink.bulk.BulkInsertWriterHelper.write(BulkInsertWriterHelper.java:110)
   	... 15 more
   `


   Then we switched to the snappy format, and the writing performance did improve to a certain extent. However, due to the Tencent Cloud COS we used for storage, there was a list frequency control problem in cow writing, so the overall performance could not be greatly improved,and the exception is as follows:

   `org.apache.hudi.exception.HoodieException: Timeout(601000ms) while waiting for instant initialize
   	at org.apache.hudi.sink.utils.TimeWait.waitFor(TimeWait.java:57)
   	at org.apache.hudi.sink.common.AbstractStreamWriteFunction.instantToWrite(AbstractStreamWriteFunction.java:276)
   	at org.apache.hudi.sink.append.AppendWriteFunction.initWriterHelper(AppendWriteFunction.java:110)
   	at org.apache.hudi.sink.append.AppendWriteFunction.processElement(AppendWriteFunction.java:84)
   	at org.apache.flink.streaming.api.operators.ProcessOperator.processElement(ProcessOperator.java:66)
   	at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.pushToOperator(CopyingChainingOutput.java:71)
   	at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.collect(CopyingChainingOutput.java:46)
   	at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.collect(CopyingChainingOutput.java:26)
   	at org.apache.flink.streaming.runtime.tasks.SourceOperatorStreamTask$AsyncDataOutputToOutput.emitRecord(SourceOperatorStreamTask.java:188)
   	at org.apache.flink.streaming.api.operators.source.SourceOutputWithWatermarks.collect(SourceOutputWithWatermarks.java:110)
   	at org.apache.flink.connector.kafka.source.reader.KafkaRecordEmitter.emitRecord(KafkaRecordEmitter.java:36)
   	at org.apache.flink.connector.kafka.source.reader.KafkaRecordEmitter.emitRecord(KafkaRecordEmitter.java:27)
   	at org.apache.flink.connector.base.source.reader.SourceReaderBase.pollNext(SourceReaderBase.java:128)
   	at org.apache.flink.streaming.api.operators.SourceOperator.emitNext(SourceOperator.java:305)
   	at org.apache.flink.streaming.runtime.io.StreamTaskSourceInput.emitNext(StreamTaskSourceInput.java:69)
   	at org.apache.flink.streaming.runtime.io.StreamOneInputProcessor.processInput(StreamOneInputProcessor.java:66)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.processInput(StreamTask.java:423)
   	at org.apache.flink.streaming.runtime.tasks.mailbox.MailboxProcessor.runMailboxLoop(MailboxProcessor.java:204)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.runMailboxLoop(StreamTask.java:684)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.executeInvoke(StreamTask.java:639)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.runWithCleanUpOnFail(StreamTask.java:650)
   	at org.apache.flink.streaming.runtime.tasks.StreamTask.invoke(StreamTask.java:623)
   	at org.apache.flink.runtime.taskmanager.Task.doRun(Task.java:779)
   	at org.apache.flink.runtime.taskmanager.Task.run(Task.java:566)
   	at java.lang.Thread.run(Thread.java:750)
   `


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1592228207

   > partitioning strategies

   For partitioning strategies, are you referring to the data buckets (or FileGroup in Hudi's notion) or just regular directories like Hive, if it is former, here is the doc about Hudi file layput: https://hudi.apache.org/docs/file_layouts.

   For cow table, each update of the existing file group would trigger a re-write of the whole parquet file, so there is somehow large write amplification.

   For mor table, Hudi just prepend the new records first, and the data compation task was defered as an async execution.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1457281256
I adjusted the` write.parquet.max.file.size` parameter to 3000, and the flink job started to run normally, but after several checkpoints, it failed. I checked the size of the written file, and the maximum was 80MB. The exception is still the same as before, as follows:
`
2023-03-06 20:51:56.793 [Checkpoint Timer] INFO org.apache.flink.runtime.checkpoint.CheckpointCoordinator [] - Checkpoint 3 of job 00000000000000000000000000000000 expired before completing.
2023-03-06 20:51:56.795 [jobmanager-future-thread-5] INFO com.tencent.cloud.tstream.flink.OceanusCheckpointListener [] - Begin to post checkpoint failed event
2023-03-06 20:51:56.851 [jobmanager-future-thread-5] INFO com.tencent.cloud.tstream.flink.OceanusCheckpointListener [] - Watchdog response: HttpResponseProxy{HTTP/1.1 200 OK [Content-Type: text/html;charset=UTF-8, Content-Length: 48, Server: Jetty(8.1.19.v20160209)] ResponseEntityProxy{[Content-Type: text/html;charset=UTF-8,Content-Length: 48,Chunked: false]}}
2023-03-06 20:51:57.128 [Checkpoint Timer] INFO org.apache.flink.runtime.checkpoint.CheckpointCoordinator [] - Triggering checkpoint 4 (type=CHECKPOINT) @ 1678107116797 for job 00000000000000000000000000000000.
2023-03-06 20:51:57.128 [pool-18-thread-1] INFO org.apache.hudi.sink.StreamWriteOperatorCoordinator [] - Executor executes action [taking checkpoint 4] success!
2023-03-06 20:52:42.977 [flink-akka.actor.default-dispatcher-24] INFO org.apache.flink.runtime.executiongraph.ExecutionGraph [] - Source: IvcVhrCan Source From Kafka with no watermarks -> hoodie_append_write: ods_icv_can_hudi_temp -> Sink: dummy (17/24) (adf8b18b3e47d3c35adcb79b1a953bb4) switched from RUNNING to FAILED on cql-ncgz4z8e-582618-taskmanager-1-1 @xxxxx (dataPort=xxx).
org.apache.hudi.exception.HoodieException: Timeout(601000ms) while waiting for instant initialize
at org.apache.hudi.sink.utils.TimeWait.waitFor(TimeWait.java:57) ~[?:?]
at org.apache.hudi.sink.common.AbstractStreamWriteFunction.instantToWrite(AbstractStreamWriteFunction.java:276) ~[?:?]
at org.apache.hudi.sink.append.AppendWriteFunction.initWriterHelper(AppendWriteFunction.java:110) ~[?:?]
at org.apache.hudi.sink.append.AppendWriteFunction.processElement(AppendWriteFunction.java:84) ~[?:?]
at org.apache.flink.streaming.api.operators.ProcessOperator.processElement(ProcessOperator.java:66) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.pushToOperator(CopyingChainingOutput.java:71) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.collect(CopyingChainingOutput.java:46) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.collect(CopyingChainingOutput.java:26) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.SourceOperatorStreamTask$AsyncDataOutputToOutput.emitRecord(SourceOperatorStreamTask.java:188) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.api.operators.source.SourceOutputWithWatermarks.collect(SourceOutputWithWatermarks.java:110) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.connector.kafka.source.reader.KafkaRecordEmitter.emitRecord(KafkaRecordEmitter.java:36) ~[?:?]
at org.apache.flink.connector.kafka.source.reader.KafkaRecordEmitter.emitRecord(KafkaRecordEmitter.java:27) ~[?:?]
at org.apache.flink.connector.base.source.reader.SourceReaderBase.pollNext(SourceReaderBase.java:128) ~[flink-table-blink_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.api.operators.SourceOperator.emitNext(SourceOperator.java:305) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.io.StreamTaskSourceInput.emitNext(StreamTaskSourceInput.java:69) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.io.StreamOneInputProcessor.processInput(StreamOneInputProcessor.java:66) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.processInput(StreamTask.java:423) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.mailbox.MailboxProcessor.runMailboxLoop(MailboxProcessor.java:204) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.runMailboxLoop(StreamTask.java:684) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.executeInvoke(StreamTask.java:639) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.runWithCleanUpOnFail(StreamTask.java:650) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.invoke(StreamTask.java:623) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.runtime.taskmanager.Task.doRun(Task.java:779) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.runtime.taskmanager.Task.run(Task.java:566) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at java.lang.Thread.run(Thread.java:750) ~[?:1.8.0_332]
2023-03-06 20:52:42.992 [flink-akka.actor.default-dispatcher-18] INFO org.apache.flink.runtime.resourcemanager.slotmanager.DeclarativeSlotManager [] - Received resource requirements from job 00000000000000000000000000000000: [ResourceRequirement{resourceProfile=ResourceProfile{UNKNOWN}, numberOfRequiredSlots=23}]
2023-03-06 20:52:42.994 [flink-akka.actor.default-dispatcher-24] WARN org.apache.hudi.sink.StreamWriteOperatorCoordinator [] - Reset the event for task [16]
org.apache.hudi.exception.HoodieException: Timeout(601000ms) while waiting for instant initialize
at org.apache.hudi.sink.utils.TimeWait.waitFor(TimeWait.java:57) ~[?:?]
at org.apache.hudi.sink.common.AbstractStreamWriteFunction.instantToWrite(AbstractStreamWriteFunction.java:276) ~[?:?]
at org.apache.hudi.sink.append.AppendWriteFunction.initWriterHelper(AppendWriteFunction.java:110) ~[?:?]
at org.apache.hudi.sink.append.AppendWriteFunction.processElement(AppendWriteFunction.java:84) ~[?:?]
at org.apache.flink.streaming.api.operators.ProcessOperator.processElement(ProcessOperator.java:66) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.pushToOperator(CopyingChainingOutput.java:71) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.collect(CopyingChainingOutput.java:46) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.CopyingChainingOutput.collect(CopyingChainingOutput.java:26) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.SourceOperatorStreamTask$AsyncDataOutputToOutput.emitRecord(SourceOperatorStreamTask.java:188) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.api.operators.source.SourceOutputWithWatermarks.collect(SourceOutputWithWatermarks.java:110) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.connector.kafka.source.reader.KafkaRecordEmitter.emitRecord(KafkaRecordEmitter.java:36) ~[?:?]
at org.apache.flink.connector.kafka.source.reader.KafkaRecordEmitter.emitRecord(KafkaRecordEmitter.java:27) ~[?:?]
at org.apache.flink.connector.base.source.reader.SourceReaderBase.pollNext(SourceReaderBase.java:128) ~[flink-table-blink_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.api.operators.SourceOperator.emitNext(SourceOperator.java:305) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.io.StreamTaskSourceInput.emitNext(StreamTaskSourceInput.java:69) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.io.StreamOneInputProcessor.processInput(StreamOneInputProcessor.java:66) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.processInput(StreamTask.java:423) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.mailbox.MailboxProcessor.runMailboxLoop(MailboxProcessor.java:204) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.runMailboxLoop(StreamTask.java:684) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.executeInvoke(StreamTask.java:639) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.runWithCleanUpOnFail(StreamTask.java:650) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.streaming.runtime.tasks.StreamTask.invoke(StreamTask.java:623) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.runtime.taskmanager.Task.doRun(Task.java:779) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at org.apache.flink.runtime.taskmanager.Task.run(Task.java:566) ~[flink-dist_2.11-1.13.6.jar:1.13.6]
at java.lang.Thread.run(Thread.java:750) ~[?:1.8.0_332]
`

Number of files in a single partition

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1457659474

   Is there any preceding error throws out before the `Timeout(xxx)` exceptions emerged ?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1449423494
Before we wrote about `3600 fields` in the hudi table, but the writing performance did not improve. Today we did another test, reducing the number of fields in the hudi table. The number of fields in the hudi table was adjusted to `1000`. The writing performance has been greatly improved, and the consumption speed of Kafka has been greatly improved, which can keep up with the production speed.
But we can't determine which step in hudi takes a long time to cause?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] Vsevolod3 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "Vsevolod3 (via GitHub)" <gi...@apache.org>.
Vsevolod3 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1587175785

   Thanks for your response. Here are our properties for state-backend (from flink-conf on EMR), and as you can see, incremental checkpointing is enabled:

   ```
   "state.backend": "rocksdb",
   "state.backend.incremental": "true",
   "state.checkpoint-storage": "filesystem",
   "state.checkpoints.dir": "s3://*****/flink-checkpoints",
   ```

   Do you see any potential problems with these configs?

   In relation to using the bucket index, are these the correct properties to try? I will do some testing with the defaults, but if you have any suggestions for improving these, please let me know.

   ```
   hoodie.index.type=BUCKET
   hoodie.bucket.index.hash.field=<some field, probably PK>
   hoodie.bucket.index.num.buckets=256
   hoodie.index.bucket.engine=SIMPLE
   hoodie.bucket.index.num.buckets=4
   ```

   Thanks in advance.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1449980799

   I understand that the 3,600 fields in our hudi table are basically double types. For such a relatively large wide table, is there any optimization plan to improve the write throughput?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1463080933

   Isn't it normal for streaming data to ck for 5 minutes? Any better optimization suggestions for ck? The bucket index I use theoretically only creates 50 files each time. I don't quite understand what you said about ` the append mode only flush new Parquets`.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1454362050

   Sorry for late reply, did you already use the append and it is still slow?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1457668010

   I checked the tasks running log, but did not see any other abnormal information.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1583958938

   The throughput would be optimized if you use the bucket index instead, BTW, what kind of state-backend did you use, did you enable the incremental checkpointing?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] Vsevolod3 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "Vsevolod3 (via GitHub)" <gi...@apache.org>.
Vsevolod3 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1582970788
We're having a similar issue with write performance. The Hudi stream_write task takes between 8 and 10 minutes for a MoR table and between 9 and 11 minutes for a CoW table to write 600K records. This performance is slow even for when the destination is completely empty and the corresponding Glue Catalog table doesn't exist. I'm including the details of our testing below:
## Test parameters:
- 600,000 records
- About 128MB of input data
- UPSERT mode (both CoW and MoR)
- Flink 1.15.2
- Hudi 0.13.0
- Partitioning: this is done by extracting the year and month element of the record created_dttm and creating columns de_year and de_month for partitioning; this results in hive-style partitions in S3, like de_year=X/de_month=Y.
## CoW Testing
### CoW results (sample):
- For operators:
- map tasks (4 parallel slots): 174ms
- bucket assigner (4 parallel slots): 1s
- stream_write (6 parallel slots): 9m 49s
- File sizes: ~450KB
### CoW options being set on HoodiePipeline.Builder:
```
'connector' = 'hudi',
'index.type' = 'BLOOM',
'compaction.schedule.enabled' = 'true',
'clustering.plan.strategy.sort.columns' = 'acct_id',
'compaction.delta_seconds' = '720',
'clustering.delta_commits' = '4',
'clustering.plan.strategy.small.file.limit' = '600',
'compaction.async.enabled' = 'true',
'compaction.max_memory' = '100',
'hoodie.parquet.max.file.size' = '125829120',
'read.streaming.enabled' = 'false',
'path' = 's3://*****/*/account/',
'hoodie.logfile.max.size' = '1073741824',
'hoodie.datasource.write.hive_style_partitioning' = 'true',
'hoodie.parquet.compression.ratio' = '0.1',
'hoodie.parquet.small.file.limit' = '104857600',
'compaction.tasks' = '4',
'precombine.field' = 'update_ts',
'write.task.max.size' = '1024.0',
'hoodie.parquet.compression.codec' = 'snappy',
'compaction.delta_commits' = '3',
'clustering.tasks' = '4',
'compaction.trigger.strategy' = 'num_or_time',
'read.tasks' = '4',
'compaction.timeout.seconds' = '1200',
'clustering.async.enabled' = 'false',
'table.type' = 'COPY_ON_WRITE',
'metadata.compaction.delta_commits' = '10',
'clustering.plan.strategy.max.num.groups' = '30',
'write.tasks' = '6',
'clustering.schedule.enabled' = 'false',
'hoodie.logfile.data.block.format' = 'avro',
'write.batch.size' = '256.0',
'write.sort.memory' = '128'
```
### CoW DAG
Attached:

## MoR Testing
### MoR results (sample):
- For operators:
- map tasks (4 parallel slots): 120ms
- bucket assigner (4 parallel slots): 1s
- stream_write (6 parallel slots): 9m 29s
- compact_plan_generate (1 parallel slot): 78ms
- compact_task (4 parallel slot): 129ms
- compact_commit (6 parallel slots): 119ms
- File sizes: ~450KB
### MoR options being set on HoodiePipeline.Builder:
```
'connector' = 'hudi',
'index.type' = 'BLOOM',
'compaction.schedule.enabled' = 'true',
'clustering.plan.strategy.sort.columns' = 'acct_id',
'compaction.delta_seconds' = '720',
'clustering.delta_commits' = '4',
'clustering.plan.strategy.small.file.limit' = '600',
'compaction.async.enabled' = 'true',
'compaction.max_memory' = '100',
'hoodie.parquet.max.file.size' = '125829120',
'read.streaming.enabled' = 'false',
'path' = 's3://*****/*/account/',
'hoodie.logfile.max.size' = '1073741824',
'hoodie.datasource.write.hive_style_partitioning' = 'true',
'hoodie.parquet.compression.ratio' = '0.1',
'hoodie.parquet.small.file.limit' = '104857600',
'compaction.tasks' = '4',
'precombine.field' = 'update_ts',
'write.task.max.size' = '1024.0',
'hoodie.parquet.compression.codec' = 'snappy',
'compaction.delta_commits' = '3',
'clustering.tasks' = '4',
'compaction.trigger.strategy' = 'num_or_time',
'read.tasks' = '4',
'compaction.timeout.seconds' = '1200',
'clustering.async.enabled' = 'false',
'table.type' = 'MERGE_ON_READ',
'metadata.compaction.delta_commits' = '10',
'clustering.plan.strategy.max.num.groups' = '30',
'write.tasks' = '6',
'clustering.schedule.enabled' = 'false',
'hoodie.logfile.data.block.format' = 'avro',
'write.batch.size' = '256.0',
'write.sort.memory' = '128'
```
### MoR DAG
Attached:

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1447894602

   Thanks for the feedback, I see that you use the hashing index with MOR table type, does increasing the parallelism can improve the writing throughput here? How about we increase the `write.tasks` to 40


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1467274664

   Thx,I will read later.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1457469715

   We are using is 0.13.0 for version of Hudi .


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] hbgstc123 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "hbgstc123 (via GitHub)" <gi...@apache.org>.
hbgstc123 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1461159933

   `org.apache.hudi.exception.HoodieException: Timeout(601000ms) while waiting for instant initialize`.
   Is there a ckp timeout before this error.  Maybe caused by ckp timtout


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1455773617

   Yes, Tencent cos currently has the problem of reading file list frequency control. Our business is still streaming signal type data transmitted from vehicles, so there will be a problem of delayed data storage and delayed reporting, resulting in. Of course, we add data processing logic for delayed reporting. The delayed reported data of the day will be written to the corresponding partition, and the data of the non-day will be written to a separate delayed partition of the day. I don't know if this delayed reporting of data processing will increase the pressure on file processing, causing the cow writing process to take more time?

   In addition, the bucket index and bucket number I use are set to 40, and I only keep the latest version, so there should be a maximum of 80 files in one hour partition, and the total number of files in one day's partition is 1920. In this case, I shouldn't have too many small files created immediately.
   Regarding increasing the size of the parquet file, I will test it.

   Also ask a question, I see the default cos of Hudi source code (https://github.com/apache/hudi/blob/release-0.13.0/hudi-common/src/main/java/org/apache/hudi/common/ fs/StorageSchemes.java) does not support the append mode, but the cow format does support the append mode, so can it be simply understood that the implementation methods of Hudi mor and cow append are different?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] Vsevolod3 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "Vsevolod3 (via GitHub)" <gi...@apache.org>.
Vsevolod3 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1591014715

   Thanks for the link, Danny. I don't speak Chinese, so I'm not sure what most of it says. I will try to apply auto-translate to that page. In the meantime, do you have anything similar that's in English?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] Vsevolod3 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "Vsevolod3 (via GitHub)" <gi...@apache.org>.
Vsevolod3 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1591123193

   Thank you, Danny. Yes, I got the best performance by using BUCKET index with non-nested, numeric, non-hive partitions. We were actually able to get it to perform in under 3 minutes for the stream_write task when we picked a partitioning field that resulted in fewer partitions (14 partitions) compared to our previous tests (> 90 partitions).

   It seems the number of partitions Hudi has to manage has a _very_ large impact on performance. Would you be able to share any documents or blog posts that explain partitioning for performance further? I read through most of the documents under Concepts on the Hudi website (e.g. https://hudi.apache.org/docs/next/indexing), but didn't find a lot dealing in depth with partitioning strategies.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] voonhous commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "voonhous (via GitHub)" <gi...@apache.org>.
voonhous commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1451874410

   You are right that there are no Flink configs for it. What i did in the past was configure it using: `hoodie.parquet.compression.codec`.  You can verify if whether the configuration has taken effect by checking your logs.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1464862561

   YES, we have adjusted the writing mode of the table, whether it is MOR or COW  table, we have tried insert/upsert mode, but the overall performance cannot be improved.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1447939996

   We are currently looking for the root cause, and the current guess is hudi bucket write. Because we are currently using the flink filesystem method to directly write parquet files to cos storage, the writing efficiency is very high, and the source is the same as hudi. The source parallelism is the same as the sink parallelism, which is 24.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1464808238

From the DAG of this diagram, it seems you are using the MOR table type + bucket index, you also enable the async compaction, for append mode we means to use the COW table + Insert operation type. Did you set up your write operation trrough `write.operation` as `insert` ?
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1449283343

   Yes, my colleague wrote the code for the  filesystem of flink job .


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1591110868

   Sorry, let me illustrate the options here, basically there are about 2 options that you need to take care for bucket index:

   1. `index.type` set it as `BUCKET`;
   2. `hoodie.bucket.index.num.buckets`: the buckets number, by default 4,

   We also have a page for Flink in english on the hudi website: https://hudi.apache.org/docs/hoodie_deltastreamer#bucket-index


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] Vsevolod3 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "Vsevolod3 (via GitHub)" <gi...@apache.org>.
Vsevolod3 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1587601662

   @danny0405 : to update, I did try the bucket index, and the performance is still in the 9-10 minute range. Here are the timings for the tasks:

   - For operators:
     - map tasks (4 parallel slots): 51ms
     - bucket assigner (4 parallel slots): 1s
     - stream_write (6 parallel slots): 9m 36s

   Here are the Hudi properties submitted to the sink builder:

   ```
     'connector' = 'hudi',
     'compaction.schedule.enabled' = 'true',
     'hoodie.index.bucket.engine' = 'SIMPLE',
     'hoodie.index.type' = 'BUCKET',
     'clustering.plan.strategy.sort.columns' = 'acct_id',
     'write.bucket_assign.tasks' = '6',
     'compaction.delta_seconds' = '720',
     'clustering.delta_commits' = '4',
     'clustering.plan.strategy.small.file.limit' = '600',
     'compaction.async.enabled' = 'true',
     'compaction.max_memory' = '100',
     'hoodie.parquet.max.file.size' = '125829120',
     'read.streaming.enabled' = 'false',
     'path' = 's3://*****/*/account/',
     'hoodie.logfile.max.size' = '1073741824',
     'hoodie.datasource.write.hive_style_partitioning' = 'true',
     'hoodie.parquet.compression.ratio' = '0.1',
     'hoodie.parquet.small.file.limit' = '104857600',
     'hoodie.bucket.index.hash.field' = 'acct_id',
     'compaction.tasks' = '4',
     'precombine.field' = 'update_ts',
     'write.task.max.size' = '1024.0',
     'hoodie.parquet.compression.codec' = 'snappy',
     'compaction.delta_commits' = '3',
     'clustering.tasks' = '4',
     'compaction.trigger.strategy' = 'num_or_time',
     'hoodie.bucket.index.num.buckets' = '256',
     'read.tasks' = '4',
     'compaction.timeout.seconds' = '1200',
     'clustering.async.enabled' = 'false',
     'table.type' = 'COPY_ON_WRITE',
     'metadata.compaction.delta_commits' = '10',
     'clustering.plan.strategy.max.num.groups' = '30',
     'write.tasks' = '6',
     'clustering.schedule.enabled' = 'false',
     'hoodie.logfile.data.block.format' = 'avro',
     'write.batch.size' = '256.0',
     'write.sort.memory' = '128'
   ```

   Also, the metadata on the parquet files written by Hudi still has hoodie_bloom_filter_type_code=DYNAMIC_V0 and org.apache.hudi.bloomfilter in it, like it's still using BLOOM index. Is this expected?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1463521133

   Thanks ,we use `insert + COW + bucket Index`,so we the write throughput should be higt. In fact,we  flink job of running , throughput was bad,i do not understand why ?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
Re: [I] [SUPPORT]How to improve the speed of Flink writing to hudi ? [hudi]
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-2141028130

   1. bucket index is always reconmended if cross-partition update is not needed or the resource is crutial for users.
   2. mor is preferrable than cow for streaming ingestion.
   3. datetime partitioning for table is suggested(to relive the pressure of the driver memory usage)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1449211546

   > we are currently using the flink filesystem method to directly write parquet files

   Does that mean you have the filesystem source?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1449725080

   The fields SE/DE really takes time, especially for string type fields which has long strings.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1451544322

   No,We have tried the insert mode, combined with the mor and cow table formats, but the write throughput still cannot be improved.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] voonhous commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "voonhous (via GitHub)" <gi...@apache.org>.
voonhous commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1451638945

   @DavidZ1 If you are running it under append-only [INSERT mode + `COPY_ON_WRITE`], you can improve write throughput by changing the default compression codec from gzip to SNAPPY / LZ4.

   Snappy should be supported out of the box, but you will be trading off storage space for write throughput.

   I would recommend LZ4 if you have the appropriate bundles included in your environment.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
Re: [I] [SUPPORT]How to improve the speed of Flink writing to hudi ? [hudi]
Posted by "HuangZhenQiu (via GitHub)" <gi...@apache.org>.
HuangZhenQiu commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-2140979488

   @danny0405
   Do we have some best practices of (COW and MOR ) for Flink ingestion to Hudi?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
Re: [I] [SUPPORT]How to improve the speed of Flink writing to hudi ? [hudi]
Posted by "Sweet-huang-main (via GitHub)" <gi...@apache.org>.
Sweet-huang-main commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-2475840606

   @DavidZ1 Hi, have you solved the problem of stream_write operator? I have the same question as yours. The version and parameters  are as follow:
   (1)Version:
   Flink 1.17.1
   Hudi 0.15.0
   Kafka 2.0.1
   (2)parameters
   Flink parallelism: 30,
   Flink solts: 2,
   Flink taskmanager.process.size: 8192m。
   (3) problem
   there is 1000,000,000 records per day from Kafka. the performance of stream_write operator is down when Flink runs about 1.5 hours.
   I guess the Hudi is difficult to solve the problem of writing disk when there are large datas.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] DavidZ1 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "DavidZ1 (via GitHub)" <gi...@apache.org>.
DavidZ1 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1460123933
About five min to ck.

--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "danny0405 (via GitHub)" <gi...@apache.org>.
danny0405 commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1459589372

   What about your avg checkpoint end-to-end time?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] voonhous commented on issue #8071: [SUPPORT]How to improve the speed of Flink writing to hudi ?
Posted by "voonhous (via GitHub)" <gi...@apache.org>.
voonhous commented on issue #8071:
URL: https://github.com/apache/hudi/issues/8071#issuecomment-1454525599

   > Sorry for late reply, did you already use the append and it is still slow?

   Yeap, judging from the stack trace, he is running his job under append only mode.

   ```log
   org.apache.hudi.sink.append.AppendWriteFunction.initWriterHelper(AppendWriteFunction.java:110
   ```

   > Then we switched to the snappy format, and the writing performance did improve to a certain extent. However, due to the Tencent Cloud COS we used for storage, there was a list frequency control problem in cow writing, so the overall performance could not be greatly improved,and the exception is as follows:

   This  feels like a COS issue. @DavidZ1 you mentioned `there was a list frequency control problem in cow writing`. So, it's spending too much time listing files? IIUC, your job might be running too many parquet files while flushing? I am not very familiar with COS, so I am taking a shot in the dark here, looking at your configurations, the default `write.parquet.max.file.size` is used, which is 120MB by default.

   Perhaps, you could try increasing this so that lesser parquet files are written? Do note that your parquet sizes will get larger.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org