You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@mxnet.apache.org by GitBox <gi...@apache.org> on 2021/05/24 13:03:52 UTC
[GitHub] [incubator-mxnet] sfraczek opened a new pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
sfraczek opened a new pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302
## Description ##
This PR introduces a pass that transforms oneDNN operators pair quantize->FC so that oneDNN performs faster u8s8s32 inner_product instead of slower s8s8s32.
This is possible due to asymmetric quantization.
This pass is re-calculating the bias (b'=b-shift*w) and it tells the quantize operator to shift the input values to positive. In prototype we used shift value of 128 but now the shift is by min_calib_range to better utilize the quantized range.
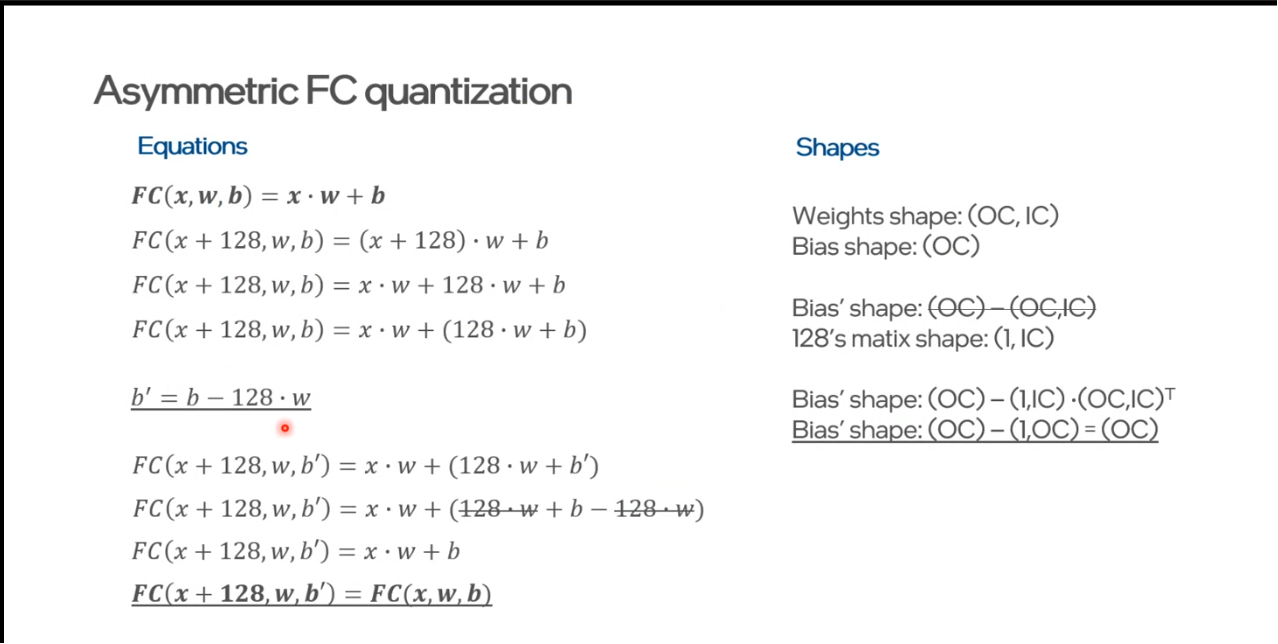
This feature is by default enabled and it can be disabled by environment flag `MXNET_DISABLE_SHIFTED_QUANTIZATION=1`.
I also fixed linter errors `include_what_you_use`.
## Checklist ##
### Essentials ###
- [x] PR's title starts with a category (e.g. [BUGFIX], [MODEL], [TUTORIAL], [FEATURE], [DOC], etc)
- [x] Changes are complete (i.e. I finished coding on this PR)
- [x] All changes have test coverage
- [ ] Code is well-documented
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r662345930
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
+ if (i == in_arg_names.size()) {
+ throw std::runtime_error(name + " not found in in_arg_names");
+ }
+ return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsFC(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+ if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+ auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+ if (param.default_param.no_bias == false &&
+ n->inputs[2].node->is_variable()) {
+ if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+ param.mkldnn_param.channel_wise_quantize.value())) {
+ return true;
+ }
+ }
+ }
+#endif
+ return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {
+ if (n->op() == Op::Get("_contrib_quantize_v2")) {
+ auto const ¶m = nnvm::get<QuantizeV2Param>(n->attrs.parsed);
+ if (param.min_calib_range.has_value() &&
+ param.min_calib_range.value() < 0.0f) {
+ return true;
+ }
+ }
+ return false;
+}
+
+// Rescales weights, min_weight and max_weight. Returns bias_int32_rescale.
+static inline float RescaleWeights(const Graph &g, const ObjectPtr &fc, NDArray* weight_tensor) {
+ ObjectPtr &quantize = fc->inputs[0].node;
+ auto min_data = std::stof(quantize->attrs.dict.at("min_calib_range"));
+ auto max_data = std::stof(quantize->attrs.dict.at("max_calib_range"));
+
+ float *min_weight = FindInArgByName(g, fc->inputs[5].node->attrs.name)->data().dptr<float>();
+ float *max_weight = FindInArgByName(g, fc->inputs[6].node->attrs.name)->data().dptr<float>();
+ float min_bias = *FindInArgByName(g, fc->inputs[7].node->attrs.name)->data().dptr<float>();
+ float max_bias = *FindInArgByName(g, fc->inputs[8].node->attrs.name)->data().dptr<float>();
+
+ float data_scale_ = kUint8Range / (max_data - min_data);
+ float weight_scale = GetQuantizeScale(kInt8, *min_weight, *max_weight);
+ float bias_scale = GetQuantizeScale(kInt8, min_bias, max_bias);
+ float bias_int32_rescale = data_scale_ * weight_scale / bias_scale;
+
+ // // TODO(zhennan): mkldnn has bug to handle INT_MAX in bias, so set the
+ // // maximum value of bias to INT_MAX / 2.
+ float bias_max_rescale = mshadow::red::limits::MaxValue<int32_t>() / 2 /
+ MaxAbs(min_bias, max_bias) / bias_scale;
+ if (bias_int32_rescale > bias_max_rescale) {
+ LOG(INFO) << "RESCALING WEIGHTS!";
+ // avoid overflow on bias
+ bias_int32_rescale = bias_max_rescale;
+ float weight_rescale =
+ bias_int32_rescale * bias_scale / data_scale_ / weight_scale;
+
+ size_t weight_size = weight_tensor->shape().Size();
+ int8_t *weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (int32_t i = 0; i < static_cast<int32_t>(weight_size); ++i) {
+ weight_ptr[i] = std::round(weight_ptr[i] * weight_rescale);
+ }
+ *min_weight *= weight_rescale;
+ *max_weight *= weight_rescale;
+ }
+ return bias_int32_rescale;
+}
+
+static inline void ShiftBias(int32_t* bias_ptr_int32, size_t bias_size,
+ NDArray* weight_tensor, int32_t shift_value) {
+ CHECK_EQ(static_cast<size_t>(weight_tensor->shape()[0]), bias_size);
+ int8_t* weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (dim_t i = 0; i < weight_tensor->shape()[0]; ++i) {
+ for (dim_t j = 0; j < weight_tensor->shape()[1]; j++) {
+ bias_ptr_int32[i] -= shift_value * (*weight_ptr++);
Review comment:
calc_index would have to be like `i*weight_tensor->shape()[1]+j`? I personally preferred incrementation although I don't know if compiler doesn't make it the same code after all
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   Current Samples per second: 69.706
   Previous Samples per second: 69.5381
   Current with disabled shifted quantization: Samples per second: 69.6905

   Bert large accuracy
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-859624074


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
szha commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r663079191


##########
File path: src/operator/quantization/quantization_utils.h
##########
@@ -187,22 +187,22 @@ inline size_t ConfigReduce(mshadow::Stream<xpu>* s,
   return broadcast::ReduceWorkspaceSize<NDim, DType>(s, *dst_shape, kWriteTo, *src_shape);
 }

-enum QuantizeOutType { kAuto = 0, kInt8, kUint8 };
+enum QuantizeOutType { qAuto = 0, qInt8, qUint8 };

Review comment:
       just curious about the naming, why the q prefix?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] bgawrych commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
bgawrych commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r656057796


##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,154 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
   return g;
 }

+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+  const std::vector<std::string>& in_arg_names =
+      g.GetAttr<std::vector<std::string>>("in_arg_names");
+  size_t i = std::distance(in_arg_names.begin(),
+                           std::find(in_arg_names.begin(), in_arg_names.end(), name));
+  if (i == in_arg_names.size()) {
+    throw std::runtime_error(name + " not found in in_arg_names");

Review comment:
       Probably we should use here LOG(FATAL)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-867612048


   Jenkins CI successfully triggered : [windows-cpu, unix-cpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r663011440


##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,155 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
   return g;
 }

+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+  const std::vector<std::string>& in_arg_names =
+      g.GetAttr<std::vector<std::string>>("in_arg_names");
+  size_t i = std::distance(in_arg_names.begin(),
+                           std::find(in_arg_names.begin(), in_arg_names.end(), name));
+  if (i == in_arg_names.size()) {
+    LOG(FATAL) << name << " not found in in_arg_names";
+  }
+  return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsOneDNNFullyConnected(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+  if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+    auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+    if (param.default_param.no_bias == false &&
+        n->inputs[2].node->is_variable()) {
+      if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+            param.mkldnn_param.channel_wise_quantize.value())) {
+        return true;
+      }
+    }
+  }
+#endif
+  return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {

Review comment:
       We could name it IsQuantizeSigned rather than Negative maybe because the point is we want to change signed to unsigned. Next PR will be refactoring it anyway so I wouldn't change details like names at this point.

##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,155 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
   return g;
 }

+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+  const std::vector<std::string>& in_arg_names =
+      g.GetAttr<std::vector<std::string>>("in_arg_names");
+  size_t i = std::distance(in_arg_names.begin(),
+                           std::find(in_arg_names.begin(), in_arg_names.end(), name));
+  if (i == in_arg_names.size()) {
+    LOG(FATAL) << name << " not found in in_arg_names";
+  }
+  return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsOneDNNFullyConnected(const ObjectPtr& n) {

Review comment:
       There is a `!` in the if so it's not ChWise. I think if we are to change the name we should do it in next PR which will have much refactoring of this.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   Current Samples per second: 69.706
   Previous Samples per second: 69.5381
   Current with disabled shifted quantization: Samples per second: 69.6905

   Bert large accuracy
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}
   ```
   accuracy is computed by naive method.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r663082456


##########
File path: src/operator/quantization/quantization_utils.h
##########
@@ -187,22 +187,22 @@ inline size_t ConfigReduce(mshadow::Stream<xpu>* s,
   return broadcast::ReduceWorkspaceSize<NDim, DType>(s, *dst_shape, kWriteTo, *src_shape);
 }

-enum QuantizeOutType { kAuto = 0, kInt8, kUint8 };
+enum QuantizeOutType { qAuto = 0, qInt8, qUint8 };

Review comment:
       Because there is already name mshadow::kInt8 and mshadow::kUint8 which I was intending to use but when I wrote just kUint8 without prefix `mshadow::` in front of it this enum got used instead and it was hard to detect error.Adding q makes a clear distinction at low cost. I think it's for the better since this enum is scarcely used anyway.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-867611955


   @mxnet-bot run ci [unix-cpu, windows-cpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-869695127


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   Current Samples per second: 69.706
   Previous Samples per second: 69.5381
   Current with disabled shifted quantization: Samples per second: 69.6905

   Bert large accuracy
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}
   ```
   computed for naive quantization method calibration with batch size 10, iterations 10.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-870438066


   Jenkins CI successfully triggered : [windows-cpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847027891


   Hey @sfraczek , Thanks for submitting the PR
   All tests are already queued to run once. If tests fail, you can trigger one or more tests again with the following commands:
   - To trigger all jobs: @mxnet-bot run ci [all]
   - To trigger specific jobs: @mxnet-bot run ci [job1, job2]
   ***
   **CI supported jobs**: [clang, website, miscellaneous, unix-gpu, edge, centos-gpu, windows-gpu, unix-cpu, windows-cpu, sanity, centos-cpu]
   ***
   _Note_:
    Only following 3 categories can trigger CI :PR Author, MXNet Committer, Jenkins Admin.
   All CI tests must pass before the PR can be merged.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-869695127


   @mxnet-bot run ci [centos-gpu, unix-cpu, windows-cpu, windows-gpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-871167908


   Jenkins CI successfully triggered : [windows-cpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   Current Samples per second: 69.706
   Previous Samples per second: 69.5381
   Current with disabled shifted quantization: Samples per second: 69.6905

   Bert large accuracy
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}
   ```
   computed for naive quantization method calibration with batch size 10 and iterations 10.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-869695184


   Jenkins CI successfully triggered : [centos-gpu, unix-cpu, windows-cpu, windows-gpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-873060986


   @szha can we merge it and open next PR based on this? @akarbown is on vacation so she can't do it..


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] anko-intel commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
anko-intel commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r662925520


##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,155 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
   return g;
 }

+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+  const std::vector<std::string>& in_arg_names =
+      g.GetAttr<std::vector<std::string>>("in_arg_names");
+  size_t i = std::distance(in_arg_names.begin(),
+                           std::find(in_arg_names.begin(), in_arg_names.end(), name));
+  if (i == in_arg_names.size()) {
+    LOG(FATAL) << name << " not found in in_arg_names";
+  }
+  return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsOneDNNFullyConnected(const ObjectPtr& n) {

Review comment:
       ```suggestion
   static inline bool IsOneDNNFullyConnectedchWise(const ObjectPtr& n) {
   ```

##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,155 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
   return g;
 }

+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+  const std::vector<std::string>& in_arg_names =
+      g.GetAttr<std::vector<std::string>>("in_arg_names");
+  size_t i = std::distance(in_arg_names.begin(),
+                           std::find(in_arg_names.begin(), in_arg_names.end(), name));
+  if (i == in_arg_names.size()) {
+    LOG(FATAL) << name << " not found in in_arg_names";
+  }
+  return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsOneDNNFullyConnected(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+  if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+    auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+    if (param.default_param.no_bias == false &&
+        n->inputs[2].node->is_variable()) {
+      if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+            param.mkldnn_param.channel_wise_quantize.value())) {
+        return true;
+      }
+    }
+  }
+#endif
+  return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {

Review comment:
       ```suggestion
   static inline bool IsQuantizeNegative(const ObjectPtr& n) {
   ```
   ?


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r657854888


##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,154 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
   return g;
 }

+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+  const std::vector<std::string>& in_arg_names =
+      g.GetAttr<std::vector<std::string>>("in_arg_names");
+  size_t i = std::distance(in_arg_names.begin(),
+                           std::find(in_arg_names.begin(), in_arg_names.end(), name));
+  if (i == in_arg_names.size()) {
+    throw std::runtime_error(name + " not found in in_arg_names");

Review comment:
       ok

##########
File path: python/mxnet/contrib/quantization.py
##########
@@ -1001,6 +1001,11 @@ def __exit__(self, exc_type, exc_value, traceback):
         nd_save(param_name, save_dict)
         net.collect_params().load(param_name, cast_dtype=True, dtype_source='saved')
         net.collect_params().reset_ctx(ctx)
+        if quantized_dtype == 'auto':
+            net.optimize_for(x=data_nd, backend="OneDNNShiftedQuantization")
+            tmp_file = os.path.join(tmpdirname, 'model')
+            net.export(tmp_file)
+            net = SymbolBlock.imports(tmp_file+'-symbol.json', data_names, tmp_file+'-0000.params')

Review comment:
       ok


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   enabled: Samples per second: 69.706
   disabled: Samples per second: 69.6905
   different machine:
   enabled: Samples per second: 42.9889
   disabled: Samples per second: 43.2449

   Bert large accuracy naive quantization method, calibration with batch size 10 and iterations 10.
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}

   Bert large accuracy naive quantization method, calibration with batch size 1 and iterations 1.
   with enabled: {"exact_match": 82.16650898770104, "f1": 89.80610967369435}
   with disabled: {"exact_match": 81.9205298013245, "f1": 89.65670255040264}
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-869695184


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r662345930
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
+ if (i == in_arg_names.size()) {
+ throw std::runtime_error(name + " not found in in_arg_names");
+ }
+ return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsFC(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+ if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+ auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+ if (param.default_param.no_bias == false &&
+ n->inputs[2].node->is_variable()) {
+ if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+ param.mkldnn_param.channel_wise_quantize.value())) {
+ return true;
+ }
+ }
+ }
+#endif
+ return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {
+ if (n->op() == Op::Get("_contrib_quantize_v2")) {
+ auto const ¶m = nnvm::get<QuantizeV2Param>(n->attrs.parsed);
+ if (param.min_calib_range.has_value() &&
+ param.min_calib_range.value() < 0.0f) {
+ return true;
+ }
+ }
+ return false;
+}
+
+// Rescales weights, min_weight and max_weight. Returns bias_int32_rescale.
+static inline float RescaleWeights(const Graph &g, const ObjectPtr &fc, NDArray* weight_tensor) {
+ ObjectPtr &quantize = fc->inputs[0].node;
+ auto min_data = std::stof(quantize->attrs.dict.at("min_calib_range"));
+ auto max_data = std::stof(quantize->attrs.dict.at("max_calib_range"));
+
+ float *min_weight = FindInArgByName(g, fc->inputs[5].node->attrs.name)->data().dptr<float>();
+ float *max_weight = FindInArgByName(g, fc->inputs[6].node->attrs.name)->data().dptr<float>();
+ float min_bias = *FindInArgByName(g, fc->inputs[7].node->attrs.name)->data().dptr<float>();
+ float max_bias = *FindInArgByName(g, fc->inputs[8].node->attrs.name)->data().dptr<float>();
+
+ float data_scale_ = kUint8Range / (max_data - min_data);
+ float weight_scale = GetQuantizeScale(kInt8, *min_weight, *max_weight);
+ float bias_scale = GetQuantizeScale(kInt8, min_bias, max_bias);
+ float bias_int32_rescale = data_scale_ * weight_scale / bias_scale;
+
+ // // TODO(zhennan): mkldnn has bug to handle INT_MAX in bias, so set the
+ // // maximum value of bias to INT_MAX / 2.
+ float bias_max_rescale = mshadow::red::limits::MaxValue<int32_t>() / 2 /
+ MaxAbs(min_bias, max_bias) / bias_scale;
+ if (bias_int32_rescale > bias_max_rescale) {
+ LOG(INFO) << "RESCALING WEIGHTS!";
+ // avoid overflow on bias
+ bias_int32_rescale = bias_max_rescale;
+ float weight_rescale =
+ bias_int32_rescale * bias_scale / data_scale_ / weight_scale;
+
+ size_t weight_size = weight_tensor->shape().Size();
+ int8_t *weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (int32_t i = 0; i < static_cast<int32_t>(weight_size); ++i) {
+ weight_ptr[i] = std::round(weight_ptr[i] * weight_rescale);
+ }
+ *min_weight *= weight_rescale;
+ *max_weight *= weight_rescale;
+ }
+ return bias_int32_rescale;
+}
+
+static inline void ShiftBias(int32_t* bias_ptr_int32, size_t bias_size,
+ NDArray* weight_tensor, int32_t shift_value) {
+ CHECK_EQ(static_cast<size_t>(weight_tensor->shape()[0]), bias_size);
+ int8_t* weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (dim_t i = 0; i < weight_tensor->shape()[0]; ++i) {
+ for (dim_t j = 0; j < weight_tensor->shape()[1]; j++) {
+ bias_ptr_int32[i] -= shift_value * (*weight_ptr++);
Review comment:
calc_index would have to be like `i*weight_tensor->shape()[1]+j`? I personally preferred incrementation (it's neat and simple operation) although I don't know if compiler doesn't make it the same code after all
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   Current Samples per second: 69.706
   Previous Samples per second: 69.5381
   Current with disabled shifted quantization: Samples per second: 69.6905

   Bert large accuracy naive quantization method, calibration with batch size 10 and iterations 10.
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}

   Bert large accuracy naive quantization method, calibration with batch size 1 and iterations 1.
   with enabled: {"exact_match": 82.16650898770104, "f1": 89.80610967369435}
   with disabled: {"exact_match": 81.9205298013245, "f1": 89.65670255040264}
   ```


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] bgawrych commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
bgawrych commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r656060043


##########
File path: python/mxnet/contrib/quantization.py
##########
@@ -1001,6 +1001,11 @@ def __exit__(self, exc_type, exc_value, traceback):
         nd_save(param_name, save_dict)
         net.collect_params().load(param_name, cast_dtype=True, dtype_source='saved')
         net.collect_params().reset_ctx(ctx)
+        if quantized_dtype == 'auto':
+            net.optimize_for(x=data_nd, backend="OneDNNShiftedQuantization")
+            tmp_file = os.path.join(tmpdirname, 'model')
+            net.export(tmp_file)
+            net = SymbolBlock.imports(tmp_file+'-symbol.json', data_names, tmp_file+'-0000.params')

Review comment:
       Add spaces around 'plus' sign


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   Current Samples per second: 69.706
   Previous Samples per second: 69.5381
   Current with disabled shifted quantization: Samples per second: 69.6905

   Bert large accuracy
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}
   ```
   computed for naive quantization method.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-859624024


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] bgawrych commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
bgawrych commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r662760474
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
+ if (i == in_arg_names.size()) {
+ throw std::runtime_error(name + " not found in in_arg_names");
+ }
+ return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsFC(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+ if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+ auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+ if (param.default_param.no_bias == false &&
+ n->inputs[2].node->is_variable()) {
+ if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+ param.mkldnn_param.channel_wise_quantize.value())) {
+ return true;
+ }
+ }
+ }
+#endif
+ return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {
+ if (n->op() == Op::Get("_contrib_quantize_v2")) {
+ auto const ¶m = nnvm::get<QuantizeV2Param>(n->attrs.parsed);
+ if (param.min_calib_range.has_value() &&
+ param.min_calib_range.value() < 0.0f) {
+ return true;
+ }
+ }
+ return false;
+}
+
+// Rescales weights, min_weight and max_weight. Returns bias_int32_rescale.
+static inline float RescaleWeights(const Graph &g, const ObjectPtr &fc, NDArray* weight_tensor) {
+ ObjectPtr &quantize = fc->inputs[0].node;
+ auto min_data = std::stof(quantize->attrs.dict.at("min_calib_range"));
+ auto max_data = std::stof(quantize->attrs.dict.at("max_calib_range"));
+
+ float *min_weight = FindInArgByName(g, fc->inputs[5].node->attrs.name)->data().dptr<float>();
+ float *max_weight = FindInArgByName(g, fc->inputs[6].node->attrs.name)->data().dptr<float>();
+ float min_bias = *FindInArgByName(g, fc->inputs[7].node->attrs.name)->data().dptr<float>();
+ float max_bias = *FindInArgByName(g, fc->inputs[8].node->attrs.name)->data().dptr<float>();
+
+ float data_scale_ = kUint8Range / (max_data - min_data);
+ float weight_scale = GetQuantizeScale(kInt8, *min_weight, *max_weight);
+ float bias_scale = GetQuantizeScale(kInt8, min_bias, max_bias);
+ float bias_int32_rescale = data_scale_ * weight_scale / bias_scale;
+
+ // // TODO(zhennan): mkldnn has bug to handle INT_MAX in bias, so set the
+ // // maximum value of bias to INT_MAX / 2.
+ float bias_max_rescale = mshadow::red::limits::MaxValue<int32_t>() / 2 /
+ MaxAbs(min_bias, max_bias) / bias_scale;
+ if (bias_int32_rescale > bias_max_rescale) {
+ LOG(INFO) << "RESCALING WEIGHTS!";
+ // avoid overflow on bias
+ bias_int32_rescale = bias_max_rescale;
+ float weight_rescale =
+ bias_int32_rescale * bias_scale / data_scale_ / weight_scale;
+
+ size_t weight_size = weight_tensor->shape().Size();
+ int8_t *weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (int32_t i = 0; i < static_cast<int32_t>(weight_size); ++i) {
+ weight_ptr[i] = std::round(weight_ptr[i] * weight_rescale);
+ }
+ *min_weight *= weight_rescale;
+ *max_weight *= weight_rescale;
+ }
+ return bias_int32_rescale;
+}
+
+static inline void ShiftBias(int32_t* bias_ptr_int32, size_t bias_size,
+ NDArray* weight_tensor, int32_t shift_value) {
+ CHECK_EQ(static_cast<size_t>(weight_tensor->shape()[0]), bias_size);
+ int8_t* weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (dim_t i = 0; i < weight_tensor->shape()[0]; ++i) {
+ for (dim_t j = 0; j < weight_tensor->shape()[1]; j++) {
+ bias_ptr_int32[i] -= shift_value * (*weight_ptr++);
Review comment:
Yes it would be `i*weight_tensor->shape()[1]+j` - When i'm reading this code at first sight I don't know whether it's incrementation of pointer or value - if no one don't have any comments about it besides me feel free to ignore
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-873060986


   @szha can we merge it and open next PR based on this? @akarbown is on vacation.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-871167879


   @mxnet-bot run ci [windows-cpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek edited a comment on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek edited a comment on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-847115025


   Current data:
   ```
   Bert large samples per second:
   Current Samples per second: 69.706
   Previous Samples per second: 69.5381
   Current with disabled shifted quantization: Samples per second: 69.6905

   Bert large accuracy
   with enabled: {"exact_match": 81.73131504257331, "f1": 89.42690117757154}
   with disabled: {"exact_match": 81.84484389782403, "f1": 89.49955637348324}
   ```
   accuracy is computed for naive quantization method.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] bgawrych commented on a change in pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
bgawrych commented on a change in pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#discussion_r642905250
##########
File path: src/operator/quantization/mkldnn/mkldnn_quantize_v2-inl.h
##########
@@ -109,13 +111,19 @@ void SgMKLDNNQuantizeOperator::Forward(const OpContext &ctx, const std::vector<N
// Write output min/max
auto out_type = GetQuantizeOutputType(param_);
- if (out_type == mshadow::kUint8) {
- quantized_range = kUint8Range;
+ const bool shifted = param_.shifted.has_value() && param_.shifted.value();
+ if (shifted) {
+ // if shifted == true we have guarantee that data_max is negative because
Review comment:
Should be "data_min is negative"
##########
File path: src/operator/quantization/mkldnn/mkldnn_quantize_v2-inl.h
##########
@@ -125,12 +133,22 @@ void SgMKLDNNQuantizeOperator::Forward(const OpContext &ctx, const std::vector<N
if (!initalized_) {
cached_data_min_ = data_min;
cached_data_max_ = data_max;
- float real_range = MaxAbs(data_min, data_max);
- float scale = quantized_range / real_range;
+ if (shifted) {
+ CHECK_LT(data_min, 0); // assert that we are working on signed
+ cached_scale_ = kUint8Range / (data_max - data_min);
+ cached_shift_ = static_cast<uint8_t>(std::round(-cached_scale_ * cached_data_min_));
+ } else {
+ cached_scale_ = GetQuantizeScale(out_type, data_min, data_max);
+ }
mkldnn::primitive_attr attr;
const int mask = 0;
- std::vector<float> scales = {scale};
+ std::vector<float> scales = {cached_scale_};
attr.set_output_scales(mask, scales);
+ if (shifted) {
+ dnnl::post_ops po;
Review comment:
Add comment:
// TODO(sfraczek): change to zero point if optimized in oneDNN
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
Review comment:
```suggestion
size_t i = std::distance(in_arg_names.begin(),
std::find(in_arg_names.begin(), in_arg_names.end(), name));
```
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
+ if (i == in_arg_names.size()) {
+ throw std::runtime_error(name + " not found in in_arg_names");
+ }
+ return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsFC(const ObjectPtr& n) {
Review comment:
Maybe IsOneDNNFullyConnected? Cause you have also macro checking if it's oneDNN
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
+ if (i == in_arg_names.size()) {
+ throw std::runtime_error(name + " not found in in_arg_names");
+ }
+ return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsFC(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+ if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+ auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+ if (param.default_param.no_bias == false &&
+ n->inputs[2].node->is_variable()) {
+ if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+ param.mkldnn_param.channel_wise_quantize.value())) {
+ return true;
+ }
+ }
+ }
+#endif
+ return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {
+ if (n->op() == Op::Get("_contrib_quantize_v2")) {
+ auto const ¶m = nnvm::get<QuantizeV2Param>(n->attrs.parsed);
+ if (param.min_calib_range.has_value() &&
+ param.min_calib_range.value() < 0.0f) {
+ return true;
+ }
+ }
+ return false;
+}
+
+// Rescales weights, min_weight and max_weight. Returns bias_int32_rescale.
+static inline float RescaleWeights(const Graph &g, const ObjectPtr &fc, NDArray* weight_tensor) {
+ ObjectPtr &quantize = fc->inputs[0].node;
+ auto min_data = std::stof(quantize->attrs.dict.at("min_calib_range"));
+ auto max_data = std::stof(quantize->attrs.dict.at("max_calib_range"));
+
+ float *min_weight = FindInArgByName(g, fc->inputs[5].node->attrs.name)->data().dptr<float>();
+ float *max_weight = FindInArgByName(g, fc->inputs[6].node->attrs.name)->data().dptr<float>();
+ float min_bias = *FindInArgByName(g, fc->inputs[7].node->attrs.name)->data().dptr<float>();
+ float max_bias = *FindInArgByName(g, fc->inputs[8].node->attrs.name)->data().dptr<float>();
+
+ float data_scale_ = kUint8Range / (max_data - min_data);
+ float weight_scale = GetQuantizeScale(kInt8, *min_weight, *max_weight);
+ float bias_scale = GetQuantizeScale(kInt8, min_bias, max_bias);
+ float bias_int32_rescale = data_scale_ * weight_scale / bias_scale;
+
+ // // TODO(zhennan): mkldnn has bug to handle INT_MAX in bias, so set the
+ // // maximum value of bias to INT_MAX / 2.
+ float bias_max_rescale = mshadow::red::limits::MaxValue<int32_t>() / 2 /
+ MaxAbs(min_bias, max_bias) / bias_scale;
+ if (bias_int32_rescale > bias_max_rescale) {
+ LOG(INFO) << "RESCALING WEIGHTS!";
+ // avoid overflow on bias
+ bias_int32_rescale = bias_max_rescale;
+ float weight_rescale =
+ bias_int32_rescale * bias_scale / data_scale_ / weight_scale;
+
+ size_t weight_size = weight_tensor->shape().Size();
+ int8_t *weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (int32_t i = 0; i < static_cast<int32_t>(weight_size); ++i) {
+ weight_ptr[i] = std::round(weight_ptr[i] * weight_rescale);
+ }
+ *min_weight *= weight_rescale;
+ *max_weight *= weight_rescale;
+ }
+ return bias_int32_rescale;
+}
+
+static inline void ShiftBias(int32_t* bias_ptr_int32, size_t bias_size,
+ NDArray* weight_tensor, int32_t shift_value) {
+ CHECK_EQ(static_cast<size_t>(weight_tensor->shape()[0]), bias_size);
+ int8_t* weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (dim_t i = 0; i < weight_tensor->shape()[0]; ++i) {
+ for (dim_t j = 0; j < weight_tensor->shape()[1]; j++) {
+ bias_ptr_int32[i] -= shift_value * (*weight_ptr++);
+ }
+ }
+}
+
+Graph OneDNNShiftedQuantization(Graph &&g) {
+ bool disable_shifted_quant = dmlc::GetEnv("MXNET_DISABLE_SHIFTED_QUANTIZATION", true);
+ LOG(INFO) << "Running OneDNN shifted quantization: " << !disable_shifted_quant;
+ // No change to aux params
+ g.attrs["new_aux_names"] = std::make_shared<nnvm::any>(std::vector<std::string>());
+ g.attrs["new_aux"] = std::make_shared<nnvm::any>(std::vector<NDArray *>());
+
+ // New args to replace the old
+ std::vector<std::string> new_arg_names;
+ std::vector<NDArray *> new_arg_vector;
+
+#if MXNET_USE_MKLDNN == 1
+ if (!disable_shifted_quant) {
+ DFSVisit(g.outputs, [&](const ObjectPtr &fc) {
+ // Find Quantize->FC pattern and rescale bias from int8 to int32 and shift
+ if (IsFC(fc)) {
+ ObjectPtr &quantize = fc->inputs[0].node;
+ if (IsQuantize(quantize)) {
+ ObjectPtr& bias_node = fc->inputs[2].node;
+ std::string bias_name_old = bias_node->attrs.name;
+ NDArray* bias_in_arg_ptr = FindInArgByName(g, bias_name_old);
+ if (bias_in_arg_ptr->dtype() != mshadow::kInt8) return;
+ std::string bias_name_s32 = bias_node->attrs.name + "_s32";
+ bias_node = CreateNode("nullptr", bias_name_s32);
+ new_arg_names.push_back(bias_name_s32);
+
+ quantize->attrs.dict["shifted"] = "True";
+ if (quantize->op()->attr_parser) quantize->op()->attr_parser(&(quantize->attrs));
+
+ NDArray *weight_tensor = FindInArgByName(g, fc->inputs[1].node->attrs.name);
+
+ float bias_int32_rescale = RescaleWeights(g, fc, weight_tensor);
+
+ new_arg_vector.push_back(
+ new NDArray(kDefaultStorage, bias_in_arg_ptr->shape(),
+ Context::CPU(), false, mshadow::kInt32));
+ int32_t *bias_ptr_int32 = new_arg_vector.back()->data().dptr<int32_t>();
+ size_t bias_size = bias_in_arg_ptr->shape().Size();
+ int8_t *bias_ptr_old = bias_in_arg_ptr->data().dptr<int8_t>();
+
+ for (size_t i = 0; i < bias_size; ++i) {
+ bias_ptr_int32[i] = static_cast<int32_t>(
+ std::round(bias_ptr_old[i] * bias_int32_rescale));
+ }
+ float min_data = std::stof(quantize->attrs.dict.at("min_calib_range"));
+ float max_data = std::stof(quantize->attrs.dict.at("max_calib_range"));
+ float data_scale = kUint8Range / (max_data - min_data);
+ uint32_t shift_value = static_cast<uint32_t>(-std::round(data_scale * min_data));
Review comment:
unify minus sign to be exactly the same as in quantize_v2 operator
##########
File path: tests/python/quantization/test_quantization.py
##########
@@ -1254,6 +1254,89 @@ def get_threshold(nd):
assert_almost_equal(np.array([th_dict['layer1'][1]]), expected_threshold, rtol=1e-2, atol=1e-4)
+@with_seed()
+def test_onednn_shifted_quantization():
+ if not is_test_for_mkldnn():
+ print("Test only for mkldnn")
+ return
+
+ def collect_param(fc_layer, p):
+ param = fc_layer.collect_params(p)[p]._reduce()
+ return param
+
+ def quantize_to_int8(param):
+ p_int8, p_min, p_max = mx.ndarray.contrib.quantize(data=param,
+ min_range=mx.ndarray.min(param),
Review comment:
justify
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
+ if (i == in_arg_names.size()) {
+ throw std::runtime_error(name + " not found in in_arg_names");
+ }
+ return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsFC(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+ if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+ auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+ if (param.default_param.no_bias == false &&
+ n->inputs[2].node->is_variable()) {
+ if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+ param.mkldnn_param.channel_wise_quantize.value())) {
+ return true;
+ }
+ }
+ }
+#endif
+ return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {
+ if (n->op() == Op::Get("_contrib_quantize_v2")) {
+ auto const ¶m = nnvm::get<QuantizeV2Param>(n->attrs.parsed);
+ if (param.min_calib_range.has_value() &&
+ param.min_calib_range.value() < 0.0f) {
+ return true;
+ }
+ }
+ return false;
+}
+
+// Rescales weights, min_weight and max_weight. Returns bias_int32_rescale.
+static inline float RescaleWeights(const Graph &g, const ObjectPtr &fc, NDArray* weight_tensor) {
+ ObjectPtr &quantize = fc->inputs[0].node;
+ auto min_data = std::stof(quantize->attrs.dict.at("min_calib_range"));
+ auto max_data = std::stof(quantize->attrs.dict.at("max_calib_range"));
+
+ float *min_weight = FindInArgByName(g, fc->inputs[5].node->attrs.name)->data().dptr<float>();
+ float *max_weight = FindInArgByName(g, fc->inputs[6].node->attrs.name)->data().dptr<float>();
+ float min_bias = *FindInArgByName(g, fc->inputs[7].node->attrs.name)->data().dptr<float>();
+ float max_bias = *FindInArgByName(g, fc->inputs[8].node->attrs.name)->data().dptr<float>();
+
+ float data_scale_ = kUint8Range / (max_data - min_data);
+ float weight_scale = GetQuantizeScale(kInt8, *min_weight, *max_weight);
+ float bias_scale = GetQuantizeScale(kInt8, min_bias, max_bias);
+ float bias_int32_rescale = data_scale_ * weight_scale / bias_scale;
+
+ // // TODO(zhennan): mkldnn has bug to handle INT_MAX in bias, so set the
+ // // maximum value of bias to INT_MAX / 2.
+ float bias_max_rescale = mshadow::red::limits::MaxValue<int32_t>() / 2 /
+ MaxAbs(min_bias, max_bias) / bias_scale;
+ if (bias_int32_rescale > bias_max_rescale) {
+ LOG(INFO) << "RESCALING WEIGHTS!";
Review comment:
Maybe this log should be more informative? e.g. with layer name (fc->attrs.name) etc.
##########
File path: tests/python/quantization/test_quantization.py
##########
@@ -1254,6 +1254,89 @@ def get_threshold(nd):
assert_almost_equal(np.array([th_dict['layer1'][1]]), expected_threshold, rtol=1e-2, atol=1e-4)
+@with_seed()
+def test_onednn_shifted_quantization():
+ if not is_test_for_mkldnn():
+ print("Test only for mkldnn")
+ return
+
+ def collect_param(fc_layer, p):
+ param = fc_layer.collect_params(p)[p]._reduce()
+ return param
+
+ def quantize_to_int8(param):
+ p_int8, p_min, p_max = mx.ndarray.contrib.quantize(data=param,
+ min_range=mx.ndarray.min(param),
+ max_range=mx.ndarray.max(param),
+ out_type='int8')
+ p_scale = 127.5/np.max(np.abs([p_max.asnumpy(), p_min.asnumpy()]))
+ return p_int8.asnumpy(), p_scale
+
+ def get_shifted_bias(quantize_attrs, weights_int8, weights_scale, bias_int8, bias_scale):
+ max_data = float(quantize_attrs['max_calib_range'])
+ min_data = float(quantize_attrs['min_calib_range'])
+ data_scale = 255.5 / (max_data - min_data)
+ shift_value = np.array(np.round(-data_scale*min_data),np.uint8)
Review comment:
add space after comma
##########
File path: tests/python/quantization/test_quantization.py
##########
@@ -1254,6 +1254,89 @@ def get_threshold(nd):
assert_almost_equal(np.array([th_dict['layer1'][1]]), expected_threshold, rtol=1e-2, atol=1e-4)
+@with_seed()
+def test_onednn_shifted_quantization():
+ if not is_test_for_mkldnn():
+ print("Test only for mkldnn")
+ return
+
+ def collect_param(fc_layer, p):
+ param = fc_layer.collect_params(p)[p]._reduce()
+ return param
+
+ def quantize_to_int8(param):
Review comment:
maybe change name to quantize_params_to_int8
##########
File path: src/operator/quantization/quantize_graph_pass.cc
##########
@@ -578,6 +579,153 @@ Graph SetCalibTableToQuantizedGraph(Graph&& g) {
return g;
}
+static NDArray* FindInArgByName(const Graph &g, const std::string& name) {
+ const std::vector<std::string>& in_arg_names =
+ g.GetAttr<std::vector<std::string>>("in_arg_names");
+ size_t i =
+ std::distance(in_arg_names.begin(),
+ std::find(in_arg_names.begin(), in_arg_names.end(), name));
+ if (i == in_arg_names.size()) {
+ throw std::runtime_error(name + " not found in in_arg_names");
+ }
+ return g.GetAttr<NDArray **>("in_args")[i];
+}
+
+static inline bool IsFC(const ObjectPtr& n) {
+#if MXNET_USE_MKLDNN == 1
+ if (n->op() == Op::Get("_sg_mkldnn_fully_connected")) {
+ auto const& param = nnvm::get<MKLDNNFCFullParam>(n->attrs.parsed);
+ if (param.default_param.no_bias == false &&
+ n->inputs[2].node->is_variable()) {
+ if (!(param.mkldnn_param.channel_wise_quantize.has_value() &&
+ param.mkldnn_param.channel_wise_quantize.value())) {
+ return true;
+ }
+ }
+ }
+#endif
+ return false;
+}
+
+static inline bool IsQuantize(const ObjectPtr& n) {
+ if (n->op() == Op::Get("_contrib_quantize_v2")) {
+ auto const ¶m = nnvm::get<QuantizeV2Param>(n->attrs.parsed);
+ if (param.min_calib_range.has_value() &&
+ param.min_calib_range.value() < 0.0f) {
+ return true;
+ }
+ }
+ return false;
+}
+
+// Rescales weights, min_weight and max_weight. Returns bias_int32_rescale.
+static inline float RescaleWeights(const Graph &g, const ObjectPtr &fc, NDArray* weight_tensor) {
+ ObjectPtr &quantize = fc->inputs[0].node;
+ auto min_data = std::stof(quantize->attrs.dict.at("min_calib_range"));
+ auto max_data = std::stof(quantize->attrs.dict.at("max_calib_range"));
+
+ float *min_weight = FindInArgByName(g, fc->inputs[5].node->attrs.name)->data().dptr<float>();
+ float *max_weight = FindInArgByName(g, fc->inputs[6].node->attrs.name)->data().dptr<float>();
+ float min_bias = *FindInArgByName(g, fc->inputs[7].node->attrs.name)->data().dptr<float>();
+ float max_bias = *FindInArgByName(g, fc->inputs[8].node->attrs.name)->data().dptr<float>();
+
+ float data_scale_ = kUint8Range / (max_data - min_data);
+ float weight_scale = GetQuantizeScale(kInt8, *min_weight, *max_weight);
+ float bias_scale = GetQuantizeScale(kInt8, min_bias, max_bias);
+ float bias_int32_rescale = data_scale_ * weight_scale / bias_scale;
+
+ // // TODO(zhennan): mkldnn has bug to handle INT_MAX in bias, so set the
+ // // maximum value of bias to INT_MAX / 2.
+ float bias_max_rescale = mshadow::red::limits::MaxValue<int32_t>() / 2 /
+ MaxAbs(min_bias, max_bias) / bias_scale;
+ if (bias_int32_rescale > bias_max_rescale) {
+ LOG(INFO) << "RESCALING WEIGHTS!";
+ // avoid overflow on bias
+ bias_int32_rescale = bias_max_rescale;
+ float weight_rescale =
+ bias_int32_rescale * bias_scale / data_scale_ / weight_scale;
+
+ size_t weight_size = weight_tensor->shape().Size();
+ int8_t *weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (int32_t i = 0; i < static_cast<int32_t>(weight_size); ++i) {
+ weight_ptr[i] = std::round(weight_ptr[i] * weight_rescale);
+ }
+ *min_weight *= weight_rescale;
+ *max_weight *= weight_rescale;
+ }
+ return bias_int32_rescale;
+}
+
+static inline void ShiftBias(int32_t* bias_ptr_int32, size_t bias_size,
+ NDArray* weight_tensor, int32_t shift_value) {
+ CHECK_EQ(static_cast<size_t>(weight_tensor->shape()[0]), bias_size);
+ int8_t* weight_ptr = weight_tensor->data().dptr<int8_t>();
+ for (dim_t i = 0; i < weight_tensor->shape()[0]; ++i) {
+ for (dim_t j = 0; j < weight_tensor->shape()[1]; j++) {
+ bias_ptr_int32[i] -= shift_value * (*weight_ptr++);
Review comment:
maybe weight_ptr[calc_index]?
##########
File path: tests/python/quantization/test_quantization.py
##########
@@ -1254,6 +1254,89 @@ def get_threshold(nd):
assert_almost_equal(np.array([th_dict['layer1'][1]]), expected_threshold, rtol=1e-2, atol=1e-4)
+@with_seed()
+def test_onednn_shifted_quantization():
+ if not is_test_for_mkldnn():
+ print("Test only for mkldnn")
+ return
+
+ def collect_param(fc_layer, p):
+ param = fc_layer.collect_params(p)[p]._reduce()
+ return param
+
+ def quantize_to_int8(param):
+ p_int8, p_min, p_max = mx.ndarray.contrib.quantize(data=param,
+ min_range=mx.ndarray.min(param),
+ max_range=mx.ndarray.max(param),
+ out_type='int8')
+ p_scale = 127.5/np.max(np.abs([p_max.asnumpy(), p_min.asnumpy()]))
+ return p_int8.asnumpy(), p_scale
+
+ def get_shifted_bias(quantize_attrs, weights_int8, weights_scale, bias_int8, bias_scale):
+ max_data = float(quantize_attrs['max_calib_range'])
+ min_data = float(quantize_attrs['min_calib_range'])
+ data_scale = 255.5 / (max_data - min_data)
+ shift_value = np.array(np.round(-data_scale*min_data),np.uint8)
+ shift_matrix = shift_value*np.ones((1, weights_int8.shape[1]), np.int32)
+ shift_matrix = np.array(np.dot(shift_matrix, weights_int8.T).squeeze(), np.int32)
+ bias_int32_rescale = data_scale * weights_scale / bias_scale
+ bias_int32 = np.array(np.round(bias_int8*bias_int32_rescale),dtype=np.int32)
+ bias_shifted = bias_int32 - shift_matrix
+ return bias_shifted
+
+ def quantize_fc_layer(fc_layer, qdtype, random_data):
+ batch_size = 1
+ calib_data = NDArrayIter(data=random_data, batch_size=batch_size)
+ calib_data = DummyIter(calib_data)
+ num_calib_examples = 5
+ fc_layer = mx.contrib.quant.quantize_net(fc_layer, quantized_dtype=qdtype,
+ exclude_layers=None,
+ exclude_layers_match=[],
+ calib_data=calib_data,
+ calib_mode='naive',
+ num_calib_examples=num_calib_examples,
+ ctx=mx.current_context())
+ fc_layer.hybridize(static_alloc=True, static_shape=True)
+ fc_layer(random_data).wait_to_read()
+
+ _, sym = fc_layer._cached_graph
+ quantize_attrs = sym.attr_dict()['data_quantize']
+ return fc_layer, quantize_attrs
+
+ def get_fc_layer(random_data):
+ fc_layer = mx.gluon.nn.Dense(5, use_bias=True, weight_initializer=mx.initializer.Normal(
Review comment:
fix formatting
##########
File path: src/operator/subgraph/mkldnn/mkldnn_fc.cc
##########
@@ -211,7 +214,7 @@ void SgMKLDNNFCOp::Forward(const OpContext &ctx,
bool support_channelwise_scale = false;
if (mkldnn_param.quantized) {
CHECK(data.dtype() == mshadow::kInt8 || data.dtype() == mshadow::kUint8);
- data_scale_ = GetQuantizeScale(data.dtype(), cached_min_data_, cached_max_data_);
+ data_scale_ = GetQuantizeScale(data.dtype(), cached_min_data_, cached_max_data_);
Review comment:
remove whitespace
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha merged pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
szha merged pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] sfraczek commented on pull request #20302: [FEATURE] Performance improvement by asymmetric quantization Quantize+FC
Posted by GitBox <gi...@apache.org>.
sfraczek commented on pull request #20302:
URL: https://github.com/apache/incubator-mxnet/pull/20302#issuecomment-870438023


   @mxnet-bot run ci [windows-cpu]


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@mxnet.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org