You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@mxnet.apache.org by GitBox <gi...@apache.org> on 2020/06/18 02:11:17 UTC
[GitHub] [incubator-mxnet] andrei5055 opened a new pull request #18582: Refactoring of Pooled Storage Manager classes
andrei5055 opened a new pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582


   ## Description ##
   The functionality provided by `GPUPooledStorageManager` and `GPUPooledRoundedStorageManager` classes was re-implemented. This allowed using caching not only for the `GPU`, but also for the `CPU` and  `CPU_Pinned` memory.

   ## Checklist ##
   ### Essentials ###
   - [x] Changes are complete (i.e. I finished coding on this PR)
   - [x] All changes have test coverage:
   - [x] Code is well-documented:
   - [x] To the best of my knowledge, examples are either not affected by this change, or have been fixed to be compatible with this change

   ### Changes ###
   - [x] Class `PooledStorageManager` implemented as a template:
   ```cpp
   template<typename BucketingStrategy, typename StoringMethod>
   class PooledStorageManager : public StorageManager,
    public BucketingStrategy, public StoringMethod { ... }
   ```
   which
   - allows using different methods/algorithms for bucketing and storing cached data;
   - eliminate duplication of code for different memory types: `gpu`, `cpu`,` cpu_pinned`;

   - [x] The default Storage Manager for CPU, CPU_Pinned memory will be `Pooled` and not `Naive` as before.

   - [x] Duplicated code related to the profiling and some parameter checks (`handle.size` / `handle.dptr`) which was spread inside the different Storage Manages now is located in corresponding methods of `StorageImpl` class.

   - [x] New environment variables which define the bucketing parameters for `CPU`, `CPU_Pinned` memory used with the Pooled Storage Managers are implemented and described in `**docs/static_site/src/pages/api/faq/env_var.md**`

   - [x] If needed, the user can
   - set MXNET_USE_NAIVE_STORAGE_MANAGERS=1 and the Naive Storage Managers for all types of memory
   - use **MXNET_[XXX]_MEM_POOL_TYPE=Unpooled**, with XXX is one of {GPU, CPU, CPU_PINNED} and start using Native storage Manager for that specific memory type.

   ## Comments ##
   Our experiments show a 2.2-2.3x improvement in training time when using `CPU` /` CPU_Pinned` memory with new Pooled Storage Managers compared to their usage with Naive (non-pooled) Storage Manager's


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] mxnet-bot commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
mxnet-bot commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-645726192


   Hey @andrei5055 , Thanks for submitting the PR
   All tests are already queued to run once. If tests fail, you can trigger one or more tests again with the following commands:
   - To trigger all jobs: @mxnet-bot run ci [all]
   - To trigger specific jobs: @mxnet-bot run ci [job1, job2]
   ***
   **CI supported jobs**: [unix-gpu, sanity, centos-cpu, centos-gpu, windows-gpu, unix-cpu, miscellaneous, edge, windows-cpu, clang, website]
   ***
   _Note_:
    Only following 3 categories can trigger CI :PR Author, MXNet Committer, Jenkins Admin.
   All CI tests must pass before the PR can be merged.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 edited a comment on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 edited a comment on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654937596
**Please, for now ignore graphs for CPU and CPU_PINNED memory. I am not sure why, but I don't see 2x run time improvement for newly implemented Pooled Storage Managers with respect to "Unpooled" ones. Perhaps, it's because I was using my workstation with limited amount of CPU memory. I will try to run the same benchmarks on the machine with more CPU memory and I will update the results.**

(Here we do have only three lines, because the Pooled Storage Manager was not implemented for CPU_PINNED memory.)
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-653164922


   @szha :  I think this PR is ready for review. Two non-required tests failed, but for some reason, CI launched both of them twice, and first launches succeeded.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on a change in pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha commented on a change in pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#discussion_r451039888


##########
File path: src/storage/cpu_device_storage.h
##########
@@ -63,15 +60,12 @@ class CPUDeviceStorage {
 };  // class CPUDeviceStorage

 inline void CPUDeviceStorage::Alloc(Storage::Handle* handle) {
-  handle->dptr = nullptr;
-  const size_t size = handle->size;
-  if (size == 0) return;
-
+  // NOTE: handle->size is NOT 0. See calling method: StorageImpl::Alloc

Review comment:
       remove the comment as it doesn't help future reader of the code. if needed, document the invariant in interface definition instead. same for other occurrences.

##########
File path: src/storage/pooled_storage_manager.h
##########
@@ -25,372 +25,420 @@
 #ifndef MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_
 #define MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_

-#if MXNET_USE_CUDA
-  #include <cuda_runtime.h>
-#endif  // MXNET_USE_CUDA
-
-#include <mxnet/base.h>
-#include <mxnet/storage.h>
-#include <unordered_map>
-#include <algorithm>
+#include <string>
 #include <vector>
+#include <algorithm>
 #include <mutex>
-#include <new>
+#include <tuple>
 #include "./storage_manager.h"
-#include "../common/cuda_utils.h"
-#include "../common/utils.h"
 #include "../profiler/storage_profiler.h"


 namespace mxnet {
 namespace storage {

+typedef enum {
+  pool_type,
+  pool_page_size,
+  large_alloc_size,
+  round_linear_cutoff,
+  pool_reserve,
+} env_var_type;
+
+const std::string env_var_name(const char* dev_type, env_var_type type);
+
 #if MXNET_USE_CUDA
+#define SET_DEVICE(device_store, contextHelper, ctx, flag) \
+      const auto *device_store = flag? contextHelper.get()->SetCurrentDevice(ctx) : nullptr;
+#define UNSET_DEVICE(device_store)    delete device_store
+
+#define SET_GPU_PROFILER(prof, contextHelper)                          \
+      auto prof = contextHelper->contextGPU()?                         \
+                  profiler::GpuDeviceStorageProfiler::Get() : nullptr; \
+      if (!prof->IsProfiling()) prof = nullptr
+
+#define GPU_PROFILER_ON_FREE(prof, pntr)    if (prof) prof->OnFree(pntr)
+#else
+// empty macros when MxNet is compile without CUDA support
+#define SET_DEVICE(...)
+#define UNSET_DEVICE(...)
+#define SET_GPU_PROFILER(prof, ...)
+#define GPU_PROFILER_ON_FREE(prof, ...)
+#endif
+
 /*!
- * \brief Storage manager with a memory pool on gpu. Memory chunks are reused based on exact size
- * match.
+ * \brief Storage manager with a memory pool for GPU/CPU/CPUPunned memory chunks
+ * memory chunks which reused based on rounded size match.
+ * Rounding method is defined by the template parameter BucketingStrategy.
+ * Memory pool type is defined by the template parameter StoringMethod
+ * Allocation/freeing of memory is done by contextHelper_, which is the pointer
+ * to one of memory specific instance of the class, derived from ContextHelper
  */
-class GPUPooledStorageManager final : public StorageManager {
+template<typename BucketingStrategy, typename StoringMethod>
+class PooledStorageManager : public StorageManager,
+             public BucketingStrategy, public StoringMethod {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    large_alloc_round_size_ = dmlc::GetEnv("MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE", 2 * 1024 * 1024);
-    if (large_alloc_round_size_ <= 0) {
-      LOG(FATAL) << "MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE cannot be set to a value <= 0, found: "
-                 << large_alloc_round_size_;
+  explicit PooledStorageManager(const Context &ctx, int num_gpu_device) {
+    const char *dev_type = nullptr;
+    switch (dev_type_ = ctx.dev_type) {
+#if MXNET_USE_CUDA
+      case Context::kGPU:       contextHelper_ = std::make_unique<ContextHelperGPU>();
+                                dev_type = "GPU";
+                                break;
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+                                if (num_gpu_device > 1) {
+                                  contextHelper_ = std::make_unique<ContextHelperPinned>();
+                                  dev_type_ = Context::kGPU;
+                                  break;
+                                }
+#else
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+#endif
+                                dev_type_ = Context::kCPU;
+      case Context::kCPU:       contextHelper_ = std::make_unique<ContextHelperCPU>();
+                                dev_type = "CPU";
+      default:                  break;
     }
-    if (page_size_ < NDEV) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than " << NDEV \
-                 << ". Got " << page_size_ << ".";
+
+    BucketingStrategy::InitRoundHelper(dev_type);
+    StoringMethod::InitContainer(this);
+    contextHelper_->set_initilal_context(ctx);
+
+    // percentage of reserved memory
+    if (dev_type) {
+      const auto env_var = env_var_name(dev_type, pool_reserve);
+      const size_t reserve = dmlc::GetEnv(env_var.c_str(), 5);
+      const size_t total = std::get<1>(contextHelper_->getMemoryInfo());
+      memory_allocation_limit_ = total * reserve / 100;
     }
   }
   /*!
    * \brief Default destructor.
    */
-  ~GPUPooledStorageManager() {
+  ~PooledStorageManager() override {
     ReleaseAll();
   }

   void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  void Free(Storage::Handle handle) override {
+    // Insert returned memory in cache
+    // NOTE: handle.dptr is NOT nullptr. See calling method: StorageImpl::Free

Review comment:
       remove comment since it doesn't refer to existing code. if needed, document in the interface definition instead.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-653212266


   @andrei5055 thanks, I will take a look. Since this PR is for refactoring so I don't expect performance change, but just in case given that this is core functionality: could you do some benchmarking on how fast the allocation is (in terms of calls per second), as well as come up with a snippet for comparing the performance before and after the change?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654562254
Here is first graph for GPU Storage Managers:

I will construct similar graphs for CPU, CPU_PINNED and Threaded Engines.
My benchmarks are based on [that script](https://github.com/apache/incubator-mxnet/issues/17335). As you could see, some lines are almost identical, as it should be.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-656967881
Regarding my previous comment...
**Please, for now ignore graphs for CPU and CPU_PINNED memory. I am not sure why, but I don't see 2x run time improvement for newly implemented Pooled Storage Managers with respect to "Unpooled" ones, which I saw on my local NVidia branch. Perhaps, it's because I was using my workstation with limited amount of CPU memory. I will try to run the same benchmarks on the machine with more CPU memory and I will update the results.**
I tried, but, unfortunately, I cannot compile MxNet on our `dbcluster` because of 5GB memory limitation we have here.
But it is not important anymore, because I notices significant difference in performance between current NVidia version of MxNet and Incubator-MxNet.


As we could see, for Batch Size > 1,the Incubator-MxNet is much faster for CPU/CPU_PINNED Storage Manager.
I do not know why this is happening, but it does not interfere with this merger.
I will make the changes you proposed.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-659742603


   @andrei5055 thanks for the refactor


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654943614
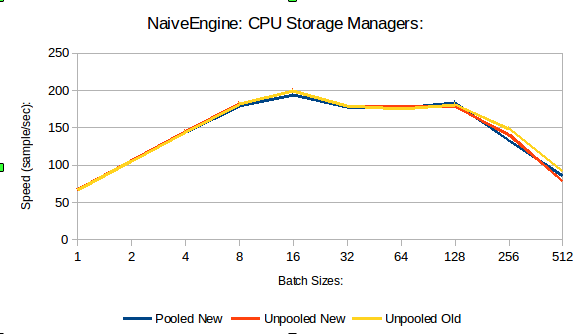
(Here we do have only three lines, because the Pooled Storage Manager was not implemented for CPU memory.)
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on a change in pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha commented on a change in pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#discussion_r443169285


##########
File path: src/storage/storage_manager_helpers.h
##########
@@ -0,0 +1,191 @@
+/*
+ * Licensed to the Apache Software Foundation (ASF) under one
+ * or more contributor license agreements.  See the NOTICE file
+ * distributed with this work for additional information
+ * regarding copyright ownership.  The ASF licenses this file
+ * to you under the Apache License, Version 2.0 (the
+ * "License"); you may not use this file except in compliance
+ * with the License.  You may obtain a copy of the License at
+ *
+ *   http://www.apache.org/licenses/LICENSE-2.0
+ *
+ * Unless required by applicable law or agreed to in writing,
+ * software distributed under the License is distributed on an
+ * "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+ * KIND, either express or implied.  See the License for the
+ * specific language governing permissions and limitations
+ * under the License.
+ */
+
+#ifndef MXNET_STORAGE_STORAGE_MANAGER_HELPERS_H_
+#define MXNET_STORAGE_STORAGE_MANAGER_HELPERS_H_
+
+#if MXNET_USE_CUDA
+#include <cuda_runtime.h>
+#include "../common/cuda_utils.h"
+typedef  mxnet::common::cuda::DeviceStore CudaDeviceStore;
+#endif  // MXNET_USE_CUDA
+
+#include <thread>
+#include <sys/sysctl.h>
+#ifndef _WIN32
+#if __APPLE__
+#include <mach/vm_statistics.h>
+#include <mach/mach_types.h>
+#include <mach/mach_init.h>
+#include <mach/mach_host.h>
+#else
+#include <sys/sysinfo.h>
+#include <sys/mman.h>
+#include <sys/fcntl.h>
+#include <unistd.h>
+#include <sys/types.h>
+#include <sys/stat.h>
+#include <sys/resource.h>
+#endif  // __APPLE__
+#else
+#include <Windows.h>
+#include <process.h>
+#endif  // _WIN32
+
+#include <unordered_map>
+#include <vector>
+#include <tuple>
+#include <atomic>
+#include <iostream>
+#include <mutex>
+#include <new>
+#include <string>
+#include <limits>

Review comment:
       You can test it locally by running `make cpplint`


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on a change in pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha commented on a change in pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#discussion_r443169232


##########
File path: src/storage/storage_manager_helpers.h
##########
@@ -0,0 +1,191 @@
+/*
+ * Licensed to the Apache Software Foundation (ASF) under one
+ * or more contributor license agreements.  See the NOTICE file
+ * distributed with this work for additional information
+ * regarding copyright ownership.  The ASF licenses this file
+ * to you under the Apache License, Version 2.0 (the
+ * "License"); you may not use this file except in compliance
+ * with the License.  You may obtain a copy of the License at
+ *
+ *   http://www.apache.org/licenses/LICENSE-2.0
+ *
+ * Unless required by applicable law or agreed to in writing,
+ * software distributed under the License is distributed on an
+ * "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY
+ * KIND, either express or implied.  See the License for the
+ * specific language governing permissions and limitations
+ * under the License.
+ */
+
+#ifndef MXNET_STORAGE_STORAGE_MANAGER_HELPERS_H_
+#define MXNET_STORAGE_STORAGE_MANAGER_HELPERS_H_
+
+#if MXNET_USE_CUDA
+#include <cuda_runtime.h>
+#include "../common/cuda_utils.h"
+typedef  mxnet::common::cuda::DeviceStore CudaDeviceStore;
+#endif  // MXNET_USE_CUDA
+
+#include <thread>
+#include <sys/sysctl.h>
+#ifndef _WIN32
+#if __APPLE__
+#include <mach/vm_statistics.h>
+#include <mach/mach_types.h>
+#include <mach/mach_init.h>
+#include <mach/mach_host.h>
+#else
+#include <sys/sysinfo.h>
+#include <sys/mman.h>
+#include <sys/fcntl.h>
+#include <unistd.h>
+#include <sys/types.h>
+#include <sys/stat.h>
+#include <sys/resource.h>
+#endif  // __APPLE__
+#else
+#include <Windows.h>
+#include <process.h>
+#endif  // _WIN32
+
+#include <unordered_map>
+#include <vector>
+#include <tuple>
+#include <atomic>
+#include <iostream>
+#include <mutex>
+#include <new>
+#include <string>
+#include <limits>

Review comment:
       [include order needs fix](http://jenkins.mxnet-ci.amazon-ml.com/blue/organizations/jenkins/mxnet-validation%2Fsanity/detail/PR-18582/4/pipeline#step-80-log-238):
   `[2020-06-19T17:55:27.961Z] src/storage/storage_manager_helpers.h:30:  Found C system header after C++ system header. Should be: storage_manager_helpers.h, c system, c++ system, other.  [build/include_order] [4]`


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 edited a comment on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 edited a comment on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654562254
Here is first graph for GPU Storage Managers:


I will construct similar graphs for CPU, CPU_PINNED and Threaded Engines.
My benchmarks are based on [that script](https://github.com/apache/incubator-mxnet/issues/17335). As you could see, some lines are almost identical, as it should be.
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 edited a comment on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 edited a comment on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654937596


(Here we do have only three lines, because the Pooled Storage Manager was not implemented for CPU_PINNED memory.)
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 edited a comment on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 edited a comment on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654943614


\
(Here we do have only three lines, because the Pooled Storage Manager was not implemented for CPU memory.)
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha merged pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha merged pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 commented on a change in pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 commented on a change in pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#discussion_r485953280


##########
File path: src/storage/pooled_storage_manager.h
##########
@@ -25,372 +25,418 @@
 #ifndef MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_
 #define MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_

-#if MXNET_USE_CUDA
-  #include <cuda_runtime.h>
-#endif  // MXNET_USE_CUDA
-
-#include <mxnet/base.h>
-#include <mxnet/storage.h>
-#include <unordered_map>
-#include <algorithm>
+#include <string>
 #include <vector>
+#include <algorithm>
 #include <mutex>
-#include <new>
+#include <tuple>
 #include "./storage_manager.h"
-#include "../common/cuda_utils.h"
-#include "../common/utils.h"
 #include "../profiler/storage_profiler.h"


 namespace mxnet {
 namespace storage {

+typedef enum {
+  pool_type,
+  pool_page_size,
+  large_alloc_size,
+  round_linear_cutoff,
+  pool_reserve,
+} env_var_type;
+
+const std::string env_var_name(const char* dev_type, env_var_type type);
+
 #if MXNET_USE_CUDA
+#define SET_DEVICE(device_store, contextHelper, ctx, flag) \
+      const auto *device_store = flag? contextHelper.get()->SetCurrentDevice(ctx) : nullptr;
+#define UNSET_DEVICE(device_store)    delete device_store
+
+#define SET_GPU_PROFILER(prof, contextHelper)                          \
+      auto prof = contextHelper->contextGPU()?                         \
+                  profiler::GpuDeviceStorageProfiler::Get() : nullptr; \
+      if (!prof->IsProfiling()) prof = nullptr
+
+#define GPU_PROFILER_ON_FREE(prof, pntr)    if (prof) prof->OnFree(pntr)
+#else
+// empty macros when MxNet is compiled without CUDA support
+#define SET_DEVICE(...)
+#define UNSET_DEVICE(...)
+#define SET_GPU_PROFILER(prof, ...)
+#define GPU_PROFILER_ON_FREE(prof, ...)
+#endif
+
 /*!
- * \brief Storage manager with a memory pool on gpu. Memory chunks are reused based on exact size
- * match.
+ * \brief Storage manager with a memory pool for GPU/CPU/CPUPunned memory chunks
+ * memory chunks which reused based on rounded size match.
+ * Rounding method is defined by the template parameter BucketingStrategy.
+ * Memory pool type is defined by the template parameter StoringMethod
+ * Allocation/freeing of memory is done by contextHelper_, which is the pointer
+ * to one of memory specific instance of the class, derived from ContextHelper
  */
-class GPUPooledStorageManager final : public StorageManager {
+template<typename BucketingStrategy, typename StoringMethod>
+class PooledStorageManager : public StorageManager,
+             public BucketingStrategy, public StoringMethod {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    large_alloc_round_size_ = dmlc::GetEnv("MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE", 2 * 1024 * 1024);
-    if (large_alloc_round_size_ <= 0) {
-      LOG(FATAL) << "MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE cannot be set to a value <= 0, found: "
-                 << large_alloc_round_size_;
+  explicit PooledStorageManager(const Context &ctx, int num_gpu_device) {
+    const char *dev_type = nullptr;
+    switch (dev_type_ = ctx.dev_type) {
+#if MXNET_USE_CUDA
+      case Context::kGPU:       contextHelper_ = std::make_unique<ContextHelperGPU>();
+                                dev_type = "GPU";
+                                break;
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+                                if (num_gpu_device > 1) {
+                                  contextHelper_ = std::make_unique<ContextHelperPinned>();
+                                  dev_type_ = Context::kGPU;
+                                  break;
+                                }
+#else
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+#endif
+                                dev_type_ = Context::kCPU;
+      case Context::kCPU:       contextHelper_ = std::make_unique<ContextHelperCPU>();
+                                dev_type = "CPU";
+      default:                  break;
     }
-    if (page_size_ < NDEV) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than " << NDEV \
-                 << ". Got " << page_size_ << ".";
+
+    BucketingStrategy::InitRoundHelper(dev_type);
+    StoringMethod::InitContainer(this);
+    contextHelper_->set_initilal_context(ctx);
+
+    // percentage of reserved memory
+    if (dev_type) {
+      const auto env_var = env_var_name(dev_type, pool_reserve);
+      const size_t reserve = dmlc::GetEnv(env_var.c_str(), 5);
+      const size_t total = std::get<1>(contextHelper_->getMemoryInfo());
+      memory_allocation_limit_ = total * reserve / 100;
     }
   }
   /*!
    * \brief Default destructor.
    */
-  ~GPUPooledStorageManager() {
+  ~PooledStorageManager() override {
     ReleaseAll();
   }

   void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  void Free(Storage::Handle handle) override {
+    // Insert returned memory in cache
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    StoringMethod::InsertInCache(BucketingStrategy::get_bucket(handle.size), handle.dptr);
+  }

   void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    SET_DEVICE(device_store, contextHelper_, handle.ctx, true);
+    contextHelper_->Free(handle.dptr);
+    SET_GPU_PROFILER(profilerGPU, contextHelper_);
+    GPU_PROFILER_ON_FREE(profilerGPU, handle.dptr);
+    UNSET_DEVICE(device_store);
+    used_memory_ -= BucketingStrategy::RoundAllocSize(handle.size);
   }

-  void ReleaseAll() override;
-
- private:
-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = RoundAllocSize(handle.size);
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
+  void ReleaseAll() override {
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    ReleaseAllNoLock();
   }

-  // Round a value 'x' up to the next multiple of 'multiple'
-  size_t RoundToMultiple(size_t x, size_t multiple) {
-    size_t retVal = ((x + multiple - 1) / multiple) * multiple;
-    return retVal;
+ private:
+  void ReleaseAllNoLock(bool set_device = true) {
+    SET_DEVICE(device_store, contextHelper_, contextHelper_->initilal_context(), set_device);
+    used_memory_ -= StoringMethod::ReleaseAllNoLock(contextHelper_.get(), this);
+    UNSET_DEVICE(device_store);
   }

-  size_t RoundAllocSize(size_t size) {
-    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
-    size = RoundToMultiple(size, page_size_);
-    // To ensure proper freeing under some driver variants, make sure
-    // large allocs entirely occupy their slabs, which cannot then be
-    // locked by smaller permanent allocations sharing the slab.
-    if (size > large_alloc_round_size_)
-      size = RoundToMultiple(size, large_alloc_round_size_);
-    return size;
+  bool MemoryIsAvalable(size_t roundSize) const {
+    const auto free = contextHelper_->freeMemorySize();
+    return free > roundSize && memory_allocation_limit_ <= free - roundSize;
   }

- private:
+  // device type of used context
+  Context::DeviceType dev_type_;
   // used memory
   size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
-  // size that large allocations should be rounded to, for proper freeing.
-  size_t large_alloc_round_size_;
-  // percentage of reserved memory
-  int reserve_;
-  // number of devices
-  const size_t NDEV = 32;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::unordered_map<size_t, std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledStorageManager);
-};  // class GPUPooledStorageManager
-
-void GPUPooledStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
-  }
+  // minimum amount of memory, which will never be allocated
+  size_t memory_allocation_limit_ = 0;
+  // Pointer to the Helper, supporting some context-specific operations in GPU/CPU/CPUPinned context
+  std::unique_ptr<ContextHelper> contextHelper_;
+};
+
+template<typename BucketingStrategy, typename StoringMethod>
+void PooledStorageManager<BucketingStrategy, StoringMethod>::Alloc(Storage::Handle* handle) {
+  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+  const auto bucket_id = BucketingStrategy::get_bucket(handle->size);
+  size_t roundSize = 0;
+  auto reuse_pool = StoringMethod::GetMemStorage(bucket_id);
+  if (!reuse_pool) {
+    SET_DEVICE(device_store, contextHelper_, handle->ctx, true);
+    roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+    if (!MemoryIsAvalable(roundSize))
+      ReleaseAllNoLock(false);
+
+    void *ret = nullptr;
+    auto e = contextHelper_->Malloc(&ret, roundSize);
+    if (e) {
+      const std::string err(
+#if MXNET_USE_CUDA
+      dev_type_ == Context::kGPU?
+         cudaGetErrorString(static_cast<cudaError_t>(e)) :
+#endif
+         std::strerror(errno));

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle->size);
-  auto&& reuse_it = memory_pool_.find(size);
-  if (reuse_it == memory_pool_.end() || reuse_it->second.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
-      }
+      LOG(FATAL) << "Memory allocation failed " << err;
     }
-    used_memory_ += size;
+
+    UNSET_DEVICE(device_store);
+
+    used_memory_ += roundSize;
     handle->dptr = ret;
-    // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, false);
   } else {
-    auto&& reuse_pool = reuse_it->second;
-    auto ret = reuse_pool.back();
-    reuse_pool.pop_back();
-    handle->dptr = ret;
+    // Reusing memory
+    handle->dptr = reuse_pool->back();
+    reuse_pool->pop_back();
+  }
+#if MXNET_USE_CUDA
+  SET_GPU_PROFILER(profilerGPU, contextHelper_);
+  if (profilerGPU) {
+    if (reuse_pool)  // roundSize was not calculated
+      roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+
     // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, true);
+    profilerGPU->OnAlloc(*handle, roundSize, reuse_pool);
   }
+#endif
 }

-void GPUPooledStorageManager::Free(Storage::Handle handle) {
-  // Do nothing if dptr is nullptr. Otherwise, nullptr may be reused
-  // which can cause illegal memory access error.
-  if (handle.dptr == nullptr) return;

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle.size);
-  auto&& reuse_pool = memory_pool_[size];
-  reuse_pool.push_back(handle.dptr);
-}
+/*!
+ * \brief Base class for Rounding Method classes.
+ */
+class RoundHelper {
+ public:
+  virtual size_t get_size(size_t  /*bucket*/) const { return 0; }
+  virtual std::tuple<size_t, size_t> getContainerParam() const {
+     return std::tuple<size_t, size_t>(0, 0);
+  }

-void GPUPooledStorageManager::ReleaseAll() {
-  for (auto&& i : memory_pool_) {
-    for (auto&& j : i.second) {
-      Storage::Handle handle;
-      handle.dptr = j;
-      handle.size = i.first;
-      handle.ctx = initial_context_;
-      DirectFreeNoLock(handle);
+ protected:
+  void InitRoundHelper(const char* dev_type) {
+    const auto env_var = env_var_name(dev_type, pool_page_size);
+    page_size_ = dmlc::GetEnv(env_var.c_str(), 4096);
+    if (page_size_ < NDEV) {
+      LOG(FATAL) << env_var << " cannot be set to a value smaller than " << NDEV \
+                    << ". Got " << page_size_ << ".";
     }
   }
-  memory_pool_.clear();
-}
+
+  // page size
+  size_t page_size_ = 0;
+
+ private:
+  // number of devices
+  const size_t NDEV = 32;
+};  // class RoundHelper

 /*!
- * \brief Storage manager with a memory pool, with rounded size, on gpu.
+ * \brief Rounding method used by CPU/GPU mem pool.
+ * Round up small allocs to multiple of page_size_ or large_alloc_round_size_
+ */
+class RoundMultiple : protected RoundHelper {
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto env_var = env_var_name(dev_type, large_alloc_size);
+    large_alloc_round_size_ = dmlc::GetEnv(env_var.c_str(), 2*1024*1024);
+    if (large_alloc_round_size_ <= 0) {
+      LOG(FATAL) << env_var << " cannot be set to a value <= 0, found: "
+                 << large_alloc_round_size_;
+    }
+  }
+
+  size_t RoundAllocSize(size_t size) const {
+    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
+    size = RoundToMultiple(size, page_size_);
+    // To ensure proper freeing under some driver variants, make sure
+    // large allocs entirely occupy their slabs, which cannot then be
+    // locked by smaller permanent allocations sharing the slab.
+    return  size > large_alloc_round_size_? RoundToMultiple(size, large_alloc_round_size_) : size;
+  }
+  inline size_t get_bucket(size_t size) const                   { return RoundAllocSize(size); }
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return bucket_id; }
+
+ private:
+  // Round a value 'x' up to the next multiple of 'multiple'
+  inline static size_t RoundToMultiple(size_t x, size_t multiple) {
+    return ((x + multiple - 1) / multiple) * multiple;
+  }
+
+  // size that large allocations should be rounded to, for proper freeing.
+  size_t large_alloc_round_size_;
+};  // class RoundMultiple
+
+/*!
+ * \brief Rounding method used by CPU/GPU mem pool.
  *
- * This GPU mem pool uses a mixture of nearest pow2 (exponential) rounding and
+ * This Rounding method uses a mixture of nearest pow2 (exponential) rounding and
  * nearest multiple (linear) rounding to help alleviate the memory allocation stress
  * in which the default naive exact-size-match pool falls short, such as in variable-length
  * input/output cases like RNN workloads.
  *
  * \param cutoff the cutoff at which rounding is switched from exponential to linear. It's set
- * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable. Must be between 20 (1 MB)
- * and 34 (16 GB).
+ * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF / MXNET_CPU_MEM_POOL_ROUND_LINEAR_CUTOFF /
+ * MXNET_CPU_PINNED_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable.
+ * Must be between 20 (1 MB) and 34 (16 GB).
  * Suppose the cutoff is X, the memory size buckets look like this:
  * exp2(0), exp2(1), ..., exp2(X), 2*exp2(X), 3*exp2(X), ...
  */
-class GPUPooledRoundedStorageManager final : public StorageManager {
+class RoundPower2 : public RoundHelper {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledRoundedStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    cut_off_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF", 24);
-    if (page_size_ < 32) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than 32. " \
-                 << "Got: " << page_size_ << ".";
-    }
-    if (page_size_ != 1ul << common::ilog2ul(page_size_ - 1)) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE must be a power of 2. Got: " << page_size_ << ".";
+  size_t get_size(size_t bucket) const override {
+    return bucket <= cut_off_? 1ul << bucket : (bucket - cut_off_ + 1) << cut_off_;
+  }
+
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto log_pager_size = common::ilog2ul(page_size_ - 1);
+    if (page_size_ != 1ul << log_pager_size) {
+      LOG(FATAL) << env_var_name(dev_type, pool_page_size) \
+                 << " must be a power of 2. Got: " << page_size_ << ".";
     }
-    page_size_ = common::ilog2ul(page_size_ - 1);
+    page_size_ = log_pager_size;
+
+    const auto linear_cutoff = env_var_name(dev_type, round_linear_cutoff);
+    cut_off_ = dmlc::GetEnv(linear_cutoff.c_str(), 24);
     if (cut_off_ < 20 || cut_off_ > LOG2_MAX_MEM) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value " \
                  << "smaller than 20 or greater than " << LOG2_MAX_MEM << ". Got: " \
                  << cut_off_ << ".";
     }
     if (cut_off_ < page_size_) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
-                 << "smaller than log2 of MXNET_GPU_MEM_POOL_PAGE_SIZE. Got: " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value smaller than log2 of " \
+                 << env_var_name(dev_type, pool_page_size) << ". Got: " \
                  << cut_off_ << " vs " << page_size_ << ".";
     }
-    memory_pool_ = std::vector<std::vector<void*>>((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_);
-  }
-  /*!
-   * \brief Default destructor.
-   */
-  ~GPUPooledRoundedStorageManager() {
-    ReleaseAll();
   }

-  void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  inline size_t get_bucket(size_t s) const {
+    const size_t log_size = common::ilog2ul(s - 1);
+    if (log_size > cut_off_)
+      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;

-  void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    return std::max(log_size, page_size_);
   }

-  void ReleaseAll() override;
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return get_size(bucket_id); }
+  inline size_t RoundAllocSize(size_t size) const { return get_size(get_bucket(size)); }
+  std::tuple<size_t, size_t> getContainerParam() const override {
+    return std::make_tuple((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_,
+                       get_bucket(page_size_) - 1);
+  }

  private:
-  inline int div_pow2_round_up(size_t s, int divisor_log2) {
+  inline static int div_pow2_round_up(size_t s, int divisor_log2) {
     // (1025, 10) -> 2
     // (2048, 10) -> 2
     // (2049, 10) -> 3
-    size_t result = s >> divisor_log2;
+    const size_t result = s >> divisor_log2;
     return static_cast<int>(result + (s > (result << divisor_log2) ? 1 : 0));
   }
-  inline int get_bucket(size_t s) {
-    int log_size = common::ilog2ul(s - 1);
-    if (log_size > static_cast<int>(cut_off_))
-      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;
-    else
-      return std::max(log_size, static_cast<int>(page_size_));
-  }
-  inline size_t get_size(int bucket) {
-    if (bucket <= static_cast<int>(cut_off_))
-      return 1ul << bucket;
-    else
-      return (bucket - cut_off_ + 1) * (1ul << cut_off_);
-  }

-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = get_size(get_bucket(handle.size));
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
-  }
-
- private:
   // log2 of maximum page size. 16GB
   const size_t LOG2_MAX_MEM = 34;
-  // address width in bits
-  static const int addr_width = sizeof(size_t) * 8;
-  // used memory
-  size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
   // log2 of memory size before switching to exponential mode to linear mode
-  size_t cut_off_;
-  // percentage of reserved memory
-  int reserve_;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::vector<std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledRoundedStorageManager);
-};  // class GPUPooledRoundedStorageManager
-
-void GPUPooledRoundedStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
+  size_t cut_off_ = 0;
+};  // class RoundPower2
+
+
+/*!
+ * \brief Unordered map based storage container.
+ *  The pointers to the portions of same rounded sizes memory
+ *  allocated on CPU/GPU, are stored in separate vectors.
+ *  These sizes are used as keys for accessing the vectors,
+ *  which are the elements stored in an unordered map.
+ */
+class UnorderedMapContainer {
+ protected:
+  inline void InitContainer(const RoundHelper *p)   {}
+  inline void InsertInCache(size_t key, void *dptr) { memory_pool_[key].push_back(dptr); }
+
+  inline std::vector<void*> *GetMemStorage(size_t key) {
+    auto&& reuse_it = memory_pool_.find(key);
+    return reuse_it != memory_pool_.end() && reuse_it->second.size()? &reuse_it->second : nullptr;
   }

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  int bucket = get_bucket(handle->size);
-  size_t size = get_size(bucket);
-  auto&& reuse_pool = memory_pool_[bucket];
-  if (reuse_pool.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
+  size_t ReleaseAllNoLock(const ContextHelper *contextHelper, const RoundHelper * /*rndHelper*/) {
+    SET_GPU_PROFILER(profilerGPU, contextHelper);
+    size_t released_memory = 0;
+    for (auto&& i : memory_pool_) {
+      for (auto&& j : i.second) {
+        contextHelper->Free(j);
+        GPU_PROFILER_ON_FREE(profilerGPU, j);
       }

Review comment:
       Actually, new code contains exactly the same retry (see `retry in case of fragmentation` comment)
   ```cpp
       roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
       if (!MemoryIsAvalable(roundSize))
         ReleaseAllNoLock(false);

       void *ret = nullptr;
       auto e = contextHelper_->Malloc(&ret, roundSize);
       if (e) {
         // retry in case of fragmentation
         ReleaseAllNoLock(false);
         e = contextHelper_->Malloc(&ret, roundSize);
         if (e) {
           const std::string err(
   #if MXNET_USE_CUDA
           dev_type_ == Context::kGPU?
              cudaGetErrorString(static_cast<cudaError_t>(e)) :
   #endif
              std::strerror(errno));

           LOG(FATAL) << "Memory allocation failed " << err;
         }
       }

       UNSET_DEVICE(device_store);
       used_memory_ += roundSize;
   ```

   As you could see, in that part I am using `ReleaseAllNoLock(false)` twice:

   - when the amount of free memory is below some threshold
   - after unsuccessful first attempt to allocate memory.
   After each of these two calls, we try to allocate memory by `contextHelper_->Malloc(&ret, roundSize);`

   Previously, we had exactly the same:
   ```cpp
       size_t free, total;
       cudaMemGetInfo(&free, &total);
       if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
         ReleaseAll();

       void* ret = nullptr;
       cudaError_t e = cudaMalloc(&ret, size);
       if (e != cudaSuccess) {
         if (e == cudaErrorMemoryAllocation) {
           ReleaseAll();
           e = cudaMalloc(&ret, size);
           if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
             LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
           }
         } else if (e != cudaErrorCudartUnloading) {
           LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
         }
       }
       used_memory_ += size;
   ```


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on a change in pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha commented on a change in pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#discussion_r475054411


##########
File path: src/storage/pooled_storage_manager.h
##########
@@ -25,372 +25,418 @@
 #ifndef MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_
 #define MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_

-#if MXNET_USE_CUDA
-  #include <cuda_runtime.h>
-#endif  // MXNET_USE_CUDA
-
-#include <mxnet/base.h>
-#include <mxnet/storage.h>
-#include <unordered_map>
-#include <algorithm>
+#include <string>
 #include <vector>
+#include <algorithm>
 #include <mutex>
-#include <new>
+#include <tuple>
 #include "./storage_manager.h"
-#include "../common/cuda_utils.h"
-#include "../common/utils.h"
 #include "../profiler/storage_profiler.h"


 namespace mxnet {
 namespace storage {

+typedef enum {
+  pool_type,
+  pool_page_size,
+  large_alloc_size,
+  round_linear_cutoff,
+  pool_reserve,
+} env_var_type;
+
+const std::string env_var_name(const char* dev_type, env_var_type type);
+
 #if MXNET_USE_CUDA
+#define SET_DEVICE(device_store, contextHelper, ctx, flag) \
+      const auto *device_store = flag? contextHelper.get()->SetCurrentDevice(ctx) : nullptr;
+#define UNSET_DEVICE(device_store)    delete device_store
+
+#define SET_GPU_PROFILER(prof, contextHelper)                          \
+      auto prof = contextHelper->contextGPU()?                         \
+                  profiler::GpuDeviceStorageProfiler::Get() : nullptr; \
+      if (!prof->IsProfiling()) prof = nullptr
+
+#define GPU_PROFILER_ON_FREE(prof, pntr)    if (prof) prof->OnFree(pntr)
+#else
+// empty macros when MxNet is compiled without CUDA support
+#define SET_DEVICE(...)
+#define UNSET_DEVICE(...)
+#define SET_GPU_PROFILER(prof, ...)
+#define GPU_PROFILER_ON_FREE(prof, ...)
+#endif
+
 /*!
- * \brief Storage manager with a memory pool on gpu. Memory chunks are reused based on exact size
- * match.
+ * \brief Storage manager with a memory pool for GPU/CPU/CPUPunned memory chunks
+ * memory chunks which reused based on rounded size match.
+ * Rounding method is defined by the template parameter BucketingStrategy.
+ * Memory pool type is defined by the template parameter StoringMethod
+ * Allocation/freeing of memory is done by contextHelper_, which is the pointer
+ * to one of memory specific instance of the class, derived from ContextHelper
  */
-class GPUPooledStorageManager final : public StorageManager {
+template<typename BucketingStrategy, typename StoringMethod>
+class PooledStorageManager : public StorageManager,
+             public BucketingStrategy, public StoringMethod {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    large_alloc_round_size_ = dmlc::GetEnv("MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE", 2 * 1024 * 1024);
-    if (large_alloc_round_size_ <= 0) {
-      LOG(FATAL) << "MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE cannot be set to a value <= 0, found: "
-                 << large_alloc_round_size_;
+  explicit PooledStorageManager(const Context &ctx, int num_gpu_device) {
+    const char *dev_type = nullptr;
+    switch (dev_type_ = ctx.dev_type) {
+#if MXNET_USE_CUDA
+      case Context::kGPU:       contextHelper_ = std::make_unique<ContextHelperGPU>();
+                                dev_type = "GPU";
+                                break;
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+                                if (num_gpu_device > 1) {
+                                  contextHelper_ = std::make_unique<ContextHelperPinned>();
+                                  dev_type_ = Context::kGPU;
+                                  break;
+                                }
+#else
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+#endif
+                                dev_type_ = Context::kCPU;
+      case Context::kCPU:       contextHelper_ = std::make_unique<ContextHelperCPU>();
+                                dev_type = "CPU";
+      default:                  break;
     }
-    if (page_size_ < NDEV) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than " << NDEV \
-                 << ". Got " << page_size_ << ".";
+
+    BucketingStrategy::InitRoundHelper(dev_type);
+    StoringMethod::InitContainer(this);
+    contextHelper_->set_initilal_context(ctx);
+
+    // percentage of reserved memory
+    if (dev_type) {
+      const auto env_var = env_var_name(dev_type, pool_reserve);
+      const size_t reserve = dmlc::GetEnv(env_var.c_str(), 5);
+      const size_t total = std::get<1>(contextHelper_->getMemoryInfo());
+      memory_allocation_limit_ = total * reserve / 100;
     }
   }
   /*!
    * \brief Default destructor.
    */
-  ~GPUPooledStorageManager() {
+  ~PooledStorageManager() override {
     ReleaseAll();
   }

   void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  void Free(Storage::Handle handle) override {
+    // Insert returned memory in cache
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    StoringMethod::InsertInCache(BucketingStrategy::get_bucket(handle.size), handle.dptr);
+  }

   void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    SET_DEVICE(device_store, contextHelper_, handle.ctx, true);
+    contextHelper_->Free(handle.dptr);
+    SET_GPU_PROFILER(profilerGPU, contextHelper_);
+    GPU_PROFILER_ON_FREE(profilerGPU, handle.dptr);
+    UNSET_DEVICE(device_store);
+    used_memory_ -= BucketingStrategy::RoundAllocSize(handle.size);
   }

-  void ReleaseAll() override;
-
- private:
-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = RoundAllocSize(handle.size);
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
+  void ReleaseAll() override {
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    ReleaseAllNoLock();
   }

-  // Round a value 'x' up to the next multiple of 'multiple'
-  size_t RoundToMultiple(size_t x, size_t multiple) {
-    size_t retVal = ((x + multiple - 1) / multiple) * multiple;
-    return retVal;
+ private:
+  void ReleaseAllNoLock(bool set_device = true) {
+    SET_DEVICE(device_store, contextHelper_, contextHelper_->initilal_context(), set_device);
+    used_memory_ -= StoringMethod::ReleaseAllNoLock(contextHelper_.get(), this);
+    UNSET_DEVICE(device_store);
   }

-  size_t RoundAllocSize(size_t size) {
-    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
-    size = RoundToMultiple(size, page_size_);
-    // To ensure proper freeing under some driver variants, make sure
-    // large allocs entirely occupy their slabs, which cannot then be
-    // locked by smaller permanent allocations sharing the slab.
-    if (size > large_alloc_round_size_)
-      size = RoundToMultiple(size, large_alloc_round_size_);
-    return size;
+  bool MemoryIsAvalable(size_t roundSize) const {
+    const auto free = contextHelper_->freeMemorySize();
+    return free > roundSize && memory_allocation_limit_ <= free - roundSize;
   }

- private:
+  // device type of used context
+  Context::DeviceType dev_type_;
   // used memory
   size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
-  // size that large allocations should be rounded to, for proper freeing.
-  size_t large_alloc_round_size_;
-  // percentage of reserved memory
-  int reserve_;
-  // number of devices
-  const size_t NDEV = 32;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::unordered_map<size_t, std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledStorageManager);
-};  // class GPUPooledStorageManager
-
-void GPUPooledStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
-  }
+  // minimum amount of memory, which will never be allocated
+  size_t memory_allocation_limit_ = 0;
+  // Pointer to the Helper, supporting some context-specific operations in GPU/CPU/CPUPinned context
+  std::unique_ptr<ContextHelper> contextHelper_;
+};
+
+template<typename BucketingStrategy, typename StoringMethod>
+void PooledStorageManager<BucketingStrategy, StoringMethod>::Alloc(Storage::Handle* handle) {
+  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+  const auto bucket_id = BucketingStrategy::get_bucket(handle->size);
+  size_t roundSize = 0;
+  auto reuse_pool = StoringMethod::GetMemStorage(bucket_id);
+  if (!reuse_pool) {
+    SET_DEVICE(device_store, contextHelper_, handle->ctx, true);
+    roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+    if (!MemoryIsAvalable(roundSize))
+      ReleaseAllNoLock(false);
+
+    void *ret = nullptr;
+    auto e = contextHelper_->Malloc(&ret, roundSize);
+    if (e) {
+      const std::string err(
+#if MXNET_USE_CUDA
+      dev_type_ == Context::kGPU?
+         cudaGetErrorString(static_cast<cudaError_t>(e)) :
+#endif
+         std::strerror(errno));

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle->size);
-  auto&& reuse_it = memory_pool_.find(size);
-  if (reuse_it == memory_pool_.end() || reuse_it->second.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
-      }
+      LOG(FATAL) << "Memory allocation failed " << err;
     }
-    used_memory_ += size;
+
+    UNSET_DEVICE(device_store);
+
+    used_memory_ += roundSize;
     handle->dptr = ret;
-    // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, false);
   } else {
-    auto&& reuse_pool = reuse_it->second;
-    auto ret = reuse_pool.back();
-    reuse_pool.pop_back();
-    handle->dptr = ret;
+    // Reusing memory
+    handle->dptr = reuse_pool->back();
+    reuse_pool->pop_back();
+  }
+#if MXNET_USE_CUDA
+  SET_GPU_PROFILER(profilerGPU, contextHelper_);
+  if (profilerGPU) {
+    if (reuse_pool)  // roundSize was not calculated
+      roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+
     // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, true);
+    profilerGPU->OnAlloc(*handle, roundSize, reuse_pool);
   }
+#endif
 }

-void GPUPooledStorageManager::Free(Storage::Handle handle) {
-  // Do nothing if dptr is nullptr. Otherwise, nullptr may be reused
-  // which can cause illegal memory access error.
-  if (handle.dptr == nullptr) return;

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle.size);
-  auto&& reuse_pool = memory_pool_[size];
-  reuse_pool.push_back(handle.dptr);
-}
+/*!
+ * \brief Base class for Rounding Method classes.
+ */
+class RoundHelper {
+ public:
+  virtual size_t get_size(size_t  /*bucket*/) const { return 0; }
+  virtual std::tuple<size_t, size_t> getContainerParam() const {
+     return std::tuple<size_t, size_t>(0, 0);
+  }

-void GPUPooledStorageManager::ReleaseAll() {
-  for (auto&& i : memory_pool_) {
-    for (auto&& j : i.second) {
-      Storage::Handle handle;
-      handle.dptr = j;
-      handle.size = i.first;
-      handle.ctx = initial_context_;
-      DirectFreeNoLock(handle);
+ protected:
+  void InitRoundHelper(const char* dev_type) {
+    const auto env_var = env_var_name(dev_type, pool_page_size);
+    page_size_ = dmlc::GetEnv(env_var.c_str(), 4096);
+    if (page_size_ < NDEV) {
+      LOG(FATAL) << env_var << " cannot be set to a value smaller than " << NDEV \
+                    << ". Got " << page_size_ << ".";
     }
   }
-  memory_pool_.clear();
-}
+
+  // page size
+  size_t page_size_ = 0;
+
+ private:
+  // number of devices
+  const size_t NDEV = 32;
+};  // class RoundHelper

 /*!
- * \brief Storage manager with a memory pool, with rounded size, on gpu.
+ * \brief Rounding method used by CPU/GPU mem pool.
+ * Round up small allocs to multiple of page_size_ or large_alloc_round_size_
+ */
+class RoundMultiple : protected RoundHelper {
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto env_var = env_var_name(dev_type, large_alloc_size);
+    large_alloc_round_size_ = dmlc::GetEnv(env_var.c_str(), 2*1024*1024);
+    if (large_alloc_round_size_ <= 0) {
+      LOG(FATAL) << env_var << " cannot be set to a value <= 0, found: "
+                 << large_alloc_round_size_;
+    }
+  }
+
+  size_t RoundAllocSize(size_t size) const {
+    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
+    size = RoundToMultiple(size, page_size_);
+    // To ensure proper freeing under some driver variants, make sure
+    // large allocs entirely occupy their slabs, which cannot then be
+    // locked by smaller permanent allocations sharing the slab.
+    return  size > large_alloc_round_size_? RoundToMultiple(size, large_alloc_round_size_) : size;
+  }
+  inline size_t get_bucket(size_t size) const                   { return RoundAllocSize(size); }
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return bucket_id; }
+
+ private:
+  // Round a value 'x' up to the next multiple of 'multiple'
+  inline static size_t RoundToMultiple(size_t x, size_t multiple) {
+    return ((x + multiple - 1) / multiple) * multiple;
+  }
+
+  // size that large allocations should be rounded to, for proper freeing.
+  size_t large_alloc_round_size_;
+};  // class RoundMultiple
+
+/*!
+ * \brief Rounding method used by CPU/GPU mem pool.
  *
- * This GPU mem pool uses a mixture of nearest pow2 (exponential) rounding and
+ * This Rounding method uses a mixture of nearest pow2 (exponential) rounding and
  * nearest multiple (linear) rounding to help alleviate the memory allocation stress
  * in which the default naive exact-size-match pool falls short, such as in variable-length
  * input/output cases like RNN workloads.
  *
  * \param cutoff the cutoff at which rounding is switched from exponential to linear. It's set
- * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable. Must be between 20 (1 MB)
- * and 34 (16 GB).
+ * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF / MXNET_CPU_MEM_POOL_ROUND_LINEAR_CUTOFF /
+ * MXNET_CPU_PINNED_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable.
+ * Must be between 20 (1 MB) and 34 (16 GB).
  * Suppose the cutoff is X, the memory size buckets look like this:
  * exp2(0), exp2(1), ..., exp2(X), 2*exp2(X), 3*exp2(X), ...
  */
-class GPUPooledRoundedStorageManager final : public StorageManager {
+class RoundPower2 : public RoundHelper {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledRoundedStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    cut_off_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF", 24);
-    if (page_size_ < 32) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than 32. " \
-                 << "Got: " << page_size_ << ".";
-    }
-    if (page_size_ != 1ul << common::ilog2ul(page_size_ - 1)) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE must be a power of 2. Got: " << page_size_ << ".";
+  size_t get_size(size_t bucket) const override {
+    return bucket <= cut_off_? 1ul << bucket : (bucket - cut_off_ + 1) << cut_off_;
+  }
+
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto log_pager_size = common::ilog2ul(page_size_ - 1);
+    if (page_size_ != 1ul << log_pager_size) {
+      LOG(FATAL) << env_var_name(dev_type, pool_page_size) \
+                 << " must be a power of 2. Got: " << page_size_ << ".";
     }
-    page_size_ = common::ilog2ul(page_size_ - 1);
+    page_size_ = log_pager_size;
+
+    const auto linear_cutoff = env_var_name(dev_type, round_linear_cutoff);
+    cut_off_ = dmlc::GetEnv(linear_cutoff.c_str(), 24);
     if (cut_off_ < 20 || cut_off_ > LOG2_MAX_MEM) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value " \
                  << "smaller than 20 or greater than " << LOG2_MAX_MEM << ". Got: " \
                  << cut_off_ << ".";
     }
     if (cut_off_ < page_size_) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
-                 << "smaller than log2 of MXNET_GPU_MEM_POOL_PAGE_SIZE. Got: " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value smaller than log2 of " \
+                 << env_var_name(dev_type, pool_page_size) << ". Got: " \
                  << cut_off_ << " vs " << page_size_ << ".";
     }
-    memory_pool_ = std::vector<std::vector<void*>>((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_);
-  }
-  /*!
-   * \brief Default destructor.
-   */
-  ~GPUPooledRoundedStorageManager() {
-    ReleaseAll();
   }

-  void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  inline size_t get_bucket(size_t s) const {
+    const size_t log_size = common::ilog2ul(s - 1);
+    if (log_size > cut_off_)
+      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;

-  void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    return std::max(log_size, page_size_);
   }

-  void ReleaseAll() override;
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return get_size(bucket_id); }
+  inline size_t RoundAllocSize(size_t size) const { return get_size(get_bucket(size)); }
+  std::tuple<size_t, size_t> getContainerParam() const override {
+    return std::make_tuple((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_,
+                       get_bucket(page_size_) - 1);
+  }

  private:
-  inline int div_pow2_round_up(size_t s, int divisor_log2) {
+  inline static int div_pow2_round_up(size_t s, int divisor_log2) {
     // (1025, 10) -> 2
     // (2048, 10) -> 2
     // (2049, 10) -> 3
-    size_t result = s >> divisor_log2;
+    const size_t result = s >> divisor_log2;
     return static_cast<int>(result + (s > (result << divisor_log2) ? 1 : 0));
   }
-  inline int get_bucket(size_t s) {
-    int log_size = common::ilog2ul(s - 1);
-    if (log_size > static_cast<int>(cut_off_))
-      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;
-    else
-      return std::max(log_size, static_cast<int>(page_size_));
-  }
-  inline size_t get_size(int bucket) {
-    if (bucket <= static_cast<int>(cut_off_))
-      return 1ul << bucket;
-    else
-      return (bucket - cut_off_ + 1) * (1ul << cut_off_);
-  }

-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = get_size(get_bucket(handle.size));
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
-  }
-
- private:
   // log2 of maximum page size. 16GB
   const size_t LOG2_MAX_MEM = 34;
-  // address width in bits
-  static const int addr_width = sizeof(size_t) * 8;
-  // used memory
-  size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
   // log2 of memory size before switching to exponential mode to linear mode
-  size_t cut_off_;
-  // percentage of reserved memory
-  int reserve_;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::vector<std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledRoundedStorageManager);
-};  // class GPUPooledRoundedStorageManager
-
-void GPUPooledRoundedStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
+  size_t cut_off_ = 0;
+};  // class RoundPower2
+
+
+/*!
+ * \brief Unordered map based storage container.
+ *  The pointers to the portions of same rounded sizes memory
+ *  allocated on CPU/GPU, are stored in separate vectors.
+ *  These sizes are used as keys for accessing the vectors,
+ *  which are the elements stored in an unordered map.
+ */
+class UnorderedMapContainer {
+ protected:
+  inline void InitContainer(const RoundHelper *p)   {}
+  inline void InsertInCache(size_t key, void *dptr) { memory_pool_[key].push_back(dptr); }
+
+  inline std::vector<void*> *GetMemStorage(size_t key) {
+    auto&& reuse_it = memory_pool_.find(key);
+    return reuse_it != memory_pool_.end() && reuse_it->second.size()? &reuse_it->second : nullptr;
   }

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  int bucket = get_bucket(handle->size);
-  size_t size = get_size(bucket);
-  auto&& reuse_pool = memory_pool_[bucket];
-  if (reuse_pool.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
+  size_t ReleaseAllNoLock(const ContextHelper *contextHelper, const RoundHelper * /*rndHelper*/) {
+    SET_GPU_PROFILER(profilerGPU, contextHelper);
+    size_t released_memory = 0;
+    for (auto&& i : memory_pool_) {
+      for (auto&& j : i.second) {
+        contextHelper->Free(j);
+        GPU_PROFILER_ON_FREE(profilerGPU, j);
       }

Review comment:
       Looks like this part of retry was dropped in the new code. This logic is for the purpose of solving memory fragmentation issue (i.e. no available consecutive space that's large enough, even when available space is enough)
   @andrei5055 could you add it back?


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 commented on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 commented on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654937596

(Here we do have only three lines, because the Pooled Storage Manager was not implemented for CPU_PINNED memory.)
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 commented on a change in pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 commented on a change in pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#discussion_r485994975


##########
File path: src/storage/pooled_storage_manager.h
##########
@@ -25,372 +25,418 @@
 #ifndef MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_
 #define MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_

-#if MXNET_USE_CUDA
-  #include <cuda_runtime.h>
-#endif  // MXNET_USE_CUDA
-
-#include <mxnet/base.h>
-#include <mxnet/storage.h>
-#include <unordered_map>
-#include <algorithm>
+#include <string>
 #include <vector>
+#include <algorithm>
 #include <mutex>
-#include <new>
+#include <tuple>
 #include "./storage_manager.h"
-#include "../common/cuda_utils.h"
-#include "../common/utils.h"
 #include "../profiler/storage_profiler.h"


 namespace mxnet {
 namespace storage {

+typedef enum {
+  pool_type,
+  pool_page_size,
+  large_alloc_size,
+  round_linear_cutoff,
+  pool_reserve,
+} env_var_type;
+
+const std::string env_var_name(const char* dev_type, env_var_type type);
+
 #if MXNET_USE_CUDA
+#define SET_DEVICE(device_store, contextHelper, ctx, flag) \
+      const auto *device_store = flag? contextHelper.get()->SetCurrentDevice(ctx) : nullptr;
+#define UNSET_DEVICE(device_store)    delete device_store
+
+#define SET_GPU_PROFILER(prof, contextHelper)                          \
+      auto prof = contextHelper->contextGPU()?                         \
+                  profiler::GpuDeviceStorageProfiler::Get() : nullptr; \
+      if (!prof->IsProfiling()) prof = nullptr
+
+#define GPU_PROFILER_ON_FREE(prof, pntr)    if (prof) prof->OnFree(pntr)
+#else
+// empty macros when MxNet is compiled without CUDA support
+#define SET_DEVICE(...)
+#define UNSET_DEVICE(...)
+#define SET_GPU_PROFILER(prof, ...)
+#define GPU_PROFILER_ON_FREE(prof, ...)
+#endif
+
 /*!
- * \brief Storage manager with a memory pool on gpu. Memory chunks are reused based on exact size
- * match.
+ * \brief Storage manager with a memory pool for GPU/CPU/CPUPunned memory chunks
+ * memory chunks which reused based on rounded size match.
+ * Rounding method is defined by the template parameter BucketingStrategy.
+ * Memory pool type is defined by the template parameter StoringMethod
+ * Allocation/freeing of memory is done by contextHelper_, which is the pointer
+ * to one of memory specific instance of the class, derived from ContextHelper
  */
-class GPUPooledStorageManager final : public StorageManager {
+template<typename BucketingStrategy, typename StoringMethod>
+class PooledStorageManager : public StorageManager,
+             public BucketingStrategy, public StoringMethod {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    large_alloc_round_size_ = dmlc::GetEnv("MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE", 2 * 1024 * 1024);
-    if (large_alloc_round_size_ <= 0) {
-      LOG(FATAL) << "MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE cannot be set to a value <= 0, found: "
-                 << large_alloc_round_size_;
+  explicit PooledStorageManager(const Context &ctx, int num_gpu_device) {
+    const char *dev_type = nullptr;
+    switch (dev_type_ = ctx.dev_type) {
+#if MXNET_USE_CUDA
+      case Context::kGPU:       contextHelper_ = std::make_unique<ContextHelperGPU>();
+                                dev_type = "GPU";
+                                break;
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+                                if (num_gpu_device > 1) {
+                                  contextHelper_ = std::make_unique<ContextHelperPinned>();
+                                  dev_type_ = Context::kGPU;
+                                  break;
+                                }
+#else
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+#endif
+                                dev_type_ = Context::kCPU;
+      case Context::kCPU:       contextHelper_ = std::make_unique<ContextHelperCPU>();
+                                dev_type = "CPU";
+      default:                  break;
     }
-    if (page_size_ < NDEV) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than " << NDEV \
-                 << ". Got " << page_size_ << ".";
+
+    BucketingStrategy::InitRoundHelper(dev_type);
+    StoringMethod::InitContainer(this);
+    contextHelper_->set_initilal_context(ctx);
+
+    // percentage of reserved memory
+    if (dev_type) {
+      const auto env_var = env_var_name(dev_type, pool_reserve);
+      const size_t reserve = dmlc::GetEnv(env_var.c_str(), 5);
+      const size_t total = std::get<1>(contextHelper_->getMemoryInfo());
+      memory_allocation_limit_ = total * reserve / 100;
     }
   }
   /*!
    * \brief Default destructor.
    */
-  ~GPUPooledStorageManager() {
+  ~PooledStorageManager() override {
     ReleaseAll();
   }

   void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  void Free(Storage::Handle handle) override {
+    // Insert returned memory in cache
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    StoringMethod::InsertInCache(BucketingStrategy::get_bucket(handle.size), handle.dptr);
+  }

   void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    SET_DEVICE(device_store, contextHelper_, handle.ctx, true);
+    contextHelper_->Free(handle.dptr);
+    SET_GPU_PROFILER(profilerGPU, contextHelper_);
+    GPU_PROFILER_ON_FREE(profilerGPU, handle.dptr);
+    UNSET_DEVICE(device_store);
+    used_memory_ -= BucketingStrategy::RoundAllocSize(handle.size);
   }

-  void ReleaseAll() override;
-
- private:
-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = RoundAllocSize(handle.size);
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
+  void ReleaseAll() override {
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    ReleaseAllNoLock();
   }

-  // Round a value 'x' up to the next multiple of 'multiple'
-  size_t RoundToMultiple(size_t x, size_t multiple) {
-    size_t retVal = ((x + multiple - 1) / multiple) * multiple;
-    return retVal;
+ private:
+  void ReleaseAllNoLock(bool set_device = true) {
+    SET_DEVICE(device_store, contextHelper_, contextHelper_->initilal_context(), set_device);
+    used_memory_ -= StoringMethod::ReleaseAllNoLock(contextHelper_.get(), this);
+    UNSET_DEVICE(device_store);
   }

-  size_t RoundAllocSize(size_t size) {
-    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
-    size = RoundToMultiple(size, page_size_);
-    // To ensure proper freeing under some driver variants, make sure
-    // large allocs entirely occupy their slabs, which cannot then be
-    // locked by smaller permanent allocations sharing the slab.
-    if (size > large_alloc_round_size_)
-      size = RoundToMultiple(size, large_alloc_round_size_);
-    return size;
+  bool MemoryIsAvalable(size_t roundSize) const {
+    const auto free = contextHelper_->freeMemorySize();
+    return free > roundSize && memory_allocation_limit_ <= free - roundSize;
   }

- private:
+  // device type of used context
+  Context::DeviceType dev_type_;
   // used memory
   size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
-  // size that large allocations should be rounded to, for proper freeing.
-  size_t large_alloc_round_size_;
-  // percentage of reserved memory
-  int reserve_;
-  // number of devices
-  const size_t NDEV = 32;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::unordered_map<size_t, std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledStorageManager);
-};  // class GPUPooledStorageManager
-
-void GPUPooledStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
-  }
+  // minimum amount of memory, which will never be allocated
+  size_t memory_allocation_limit_ = 0;
+  // Pointer to the Helper, supporting some context-specific operations in GPU/CPU/CPUPinned context
+  std::unique_ptr<ContextHelper> contextHelper_;
+};
+
+template<typename BucketingStrategy, typename StoringMethod>
+void PooledStorageManager<BucketingStrategy, StoringMethod>::Alloc(Storage::Handle* handle) {
+  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+  const auto bucket_id = BucketingStrategy::get_bucket(handle->size);
+  size_t roundSize = 0;
+  auto reuse_pool = StoringMethod::GetMemStorage(bucket_id);
+  if (!reuse_pool) {
+    SET_DEVICE(device_store, contextHelper_, handle->ctx, true);
+    roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+    if (!MemoryIsAvalable(roundSize))
+      ReleaseAllNoLock(false);
+
+    void *ret = nullptr;
+    auto e = contextHelper_->Malloc(&ret, roundSize);
+    if (e) {
+      const std::string err(
+#if MXNET_USE_CUDA
+      dev_type_ == Context::kGPU?
+         cudaGetErrorString(static_cast<cudaError_t>(e)) :
+#endif
+         std::strerror(errno));

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle->size);
-  auto&& reuse_it = memory_pool_.find(size);
-  if (reuse_it == memory_pool_.end() || reuse_it->second.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
-      }
+      LOG(FATAL) << "Memory allocation failed " << err;
     }
-    used_memory_ += size;
+
+    UNSET_DEVICE(device_store);
+
+    used_memory_ += roundSize;
     handle->dptr = ret;
-    // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, false);
   } else {
-    auto&& reuse_pool = reuse_it->second;
-    auto ret = reuse_pool.back();
-    reuse_pool.pop_back();
-    handle->dptr = ret;
+    // Reusing memory
+    handle->dptr = reuse_pool->back();
+    reuse_pool->pop_back();
+  }
+#if MXNET_USE_CUDA
+  SET_GPU_PROFILER(profilerGPU, contextHelper_);
+  if (profilerGPU) {
+    if (reuse_pool)  // roundSize was not calculated
+      roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+
     // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, true);
+    profilerGPU->OnAlloc(*handle, roundSize, reuse_pool);
   }
+#endif
 }

-void GPUPooledStorageManager::Free(Storage::Handle handle) {
-  // Do nothing if dptr is nullptr. Otherwise, nullptr may be reused
-  // which can cause illegal memory access error.
-  if (handle.dptr == nullptr) return;

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle.size);
-  auto&& reuse_pool = memory_pool_[size];
-  reuse_pool.push_back(handle.dptr);
-}
+/*!
+ * \brief Base class for Rounding Method classes.
+ */
+class RoundHelper {
+ public:
+  virtual size_t get_size(size_t  /*bucket*/) const { return 0; }
+  virtual std::tuple<size_t, size_t> getContainerParam() const {
+     return std::tuple<size_t, size_t>(0, 0);
+  }

-void GPUPooledStorageManager::ReleaseAll() {
-  for (auto&& i : memory_pool_) {
-    for (auto&& j : i.second) {
-      Storage::Handle handle;
-      handle.dptr = j;
-      handle.size = i.first;
-      handle.ctx = initial_context_;
-      DirectFreeNoLock(handle);
+ protected:
+  void InitRoundHelper(const char* dev_type) {
+    const auto env_var = env_var_name(dev_type, pool_page_size);
+    page_size_ = dmlc::GetEnv(env_var.c_str(), 4096);
+    if (page_size_ < NDEV) {
+      LOG(FATAL) << env_var << " cannot be set to a value smaller than " << NDEV \
+                    << ". Got " << page_size_ << ".";
     }
   }
-  memory_pool_.clear();
-}
+
+  // page size
+  size_t page_size_ = 0;
+
+ private:
+  // number of devices
+  const size_t NDEV = 32;
+};  // class RoundHelper

 /*!
- * \brief Storage manager with a memory pool, with rounded size, on gpu.
+ * \brief Rounding method used by CPU/GPU mem pool.
+ * Round up small allocs to multiple of page_size_ or large_alloc_round_size_
+ */
+class RoundMultiple : protected RoundHelper {
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto env_var = env_var_name(dev_type, large_alloc_size);
+    large_alloc_round_size_ = dmlc::GetEnv(env_var.c_str(), 2*1024*1024);
+    if (large_alloc_round_size_ <= 0) {
+      LOG(FATAL) << env_var << " cannot be set to a value <= 0, found: "
+                 << large_alloc_round_size_;
+    }
+  }
+
+  size_t RoundAllocSize(size_t size) const {
+    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
+    size = RoundToMultiple(size, page_size_);
+    // To ensure proper freeing under some driver variants, make sure
+    // large allocs entirely occupy their slabs, which cannot then be
+    // locked by smaller permanent allocations sharing the slab.
+    return  size > large_alloc_round_size_? RoundToMultiple(size, large_alloc_round_size_) : size;
+  }
+  inline size_t get_bucket(size_t size) const                   { return RoundAllocSize(size); }
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return bucket_id; }
+
+ private:
+  // Round a value 'x' up to the next multiple of 'multiple'
+  inline static size_t RoundToMultiple(size_t x, size_t multiple) {
+    return ((x + multiple - 1) / multiple) * multiple;
+  }
+
+  // size that large allocations should be rounded to, for proper freeing.
+  size_t large_alloc_round_size_;
+};  // class RoundMultiple
+
+/*!
+ * \brief Rounding method used by CPU/GPU mem pool.
  *
- * This GPU mem pool uses a mixture of nearest pow2 (exponential) rounding and
+ * This Rounding method uses a mixture of nearest pow2 (exponential) rounding and
  * nearest multiple (linear) rounding to help alleviate the memory allocation stress
  * in which the default naive exact-size-match pool falls short, such as in variable-length
  * input/output cases like RNN workloads.
  *
  * \param cutoff the cutoff at which rounding is switched from exponential to linear. It's set
- * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable. Must be between 20 (1 MB)
- * and 34 (16 GB).
+ * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF / MXNET_CPU_MEM_POOL_ROUND_LINEAR_CUTOFF /
+ * MXNET_CPU_PINNED_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable.
+ * Must be between 20 (1 MB) and 34 (16 GB).
  * Suppose the cutoff is X, the memory size buckets look like this:
  * exp2(0), exp2(1), ..., exp2(X), 2*exp2(X), 3*exp2(X), ...
  */
-class GPUPooledRoundedStorageManager final : public StorageManager {
+class RoundPower2 : public RoundHelper {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledRoundedStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    cut_off_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF", 24);
-    if (page_size_ < 32) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than 32. " \
-                 << "Got: " << page_size_ << ".";
-    }
-    if (page_size_ != 1ul << common::ilog2ul(page_size_ - 1)) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE must be a power of 2. Got: " << page_size_ << ".";
+  size_t get_size(size_t bucket) const override {
+    return bucket <= cut_off_? 1ul << bucket : (bucket - cut_off_ + 1) << cut_off_;
+  }
+
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto log_pager_size = common::ilog2ul(page_size_ - 1);
+    if (page_size_ != 1ul << log_pager_size) {
+      LOG(FATAL) << env_var_name(dev_type, pool_page_size) \
+                 << " must be a power of 2. Got: " << page_size_ << ".";
     }
-    page_size_ = common::ilog2ul(page_size_ - 1);
+    page_size_ = log_pager_size;
+
+    const auto linear_cutoff = env_var_name(dev_type, round_linear_cutoff);
+    cut_off_ = dmlc::GetEnv(linear_cutoff.c_str(), 24);
     if (cut_off_ < 20 || cut_off_ > LOG2_MAX_MEM) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value " \
                  << "smaller than 20 or greater than " << LOG2_MAX_MEM << ". Got: " \
                  << cut_off_ << ".";
     }
     if (cut_off_ < page_size_) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
-                 << "smaller than log2 of MXNET_GPU_MEM_POOL_PAGE_SIZE. Got: " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value smaller than log2 of " \
+                 << env_var_name(dev_type, pool_page_size) << ". Got: " \
                  << cut_off_ << " vs " << page_size_ << ".";
     }
-    memory_pool_ = std::vector<std::vector<void*>>((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_);
-  }
-  /*!
-   * \brief Default destructor.
-   */
-  ~GPUPooledRoundedStorageManager() {
-    ReleaseAll();
   }

-  void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  inline size_t get_bucket(size_t s) const {
+    const size_t log_size = common::ilog2ul(s - 1);
+    if (log_size > cut_off_)
+      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;

-  void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    return std::max(log_size, page_size_);
   }

-  void ReleaseAll() override;
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return get_size(bucket_id); }
+  inline size_t RoundAllocSize(size_t size) const { return get_size(get_bucket(size)); }
+  std::tuple<size_t, size_t> getContainerParam() const override {
+    return std::make_tuple((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_,
+                       get_bucket(page_size_) - 1);
+  }

  private:
-  inline int div_pow2_round_up(size_t s, int divisor_log2) {
+  inline static int div_pow2_round_up(size_t s, int divisor_log2) {
     // (1025, 10) -> 2
     // (2048, 10) -> 2
     // (2049, 10) -> 3
-    size_t result = s >> divisor_log2;
+    const size_t result = s >> divisor_log2;
     return static_cast<int>(result + (s > (result << divisor_log2) ? 1 : 0));
   }
-  inline int get_bucket(size_t s) {
-    int log_size = common::ilog2ul(s - 1);
-    if (log_size > static_cast<int>(cut_off_))
-      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;
-    else
-      return std::max(log_size, static_cast<int>(page_size_));
-  }
-  inline size_t get_size(int bucket) {
-    if (bucket <= static_cast<int>(cut_off_))
-      return 1ul << bucket;
-    else
-      return (bucket - cut_off_ + 1) * (1ul << cut_off_);
-  }

-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = get_size(get_bucket(handle.size));
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
-  }
-
- private:
   // log2 of maximum page size. 16GB
   const size_t LOG2_MAX_MEM = 34;
-  // address width in bits
-  static const int addr_width = sizeof(size_t) * 8;
-  // used memory
-  size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
   // log2 of memory size before switching to exponential mode to linear mode
-  size_t cut_off_;
-  // percentage of reserved memory
-  int reserve_;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::vector<std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledRoundedStorageManager);
-};  // class GPUPooledRoundedStorageManager
-
-void GPUPooledRoundedStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
+  size_t cut_off_ = 0;
+};  // class RoundPower2
+
+
+/*!
+ * \brief Unordered map based storage container.
+ *  The pointers to the portions of same rounded sizes memory
+ *  allocated on CPU/GPU, are stored in separate vectors.
+ *  These sizes are used as keys for accessing the vectors,
+ *  which are the elements stored in an unordered map.
+ */
+class UnorderedMapContainer {
+ protected:
+  inline void InitContainer(const RoundHelper *p)   {}
+  inline void InsertInCache(size_t key, void *dptr) { memory_pool_[key].push_back(dptr); }
+
+  inline std::vector<void*> *GetMemStorage(size_t key) {
+    auto&& reuse_it = memory_pool_.find(key);
+    return reuse_it != memory_pool_.end() && reuse_it->second.size()? &reuse_it->second : nullptr;
   }

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  int bucket = get_bucket(handle->size);
-  size_t size = get_size(bucket);
-  auto&& reuse_pool = memory_pool_[bucket];
-  if (reuse_pool.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
+  size_t ReleaseAllNoLock(const ContextHelper *contextHelper, const RoundHelper * /*rndHelper*/) {
+    SET_GPU_PROFILER(profilerGPU, contextHelper);
+    size_t released_memory = 0;
+    for (auto&& i : memory_pool_) {
+      for (auto&& j : i.second) {
+        contextHelper->Free(j);
+        GPU_PROFILER_ON_FREE(profilerGPU, j);
       }

Review comment:
       Oh, sorry, I didn't notice that it was your change.

   In fact, my initial @NVidia implementation had these or very similar lines (and it's why I thought these lines were from my PR). But @ptrendx convinced me that they are useless. Also, I've done some experiments trying to find real-life cases where these lines actually work, and couldn't find any such cases. So I decided not to include them in my PR.


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 edited a comment on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 edited a comment on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654937596
**Please, for now ignore graphs for CPU and CPU_PINNED memory. I am not sure why, but I don't see 2x run time improvement for newly implemented Pooled Storage Managers with respect to "Unpooled" ones, which I saw on my local NVidia branch. Perhaps, it's because I was using my workstation with limited amount of CPU memory. I will try to run the same benchmarks on the machine with more CPU memory and I will update the results.**

(Here we do have only three lines, because the Pooled Storage Manager was not implemented for CPU_PINNED memory.)
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] szha commented on a change in pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
szha commented on a change in pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#discussion_r485967200


##########
File path: src/storage/pooled_storage_manager.h
##########
@@ -25,372 +25,418 @@
 #ifndef MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_
 #define MXNET_STORAGE_POOLED_STORAGE_MANAGER_H_

-#if MXNET_USE_CUDA
-  #include <cuda_runtime.h>
-#endif  // MXNET_USE_CUDA
-
-#include <mxnet/base.h>
-#include <mxnet/storage.h>
-#include <unordered_map>
-#include <algorithm>
+#include <string>
 #include <vector>
+#include <algorithm>
 #include <mutex>
-#include <new>
+#include <tuple>
 #include "./storage_manager.h"
-#include "../common/cuda_utils.h"
-#include "../common/utils.h"
 #include "../profiler/storage_profiler.h"


 namespace mxnet {
 namespace storage {

+typedef enum {
+  pool_type,
+  pool_page_size,
+  large_alloc_size,
+  round_linear_cutoff,
+  pool_reserve,
+} env_var_type;
+
+const std::string env_var_name(const char* dev_type, env_var_type type);
+
 #if MXNET_USE_CUDA
+#define SET_DEVICE(device_store, contextHelper, ctx, flag) \
+      const auto *device_store = flag? contextHelper.get()->SetCurrentDevice(ctx) : nullptr;
+#define UNSET_DEVICE(device_store)    delete device_store
+
+#define SET_GPU_PROFILER(prof, contextHelper)                          \
+      auto prof = contextHelper->contextGPU()?                         \
+                  profiler::GpuDeviceStorageProfiler::Get() : nullptr; \
+      if (!prof->IsProfiling()) prof = nullptr
+
+#define GPU_PROFILER_ON_FREE(prof, pntr)    if (prof) prof->OnFree(pntr)
+#else
+// empty macros when MxNet is compiled without CUDA support
+#define SET_DEVICE(...)
+#define UNSET_DEVICE(...)
+#define SET_GPU_PROFILER(prof, ...)
+#define GPU_PROFILER_ON_FREE(prof, ...)
+#endif
+
 /*!
- * \brief Storage manager with a memory pool on gpu. Memory chunks are reused based on exact size
- * match.
+ * \brief Storage manager with a memory pool for GPU/CPU/CPUPunned memory chunks
+ * memory chunks which reused based on rounded size match.
+ * Rounding method is defined by the template parameter BucketingStrategy.
+ * Memory pool type is defined by the template parameter StoringMethod
+ * Allocation/freeing of memory is done by contextHelper_, which is the pointer
+ * to one of memory specific instance of the class, derived from ContextHelper
  */
-class GPUPooledStorageManager final : public StorageManager {
+template<typename BucketingStrategy, typename StoringMethod>
+class PooledStorageManager : public StorageManager,
+             public BucketingStrategy, public StoringMethod {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    large_alloc_round_size_ = dmlc::GetEnv("MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE", 2 * 1024 * 1024);
-    if (large_alloc_round_size_ <= 0) {
-      LOG(FATAL) << "MXNET_GPU_MEM_LARGE_ALLOC_ROUND_SIZE cannot be set to a value <= 0, found: "
-                 << large_alloc_round_size_;
+  explicit PooledStorageManager(const Context &ctx, int num_gpu_device) {
+    const char *dev_type = nullptr;
+    switch (dev_type_ = ctx.dev_type) {
+#if MXNET_USE_CUDA
+      case Context::kGPU:       contextHelper_ = std::make_unique<ContextHelperGPU>();
+                                dev_type = "GPU";
+                                break;
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+                                if (num_gpu_device > 1) {
+                                  contextHelper_ = std::make_unique<ContextHelperPinned>();
+                                  dev_type_ = Context::kGPU;
+                                  break;
+                                }
+#else
+      case Context::kCPUPinned: dev_type = "CPU_PINNED";
+#endif
+                                dev_type_ = Context::kCPU;
+      case Context::kCPU:       contextHelper_ = std::make_unique<ContextHelperCPU>();
+                                dev_type = "CPU";
+      default:                  break;
     }
-    if (page_size_ < NDEV) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than " << NDEV \
-                 << ". Got " << page_size_ << ".";
+
+    BucketingStrategy::InitRoundHelper(dev_type);
+    StoringMethod::InitContainer(this);
+    contextHelper_->set_initilal_context(ctx);
+
+    // percentage of reserved memory
+    if (dev_type) {
+      const auto env_var = env_var_name(dev_type, pool_reserve);
+      const size_t reserve = dmlc::GetEnv(env_var.c_str(), 5);
+      const size_t total = std::get<1>(contextHelper_->getMemoryInfo());
+      memory_allocation_limit_ = total * reserve / 100;
     }
   }
   /*!
    * \brief Default destructor.
    */
-  ~GPUPooledStorageManager() {
+  ~PooledStorageManager() override {
     ReleaseAll();
   }

   void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  void Free(Storage::Handle handle) override {
+    // Insert returned memory in cache
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    StoringMethod::InsertInCache(BucketingStrategy::get_bucket(handle.size), handle.dptr);
+  }

   void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    SET_DEVICE(device_store, contextHelper_, handle.ctx, true);
+    contextHelper_->Free(handle.dptr);
+    SET_GPU_PROFILER(profilerGPU, contextHelper_);
+    GPU_PROFILER_ON_FREE(profilerGPU, handle.dptr);
+    UNSET_DEVICE(device_store);
+    used_memory_ -= BucketingStrategy::RoundAllocSize(handle.size);
   }

-  void ReleaseAll() override;
-
- private:
-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = RoundAllocSize(handle.size);
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
+  void ReleaseAll() override {
+    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+    ReleaseAllNoLock();
   }

-  // Round a value 'x' up to the next multiple of 'multiple'
-  size_t RoundToMultiple(size_t x, size_t multiple) {
-    size_t retVal = ((x + multiple - 1) / multiple) * multiple;
-    return retVal;
+ private:
+  void ReleaseAllNoLock(bool set_device = true) {
+    SET_DEVICE(device_store, contextHelper_, contextHelper_->initilal_context(), set_device);
+    used_memory_ -= StoringMethod::ReleaseAllNoLock(contextHelper_.get(), this);
+    UNSET_DEVICE(device_store);
   }

-  size_t RoundAllocSize(size_t size) {
-    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
-    size = RoundToMultiple(size, page_size_);
-    // To ensure proper freeing under some driver variants, make sure
-    // large allocs entirely occupy their slabs, which cannot then be
-    // locked by smaller permanent allocations sharing the slab.
-    if (size > large_alloc_round_size_)
-      size = RoundToMultiple(size, large_alloc_round_size_);
-    return size;
+  bool MemoryIsAvalable(size_t roundSize) const {
+    const auto free = contextHelper_->freeMemorySize();
+    return free > roundSize && memory_allocation_limit_ <= free - roundSize;
   }

- private:
+  // device type of used context
+  Context::DeviceType dev_type_;
   // used memory
   size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
-  // size that large allocations should be rounded to, for proper freeing.
-  size_t large_alloc_round_size_;
-  // percentage of reserved memory
-  int reserve_;
-  // number of devices
-  const size_t NDEV = 32;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::unordered_map<size_t, std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledStorageManager);
-};  // class GPUPooledStorageManager
-
-void GPUPooledStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
-  }
+  // minimum amount of memory, which will never be allocated
+  size_t memory_allocation_limit_ = 0;
+  // Pointer to the Helper, supporting some context-specific operations in GPU/CPU/CPUPinned context
+  std::unique_ptr<ContextHelper> contextHelper_;
+};
+
+template<typename BucketingStrategy, typename StoringMethod>
+void PooledStorageManager<BucketingStrategy, StoringMethod>::Alloc(Storage::Handle* handle) {
+  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(dev_type_));
+  const auto bucket_id = BucketingStrategy::get_bucket(handle->size);
+  size_t roundSize = 0;
+  auto reuse_pool = StoringMethod::GetMemStorage(bucket_id);
+  if (!reuse_pool) {
+    SET_DEVICE(device_store, contextHelper_, handle->ctx, true);
+    roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+    if (!MemoryIsAvalable(roundSize))
+      ReleaseAllNoLock(false);
+
+    void *ret = nullptr;
+    auto e = contextHelper_->Malloc(&ret, roundSize);
+    if (e) {
+      const std::string err(
+#if MXNET_USE_CUDA
+      dev_type_ == Context::kGPU?
+         cudaGetErrorString(static_cast<cudaError_t>(e)) :
+#endif
+         std::strerror(errno));

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle->size);
-  auto&& reuse_it = memory_pool_.find(size);
-  if (reuse_it == memory_pool_.end() || reuse_it->second.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
-      }
+      LOG(FATAL) << "Memory allocation failed " << err;
     }
-    used_memory_ += size;
+
+    UNSET_DEVICE(device_store);
+
+    used_memory_ += roundSize;
     handle->dptr = ret;
-    // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, false);
   } else {
-    auto&& reuse_pool = reuse_it->second;
-    auto ret = reuse_pool.back();
-    reuse_pool.pop_back();
-    handle->dptr = ret;
+    // Reusing memory
+    handle->dptr = reuse_pool->back();
+    reuse_pool->pop_back();
+  }
+#if MXNET_USE_CUDA
+  SET_GPU_PROFILER(profilerGPU, contextHelper_);
+  if (profilerGPU) {
+    if (reuse_pool)  // roundSize was not calculated
+      roundSize = BucketingStrategy::RoundAllocSizeForBucket(bucket_id);
+
     // record the allocation event in the memory profiler
-    profiler::GpuDeviceStorageProfiler::Get()->OnAlloc(*handle, size, true);
+    profilerGPU->OnAlloc(*handle, roundSize, reuse_pool);
   }
+#endif
 }

-void GPUPooledStorageManager::Free(Storage::Handle handle) {
-  // Do nothing if dptr is nullptr. Otherwise, nullptr may be reused
-  // which can cause illegal memory access error.
-  if (handle.dptr == nullptr) return;

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  size_t size = RoundAllocSize(handle.size);
-  auto&& reuse_pool = memory_pool_[size];
-  reuse_pool.push_back(handle.dptr);
-}
+/*!
+ * \brief Base class for Rounding Method classes.
+ */
+class RoundHelper {
+ public:
+  virtual size_t get_size(size_t  /*bucket*/) const { return 0; }
+  virtual std::tuple<size_t, size_t> getContainerParam() const {
+     return std::tuple<size_t, size_t>(0, 0);
+  }

-void GPUPooledStorageManager::ReleaseAll() {
-  for (auto&& i : memory_pool_) {
-    for (auto&& j : i.second) {
-      Storage::Handle handle;
-      handle.dptr = j;
-      handle.size = i.first;
-      handle.ctx = initial_context_;
-      DirectFreeNoLock(handle);
+ protected:
+  void InitRoundHelper(const char* dev_type) {
+    const auto env_var = env_var_name(dev_type, pool_page_size);
+    page_size_ = dmlc::GetEnv(env_var.c_str(), 4096);
+    if (page_size_ < NDEV) {
+      LOG(FATAL) << env_var << " cannot be set to a value smaller than " << NDEV \
+                    << ". Got " << page_size_ << ".";
     }
   }
-  memory_pool_.clear();
-}
+
+  // page size
+  size_t page_size_ = 0;
+
+ private:
+  // number of devices
+  const size_t NDEV = 32;
+};  // class RoundHelper

 /*!
- * \brief Storage manager with a memory pool, with rounded size, on gpu.
+ * \brief Rounding method used by CPU/GPU mem pool.
+ * Round up small allocs to multiple of page_size_ or large_alloc_round_size_
+ */
+class RoundMultiple : protected RoundHelper {
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto env_var = env_var_name(dev_type, large_alloc_size);
+    large_alloc_round_size_ = dmlc::GetEnv(env_var.c_str(), 2*1024*1024);
+    if (large_alloc_round_size_ <= 0) {
+      LOG(FATAL) << env_var << " cannot be set to a value <= 0, found: "
+                 << large_alloc_round_size_;
+    }
+  }
+
+  size_t RoundAllocSize(size_t size) const {
+    // Round up small allocs to multiple of page_size_ to consolidate the pool lookups
+    size = RoundToMultiple(size, page_size_);
+    // To ensure proper freeing under some driver variants, make sure
+    // large allocs entirely occupy their slabs, which cannot then be
+    // locked by smaller permanent allocations sharing the slab.
+    return  size > large_alloc_round_size_? RoundToMultiple(size, large_alloc_round_size_) : size;
+  }
+  inline size_t get_bucket(size_t size) const                   { return RoundAllocSize(size); }
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return bucket_id; }
+
+ private:
+  // Round a value 'x' up to the next multiple of 'multiple'
+  inline static size_t RoundToMultiple(size_t x, size_t multiple) {
+    return ((x + multiple - 1) / multiple) * multiple;
+  }
+
+  // size that large allocations should be rounded to, for proper freeing.
+  size_t large_alloc_round_size_;
+};  // class RoundMultiple
+
+/*!
+ * \brief Rounding method used by CPU/GPU mem pool.
  *
- * This GPU mem pool uses a mixture of nearest pow2 (exponential) rounding and
+ * This Rounding method uses a mixture of nearest pow2 (exponential) rounding and
  * nearest multiple (linear) rounding to help alleviate the memory allocation stress
  * in which the default naive exact-size-match pool falls short, such as in variable-length
  * input/output cases like RNN workloads.
  *
  * \param cutoff the cutoff at which rounding is switched from exponential to linear. It's set
- * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable. Must be between 20 (1 MB)
- * and 34 (16 GB).
+ * through MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF / MXNET_CPU_MEM_POOL_ROUND_LINEAR_CUTOFF /
+ * MXNET_CPU_PINNED_MEM_POOL_ROUND_LINEAR_CUTOFF environment variable.
+ * Must be between 20 (1 MB) and 34 (16 GB).
  * Suppose the cutoff is X, the memory size buckets look like this:
  * exp2(0), exp2(1), ..., exp2(X), 2*exp2(X), 3*exp2(X), ...
  */
-class GPUPooledRoundedStorageManager final : public StorageManager {
+class RoundPower2 : public RoundHelper {
  public:
-  /*!
-   * \brief Default constructor.
-   *
-   * \param initial_context context used by this Storage Manager
-   */
-  explicit GPUPooledRoundedStorageManager(Context initial_context) :
-    initial_context_(initial_context) {
-    reserve_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_RESERVE", 5);
-    page_size_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_PAGE_SIZE", 4096);
-    cut_off_ = dmlc::GetEnv("MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF", 24);
-    if (page_size_ < 32) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE cannot be set to a value smaller than 32. " \
-                 << "Got: " << page_size_ << ".";
-    }
-    if (page_size_ != 1ul << common::ilog2ul(page_size_ - 1)) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_PAGE_SIZE must be a power of 2. Got: " << page_size_ << ".";
+  size_t get_size(size_t bucket) const override {
+    return bucket <= cut_off_? 1ul << bucket : (bucket - cut_off_ + 1) << cut_off_;
+  }
+
+ protected:
+  void InitRoundHelper(const char *dev_type) {
+    RoundHelper::InitRoundHelper(dev_type);
+    const auto log_pager_size = common::ilog2ul(page_size_ - 1);
+    if (page_size_ != 1ul << log_pager_size) {
+      LOG(FATAL) << env_var_name(dev_type, pool_page_size) \
+                 << " must be a power of 2. Got: " << page_size_ << ".";
     }
-    page_size_ = common::ilog2ul(page_size_ - 1);
+    page_size_ = log_pager_size;
+
+    const auto linear_cutoff = env_var_name(dev_type, round_linear_cutoff);
+    cut_off_ = dmlc::GetEnv(linear_cutoff.c_str(), 24);
     if (cut_off_ < 20 || cut_off_ > LOG2_MAX_MEM) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value " \
                  << "smaller than 20 or greater than " << LOG2_MAX_MEM << ". Got: " \
                  << cut_off_ << ".";
     }
     if (cut_off_ < page_size_) {
-      LOG(FATAL) << "MXNET_GPU_MEM_POOL_ROUND_LINEAR_CUTOFF cannot be set to a value " \
-                 << "smaller than log2 of MXNET_GPU_MEM_POOL_PAGE_SIZE. Got: " \
+      LOG(FATAL) << linear_cutoff << " cannot be set to a value smaller than log2 of " \
+                 << env_var_name(dev_type, pool_page_size) << ". Got: " \
                  << cut_off_ << " vs " << page_size_ << ".";
     }
-    memory_pool_ = std::vector<std::vector<void*>>((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_);
-  }
-  /*!
-   * \brief Default destructor.
-   */
-  ~GPUPooledRoundedStorageManager() {
-    ReleaseAll();
   }

-  void Alloc(Storage::Handle* handle) override;
-  void Free(Storage::Handle handle) override;
+  inline size_t get_bucket(size_t s) const {
+    const size_t log_size = common::ilog2ul(s - 1);
+    if (log_size > cut_off_)
+      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;

-  void DirectFree(Storage::Handle handle) override {
-    std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-    DirectFreeNoLock(handle);
+    return std::max(log_size, page_size_);
   }

-  void ReleaseAll() override;
+  inline size_t RoundAllocSizeForBucket(size_t bucket_id) const { return get_size(bucket_id); }
+  inline size_t RoundAllocSize(size_t size) const { return get_size(get_bucket(size)); }
+  std::tuple<size_t, size_t> getContainerParam() const override {
+    return std::make_tuple((1ul << (LOG2_MAX_MEM - cut_off_)) + cut_off_,
+                       get_bucket(page_size_) - 1);
+  }

  private:
-  inline int div_pow2_round_up(size_t s, int divisor_log2) {
+  inline static int div_pow2_round_up(size_t s, int divisor_log2) {
     // (1025, 10) -> 2
     // (2048, 10) -> 2
     // (2049, 10) -> 3
-    size_t result = s >> divisor_log2;
+    const size_t result = s >> divisor_log2;
     return static_cast<int>(result + (s > (result << divisor_log2) ? 1 : 0));
   }
-  inline int get_bucket(size_t s) {
-    int log_size = common::ilog2ul(s - 1);
-    if (log_size > static_cast<int>(cut_off_))
-      return div_pow2_round_up(s, cut_off_) - 1 + cut_off_;
-    else
-      return std::max(log_size, static_cast<int>(page_size_));
-  }
-  inline size_t get_size(int bucket) {
-    if (bucket <= static_cast<int>(cut_off_))
-      return 1ul << bucket;
-    else
-      return (bucket - cut_off_ + 1) * (1ul << cut_off_);
-  }

-  void DirectFreeNoLock(Storage::Handle handle) {
-    mxnet::common::cuda::DeviceStore device_store(handle.ctx.real_dev_id(), true);
-    cudaError_t err = cudaFree(handle.dptr);
-    size_t size = get_size(get_bucket(handle.size));
-    // ignore unloading error, as memory has already been recycled
-    if (err != cudaSuccess && err != cudaErrorCudartUnloading) {
-      LOG(FATAL) << "CUDA: " << cudaGetErrorString(err);
-    }
-    used_memory_ -= size;
-    profiler::GpuDeviceStorageProfiler::Get()->OnFree(handle);
-  }
-
- private:
   // log2 of maximum page size. 16GB
   const size_t LOG2_MAX_MEM = 34;
-  // address width in bits
-  static const int addr_width = sizeof(size_t) * 8;
-  // used memory
-  size_t used_memory_ = 0;
-  // page size
-  size_t page_size_;
   // log2 of memory size before switching to exponential mode to linear mode
-  size_t cut_off_;
-  // percentage of reserved memory
-  int reserve_;
-  // context used by this Storage Manager
-  const Context initial_context_;
-  // memory pool
-  std::vector<std::vector<void*>> memory_pool_;
-  DISALLOW_COPY_AND_ASSIGN(GPUPooledRoundedStorageManager);
-};  // class GPUPooledRoundedStorageManager
-
-void GPUPooledRoundedStorageManager::Alloc(Storage::Handle* handle) {
-  // Set dptr to nullptr when handle size is 0.
-  if (handle->size == 0) {
-    handle->dptr = nullptr;
-    return;
+  size_t cut_off_ = 0;
+};  // class RoundPower2
+
+
+/*!
+ * \brief Unordered map based storage container.
+ *  The pointers to the portions of same rounded sizes memory
+ *  allocated on CPU/GPU, are stored in separate vectors.
+ *  These sizes are used as keys for accessing the vectors,
+ *  which are the elements stored in an unordered map.
+ */
+class UnorderedMapContainer {
+ protected:
+  inline void InitContainer(const RoundHelper *p)   {}
+  inline void InsertInCache(size_t key, void *dptr) { memory_pool_[key].push_back(dptr); }
+
+  inline std::vector<void*> *GetMemStorage(size_t key) {
+    auto&& reuse_it = memory_pool_.find(key);
+    return reuse_it != memory_pool_.end() && reuse_it->second.size()? &reuse_it->second : nullptr;
   }

-  std::lock_guard<std::mutex> lock(Storage::Get()->GetMutex(Context::kGPU));
-  int bucket = get_bucket(handle->size);
-  size_t size = get_size(bucket);
-  auto&& reuse_pool = memory_pool_[bucket];
-  if (reuse_pool.size() == 0) {
-    mxnet::common::cuda::DeviceStore device_store(handle->ctx.real_dev_id(), true);
-    size_t free, total;
-    cudaMemGetInfo(&free, &total);
-    if (free <= total * reserve_ / 100 || size > free - total * reserve_ / 100)
-      ReleaseAll();
-
-    void* ret = nullptr;
-    cudaError_t e = cudaMalloc(&ret, size);
-    if (e != cudaSuccess) {
-      if (e == cudaErrorMemoryAllocation) {
-        ReleaseAll();
-        e = cudaMalloc(&ret, size);
-        if (e != cudaSuccess && e != cudaErrorCudartUnloading) {
-          LOG(FATAL) << "cudaMalloc retry failed: " << cudaGetErrorString(e);
-        }
-      } else if (e != cudaErrorCudartUnloading) {
-        LOG(FATAL) << "cudaMalloc failed: " << cudaGetErrorString(e);
+  size_t ReleaseAllNoLock(const ContextHelper *contextHelper, const RoundHelper * /*rndHelper*/) {
+    SET_GPU_PROFILER(profilerGPU, contextHelper);
+    size_t released_memory = 0;
+    for (auto&& i : memory_pool_) {
+      for (auto&& j : i.second) {
+        contextHelper->Free(j);
+        GPU_PROFILER_ON_FREE(profilerGPU, j);
       }

Review comment:
       It wasn't in your PR https://github.com/andrei5055/incubator-mxnet/blob/97dfc823d8b89751ff8be459a0357195e383a23d/src/storage/pooled_storage_manager.h#L178-L189

   I added it in https://github.com/apache/incubator-mxnet/pull/18987/files


----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [incubator-mxnet] andrei5055 edited a comment on pull request #18582: Refactoring of Pooled Storage Manager classes
Posted by GitBox <gi...@apache.org>.
andrei5055 edited a comment on pull request #18582:
URL: https://github.com/apache/incubator-mxnet/pull/18582#issuecomment-654937596
**Please, for now ignore graphs for CPU and CPU_PINNED memory. I am not sure why, but I don't see 2x run time improvement for newly implemented Pooled Storage Managers with respect to "Unpooled" ones, which I saw on my local NVidia branch. Perhaps, it's because I was using my workstation with limited amount of CPU memory. I will try to run the same benchmarks on the machine with more CPU memory and I will update the results.**


(Here we do have only three lines, because the Pooled Storage Manager was not implemented for CPU_PINNED memory.)
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org