You are viewing a plain text version of this content. The canonical link for it is here.
Posted to reviews@spark.apache.org by GitBox <gi...@apache.org> on 2020/12/22 06:49:30 UTC
[GitHub] [spark] LuciferYang commented on pull request #30663: [SPARK-33700][SQL] Avoid file meta reading when enableFilterPushDown is true and filters is empty for Orc
LuciferYang commented on pull request #30663:
URL: https://github.com/apache/spark/pull/30663#issuecomment-749378207
@HyukjinKwon @dongjoon-hyun
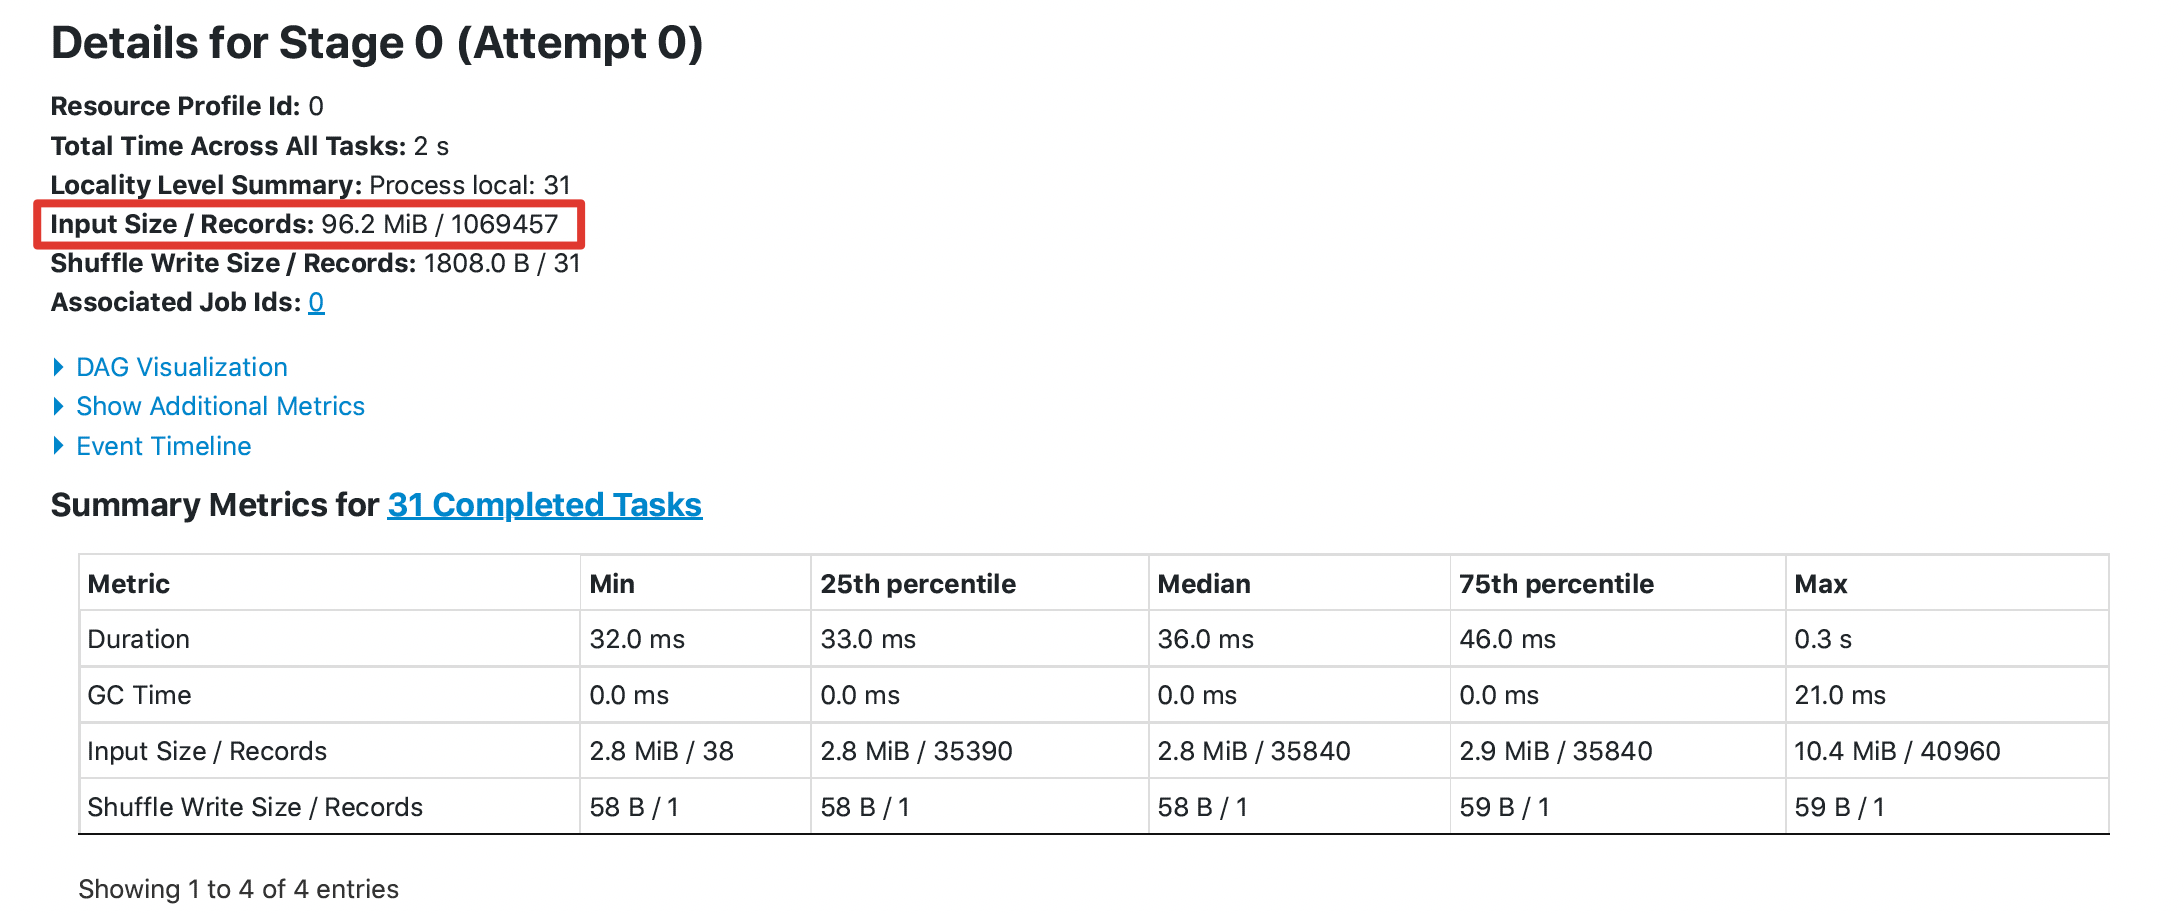
It seems that it is not easy to prove this optimization through UT. I did the following test, taking DataSourceV1 as an example:
1. 10 files and each file has 1100 columns , each file about 400m
2. Execute a simple query without filter `select count(xxx) from orc_table`
The key results are as follows:
**without this pr**
**with this pr**
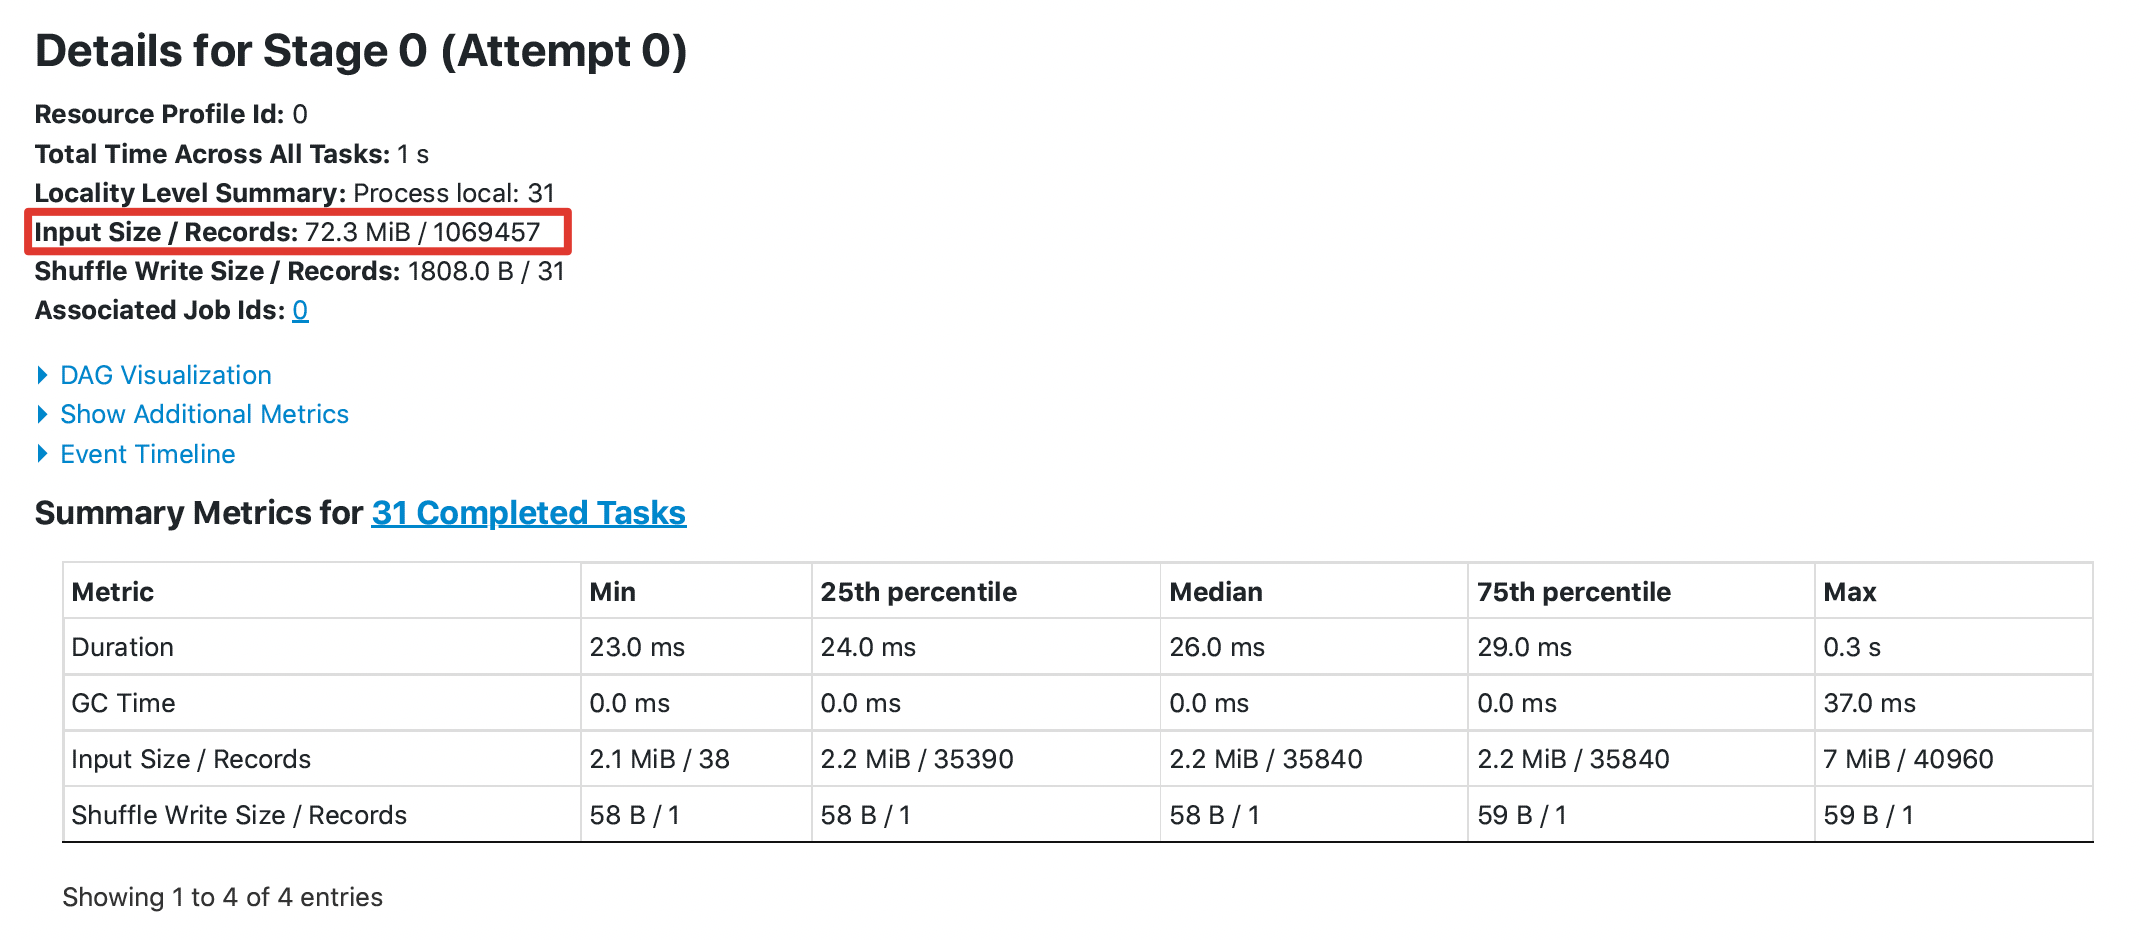
The `Input Size` from `96.2 MiB` to `72.3 MiB`, the `Total Time Across All Tasks` from 2s to 1s
----------------------------------------------------------------
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: reviews-unsubscribe@spark.apache.org
For additional commands, e-mail: reviews-help@spark.apache.org