You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@mxnet.apache.org by qk...@apache.org on 2017/08/13 21:11:15 UTC
[incubator-mxnet] branch master updated: [R] vignette update (#7437)
This is an automated email from the ASF dual-hosted git repository.
qkou pushed a commit to branch master
in repository https://gitbox.apache.org/repos/asf/incubator-mxnet.git
The following commit(s) were added to refs/heads/master by this push:
new 0142ea0 [R] vignette update (#7437)
0142ea0 is described below
commit 0142ea0f330393499ece834b9d7b6d5d00fd8f3c
Author: Qiang Kou (KK) <qk...@qkou.info>
AuthorDate: Sun Aug 13 21:11:12 2017 +0000
[R] vignette update (#7437)
---
...ckFunctionTutorial.Rmd => CallbackFunction.Rmd} | 19 +-
R-package/vignettes/CatsDogsFinetune.Rmd | 12 +-
R-package/vignettes/CharRnnModel.Rmd | 27 +--
R-package/vignettes/CustomIterator.Rmd | 207 ++++++++++++++++++
R-package/vignettes/CustomLossFunction.Rmd | 20 +-
.../classifyRealImageWithPretrainedModel.Rmd | 38 ++--
R-package/vignettes/fiveMinutesNeuralNetwork.Rmd | 12 +-
R-package/vignettes/mnistCompetition.Rmd | 82 +++----
R-package/vignettes/ndarray.Rmd | 148 +++++++++++++
R-package/vignettes/ndarrayAndSymbolTutorial.Rmd | 242 ---------------------
R-package/vignettes/symbol.Rmd | 103 +++++++++
11 files changed, 563 insertions(+), 347 deletions(-)
diff --git a/R-package/vignettes/CallbackFunctionTutorial.Rmd b/R-package/vignettes/CallbackFunction.Rmd
similarity index 93%
rename from R-package/vignettes/CallbackFunctionTutorial.Rmd
rename to R-package/vignettes/CallbackFunction.Rmd
index 91b4c09..12b7e28 100644
--- a/R-package/vignettes/CallbackFunctionTutorial.Rmd
+++ b/R-package/vignettes/CallbackFunction.Rmd
@@ -1,13 +1,9 @@
-MXNet R Tutorial for Callback Function
-======================================
+# Customized callback function
This vignette gives users a guideline for using and writing callback functions,
which can be very useful in model training.
-This tutorial is written in Rmarkdown. You can find the Rmarkdown source from [here](https://github.com/dmlc/mxnet/blob/master/R-package/vignettes/CallbackFunctionTutorial.Rmd)
-
-Model training example
-----------
+## Model training example
Let's begin from a small example. We can build and train a model using the following code:
@@ -32,8 +28,8 @@ model <- mx.model.FeedForward.create(
Besides, we provide two optional parameters, `batch.end.callback` and `epoch.end.callback`, which can provide great flexibility in model training.
-How to use callback functions
----------
+## How to use callback functions
+
Two callback functions are provided in this package:
@@ -76,8 +72,8 @@ head(logger$train)
head(logger$eval)
```
-How to write your own callback functions
-----------
+## How to write your own callback functions
+
You can find the source code for two callback functions from [here](https://github.com/dmlc/mxnet/blob/master/R-package/R/callback.R) and they can be used as your template:
@@ -159,3 +155,6 @@ model <- mx.model.FeedForward.create(
```
You can see once the validation metric goes below the threshold we set, the training process will stop early.
+
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/CatsDogsFinetune.Rmd b/R-package/vignettes/CatsDogsFinetune.Rmd
index 95f90be..680b5a3 100644
--- a/R-package/vignettes/CatsDogsFinetune.Rmd
+++ b/R-package/vignettes/CatsDogsFinetune.Rmd
@@ -1,5 +1,4 @@
-Dogs vs. Cats classification with mxnet and R
-=============================================
+# Dogs vs. Cats classification with mxnet and R
## Packages and prerequisites
@@ -13,11 +12,11 @@ It is an end-to-end R solution for the dogs vs cats Kaggle competition (https://
and it can be used as an example for fine-tuning.
All the code has been test on Ubuntu 16.04.
-
```{r, echo=FALSE}
knitr::opts_chunk$set(eval = FALSE)
```
+
```{r}
library(imager)
library(mxnet)
@@ -106,7 +105,7 @@ Map(function(x, y) {
### Creating .rec files
-```{r, eval = FALSE}
+```{r}
cat_files <- list.files("train_pad_224x224/cat/", recursive=TRUE)
cat_files <- paste0("cat/", cat_files)
@@ -169,6 +168,8 @@ and we need to replace the last fully connected layer with a new layer for 2 cla
```{r}
+download.file('http://data.dmlc.ml/data/Inception.zip', destfile = 'Inception.zip')
+unzip("Inception.zip")
inception_bn <- mx.model.load("./Inception-BN", iteration = 126)
symbol <- inception_bn$symbol
@@ -266,3 +267,6 @@ probs <- t(do.call(cbind, probs))
preds <- data.frame(id = 1:12500, label = probs[, 2])
write.csv(preds, "subm.csv", row.names = FALSE, quote = FALSE)
```
+
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/CharRnnModel.Rmd b/R-package/vignettes/CharRnnModel.Rmd
index 9dc00a3..9d3fd5c 100644
--- a/R-package/vignettes/CharRnnModel.Rmd
+++ b/R-package/vignettes/CharRnnModel.Rmd
@@ -1,11 +1,7 @@
-Char RNN Example
-=============================================
+# Char RNN Example
-This example aims to show how to use the LSTM model to build a char-level language model, and generate text from it. We use a tiny shakespeare text for demo purpose. Data can be found at [here](https://github.com/dmlc/web-data/tree/master/mxnet/tinyshakespeare).
-This tutorial is written in Rmarkdown. You can find the Rmarkdown source from [here](https://github.com/dmlc/mxnet/blob/master/R-package/vignettes/CharRnnModel.Rmd).
-Load Data
----------
+## Load Data
First of all, load in the data and preprocess it.
@@ -148,8 +144,8 @@ X.train <- list(data=X.train.data, label=X.train.label)
X.val <- list(data=X.val.data, label=X.val.label)
```
-Training Model
---------------
+## Training Model
+
In `mxnet`, we have a function called `mx.lstm` so that users can build a general lstm model.
@@ -172,8 +168,8 @@ model <- mx.lstm(X.train, X.val,
```
-Inference from model
---------------------
+## Inference from model
+
Some helper functions for random sample.
@@ -258,14 +254,19 @@ for (i in (1:(seq.len-1))) {
message(out)
```
The result:
+
```
ah not a drobl greens
Settled asing lately sistering sounted to their hight
```
-Other RNN models
-----------------
+## Other RNN models
+
In `mxnet`, other RNN models like custom RNN and gru is also provided.
- For **custom RNN model**, you can replace `mx.lstm` with `mx.rnn` to train rnn model. Also, you can replace `mx.lstm.inference` and `mx.lstm.forward` with `mx.rnn.inference` and `mx.rnn.forward` to inference from rnn model and get forward result from the inference model.
-- For **GRU model**, you can replace `mx.lstm` with `mx.gru` to train gru model. Also, you can replace `mx.lstm.inference` and `mx.lstm.forward` with `mx.gru.inference` and `mx.gru.forward` to inference from gru model and get forward result from the inference model.
\ No newline at end of file
+- For **GRU model**, you can replace `mx.lstm` with `mx.gru` to train gru model. Also, you can replace `mx.lstm.inference` and `mx.lstm.forward` with `mx.gru.inference` and `mx.gru.forward` to inference from gru model and get forward result from the inference model.
+
+
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
\ No newline at end of file
diff --git a/R-package/vignettes/CustomIterator.Rmd b/R-package/vignettes/CustomIterator.Rmd
new file mode 100644
index 0000000..22ac90f
--- /dev/null
+++ b/R-package/vignettes/CustomIterator.Rmd
@@ -0,0 +1,207 @@
+# Customized iterator
+
+
+This tutorial provides a guideline on how to use and write custom iterators, which can very useful when having a dataset that does not fit into memory.
+
+## Getting the data
+
+The data we are going to use is the [MNIST dataset](http://yann.lecun.com/exdb/mnist/) in CSV format, which can be found from [here](https://www.kaggle.com/c/digit-recognizer/data).
+
+To download the data:
+
+```{r}
+download.file('https://s3-us-west-2.amazonaws.com/apache-mxnet/R/data/mnist_csv.zip',
+ destfile = 'mnist_csv.zip')
+unzip('mnist_csv.zip', exdir = '.')
+```
+
+You'll get two files, `mnist_train.csv` that contains 60.000 examples of hand written numbers and `mxnist_test.csv` that contains 10.000 examples. The first element of each line in the CSV is the label, which is a number between 0 and 9. The rest of the line are 784 numbers between 0 and 255, corresponding to the levels of grey of a matrix of 28x28. Therefore, each line contains an image of 28x28 pixels of a hand written number and its true label.
+
+## Custom CSV Iterator
+
+Next we are going to create a custom CSV Iterator based on the [C++ CSVIterator class](https://github.com/dmlc/mxnet/blob/master/src/io/iter_csv.cc).
+
+For that we are going to use the R function `mx.io.CSVIter` as a base class. This class has as parameters `data.csv, data.shape, batch.size` and two main functions, `iter.next()` that calls the iterator in the next batch of data and `value()` that returns the train data and the label.
+
+The R Custom Iterator needs to inherit from the C++ data iterator class, for that we used the class `Rcpp_MXArrayDataIter` extracted with RCPP. Also, it needs to have the same parameters: `data.csv, data.shape, batch.size`. Apart from that, we can also add the field `iter`, which is the CSV Iterator that we are going to expand.
+
+```{r, eval=FALSE}
+CustomCSVIter <- setRefClass("CustomCSVIter",
+ fields=c("iter", "data.csv", "data.shape", "batch.size"),
+ contains = "Rcpp_MXArrayDataIter",
+ #...
+ )
+```
+
+The next step is to initialize the class. For that we call the base `mx.io.CSVIter` and fill the rest of the fields.
+
+```{r, eval=FALSE}
+CustomCSVIter <- setRefClass("CustomCSVIter",
+ fields=c("iter", "data.csv", "data.shape", "batch.size"),
+ contains = "Rcpp_MXArrayDataIter",
+ methods=list(
+ initialize=function(iter, data.csv, data.shape, batch.size){
+ feature_len <- data.shape*data.shape + 1
+ csv_iter <- mx.io.CSVIter(data.csv=data.csv, data.shape=c(feature_len), batch.size=batch.size)
+ .self$iter <- csv_iter
+ .self$data.csv <- data.csv
+ .self$data.shape <- data.shape
+ .self$batch.size <- batch.size
+ .self
+ },
+ #...
+ )
+ )
+```
+
+So far there is no difference between the original class and the custom class. Let's implement the function `value()`. In this case what we are going to do is transform the data that comes from the original class as an array of 785 numbers into a matrix of 28x28 and a label. We will also normalize the training data to be between 0 and 1.
+
+```{r, eval=FALSE}
+CustomCSVIter <- setRefClass("CustomCSVIter",
+ fields=c("iter", "data.csv", "data.shape", "batch.size"),
+ contains = "Rcpp_MXArrayDataIter",
+ methods=list(
+ initialize=function(iter, data.csv, data.shape, batch.size){
+ feature_len <- data.shape*data.shape + 1
+ csv_iter <- mx.io.CSVIter(data.csv=data.csv, data.shape=c(feature_len), batch.size=batch.size)
+ .self$iter <- csv_iter
+ .self$data.csv <- data.csv
+ .self$data.shape <- data.shape
+ .self$batch.size <- batch.size
+ .self
+ },
+ value=function(){
+ val <- as.array(.self$iter$value()$data)
+ val.x <- val[-1,]
+ val.y <- val[1,]
+ val.x <- val.x/255
+ dim(val.x) <- c(data.shape, data.shape, 1, ncol(val.x))
+ val.x <- mx.nd.array(val.x)
+ val.y <- mx.nd.array(val.y)
+ list(data=val.x, label=val.y)
+ },
+ #...
+ )
+ )
+```
+Finally we are going to add the rest of the functions needed for the training to work correctly. The final `CustomCSVIter` looks like this:
+
+```{r}
+CustomCSVIter <- setRefClass("CustomCSVIter",
+ fields=c("iter", "data.csv", "data.shape", "batch.size"),
+ contains = "Rcpp_MXArrayDataIter",
+ methods=list(
+ initialize=function(iter, data.csv, data.shape, batch.size){
+ feature_len <- data.shape*data.shape + 1
+ csv_iter <- mx.io.CSVIter(data.csv=data.csv, data.shape=c(feature_len), batch.size=batch.size)
+ .self$iter <- csv_iter
+ .self$data.csv <- data.csv
+ .self$data.shape <- data.shape
+ .self$batch.size <- batch.size
+ .self
+ },
+ value=function(){
+ val <- as.array(.self$iter$value()$data)
+ val.x <- val[-1,]
+ val.y <- val[1,]
+ val.x <- val.x/255
+ dim(val.x) <- c(data.shape, data.shape, 1, ncol(val.x))
+ val.x <- mx.nd.array(val.x)
+ val.y <- mx.nd.array(val.y)
+ list(data=val.x, label=val.y)
+ },
+ iter.next=function(){
+ .self$iter$iter.next()
+ },
+ reset=function(){
+ .self$iter$reset()
+ },
+ num.pad=function(){
+ .self$iter$num.pad()
+ },
+ finalize=function(){
+ .self$iter$finalize()
+ }
+ )
+ )
+```
+
+To call the class we can just do:
+
+```{r}
+batch.size <- 100
+train.iter <- CustomCSVIter$new(iter = NULL, data.csv = "mnist_train.csv", data.shape = 28, batch.size = batch.size)
+```
+
+## CNN Model
+
+
+For this tutorial we are going to use the known LeNet architecture:
+
+```{r}
+library(mxnet)
+lenet.model <- function(){
+ data <- mx.symbol.Variable('data')
+ conv1 <- mx.symbol.Convolution(data=data, kernel=c(5,5), num_filter=20) #first conv
+ tanh1 <- mx.symbol.Activation(data=conv1, act_type="tanh")
+ pool1 <- mx.symbol.Pooling(data=tanh1, pool_type="max", kernel=c(2,2), stride=c(2,2))
+ conv2 <- mx.symbol.Convolution(data=pool1, kernel=c(5,5), num_filter=50)# second conv
+ tanh2 <- mx.symbol.Activation(data=conv2, act_type="tanh")
+ pool2 <- mx.symbol.Pooling(data=tanh2, pool_type="max", kernel=c(2,2), stride=c(2,2))
+ flatten <- mx.symbol.Flatten(data=pool2)
+ fc1 <- mx.symbol.FullyConnected(data=flatten, num_hidden=100) # first fullc
+ tanh3 <- mx.symbol.Activation(data=fc1, act_type="tanh")
+ fc2 <- mx.symbol.FullyConnected(data=tanh3, num_hidden=10) # second fullc
+ network <- mx.symbol.SoftmaxOutput(data=fc2) # loss
+ network
+}
+network <- lenet.model()
+```
+
+## Training with the Custom Iterator
+
+Finally, we can directly add the custom iterator as the training data source.
+
+```{r, eval=FALSE}
+model <- mx.model.FeedForward.create(symbol=network,
+ X=train.iter,
+ ctx=mx.gpu(0),
+ num.round=10,
+ array.batch.size=batch.size,
+ learning.rate=0.1,
+ momentum=0.9,
+ eval.metric=mx.metric.accuracy,
+ wd=0.00001,
+ batch.end.callback=mx.callback.log.speedometer(batch.size, frequency = 100)
+ )
+```
+
+The last 2 iterations with a K80 GPU looks like this:
+
+```
+## [8] Train-accuracy=0.998866666666667
+## Batch [100] Speed: 15413.0104454713 samples/sec Train-accuracy=0.999
+## Batch [200] Speed: 16629.3412459049 samples/sec Train-accuracy=0.99935
+## Batch [300] Speed: 18412.6900509319 samples/sec Train-accuracy=0.9995
+## Batch [400] Speed: 16757.2882328335 samples/sec Train-accuracy=0.999425
+## Batch [500] Speed: 17116.6529207406 samples/sec Train-accuracy=0.99946
+## Batch [600] Speed: 19627.589505195 samples/sec Train-accuracy=0.99945
+## [9] Train-accuracy=0.9991
+## Batch [100] Speed: 18971.5745536982 samples/sec Train-accuracy=0.9992
+## Batch [200] Speed: 15554.8822435383 samples/sec Train-accuracy=0.99955
+## Batch [300] Speed: 18327.6950115053 samples/sec Train-accuracy=0.9997
+## Batch [400] Speed: 17103.0705411788 samples/sec Train-accuracy=0.9997
+## Batch [500] Speed: 15104.8656902394 samples/sec Train-accuracy=0.99974
+## Batch [600] Speed: 13818.7899518255 samples/sec Train-accuracy=0.99975
+## [10] Train-accuracy=0.99975
+```
+
+## Conclusion
+
+
+We have shown how to create a custom CSV Iterator by extending the class `mx.io.CSVIter`. In our class, we iteratively read from a CSV file a batch of data that will be transformed and then processed in the stochastic gradient descent optimization. That way, we are able to manage CSV files that are bigger than the memory of the machine we are using.
+
+Based of this custom iterator, we can also create data loaders that internally transform or expand the data, allowing to manage files of any size.
+
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/CustomLossFunction.Rmd b/R-package/vignettes/CustomLossFunction.Rmd
index 1817109..85e8825 100644
--- a/R-package/vignettes/CustomLossFunction.Rmd
+++ b/R-package/vignettes/CustomLossFunction.Rmd
@@ -1,18 +1,8 @@
----
-title: "Customized loss function"
-output:
- md_document:
- variant: markdown_github
----
-
-```{r setup, include=FALSE}
-knitr::opts_chunk$set(echo = TRUE)
-```
+# Customized loss function
This tutorial provides guidelines for using customized loss function in network construction.
-Model Training Example
-----------
+## Model Training Example
Let's begin with a small regression example. We can build and train a regression model with the following code:
@@ -56,8 +46,7 @@ Besides the `LinearRegressionOutput`, we also provide `LogisticRegressionOutput`
However, this might not be enough for real-world models. You can provide your own loss function
by using `mx.symbol.MakeLoss` when constructing the network.
-How to Use Your Own Loss Function
----------
+## How to Use Your Own Loss Function
We still use our previous example, but this time we use `mx.symbol.MakeLoss` to minimize the `(pred-label)^2`
@@ -157,3 +146,6 @@ pred6 <- predict(model6, test.x)
sum(abs(test.y - pred6[1,])) / length(test.y)
```
+We got the same result as expected.
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/classifyRealImageWithPretrainedModel.Rmd b/R-package/vignettes/classifyRealImageWithPretrainedModel.Rmd
index f9d14d9..ff631e0 100644
--- a/R-package/vignettes/classifyRealImageWithPretrainedModel.Rmd
+++ b/R-package/vignettes/classifyRealImageWithPretrainedModel.Rmd
@@ -1,5 +1,5 @@
-Classify Real-world Images with Pre-trained Model
-=================================================
+# Classify Real-world Images with Pre-trained Model
+
MXNet is a flexible and efficient deep learning framework. One of the cool things that a deep learning
algorithm can do is to classify real world images.
@@ -10,12 +10,7 @@ real world image. The network architecture is described in [1].
The pre-trained Inception-BatchNorm network can be downloaded from [this link](http://data.mxnet.io/mxnet/data/Inception.zip).
This model gives the recent state-of-art prediction accuracy on the image net dataset.
-Preface
--------
-This tutorial is written in Rmarkdown. You can find the Rmarkdown source from [here](https://github.com/dmlc/mxnet/blob/master/R-package/vignettes/classifyRealImageWithPretrainedModel.Rmd)
-
-Package Loading
----------------
+## Package Loading
To get started, we load the `mxnet` package first.
@@ -29,13 +24,15 @@ In this example, we also need the imager package to load and preprocess the imag
require(imager)
```
-Load the Pretrained Model
--------------------------
+## Load the Pretrained Model
+
Make sure you unzip the pre-trained model in current folder. And we can use the model
loading function to load the model into R.
```{r}
+download.file('http://data.dmlc.ml/data/Inception.zip', destfile = 'Inception.zip')
+unzip("Inception.zip")
model <- mx.model.load("Inception/Inception_BN", iteration = 39)
```
@@ -45,8 +42,8 @@ We also need to load in the mean image, which is used for preprocessing using ``
mean.img <- as.array(mx.nd.load("Inception/mean_224.nd")[["mean_img"]])
```
-Load and Preprocess the Image
------------------------------
+## Load and Preprocess the Image
+
Now we are ready to classify a real image. In this example, we simply take the parrots image
from imager package. But you can always change it to other images.
@@ -91,8 +88,8 @@ We use the defined preprocessing function to get the normalized image.
normed <- preproc.image(im, mean.img)
```
-Classify the Image
-------------------
+## Classify the Image
+
Now we are ready to classify the image! We can use the predict function
to get the probability over classes.
@@ -105,6 +102,7 @@ As you can see ```prob``` is a 1 times 1000 array, which gives the probability
over the 1000 image classes of the input.
We can use the ```max.col``` on the transpose of prob. get the class index.
+
```{r}
max.idx <- max.col(t(prob))
max.idx
@@ -126,8 +124,8 @@ print(paste0("Predicted Top-class: ", synsets[[max.idx]]))
Actually I do not know what does the word mean when I saw it.
So I searched on the web to check it out.. and hmm it does get the right answer :)
-Extract features
-------------------
+## Extract features
+
Besides the final classification results, we can also extract the internal features.
We need to get feature layer symbol out of internals first. Here we use `global_pool_output`
@@ -157,6 +155,10 @@ dim(global_pooling_feature)
```
-Reference
----------
+## Reference
+
+
[1] Ioffe, Sergey, and Christian Szegedy. "Batch normalization: Accelerating deep network training by reducing internal covariate shift." arXiv preprint arXiv:1502.03167 (2015).
+
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/fiveMinutesNeuralNetwork.Rmd b/R-package/vignettes/fiveMinutesNeuralNetwork.Rmd
index bc45c96..fb023bb 100644
--- a/R-package/vignettes/fiveMinutesNeuralNetwork.Rmd
+++ b/R-package/vignettes/fiveMinutesNeuralNetwork.Rmd
@@ -1,17 +1,9 @@
-Neural Network with MXNet in Five Minutes
-=============================================
+# Neural Network with MXNet in Five Minutes
This is the first tutorial for new users of the R package `mxnet`. You will learn to construct a neural network to do regression in 5 minutes.
We will show you how to do classification and regression tasks respectively. The data we use comes from the package `mlbench`.
-## Preface
-
-This tutorial is written in Rmarkdown.
-
-- You can directly view the hosted version of the tutorial from [MXNet R Document](http://mxnet.readthedocs.io/en/latest/packages/r/fiveMinutesNeuralNetwork.html)
-- You can find the download the Rmarkdown source from [here](https://github.com/dmlc/mxnet/blob/master/R-package/vignettes/fiveMinutesNeuralNetwork.Rmd)
-
## Classification
First of all, let us load in the data and preprocess it:
@@ -177,3 +169,5 @@ dim(test.y)
```
Congratulations! Now you have learnt the basic for using `mxnet`. Please check the other tutorials for advanced features.
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/mnistCompetition.Rmd b/R-package/vignettes/mnistCompetition.Rmd
index 7414541..988fd18 100644
--- a/R-package/vignettes/mnistCompetition.Rmd
+++ b/R-package/vignettes/mnistCompetition.Rmd
@@ -1,19 +1,21 @@
-Handwritten Digits Classification Competition
-=============================================
+# Handwritten Digits Classification Competition
[MNIST](http://yann.lecun.com/exdb/mnist/) is a handwritten digits image data set created by Yann LeCun. Every digit is represented by a 28x28 image. It has become a standard data set to test classifiers on simple image input. Neural network is no doubt a strong model for image classification tasks. There's a [long-term hosted competition](https://www.kaggle.com/c/digit-recognizer) on Kaggle using this data set.
We will present the basic usage of [mxnet](https://github.com/dmlc/mxnet/tree/master/R-package) to compete in this challenge.
-This tutorial is written in Rmarkdown. You can download the source [here](https://github.com/dmlc/mxnet/blob/master/R-package/vignettes/mnistCompetition.Rmd) and view a
-hosted version of tutorial [here](http://mxnet.readthedocs.io/en/latest/packages/r/mnistCompetition.html).
-
## Data Loading
First, let us download the data from [here](https://www.kaggle.com/c/digit-recognizer/data), and put them under the `data/` folder in your working directory.
Then we can read them in R and convert to matrices.
-```{r, eval=FALSE}
+```{r, echo=FALSE}
+download.file('https://s3-us-west-2.amazonaws.com/apache-mxnet/R/data/mnist_csv.zip', destfile = 'mnist_csv.zip')
+unzip('mnist_csv.zip', exdir = '.')
+```
+
+
+```{r}
require(mxnet)
train <- read.csv("train.csv", header=TRUE)
test <- read.csv("test.csv", header=TRUE)
@@ -57,7 +59,7 @@ test.y <- load_label_file('mnist/t10k-labels-idx1-ubyte')
Here every image is represented as a single row in train/test. The greyscale of each image falls in the range [0, 255], we can linearly transform it into [0,1] by
-```{r, eval=FALSE}
+```{r}
train.x <- t(train.x/255)
test <- t(test/255)
```
@@ -65,7 +67,7 @@ We also transpose the input matrix to npixel x nexamples, which is the column ma
In the label part, we see the number of each digit is fairly even:
-```{r, eval=FALSE}
+```{r}
table(train.y)
```
@@ -73,7 +75,7 @@ table(train.y)
Now we have the data. The next step is to configure the structure of our network.
-```{r, eval=FALSE}
+```{r}
data <- mx.symbol.Variable("data")
fc1 <- mx.symbol.FullyConnected(data, name="fc1", num_hidden=128)
act1 <- mx.symbol.Activation(fc1, name="relu1", act_type="relu")
@@ -108,40 +110,42 @@ softmax <- mx.symbol.Variable("data") %>%
We are almost ready for the training process. Before we start the computation, let's decide what device should we use.
-```{r, eval=FALSE}
+```{r}
devices <- mx.cpu()
```
Here we assign CPU to `mxnet`. After all these preparation, you can run the following command to train the neural network! Note that `mx.set.seed` is the correct function to control the random process in `mxnet`.
-```{r, eval=FALSE}
+```{r}
mx.set.seed(0)
-model <- mx.model.FeedForward.create(softmax, X=train.x, y=train.y,
- ctx=devices, num.round=10, array.batch.size=100,
- learning.rate=0.07, momentum=0.9, eval.metric=mx.metric.accuracy,
- initializer=mx.init.uniform(0.07),
- batch.end.callback=mx.callback.log.train.metric(100))
+model <- mx.model.FeedForward.create(softmax, X = train.x, y = train.y,
+ ctx = devices, num.round = 5,
+ array.batch.size = 100,
+ learning.rate = 0.07, momentum = 0.9,
+ eval.metric = mx.metric.accuracy,
+ initializer = mx.init.uniform(0.07),
+ batch.end.callback = mx.callback.log.train.metric(100))
```
## Prediction and Submission
To make prediction, we can simply write
-```{r, eval=FALSE}
+```{r}
preds <- predict(model, test)
dim(preds)
```
It is a matrix with 28000 rows and 10 cols, containing the desired classification probabilities from the output layer. To extract the maximum label for each row, we can use the `max.col` in R:
-```{r, eval=FALSE}
+```{r}
pred.label <- max.col(t(preds)) - 1
table(pred.label)
```
With a little extra effort in the csv format, we can have our submission to the competition!
-```{r, eval=FALSE}
+```{r, eval = FALSE}
submission <- data.frame(ImageId=1:ncol(test), Label=pred.label)
write.csv(submission, file='submission.csv', row.names=FALSE, quote=FALSE)
```
@@ -179,16 +183,16 @@ lenet <- mx.symbol.SoftmaxOutput(data=fc2)
Then let us reshape the matrices into arrays:
-```{r, eval=FALSE}
+```{r}
train.array <- train.x
dim(train.array) <- c(28, 28, 1, ncol(train.x))
-test.array <- test.x
-dim(test.array) <- c(28, 28, 1, ncol(test.x))
+test.array <- test
+dim(test.array) <- c(28, 28, 1, ncol(test))
```
Next we are going to compare the training speed on different devices, so the definition of the devices goes first:
-```{r, eval=FALSE}
+```{r}
n.gpu <- 1
device.cpu <- mx.cpu()
device.gpu <- lapply(0:(n.gpu-1), function(i) {
@@ -201,38 +205,42 @@ but since internal computation of cpu is already multi-threaded, there is less g
We start by training on CPU first. Because it takes a bit time to do so, we will only run it for one iteration.
-```{r, eval=FALSE}
+```{r}
mx.set.seed(0)
tic <- proc.time()
-model <- mx.model.FeedForward.create(lenet, X=train.array, y=train.y,
- ctx=device.cpu, num.round=1, array.batch.size=100,
- learning.rate=0.05, momentum=0.9, wd=0.00001,
- eval.metric=mx.metric.accuracy,
- batch.end.callback=mx.callback.log.train.metric(100))
+model <- mx.model.FeedForward.create(lenet, X = train.array, y = train.y,
+ ctx = device.cpu, num.round = 1,
+ array.batch.size = 100,
+ learning.rate = 0.05, momentum = 0.9, wd = 0.00001,
+ eval.metric = mx.metric.accuracy,
+ batch.end.callback = mx.callback.log.train.metric(100))
print(proc.time() - tic)
```
Training on GPU:
-```{r, eval=FALSE}
+```{r}
mx.set.seed(0)
tic <- proc.time()
-model <- mx.model.FeedForward.create(lenet, X=train.array, y=train.y,
- ctx=device.gpu, num.round=5, array.batch.size=100,
- learning.rate=0.05, momentum=0.9, wd=0.00001,
- eval.metric=mx.metric.accuracy,
- batch.end.callback=mx.callback.log.train.metric(100))
+model <- mx.model.FeedForward.create(lenet, X = train.array, y = train.y,
+ ctx = device.gpu, num.round = 5,
+ array.batch.size = 100,
+ learning.rate = 0.05, momentum = 0.9, wd = 0.00001,
+ eval.metric = mx.metric.accuracy,
+ batch.end.callback = mx.callback.log.train.metric(100))
print(proc.time() - tic)
```
As you can see by using GPU, we can get a much faster speedup in training!
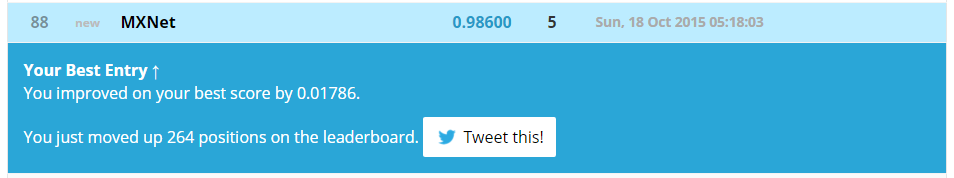
Finally we can submit the result to Kaggle again to see the improvement of our ranking!
-```{r, eval=FALSE}
+```{r, eval = FALSE}
preds <- predict(model, test.array)
pred.label <- max.col(t(preds)) - 1
submission <- data.frame(ImageId=1:ncol(test), Label=pred.label)
write.csv(submission, file='submission.csv', row.names=FALSE, quote=FALSE)
```
-
+
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/ndarray.Rmd b/R-package/vignettes/ndarray.Rmd
new file mode 100644
index 0000000..08786b2
--- /dev/null
+++ b/R-package/vignettes/ndarray.Rmd
@@ -0,0 +1,148 @@
+# NDArray: Vectorized Tensor Computations on CPUs and GPUs
+
+`NDArray` is the basic vectorized operation unit in MXNet for matrix and tensor computations.
+Users can perform usual calculations as on an R"s array, but with two additional features:
+
+- Multiple devices: All operations can be run on various devices including
+CPUs and GPUs.
+
+- Automatic parallelization: All operations are automatically executed in
+ parallel with each other.
+
+## Create and Initialize
+
+Let"s create `NDArray` on either a GPU or a CPU:
+
+```{r}
+require(mxnet)
+a <- mx.nd.zeros(c(2, 3)) # create a 2-by-3 matrix on cpu
+b <- mx.nd.zeros(c(2, 3), mx.cpu()) # create a 2-by-3 matrix on cpu
+c <- mx.nd.zeros(c(2, 3), mx.gpu(0)) # create a 2-by-3 matrix on gpu 0, if you have CUDA enabled.
+```
+
+Typically for CUDA-enabled devices, the device id of a GPU starts from 0.
+That's why we passed in 0 to the GPU id.
+
+We can initialize an `NDArray` object in various ways:
+
+
+```{r}
+a <- mx.nd.ones(c(4, 4))
+b <- mx.rnorm(c(4, 5))
+c <- mx.nd.array(1:5)
+```
+
+To check the numbers in an `NDArray`, we can simply run:
+
+
+```{r}
+a <- mx.nd.ones(c(2, 3))
+b <- as.array(a)
+class(b)
+```
+
+```{r}
+b
+```
+
+## Performing Basic Operations
+
+### Elemental-wise Operations
+
+You can perform elemental-wise operations on `NDArray` objects, as follows:
+
+
+```{r}
+a <- mx.nd.ones(c(2, 4)) * 2
+b <- mx.nd.ones(c(2, 4)) / 8
+as.array(a)
+```
+
+```{r}
+as.array(b)
+```
+
+```{r}
+c <- a + b
+as.array(c)
+```
+
+```{r}
+d <- c / a - 5
+as.array(d)
+```
+
+If two `NDArray`s are located on different devices, we need to explicitly move them to the same one. For instance:
+
+
+```{r}
+a <- mx.nd.ones(c(2, 3)) * 2
+b <- mx.nd.ones(c(2, 3), mx.gpu()) / 8
+c <- mx.nd.copyto(a, mx.gpu()) * b
+as.array(c)
+```
+
+### Loading and Saving
+
+You can save a list of `NDArray` object to your disk with `mx.nd.save`:
+
+
+```{r}
+a <- mx.nd.ones(c(2, 3))
+mx.nd.save(list(a), "temp.ndarray")
+```
+
+You can load it back easily:
+
+
+```{r}
+a <- mx.nd.load("temp.ndarray")
+as.array(a[[1]])
+```
+
+We can directly save data to and load it from a distributed file system, such as Amazon S3 and HDFS:
+
+
+```{r, eval=FALSE}
+mx.nd.save(list(a), "s3://mybucket/mydata.bin")
+mx.nd.save(list(a), "hdfs///users/myname/mydata.bin")
+```
+
+## Automatic Parallelization
+
+`NDArray` can automatically execute operations in parallel. Automatic parallelization is useful when
+using multiple resources, such as CPU cards, GPU cards, and CPU-to-GPU memory bandwidth.
+
+For example, if we write `a <- a + 1` followed by `b <- b + 1`, and `a` is on a CPU and
+`b` is on a GPU, executing them in parallel improves
+efficiency. Furthermore, because copying data between CPUs and GPUs are also expensive, running in parallel with other computations further increases efficiency.
+
+It's hard to find the code that can be executed in parallel by eye. In the
+following example, `a <- a + 1` and `c <- c * 3` can be executed in parallel, but `a <- a + 1` and
+`b <- b * 3` should be in sequential.
+
+
+```{r}
+a <- mx.nd.ones(c(2,3))
+b <- a
+c <- mx.nd.copyto(a, mx.cpu())
+a <- a + 1
+b <- b * 3
+c <- c * 3
+```
+
+Luckily, MXNet can automatically resolve the dependencies and
+execute operations in parallel accurately. This allows us to write our program assuming there is only a single thread. MXNet will
+automatically dispatch the program to multiple devices.
+
+MXNet achieves this with lazy evaluation. Each operation is issued to an
+internal engine, and then returned. For example, if we run `a <- a + 1`, it
+returns immediately after pushing the plus operator to the engine. This
+asynchronous processing allows us to push more operators to the engine. It determines
+the read and write dependencies and the best way to execute them in
+parallel.
+
+The actual computations are finished, allowing us to copy the results someplace else, such as `as.array(a)` or `mx.nd.save(a, "temp.dat")`. To write highly parallelized codes, we only need to postpone when we need
+the results.
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
diff --git a/R-package/vignettes/ndarrayAndSymbolTutorial.Rmd b/R-package/vignettes/ndarrayAndSymbolTutorial.Rmd
deleted file mode 100644
index a47147c..0000000
--- a/R-package/vignettes/ndarrayAndSymbolTutorial.Rmd
+++ /dev/null
@@ -1,242 +0,0 @@
-MXNet R Tutorial on NDArray and Symbol
-======================================
-
-This vignette gives a general overview of MXNet"s R package. MXNet contains a
-mixed flavor of elements to bake flexible and efficient
-applications. There are two major concepts introduced in this tutorial.
-
-* [NDArray](#ndarray-numpy-style-tensor-computations-on-cpus-and-gpus)
- offers matrix and tensor computations on both CPU and GPU, with automatic
- parallelization
-* [Symbol](#symbol-and-automatic-differentiation) makes defining a neural
- network extremely easy, and provides automatic differentiation.
-
-## NDArray: Vectorized tensor computations on CPUs and GPUs
-
-`NDArray` is the basic vectorized operation unit in MXNet for matrix and tensor computations.
-Users can perform usual calculations as on R"s array, but with two additional features:
-
-1. **multiple devices**: all operations can be run on various devices including
-CPU and GPU
-2. **automatic parallelization**: all operations are automatically executed in
- parallel with each other
-
-### Create and Initialization
-
-Let"s create `NDArray` on either GPU or CPU
-
-```{r}
-require(mxnet)
-a <- mx.nd.zeros(c(2, 3)) # create a 2-by-3 matrix on cpu
-b <- mx.nd.zeros(c(2, 3), mx.cpu()) # create a 2-by-3 matrix on cpu
-# c <- mx.nd.zeros(c(2, 3), mx.gpu(0)) # create a 2-by-3 matrix on gpu 0, if you have CUA enabled.
-```
-
-As a side note, normally for CUDA enabled devices, the device id of GPU starts from 0.
-So that is why we passed in 0 to GPU id. We can also initialize an `NDArray` object in various ways:
-
-```{r}
-a <- mx.nd.ones(c(4, 4))
-b <- mx.rnorm(c(4, 5))
-c <- mx.nd.array(1:5)
-```
-
-To check the numbers in an `NDArray`, we can simply run
-
-```{r}
-a <- mx.nd.ones(c(2, 3))
-b <- as.array(a)
-class(b)
-b
-```
-
-### Basic Operations
-
-#### Elemental-wise operations
-
-You can perform elemental-wise operations on `NDArray` objects:
-
-```{r}
-a <- mx.nd.ones(c(2, 4)) * 2
-b <- mx.nd.ones(c(2, 4)) / 8
-as.array(a)
-as.array(b)
-c <- a + b
-as.array(c)
-d <- c / a - 5
-as.array(d)
-```
-
-If two `NDArray`s sit on different devices, we need to explicitly move them
-into the same one. For instance:
-
-```{r, eval=FALSE}
-a <- mx.nd.ones(c(2, 3)) * 2
-b <- mx.nd.ones(c(2, 3), mx.gpu()) / 8
-c <- mx.nd.copyto(a, mx.gpu()) * b
-as.array(c)
-```
-
-#### Load and Save
-
-You can save a list of `NDArray` object to your disk with `mx.nd.save`:
-
-```{r}
-a <- mx.nd.ones(c(2, 3))
-mx.nd.save(a, "temp.ndarray")
-```
-
-You can also load it back easily:
-
-```{r}
-a <- mx.nd.load("temp.ndarray")
-as.array(a[[1]])
-```
-
-In case you want to save data to the distributed file system such as S3 and HDFS,
-we can directly save to and load from them. For example:
-
-```{r,eval=FALSE}
-mx.nd.save(list(a), "s3://mybucket/mydata.bin")
-mx.nd.save(list(a), "hdfs///users/myname/mydata.bin")
-```
-
-### Automatic Parallelization
-
-`NDArray` can automatically execute operations in parallel. It is desirable when we
-use multiple resources such as CPU, GPU cards, and CPU-to-GPU memory bandwidth.
-
-For example, if we write `a <- a + 1` followed by `b <- b + 1`, and `a` is on CPU while
-`b` is on GPU, then want to execute them in parallel to improve the
-efficiency. Furthermore, data copy between CPU and GPU are also expensive, we
-hope to run it parallel with other computations as well.
-
-However, finding the codes can be executed in parallel by eye is hard. In the
-following example, `a <- a + 1` and `c <- c * 3` can be executed in parallel, but `a <- a + 1` and
-`b <- b * 3` should be in sequential.
-
-```{r}
-a <- mx.nd.ones(c(2,3))
-b <- a
-c <- mx.nd.copyto(a, mx.cpu())
-a <- a + 1
-b <- b * 3
-c <- c * 3
-```
-
-Luckily, MXNet can automatically resolve the dependencies and
-execute operations in parallel with correctness guaranteed. In other words, we
-can write program as by assuming there is only a single thread, while MXNet will
-automatically dispatch it into multi-devices, such as multi GPU cards or multi
-machines.
-
-It is achieved by lazy evaluation. Any operation we write down is issued into a
-internal engine, and then returned. For example, if we run `a <- a + 1`, it
-returns immediately after pushing the plus operator to the engine. This
-asynchronous allows us to push more operators to the engine, so it can determine
-the read and write dependency and find a best way to execute them in
-parallel.
-
-The actual computations are finished if we want to copy the results into some
-other place, such as `as.array(a)` or `mx.nd.save(a, "temp.dat")`. Therefore, if we
-want to write highly parallelized codes, we only need to postpone when we need
-the results.
-
-## Symbol and Automatic Differentiation
-
-WIth the computational unit `NDArray`, we need a way to construct neural networks. MXNet provides a symbolic interface named Symbol to do so. The symbol combines both flexibility and efficiency.
-
-### Basic Composition of Symbols
-
-The following codes create a two layer perceptrons network:
-
-```{r}
-require(mxnet)
-net <- mx.symbol.Variable("data")
-net <- mx.symbol.FullyConnected(data=net, name="fc1", num_hidden=128)
-net <- mx.symbol.Activation(data=net, name="relu1", act_type="relu")
-net <- mx.symbol.FullyConnected(data=net, name="fc2", num_hidden=64)
-net <- mx.symbol.SoftmaxOutput(data=net, name="out")
-class(net)
-```
-
-Each symbol takes a (unique) string name. *Variable* often defines the inputs,
-or free variables. Other symbols take a symbol as the input (*data*),
-and may accept other hyper-parameters such as the number of hidden neurons (*num_hidden*)
-or the activation type (*act_type*).
-
-The symbol can be simply viewed as a function taking several arguments, whose
-names are automatically generated and can be get by
-
-```{r}
-arguments(net)
-```
-
-As can be seen, these arguments are the parameters need by each symbol:
-
-- *data* : input data needed by the variable *data*
-- *fc1_weight* and *fc1_bias* : the weight and bias for the first fully connected layer *fc1*
-- *fc2_weight* and *fc2_bias* : the weight and bias for the second fully connected layer *fc2*
-- *out_label* : the label needed by the loss
-
-We can also specify the automatic generated names explicitly:
-
-```{r}
-data <- mx.symbol.Variable("data")
-w <- mx.symbol.Variable("myweight")
-net <- mx.symbol.FullyConnected(data=data, weight=w, name="fc1", num_hidden=128)
-arguments(net)
-```
-
-### More Complicated Composition
-
-MXNet provides well-optimized symbols for
-commonly used layers in deep learning. We can also easily define new operators
-in python. The following example first performs an elementwise add between two
-symbols, then feed them to the fully connected operator.
-
-```{r}
-lhs <- mx.symbol.Variable("data1")
-rhs <- mx.symbol.Variable("data2")
-net <- mx.symbol.FullyConnected(data=lhs + rhs, name="fc1", num_hidden=128)
-arguments(net)
-```
-
-We can also construct symbol in a more flexible way rather than the single
-forward composition we addressed before.
-
-```{r}
-net <- mx.symbol.Variable("data")
-net <- mx.symbol.FullyConnected(data=net, name="fc1", num_hidden=128)
-net2 <- mx.symbol.Variable("data2")
-net2 <- mx.symbol.FullyConnected(data=net2, name="net2", num_hidden=128)
-composed.net <- mx.apply(net, data=net2, name="compose")
-arguments(composed.net)
-```
-
-In the above example, *net* is used a function to apply to an existing symbol
-*net*, the resulting *composed.net* will replace the original argument *data* by
-*net2* instead.
-
-### Training a Neural Net.
-
-The [model API](../../R-package/R/model.R) is a thin wrapper around the symbolic executors to support neural net training.
-
-You are also highly encouraged to read [Symbolic Configuration and Execution in Pictures for python package](../python/symbol_in_pictures.md),
-which provides a detailed explanation of concepts in pictures.
-
-### How Efficient is Symbolic API
-
-In short, they are designed to be very efficient in both memory and runtime.
-
-The major reason for us to introduce Symbolic API, is to bring the efficient C++
-operations in powerful toolkits such as cxxnet and caffe together with the
-flexible dynamic NArray operations. All the memory and computation resources are
-allocated statically during Bind, to maximize the runtime performance and memory
-utilization.
-
-The coarse grained operators are equivalent to cxxnet layers, which are
-extremely efficient. We also provide fine grained operators for more flexible
-composition. Because we are also doing more inplace memory allocation, mxnet can
-be ***more memory efficient*** than cxxnet, and gets to same runtime, with
-greater flexiblity.
diff --git a/R-package/vignettes/symbol.Rmd b/R-package/vignettes/symbol.Rmd
new file mode 100644
index 0000000..228c6b2
--- /dev/null
+++ b/R-package/vignettes/symbol.Rmd
@@ -0,0 +1,103 @@
+# Symbol and Automatic Differentiation
+
+The computational unit `NDArray` requires a way to construct neural networks. MXNet provides a symbolic interface, named Symbol, to do this. Symbol combines both flexibility and efficiency.
+
+## Basic Composition of Symbols
+
+The following code creates a two-layer perceptron network:
+
+
+```{r}
+require(mxnet)
+net <- mx.symbol.Variable("data")
+net <- mx.symbol.FullyConnected(data=net, name="fc1", num_hidden=128)
+net <- mx.symbol.Activation(data=net, name="relu1", act_type="relu")
+net <- mx.symbol.FullyConnected(data=net, name="fc2", num_hidden=64)
+net <- mx.symbol.Softmax(data=net, name="out")
+class(net)
+```
+
+
+Each symbol takes a (unique) string name. *Variable* often defines the inputs,
+or free variables. Other symbols take a symbol as the input (*data*),
+and may accept other hyper parameters, such as the number of hidden neurons (*num_hidden*)
+or the activation type (*act_type*).
+
+A symbol can be viewed as a function that takes several arguments, whose
+names are automatically generated and can be retrieved with the following command:
+
+
+```{r}
+arguments(net)
+```
+
+The arguments are the parameters need by each symbol:
+
+- *data*: Input data needed by the variable *data*
+- *fc1_weight* and *fc1_bias*: The weight and bias for the first fully connected layer, *fc1*
+- *fc2_weight* and *fc2_bias*: The weight and bias for the second fully connected layer, *fc2*
+- *out_label*: The label needed by the loss
+
+We can also specify the automatically generated names explicitly:
+
+
+```{r}
+data <- mx.symbol.Variable("data")
+w <- mx.symbol.Variable("myweight")
+net <- mx.symbol.FullyConnected(data=data, weight=w, name="fc1", num_hidden=128)
+arguments(net)
+```
+
+## More Complicated Composition of Symbols
+
+MXNet provides well-optimized symbols for
+commonly used layers in deep learning. You can also define new operators
+in Python. The following example first performs an element-wise add between two
+symbols, then feeds them to the fully connected operator:
+
+
+```{r}
+lhs <- mx.symbol.Variable("data1")
+rhs <- mx.symbol.Variable("data2")
+net <- mx.symbol.FullyConnected(data=lhs + rhs, name="fc1", num_hidden=128)
+arguments(net)
+```
+
+We can construct a symbol more flexibly than by using the single
+forward composition, for example:
+
+```{r}
+net <- mx.symbol.Variable("data")
+net <- mx.symbol.FullyConnected(data=net, name="fc1", num_hidden=128)
+net2 <- mx.symbol.Variable("data2")
+net2 <- mx.symbol.FullyConnected(data=net2, name="net2", num_hidden=128)
+composed.net <- mx.apply(net, data=net2, name="compose")
+arguments(composed.net)
+```
+
+In the example, *net* is used as a function to apply to an existing symbol
+*net*. The resulting *composed.net* will replace the original argument *data* with
+*net2* instead.
+
+## Training a Neural Net
+
+The [model API](../../../R-package/R/model.R) is a thin wrapper around the symbolic executors to support neural net training.
+
+We encourage you to read [Symbolic Configuration and Execution in Pictures for python package](../python/symbol_in_pictures.md)for a detailed explanation of concepts in pictures.
+
+## How Efficient Is the Symbolic API?
+
+The Symbolic API brings the efficient C++
+operations in powerful toolkits, such as CXXNet and Caffe, together with the
+flexible dynamic NDArray operations. All of the memory and computation resources are
+allocated statically during bind operations, to maximize runtime performance and memory
+utilization.
+
+The coarse-grained operators are equivalent to CXXNet layers, which are
+extremely efficient. We also provide fine-grained operators for more flexible
+composition. Because MXNet does more in-place memory allocation, it can
+be more memory efficient than CXXNet and gets to the same runtime with
+greater flexibility.
+
+
+<!-- INSERT SOURCE DOWNLOAD BUTTONS -->
\ No newline at end of file
--
To stop receiving notification emails like this one, please contact
['"commits@mxnet.apache.org" <co...@mxnet.apache.org>'].