You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@hugegraph.apache.org by "imbajin (via GitHub)" <gi...@apache.org> on 2026/10/10 13:20:48 UTC
[PR] fix(server): preserve graphs during task shutdown [hugegraph]
imbajin opened a new pull request, #3308:
URL: https://github.com/apache/hugegraph/pull/3308
## Purpose
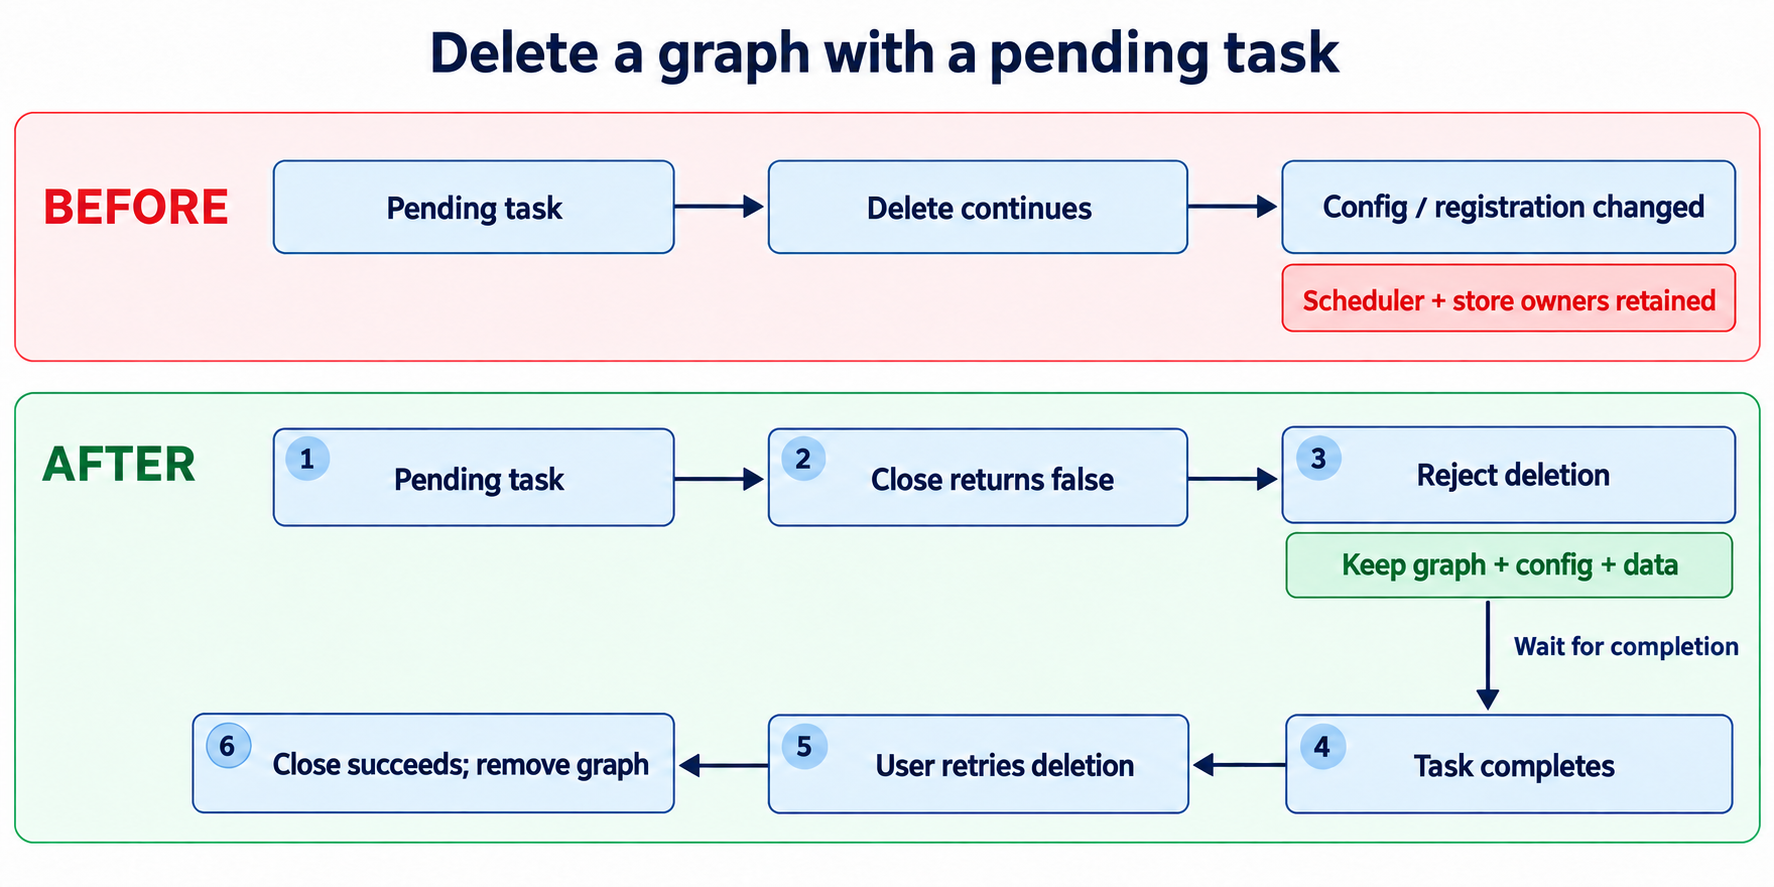
Deleting a graph could remove its configuration or registration before the local task scheduler finished closing. Pending tasks or an incomplete close then left deletion partially applied and difficult to retry. Deletion now requires local scheduler shutdown before destructive cleanup and retains registrations when graph closure fails, allowing an explicit retry.
## Main changes
- Reject destructive graph deletion until the local scheduler acknowledges shutdown; retain configuration, data and registrations while tasks are still draining.
- Fence new local task admission during scheduler closure and include queued dispatches in the existing task accounting.
- Keep task reservations until execution and owner cleanup finish; run cancellation callbacks outside the request thread so they cannot close its transaction.
- Preserve registrations and propagate errors from incomplete graph closure. Retry skips completed cleanup; it does not roll back data or metadata already removed during a later failure.
- Document explicit retry and the limits of remote notifications. No automatic notification replay or cluster-wide admission protocol is added.
## Verification
Focused Maven reactor tests pass using real in-memory graphs and transactions. They cover deletion refusal, explicit retry, authorization, graph-space cleanup, queued work, cancellation callbacks, caller transactions and admission races. Reverting the relevant fixes reproduces registration loss, premature task-accounting release and caller-transaction closure. EditorConfig, Checkstyle and the affected reactor compilation pass.
## Documentation
The retry contract is documented in `docs/server-runtime.md`.
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4253762391


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/StandardHugeGraph.java:
##########
@@ -1212,12 +1213,16 @@ public void create(String configPath, GlobalMasterInfo nodeInfo) {

     @Override
     public void drop() {
+        this.checkGraphNotClosed();
+        TaskScheduler scheduler = this.taskManager.getScheduler(this.params);
+        if (scheduler != null && !scheduler.close()) {
+            // Fence admission before waiting for actual task owners to exit.
+            this.waitUntilAllTasksCompleted();

Review Comment:
   Addressed in [the maintenance-contract correction](https://github.com/apache/hugegraph/commit/7b0ed580b25be26f522bb4de92ad5cf61581c5f9) using the explicit retained-fence option in this review. Admission remains closed after refusal. Both local and PD timeout/second-close refusal messages now say so, with deletion retry after owners exit or server restart to resume task admission. The runtime document limits restart recovery to before destructive cleanup and explains that retaining graph data/configuration does not restore normal asynchronous task service.

   The existing local/PD refusal regressions now assert these messages and reject a new task, while retaining their data/configuration/metadata checks and successful deletion retry after the original owner exits. Reopening a flag would not restore the distributed scheduler's cancelled cron, so no recovery protocol is added here.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(server): preserve graphs during task shutdown [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4243546942


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/DistributedTaskScheduler.java:
##########
@@ -564,7 +777,8 @@ public boolean close() {
         }

         // cancel all running tasks
-        for (HugeTask<?> task : this.runningTasks.values()) {
+        for (PendingTask pending : this.runningTasks.values()) {

Review Comment:
   Closing now releases an unstarted persistent dispatch only when it has no cancellation or deletion coordination, without changing its task or durable NEW status. The identity check also protects concurrent close snapshots. Regressions verify ordinary and concurrent closes, shared-worker saturation, and actual durable redispatch by a replacement scheduler.

   The latest-head Linux Memory unit, core and API suites passed, including the durable redispatch and RocksDB reload regressions. The full CI and coverage checks are also passing.


##########
hugegraph-server/hugegraph-api/src/main/java/org/apache/hugegraph/core/GraphManager.java:
##########
@@ -2268,40 +2266,77 @@ public void dropGraph(String graphSpace, String name, boolean clear) {
         }

         String graphName = spaceGraphName(graphSpace, name);
+        boolean alreadyClosed = g.closed();
+        E.checkState(!clear || !alreadyClosed || this.removingGraphs.contains(graphName),
+                     "Can't clear an already closed graph '%s' without an accepted deletion", graphName);
+        // Task results still need the backend until their scheduler has drained.
+        TaskScheduler scheduler = null;
+        if (clear && !alreadyClosed) {
+            try {
+                // Keep the auth proxy's cached owner and its pre-close ADMIN check.
+                scheduler = g.taskScheduler();
+            } catch (IllegalStateException e) {
+                if (!(g instanceof StandardHugeGraph) ||
+                    TaskManager.instance().getScheduler(g) != null) {
+                    throw e;
+                }
+                // A previous plain-graph close removed its scheduler but retained owners.
+            }
+        }
+        if (clear && scheduler != null && !scheduler.close()) {
+            throw new HugeException("Can't drop graph '%s' while tasks are active, " +
+                                    "please retry later", graphName);
+        }
         if (clear) {
-            this.removingGraphs.add(graphName);
             try {
-                this.metaManager.removeGraphConfig(graphSpace, name);
+                if (!this.removingGraphs.contains(graphName)) {
+                    this.metaManager.removeGraphConfig(graphSpace, name);
+                    this.removingGraphs.add(graphName);
+                }
                 this.metaManager.notifyGraphRemove(graphSpace, name);
             } catch (Exception e) {
                 throw new HugeException(
-                        "Failed to remove graph config of '%s'", name, e);
+                        "Failed to remove graph config of '%s'", e, name);
             }

-            /**
-             * close task scheduler before clear data,
-             * because taskinfo stored in backend in
-             * {@link org.apache.hugegraph.task.DistributedTaskScheduler}
-             */
+            if (!alreadyClosed) {
+                // Unwrapping an auth proxy preserves its ADMIN permission check.
+                HugeGraph underlying = g.hugegraph();
+                if (underlying instanceof StandardHugeGraph) {
+                    ((StandardHugeGraph) underlying).clearBackendForDrop();
+                } else {
+                    g.clearBackend();
+                }
+            }
             try {
-                g.taskScheduler().close();
-            } catch (Throwable t) {
-                LOG.warn(String.format(
-                                 "Error when close TaskScheduler of %s",
-                                 graphName),
-                         t);
+                if (!alreadyClosed) {
+                    g.close();
+                }
+            } catch (Exception e) {
+                if (!g.closed()) {
+                    throw new HugeException("Failed to close graph '%s', please retry later",
+                                            e, graphName);
+                }
+                LOG.warn("Graph '{}' closed with an owner cleanup failure", graphName, e);
             }
-
-            g.clearBackend();
+        } else {
+            // Remote notifications detach owners only after close succeeds.
             try {
                 g.close();
             } catch (Exception e) {
-                LOG.warn("Failed to close graph", e);
+                if (!g.closed()) {
+                    throw new HugeException("Failed to close graph '%s', please retry later",

Review Comment:
   Reload now retains graphs whose close fails, reopens successfully detached graphs, and reports the incomplete closure after recovery. It also preserves backend data and local properties on the non-PD close-only path. Real RocksDB regressions force a partial close failure and verify registrations, persisted vertices and configuration before and after an explicit retry.

   The latest-head Linux Memory unit, core and API suites passed, including the durable redispatch and RocksDB reload regressions. The full CI and coverage checks are also passing.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4250985693


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/DistributedTaskScheduler.java:
##########
@@ -120,7 +125,7 @@ private static boolean sleep(long ms) {
         }
     }

-    public void cronSchedule() {
+    public synchronized void cronSchedule() {

Review Comment:
   Removed the method-level cron monitor. Production cron already runs on its single scheduler executor; the short schedule/start/physical-owner registration gates remain coordinated with close. Close can now set the admission fence immediately and reach its existing timed cron barrier even when a cron query is blocked.

   The new regression submits actual cron work to the same executor and blocks its query path. It fails against the previous synchronized method at the close-fence assertion. With this correction it verifies admission rejection, a real barrier timeout returning false, and successful close after the cron is released. Formatting, clean reactor compilation and the final focused regressions passed. No new lock, state or executor was introduced.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#issuecomment-6137004709

   Addressed the [Memory CI fixture race](https://github.com/apache/hugegraph/pull/3308#issuecomment-6136236611) in [the four-line test correction](https://github.com/apache/hugegraph/commit/337d7b68f1a054ed2f85a0c651f4f65c54cf3455). The existing gate now holds the injected consumer failure until provide() returns. The original await() RuntimeException/message assertions, one-second test timeout and executor cleanup are unchanged; production Consumers is unchanged.

   A controlled real-consumer post-offer interleaving reproduced the old failure escaping from provide(), then confirmed the gated version reports that same exception from await(). All ConsumersTest cases, formatting and the clean reactor compile passed. The diagnostic queue observer is external evidence only. The branch is rebased onto current ASF master; Java/POM/proto/config sources match the tested version. Latest-head Linux CI and full coverage are still pending.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4253762199


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/TaskManager.java:
##########
@@ -261,7 +251,8 @@ public ServerInfoManager getServerInfoManager(HugeGraphParams graph) {
     }

     public void shutdown(long timeout) {
-        assert this.schedulers.isEmpty() : this.schedulers.size();
+        E.checkState(this.schedulers.isEmpty(),

Review Comment:
   Fixed in [the shutdown-grace correction](https://github.com/apache/hugegraph/commit/d61a8cd4244927416f50d50ce9ef8f6c1e70a39d). The introduced hard precondition is now a warning; the existing executor shutdown/await sequence is preserved. Retained schedulers are not removed and global resource shutdown does not acknowledge graph closure.

   The new isolated regression fails at the old guard. After the correction, a real worker completes its final database-executor callback and all shared executors terminate while the scheduler registration remains. Separate Memory and RocksDB JVMs also ran an actual persistent task through refused graph close and HugeFactory.shutdown, then queried its SUCCESS record directly from the backend; graph data/configuration remained intact. The inherited timeout short-circuit and other producer shutdown-order issues are recorded separately, without expanding this PR.


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/StandardHugeGraph.java:
##########
@@ -1212,12 +1213,16 @@ public void create(String configPath, GlobalMasterInfo nodeInfo) {

     @Override
     public void drop() {
+        this.checkGraphNotClosed();
+        TaskScheduler scheduler = this.taskManager.getScheduler(this.params);
+        if (scheduler != null && !scheduler.close()) {
+            // Fence admission before waiting for actual task owners to exit.
+            this.waitUntilAllTasksCompleted();

Review Comment:
   Addressed in [the maintenance-contract correction](https://github.com/apache/hugegraph/commit/d61a8cd4244927416f50d50ce9ef8f6c1e70a39d) using the explicit retained-fence option in this review. Admission remains closed after refusal. Both local and PD timeout/second-close refusal messages now say so, with deletion retry after owners exit or server restart to resume task admission. The runtime document limits restart recovery to before destructive cleanup and explains that retaining graph data/configuration does not restore normal asynchronous task service.

   The existing local/PD refusal regressions now assert these messages and reject a new task, while retaining their data/configuration/metadata checks and successful deletion retry after the original owner exits. Reopening a flag would not restore the distributed scheduler's cancelled cron, so no recovery protocol is added here.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): preserve task and graph lifecycle [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4247598006


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/DistributedTaskScheduler.java:
##########
@@ -469,17 +550,200 @@ private void saveTaskWithoutResult(HugeTask<?> task) {
         });
     }

+    private boolean cancelLocal(PendingTask pending, Consumer<Boolean> afterCancel) {
+        return this.cancelLocal(pending, null, afterCancel);
+    }
+
+    private boolean cancelLocal(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel) {
+        return this.cancelLocal(pending, beforeCancel, afterCancel, false);
+    }
+
+    private boolean cancelLocal(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel, boolean terminalOnly) {
+        if (SCHEDULER_WORKER.get() == this.schedulerExecutor) {
+            return this.cancelOwned(pending, beforeCancel, afterCancel, terminalOnly);
+        }
+        // Keep callbacks and final persistence off the request/close thread and
+        // the DB worker, because callbacks may synchronously save to that worker.
+        return this.call(() -> {
+            SCHEDULER_WORKER.set(this.schedulerExecutor);
+            try {
+                return this.cancelOwned(pending, beforeCancel, afterCancel, terminalOnly);
+            } finally {
+                SCHEDULER_WORKER.remove();
+                // An interrupted request may stop waiting before this owner finishes.
+                this.finishCancelledQueued(pending);
+            }
+        }, this.schedulerExecutor, true);
+    }
+
+    private boolean cancelOwned(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel, boolean terminalOnly) {
+        LockResult acquired = null;
+        boolean acquire;
+        synchronized (pending) {
+            if (this.runningTasks.get(pending.task.id()) != pending) {
+                return false;
+            }
+            acquire = !pending.task.ephemeralTask() && pending.taskLock == null;
+            pending.cancellationDepth++;
+        }
+        boolean entered = false;
+        boolean coordinated = false;
+        try {
+            if (acquire) {
+                // Don't block publication/release of this runner's token during the lock RPC.
+                acquired = this.tryLockTask(pending.task.id().asString());
+                if (!acquired.lockSuccess()) {
+                    return false;
+                }
+                synchronized (pending) {
+                    pending.taskLock = acquired;
+                }
+            }
+            entered = true;
+            if (!pending.task.ephemeralTask()) {
+                HugeTask<?> stored;
+                try {
+                    stored = this.taskWithoutResult(pending.task.id());
+                } catch (NotFoundException e) {
+                    pending.discardQueued = true;
+                    coordinated = true;
+                    return false;
+                }
+                if (beforeCancel == null) {
+                    if (TaskStatus.COMPLETED_STATUSES.contains(stored.status())) {
+                        pending.discardQueued = true;
+                        coordinated = true;
+                        return false;
+                    }
+                    if (terminalOnly) {
+                        if (stored.status() == TaskStatus.DELETING) {
+                            pending.discardQueued = true;
+                            coordinated = true;
+                        } else if (pending.task.isCancelled() &&
+                                   pending.task.status() == TaskStatus.CANCELLED &&
+                                   stored.status() == TaskStatus.CANCELLING) {

Review Comment:
   [P1] Retry cancellation persistence for an already-running owner

   This only repairs the queued-reservation case, whose record has already been changed to CANCELLING. For a persistent task holding pending.taskLock, cancel() skips requestCancellation and cancelOwned() skips the acquired != null transition, so a transient failure of done/cancelled/final save can leave the record RUNNING while the in-memory task is CANCELLED and coordinationPending stays true. Once the worker exits, close() retries through terminalOnly, but this condition never persists the terminal state or clears the ticket. Because close() already cancelled cron, later close retries remain blocked even after the store recovers.

   Please cover a running LockHoldingJob failure/recovery case and allow the owned RUNNING case to finish safely without replaying callbacks or overwriting a remote terminal/DELETING state. The new checkCancellationPersistence test gates execution before the owner acquires its lock, so it covers the queued case only.

   Evidence boundary: independently traced the source and reproduced this with extracted cancel/cancelOwned/terminal-cleanup methods and real JDK FutureTask in a bounded cloud model. After three recovered retries, the running case retained stored RUNNING/ticket=1; the queued control reached CANCELLED/ticket=0, with callbacks remaining exactly once. Storage/PD locks/dispatch were stubbed; this is not a live PD/HStore validation.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): preserve task and graph lifecycle [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4248129135


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/DistributedTaskScheduler.java:
##########
@@ -469,17 +550,200 @@ private void saveTaskWithoutResult(HugeTask<?> task) {
         });
     }

+    private boolean cancelLocal(PendingTask pending, Consumer<Boolean> afterCancel) {
+        return this.cancelLocal(pending, null, afterCancel);
+    }
+
+    private boolean cancelLocal(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel) {
+        return this.cancelLocal(pending, beforeCancel, afterCancel, false);
+    }
+
+    private boolean cancelLocal(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel, boolean terminalOnly) {
+        if (SCHEDULER_WORKER.get() == this.schedulerExecutor) {
+            return this.cancelOwned(pending, beforeCancel, afterCancel, terminalOnly);
+        }
+        // Keep callbacks and final persistence off the request/close thread and
+        // the DB worker, because callbacks may synchronously save to that worker.
+        return this.call(() -> {
+            SCHEDULER_WORKER.set(this.schedulerExecutor);
+            try {
+                return this.cancelOwned(pending, beforeCancel, afterCancel, terminalOnly);
+            } finally {
+                SCHEDULER_WORKER.remove();
+                // An interrupted request may stop waiting before this owner finishes.
+                this.finishCancelledQueued(pending);
+            }
+        }, this.schedulerExecutor, true);
+    }
+
+    private boolean cancelOwned(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel, boolean terminalOnly) {
+        LockResult acquired = null;
+        boolean acquire;
+        synchronized (pending) {
+            if (this.runningTasks.get(pending.task.id()) != pending) {
+                return false;
+            }
+            acquire = !pending.task.ephemeralTask() && pending.taskLock == null;
+            pending.cancellationDepth++;
+        }
+        boolean entered = false;
+        boolean coordinated = false;
+        try {
+            if (acquire) {
+                // Don't block publication/release of this runner's token during the lock RPC.
+                acquired = this.tryLockTask(pending.task.id().asString());
+                if (!acquired.lockSuccess()) {
+                    return false;
+                }
+                synchronized (pending) {
+                    pending.taskLock = acquired;
+                }
+            }
+            entered = true;
+            if (!pending.task.ephemeralTask()) {
+                HugeTask<?> stored;
+                try {
+                    stored = this.taskWithoutResult(pending.task.id());
+                } catch (NotFoundException e) {
+                    pending.discardQueued = true;
+                    coordinated = true;
+                    return false;
+                }
+                if (beforeCancel == null) {
+                    if (TaskStatus.COMPLETED_STATUSES.contains(stored.status())) {
+                        pending.discardQueued = true;
+                        coordinated = true;
+                        return false;
+                    }
+                    if (terminalOnly) {
+                        if (stored.status() == TaskStatus.DELETING) {
+                            pending.discardQueued = true;
+                            coordinated = true;
+                        } else if (pending.task.isCancelled() &&
+                                   pending.task.status() == TaskStatus.CANCELLED &&
+                                   stored.status() == TaskStatus.CANCELLING) {

Review Comment:
   Fixed the running-owner terminal-save recovery on the original source branch. A close retry now retains and retries coordination for the owner that already held the task lock, without replaying its completion callback. The remote SUCCESS/DELETING protections remain in place.

   A real running-task fault injection reproduces the stuck close before the fix and verifies successful recovery after persistence is restored. The focused regressions, combined task/graph suite, clean compilation and three independent final reviews passed. New-head CI is pending; full PD/HStore/Raft topology validation remains separate.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4250613665


##########
hugegraph-server/hugegraph-api/src/main/java/org/apache/hugegraph/core/GraphManager.java:
##########
@@ -2268,40 +2266,77 @@ public void dropGraph(String graphSpace, String name, boolean clear) {
         }

         String graphName = spaceGraphName(graphSpace, name);
+        boolean alreadyClosed = g.closed();
+        E.checkState(!clear || !alreadyClosed || this.removingGraphs.contains(graphName),
+                     "Can't clear an already closed graph '%s' without an accepted deletion", graphName);
+        // Task results still need the backend until their scheduler has drained.
+        TaskScheduler scheduler = null;
+        if (clear && !alreadyClosed) {
+            try {
+                // Keep the auth proxy's cached owner and its pre-close ADMIN check.
+                scheduler = g.taskScheduler();
+            } catch (IllegalStateException e) {
+                if (!(g instanceof StandardHugeGraph) ||
+                    TaskManager.instance().getScheduler(g) != null) {
+                    throw e;
+                }
+                // A previous plain-graph close removed its scheduler but retained owners.
+            }
+        }
+        if (clear && scheduler != null && !scheduler.close()) {
+            throw new HugeException("Can't drop graph '%s' while tasks are active, " +
+                                    "please retry later", graphName);
+        }
         if (clear) {
-            this.removingGraphs.add(graphName);
             try {
-                this.metaManager.removeGraphConfig(graphSpace, name);
+                if (!this.removingGraphs.contains(graphName)) {
+                    this.metaManager.removeGraphConfig(graphSpace, name);
+                    this.removingGraphs.add(graphName);
+                }
                 this.metaManager.notifyGraphRemove(graphSpace, name);
             } catch (Exception e) {
                 throw new HugeException(
-                        "Failed to remove graph config of '%s'", name, e);
+                        "Failed to remove graph config of '%s'", e, name);
             }

-            /**
-             * close task scheduler before clear data,
-             * because taskinfo stored in backend in
-             * {@link org.apache.hugegraph.task.DistributedTaskScheduler}
-             */
+            if (!alreadyClosed) {
+                // Unwrapping an auth proxy preserves its ADMIN permission check.
+                HugeGraph underlying = g.hugegraph();
+                if (underlying instanceof StandardHugeGraph) {
+                    ((StandardHugeGraph) underlying).clearBackendForDrop();
+                } else {
+                    g.clearBackend();
+                }
+            }
             try {
-                g.taskScheduler().close();
-            } catch (Throwable t) {
-                LOG.warn(String.format(
-                                 "Error when close TaskScheduler of %s",
-                                 graphName),
-                         t);
+                if (!alreadyClosed) {
+                    g.close();
+                }
+            } catch (Exception e) {
+                if (!g.closed()) {
+                    throw new HugeException("Failed to close graph '%s', please retry later",
+                                            e, graphName);
+                }
+                LOG.warn("Graph '{}' closed with an owner cleanup failure", graphName, e);
             }
-
-            g.clearBackend();
+        } else {
+            // Remote notifications detach owners only after close succeeds.
             try {
                 g.close();
             } catch (Exception e) {
-                LOG.warn("Failed to close graph", e);
+                if (!g.closed()) {
+                    throw new HugeException("Failed to close graph '%s', please retry later",

Review Comment:
   The earlier reload recovery fix has been intentionally removed to keep this PR focused on local drain and deletion. The close failure remains visible and an open graph remains registered; full reload recovery is deferred rather than claimed fixed by this version. The runtime contract now requires restart for configuration changes, and the broader website documentation is held as a draft pending reconciliation.


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/DistributedTaskScheduler.java:
##########
@@ -469,17 +550,200 @@ private void saveTaskWithoutResult(HugeTask<?> task) {
         });
     }

+    private boolean cancelLocal(PendingTask pending, Consumer<Boolean> afterCancel) {
+        return this.cancelLocal(pending, null, afterCancel);
+    }
+
+    private boolean cancelLocal(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel) {
+        return this.cancelLocal(pending, beforeCancel, afterCancel, false);
+    }
+
+    private boolean cancelLocal(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel, boolean terminalOnly) {
+        if (SCHEDULER_WORKER.get() == this.schedulerExecutor) {
+            return this.cancelOwned(pending, beforeCancel, afterCancel, terminalOnly);
+        }
+        // Keep callbacks and final persistence off the request/close thread and
+        // the DB worker, because callbacks may synchronously save to that worker.
+        return this.call(() -> {
+            SCHEDULER_WORKER.set(this.schedulerExecutor);
+            try {
+                return this.cancelOwned(pending, beforeCancel, afterCancel, terminalOnly);
+            } finally {
+                SCHEDULER_WORKER.remove();
+                // An interrupted request may stop waiting before this owner finishes.
+                this.finishCancelledQueued(pending);
+            }
+        }, this.schedulerExecutor, true);
+    }
+
+    private boolean cancelOwned(PendingTask pending, Runnable beforeCancel,
+                                Consumer<Boolean> afterCancel, boolean terminalOnly) {
+        LockResult acquired = null;
+        boolean acquire;
+        synchronized (pending) {
+            if (this.runningTasks.get(pending.task.id()) != pending) {
+                return false;
+            }
+            acquire = !pending.task.ephemeralTask() && pending.taskLock == null;
+            pending.cancellationDepth++;
+        }
+        boolean entered = false;
+        boolean coordinated = false;
+        try {
+            if (acquire) {
+                // Don't block publication/release of this runner's token during the lock RPC.
+                acquired = this.tryLockTask(pending.task.id().asString());
+                if (!acquired.lockSuccess()) {
+                    return false;
+                }
+                synchronized (pending) {
+                    pending.taskLock = acquired;
+                }
+            }
+            entered = true;
+            if (!pending.task.ephemeralTask()) {
+                HugeTask<?> stored;
+                try {
+                    stored = this.taskWithoutResult(pending.task.id());
+                } catch (NotFoundException e) {
+                    pending.discardQueued = true;
+                    coordinated = true;
+                    return false;
+                }
+                if (beforeCancel == null) {
+                    if (TaskStatus.COMPLETED_STATUSES.contains(stored.status())) {
+                        pending.discardQueued = true;
+                        coordinated = true;
+                        return false;
+                    }
+                    if (terminalOnly) {
+                        if (stored.status() == TaskStatus.DELETING) {
+                            pending.discardQueued = true;
+                            coordinated = true;
+                        } else if (pending.task.isCancelled() &&
+                                   pending.task.status() == TaskStatus.CANCELLED &&
+                                   stored.status() == TaskStatus.CANCELLING) {

Review Comment:
   The broad cancellation-persistence replay protocol has been deferred with task-record recovery. This version guarantees that physical execution, accepted local callbacks and native cleanup have finished before graph deletion; it does not guarantee recovery of every final task-status publication failure. Failed/uncertain scheduler cleanup retains the scheduler and graph instead of acknowledging deletion. Such storage/recovery failures require explicit maintenance, as documented.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(server): preserve graphs during task shutdown [hugegraph]
Posted by "bitflicker64 (via GitHub)" <gi...@apache.org>.
bitflicker64 commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4240715704


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/StandardHugeGraph.java:
##########
@@ -1203,26 +1204,46 @@ public void create(String configPath, GlobalMasterInfo nodeInfo) {
         this.configuration.file(confPath);
     }

+    public synchronized void clearBackendForDrop() {
+        if (!this.dropBackendCleared) {
+            this.clearBackend();
+            this.dropBackendCleared = true;
+        }
+    }
+
     @Override
     public void drop() {
-        this.clearBackend();
+        E.checkState(!this.closed() || this.dropBackendCleared,
+                     "Can't drop an already closed graph '%s' before clearing its backend",
+                     this.spaceGraphName());
+        if (!this.closed()) {
+            TaskScheduler scheduler = this.taskManager.getScheduler(this.params);
+            if (scheduler != null && !scheduler.close()) {

Review Comment:
   Important: With the local scheduler (every non-hstore graph) this refuses a drop as soon as any task is pending, where master waited up to `task.wait_timeout` for it. `StandardTaskScheduler.close()` returns `false` immediately when `pendingTasks() != 0` (`StandardTaskScheduler.java:449`), so `drop()` throws here before `clearBackendForDrop()` reaches `waitUntilAllTasksCompleted()`. On master `drop()` started with `clearBackend()`, and that wait let short tasks finish.

   I ran the same probe on both trees (memory backend, default `task.wait_timeout=10`, one task that sleeps 1.5 s, then `GraphManager.dropGraphLocal`):

   - 87a06a9b: the drop returns after 1720 ms and the graph is closed.
   - 9918ff25: the drop throws `Can't drop graph 'DEFAULT-probe_short_task' while tasks are active, please retry later` after 0 ms. A second call after the task ends succeeds.

   So deleting a graph right after submitting an async job now fails where it used to succeed, and admission stays closed (`admissionClosed` is never reset) on a graph the caller may decide to keep.

   Could the drop close admission first and then wait up to `task.wait_timeout` for `pendingTasks()` to reach zero before it refuses? The wait has to sit outside the scheduler monitor, because `finishExecution()` is `synchronized`.


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/DistributedTaskScheduler.java:
##########
@@ -564,7 +777,8 @@ public boolean close() {
         }

         // cancel all running tasks
-        for (HugeTask<?> task : this.runningTasks.values()) {
+        for (PendingTask pending : this.runningTasks.values()) {

Review Comment:
   Important: `close()` now cancels persistent tasks that were dispatched but never started, and it does so on closes that are not deletions.

   `schedule()` calls `tryStartHugeTask(task, true)` (line 306), which reserves the task in `runningTasks` and puts it in the pool queue even when every worker is busy. This loop then calls `cancel()` for each reservation. A reservation that has not started owns no task lock, so line 358 writes `CANCELLING`, and the callback at lines 365-367 saves the task as `CANCELLED`. `checkQueuedOwnedCancellation(true)` in `DistributedTaskAdmissionTest` asserts this outcome: the job never ran and its stored status is `CANCELLED` after `scheduler.close()`.

   On master a task submitted while the workers were busy stayed `NEW` in the store (`tryStartHugeTask` returned `false` without submitting), `runningTasks` held only tasks that had started, and `close()` left the backlog for cron or another server. `GraphManager.reload()` closes graphs without deleting them, so after a reload the accepted backlog is cancelled instead of run.

   For a reservation that has not started and holds no lock, please release it with `cancelBeforeStart()` and leave the stored status `NEW`, at least when the close is not part of a deletion. That test would then need to expect `NEW`.


##########
hugegraph-server/hugegraph-api/src/main/java/org/apache/hugegraph/core/GraphManager.java:
##########
@@ -2268,40 +2266,77 @@ public void dropGraph(String graphSpace, String name, boolean clear) {
         }

         String graphName = spaceGraphName(graphSpace, name);
+        boolean alreadyClosed = g.closed();
+        E.checkState(!clear || !alreadyClosed || this.removingGraphs.contains(graphName),
+                     "Can't clear an already closed graph '%s' without an accepted deletion", graphName);
+        // Task results still need the backend until their scheduler has drained.
+        TaskScheduler scheduler = null;
+        if (clear && !alreadyClosed) {
+            try {
+                // Keep the auth proxy's cached owner and its pre-close ADMIN check.
+                scheduler = g.taskScheduler();
+            } catch (IllegalStateException e) {
+                if (!(g instanceof StandardHugeGraph) ||
+                    TaskManager.instance().getScheduler(g) != null) {
+                    throw e;
+                }
+                // A previous plain-graph close removed its scheduler but retained owners.
+            }
+        }
+        if (clear && scheduler != null && !scheduler.close()) {
+            throw new HugeException("Can't drop graph '%s' while tasks are active, " +
+                                    "please retry later", graphName);
+        }
         if (clear) {
-            this.removingGraphs.add(graphName);
             try {
-                this.metaManager.removeGraphConfig(graphSpace, name);
+                if (!this.removingGraphs.contains(graphName)) {
+                    this.metaManager.removeGraphConfig(graphSpace, name);
+                    this.removingGraphs.add(graphName);
+                }
                 this.metaManager.notifyGraphRemove(graphSpace, name);
             } catch (Exception e) {
                 throw new HugeException(
-                        "Failed to remove graph config of '%s'", name, e);
+                        "Failed to remove graph config of '%s'", e, name);
             }

-            /**
-             * close task scheduler before clear data,
-             * because taskinfo stored in backend in
-             * {@link org.apache.hugegraph.task.DistributedTaskScheduler}
-             */
+            if (!alreadyClosed) {
+                // Unwrapping an auth proxy preserves its ADMIN permission check.
+                HugeGraph underlying = g.hugegraph();
+                if (underlying instanceof StandardHugeGraph) {
+                    ((StandardHugeGraph) underlying).clearBackendForDrop();
+                } else {
+                    g.clearBackend();
+                }
+            }
             try {
-                g.taskScheduler().close();
-            } catch (Throwable t) {
-                LOG.warn(String.format(
-                                 "Error when close TaskScheduler of %s",
-                                 graphName),
-                         t);
+                if (!alreadyClosed) {
+                    g.close();
+                }
+            } catch (Exception e) {
+                if (!g.closed()) {
+                    throw new HugeException("Failed to close graph '%s', please retry later",
+                                            e, graphName);
+                }
+                LOG.warn("Graph '{}' closed with an owner cleanup failure", graphName, e);
             }
-
-            g.clearBackend();
+        } else {
+            // Remote notifications detach owners only after close succeeds.
             try {
                 g.close();
             } catch (Exception e) {
-                LOG.warn("Failed to close graph", e);
+                if (!g.closed()) {
+                    throw new HugeException("Failed to close graph '%s', please retry later",

Review Comment:
   Important: This throw also runs under `reload()` (line 704), which calls `dropGraph(space, name, false)` for every graph in a loop with no catch.

   On master the non-clear path had no close check: a close failure was logged after `this.graphs.remove`, the graph was detached anyway, and `reload()` went on to `loadGraphsFromMeta()`. At this head the first graph whose close is incomplete aborts `reload()`. On this PD-only path that means `DistributedTaskScheduler.close()` returned `false` (a cancelled task still running after the 10 s wait at line 791, or the cron barrier timing out at line 764), or a non-hstore graph with one pending task. Graphs iterated before that one are already removed from `this.graphs` and are not reopened, because the load steps after the loop are skipped. They stay unavailable on this server until a later reload gets through.

   `graphRemoveHandler` catches the exception at line 2728, `reload()` does not. Please catch per graph in `reload()` and still run the load steps for the graphs that were detached before reporting the ones that could not close. The `this.graphs.isEmpty()` check at lines 707-712 needs the same treatment, since a retained graph would otherwise skip the load steps as well.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(server): preserve graphs during task shutdown [hugegraph]
Posted by "codecov[bot] (via GitHub)" <gi...@apache.org>.
codecov[bot] commented on PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#issuecomment-6098022777

   ## [Codecov](https://app.codecov.io/gh/apache/hugegraph/pull/3308?dropdown=coverage&src=pr&el=h1&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache) Report
   :white_check_mark: All modified and coverable lines are covered by tests.
   :white_check_mark: Project coverage is 48.90%. Comparing base ([`87a06a9`](https://app.codecov.io/gh/apache/hugegraph/commit/87a06a9b617e79e5d5b2dd3d75585f7f80d67a25?dropdown=coverage&el=desc&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache)) to head ([`0a77e41`](https://app.codecov.io/gh/apache/hugegraph/commit/0a77e4197fcc95c2e52d0644f5a62aa8d782da60?dropdown=coverage&el=desc&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache)).

   <details><summary>Additional details and impacted files</summary>


   ```diff
   @@             Coverage Diff              @@
   ##             master    #3308      +/-   ##
   ============================================
   + Coverage     41.92%   48.90%   +6.97%
   + Complexity     7101      820    -6281
   ============================================
     Files           770       66     -704
     Lines         67320     6137   -61183
     Branches       9042      658    -8384
   ============================================
   - Hits          28226     3001   -25225
   + Misses        35879     2889   -32990
   + Partials       3215      247    -2968
   ```
   </details>

   [:umbrella: View full report in Codecov by Harness](https://app.codecov.io/gh/apache/hugegraph/pull/3308?dropdown=coverage&src=pr&el=continue&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache).
   :loudspeaker: Have feedback on the report? [Share it here](https://about.codecov.io/codecov-pr-comment-feedback/?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache).
   <details><summary> :rocket: New features to boost your workflow: </summary>

   - :snowflake: [Test Analytics](https://docs.codecov.com/docs/test-analytics): Detect flaky tests, report on failures, and find test suite problems.
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(server): preserve graphs during task shutdown [hugegraph]
Posted by "codecov[bot] (via GitHub)" <gi...@apache.org>.
codecov[bot] commented on PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#issuecomment-6098022777

   ## [Codecov](https://app.codecov.io/gh/apache/hugegraph/pull/3308?dropdown=coverage&src=pr&el=h1&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache) Report
   :white_check_mark: All modified and coverable lines are covered by tests.
   :white_check_mark: Project coverage is 48.90%. Comparing base ([`87a06a9`](https://app.codecov.io/gh/apache/hugegraph/commit/87a06a9b617e79e5d5b2dd3d75585f7f80d67a25?dropdown=coverage&el=desc&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache)) to head ([`0a77e41`](https://app.codecov.io/gh/apache/hugegraph/commit/0a77e4197fcc95c2e52d0644f5a62aa8d782da60?dropdown=coverage&el=desc&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache)).

   <details><summary>Additional details and impacted files</summary>


   ```diff
   @@             Coverage Diff              @@
   ##             master    #3308      +/-   ##
   ============================================
   + Coverage     41.92%   48.90%   +6.97%
   + Complexity     7101      820    -6281
   ============================================
     Files           770       66     -704
     Lines         67320     6137   -61183
     Branches       9042      658    -8384
   ============================================
   - Hits          28226     3001   -25225
   + Misses        35879     2889   -32990
   + Partials       3215      247    -2968
   ```
   </details>

   [:umbrella: View full report in Codecov by Harness](https://app.codecov.io/gh/apache/hugegraph/pull/3308?dropdown=coverage&src=pr&el=continue&utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache).
   :loudspeaker: Have feedback on the report? [Share it here](https://about.codecov.io/codecov-pr-comment-feedback/?utm_medium=referral&utm_source=github&utm_content=comment&utm_campaign=pr+comments&utm_term=apache).
   <details><summary> :rocket: New features to boost your workflow: </summary>

   - :snowflake: [Test Analytics](https://docs.codecov.com/docs/test-analytics): Detect flaky tests, report on failures, and find test suite problems.
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4253762199


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/TaskManager.java:
##########
@@ -261,7 +251,8 @@ public ServerInfoManager getServerInfoManager(HugeGraphParams graph) {
     }

     public void shutdown(long timeout) {
-        assert this.schedulers.isEmpty() : this.schedulers.size();
+        E.checkState(this.schedulers.isEmpty(),

Review Comment:
   Fixed in [the shutdown-grace correction](https://github.com/apache/hugegraph/commit/7b0ed580b25be26f522bb4de92ad5cf61581c5f9). The introduced hard precondition is now a warning; the existing executor shutdown/await sequence is preserved. Retained schedulers are not removed and global resource shutdown does not acknowledge graph closure.

   The new isolated regression fails at the old guard. After the correction, a real worker completes its final database-executor callback and all shared executors terminate while the scheduler registration remains. Separate Memory and RocksDB JVMs also ran an actual persistent task through refused graph close and HugeFactory.shutdown, then queried its SUCCESS record directly from the backend; graph data/configuration remained intact. The inherited timeout short-circuit and other producer shutdown-order issues are recorded separately, without expanding this PR.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] refactor(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin merged PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "bitflicker64 (via GitHub)" <gi...@apache.org>.
bitflicker64 commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4253638599


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/StandardHugeGraph.java:
##########
@@ -1212,12 +1213,16 @@ public void create(String configPath, GlobalMasterInfo nodeInfo) {

     @Override
     public void drop() {
+        this.checkGraphNotClosed();
+        TaskScheduler scheduler = this.taskManager.getScheduler(this.params);
+        if (scheduler != null && !scheduler.close()) {
+            // Fence admission before waiting for actual task owners to exit.
+            this.waitUntilAllTasksCompleted();

Review Comment:
   Important: When the drop is refused here, the graph is kept but its local scheduler never accepts work again. `scheduler.close()` on line 1218 sets `admissionClosed = true` (`StandardTaskScheduler.java:444`), that is the only assignment to the field, and `schedule()` and `restoreTasks()` then throw `Task scheduler for graph '...' is closing`. `StandardTaskAdmissionTest.testCancelledWorkerFencesAdmissionUntilActualExit` asserts this after a `close()` that returned `false`.

   On master a drop that timed out in `clearBackend()` had not touched the scheduler, so the graph stayed fully usable. At this head, with the default `task.wait_timeout=10`, a delete issued while a job longer than 10 s is running is refused, and from then on every async job on that graph (index rebuild, schema removal, Gremlin job) fails until a later delete succeeds or the server restarts. The new section in `docs/server-runtime.md` says the graph stays registered with its data and configuration and does not mention this. The fence in `GraphManager.dropGraph` (lines 2264-2272) has the same effect for a graph on the local scheduler.

   Please reopen admission when the drop is refused, in both places. If the fence is meant to stay closed, the error message and the runtime doc should say that the graph accepts no tasks until it is deleted or the server restarts.


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/TaskManager.java:
##########
@@ -261,7 +251,8 @@ public ServerInfoManager getServerInfoManager(HugeGraphParams graph) {
     }

     public void shutdown(long timeout) {
-        assert this.schedulers.isEmpty() : this.schedulers.size();
+        E.checkState(this.schedulers.isEmpty(),

Review Comment:
   Important: `HugeFactory.shutdown()` now fails, and leaves every task executor running, whenever one scheduler is still registered. On master this line was an `assert`, which the server does not enable (`bin/hugegraph-server.sh` passes no `-ea`), so shutdown went on to `shutdown()` and `awaitTermination(timeout)` each executor.

   A scheduler stays registered in ordinary cases, not only after a refused deletion. `StandardTaskScheduler.close()` returns `false` as soon as `pendingTasks() != 0` (line 447), and `closeScheduler()` then keeps it (line 132). Stopping a server while one async task is running therefore goes: `graph.close()` fails, `HugeGraphServer.stop()` calls `HugeFactory.shutdown(30L)`, this check throws, and `stop()` only logs `Failed to stop HugeGraph`. The running task loses the up to 30 s it had on master to finish and save its status, `OltpTraverser.destroy()` is skipped, and an embedded caller of `HugeFactory.shutdown(timeout)` now gets `HugeException: Failed to shutdown` with the executors still alive.

   This is from reading the code at bb3ebc85 against 68fb0453, not from a run.

   Could `shutdown()` still stop the executors when schedulers remain? For example: retry `close()` on the retained schedulers within `timeout`, shut the executors down either way, and name the schedulers that never drained in the exception thrown at the end.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4253751467


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/TaskManager.java:
##########
@@ -261,7 +251,8 @@ public ServerInfoManager getServerInfoManager(HugeGraphParams graph) {
     }

     public void shutdown(long timeout) {
-        assert this.schedulers.isEmpty() : this.schedulers.size();
+        E.checkState(this.schedulers.isEmpty(),

Review Comment:
   Independent source cross-check confirms the new early guard skips all executor shutdown/await attempts when a scheduler remains after the final graph-close attempt. The JVM shutdown hook then loses its graceful-drain opportunity; a continuing embedded JVM retains live pools. A task merely running when stop begins is not sufficient if it drains before that final close, and base shutdown was already conditional pool-by-pool.

   One safety constraint on the suggested fix: please do not tear down supporting executors unconditionally while owners are still retained. Distributed scheduler close uses its scheduler executor, and pending tasks still need task-database persistence. A bounded owner drain/close retry followed by safely ordered executor cleanup and explicit retained-owner failure preserves that contract. This is source verification, not a new runtime reproduction.


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/StandardHugeGraph.java:
##########
@@ -1212,12 +1213,16 @@ public void create(String configPath, GlobalMasterInfo nodeInfo) {

     @Override
     public void drop() {
+        this.checkGraphNotClosed();
+        TaskScheduler scheduler = this.taskManager.getScheduler(this.params);
+        if (scheduler != null && !scheduler.close()) {
+            // Fence admission before waiting for actual task owners to exit.
+            this.waitUntilAllTasksCompleted();

Review Comment:
   The persistent admission fence is real, but this part was already raised in https://github.com/apache/hugegraph/pull/3308#discussion_r4240715704 and is consistent with the current retry-only maintenance contract in docs/server-runtime.md. Earlier feedback also required fencing before returning with pending work, so automatic reopening would need an explicit abort protocol for concurrent or partially destructive deletion.

   The smallest safe clarification is to state in the refusal error and runtime guide that new task admission remains closed, deletion can be retried after owners exit, and resuming ordinary use requires an appropriate close/reopen or restart procedure. I would track this as the existing recovery-contract clarification rather than a second newly discovered code defect. No additional runtime test was performed in this cross-check.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#issuecomment-6136236611

   Source cross-check of the current [memory CI error](https://github.com/apache/hugegraph/actions/runs/38330840739/job/115080354182): `ConsumersTest.testAwaitThrowsWhenConsumerThrows` calls `provide(1)` before entering the try/catch around `await()`. If the consumer throws immediately after the offer, `provide()` observes `stopped` and rethrows that original exception first. This matches the uncaught worker exception in this run.

   Both `Consumers.java` and `ConsumersTest.java` are byte-identical in base 68fb045, bb3ebc85, d61a8cd4 and the tested merge. This is a source-supported diagnosis of an existing fixture race, not a reproduced regression introduced by the shutdown correction. A focused fix is to gate the consumer's throw until `provide()` returns, then assert the intended `await()` failure. Please retain the exception assertion rather than weakening it or treating a retry alone as proof. No new test was run for this review.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(server): preserve graphs during task shutdown [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4242958978


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/StandardHugeGraph.java:
##########
@@ -1203,26 +1204,46 @@ public void create(String configPath, GlobalMasterInfo nodeInfo) {
         this.configuration.file(confPath);
     }

+    public synchronized void clearBackendForDrop() {
+        if (!this.dropBackendCleared) {
+            this.clearBackend();
+            this.dropBackendCleared = true;
+        }
+    }
+
     @Override
     public void drop() {
-        this.clearBackend();
+        E.checkState(!this.closed() || this.dropBackendCleared,
+                     "Can't drop an already closed graph '%s' before clearing its backend",
+                     this.spaceGraphName());
+        if (!this.closed()) {
+            TaskScheduler scheduler = this.taskManager.getScheduler(this.params);
+            if (scheduler != null && !scheduler.close()) {

Review Comment:
   Restored the configured wait before destructive cleanup. close() first fences admission; drop() then waits up to task.wait_timeout outside the scheduler monitor and rechecks the close acknowledgement before clearing the backend. A short task can finish and deletion succeeds in the same request. A timeout still retains data, configuration and registrations for retry. The real short-task and active-owner timeout regressions both pass against the unchanged production source.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on code in PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#discussion_r4250798813


##########
hugegraph-server/hugegraph-core/src/main/java/org/apache/hugegraph/task/DistributedTaskScheduler.java:
##########
@@ -120,7 +125,7 @@ private static boolean sleep(long ms) {
         }
     }

-    public void cronSchedule() {
+    public synchronized void cronSchedule() {

Review Comment:
   [P2] Keep the close fence independent of long-running cron work

   Making the entire cronSchedule() method synchronized also puts its database queries and synchronous cancellation callbacks under the scheduler monitor. close() now needs that same monitor before setting closed, so if an in-flight cron is blocked in storage or a callback, close() blocks at monitor acquisition and never reaches the existing timed cron barrier. Previously it could fence admission and return false when that barrier timed out. This can leave graph deletion/shutdown waiting indefinitely instead of returning a retryable refusal.

   Please keep admission coordination narrow, without holding this monitor across cron I/O/callbacks, and add a test that blocks a real cron operation and verifies close can still fence admission and reach its timeout path.

   This was independently cross-checked against base 68fb045 from source; no new runtime reproduction was performed. The current timeout tests mock waitUntilAllTasksCompleted and do not exercise this monitor-contention path.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org
Re: [PR] fix(core): drain tasks before graph deletion [hugegraph]
Posted by "imbajin (via GitHub)" <gi...@apache.org>.
imbajin commented on PR #3308:
URL: https://github.com/apache/hugegraph/pull/3308#issuecomment-6129087552

   The scope has been narrowed to local task admission, physical execution/callback drain, and safe graph deletion. Global lifecycle coordination, hot reload restoration, cross-Server notification reconciliation, task-record deletion recovery, and fallback executors have been removed from this PR and recorded for separate work.

   Previous descriptions claiming those broader guarantees are superseded. Configuration changes require a restart while reload recovery is deferred; all Servers must stop writes and tasks before deletion. The broader website documentation PRs are now drafts pending reconciliation.

   Core regression tests and clean compilation passed. The missing-graph fixture now uses normal GraphManager construction and still requires the original IllegalArgumentException. Current-head Linux CI and complete coverage are pending.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: issues-unsubscribe@hugegraph.apache.org
For additional commands, e-mail: issues-help@hugegraph.apache.org