You are viewing a plain text version of this content. The canonical link for it is here.
Posted to issues@carbondata.apache.org by sv71294 <gi...@git.apache.org> on 2018/06/26 10:37:53 UTC
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
GitHub user sv71294 opened a pull request:

    https://github.com/apache/carbondata/pull/2412

    [CARBONDATA-2656] Presto vector stream readers performance Enhancement

    **Background**:
    In the present system, we create carbonColumnVectorImpl object in carbonVectorbatch where carbon core fill up vector data (one by one) in column matched data type array, later which at the time of presto block builder call, read by stream readers (based on data type) and iterated to fill up in block and returned to presto.

    **Solution**:
    We can eliminate the extra iteration over the carbonColumnVectorImpl object -> vectorArray, by extending it to StreamReaders which will fill up carbon-core vector data (one by one) directly to the block(presto), and on the call of block builder it will return the block to the Presto.

    Be sure to do all of the following checklist to help us incorporate
    your contribution quickly and easily:

     - [x] Any interfaces changed?

     - [x] Any backward compatibility impacted? no

     - [x] Document update required? no

     - [x] Testing done
            Please provide details on
            - Whether new unit test cases have been added or why no new tests are required?
            - How it is tested? Please attach test report.
            - Is it a performance related change? Please attach the performance test report.
            - Any additional information to help reviewers in testing this change.
           [Preformance test report](https://goo.gl/duTMBh)
     - [x] For large changes, please consider breaking it into sub-tasks under an umbrella JIRA.


You can merge this pull request into a Git repository by running:

    $ git pull https://github.com/sv71294/carbondata carbon-presto-direct-reader

Alternatively you can review and apply these changes as the patch at:

    https://github.com/apache/carbondata/pull/2412.patch

To close this pull request, make a commit to your master/trunk branch
with (at least) the following in the commit message:

    This closes #2412

----
commit b5597f8d727ea75dba7935f1505cee97fd56123a
Author: sv71294 <sv...@...>
Date:   2018-06-05T12:14:58Z

    direct vector readers

----


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199069311

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/BooleanStreamReader.java ---
    @@ -17,91 +17,64 @@

     package org.apache.carbondata.presto.readers;

    -import java.io.IOException;
    -
     import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
     import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
     import org.apache.carbondata.core.util.DataTypeUtil;

     import com.facebook.presto.spi.block.Block;
     import com.facebook.presto.spi.block.BlockBuilder;
     import com.facebook.presto.spi.block.BlockBuilderStatus;
    +import com.facebook.presto.spi.type.BooleanType;
     import com.facebook.presto.spi.type.Type;

    -public class BooleanStreamReader extends AbstractStreamReader {
    +public class BooleanStreamReader extends CarbonColumnVectorImpl
    +    implements PrestoVectorBlockBuilder {

    -  private boolean isDictionary;
    -  private Dictionary dictionary;
    +  protected int batchSize;

    -  public BooleanStreamReader() {
    +  protected Type type = BooleanType.BOOLEAN;
    --- End diff --

    added the type for the block bluider


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    @chenliang613 done


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199068654

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/PrestoCarbonVectorizedRecordReader.java ---
    @@ -80,11 +80,14 @@

       private long queryStartTime;

    +  private CarbonDictionaryDecodeReadSupport readSupport;
    +
       public PrestoCarbonVectorizedRecordReader(QueryExecutor queryExecutor, QueryModel queryModel,
    -      AbstractDetailQueryResultIterator iterator) {
    +      AbstractDetailQueryResultIterator iterator, CarbonDictionaryDecodeReadSupport readSupport) {
    --- End diff --

    added dictionary read support for streamReaders


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199068020

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbondataPageSource.java ---
    @@ -166,61 +146,32 @@ protected void closeWithSuppression(Throwable throwable)
       /**
        * Lazy Block Implementation for the Carbondata
        */
    -  private final class CarbondataBlockLoader
    -      implements LazyBlockLoader<LazyBlock>
    -  {
    +  private final class CarbondataBlockLoader implements LazyBlockLoader<LazyBlock> {
         private final int expectedBatchId = batchId;
         private final int columnIndex;
    -    private final Type type;
         private boolean loaded;

    -    public CarbondataBlockLoader(int columnIndex, Type type)
    -    {
    +    CarbondataBlockLoader(int columnIndex) {
           this.columnIndex = columnIndex;
    -      this.type = requireNonNull(type, "type is null");
         }

    -    @Override
    -    public final void load(LazyBlock lazyBlock)
    -    {
    +    @Override public final void load(LazyBlock lazyBlock) {
           if (loaded) {
             return;
           }
           checkState(batchId == expectedBatchId);
           try {
    -        Block block = readers[columnIndex].readBlock(type);
    +        PrestoVectorBlockBuilder blockBuilder =
    +            (PrestoVectorBlockBuilder) vectorReader.getColumnarBatch().column(columnIndex);
    +        blockBuilder.setBatchSize(lazyBlock.getPositionCount());
    +        Block block = blockBuilder.buildBlock();
             sizeOfData += block.getSizeInBytes();
             lazyBlock.setBlock(block);
    -      }
    -      catch (IOException e) {
    +      } catch (Exception e) {
             throw new CarbonDataLoadingException("Error in Reading Data from Carbondata ", e);
           }
           loaded = true;
         }
    -
       }

    -
    -  /**
    -   * Create the Stream Reader for every column based on their type
    -   * This method will be initialized only once based on the types.
    -   *
    -   * @return
    -   */
    -  private StreamReader[] createStreamReaders( ) {
    --- End diff --

    removed from this class moved to CarbonVectorBatch


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/7106/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5787/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199068264

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbondataPageSource.java ---
    @@ -166,61 +146,32 @@ protected void closeWithSuppression(Throwable throwable)
       /**
        * Lazy Block Implementation for the Carbondata
        */
    -  private final class CarbondataBlockLoader
    -      implements LazyBlockLoader<LazyBlock>
    -  {
    +  private final class CarbondataBlockLoader implements LazyBlockLoader<LazyBlock> {
         private final int expectedBatchId = batchId;
         private final int columnIndex;
    -    private final Type type;
         private boolean loaded;

    -    public CarbondataBlockLoader(int columnIndex, Type type)
    -    {
    +    CarbondataBlockLoader(int columnIndex) {
           this.columnIndex = columnIndex;
    -      this.type = requireNonNull(type, "type is null");
         }

    -    @Override
    -    public final void load(LazyBlock lazyBlock)
    -    {
    +    @Override public final void load(LazyBlock lazyBlock) {
           if (loaded) {
             return;
           }
           checkState(batchId == expectedBatchId);
           try {
    -        Block block = readers[columnIndex].readBlock(type);
    +        PrestoVectorBlockBuilder blockBuilder =
    --- End diff --

    getting presto block from the update streamReaders which extends CarbonColumnVectorImpl and implements PrestoVectorBlockBuilder


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199069988

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/BooleanStreamReader.java ---
    @@ -17,91 +17,64 @@

     package org.apache.carbondata.presto.readers;

    -import java.io.IOException;
    -
     import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
     import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
     import org.apache.carbondata.core.util.DataTypeUtil;

     import com.facebook.presto.spi.block.Block;
     import com.facebook.presto.spi.block.BlockBuilder;
     import com.facebook.presto.spi.block.BlockBuilderStatus;
    +import com.facebook.presto.spi.type.BooleanType;
     import com.facebook.presto.spi.type.Type;

    -public class BooleanStreamReader extends AbstractStreamReader {
    +public class BooleanStreamReader extends CarbonColumnVectorImpl
    +    implements PrestoVectorBlockBuilder {

    -  private boolean isDictionary;
    -  private Dictionary dictionary;
    +  protected int batchSize;

    -  public BooleanStreamReader() {
    +  protected Type type = BooleanType.BOOLEAN;

    -  }
    +  protected BlockBuilder builder;

    -  public BooleanStreamReader(boolean isDictionary, Dictionary dictionary) {
    -    this.isDictionary = isDictionary;
    +  private Dictionary dictionary;
    +
    +  public BooleanStreamReader(int batchSize, DataType dataType, Dictionary dictionary) {
    +    super(batchSize, dataType);
    +    this.batchSize = batchSize;
    +    this.builder = type.createBlockBuilder(new BlockBuilderStatus(), batchSize);
         this.dictionary = dictionary;
       }

    -  public Block readBlock(Type type) throws IOException {
    -    int numberOfRows = 0;
    -    BlockBuilder builder = null;
    -    if (isVectorReader) {
    -      numberOfRows = batchSize;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      if (columnVector != null) {
    -        if (isDictionary) {
    -          populateDictionaryVector(type, numberOfRows, builder);
    -        } else {
    -          if (columnVector.anyNullsSet()) {
    -            handleNullInVector(type, numberOfRows, builder);
    -          } else {
    -            populateVector(type, numberOfRows, builder);
    -          }
    -        }
    -      }
    -    } else {
    -      numberOfRows = streamData.length;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      for (int i = 0; i < numberOfRows; i++) {
    -        type.writeBoolean(builder, byteToBoolean(streamData[i]));
    -      }
    -    }
    -
    +  @Override public Block buildBlock() {
         return builder.build();
       }

    -  private void handleNullInVector(Type type, int numberOfRows, BlockBuilder builder) {
    -    for (int i = 0; i < numberOfRows; i++) {
    -      if (columnVector.isNullAt(i)) {
    -        builder.appendNull();
    -      } else {
    -        type.writeBoolean(builder, byteToBoolean(columnVector.getData(i)));
    -      }
    +  @Override public void setBatchSize(int batchSize) {
    +    this.batchSize = batchSize;
    +  }
    +
    +  @Override public void putInt(int rowId, int value) {
    --- End diff --

    in case of dictionary over the column, int is received and the actual value is retrieved from the dictionary support


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5427/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by ravipesala <gi...@git.apache.org>.
Github user ravipesala commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    SDV Build Success , Please check CI http://144.76.159.231:8080/job/ApacheSDVTests/5763/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5390/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by bhavya411 <gi...@git.apache.org>.
Github user bhavya411 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r198136861

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/ObjectStreamReader.java ---
    @@ -17,50 +17,50 @@

     package org.apache.carbondata.presto.readers;

    -import java.io.IOException;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
    +import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;

     import com.facebook.presto.spi.block.Block;
     import com.facebook.presto.spi.block.BlockBuilder;
     import com.facebook.presto.spi.block.BlockBuilderStatus;
    +import com.facebook.presto.spi.type.IntegerType;
     import com.facebook.presto.spi.type.Type;

     /**
      * Class to read the Object Stream
      */
    -public class ObjectStreamReader  extends AbstractStreamReader {
    +public class ObjectStreamReader extends CarbonColumnVectorImpl implements PrestoVectorBlockBuilder {

    +  protected int batchSize;

    +  protected Type type = IntegerType.INTEGER;

    -  public ObjectStreamReader() {
    +  protected BlockBuilder builder;

    +  public ObjectStreamReader(int batchSize, DataType dataType) {
    +    super(batchSize, dataType);
    +    this.batchSize = batchSize;
    +    this.builder = type.createBlockBuilder(new BlockBuilderStatus(), batchSize);
       }

    -  /**
    -   * Function to create the object Block
    -   * @param type
    -   * @return
    -   * @throws IOException
    -   */
    -  public Block readBlock(Type type) throws IOException {
    -    int numberOfRows = 0;
    -    BlockBuilder builder = null;
    -    if (isVectorReader) {
    -      numberOfRows = batchSize;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      if (columnVector != null) {
    -        for (int i = 0; i < numberOfRows; i++) {
    -          type.writeObject(builder, columnVector.getData(i));
    -        }
    -      }
    -    } else {
    -      numberOfRows = streamData.length;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      for (int i = 0; i < numberOfRows; i++) {
    -        type.writeObject(builder, streamData[i]);
    -      }
    -    }
    -
    +  @Override public Block buildBlock(int blockSize) {
    --- End diff --

    remove the parameter blockSize


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5384/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by bhavya411 <gi...@git.apache.org>.
Github user bhavya411 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r198136493

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbondataPageSource.java ---
    @@ -166,61 +146,31 @@ protected void closeWithSuppression(Throwable throwable)
       /**
        * Lazy Block Implementation for the Carbondata
        */
    -  private final class CarbondataBlockLoader
    -      implements LazyBlockLoader<LazyBlock>
    -  {
    +  private final class CarbondataBlockLoader implements LazyBlockLoader<LazyBlock> {
         private final int expectedBatchId = batchId;
         private final int columnIndex;
    -    private final Type type;
         private boolean loaded;

    -    public CarbondataBlockLoader(int columnIndex, Type type)
    -    {
    +    CarbondataBlockLoader(int columnIndex) {
           this.columnIndex = columnIndex;
    -      this.type = requireNonNull(type, "type is null");
         }

    -    @Override
    -    public final void load(LazyBlock lazyBlock)
    -    {
    +    @Override public final void load(LazyBlock lazyBlock) {
           if (loaded) {
             return;
           }
           checkState(batchId == expectedBatchId);
           try {
    -        Block block = readers[columnIndex].readBlock(type);
    +        Block block =
    +            ((PrestoVectorBlockBuilder) vectorReader.getColumnarBatch().column(columnIndex))
    +                .buildBlock(lazyBlock.getPositionCount());
    --- End diff --

    You should be setting the batch size only, no need for two fields


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed  with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/6555/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by ravipesala <gi...@git.apache.org>.
Github user ravipesala commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    SDV Build Success , Please check CI http://144.76.159.231:8080/job/ApacheSDVTests/5899/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199068748

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/PrestoCarbonVectorizedRecordReader.java ---
    @@ -251,6 +251,9 @@ private boolean nextBatch() {
         return false;
       }

    +  public CarbonVectorBatch getColumnarBatch() {
    --- End diff --

    getter function for the columnar batch


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/7017/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed  with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/7011/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5788/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    retest this please


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/6043/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    retest this please


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    @bhavya411 mentioned changes are done, please review the latest code.


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r198116335

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbonVectorBatch.java ---
    @@ -20,50 +20,81 @@
     import java.util.HashSet;
     import java.util.Set;

    +import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
    +import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.metadata.datatype.DecimalType;
     import org.apache.carbondata.core.metadata.datatype.StructField;
     import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
    +import org.apache.carbondata.presto.readers.BooleanStreamReader;
    +import org.apache.carbondata.presto.readers.DecimalSliceStreamReader;
    +import org.apache.carbondata.presto.readers.DoubleStreamReader;
    +import org.apache.carbondata.presto.readers.IntegerStreamReader;
    +import org.apache.carbondata.presto.readers.LongStreamReader;
    +import org.apache.carbondata.presto.readers.ObjectStreamReader;
    +import org.apache.carbondata.presto.readers.ShortStreamReader;
    +import org.apache.carbondata.presto.readers.SliceStreamReader;
    +import org.apache.carbondata.presto.readers.TimestampStreamReader;
    +
    +import com.facebook.presto.spi.block.SliceArrayBlock;

     public class CarbonVectorBatch {

    -  private static final int DEFAULT_BATCH_SIZE =  4 * 1024;
    +  private static final int DEFAULT_BATCH_SIZE = 4 * 1024;

    -  private final StructField[] schema;
       private final int capacity;
    -  private int numRows;
       private final CarbonColumnVectorImpl[] columns;
    -
       // True if the row is filtered.
       private final boolean[] filteredRows;
    -
       // Column indices that cannot have null values.
       private final Set<Integer> nullFilteredColumns;
    -
    +  private int numRows;
       // Total number of rows that have been filtered.
       private int numRowsFiltered = 0;

    -
    -  private CarbonVectorBatch(StructField[] schema, int maxRows) {
    -    this.schema = schema;
    +  private CarbonVectorBatch(StructField[] schema, CarbonDictionaryDecodeReadSupport readSupport,
    +      int maxRows) {
         this.capacity = maxRows;
         this.columns = new CarbonColumnVectorImpl[schema.length];
         this.nullFilteredColumns = new HashSet<>();
         this.filteredRows = new boolean[maxRows];
    +    Dictionary[] dictionaries = readSupport.getDictionaries();
    +    DataType[] dataTypes = readSupport.getDataTypes();

         for (int i = 0; i < schema.length; ++i) {
    -      StructField field = schema[i];
    -      columns[i] = new CarbonColumnVectorImpl(maxRows, field.getDataType());
    +      columns[i] = createDirectStreamReader(maxRows, dataTypes[i], schema[i], dictionaries[i],
    +          readSupport.getSliceArrayBlock(i));
    --- End diff --

    actually, we are getting the index value directly by getSliceArrayBlock instead of the array.


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5797/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    retest this please


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by bhavya411 <gi...@git.apache.org>.
Github user bhavya411 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r198107936

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbonVectorBatch.java ---
    @@ -20,50 +20,81 @@
     import java.util.HashSet;
     import java.util.Set;

    +import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
    +import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.metadata.datatype.DecimalType;
     import org.apache.carbondata.core.metadata.datatype.StructField;
     import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
    +import org.apache.carbondata.presto.readers.BooleanStreamReader;
    +import org.apache.carbondata.presto.readers.DecimalSliceStreamReader;
    +import org.apache.carbondata.presto.readers.DoubleStreamReader;
    +import org.apache.carbondata.presto.readers.IntegerStreamReader;
    +import org.apache.carbondata.presto.readers.LongStreamReader;
    +import org.apache.carbondata.presto.readers.ObjectStreamReader;
    +import org.apache.carbondata.presto.readers.ShortStreamReader;
    +import org.apache.carbondata.presto.readers.SliceStreamReader;
    +import org.apache.carbondata.presto.readers.TimestampStreamReader;
    +
    +import com.facebook.presto.spi.block.SliceArrayBlock;

     public class CarbonVectorBatch {

    -  private static final int DEFAULT_BATCH_SIZE =  4 * 1024;
    +  private static final int DEFAULT_BATCH_SIZE = 4 * 1024;

    -  private final StructField[] schema;
       private final int capacity;
    -  private int numRows;
       private final CarbonColumnVectorImpl[] columns;
    -
       // True if the row is filtered.
       private final boolean[] filteredRows;
    -
       // Column indices that cannot have null values.
       private final Set<Integer> nullFilteredColumns;
    -
    +  private int numRows;
       // Total number of rows that have been filtered.
       private int numRowsFiltered = 0;

    -
    -  private CarbonVectorBatch(StructField[] schema, int maxRows) {
    -    this.schema = schema;
    +  private CarbonVectorBatch(StructField[] schema, CarbonDictionaryDecodeReadSupport readSupport,
    +      int maxRows) {
         this.capacity = maxRows;
         this.columns = new CarbonColumnVectorImpl[schema.length];
         this.nullFilteredColumns = new HashSet<>();
         this.filteredRows = new boolean[maxRows];
    +    Dictionary[] dictionaries = readSupport.getDictionaries();
    +    DataType[] dataTypes = readSupport.getDataTypes();

         for (int i = 0; i < schema.length; ++i) {
    -      StructField field = schema[i];
    -      columns[i] = new CarbonColumnVectorImpl(maxRows, field.getDataType());
    +      columns[i] = createDirectStreamReader(maxRows, dataTypes[i], schema[i], dictionaries[i],
    +          readSupport.getSliceArrayBlock(i));
    --- End diff --

    To be consistent can you get the sliceArrayBlock and pass it on as a parameter.


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199069051

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/AbstractStreamReader.java ---
    @@ -1,66 +0,0 @@
    -/*
    --- End diff --

    no need this class now, as we have updated the interface and now streamReaders extends  CarbonColumnVectorImpl, all functionalities are captured within the reader


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by ravipesala <gi...@git.apache.org>.
Github user ravipesala commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    SDV Build Fail , Please check CI http://144.76.159.231:8080/job/ApacheSDVTests/5760/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by chenliang613 <gi...@git.apache.org>.
Github user chenliang613 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Used the below script to build data:
    ```
    import scala.util.Random
    val r = new Random()
    val df = spark.sparkContext.parallelize(1 to 1000000000).map(x => ("No." + r.nextInt(10000), "country" + x % 8, "city" + x % 50, x % 300)).toDF("ID", "country", "city", "population")
    ```
    Two issues:
    1. On presto client, i ran two times as per the below script but get the different results:
    ```
    presto:default> select country,sum(population) from carbon_table group by country;
     country  |    _col1
    ----------+-------------
     country4 | 18508531250
     country2 | 18758431703
     country0 | 18508717865
     country7 | 18884021774
     country1 | 18633160595
     country5 | 18633480022
     country6 | 18757895175
     country3 | 18883151243
    (8 rows)

    Query 20180630_041406_00004_crn9q, FINISHED, 1 node
    Splits: 65 total, 65 done (100.00%)
    1:01 [1000M rows, 8.4GB] [16.5M rows/s, 142MB/s]

    presto:default> select country,sum(population) from carbon_table group by country;
     country  |    _col1
    ----------+-------------
     country4 | 18500014852
     country0 | 18499993972
     country5 | 18624989449
     country1 | 18625008398
     country3 | 18874966666
     country6 | 18749995166
     country7 | 18874992446
     country2 | 18749999687
    (8 rows)

    Query 20180630_041510_00005_crn9q, FINISHED, 1 node
    Splits: 65 total, 65 done (100.00%)
    0:59 [1000M rows, 8.4GB] [17M rows/s, 146MB/s]
    ```
    2. For aggregation scenarios with 1 billion row data, presto performance is much lower than spark, as below: (presto is around 1 mins, spark is around 33 seconds)
    ```
    scala> benchmark { carbon.sql("select country,sum(population) from carbon_table group by country").show}
    +--------+---------------+
    | country|sum(population)|
    +--------+---------------+
    |country4|    18499998700|
    |country1|    18624998800|
    |country3|    18874998800|
    |country7|    18874998700|
    |country2|    18749998800|
    |country6|    18749998700|
    |country5|    18624998700|
    |country0|    18499998900|
    +--------+---------------+

    33849.999703ms
    ```


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:
https://github.com/apache/carbondata/pull/2412
Hi Liang,
I tried to reproduce the same issue, with provided script, I created the table and executed the SQL.
I am getting the same result with SPARK as well as with PRESTO (within almost same time), please check the attached screenshot.
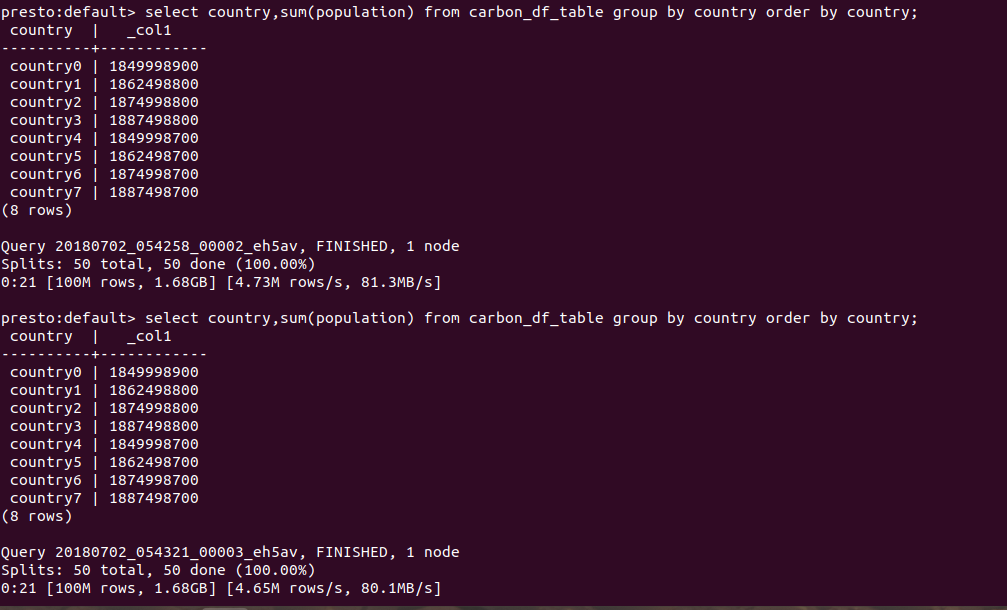
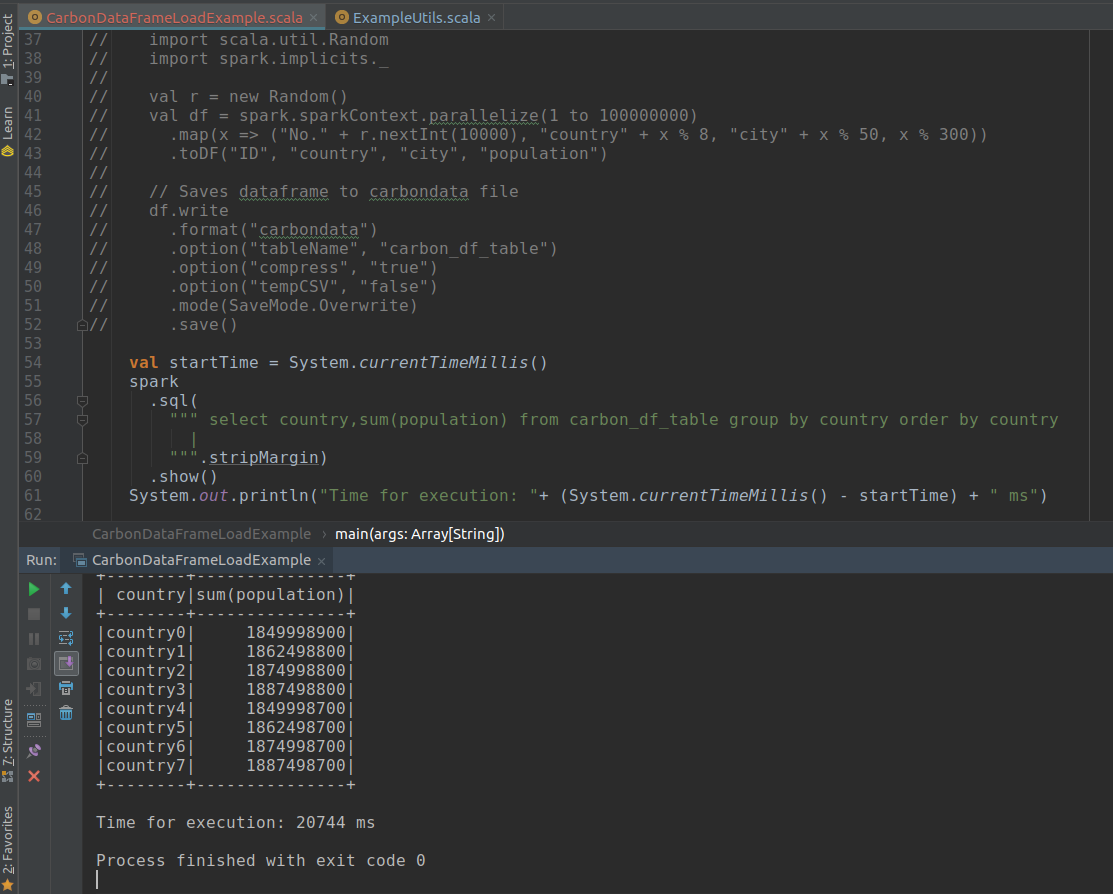
---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed  with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/6577/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by ravipesala <gi...@git.apache.org>.
Github user ravipesala commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    SDV Build Fail , Please check CI http://144.76.159.231:8080/job/ApacheSDVTests/5761/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199066588

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbonVectorBatch.java ---
    @@ -20,50 +20,81 @@
     import java.util.HashSet;
     import java.util.Set;

    +import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
    +import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.metadata.datatype.DecimalType;
     import org.apache.carbondata.core.metadata.datatype.StructField;
     import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
    +import org.apache.carbondata.presto.readers.BooleanStreamReader;
    +import org.apache.carbondata.presto.readers.DecimalSliceStreamReader;
    +import org.apache.carbondata.presto.readers.DoubleStreamReader;
    +import org.apache.carbondata.presto.readers.IntegerStreamReader;
    +import org.apache.carbondata.presto.readers.LongStreamReader;
    +import org.apache.carbondata.presto.readers.ObjectStreamReader;
    +import org.apache.carbondata.presto.readers.ShortStreamReader;
    +import org.apache.carbondata.presto.readers.SliceStreamReader;
    +import org.apache.carbondata.presto.readers.TimestampStreamReader;
    +
    +import com.facebook.presto.spi.block.SliceArrayBlock;

     public class CarbonVectorBatch {

    -  private static final int DEFAULT_BATCH_SIZE =  4 * 1024;
    +  private static final int DEFAULT_BATCH_SIZE = 4 * 1024;

    -  private final StructField[] schema;
       private final int capacity;
    -  private int numRows;
       private final CarbonColumnVectorImpl[] columns;
    -
       // True if the row is filtered.
       private final boolean[] filteredRows;
    -
       // Column indices that cannot have null values.
       private final Set<Integer> nullFilteredColumns;
    -
    +  private int numRows;
       // Total number of rows that have been filtered.
       private int numRowsFiltered = 0;

    -
    -  private CarbonVectorBatch(StructField[] schema, int maxRows) {
    -    this.schema = schema;
    +  private CarbonVectorBatch(StructField[] schema, CarbonDictionaryDecodeReadSupport readSupport,
    +      int maxRows) {
         this.capacity = maxRows;
         this.columns = new CarbonColumnVectorImpl[schema.length];
         this.nullFilteredColumns = new HashSet<>();
         this.filteredRows = new boolean[maxRows];
    +    Dictionary[] dictionaries = readSupport.getDictionaries();
    +    DataType[] dataTypes = readSupport.getDataTypes();

         for (int i = 0; i < schema.length; ++i) {
    -      StructField field = schema[i];
    -      columns[i] = new CarbonColumnVectorImpl(maxRows, field.getDataType());
    +      columns[i] = createDirectStreamReader(maxRows, dataTypes[i], schema[i], dictionaries[i],
    +          readSupport.getSliceArrayBlock(i));
         }
    -
       }

    -
    -  public static CarbonVectorBatch allocate(StructField[] schema) {
    -    return new CarbonVectorBatch(schema, DEFAULT_BATCH_SIZE);
    +  public static CarbonVectorBatch allocate(StructField[] schema,
    --- End diff --

    added the dictionary read support for the stream readers


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by asfgit <gi...@git.apache.org>.
Github user asfgit closed the pull request at:

    https://github.com/apache/carbondata/pull/2412


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199068669

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/PrestoCarbonVectorizedRecordReader.java ---
    @@ -212,7 +213,7 @@ private void initBatch() {
           }
         }

    -    columnarBatch = CarbonVectorBatch.allocate(fields);
    +    columnarBatch = CarbonVectorBatch.allocate(fields, readSupport);
    --- End diff --

    added dictionary read support for streamReaders


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199070321

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/BooleanStreamReader.java ---
    @@ -17,91 +17,64 @@

     package org.apache.carbondata.presto.readers;

    -import java.io.IOException;
    -
     import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
     import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
     import org.apache.carbondata.core.util.DataTypeUtil;

     import com.facebook.presto.spi.block.Block;
     import com.facebook.presto.spi.block.BlockBuilder;
     import com.facebook.presto.spi.block.BlockBuilderStatus;
    +import com.facebook.presto.spi.type.BooleanType;
     import com.facebook.presto.spi.type.Type;

    -public class BooleanStreamReader extends AbstractStreamReader {
    +public class BooleanStreamReader extends CarbonColumnVectorImpl
    +    implements PrestoVectorBlockBuilder {

    -  private boolean isDictionary;
    -  private Dictionary dictionary;
    +  protected int batchSize;

    -  public BooleanStreamReader() {
    +  protected Type type = BooleanType.BOOLEAN;

    -  }
    +  protected BlockBuilder builder;

    -  public BooleanStreamReader(boolean isDictionary, Dictionary dictionary) {
    -    this.isDictionary = isDictionary;
    +  private Dictionary dictionary;
    +
    +  public BooleanStreamReader(int batchSize, DataType dataType, Dictionary dictionary) {
    +    super(batchSize, dataType);
    +    this.batchSize = batchSize;
    +    this.builder = type.createBlockBuilder(new BlockBuilderStatus(), batchSize);
         this.dictionary = dictionary;
       }

    -  public Block readBlock(Type type) throws IOException {
    -    int numberOfRows = 0;
    -    BlockBuilder builder = null;
    -    if (isVectorReader) {
    -      numberOfRows = batchSize;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      if (columnVector != null) {
    -        if (isDictionary) {
    -          populateDictionaryVector(type, numberOfRows, builder);
    -        } else {
    -          if (columnVector.anyNullsSet()) {
    -            handleNullInVector(type, numberOfRows, builder);
    -          } else {
    -            populateVector(type, numberOfRows, builder);
    -          }
    -        }
    -      }
    -    } else {
    -      numberOfRows = streamData.length;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      for (int i = 0; i < numberOfRows; i++) {
    -        type.writeBoolean(builder, byteToBoolean(streamData[i]));
    -      }
    -    }
    -
    +  @Override public Block buildBlock() {
         return builder.build();
       }

    -  private void handleNullInVector(Type type, int numberOfRows, BlockBuilder builder) {
    -    for (int i = 0; i < numberOfRows; i++) {
    -      if (columnVector.isNullAt(i)) {
    -        builder.appendNull();
    -      } else {
    -        type.writeBoolean(builder, byteToBoolean(columnVector.getData(i)));
    -      }
    +  @Override public void setBatchSize(int batchSize) {
    +    this.batchSize = batchSize;
    +  }
    +
    +  @Override public void putInt(int rowId, int value) {
    +    Object data = DataTypeUtil
    +        .getDataBasedOnDataType(dictionary.getDictionaryValueForKey(value), DataTypes.BOOLEAN);
    +    if (data != null) {
    +      type.writeBoolean(builder, (boolean) data);
    +    } else {
    +      builder.appendNull();
         }
       }

    -  private void populateVector(Type type, int numberOfRows, BlockBuilder builder) {
    --- End diff --

    handled by putBoolean


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199067892

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbondataPageSource.java ---
    @@ -108,22 +96,16 @@ public CarbondataPageSource(CarbonDictionaryDecodeReadSupport readSupport,
             return null;
           }

    -      Block[] blocks = new Block[types.size()];
    +      Block[] blocks = new Block[columnHandles.size()];
           for (int column = 0; column < blocks.length; column++) {
    -        Type type = types.get(column);
    --- End diff --

    readers are removed from this class, handled in CarbonVectorBatch


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    retest this please


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199070456

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/BooleanStreamReader.java ---
    @@ -17,91 +17,64 @@

     package org.apache.carbondata.presto.readers;

    -import java.io.IOException;
    -
     import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
     import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
     import org.apache.carbondata.core.util.DataTypeUtil;

     import com.facebook.presto.spi.block.Block;
     import com.facebook.presto.spi.block.BlockBuilder;
     import com.facebook.presto.spi.block.BlockBuilderStatus;
    +import com.facebook.presto.spi.type.BooleanType;
     import com.facebook.presto.spi.type.Type;

    -public class BooleanStreamReader extends AbstractStreamReader {
    +public class BooleanStreamReader extends CarbonColumnVectorImpl
    +    implements PrestoVectorBlockBuilder {

    -  private boolean isDictionary;
    -  private Dictionary dictionary;
    +  protected int batchSize;

    -  public BooleanStreamReader() {
    +  protected Type type = BooleanType.BOOLEAN;

    -  }
    +  protected BlockBuilder builder;

    -  public BooleanStreamReader(boolean isDictionary, Dictionary dictionary) {
    -    this.isDictionary = isDictionary;
    +  private Dictionary dictionary;
    +
    +  public BooleanStreamReader(int batchSize, DataType dataType, Dictionary dictionary) {
    +    super(batchSize, dataType);
    +    this.batchSize = batchSize;
    +    this.builder = type.createBlockBuilder(new BlockBuilderStatus(), batchSize);
         this.dictionary = dictionary;
       }

    -  public Block readBlock(Type type) throws IOException {
    --- End diff --

    builder is created with constructor and insertion function is done within the vector-filling process of CarbonColumnVectorImpl


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    retest this please


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed  with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/6563/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199066373

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbonVectorBatch.java ---
    @@ -20,50 +20,81 @@
     import java.util.HashSet;
     import java.util.Set;

    +import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
    +import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.metadata.datatype.DecimalType;
     import org.apache.carbondata.core.metadata.datatype.StructField;
     import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
    +import org.apache.carbondata.presto.readers.BooleanStreamReader;
    +import org.apache.carbondata.presto.readers.DecimalSliceStreamReader;
    +import org.apache.carbondata.presto.readers.DoubleStreamReader;
    +import org.apache.carbondata.presto.readers.IntegerStreamReader;
    +import org.apache.carbondata.presto.readers.LongStreamReader;
    +import org.apache.carbondata.presto.readers.ObjectStreamReader;
    +import org.apache.carbondata.presto.readers.ShortStreamReader;
    +import org.apache.carbondata.presto.readers.SliceStreamReader;
    +import org.apache.carbondata.presto.readers.TimestampStreamReader;
    +
    +import com.facebook.presto.spi.block.SliceArrayBlock;

     public class CarbonVectorBatch {

    -  private static final int DEFAULT_BATCH_SIZE =  4 * 1024;
    +  private static final int DEFAULT_BATCH_SIZE = 4 * 1024;

    -  private final StructField[] schema;
    --- End diff --

    no need to have this in class level, I have moved it in the constructor


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199066819

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbonVectorBatch.java ---
    @@ -20,50 +20,81 @@
     import java.util.HashSet;
     import java.util.Set;

    +import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
    +import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.metadata.datatype.DecimalType;
     import org.apache.carbondata.core.metadata.datatype.StructField;
     import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
    +import org.apache.carbondata.presto.readers.BooleanStreamReader;
    +import org.apache.carbondata.presto.readers.DecimalSliceStreamReader;
    +import org.apache.carbondata.presto.readers.DoubleStreamReader;
    +import org.apache.carbondata.presto.readers.IntegerStreamReader;
    +import org.apache.carbondata.presto.readers.LongStreamReader;
    +import org.apache.carbondata.presto.readers.ObjectStreamReader;
    +import org.apache.carbondata.presto.readers.ShortStreamReader;
    +import org.apache.carbondata.presto.readers.SliceStreamReader;
    +import org.apache.carbondata.presto.readers.TimestampStreamReader;
    +
    +import com.facebook.presto.spi.block.SliceArrayBlock;

     public class CarbonVectorBatch {

    -  private static final int DEFAULT_BATCH_SIZE =  4 * 1024;
    +  private static final int DEFAULT_BATCH_SIZE = 4 * 1024;

    -  private final StructField[] schema;
       private final int capacity;
    -  private int numRows;
       private final CarbonColumnVectorImpl[] columns;
    -
       // True if the row is filtered.
       private final boolean[] filteredRows;
    -
       // Column indices that cannot have null values.
       private final Set<Integer> nullFilteredColumns;
    -
    +  private int numRows;
       // Total number of rows that have been filtered.
       private int numRowsFiltered = 0;

    -
    -  private CarbonVectorBatch(StructField[] schema, int maxRows) {
    -    this.schema = schema;
    +  private CarbonVectorBatch(StructField[] schema, CarbonDictionaryDecodeReadSupport readSupport,
    +      int maxRows) {
         this.capacity = maxRows;
         this.columns = new CarbonColumnVectorImpl[schema.length];
         this.nullFilteredColumns = new HashSet<>();
         this.filteredRows = new boolean[maxRows];
    +    Dictionary[] dictionaries = readSupport.getDictionaries();
    +    DataType[] dataTypes = readSupport.getDataTypes();

         for (int i = 0; i < schema.length; ++i) {
    -      StructField field = schema[i];
    -      columns[i] = new CarbonColumnVectorImpl(maxRows, field.getDataType());
    +      columns[i] = createDirectStreamReader(maxRows, dataTypes[i], schema[i], dictionaries[i],
    +          readSupport.getSliceArrayBlock(i));
         }
    -
       }

    -
    -  public static CarbonVectorBatch allocate(StructField[] schema) {
    -    return new CarbonVectorBatch(schema, DEFAULT_BATCH_SIZE);
    +  public static CarbonVectorBatch allocate(StructField[] schema,
    +      CarbonDictionaryDecodeReadSupport readSupport) {
    +    return new CarbonVectorBatch(schema, readSupport, DEFAULT_BATCH_SIZE);
       }

    -  public static CarbonVectorBatch allocate(StructField[] schema,  int maxRows) {
    -    return new CarbonVectorBatch(schema, maxRows);
    +  private CarbonColumnVectorImpl createDirectStreamReader(int batchSize, DataType dataType,
    --- End diff --

    added the method to create updated streamReaders (which extends CarbonColumnVectorImpl) instead of CarbonColumnVectorImpl


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/7274/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    retest this please


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199083404

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/DecimalSliceStreamReader.java ---
    @@ -45,80 +45,66 @@
     /**
      * Reader for DecimalValues
      */
    -public class DecimalSliceStreamReader  extends AbstractStreamReader {
    +public class DecimalSliceStreamReader extends CarbonColumnVectorImpl
    +    implements PrestoVectorBlockBuilder {

    +  private final char[] buffer = new char[100];
    +  protected int batchSize;
    +  protected Type type;
    +  protected BlockBuilder builder;
       private Dictionary dictionary;
    -  private boolean isDictionary;

    +  public DecimalSliceStreamReader(int batchSize,
    +      org.apache.carbondata.core.metadata.datatype.DecimalType dataType, Dictionary dictionary) {
    +    super(batchSize, dataType);
    +    this.type = DecimalType.createDecimalType(dataType.getPrecision(), dataType.getScale());
    --- End diff --

    here type is decided with the precision value by the presto whether shortDecimal or longDecimal


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5417/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by chenliang613 <gi...@git.apache.org>.
Github user chenliang613 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    @sv71294
    After setting the below two parameters, my side's test result  be same. but the performance need to check.
    enable.unsafe.columnpage=false
    enable.unsafe.sort=false


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199067368

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbondataPageSource.java ---
    @@ -47,25 +44,18 @@

       private static final LogService logger =
           LogServiceFactory.getLogService(CarbondataPageSource.class.getName());
    -  private final List<Type> types;
    +  private List<ColumnHandle> columnHandles;
       private boolean closed;
       private PrestoCarbonVectorizedRecordReader vectorReader;
    -  private CarbonDictionaryDecodeReadSupport<Object[]> readSupport;
    -  List<ColumnHandle> columnHandles;
       private long sizeOfData = 0;
    -  private final StreamReader[] readers ;
       private int batchId;
       private long nanoStart;
       private long nanoEnd;

    -  public CarbondataPageSource(CarbonDictionaryDecodeReadSupport readSupport,
    -      PrestoCarbonVectorizedRecordReader vectorizedRecordReader,
    -      List<ColumnHandle> columnHandles ) {
    +  CarbondataPageSource(PrestoCarbonVectorizedRecordReader vectorizedRecordReader,
    --- End diff --

    no need of creating streamReader and dictionary read support here, as they are moved to  CarbonVectorBatch


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199063837

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbonVectorBatch.java ---
    @@ -20,50 +20,81 @@
     import java.util.HashSet;
     import java.util.Set;

    +import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
    +import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.metadata.datatype.DecimalType;
     import org.apache.carbondata.core.metadata.datatype.StructField;
     import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
    +import org.apache.carbondata.presto.readers.BooleanStreamReader;
    +import org.apache.carbondata.presto.readers.DecimalSliceStreamReader;
    +import org.apache.carbondata.presto.readers.DoubleStreamReader;
    +import org.apache.carbondata.presto.readers.IntegerStreamReader;
    +import org.apache.carbondata.presto.readers.LongStreamReader;
    +import org.apache.carbondata.presto.readers.ObjectStreamReader;
    +import org.apache.carbondata.presto.readers.ShortStreamReader;
    +import org.apache.carbondata.presto.readers.SliceStreamReader;
    +import org.apache.carbondata.presto.readers.TimestampStreamReader;
    +
    +import com.facebook.presto.spi.block.SliceArrayBlock;

     public class CarbonVectorBatch {

    -  private static final int DEFAULT_BATCH_SIZE =  4 * 1024;
    +  private static final int DEFAULT_BATCH_SIZE = 4 * 1024;

    -  private final StructField[] schema;
       private final int capacity;
    -  private int numRows;
       private final CarbonColumnVectorImpl[] columns;
    -
       // True if the row is filtered.
       private final boolean[] filteredRows;
    -
       // Column indices that cannot have null values.
       private final Set<Integer> nullFilteredColumns;
    -
    +  private int numRows;
       // Total number of rows that have been filtered.
       private int numRowsFiltered = 0;

    -
    -  private CarbonVectorBatch(StructField[] schema, int maxRows) {
    -    this.schema = schema;
    +  private CarbonVectorBatch(StructField[] schema, CarbonDictionaryDecodeReadSupport readSupport,
    --- End diff --

    added the dictionary read support for the stream readers


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5408/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    retest this please


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by chenliang613 <gi...@git.apache.org>.
Github user chenliang613 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    LGTM, verified, this pr can improve the performance by 20%.  Thanks for the contribution.


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by chenliang613 <gi...@git.apache.org>.
Github user chenliang613 commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    @sv71294  can you requash the two commits to one commit.


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by ravipesala <gi...@git.apache.org>.
Github user ravipesala commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    SDV Build Success , Please check CI http://144.76.159.231:8080/job/ApacheSDVTests/5462/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by ravipesala <gi...@git.apache.org>.
Github user ravipesala commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    SDV Build Success , Please check CI http://144.76.159.231:8080/job/ApacheSDVTests/5906/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/6594/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by ravipesala <gi...@git.apache.org>.
Github user ravipesala commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    SDV Build Success , Please check CI http://144.76.159.231:8080/job/ApacheSDVTests/5472/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199070375

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/BooleanStreamReader.java ---
    @@ -17,91 +17,64 @@

     package org.apache.carbondata.presto.readers;

    -import java.io.IOException;
    -
     import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
     import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
     import org.apache.carbondata.core.util.DataTypeUtil;

     import com.facebook.presto.spi.block.Block;
     import com.facebook.presto.spi.block.BlockBuilder;
     import com.facebook.presto.spi.block.BlockBuilderStatus;
    +import com.facebook.presto.spi.type.BooleanType;
     import com.facebook.presto.spi.type.Type;

    -public class BooleanStreamReader extends AbstractStreamReader {
    +public class BooleanStreamReader extends CarbonColumnVectorImpl
    +    implements PrestoVectorBlockBuilder {

    -  private boolean isDictionary;
    -  private Dictionary dictionary;
    +  protected int batchSize;

    -  public BooleanStreamReader() {
    +  protected Type type = BooleanType.BOOLEAN;

    -  }
    +  protected BlockBuilder builder;

    -  public BooleanStreamReader(boolean isDictionary, Dictionary dictionary) {
    -    this.isDictionary = isDictionary;
    +  private Dictionary dictionary;
    +
    +  public BooleanStreamReader(int batchSize, DataType dataType, Dictionary dictionary) {
    +    super(batchSize, dataType);
    +    this.batchSize = batchSize;
    +    this.builder = type.createBlockBuilder(new BlockBuilderStatus(), batchSize);
         this.dictionary = dictionary;
       }

    -  public Block readBlock(Type type) throws IOException {
    -    int numberOfRows = 0;
    -    BlockBuilder builder = null;
    -    if (isVectorReader) {
    -      numberOfRows = batchSize;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      if (columnVector != null) {
    -        if (isDictionary) {
    -          populateDictionaryVector(type, numberOfRows, builder);
    -        } else {
    -          if (columnVector.anyNullsSet()) {
    -            handleNullInVector(type, numberOfRows, builder);
    -          } else {
    -            populateVector(type, numberOfRows, builder);
    -          }
    -        }
    -      }
    -    } else {
    -      numberOfRows = streamData.length;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      for (int i = 0; i < numberOfRows; i++) {
    -        type.writeBoolean(builder, byteToBoolean(streamData[i]));
    -      }
    -    }
    -
    +  @Override public Block buildBlock() {
         return builder.build();
       }

    -  private void handleNullInVector(Type type, int numberOfRows, BlockBuilder builder) {
    -    for (int i = 0; i < numberOfRows; i++) {
    -      if (columnVector.isNullAt(i)) {
    -        builder.appendNull();
    -      } else {
    -        type.writeBoolean(builder, byteToBoolean(columnVector.getData(i)));
    -      }
    +  @Override public void setBatchSize(int batchSize) {
    +    this.batchSize = batchSize;
    +  }
    +
    +  @Override public void putInt(int rowId, int value) {
    +    Object data = DataTypeUtil
    +        .getDataBasedOnDataType(dictionary.getDictionaryValueForKey(value), DataTypes.BOOLEAN);
    +    if (data != null) {
    +      type.writeBoolean(builder, (boolean) data);
    +    } else {
    +      builder.appendNull();
         }
       }

    -  private void populateVector(Type type, int numberOfRows, BlockBuilder builder) {
    -      for (int i = 0; i < numberOfRows; i++) {
    -        type.writeBoolean(builder, byteToBoolean(columnVector.getData(i)));
    -      }
    +  @Override public void putBoolean(int rowId, boolean value) {
    +    type.writeBoolean(builder, value);
       }

    -  private void populateDictionaryVector(Type type, int numberOfRows, BlockBuilder builder) {
    --- End diff --

    handled in putInt


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199070166

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/readers/BooleanStreamReader.java ---
    @@ -17,91 +17,64 @@

     package org.apache.carbondata.presto.readers;

    -import java.io.IOException;
    -
     import org.apache.carbondata.core.cache.dictionary.Dictionary;
    +import org.apache.carbondata.core.metadata.datatype.DataType;
     import org.apache.carbondata.core.metadata.datatype.DataTypes;
    +import org.apache.carbondata.core.scan.result.vector.impl.CarbonColumnVectorImpl;
     import org.apache.carbondata.core.util.DataTypeUtil;

     import com.facebook.presto.spi.block.Block;
     import com.facebook.presto.spi.block.BlockBuilder;
     import com.facebook.presto.spi.block.BlockBuilderStatus;
    +import com.facebook.presto.spi.type.BooleanType;
     import com.facebook.presto.spi.type.Type;

    -public class BooleanStreamReader extends AbstractStreamReader {
    +public class BooleanStreamReader extends CarbonColumnVectorImpl
    +    implements PrestoVectorBlockBuilder {

    -  private boolean isDictionary;
    -  private Dictionary dictionary;
    +  protected int batchSize;

    -  public BooleanStreamReader() {
    +  protected Type type = BooleanType.BOOLEAN;

    -  }
    +  protected BlockBuilder builder;

    -  public BooleanStreamReader(boolean isDictionary, Dictionary dictionary) {
    -    this.isDictionary = isDictionary;
    +  private Dictionary dictionary;
    +
    +  public BooleanStreamReader(int batchSize, DataType dataType, Dictionary dictionary) {
    +    super(batchSize, dataType);
    +    this.batchSize = batchSize;
    +    this.builder = type.createBlockBuilder(new BlockBuilderStatus(), batchSize);
         this.dictionary = dictionary;
       }

    -  public Block readBlock(Type type) throws IOException {
    -    int numberOfRows = 0;
    -    BlockBuilder builder = null;
    -    if (isVectorReader) {
    -      numberOfRows = batchSize;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      if (columnVector != null) {
    -        if (isDictionary) {
    -          populateDictionaryVector(type, numberOfRows, builder);
    -        } else {
    -          if (columnVector.anyNullsSet()) {
    -            handleNullInVector(type, numberOfRows, builder);
    -          } else {
    -            populateVector(type, numberOfRows, builder);
    -          }
    -        }
    -      }
    -    } else {
    -      numberOfRows = streamData.length;
    -      builder = type.createBlockBuilder(new BlockBuilderStatus(), numberOfRows);
    -      for (int i = 0; i < numberOfRows; i++) {
    -        type.writeBoolean(builder, byteToBoolean(streamData[i]));
    -      }
    -    }
    -
    +  @Override public Block buildBlock() {
         return builder.build();
       }

    -  private void handleNullInVector(Type type, int numberOfRows, BlockBuilder builder) {
    -    for (int i = 0; i < numberOfRows; i++) {
    -      if (columnVector.isNullAt(i)) {
    -        builder.appendNull();
    -      } else {
    -        type.writeBoolean(builder, byteToBoolean(columnVector.getData(i)));
    -      }
    +  @Override public void setBatchSize(int batchSize) {
    +    this.batchSize = batchSize;
    +  }
    +
    +  @Override public void putInt(int rowId, int value) {
    +    Object data = DataTypeUtil
    +        .getDataBasedOnDataType(dictionary.getDictionaryValueForKey(value), DataTypes.BOOLEAN);
    +    if (data != null) {
    +      type.writeBoolean(builder, (boolean) data);
    +    } else {
    +      builder.appendNull();
         }
       }

    -  private void populateVector(Type type, int numberOfRows, BlockBuilder builder) {
    -      for (int i = 0; i < numberOfRows; i++) {
    -        type.writeBoolean(builder, byteToBoolean(columnVector.getData(i)));
    -      }
    +  @Override public void putBoolean(int rowId, boolean value) {
    --- End diff --

    here we are directly writing the value to the builder instead of filling into the vector array


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed  with Spark 2.1.0, Please check CI http://136.243.101.176:8080/job/ApacheCarbonPRBuilder1/6585/


---
[GitHub] carbondata pull request #2412: [CARBONDATA-2656] Presto vector stream reader...
Posted by sv71294 <gi...@git.apache.org>.
Github user sv71294 commented on a diff in the pull request:

    https://github.com/apache/carbondata/pull/2412#discussion_r199068497

    --- Diff: integration/presto/src/main/java/org/apache/carbondata/presto/CarbondataPageSourceProvider.java ---
    @@ -103,7 +102,7 @@ private PrestoCarbonVectorizedRecordReader createReader(ConnectorSplit split,
           CarbonIterator iterator = queryExecutor.execute(queryModel);
           readSupport.initialize(queryModel.getProjectionColumns(), queryModel.getTable());
           PrestoCarbonVectorizedRecordReader reader = new PrestoCarbonVectorizedRecordReader(queryExecutor, queryModel,
    -          (AbstractDetailQueryResultIterator) iterator);
    +          (AbstractDetailQueryResultIterator) iterator, readSupport);
    --- End diff --

    added dictionary read support for streamReaders


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Failed with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5396/


---
[GitHub] carbondata issue #2412: [CARBONDATA-2656] Presto vector stream readers perfo...
Posted by CarbonDataQA <gi...@git.apache.org>.
Github user CarbonDataQA commented on the issue:

    https://github.com/apache/carbondata/pull/2412

    Build Success with Spark 2.2.1, Please check CI http://88.99.58.216:8080/job/ApacheCarbonPRBuilder/5882/


---