You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@maka.apache.org by "liugddx (via GitHub)" <gi...@apache.org> on 2026/09/27 06:20:29 UTC
[PR] feat(desktop): continue a partly typed composer draft inline [maka]
liugddx opened a new pull request, #5752:
URL: https://github.com/apache/maka/pull/5752
## Summary
Implements the inline continuation proposed in #5703, on top of #5629's next-prompt suggestions. When the user pauses on a partly typed draft, the composer shows a short continuation as ghost text after the caret. Tab appends it; Esc dismisses it.
| Offer | After Tab | Dark |
|---|---|---|
| 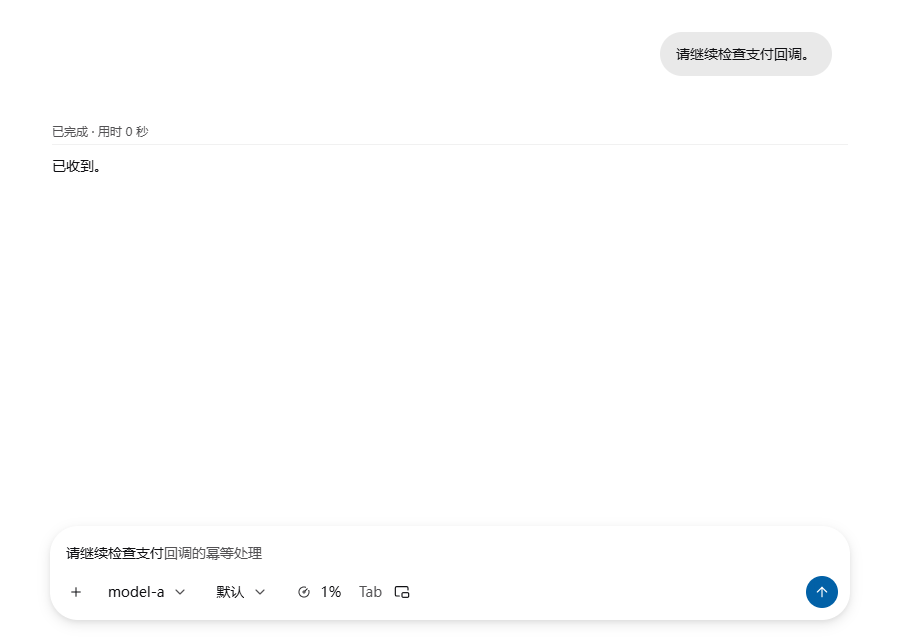 | 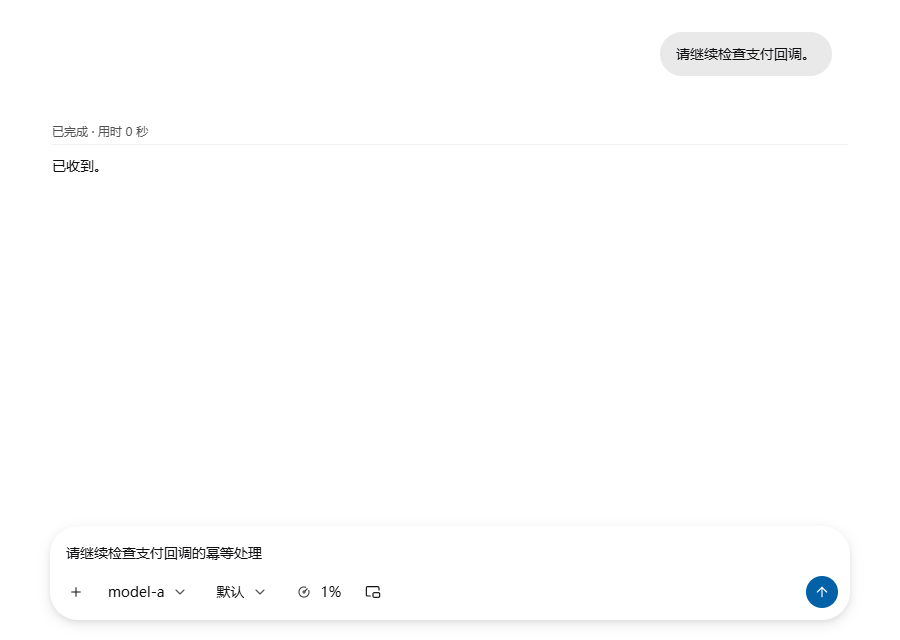 | 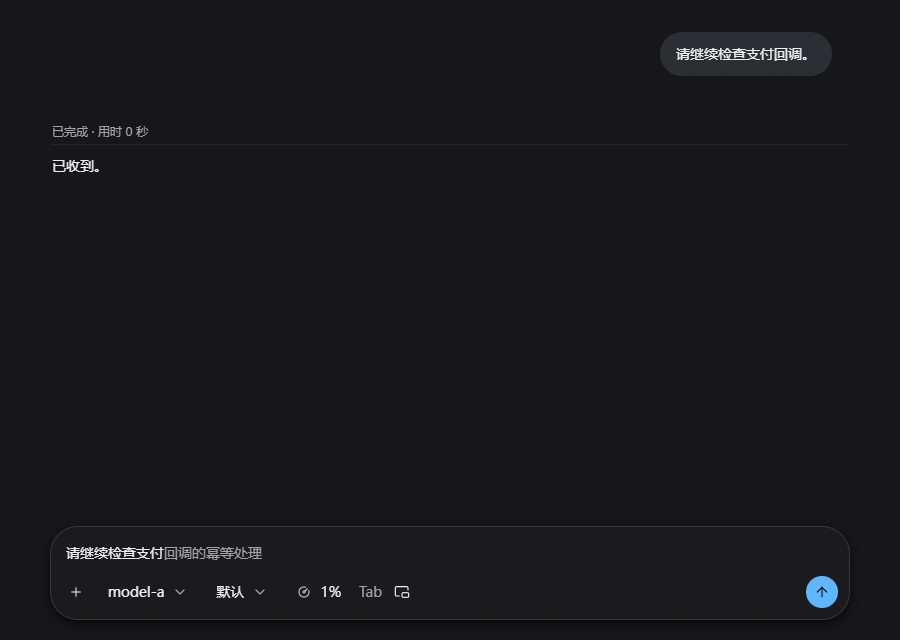 |
**Behaviour**
- **Trigger.** A 350 ms pause after the last edit, on a plain-text draft of at least 4 characters that doesn't end in whitespace and doesn't start with `/`, with the caret collapsed at the end.
- **When nothing is offered.** Inline tokens (mentions, skills, paste chips), an open trigger menu, IME composition, an editor scrolled past `maxRows`, a streaming turn, and the same `blocked` conditions next-prompt suggestions use.
- **Accepting.** Tab appends through native `insertText`, so a single Undo removes it, and nothing is sent. Accepting re-checks that the draft still equals the one the offer was made for and that the caret is still at the end.
- **Dismissing.** Esc dismisses the offer until the draft changes. Any edit hides it immediately.
- **Opt-in.** It uses the same opt-in as next-prompt suggestions, which is off by default.
**Placement without measurement (#4117).** The overlay reuses `.maka-composer-next-prompt`, which already shares the editor's grid cell, typography and wrapping. For a continuation it lays out the draft again with `visibility: hidden`, followed by the offer, so line breaking puts the offer at the caret. Nothing reads layout into state: the hook changes state only on a new draft or a settled request. The price is that drafts containing tokens get no offer. The seam contract test is untouched and passes.
**Host.** The existing `session.prompt-suggestion.generate` takes an optional `prefix` of at most 8 KiB, rejected when blank, so I bumped the compatibility epoch to 193.
- **One request in flight per Session.** A newer draft aborts the older call, so a fast typist pays for at most one call at a time. An identical draft reuses the settled result. This bounds cost without adding a protocol abort frame.
- **Its own prompt.** The model sees only the last 400 characters of the latest assistant reply and the draft; the prompt says to append, not answer, and not invent facts.
- **Its own cleanup.** An echoed prefix is removed. A leading space is kept only after word-separated text, never after CJK. `NO_SUGGESTION` and other meta output is dropped, as is anything over 40 characters.
- **Metering.** Calls are metered under a new call kind, `prompt_continuation`, with Desktop labels for it.
Fixes #5703
## Verification
- **Storybook** (real Chromium, light and dark): `Product/WorkHub › Draft Continuation`, `…Offer` and `…Accepted` play green.
- The offer appears after a pause and ignores pointer events.
- The invisible draft's glyph rects equal the typed draft's, so the offer starts at the caret.
- After Tab, the accepted text's box equals the box the offer had drawn.
- A later edit asks again; Esc dismisses and leaves the draft untouched.
- **Unit tests**
- `ui/prompt-continuation` (new, 4): pause-only requests with the latest draft; late results for an older draft are discarded; Esc suppresses re-asking until an edit; streaming, blocked and an editor veto all send nothing.
- `runtime-host/prompt-suggestion` 21/21, 4 of them new: cleanup, prompt contents, protocol bounds, and a newer draft aborting the in-flight call and reusing a settled one.
- `ui/prompt-suggestion` and the seam contract still pass. `usage-pricing-protocol` 8/8.
- **Checks:** `tsc --noEmit` for `@maka/runtime-host` and `apps/desktop`, Biome on the changed files, the ASF headers, the protocol epoch guard (192 → 193), locale hygiene, renderer architecture (`--strict-base`) and Astryx surface inventory all pass.
- **Not yet verified: real-model continuation quality.** I have a harness that runs Chinese and English partial drafts against a ChatGPT-subscription (`gpt-6-astra`) connection, but my route to chatgpt.com kept resetting TLS during this work, so I have no real-model samples yet. That is why this PR is a draft; I'll post samples, latency and usage here before marking it ready.
- The pre-commit hook cannot run on Windows (#5668, #5677), so I ran its steps manually.
## Review focus
- **The two decisions #5703 asked maintainers to sign off:** placement through an invisible mirrored draft, and one in-flight request per Session instead of a protocol abort frame.
- **Latency.** The 5 s deadline is shared with next-prompt suggestions. The Codex subscription was measured at 3–8 s per call, so some continuations there will time out.
- **One toggle.** A single opt-in currently covers both next-prompt suggestions and continuation.
## AI use
- [ ] No generative tool made a substantive contribution
- [x] Generative tooling made a substantive contribution
Tool(s) and scope: Claude Code (Claude Opus) implemented the feature and tests and ran the verification above; liugddx reviewed. The commit carries a `Generated-by` trailer.
## Checklist
- [x] Tests cover the change and fail without it
- [x] Lint, format, typecheck and the affected suites pass locally
Does this PR entail a change in behavior?
- [x] Yes — described under Summary above
- [ ] No
🤖 Generated with [Claude Code](https://claude.com/claude-code)
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org
Re: [PR] feat(desktop): continue a partly typed composer draft inline [maka]
Posted by "liugddx (via GitHub)" <gi...@apache.org>.
liugddx closed pull request #5752: feat(desktop): continue a partly typed composer draft inline
URL: https://github.com/apache/maka/pull/5752


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org
Re: [PR] feat(desktop): continue a partly typed composer draft inline [maka]
Posted by "liugddx (via GitHub)" <gi...@apache.org>.
liugddx commented on PR #5752:
URL: https://github.com/apache/maka/pull/5752#issuecomment-5854624861

   Real-model samples, which the description left pending. My route to chatgpt.com is still broken on the proxy side (the node fails to dial the apex `chatgpt.com` while `ab.chatgpt.com` and the same IPs work), so I ran these against **DeepSeek `deepseek-flash`** with an API key instead. The feature follows the Session's model, so any connection works.

   Setup: a Runtime Host from this branch on a throwaway root. One turn has the assistant reply with a fixed sentence, then I request `session.prompt-suggestion.generate` with each draft as `prefix`. There were two runs; the second is on e3b097bfa, after the spacing fix below.

   Assistant reply: *"I can refactor the parser now, or add tests for it first. Which would you prefer?"*

   | draft | run 1 | run 2 |
   |---|---|---|
   | `Let's add` | `tests first.` ❌ no leading space | ` tests first.` |
   | `Please refactor` | ` the parser now` | ` the parser` |
   | `Can you also` | ` add tests for it?` | (timeout) |
   | `Thanks, that looks good.` | none ✓ (complete) | none ✓ |

   Assistant reply: *"我可以现在把这个函数改成异步的,或者先补单元测试。你想先做哪个?"*

   | draft | run 1 | run 2 |
   |---|---|---|
   | `先补` | `单元测试` | `测试` |
   | `帮我把这个函数` | `改成异步` | (timeout) |
   | `可以,那就` | (timeout) | `这样吧` |
   | `好的,已经完成了。` | none ✓ (complete) | none ✓ |

   What this showed:
   - **Quality.** Continuations append rather than answer, follow the reply's options, and complete drafts correctly get nothing. Run 1 exposed a real bug: the model dropped the space before a new English word, so accepting would have produced `Let's addtests first.` I fixed it in e3b097bfa. The prompt now asks for a leading space when a new word starts, and cleanup adds one after sentence punctuation. A continuation that completes the current word still gets none.
   - **Cost.** Each call was about 225 input tokens and 130–840 output tokens, almost all of it reasoning, even at the least effort (#5730 sends `reasoningEffort: low` for DeepSeek).
   - **Latency.** 1.3–4.8 s. 3 of 16 requests hit the shared 5 s deadline and showed nothing. That is the main open question here: a model that cannot turn reasoning off is slow and comparatively costly for this. The options I see are to accept that, raise the deadline for continuation only, or offer continuation only on models that can disable reasoning. I'd welcome a maintainer's preference.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org
Re: [PR] feat(desktop): continue a partly typed composer draft inline [maka]
Posted by "Astro-Han (via GitHub)" <gi...@apache.org>.
Astro-Han commented on PR #5752:
URL: https://github.com/apache/maka/pull/5752#issuecomment-5855095818

   Thanks for the careful implementation and for measuring it against a real model. The engineering here is solid. My concern is with the feature itself rather than the code, so I'd rather raise it before more work goes into review rounds.

   I'm not in favour of adding model-driven draft continuation at this point, for these reasons:

   1. **It overlaps with next-prompt suggestions (#5629).** That feature already covers the "help me write the next prompt" case, and this PR shares its opt-in toggle, so users cannot enable one without the other.
   2. **Latency makes the experience unreliable.** Your own run measured 1.3–4.8 s per call, with 3 of 16 requests hitting the 5 s deadline. A continuation that arrives after the user has resumed typing is discarded, so on slower providers (the Codex subscription at 3–8 s) the feature will mostly not appear. Quality also depends entirely on the configured model; the cleanup rules reduce bad output but cannot guarantee useful output.
   3. **It adds a paid model call on every pause.** Even at the lowest reasoning effort you measured 130–840 output tokens per call. The one-in-flight and per-client rate limits raised in the current review are not yet enforced, so a user typing distinct drafts can trigger many billed calls.
   4. **There is little precedent.** None of the major coding agents offer model continuation of a partly typed chat draft; the closest example ships it off by default with warnings about request volume and reasoning-model latency.

   More tests would not change these points, since they are about cost, latency and product scope rather than correctness.

   If there is interest in as-you-type help in the composer, a more predictable direction would be completion from the user's own prompt history (no model call, deterministic, no cost). If the community still wants model continuation, I'd suggest discussing it on #5703 / dev@ first and, if there is consensus, landing it only as a clearly marked experimental feature with its own toggle, an enforced rate limit, and a restriction to fast non-reasoning models.

   I'd prefer we hold this PR until that discussion settles.

   ---
   > **Automated notice:** This comment was posted by an automated agent operated by Astro-Han, at his direction; the position is his.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org
Re: [PR] feat(desktop): continue a partly typed composer draft inline [maka]
Posted by "liugddx (via GitHub)" <gi...@apache.org>.
liugddx commented on PR #5752:
URL: https://github.com/apache/maka/pull/5752#issuecomment-5856959811

   Thank you both. @Astro-Han, I agree with your assessment, and closing this is the right call.

   Our own measurements support your points. With a bring-your-own-model setup, a continuation costs a paid, usually reasoning, call on every pause, and it arrives in 1.3–8 s, often after the user has already typed on. On the real samples it saved only a few generic words; the specific parts of a coding instruction (paths, names, requirements) are exactly what a model cannot predict. The one product I know of that ships this does so on a vendor-chosen fast non-reasoning model at no cost to the user, a premise Maka doesn't have.

   @ARE404, your five findings were all correct: the in-flight bound through cleanup, stale offers after caret or menu changes consuming Tab, the missing rate backstop, the geometry matrix, and the `// Real path:` annotations. They don't need fixing now that the feature is withdrawn, but thanks for the careful review.

   Next-prompt suggestions (#5629) already cover the high-value case of short, predictable replies after a turn. If anything from this is worth keeping, it's few-shot examples in that prompt, which I may propose separately. Closing, and closing #5703 as not planned.


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org


---------------------------------------------------------------------
To unsubscribe, e-mail: commits-unsubscribe@maka.apache.org
For additional commands, e-mail: commits-help@maka.apache.org