You are viewing a plain text version of this content. The canonical link for it is here.
Posted to commits@hudi.apache.org by GitBox <gi...@apache.org> on 2022/12/07 06:10:51 UTC
[GitHub] [hudi] zhuanshenbsj1 opened a new pull request, #7401: [HUDI-5341] IncrementalCleaning consider later clustering
zhuanshenbsj1 opened a new pull request, #7401:
URL: https://github.com/apache/hudi/pull/7401
### Change Logs
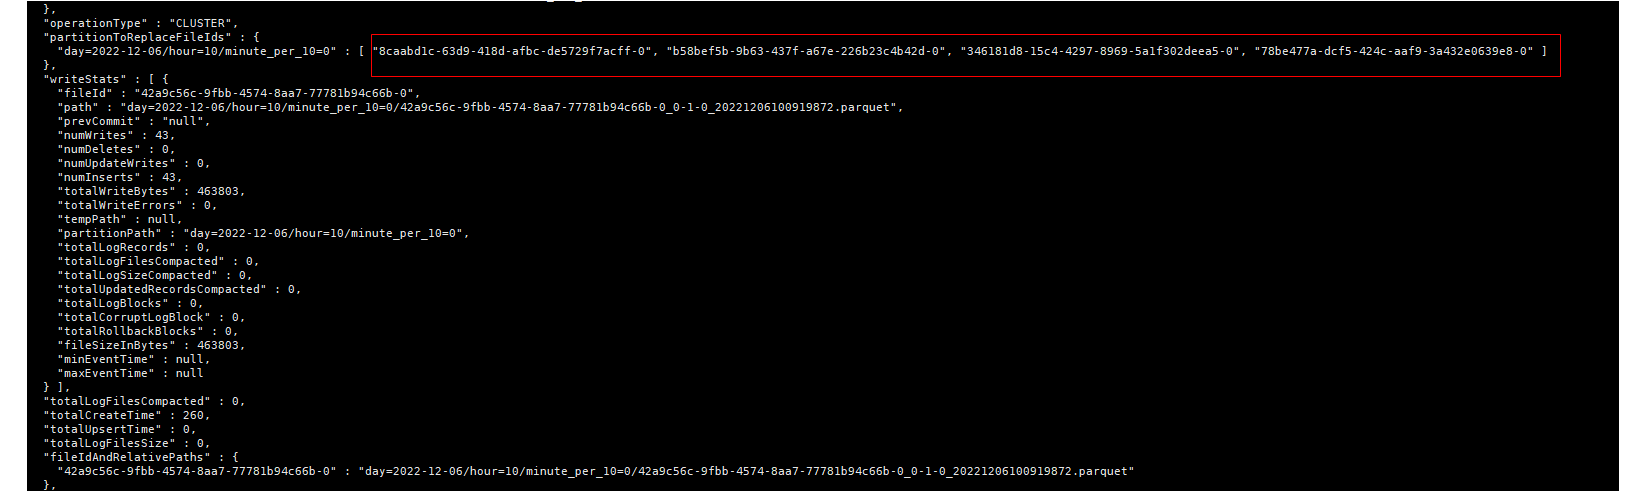
In some scenes, such as offline clustering or online sync clustering(Parallel), later plans could completed before previous plans. If later plan belong to the next partation, and cleaning speed catch up with it,Incremental Cleaning mode for getPartitionPathsForIncrementalCleaning would ignore previous plans ,eventually lead to duplicate data.
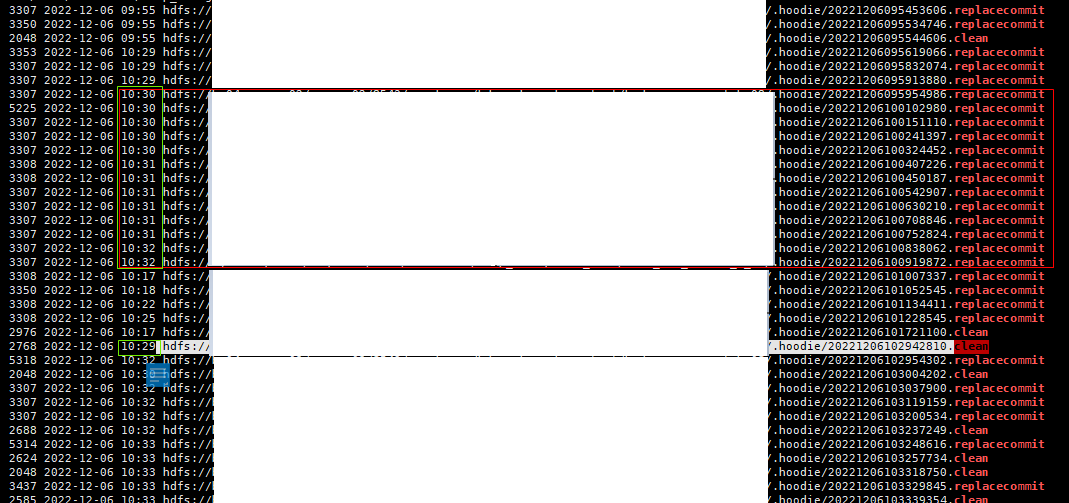
the file belong to previous clustering plan won't clean forever. and it will cause duplicate data when the instants archived.

### Impact
_Describe any public API or user-facing feature change or any performance impact._
### Risk level (write none, low medium or high below)
_If medium or high, explain what verification was done to mitigate the risks._
### Documentation Update
_Describe any necessary documentation update if there is any new feature, config, or user-facing change_
- _The config description must be updated if new configs are added or the default value of the configs are changed_
- _Any new feature or user-facing change requires updating the Hudi website. Please create a Jira ticket, attach the
ticket number here and follow the [instruction](https://hudi.apache.org/contribute/developer-setup#website) to make
changes to the website._
### Contributor's checklist
- [ ] Read through [contributor's guide](https://hudi.apache.org/contribute/how-to-contribute)
- [ ] Change Logs and Impact were stated clearly
- [ ] Adequate tests were added if applicable
- [ ] CI passed
--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.
To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org
For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] zhuanshenbsj1 closed pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
zhuanshenbsj1 closed pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
URL: https://github.com/apache/hudi/pull/7401


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] hudi-bot commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
hudi-bot commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341248769

   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "status" : "FAILURE",
       "url" : "https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504",
       "triggerID" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "triggerType" : "PUSH"
     }, {
       "hash" : "ff0887aff8930a1813f4863563e12d8b3db1b20e",
       "status" : "PENDING",
       "url" : "https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13521",
       "triggerID" : "ff0887aff8930a1813f4863563e12d8b3db1b20e",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * e52b94809103b6fc2bb39dedaf9f88dff133bf6f Azure: [FAILURE](https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504)
   * ff0887aff8930a1813f4863563e12d8b3db1b20e Azure: [PENDING](https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13521)

   <details>
   <summary>Bot commands</summary>
     @hudi-bot supports the following commands:

    - `@hudi-bot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] hudi-bot commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
hudi-bot commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1340898822

   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "status" : "FAILURE",
       "url" : "https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504",
       "triggerID" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * e52b94809103b6fc2bb39dedaf9f88dff133bf6f Azure: [FAILURE](https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504)

   <details>
   <summary>Bot commands</summary>
     @hudi-bot supports the following commands:

    - `@hudi-bot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] hudi-bot commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
hudi-bot commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341239738

   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "status" : "FAILURE",
       "url" : "https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504",
       "triggerID" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "triggerType" : "PUSH"
     }, {
       "hash" : "ff0887aff8930a1813f4863563e12d8b3db1b20e",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "ff0887aff8930a1813f4863563e12d8b3db1b20e",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * e52b94809103b6fc2bb39dedaf9f88dff133bf6f Azure: [FAILURE](https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504)
   * ff0887aff8930a1813f4863563e12d8b3db1b20e UNKNOWN

   <details>
   <summary>Bot commands</summary>
     @hudi-bot supports the following commands:

    - `@hudi-bot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] zhuanshenbsj1 commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
zhuanshenbsj1 commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341915528

   close accidentally. new pr https://github.com/apache/hudi/pull/7405


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] hudi-bot commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
hudi-bot commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1340470467

   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "status" : "UNKNOWN",
       "url" : "TBD",
       "triggerID" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * e52b94809103b6fc2bb39dedaf9f88dff133bf6f UNKNOWN

   <details>
   <summary>Bot commands</summary>
     @hudi-bot supports the following commands:

    - `@hudi-bot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] zhuanshenbsj1 commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
zhuanshenbsj1 commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341895878

   > Somehow i got the point why the data set duplication occurs, it is not because of the out of order execution of clustering, but because the fs view with clustering instants relies on the replace commit metadata to composite the file snapshots with replaced file handles, if we archive a clustering instant that has not been cleaned yet, the replace commit metadata is gone and the duplicates happens.
   >
   > One gold rule for the clustering archiving is: we can only archive the commit only when we make sure it's replaced instant has been cleaned successfully, while this should be very hard i guess because one clustering commit may replace multiple normal commits. A better way is to look up the archive timeline when there are clustering instants on the timeline.
   >
   > WDYT, @nsivabalan :)

   How abourt add a check before archive, require every instant to archive  completed time  must  earlier than the latest cleaning instant start clean time


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] zhuanshenbsj1 commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
zhuanshenbsj1 commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341932419

   close accidentally. reopen


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] hudi-bot commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
hudi-bot commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1340474846

   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "status" : "PENDING",
       "url" : "https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504",
       "triggerID" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * e52b94809103b6fc2bb39dedaf9f88dff133bf6f Azure: [PENDING](https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504)

   <details>
   <summary>Bot commands</summary>
     @hudi-bot supports the following commands:

    - `@hudi-bot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] zhuanshenbsj1 commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
zhuanshenbsj1 commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341887845

   > Somehow i got the point why the data set duplication occurs, it is not because of the out of order execution of clustering, but because the fs view with clustering instants relies on the replace commit metadata to composite the file snapshots with replaced file handles, if we archive a clustering instant that has not been cleaned yet, the replace commit metadata is gone and the duplicates happens.
   >
   > One gold rule for the clustering archiving is: we can only archive the commit only when we make sure it's replaced instant has been cleaned successfully, while this should be very hard i guess because one clustering commit may replace multiple normal commits. A better way is to look up the archive timeline when there are clustering instants on the timeline.
   >
   > WDYT, @nsivabalan :)

   how about when archive instant,  check the instant completed time before cleaning plan generate time


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] zhuanshenbsj1 commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
zhuanshenbsj1 commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341889370

   > Somehow i got the point why the data set duplication occurs, it is not because of the out of order execution of clustering, but because the fs view with clustering instants relies on the replace commit metadata to composite the file snapshots with replaced file handles, if we archive a clustering instant that has not been cleaned yet, the replace commit metadata is gone and the duplicates happens.
   >
   > One gold rule for the clustering archiving is: we can only archive the commit only when we make sure it's replaced instant has been cleaned successfully, while this should be very hard i guess because one clustering commit may replace multiple normal commits. A better way is to look up the archive timeline when there are clustering instants on the timeline.
   >
   > WDYT, @nsivabalan :)


   >


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] hudi-bot commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
hudi-bot commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341811932

   <!--
   Meta data
   {
     "version" : 1,
     "metaDataEntries" : [ {
       "hash" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "status" : "DELETED",
       "url" : "https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13504",
       "triggerID" : "e52b94809103b6fc2bb39dedaf9f88dff133bf6f",
       "triggerType" : "PUSH"
     }, {
       "hash" : "ff0887aff8930a1813f4863563e12d8b3db1b20e",
       "status" : "SUCCESS",
       "url" : "https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13521",
       "triggerID" : "ff0887aff8930a1813f4863563e12d8b3db1b20e",
       "triggerType" : "PUSH"
     } ]
   }-->
   ## CI report:

   * ff0887aff8930a1813f4863563e12d8b3db1b20e Azure: [SUCCESS](https://dev.azure.com/apache-hudi-ci-org/785b6ef4-2f42-4a89-8f0e-5f0d7039a0cc/_build/results?buildId=13521)

   <details>
   <summary>Bot commands</summary>
     @hudi-bot supports the following commands:

    - `@hudi-bot run azure` re-run the last Azure build
   </details>


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org
[GitHub] [hudi] danny0405 commented on pull request #7401: [HUDI-5341] IncrementalCleaning consider later clustering
Posted by GitBox <gi...@apache.org>.
danny0405 commented on PR #7401:
URL: https://github.com/apache/hudi/pull/7401#issuecomment-1341880971

   Somehow i got the point why the data set duplication occurs, it is not because of the out of order execution of clustering, but because the fs view with clustering instants relies on the replace commit metadata to composite the file snapshots with replaced file handles, if we archive a clustering instant that has not been cleaned yet, the replace commit metadata is gone and the duplicates happens.

   One gold rule for the clustering archiving is: we can only archive the commit only when we make sure it's replaced instant has been cleaned successfully, while this should be very hard i guess because one clustering commit may replace multiple normal commits. A better way is to look up the archive timeline when there are clustering instants on the timeline.

   WDYT, @nsivabalan :)


--
This is an automated message from the Apache Git Service.
To respond to the message, please log on to GitHub and use the
URL above to go to the specific comment.

To unsubscribe, e-mail: commits-unsubscribe@hudi.apache.org

For queries about this service, please contact Infrastructure at:
users@infra.apache.org